
Triton based sparse quantization attention kernel collection
Python
43
8 commits
updated Aug 29, 2025
README
Attention-Gym: Triton-Based Sparse and Quantization Attention
Attention-Gym is a flexible and efficient framework built on Triton, designed to help researchers and developers rapidly implement, test, and validate innovative attention mechanisms. With support for sparse and quantized attention, it provides a powerful base environment for experimenting with new algorithms and optimizing existing ones.
Requirements
python>=3.9,torch>=2.3.0,triton>=3.0.0,NVIDIA GPUs (Compute Capability 8.0+)Notice: FP8 dtype is only supported on NVIDIA GPUs (Compute Capability 9.0+)
Installation
pip install -e.
Kernels
Now Support:
- flash_attention2
- sliding_tile_attention
- sageattn_qk_int8_pv_fp16
- sageattn_qk_int8_pv_fp8
- sparge_sageattn_qk_int8_pv_fp16
- sparge_sageattn_qk_int8_pv_fp8
How to Use
To easy use:
import attention_gym
out = attention_gym.sageattn_qk_int8_pv_fp16_triton(q, k, v, tensor_layout="HND", is_causal=False)
q, k, vare FP16/BF16 dtype with the shape(batch_size, head_num, seq_len, head_dim)using defaulttensor_layout="HND". For shape(batch_size, seq_len, head_num, head_dim), settensor_layout="NHD".is_causaldetermines the use of a causal mask.
Kernel Tests
To run the tests:
pytest tests/test_sageattn_qk_int8_pv_fp16.py
Kernel Benchmark
To run the benchmarks:
python benchmarks/benchmark_sage1.py
End-to-end Performance And Accuracy
Here we compare the end-to-end performance and accuracy of the original algorithm author's CUDA implementation and the attention-gym triton implementation of each algorithm.
| Algorithm | CUDA | CUDA Time | Triton | Triton Time | Env |
|---|---|---|---|---|---|
| STA | 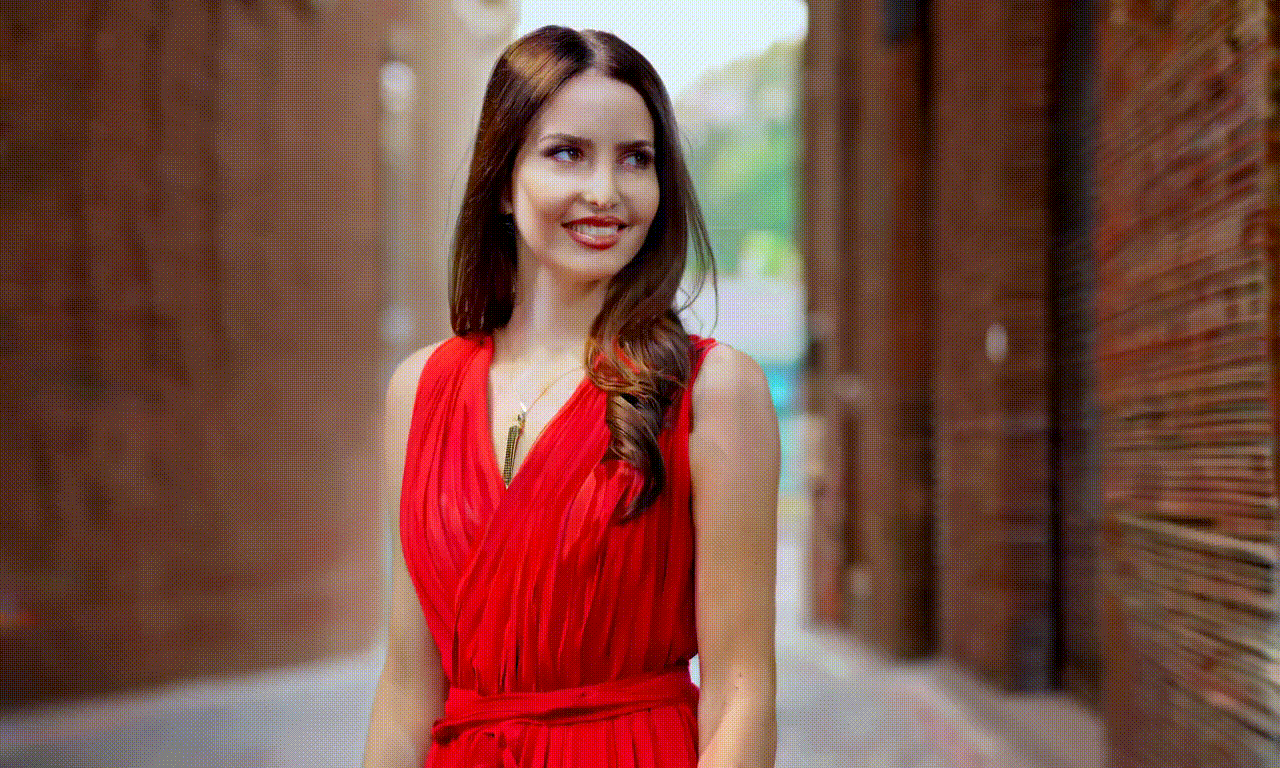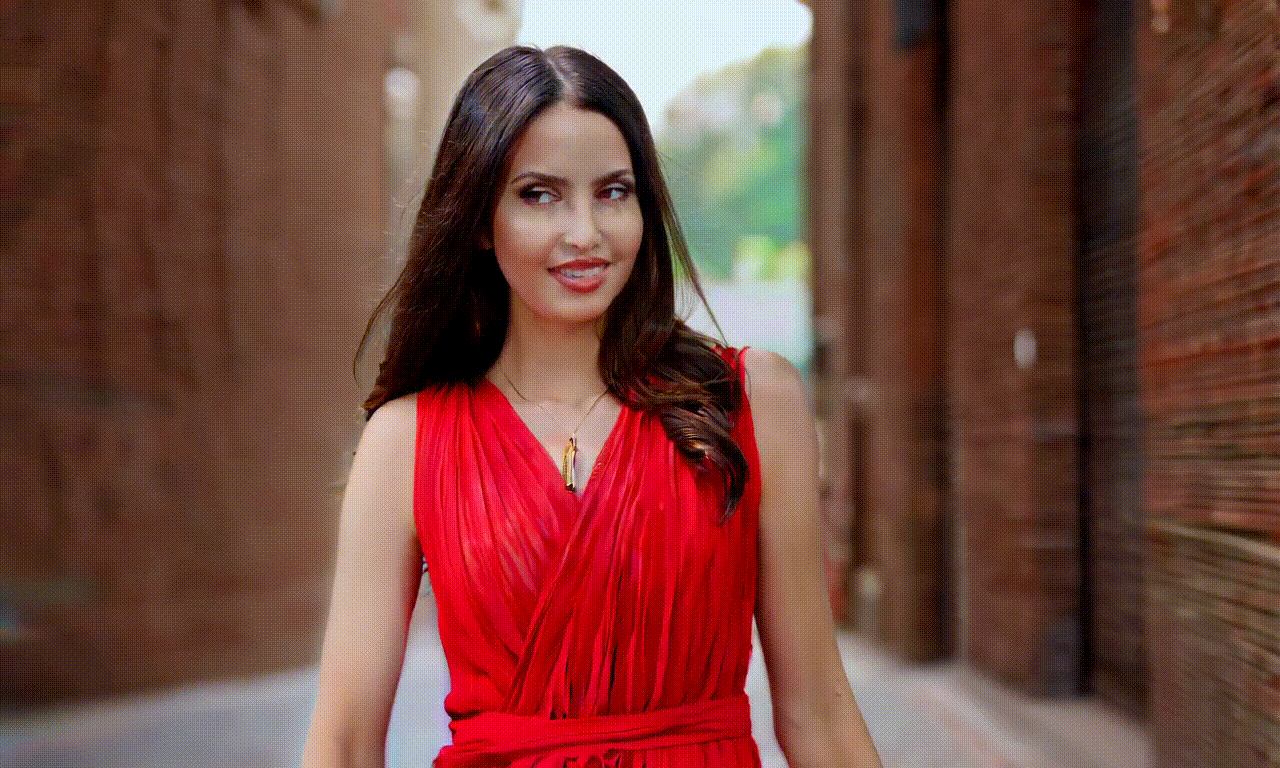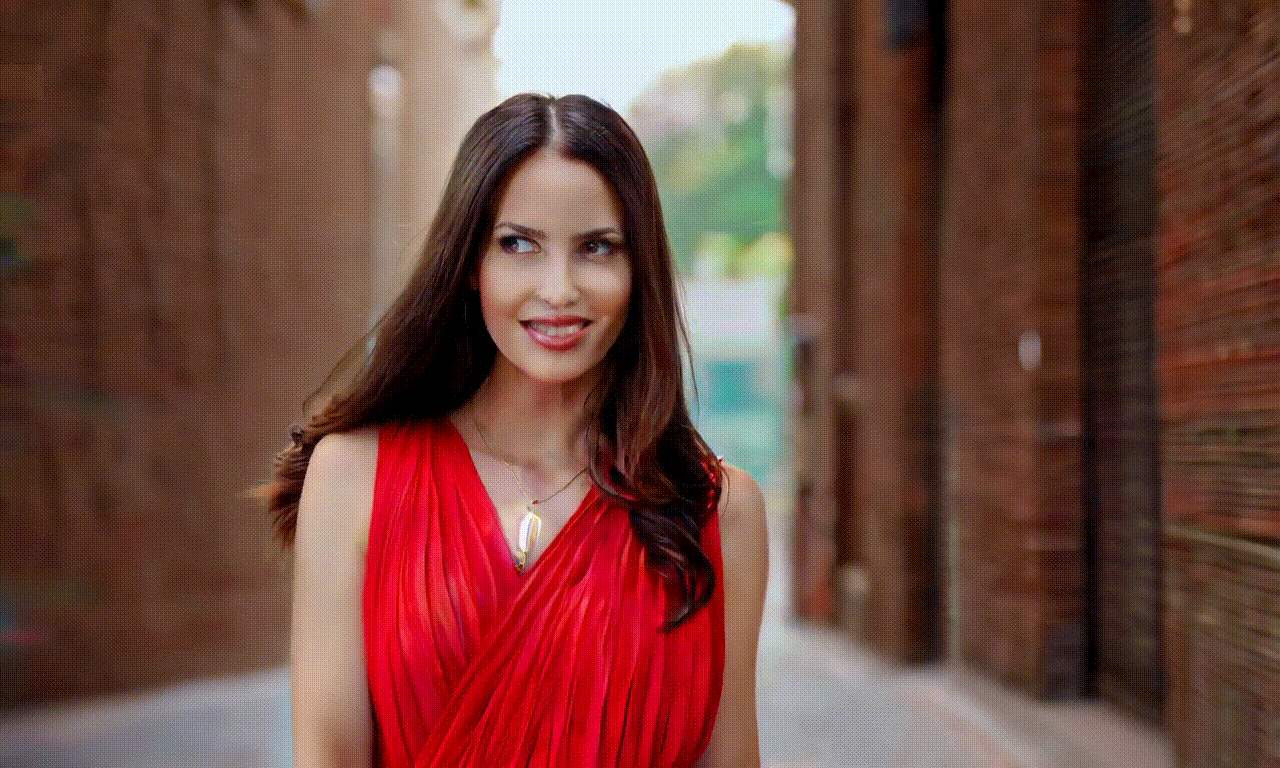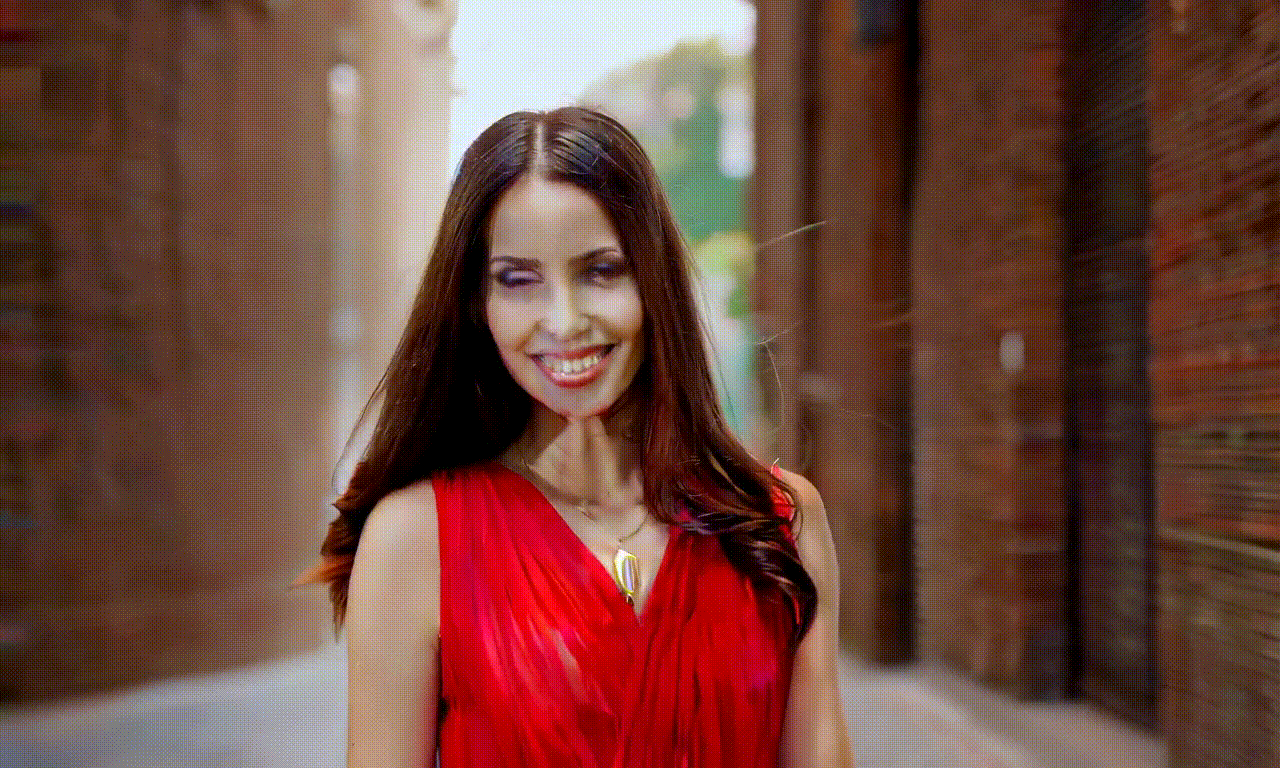 | 1639.61s | 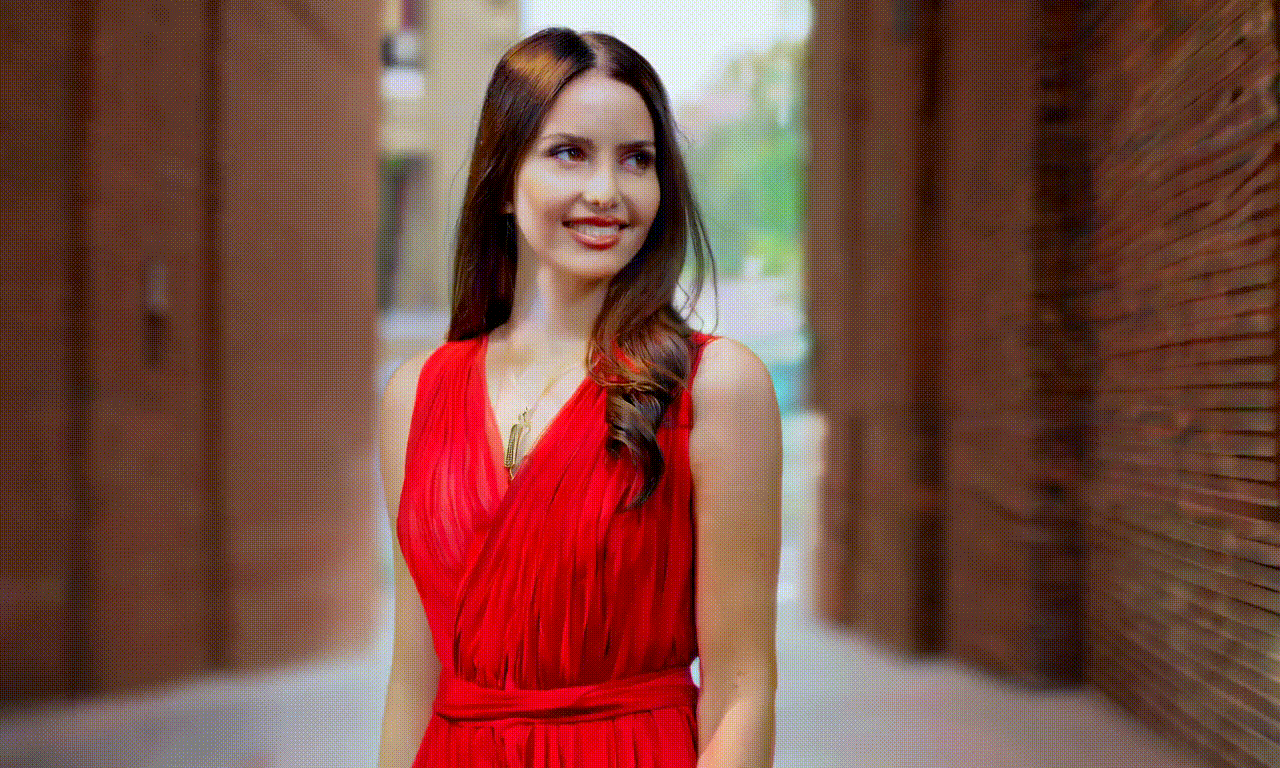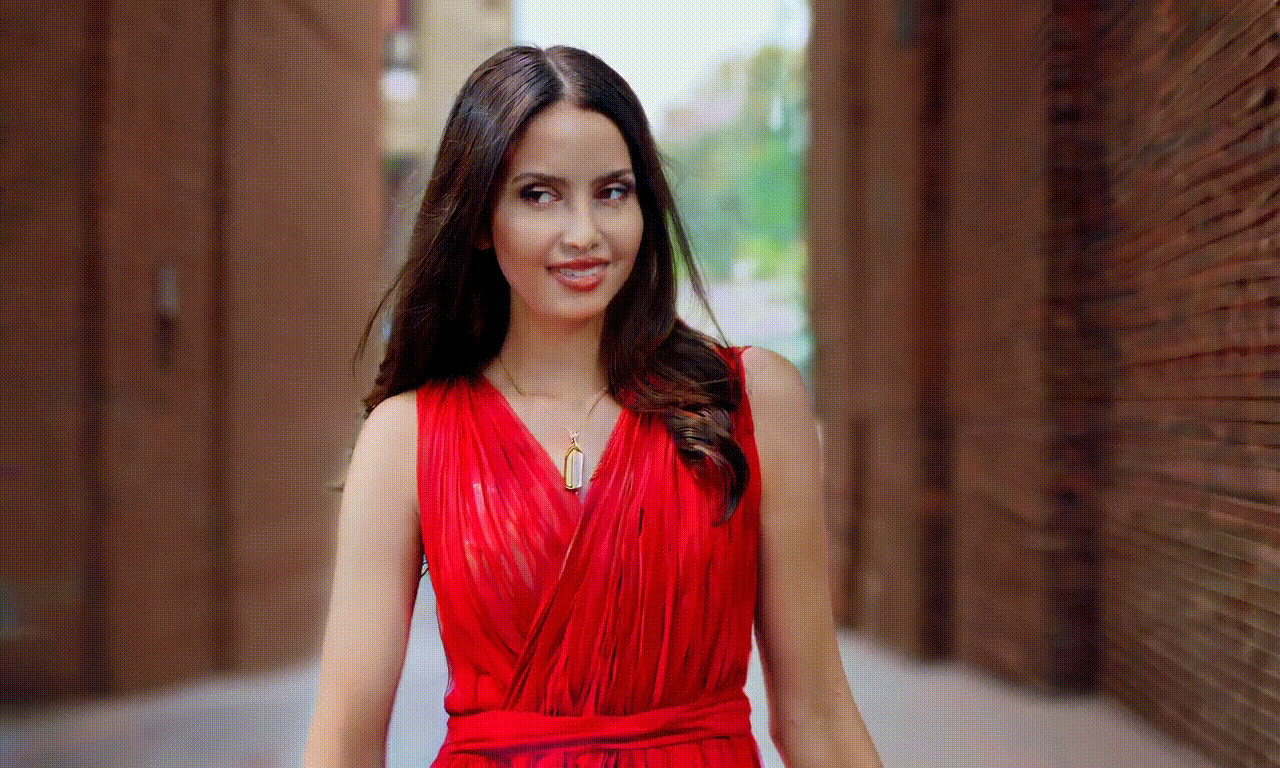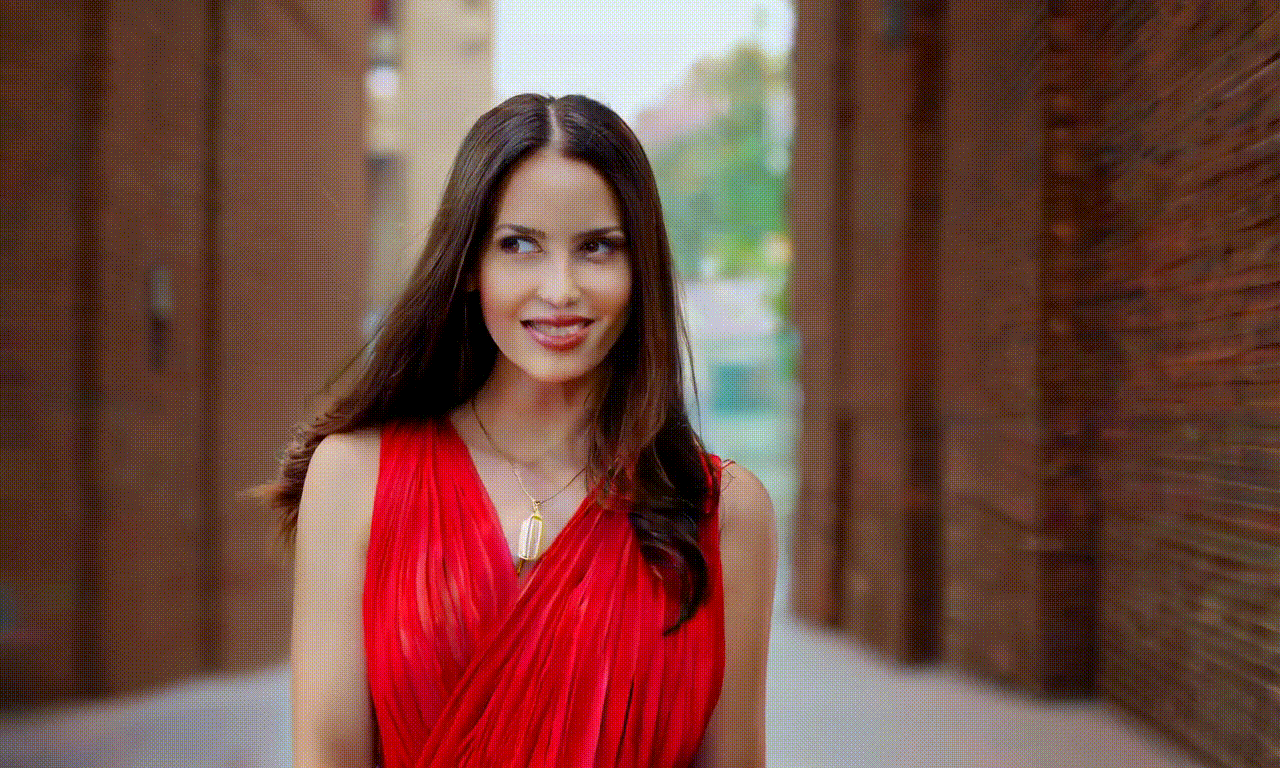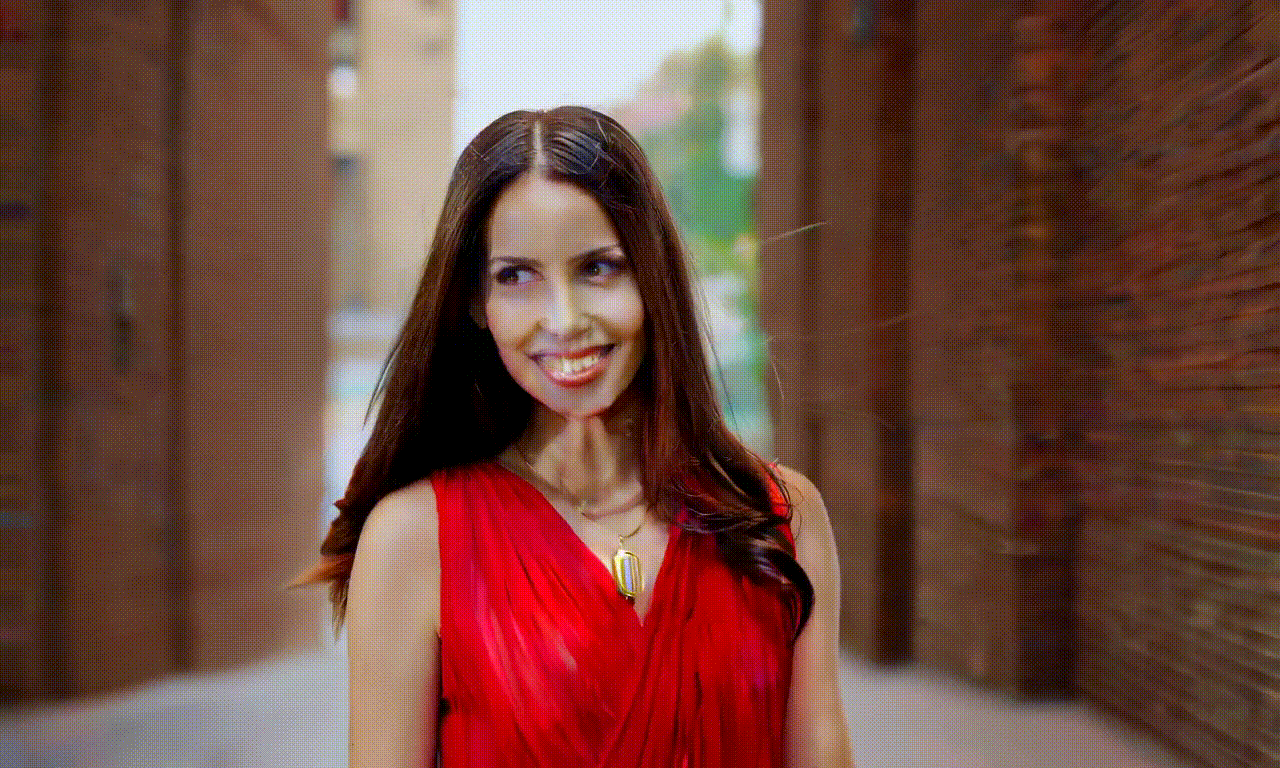 | 1853.24s | wanx2.1-14B H20 2-gpus |
| sparge_sage2 |  | 260s |  | 268s | wanx2.1-1.3B H20 1-gpu |
| sage2 | 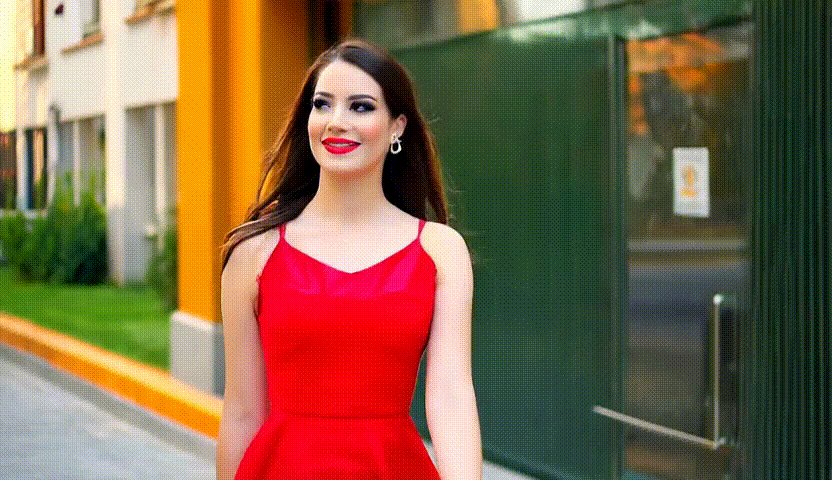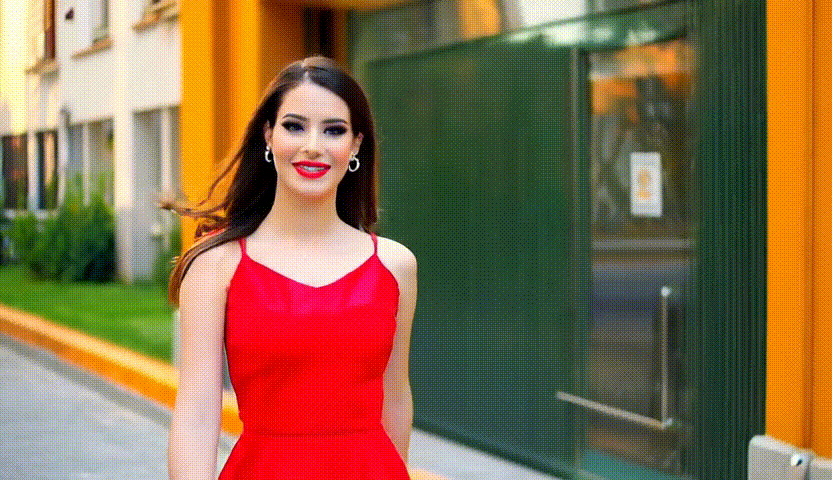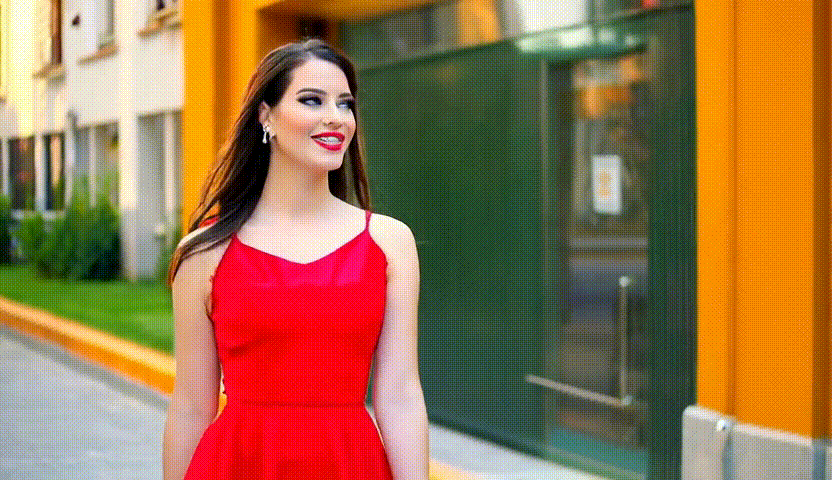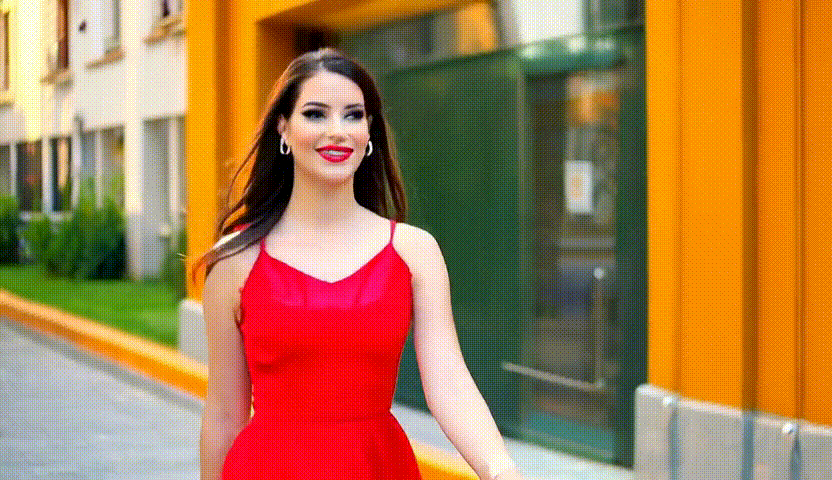 | 348.95s |  | 359.94s | wanx2.1-1.3B H20 1-gpu |
Acknowledgement
We learned the design and resued some code from the following projects: triton, FastVideo, SpargeAttn, SageAttention
Similar repos


Languages
Python
100.0%
Triton based sparse quantization attention kernel collection
Python
43
8 commits
updated Aug 29, 2025
README
Attention-Gym: Triton-Based Sparse and Quantization Attention
Attention-Gym is a flexible and efficient framework built on Triton, designed to help researchers and developers rapidly implement, test, and validate innovative attention mechanisms. With support for sparse and quantized attention, it provides a powerful base environment for experimenting with new algorithms and optimizing existing ones.
Requirements
python>=3.9,torch>=2.3.0,triton>=3.0.0,NVIDIA GPUs (Compute Capability 8.0+)Notice: FP8 dtype is only supported on NVIDIA GPUs (Compute Capability 9.0+)
Installation
pip install -e.
Kernels
Now Support:
- flash_attention2
- sliding_tile_attention
- sageattn_qk_int8_pv_fp16
- sageattn_qk_int8_pv_fp8
- sparge_sageattn_qk_int8_pv_fp16
- sparge_sageattn_qk_int8_pv_fp8
How to Use
To easy use:
import attention_gym
out = attention_gym.sageattn_qk_int8_pv_fp16_triton(q, k, v, tensor_layout="HND", is_causal=False)
q, k, vare FP16/BF16 dtype with the shape(batch_size, head_num, seq_len, head_dim)using defaulttensor_layout="HND". For shape(batch_size, seq_len, head_num, head_dim), settensor_layout="NHD".is_causaldetermines the use of a causal mask.
Kernel Tests
To run the tests:
pytest tests/test_sageattn_qk_int8_pv_fp16.py
Kernel Benchmark
To run the benchmarks:
python benchmarks/benchmark_sage1.py
End-to-end Performance And Accuracy
Here we compare the end-to-end performance and accuracy of the original algorithm author's CUDA implementation and the attention-gym triton implementation of each algorithm.
| Algorithm | CUDA | CUDA Time | Triton | Triton Time | Env |
|---|---|---|---|---|---|
| STA | | 1639.61s | | 1853.24s | wanx2.1-14B H20 2-gpus |
| sparge_sage2 | | 260s | | 268s | wanx2.1-1.3B H20 1-gpu |
| sage2 | | 348.95s | | 359.94s | wanx2.1-1.3B H20 1-gpu |
Acknowledgement
We learned the design and resued some code from the following projects: triton, FastVideo, SpargeAttn, SageAttention
Similar repos
Languages
Python
100.0%