
README
LLM KV Cache Sparsity
Implement some method of LLM KV Cache Sparsity, including:
- Efficient Streaming Language Models with Attention Sinks, also called "SinkCache"
- H2O: Heavy-Hitter Oracle for Efficient Generative Inference of Large Language Models
- SnapKV: LLM Knows What You are Looking for Before Generation
To Run
pip install -r requirements.txt
# edit longbench loading method `load_from_disk` in example/test.py
python example/test.py --sparsity_method snapkv
The result file will write to results folder.
Then you can use longbench_eval/eval.py to get the scores.
The core code for KV Cache eviction is in models/kv_clusters.py
Results
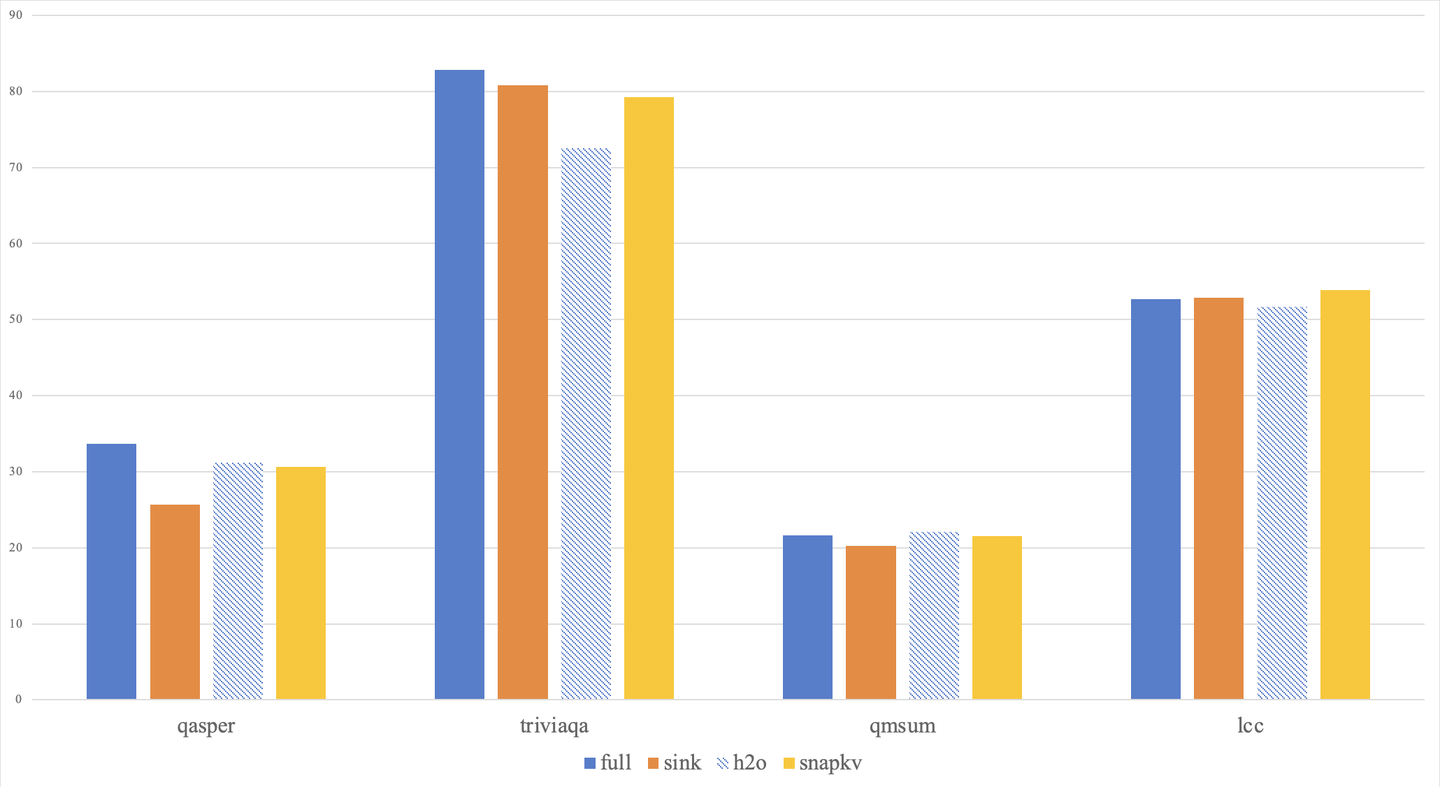
Todo
- Sink, H2O, SnapKV
- DejaVu
Similar repos


Languages
Python
100.0%
README
LLM KV Cache Sparsity
Implement some method of LLM KV Cache Sparsity, including:
- Efficient Streaming Language Models with Attention Sinks, also called "SinkCache"
- H2O: Heavy-Hitter Oracle for Efficient Generative Inference of Large Language Models
- SnapKV: LLM Knows What You are Looking for Before Generation
To Run
pip install -r requirements.txt
# edit longbench loading method `load_from_disk` in example/test.py
python example/test.py --sparsity_method snapkv
The result file will write to results folder.
Then you can use longbench_eval/eval.py to get the scores.
The core code for KV Cache eviction is in models/kv_clusters.py
Results
Todo
- Sink, H2O, SnapKV
- DejaVu
Similar repos
Languages
Python
100.0%