Advanced hate speech detection in Tamil-English code-mixed social media content using hybrid deep learning architectures.
Jupyter Notebook
0
1 commits
updated Jul 30, 2025

🎯 Advanced hate speech detection in Tamil-English code-mixed social media content using hybrid deep learning architectures
This repository contains our award-winning submission to the LT-EDI 2025 shared task on caste and migration-based hate speech detection in code-mixed Tamil social media content. Our innovative multi-scale hybrid architecture combines classical TF-IDF features with state-of-the-art transformer embeddings, achieving 3rd place with an impressive F1-score of 0.818.
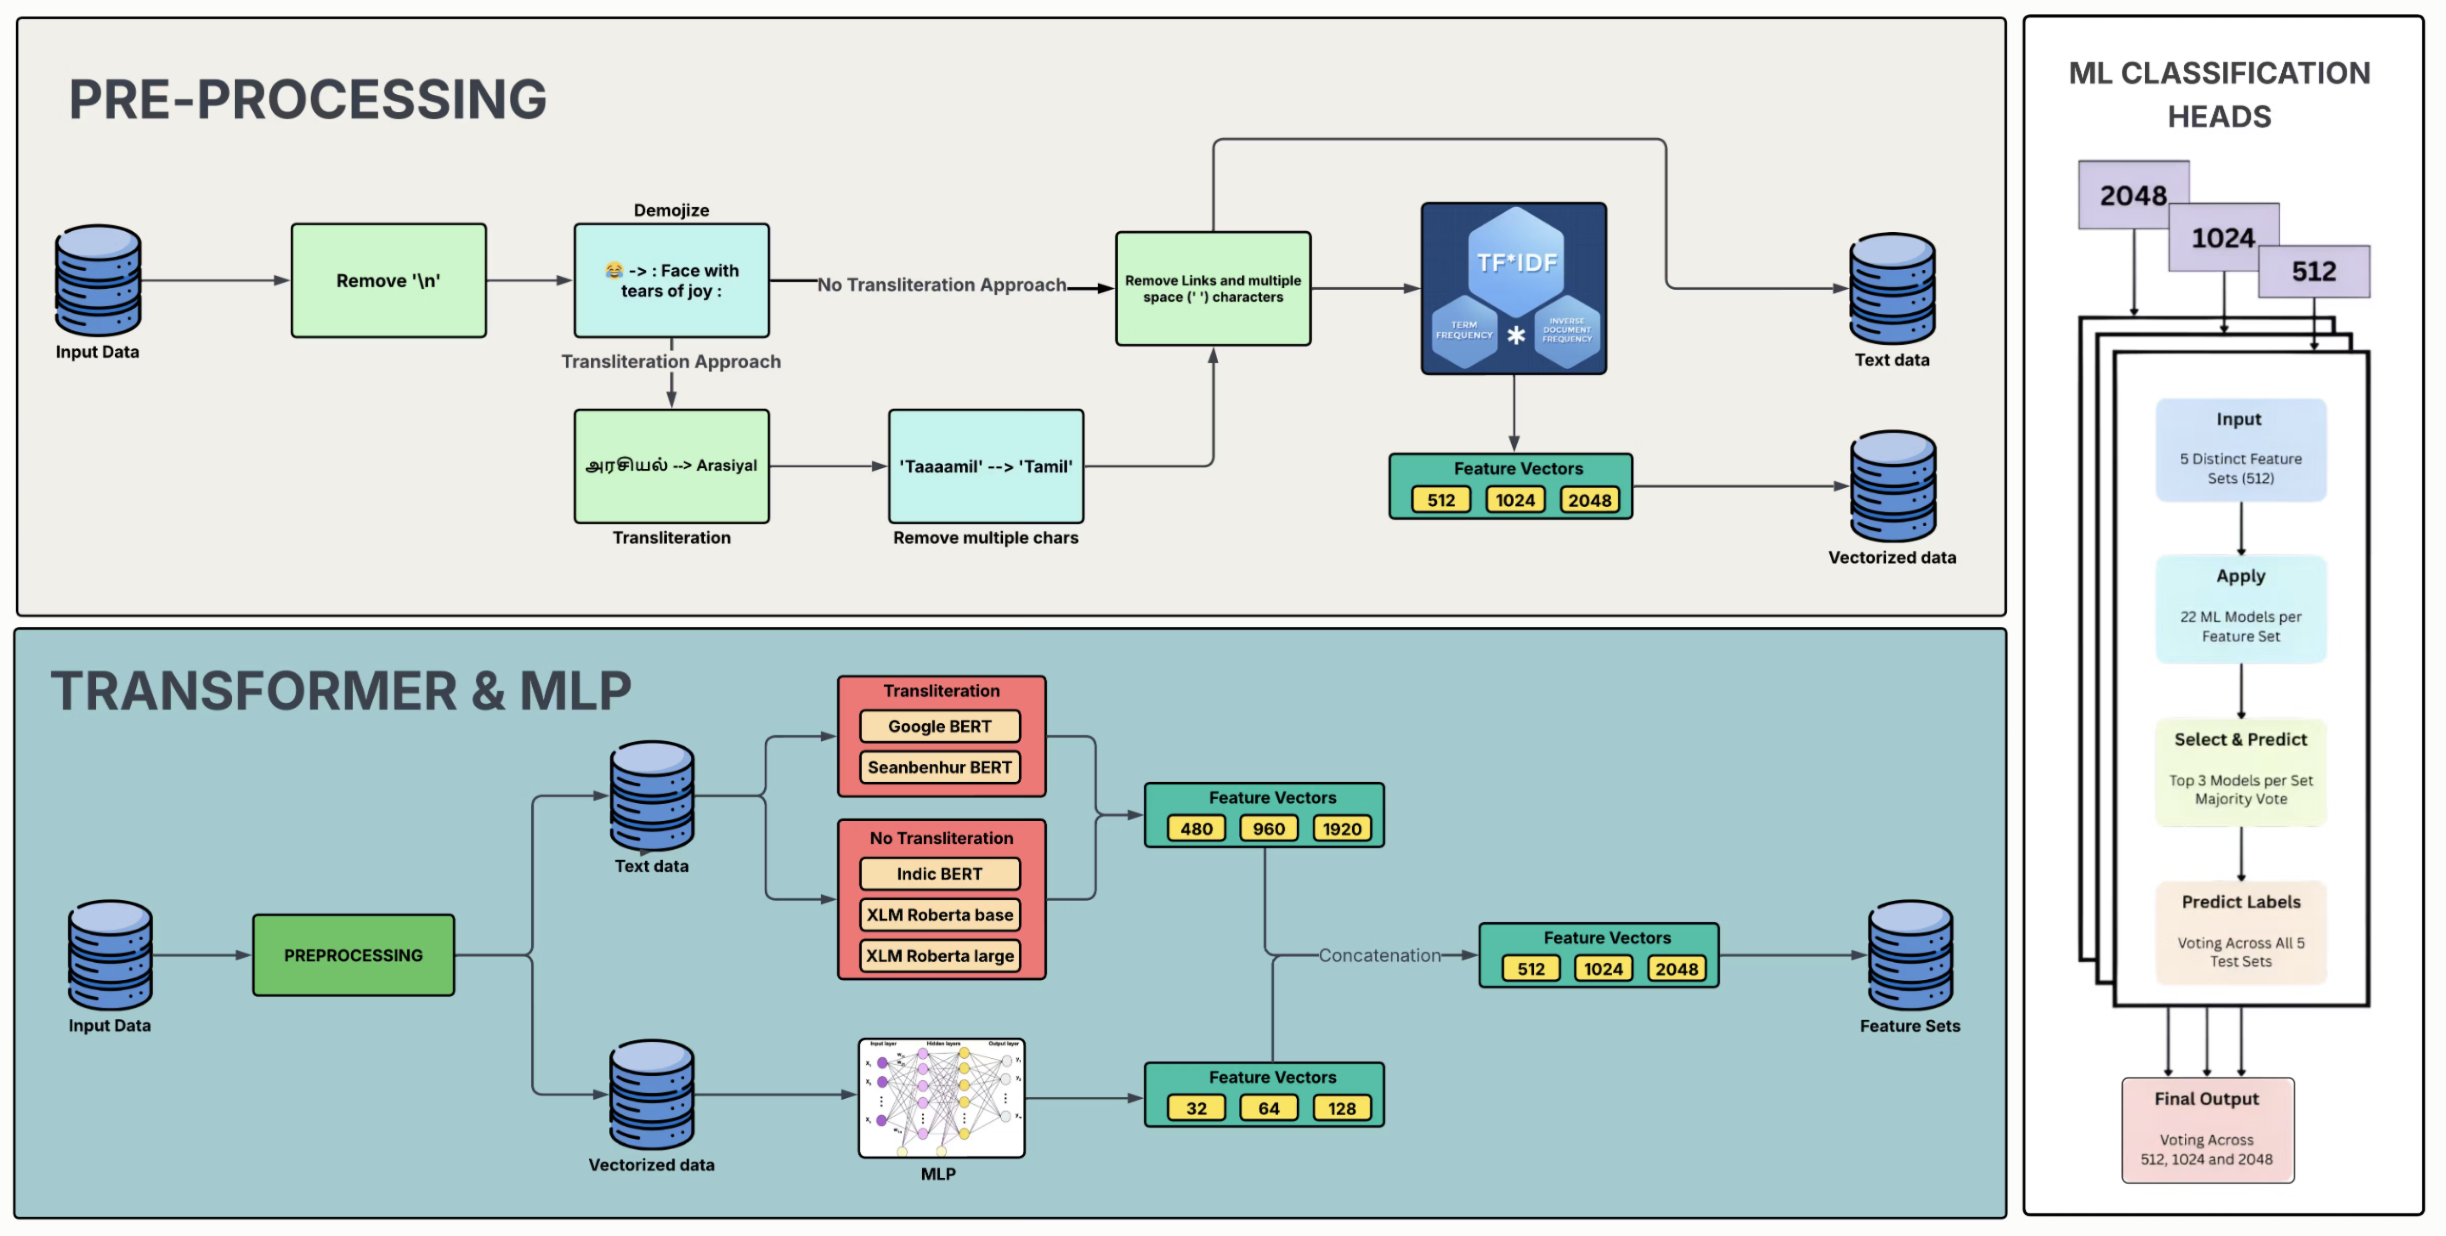
🏗️ Multi-scale Hybrid Architecture Overview
Our solution achieved outstanding performance in the LT-EDI 2025 shared task:
| 🏅 Rank | 👥 Team Name | 📊 F1-Score | 📈 Performance |
|---|---|---|---|
| 🥇 1st | CUET_N317 | 0.88105 | Leading |
| 🥈 2nd | CUET's_white_walkers | 0.86289 | Strong |
| 🥉 3rd | Wise (Ours) | 0.81827 | Excellent |
| 4th | CUET_blitz_aces | 0.81682 | Good |
| 5th | hinterwelt | 0.80916 | Good |
🎓 Amrita School of Artificial Intelligence
Coimbatore, Amrita Vishwa Vidyapeetham, India
| 👤 Team Member | 🎯 Role | 🔗 Profile |
|---|---|---|
| Ganesh Sundhar S | Lead Researcher | Deep Learning & NLP |
| Durai Singh K | ML Engineer | Feature Engineering & Ensemble |
| Gnanasabesan G | Data Scientist | Preprocessing & Analysis |
| Hari Krishnan N | AI Researcher | Model Architecture |
| Dhanush MC | Software Engineer | Pipeline & Optimization |
🗃️ LT-EDI 2025 Tamil-English Code-Mixed Hate Speech Dataset
| 📊 Split | 🔢 Count | 📝 Description |
|---|---|---|
| 🚂 Training | 5,512 | Comments for model training |
| 🔍 Development | 787 | Comments for validation |
| 🧪 Test | 1,576 | Comments for final evaluation |
| 📦 Total | 7,875 | Complete dataset |
| 🏷️ Label | 📝 Description | 🎯 Target |
|---|---|---|
0 | Non-hate speech | Safe content |
1 | Hate speech | Caste/migration-based hate |
🔸 Non-hate: "Good morning anna, how are you doing today?"
🔹 Hate: "[Contains offensive content targeting specific communities]"
Note: The dataset contains Tamil-English code-mixed social media comments with varying degrees of code-switching and transliteration.
Our approach implements a sophisticated multi-stage pipeline that combines classical and modern NLP techniques.
Input Text → Replace newlines → Convert emojis → Remove URLs →
Normalize spaces → Convert to lowercase → Output
Input Text → Basic cleaning → Tamil Unicode to English →
Remove repeated chars → Remove non-ASCII → Output
📋 Preprocessing Steps:
graph LR
    A[Raw Text] --> B[TF-IDF Vectorizer]
    B --> C[~22,000 dimensions]
    C --> D[Truncated SVD]
    D --> E[512/1024/2048 dims]
    E --> F[MLP Compression]
    F --> G[32/64/128 dims]
| 🤖 Model | 📚 Type | 🔤 Input | 📐 Dimensions |
|---|---|---|---|
| Google BERT | bert-large-uncased | Transliterated | 768 → 960 |
| XLM-RoBERTa Base | xlm-roberta-base | Original | 768 → 960 |
| XLM-RoBERTa Large | xlm-roberta-large | Original | 1024 → 960 |
| IndicBERT | IndicBERTv2-MLM | Original | 768 → 960 |
| Seanbenhur BERT | tanglish-offensive | Transliterated | 768 → 960 |
graph TD
    A[TF-IDF Features] --> D[Feature Fusion]
    B[BERT Embeddings] --> D
    C[RoBERTa Embeddings] --> D
    D --> E[ML Classifiers]
    E --> F[Level 1: Top-3 Voting]
    F --> G[Level 2: Cross-Model Voting]
    G --> H[Level 3: Multi-Scale Voting]
    H --> I[Final Prediction]
🌳 Tree-Based Models:
📏 Linear Models:
🔮 Other Models:
🔧 Comprehensive System Architecture
| 🤖 Transformer | 🏆 Best Model | 📈 F1-Score | 🎯 Performance |
|---|---|---|---|
| Google BERT | Random Forest | 0.803 | 🟢 Good |
| IndicBERT | Random Forest | 0.817 | 🟡 Very Good |
| SeanBenhur BERT | XGBoost | 0.814 | 🟡 Very Good |
| XLM-R Base | Random Forest | 0.807 | 🟢 Good |
| XLM-R Large | Extra Trees | 0.806 | 🟢 Good |
| 🤖 Transformer | 🏆 Best Model | 📈 F1-Score | 🎯 Performance |
|---|---|---|---|
| Google BERT | SVM | 0.818 | 🟡 Very Good |
| IndicBERT | Random Forest | 0.829 | 🟠 Excellent |
| SeanBenhur BERT | Random Forest | 0.822 | 🟡 Very Good |
| XLM-R Base | Nu-SVM | 0.825 | 🟡 Very Good |
| XLM-R Large | Random Forest | 0.830 | 🟠 Excellent |
| 🤖 Transformer | 🏆 Best Model | 📈 F1-Score | 🎯 Performance |
|---|---|---|---|
| Google BERT | Gradient Boosting | 0.839 | 🔥 Outstanding |
| IndicBERT | Ridge Regression | 0.824 | 🟡 Very Good |
| SeanBenhur BERT | Nu-SVM | 0.826 | 🟡 Very Good |
| XLM-R Base | Random Forest | 0.835 | 🟠 Excellent |
| XLM-R Large | Random Forest | 0.833 | 🟠 Excellent |
🎊 LT-EDI 2025 Leaderboard
| 🏅 Rank | 👥 Team Name | 📊 F1-Score | 📈 Gap | 🎯 Status |
|---|---|---|---|---|
| 🥇 1st | CUET_N317 | 0.88105 | - | 🔥 Winner |
| 🥈 2nd | CUET's_white_walkers | 0.86289 | -0.018 | 🚀 Runner-up |
| 🥉 3rd | Wise (Ours) | 0.81827 | -0.044 | ✨ Bronze |
| 4th | CUET_blitz_aces | 0.81682 | -0.001 | 📈 Close |
| 5th | hinterwelt | 0.80916 | -0.009 | 💪 Strong |
🎯 Achievement: Our team secured 3rd place out of numerous international participants, demonstrating the effectiveness of our multi-scale ensemble approach!
📈 Model Training Visualization Across Different Dimensions
| 🤖 Model | 📈 Training Graph |
|---|---|
| Google BERT | 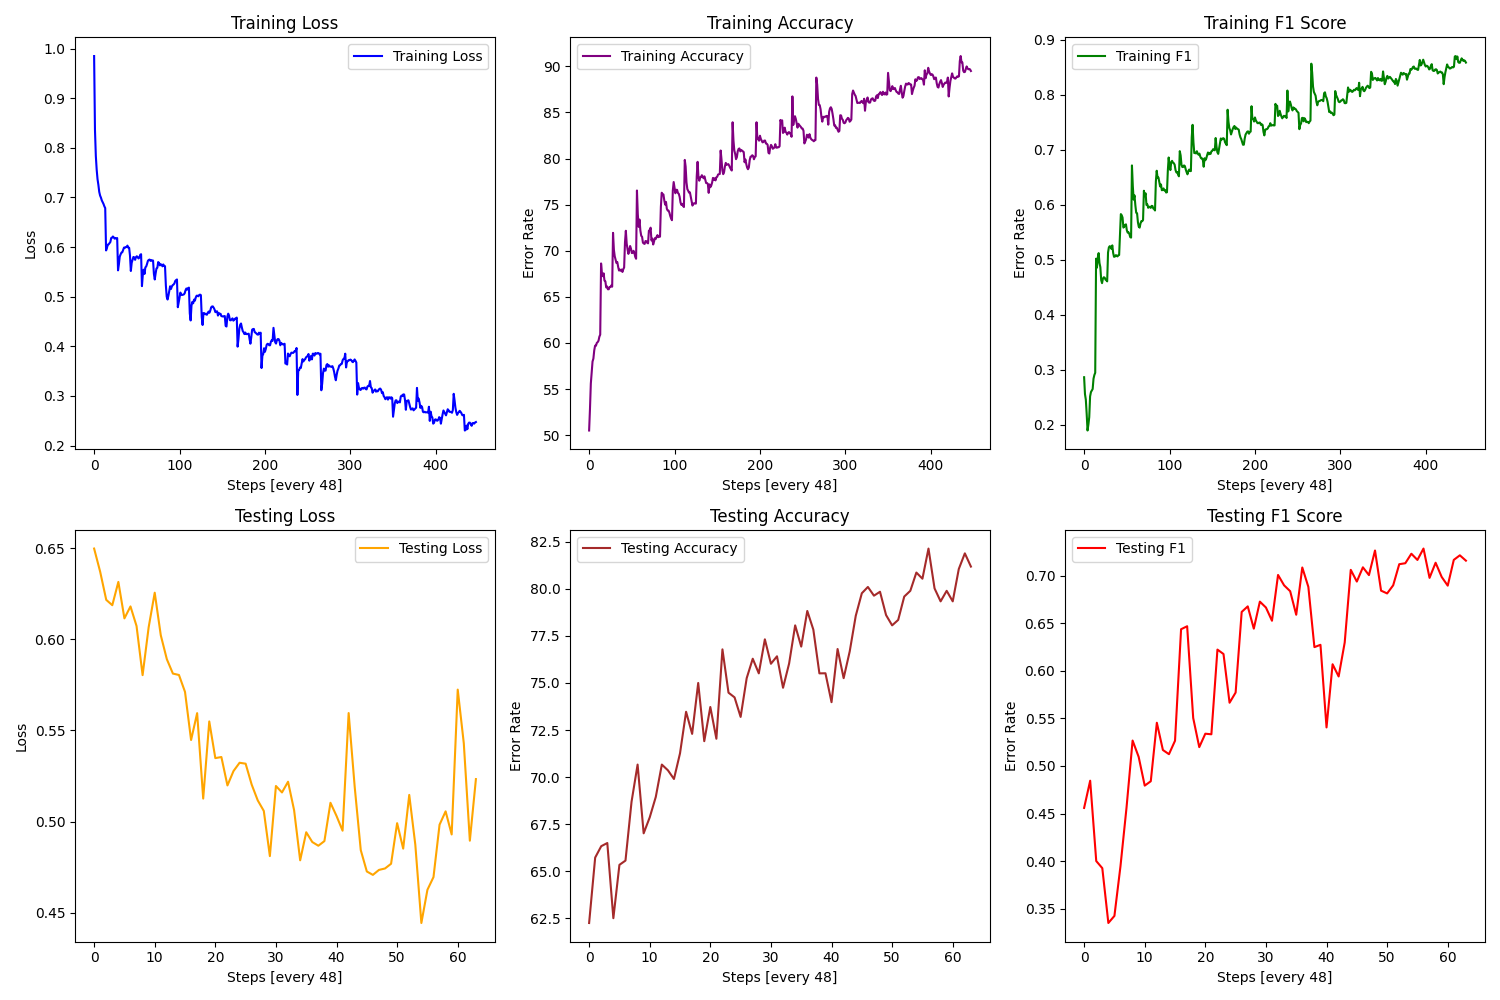 |
| IndicBERT | 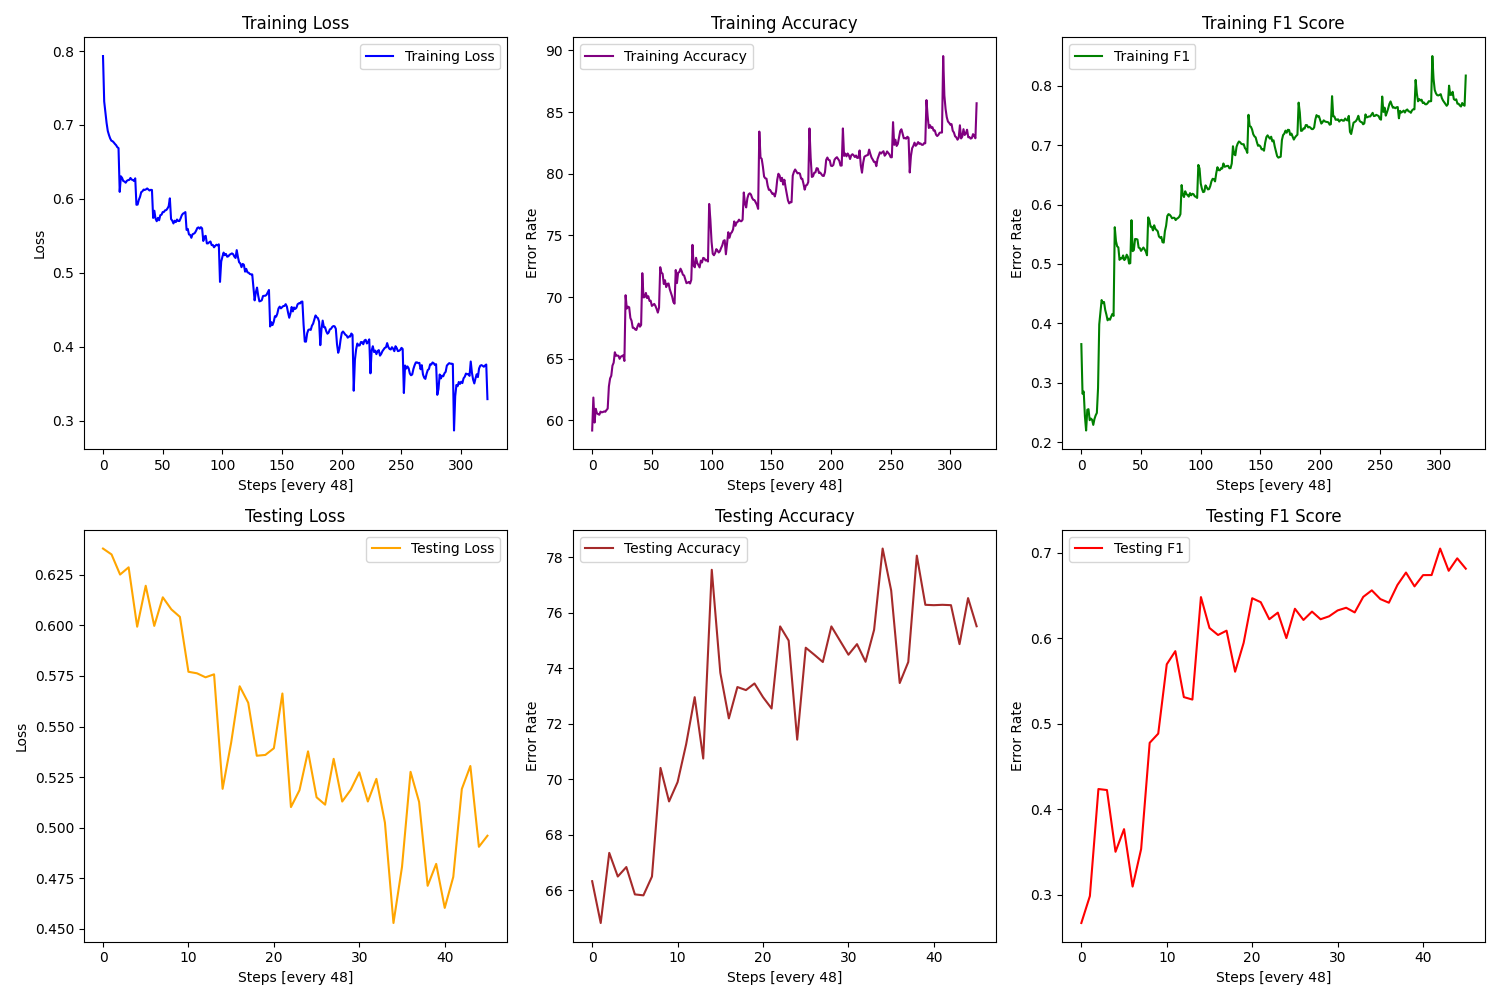 |
| Seanbenhur BERT | 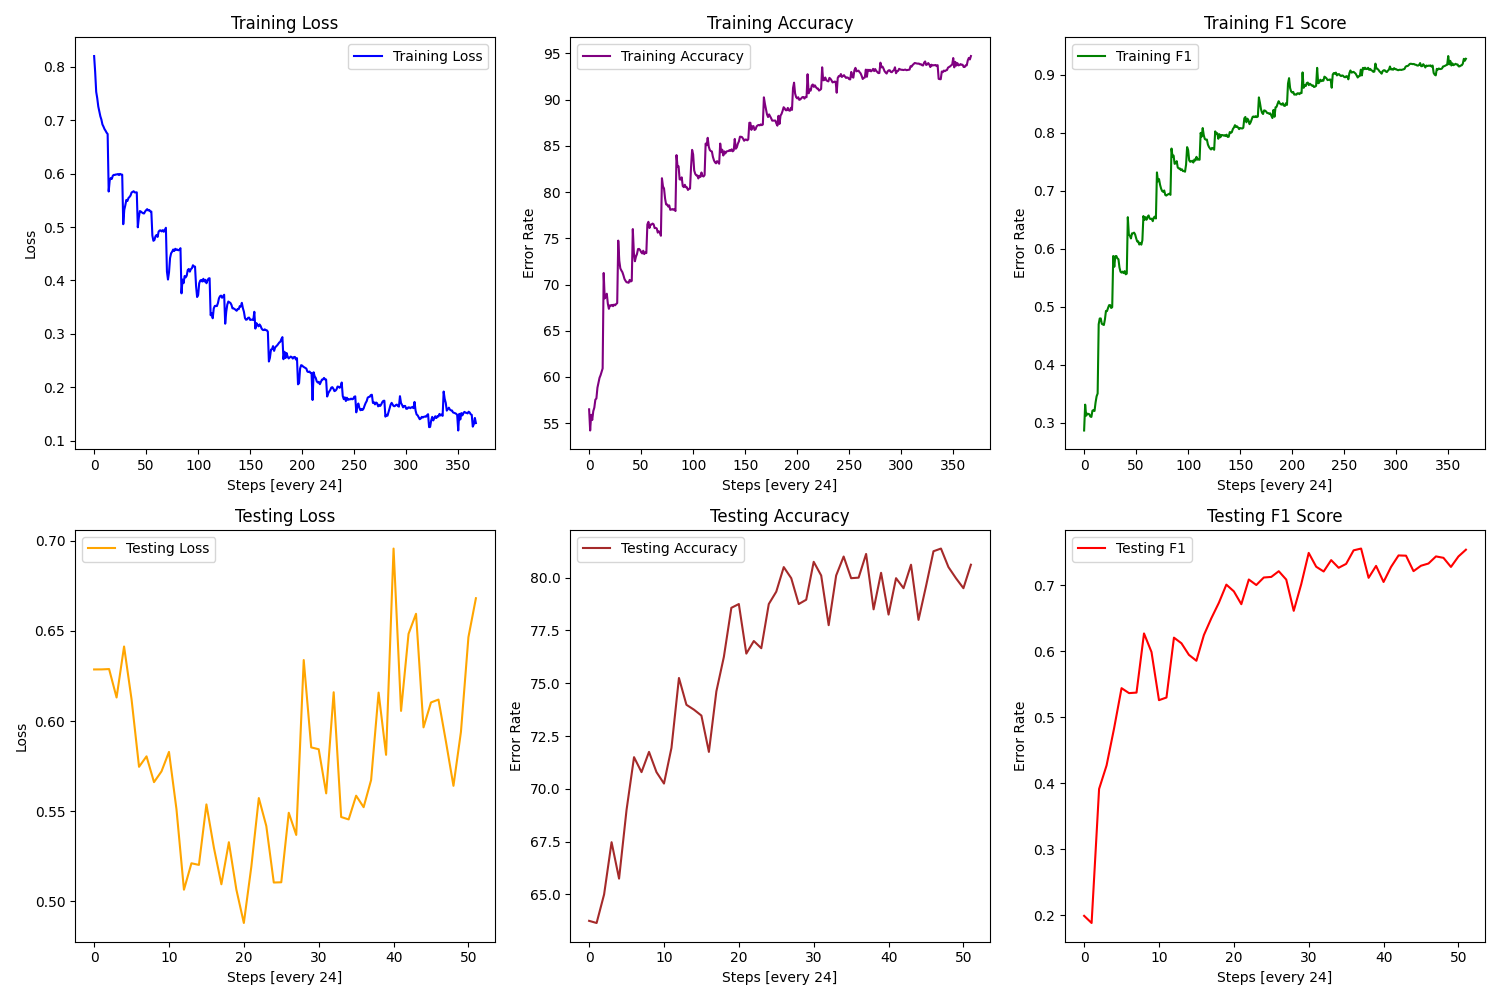 |
| XLM-RoBERTa Base | 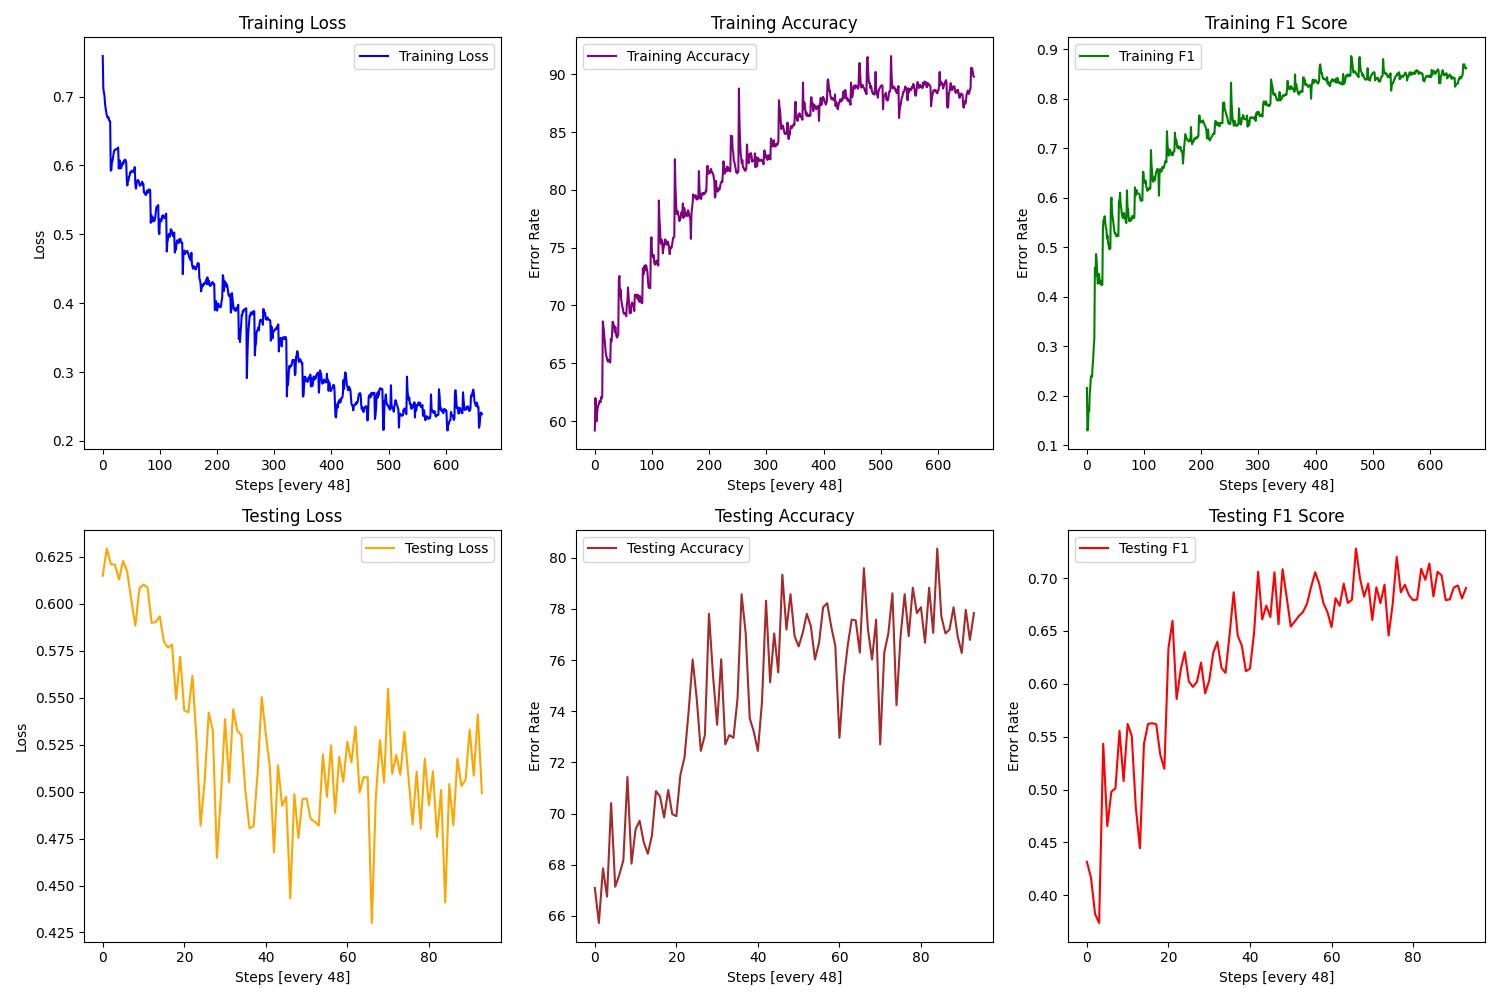 |
| XLM-RoBERTa Large | 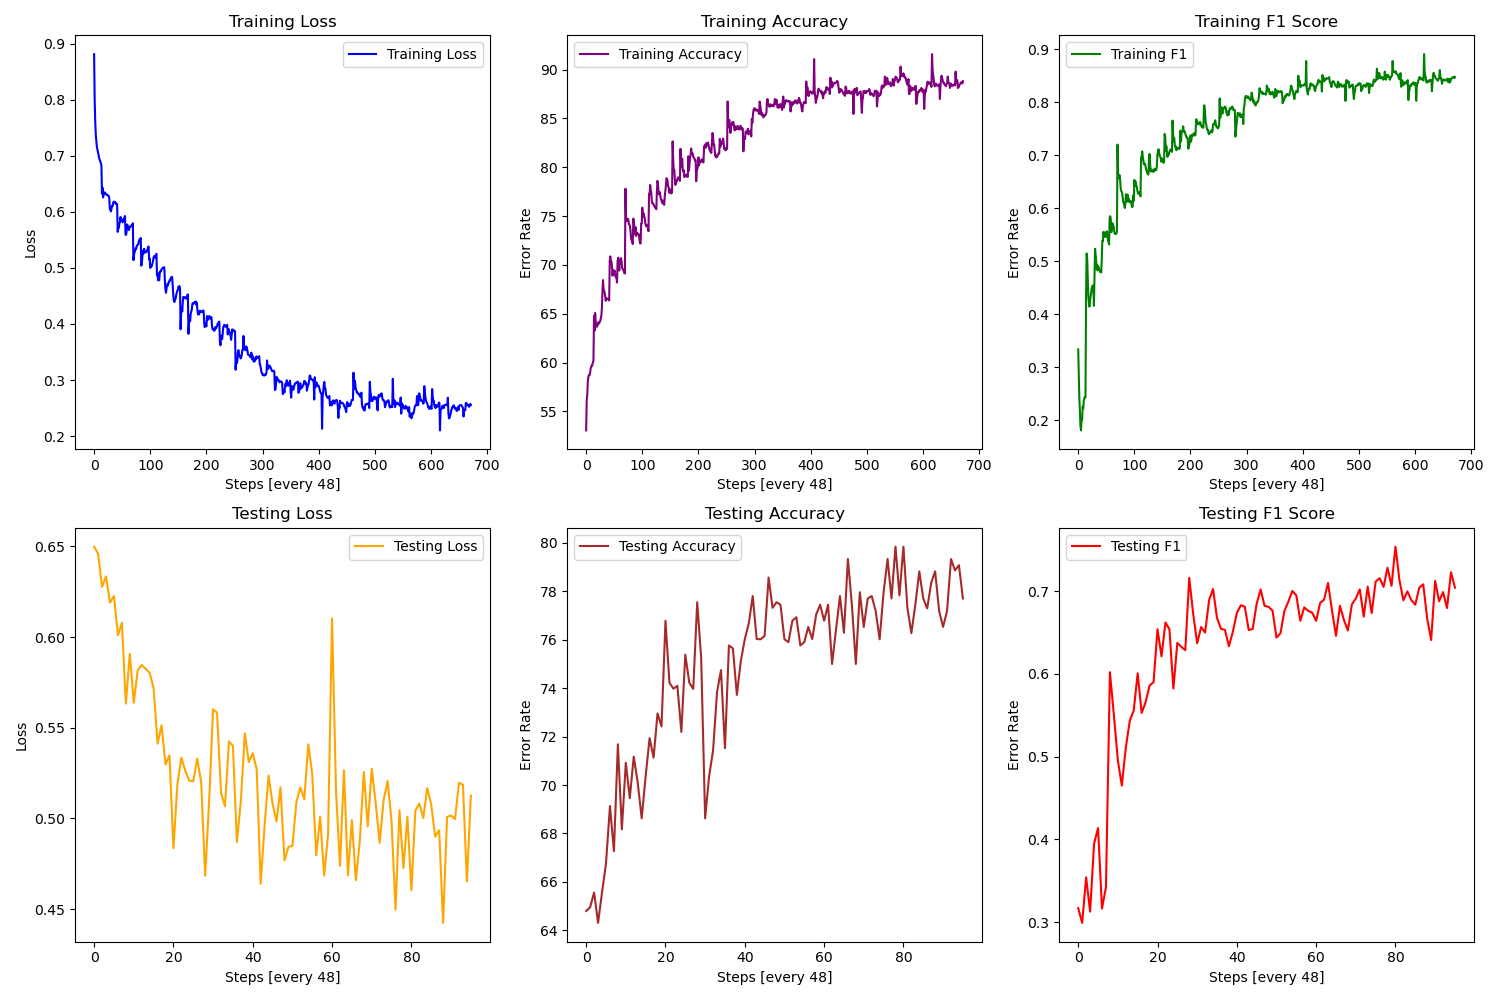 |
| 🤖 Model | 📈 Training Graph |
|---|---|
| Google BERT | 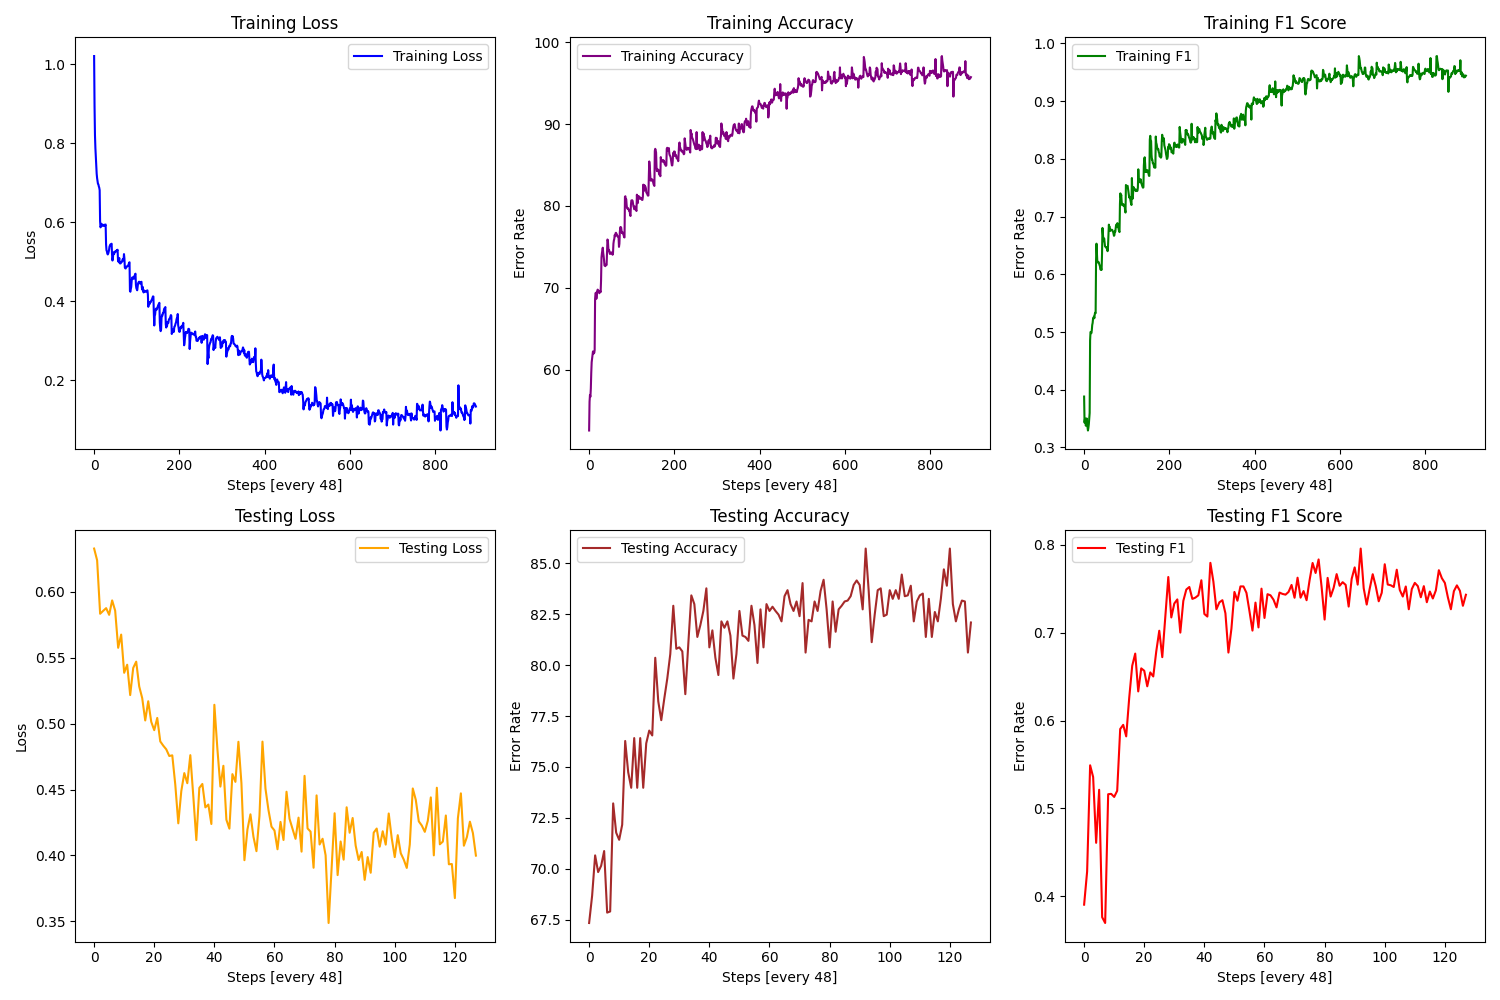 |
| IndicBERT | 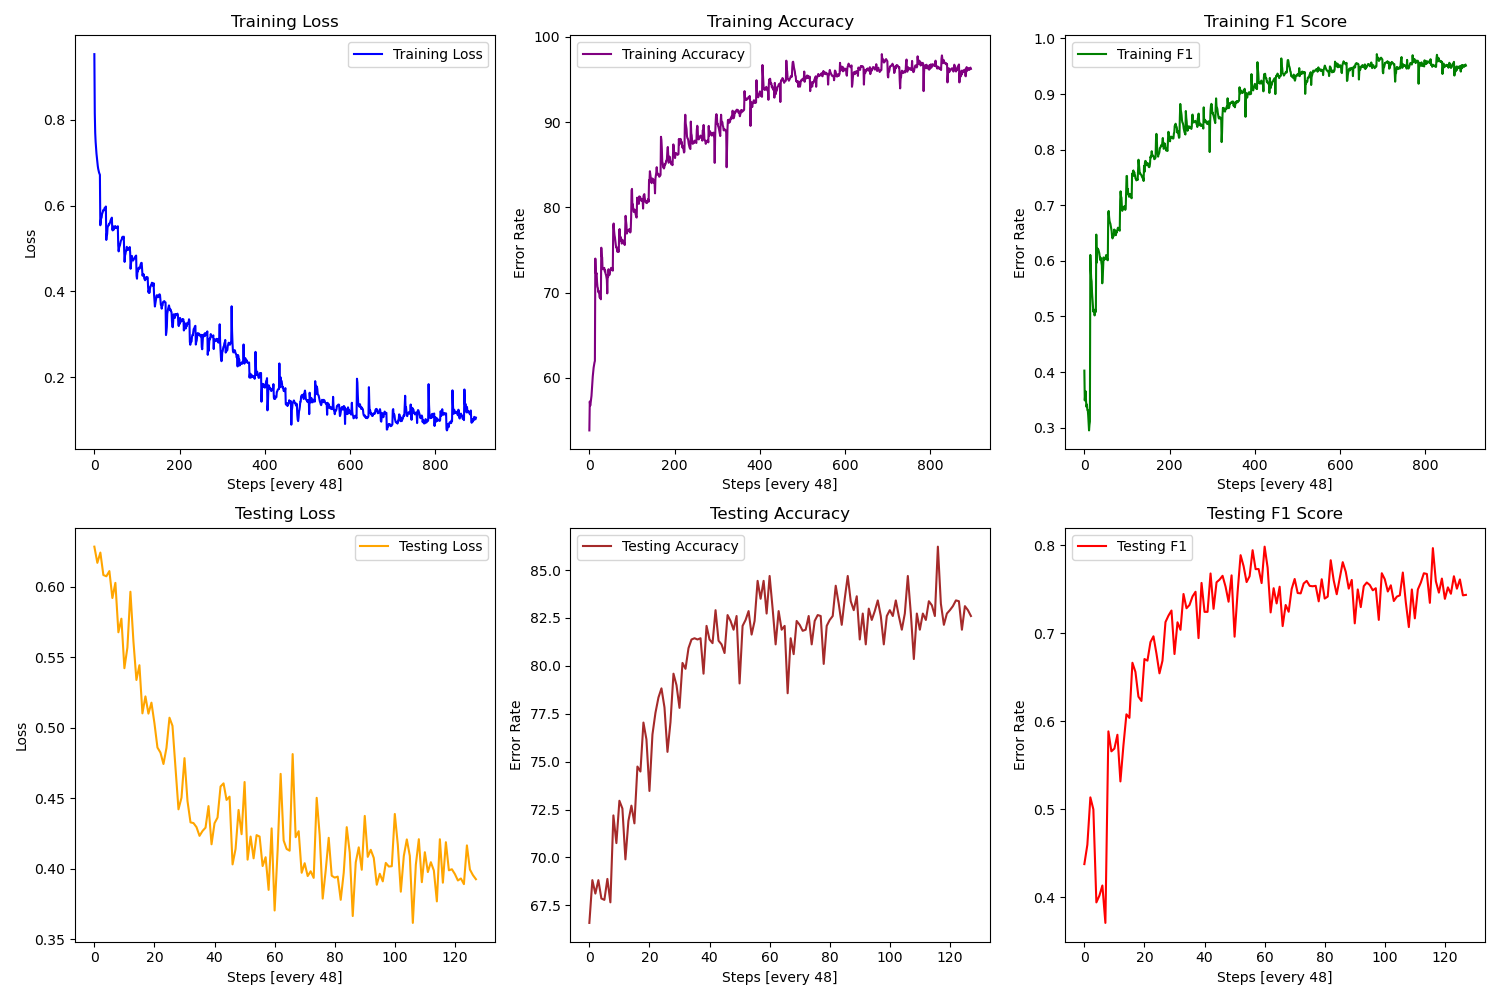 |
| Seanbenhur BERT | 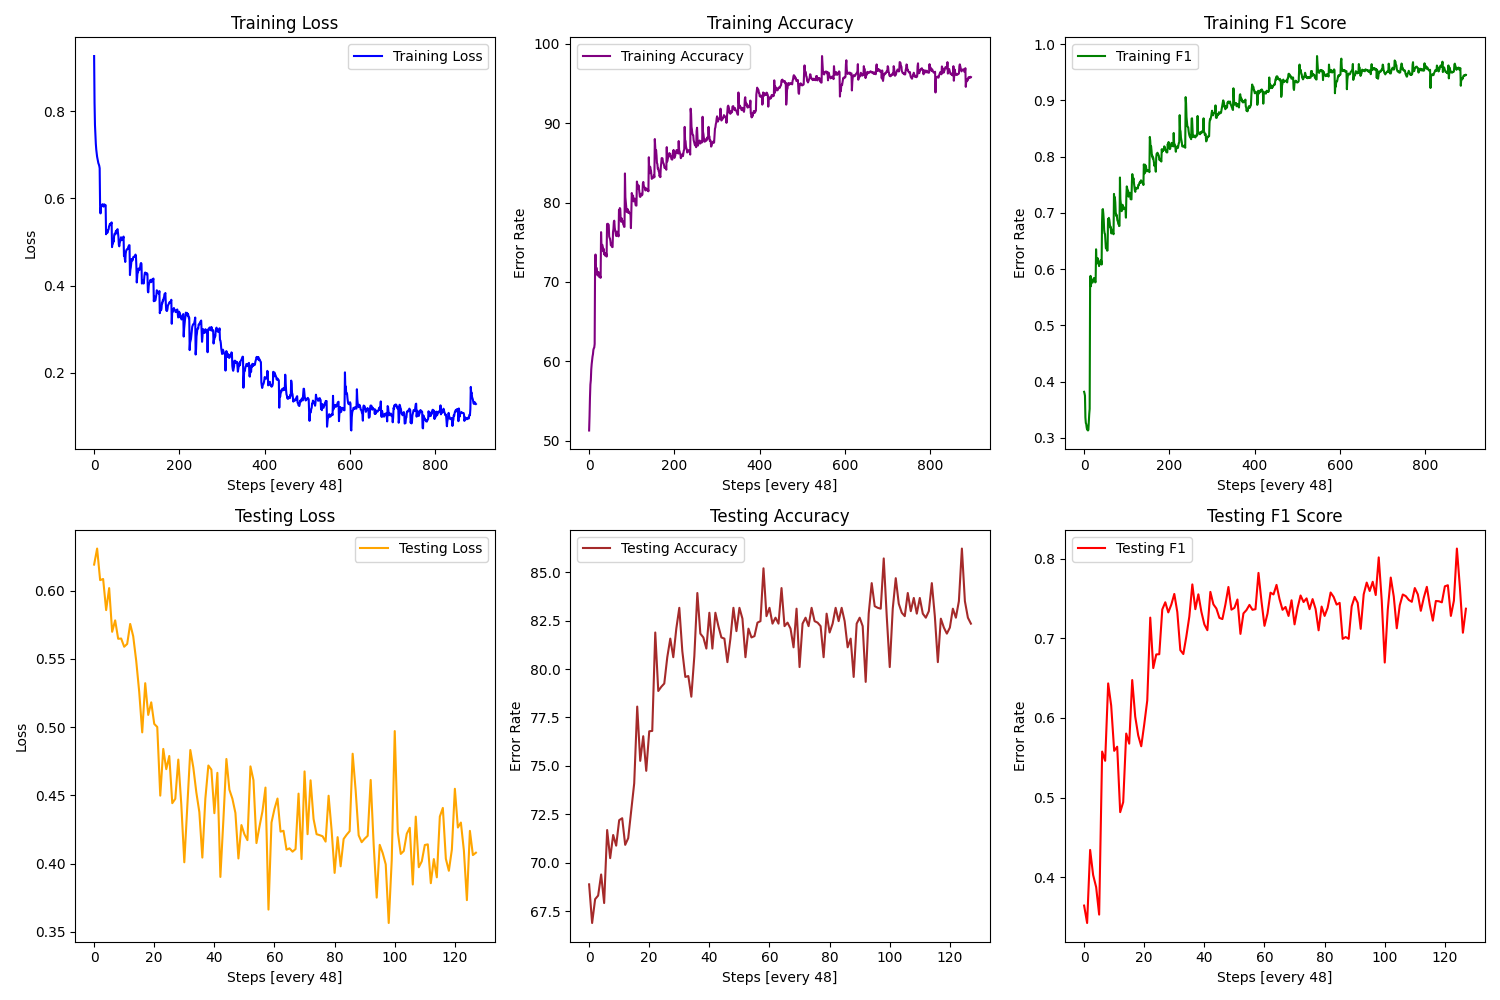 |
| XLM-RoBERTa Base | 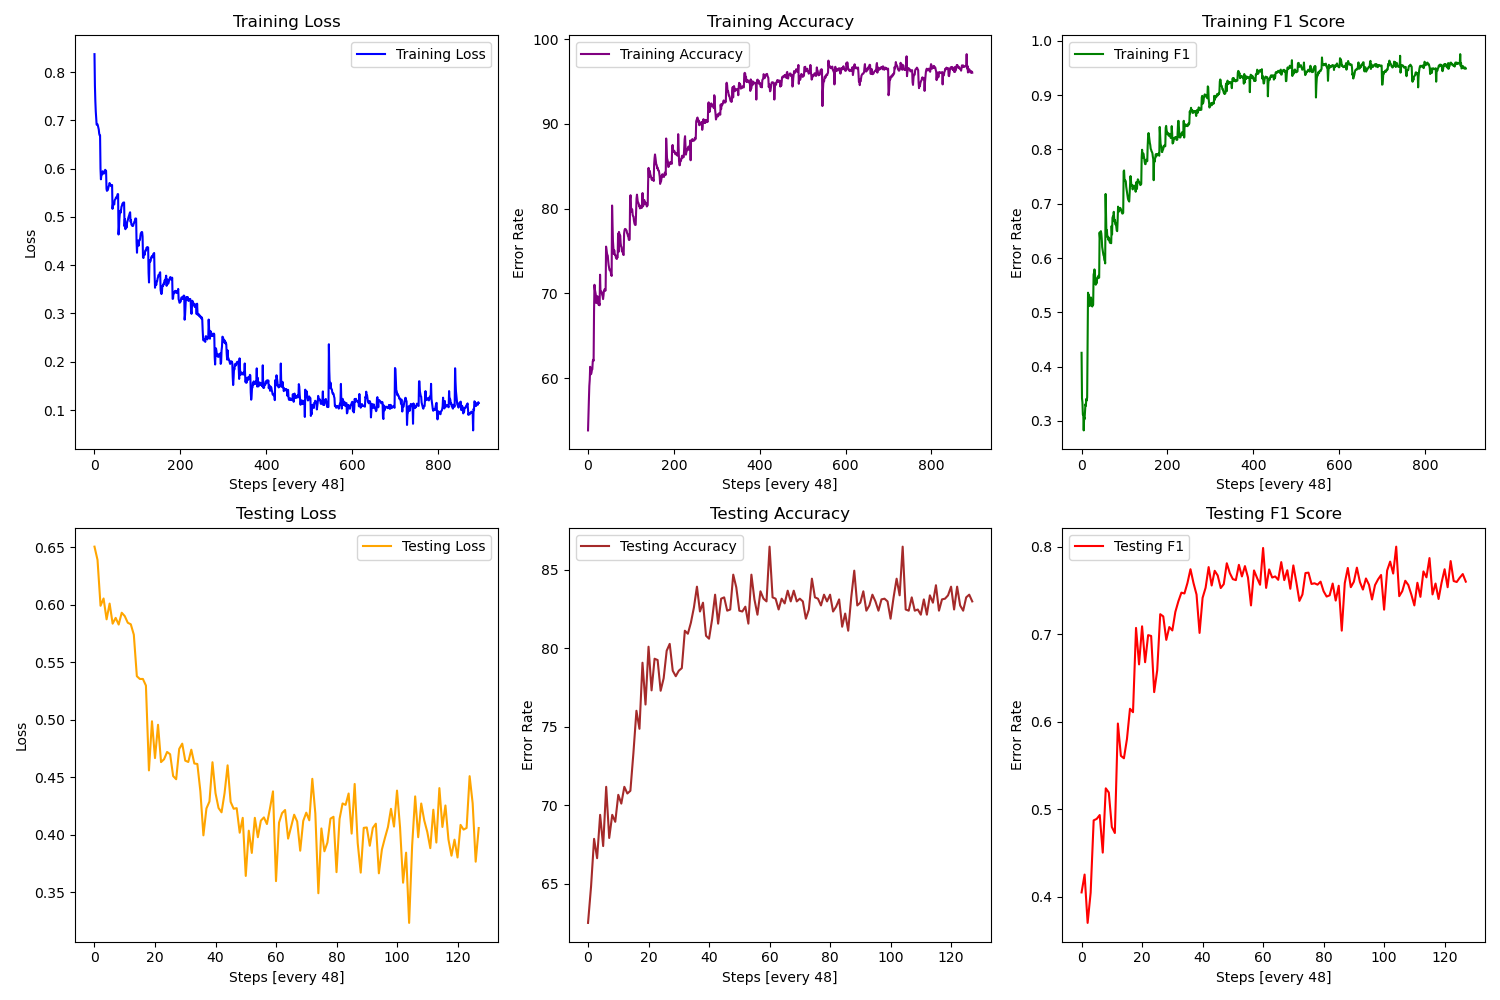 |
| XLM-RoBERTa Large | 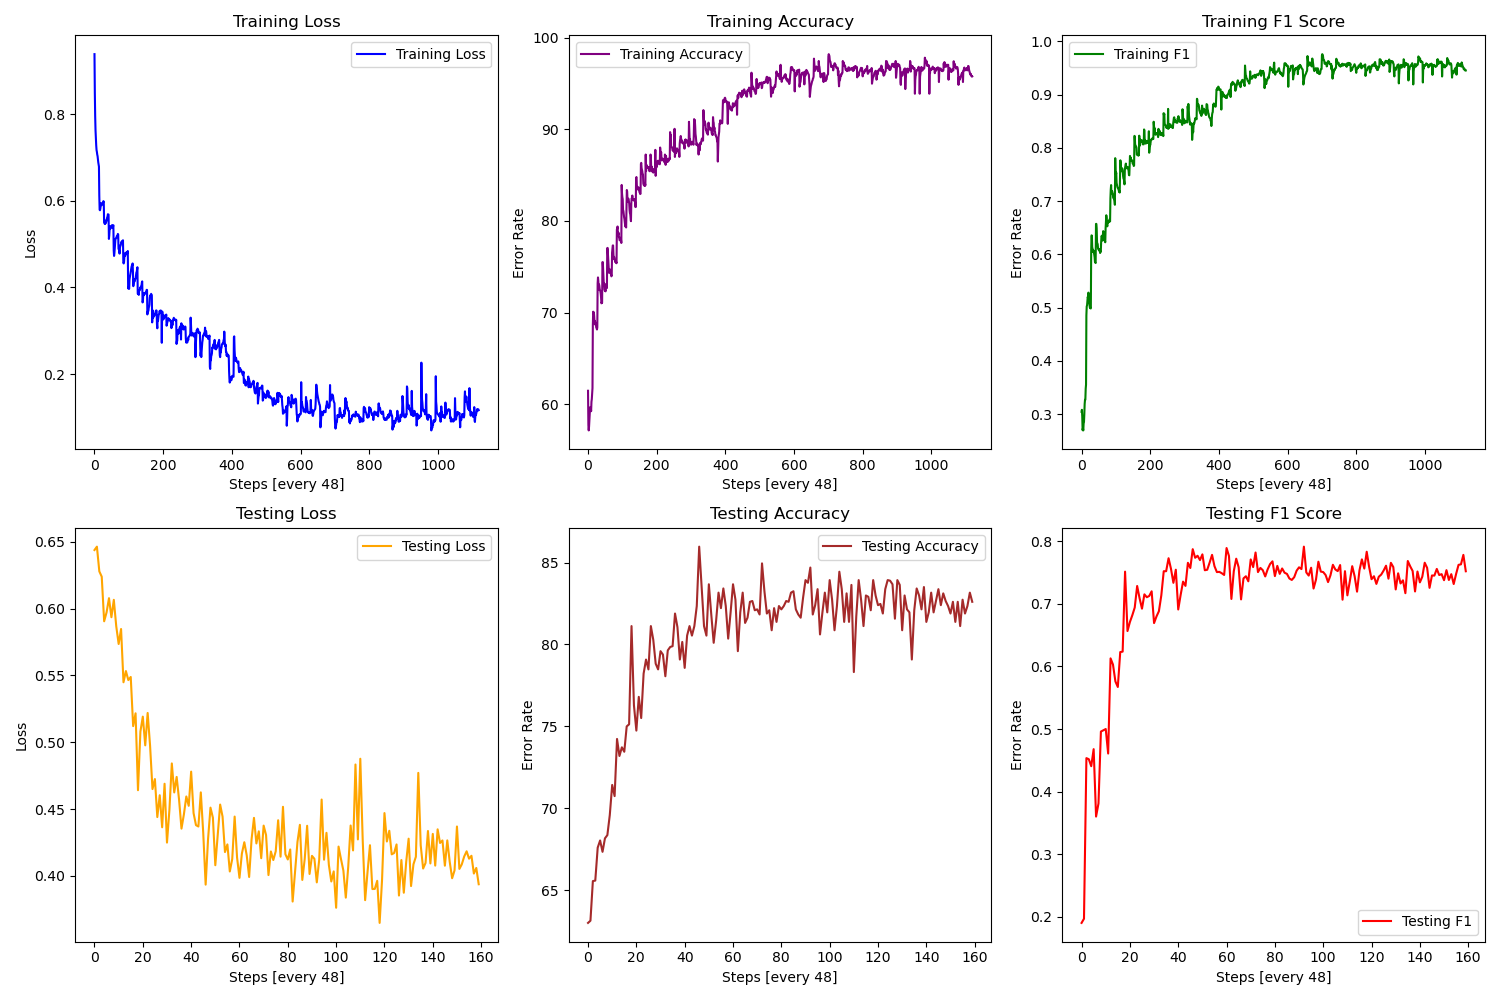 |
| 🤖 Model | 📈 Training Graph |
|---|---|
| Google BERT | 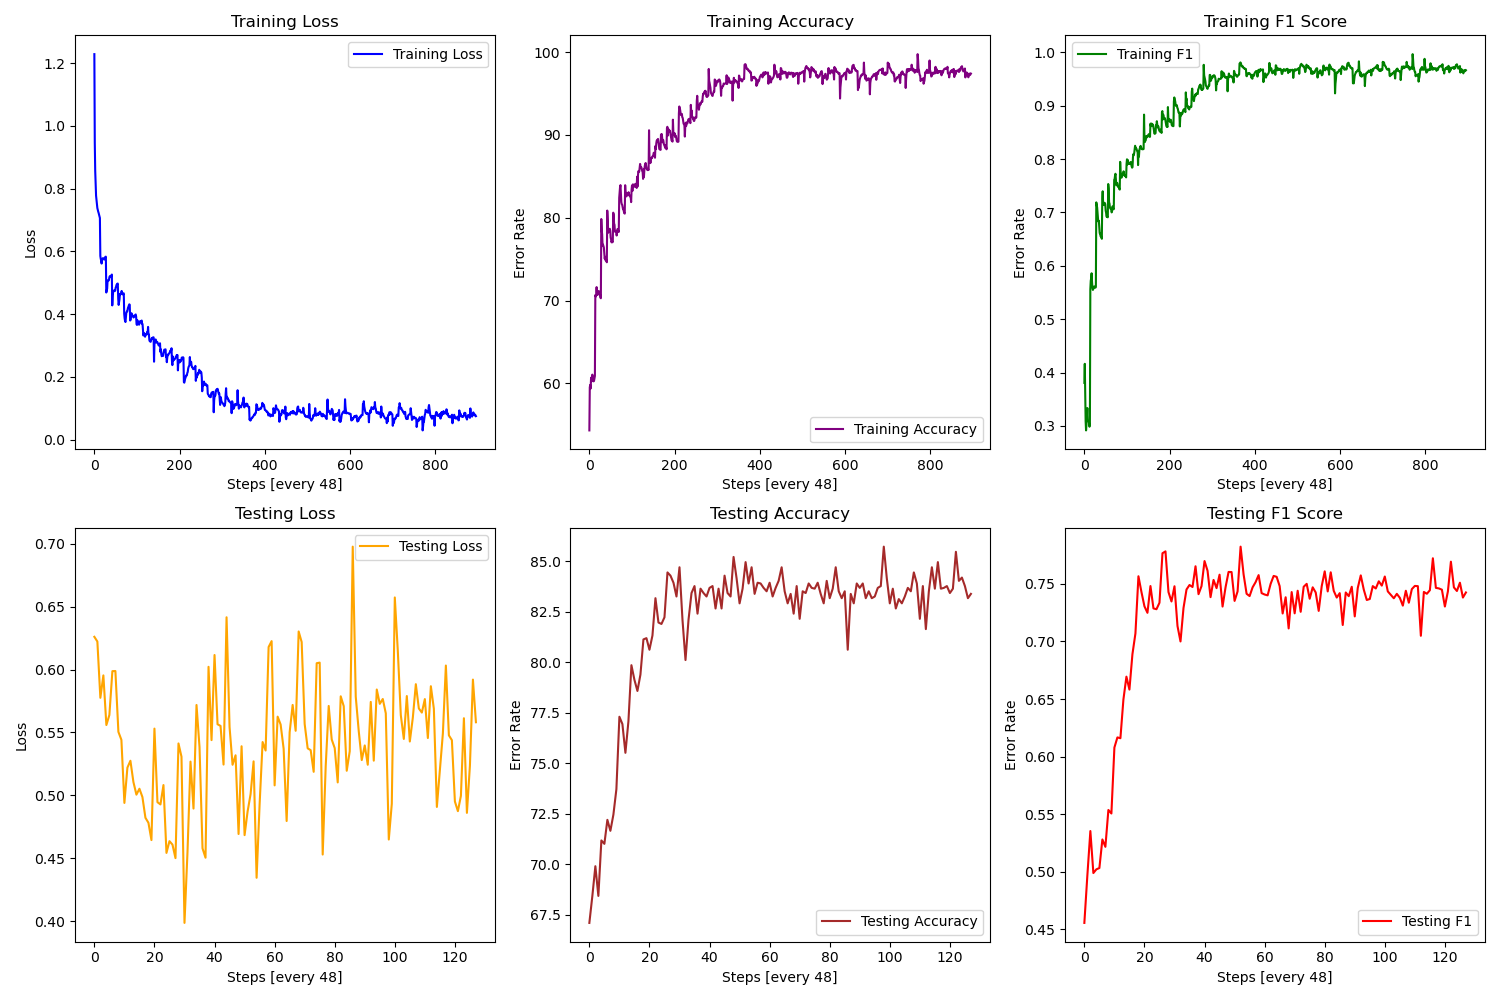 |
| IndicBERT | 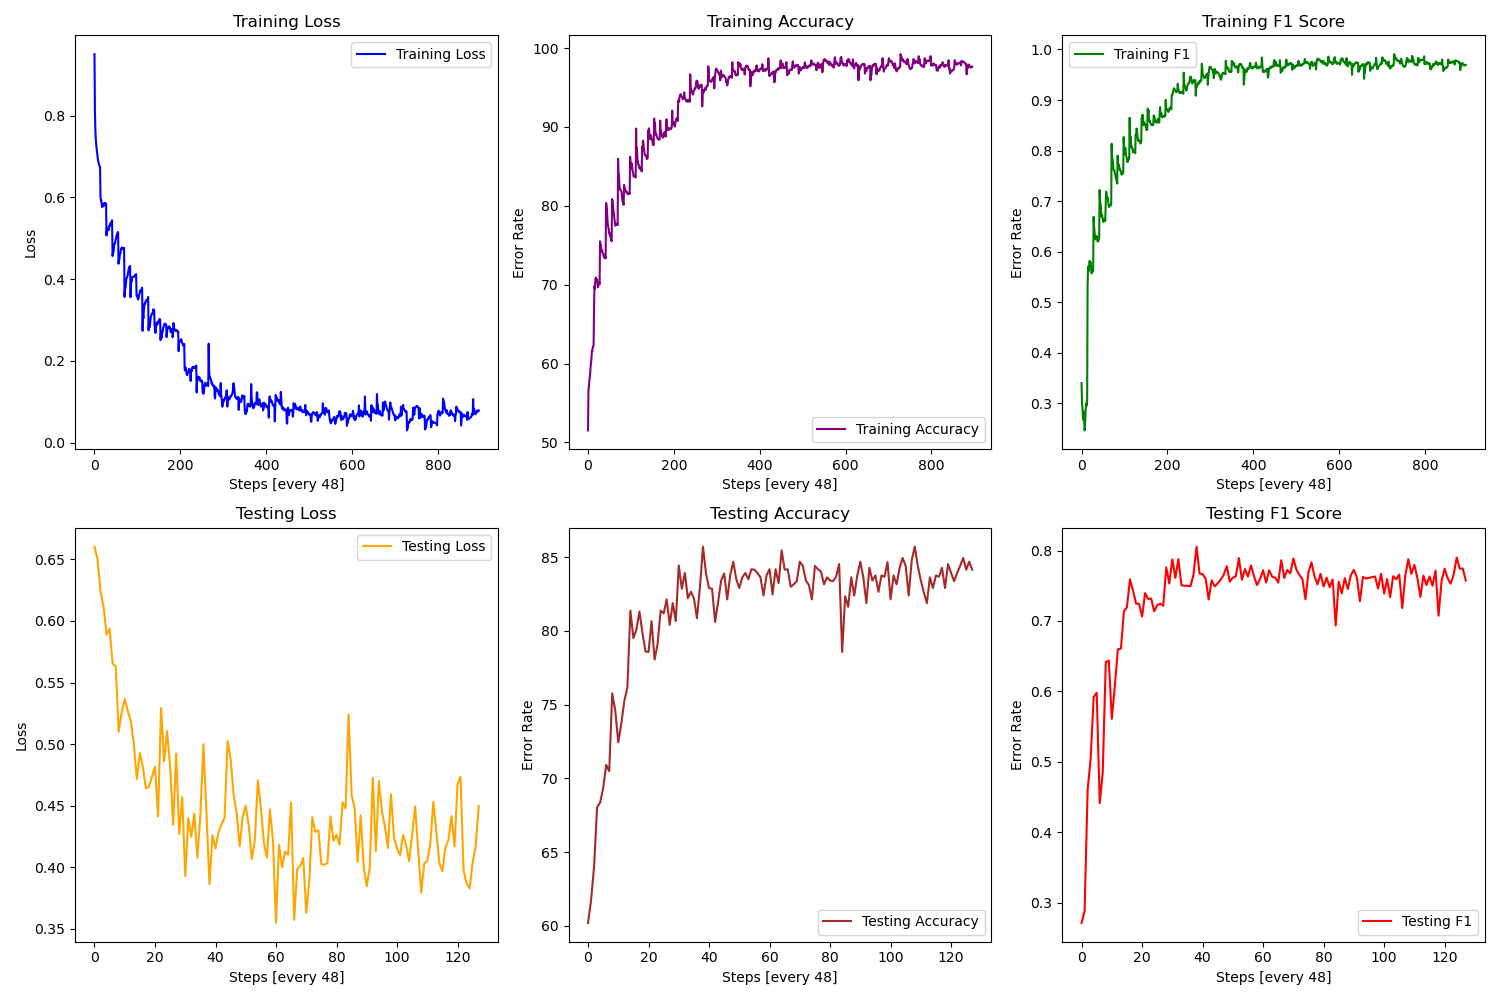 |
| Seanbenhur BERT | 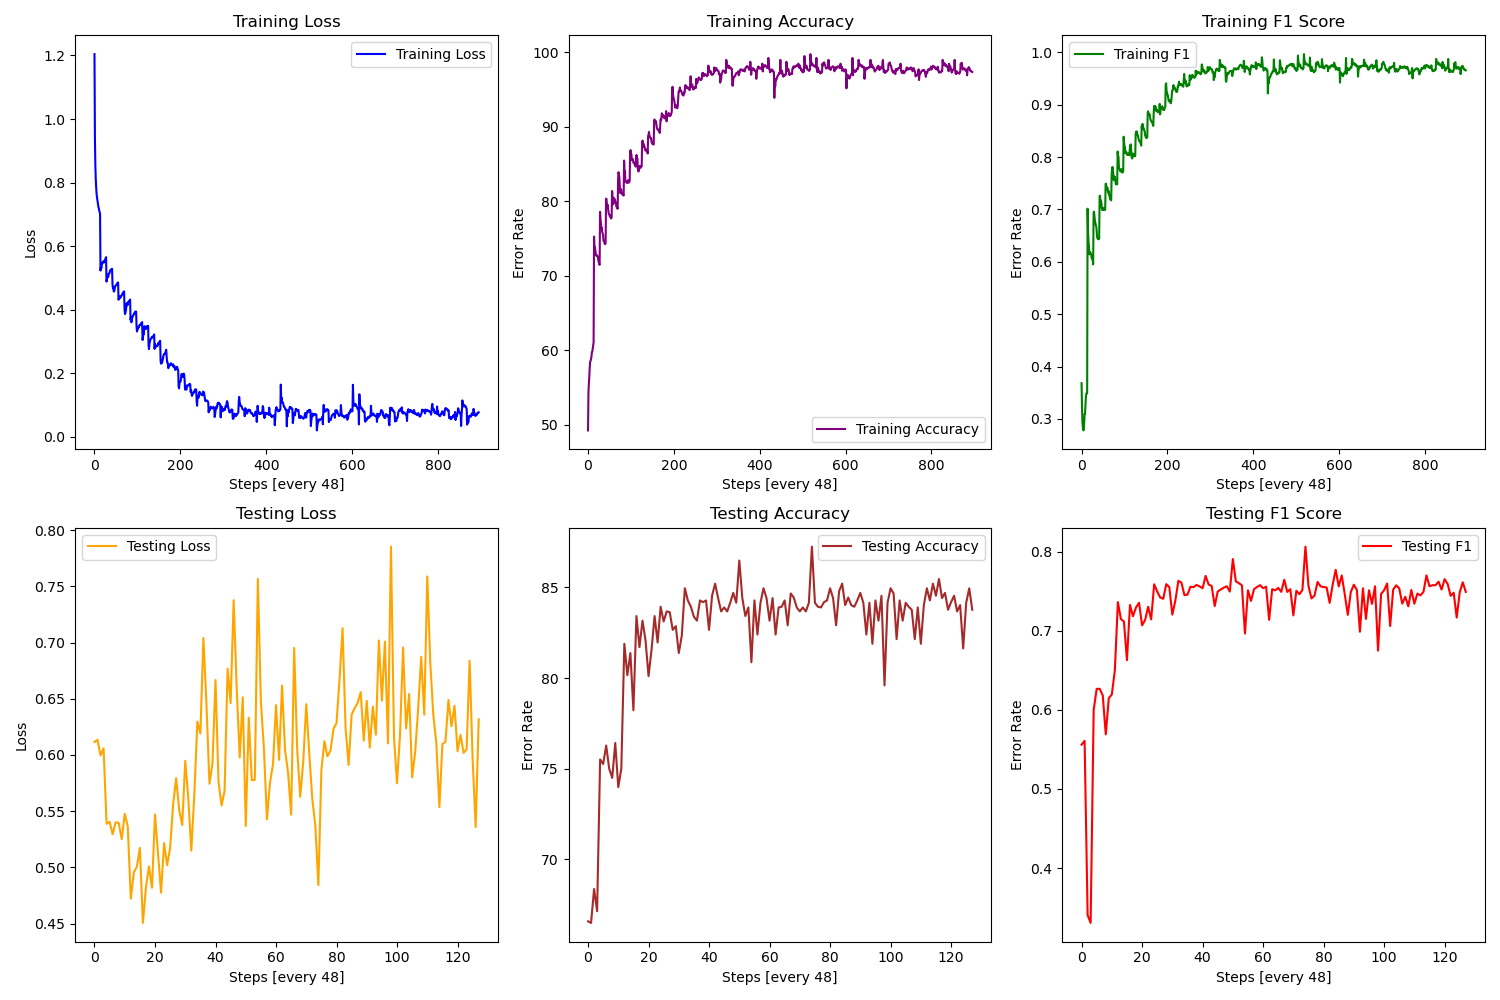 |
| XLM-RoBERTa Base | 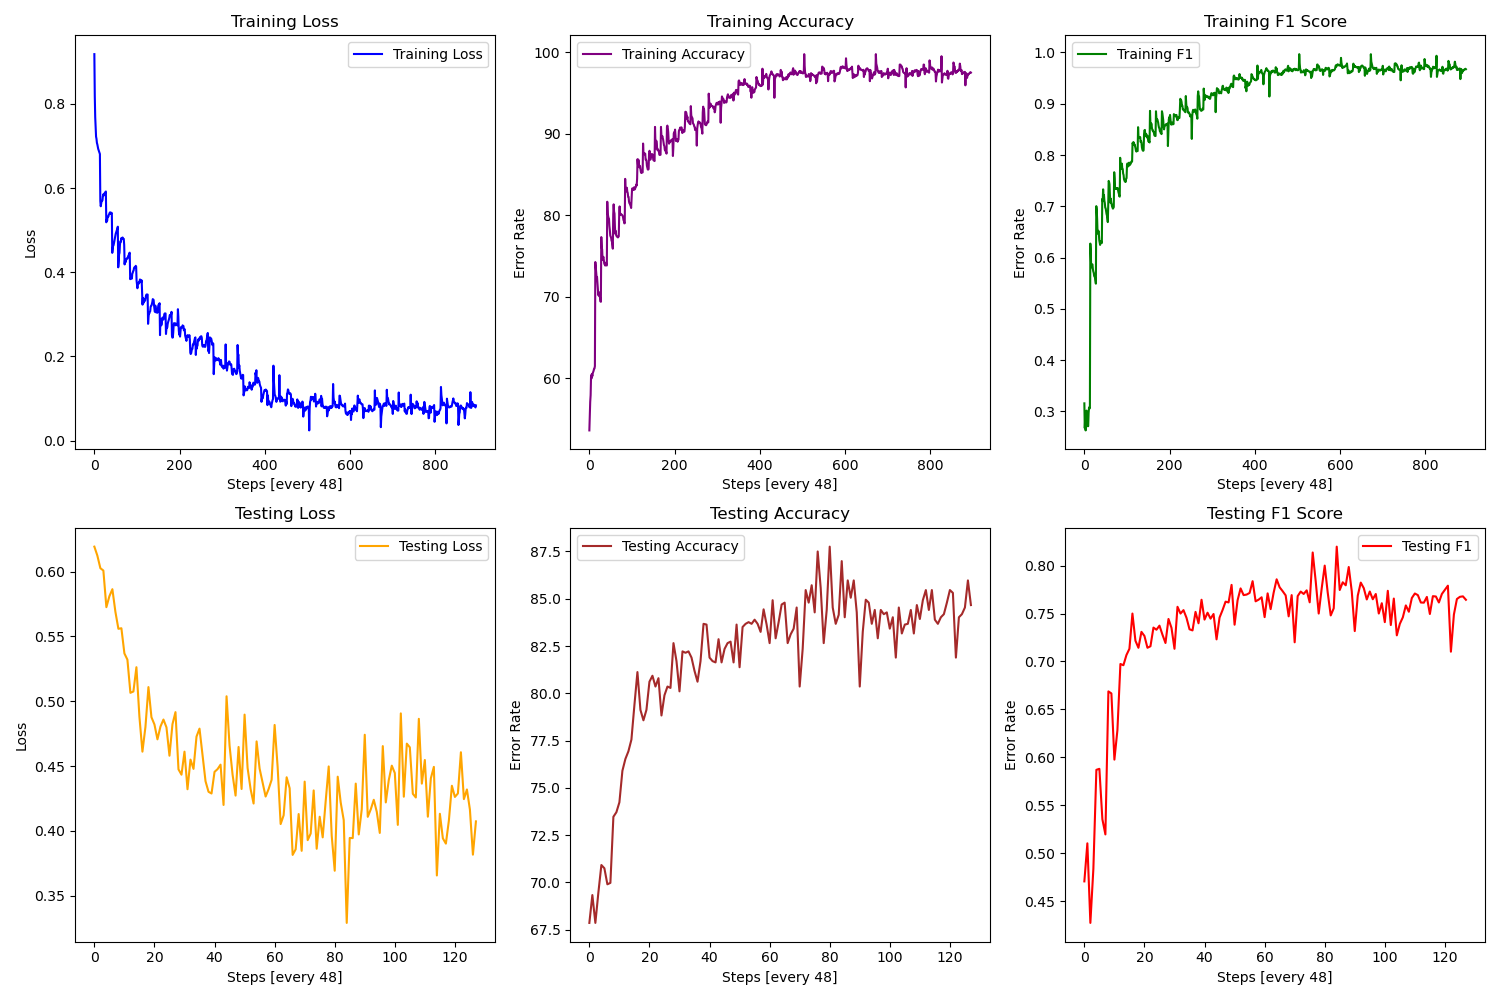 |
| XLM-RoBERTa Large | 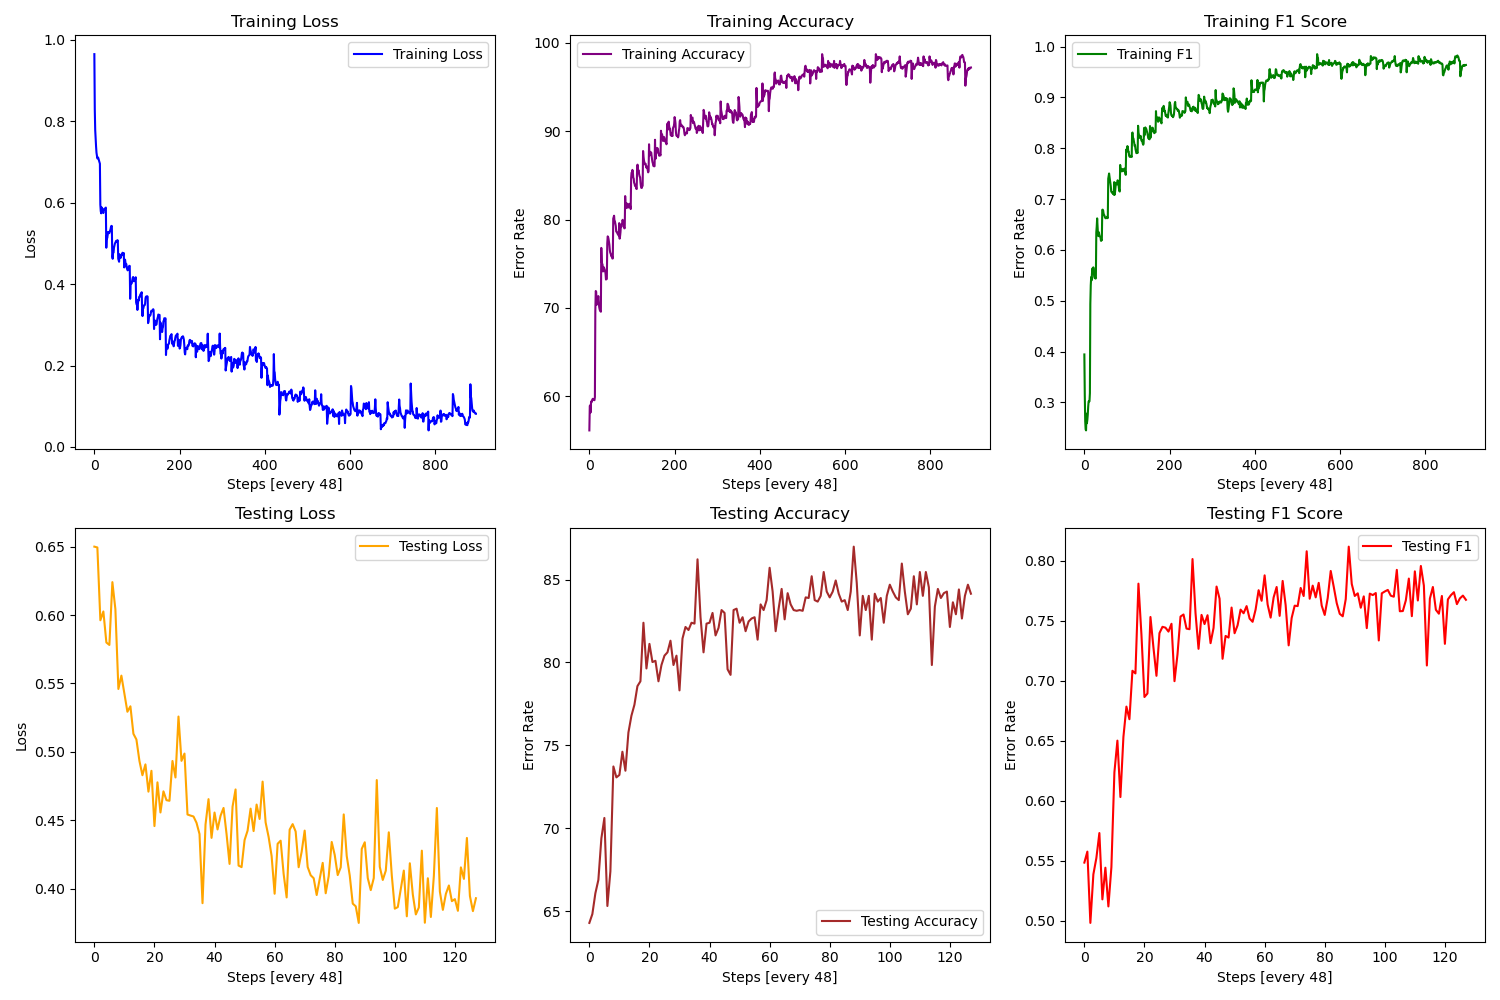 |
# Python 3.8+ required
python --version  # Should be >= 3.8
# Clone the repository
git clone https://github.com/your-username/CasteMigrationHateSpeech.git
cd CasteMigrationHateSpeech

# Install dependencies
pip install -r requirements.txt

# Install additional dependencies
pip install torch torchvision transformers
pip install xgboost lightgbm catboost
# Navigate to preprocessors
cd "DL Feature set 1024/Processors"

# Run preprocessing notebooks
jupyter notebook with_transliteration_processor.ipynb
jupyter notebook no_transliteration_processor.ipynb
# Generate TF-IDF features
jupyter notebook tf_idf_vectorizer.ipynb

# Apply vectorizer
jupyter notebook apply_vectorizer.ipynb
# Navigate to trainers
cd "../Trainers"

# Train transformer models
python training_bert.py  # Configure model in script
# Navigate to ML heads
cd "../../ML Classification Heads"

# Run ensemble classification
jupyter notebook code.ipynb
🏆 CasteMigrationHateSpeech-main/
│
├── 📊 DL Feature set 512/          # 512-dimensional experiments
│   ├── 🤖 Models/                  # Transformer model definitions
│   │   ├── google_bert.py
│   │   ├── indic_model.py
│   │   ├── tanglish_model.py
│   │   ├── xlm_roberta_base.py
│   │   └── xlm_roberta_large.py
│   │
│   ├── 📄 No trans data/           # Non-transliterated features
│   │   ├── test_features_no_trans.csv
│   │   ├── test_processed_no_trans.csv
│   │   └── tfidf_vectorizer_2.pkl
│   │
│   ├── 📊 Original Data/           # Raw dataset
│   │   └── test.csv
│   │
│   ├── 🔧 Processors/              # Data preprocessing scripts
│   │   ├── apply_vectorizer.ipynb
│   │   ├── no_transliteration_processor.ipynb
│   │   ├── tf_idf_vectorizer.ipynb
│   │   └── with_transliteration_processor.ipynb
│   │
│   ├── 📈 Train Data/              # Training results & visualizations
│   │   ├── Graphs/                 # Training performance plots
│   │   ├── Logs/                   # Training logs
│   │   └── Results/                # Model outputs
│   │
│   └── 🏋️ Trainers/                # Training infrastructure
│       ├── classification_features_generator.ipynb
│       ├── dataset.py
│       ├── logger.py
│       ├── trainer.py
│       └── training_bert.py
│
├── 📊 DL Feature set 1024/         # 1024-dimensional experiments
│   └── [Same structure as 512]
│
├── 📊 DL Feature set 2048/         # 2048-dimensional experiments
│   └── [Same structure as 512]
│
├── 🔄 Trans data/                  # Transliterated features
│   ├── test_features.csv
│   ├── test_processed.csv
│   └── tfidf_vectorizer_1.pkl
│
├── 🖼️ Images/                       # Documentation assets
│   └── overview.png
│
├── 🎯 ML Classification Heads/     # Ensemble classification
│   ├── size 512/                   # 512-dim ensemble results
│   ├── size 1024/                  # 1024-dim ensemble results
│   ├── size 2048/                  # 2048-dim ensemble results
│   ├── code.ipynb                  # Main ensemble script
│   ├── final_1024.csv             # Final predictions
│   ├── final_2048.csv
│   ├── final_512.csv
│   └── best_submission.csv         # Competition submission
│
└── 📖 README.md                    # This file
🛠️ Technology Stack
| 🏷️ Package | 🔢 Version | 📝 Purpose |
|---|---|---|
 | 3.8+ | Programming language |
 | 2.0+ | Deep learning framework |
 | 4.0+ | Pre-trained models |
 | 1.0+ | Machine learning |
| 🏷️ Package | 📝 Purpose |
|---|---|
xgboost | Gradient boosting |
lightgbm | Light gradient boosting |
catboost | Categorical boosting |
pandas | Data manipulation |
numpy | Numerical computing |
nltk | Natural language processing |
emoji | Emoji handling |
pip install torch>=2.0 transformers>=4.0 scikit-learn>=1.0 \
    xgboost lightgbm catboost pandas numpy nltk emoji \
    matplotlib seaborn tqdm jupyter
| 💡 Finding | 📊 Impact | 🔍 Details |
|---|---|---|
| 🔢 Multi-scale representations | +3.6% F1 | Different dimensions (512/1024/2048) capture varying feature granularity |
| 🤝 Hybrid features | +2.8% F1 | TF-IDF + transformers = statistical + contextual information |
| 🔧 Model-specific preprocessing | +1.9% F1 | Transliteration vs. original text per model type |
| 🗳️ Ensemble diversity | +4.2% F1 | Hierarchical voting across features, models, and scales |
🔥 Best Performing: 2048-dimensional features
🎯 Most Consistent: Random Forest classifiers
🚀 Biggest Surprise: Gradient Boosting on Google BERT
📊 Sweet Spot: 1024-dimensional IndicBERT
Advanced hate speech detection in Tamil-English code-mixed social media content using hybrid deep learning architectures.
Jupyter Notebook
0
1 commits
updated Jul 30, 2025
🎯 Advanced hate speech detection in Tamil-English code-mixed social media content using hybrid deep learning architectures
This repository contains our award-winning submission to the LT-EDI 2025 shared task on caste and migration-based hate speech detection in code-mixed Tamil social media content. Our innovative multi-scale hybrid architecture combines classical TF-IDF features with state-of-the-art transformer embeddings, achieving 3rd place with an impressive F1-score of 0.818.
🏗️ Multi-scale Hybrid Architecture Overview
Our solution achieved outstanding performance in the LT-EDI 2025 shared task:
| 🏅 Rank | 👥 Team Name | 📊 F1-Score | 📈 Performance |
|---|---|---|---|
| 🥇 1st | CUET_N317 | 0.88105 | Leading |
| 🥈 2nd | CUET's_white_walkers | 0.86289 | Strong |
| 🥉 3rd | Wise (Ours) | 0.81827 | Excellent |
| 4th | CUET_blitz_aces | 0.81682 | Good |
| 5th | hinterwelt | 0.80916 | Good |
🎓 Amrita School of Artificial Intelligence
Coimbatore, Amrita Vishwa Vidyapeetham, India
| 👤 Team Member | 🎯 Role | 🔗 Profile |
|---|---|---|
| Ganesh Sundhar S | Lead Researcher | Deep Learning & NLP |
| Durai Singh K | ML Engineer | Feature Engineering & Ensemble |
| Gnanasabesan G | Data Scientist | Preprocessing & Analysis |
| Hari Krishnan N | AI Researcher | Model Architecture |
| Dhanush MC | Software Engineer | Pipeline & Optimization |
🗃️ LT-EDI 2025 Tamil-English Code-Mixed Hate Speech Dataset
| 📊 Split | 🔢 Count | 📝 Description |
|---|---|---|
| 🚂 Training | 5,512 | Comments for model training |
| 🔍 Development | 787 | Comments for validation |
| 🧪 Test | 1,576 | Comments for final evaluation |
| 📦 Total | 7,875 | Complete dataset |
| 🏷️ Label | 📝 Description | 🎯 Target |
|---|---|---|
0 | Non-hate speech | Safe content |
1 | Hate speech | Caste/migration-based hate |
🔸 Non-hate: "Good morning anna, how are you doing today?"
🔹 Hate: "[Contains offensive content targeting specific communities]"
Note: The dataset contains Tamil-English code-mixed social media comments with varying degrees of code-switching and transliteration.
Our approach implements a sophisticated multi-stage pipeline that combines classical and modern NLP techniques.
Input Text → Replace newlines → Convert emojis → Remove URLs →
Normalize spaces → Convert to lowercase → Output
Input Text → Basic cleaning → Tamil Unicode to English →
Remove repeated chars → Remove non-ASCII → Output
📋 Preprocessing Steps:
graph LR
    A[Raw Text] --> B[TF-IDF Vectorizer]
    B --> C[~22,000 dimensions]
    C --> D[Truncated SVD]
    D --> E[512/1024/2048 dims]
    E --> F[MLP Compression]
    F --> G[32/64/128 dims]
| 🤖 Model | 📚 Type | 🔤 Input | 📐 Dimensions |
|---|---|---|---|
| Google BERT | bert-large-uncased | Transliterated | 768 → 960 |
| XLM-RoBERTa Base | xlm-roberta-base | Original | 768 → 960 |
| XLM-RoBERTa Large | xlm-roberta-large | Original | 1024 → 960 |
| IndicBERT | IndicBERTv2-MLM | Original | 768 → 960 |
| Seanbenhur BERT | tanglish-offensive | Transliterated | 768 → 960 |
graph TD
    A[TF-IDF Features] --> D[Feature Fusion]
    B[BERT Embeddings] --> D
    C[RoBERTa Embeddings] --> D
    D --> E[ML Classifiers]
    E --> F[Level 1: Top-3 Voting]
    F --> G[Level 2: Cross-Model Voting]
    G --> H[Level 3: Multi-Scale Voting]
    H --> I[Final Prediction]
🌳 Tree-Based Models:
📏 Linear Models:
🔮 Other Models:
🔧 Comprehensive System Architecture
| 🤖 Transformer | 🏆 Best Model | 📈 F1-Score | 🎯 Performance |
|---|---|---|---|
| Google BERT | Random Forest | 0.803 | 🟢 Good |
| IndicBERT | Random Forest | 0.817 | 🟡 Very Good |
| SeanBenhur BERT | XGBoost | 0.814 | 🟡 Very Good |
| XLM-R Base | Random Forest | 0.807 | 🟢 Good |
| XLM-R Large | Extra Trees | 0.806 | 🟢 Good |
| 🤖 Transformer | 🏆 Best Model | 📈 F1-Score | 🎯 Performance |
|---|---|---|---|
| Google BERT | SVM | 0.818 | 🟡 Very Good |
| IndicBERT | Random Forest | 0.829 | 🟠 Excellent |
| SeanBenhur BERT | Random Forest | 0.822 | 🟡 Very Good |
| XLM-R Base | Nu-SVM | 0.825 | 🟡 Very Good |
| XLM-R Large | Random Forest | 0.830 | 🟠 Excellent |
| 🤖 Transformer | 🏆 Best Model | 📈 F1-Score | 🎯 Performance |
|---|---|---|---|
| Google BERT | Gradient Boosting | 0.839 | 🔥 Outstanding |
| IndicBERT | Ridge Regression | 0.824 | 🟡 Very Good |
| SeanBenhur BERT | Nu-SVM | 0.826 | 🟡 Very Good |
| XLM-R Base | Random Forest | 0.835 | 🟠 Excellent |
| XLM-R Large | Random Forest | 0.833 | 🟠 Excellent |
🎊 LT-EDI 2025 Leaderboard
| 🏅 Rank | 👥 Team Name | 📊 F1-Score | 📈 Gap | 🎯 Status |
|---|---|---|---|---|
| 🥇 1st | CUET_N317 | 0.88105 | - | 🔥 Winner |
| 🥈 2nd | CUET's_white_walkers | 0.86289 | -0.018 | 🚀 Runner-up |
| 🥉 3rd | Wise (Ours) | 0.81827 | -0.044 | ✨ Bronze |
| 4th | CUET_blitz_aces | 0.81682 | -0.001 | 📈 Close |
| 5th | hinterwelt | 0.80916 | -0.009 | 💪 Strong |
🎯 Achievement: Our team secured 3rd place out of numerous international participants, demonstrating the effectiveness of our multi-scale ensemble approach!
📈 Model Training Visualization Across Different Dimensions
| 🤖 Model | 📈 Training Graph |
|---|---|
| Google BERT | |
| IndicBERT | |
| Seanbenhur BERT | |
| XLM-RoBERTa Base | |
| XLM-RoBERTa Large | |
| 🤖 Model | 📈 Training Graph |
|---|---|
| Google BERT | |
| IndicBERT | |
| Seanbenhur BERT | |
| XLM-RoBERTa Base | |
| XLM-RoBERTa Large | |
| 🤖 Model | 📈 Training Graph |
|---|---|
| Google BERT | |
| IndicBERT | |
| Seanbenhur BERT | |
| XLM-RoBERTa Base | |
| XLM-RoBERTa Large | |
# Python 3.8+ required
python --version  # Should be >= 3.8
# Clone the repository
git clone https://github.com/your-username/CasteMigrationHateSpeech.git
cd CasteMigrationHateSpeech

# Install dependencies
pip install -r requirements.txt

# Install additional dependencies
pip install torch torchvision transformers
pip install xgboost lightgbm catboost
# Navigate to preprocessors
cd "DL Feature set 1024/Processors"

# Run preprocessing notebooks
jupyter notebook with_transliteration_processor.ipynb
jupyter notebook no_transliteration_processor.ipynb
# Generate TF-IDF features
jupyter notebook tf_idf_vectorizer.ipynb

# Apply vectorizer
jupyter notebook apply_vectorizer.ipynb
# Navigate to trainers
cd "../Trainers"

# Train transformer models
python training_bert.py  # Configure model in script
# Navigate to ML heads
cd "../../ML Classification Heads"

# Run ensemble classification
jupyter notebook code.ipynb
🏆 CasteMigrationHateSpeech-main/
│
├── 📊 DL Feature set 512/          # 512-dimensional experiments
│   ├── 🤖 Models/                  # Transformer model definitions
│   │   ├── google_bert.py
│   │   ├── indic_model.py
│   │   ├── tanglish_model.py
│   │   ├── xlm_roberta_base.py
│   │   └── xlm_roberta_large.py
│   │
│   ├── 📄 No trans data/           # Non-transliterated features
│   │   ├── test_features_no_trans.csv
│   │   ├── test_processed_no_trans.csv
│   │   └── tfidf_vectorizer_2.pkl
│   │
│   ├── 📊 Original Data/           # Raw dataset
│   │   └── test.csv
│   │
│   ├── 🔧 Processors/              # Data preprocessing scripts
│   │   ├── apply_vectorizer.ipynb
│   │   ├── no_transliteration_processor.ipynb
│   │   ├── tf_idf_vectorizer.ipynb
│   │   └── with_transliteration_processor.ipynb
│   │
│   ├── 📈 Train Data/              # Training results & visualizations
│   │   ├── Graphs/                 # Training performance plots
│   │   ├── Logs/                   # Training logs
│   │   └── Results/                # Model outputs
│   │
│   └── 🏋️ Trainers/                # Training infrastructure
│       ├── classification_features_generator.ipynb
│       ├── dataset.py
│       ├── logger.py
│       ├── trainer.py
│       └── training_bert.py
│
├── 📊 DL Feature set 1024/         # 1024-dimensional experiments
│   └── [Same structure as 512]
│
├── 📊 DL Feature set 2048/         # 2048-dimensional experiments
│   └── [Same structure as 512]
│
├── 🔄 Trans data/                  # Transliterated features
│   ├── test_features.csv
│   ├── test_processed.csv
│   └── tfidf_vectorizer_1.pkl
│
├── 🖼️ Images/                       # Documentation assets
│   └── overview.png
│
├── 🎯 ML Classification Heads/     # Ensemble classification
│   ├── size 512/                   # 512-dim ensemble results
│   ├── size 1024/                  # 1024-dim ensemble results
│   ├── size 2048/                  # 2048-dim ensemble results
│   ├── code.ipynb                  # Main ensemble script
│   ├── final_1024.csv             # Final predictions
│   ├── final_2048.csv
│   ├── final_512.csv
│   └── best_submission.csv         # Competition submission
│
└── 📖 README.md                    # This file
🛠️ Technology Stack
| 🏷️ Package | 🔢 Version | 📝 Purpose |
|---|---|---|
| 3.8+ | Programming language |
| 2.0+ | Deep learning framework |
| 4.0+ | Pre-trained models |
| 1.0+ | Machine learning |
| 🏷️ Package | 📝 Purpose |
|---|---|
xgboost | Gradient boosting |
lightgbm | Light gradient boosting |
catboost | Categorical boosting |
pandas | Data manipulation |
numpy | Numerical computing |
nltk | Natural language processing |
emoji | Emoji handling |
pip install torch>=2.0 transformers>=4.0 scikit-learn>=1.0 \
    xgboost lightgbm catboost pandas numpy nltk emoji \
    matplotlib seaborn tqdm jupyter
| 💡 Finding | 📊 Impact | 🔍 Details |
|---|---|---|
| 🔢 Multi-scale representations | +3.6% F1 | Different dimensions (512/1024/2048) capture varying feature granularity |
| 🤝 Hybrid features | +2.8% F1 | TF-IDF + transformers = statistical + contextual information |
| 🔧 Model-specific preprocessing | +1.9% F1 | Transliteration vs. original text per model type |
| 🗳️ Ensemble diversity | +4.2% F1 | Hierarchical voting across features, models, and scales |
🔥 Best Performing: 2048-dimensional features
🎯 Most Consistent: Random Forest classifiers
🚀 Biggest Surprise: Gradient Boosting on Google BERT
📊 Sweet Spot: 1024-dimensional IndicBERT



