Multiclass sentiment analysis of Tamil political X (Twitter) comments using transformer models and hybrid classification. Achieved F1-score of 0.3122 with IndicBERT + Random Forest approach, ranked 14th in NAACL benchmark.
Python
0
12 commits
updated Jun 3, 2025
This project implements a multiclass sentiment analysis system for Tamil political comments from X (Twitter) using transformer-based models. The system classifies Tamil text into seven sentiment categories while handling challenges like morphological richness, agglutinative structure, code-mixing, slang, and sarcasm.
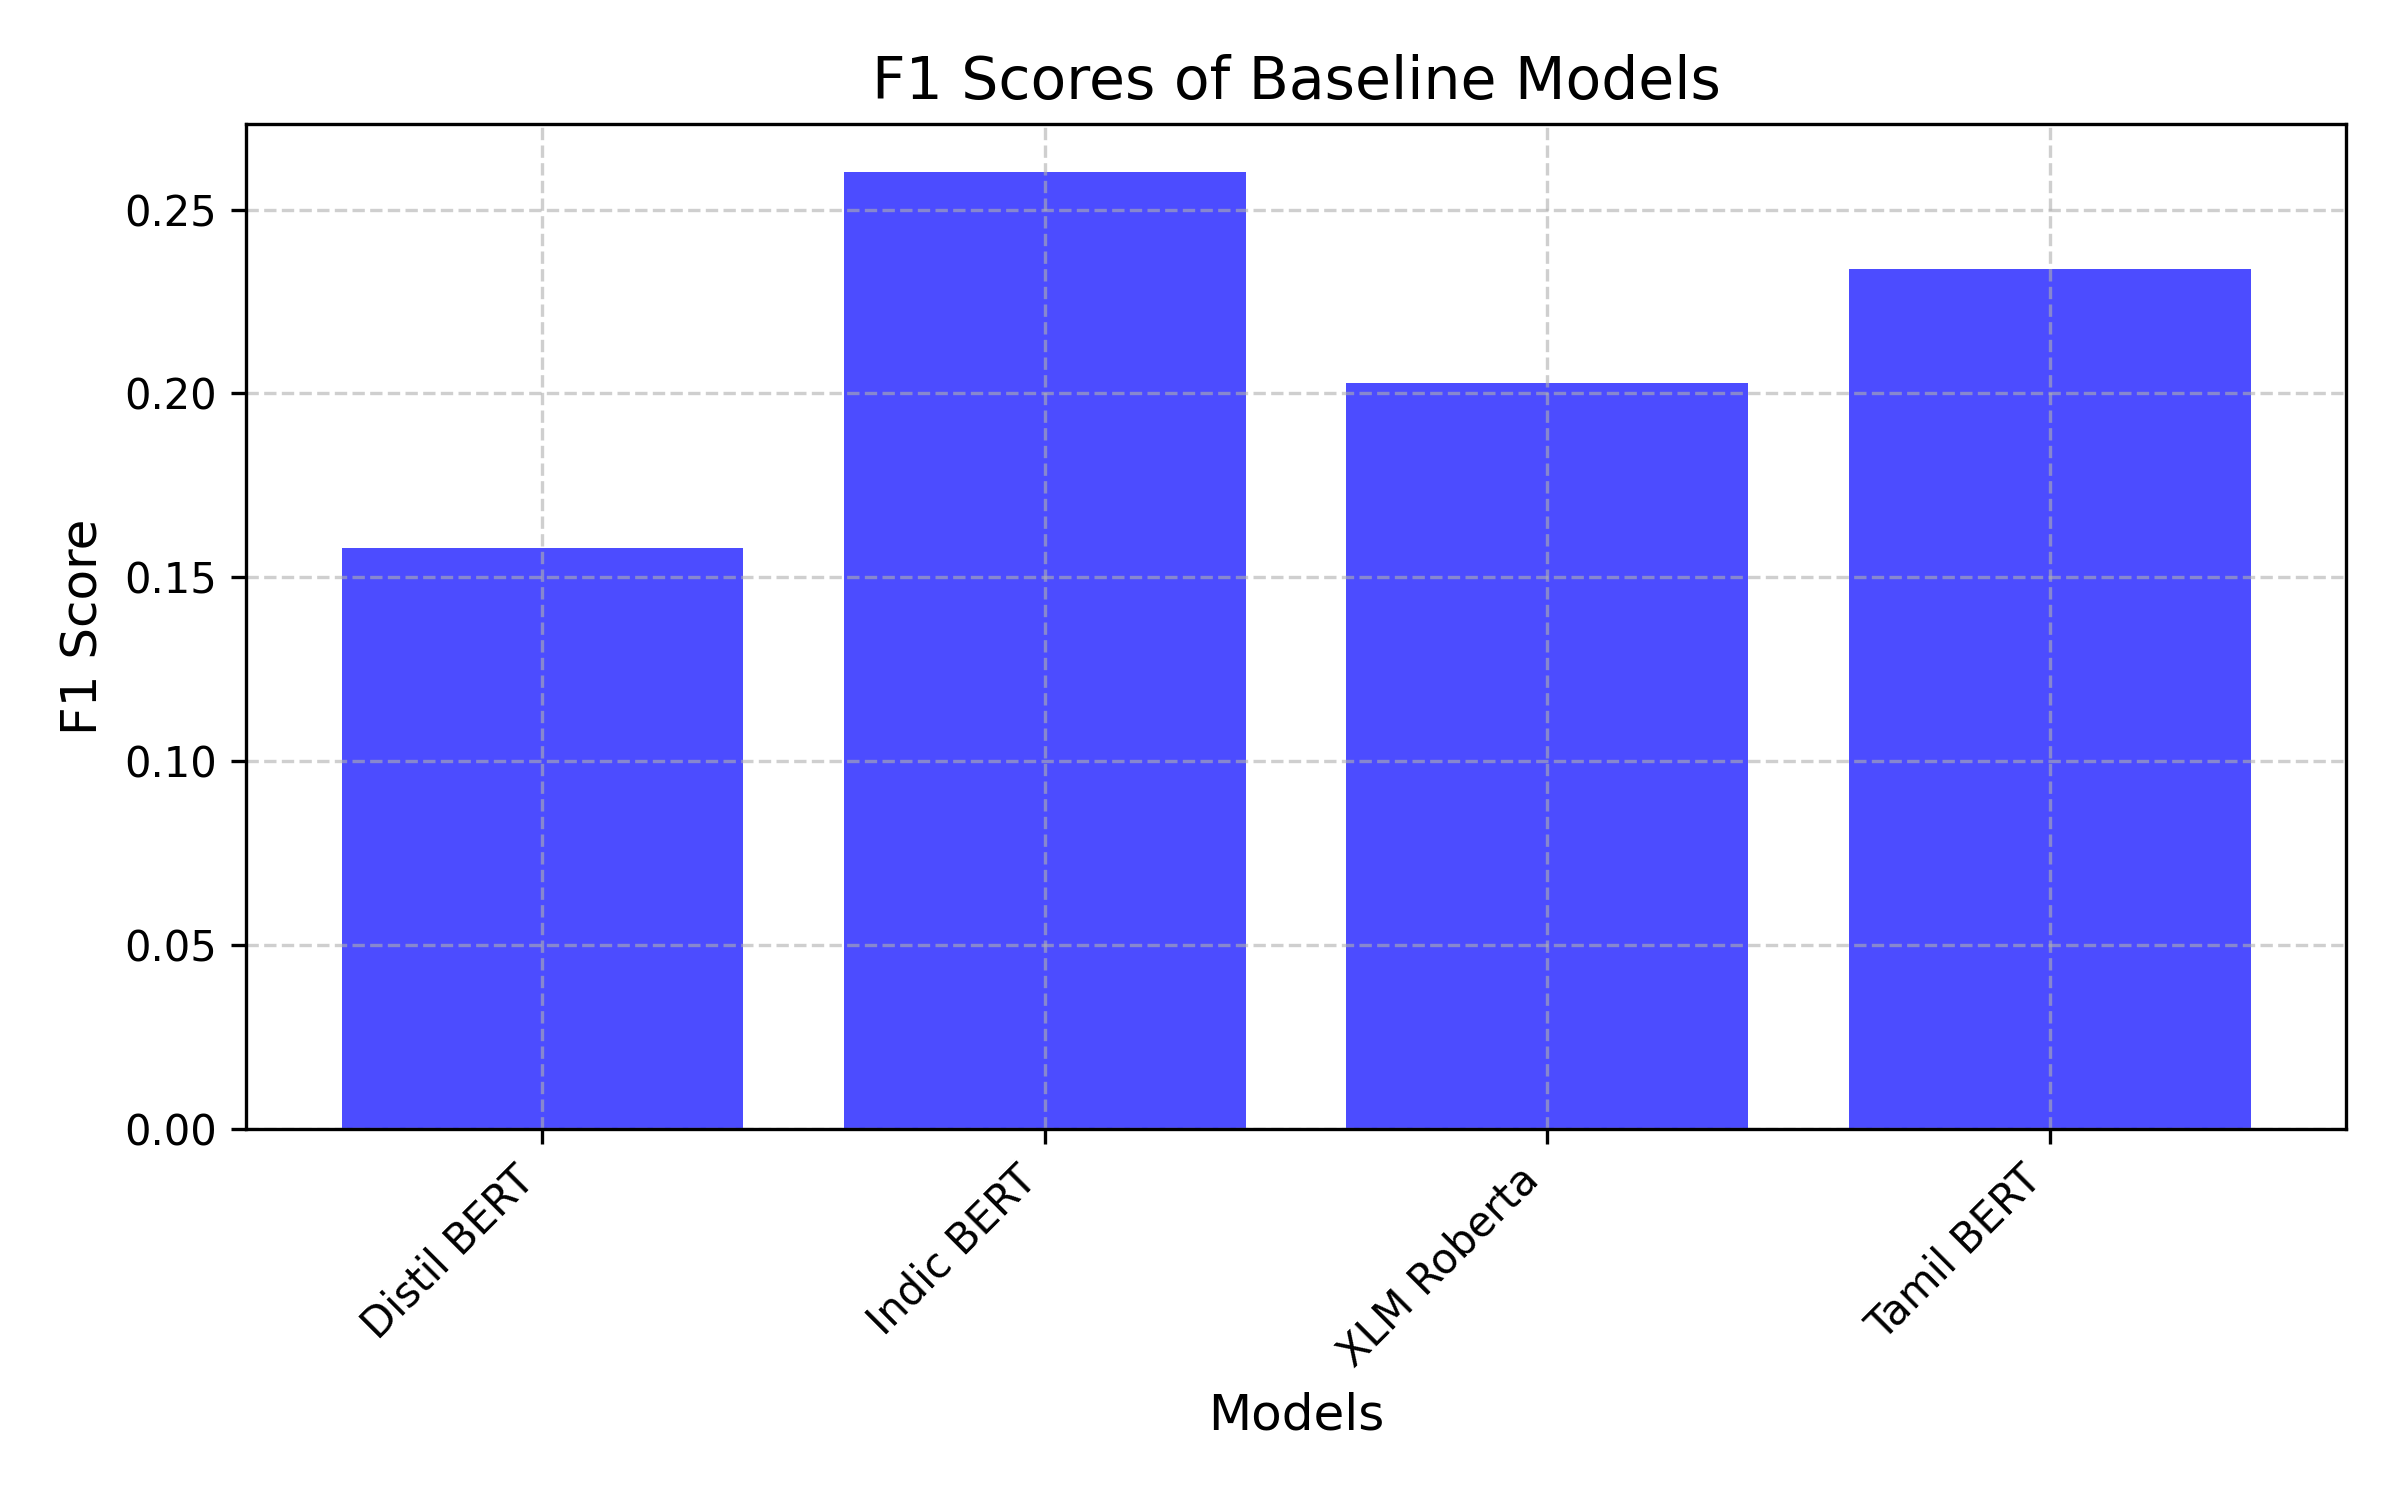
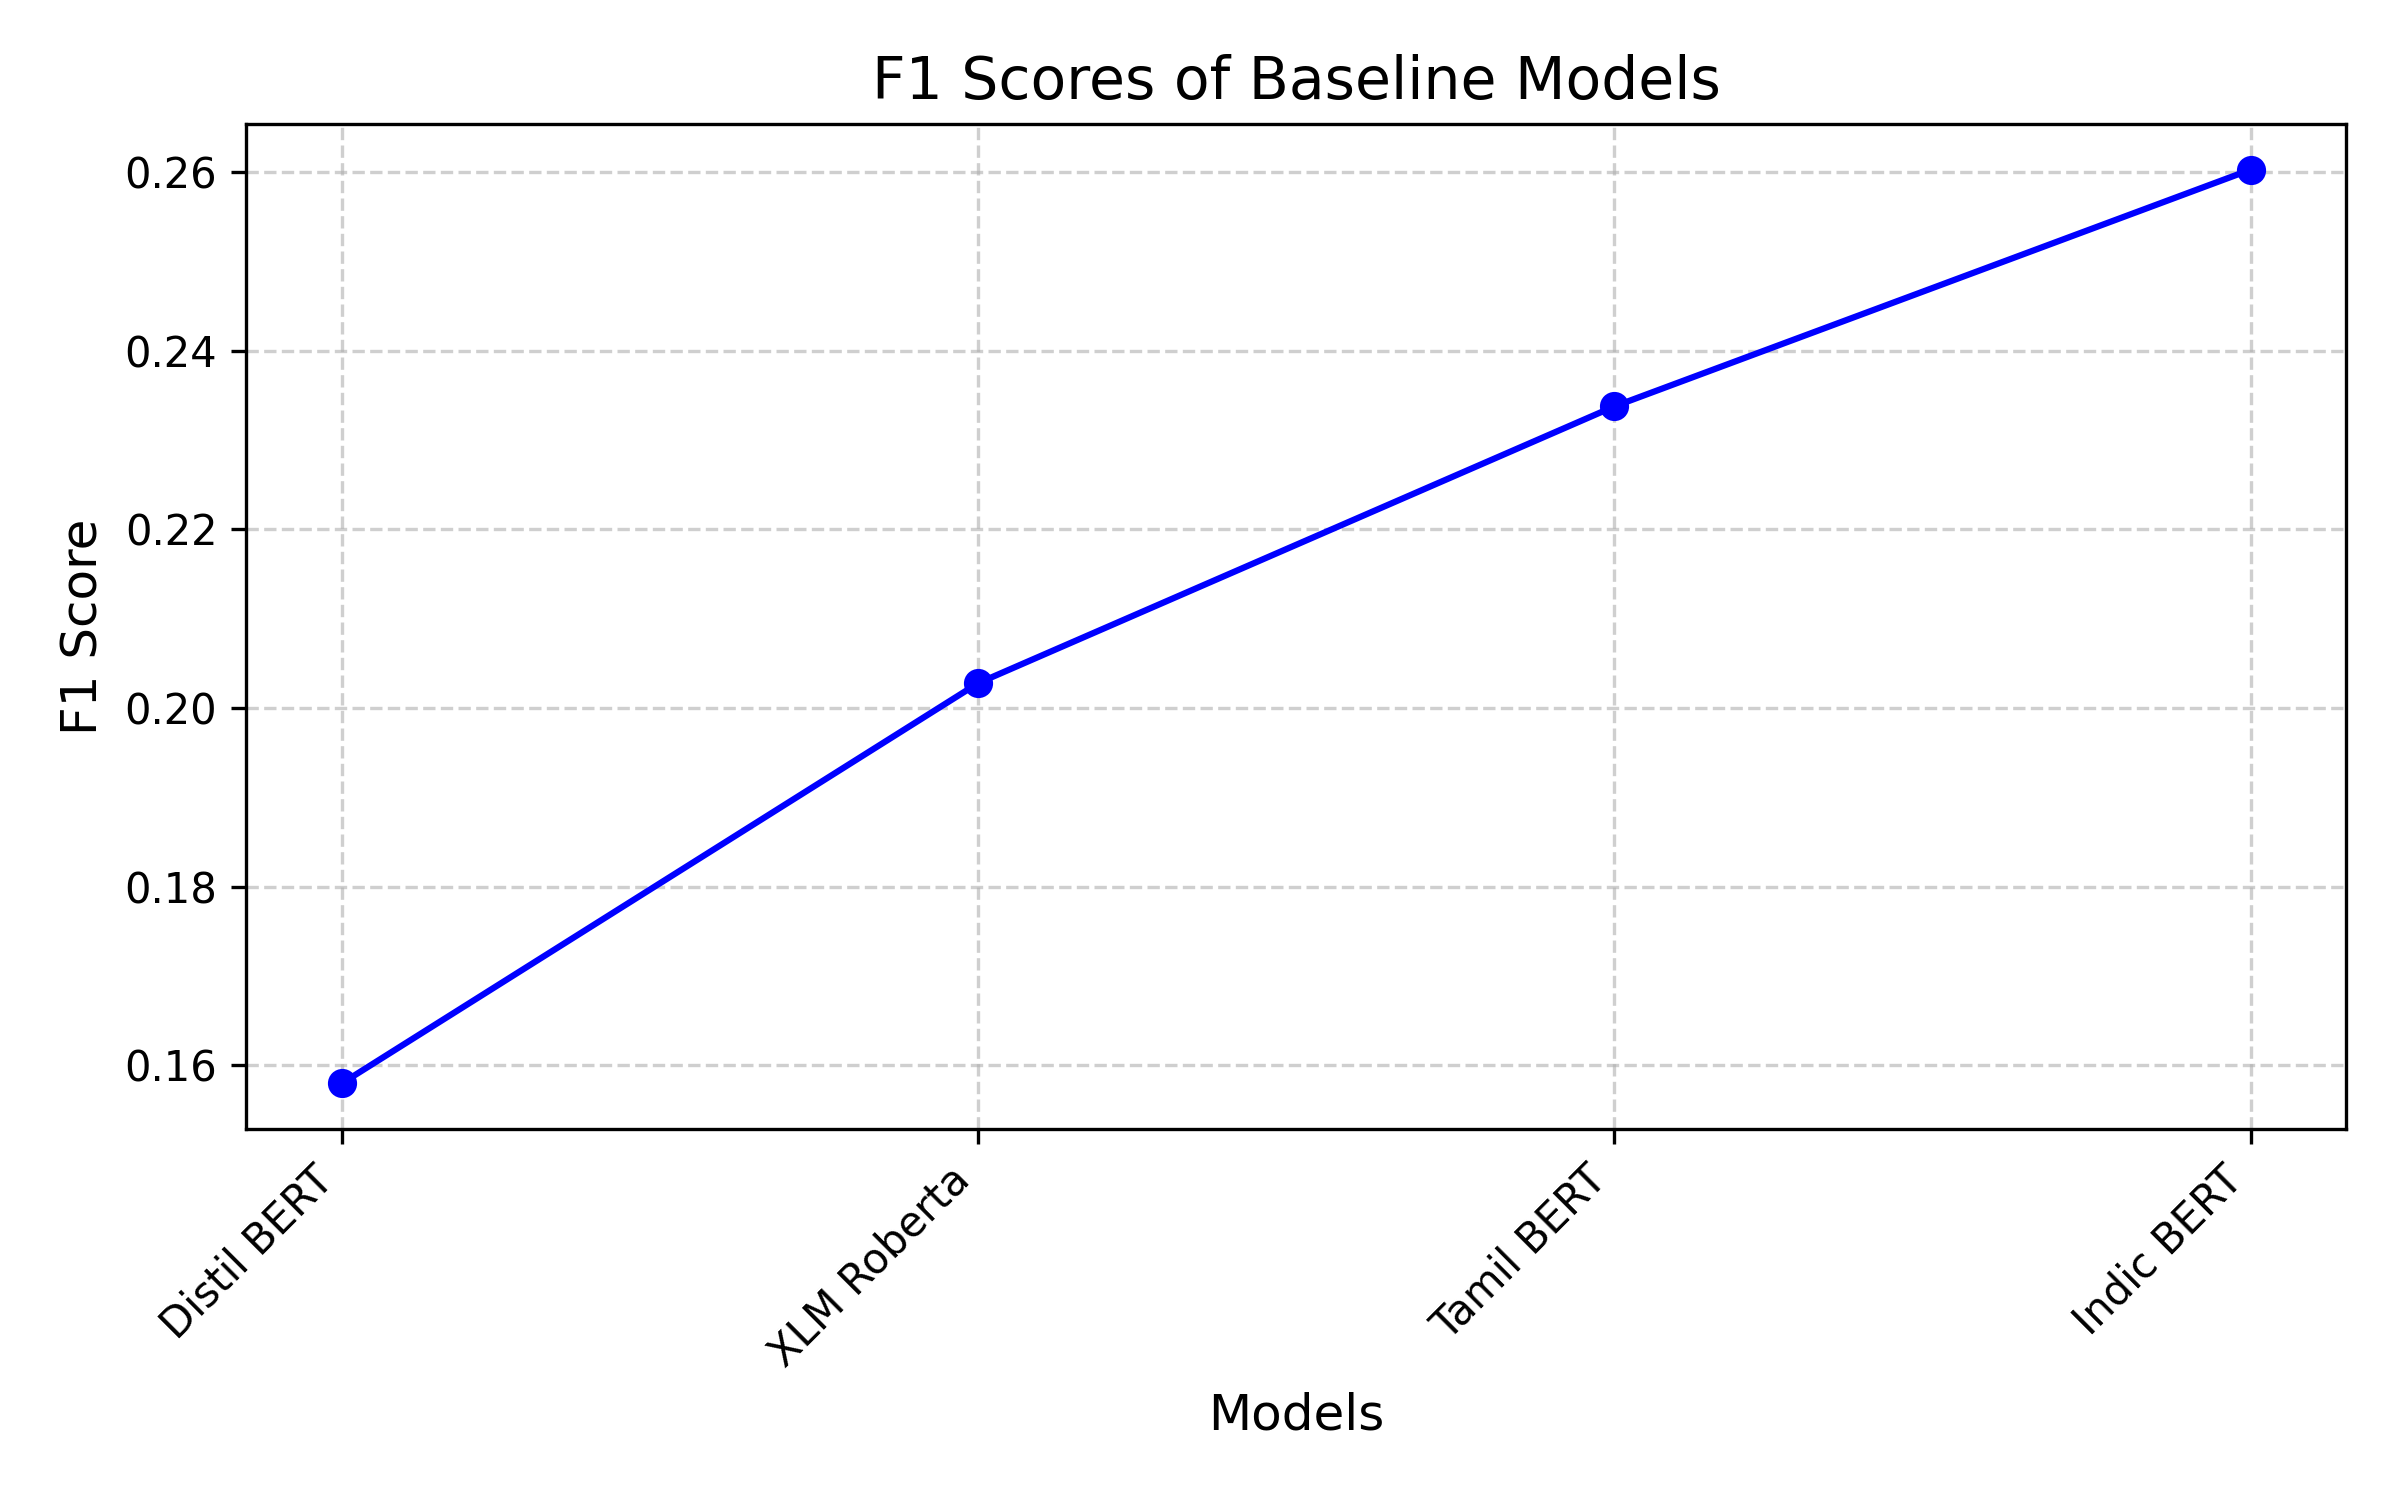 Comparison of different transformer-based base models for Tamil sentiment analysis
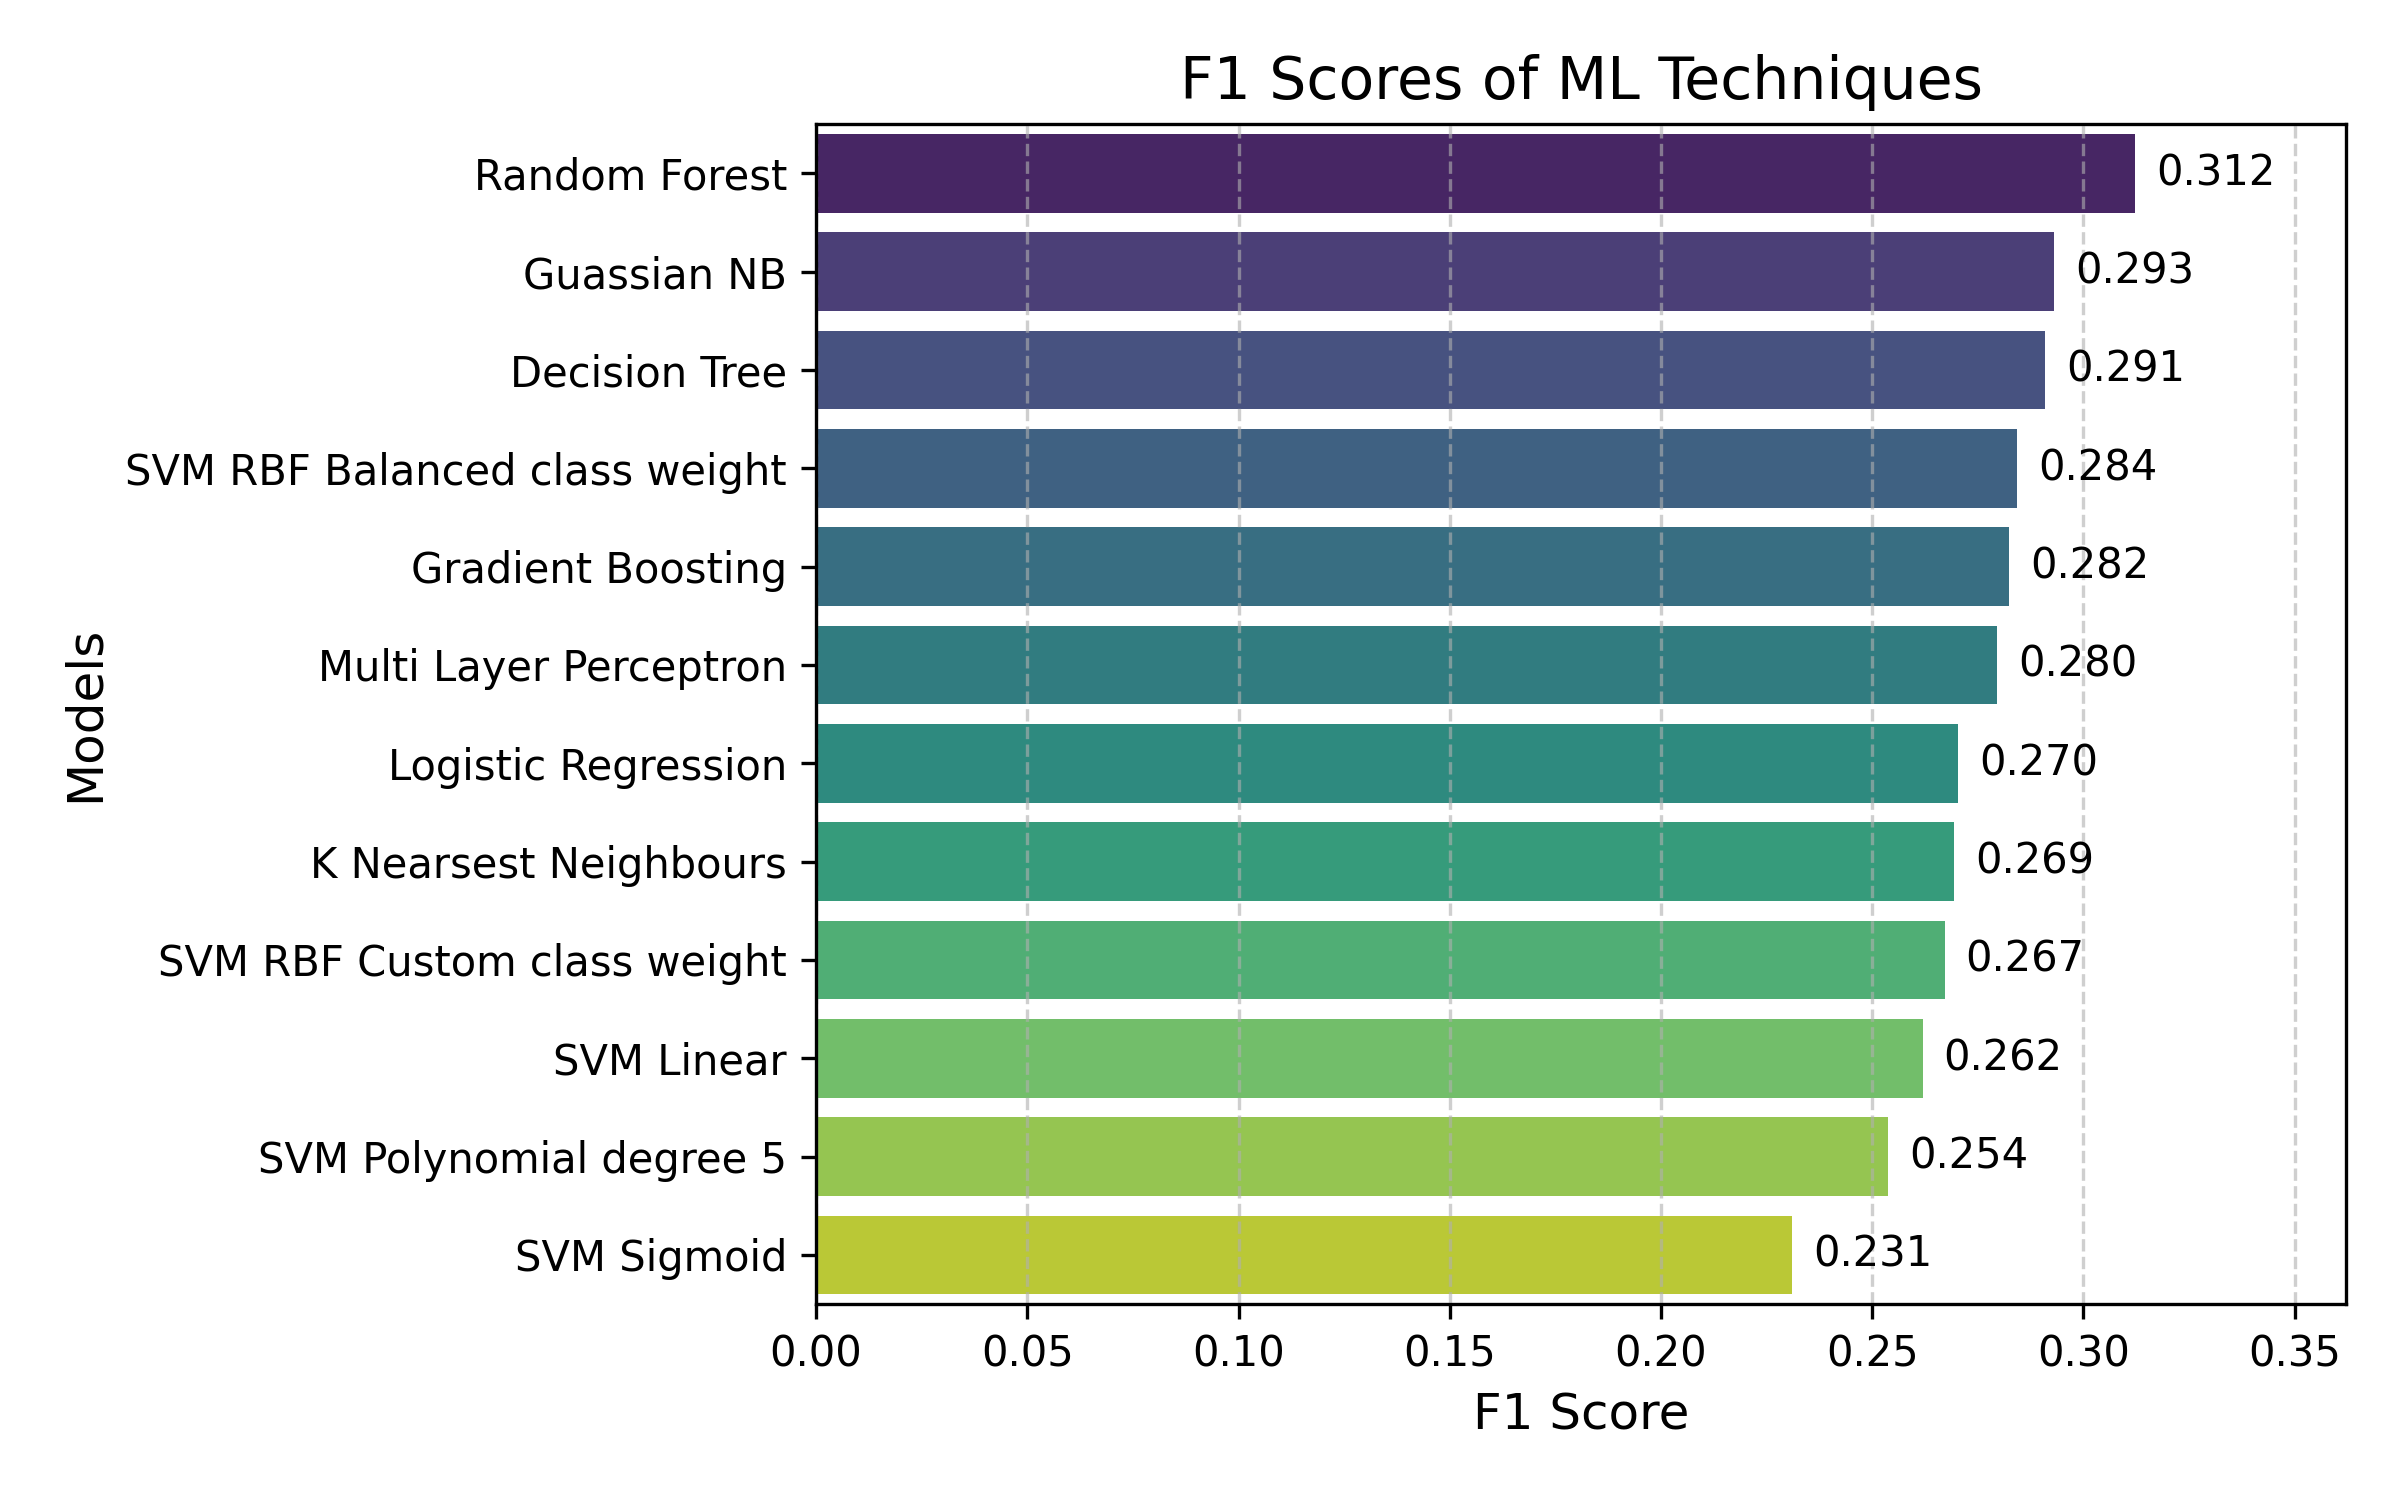 Performance comparison of machine learning models used as classification heads
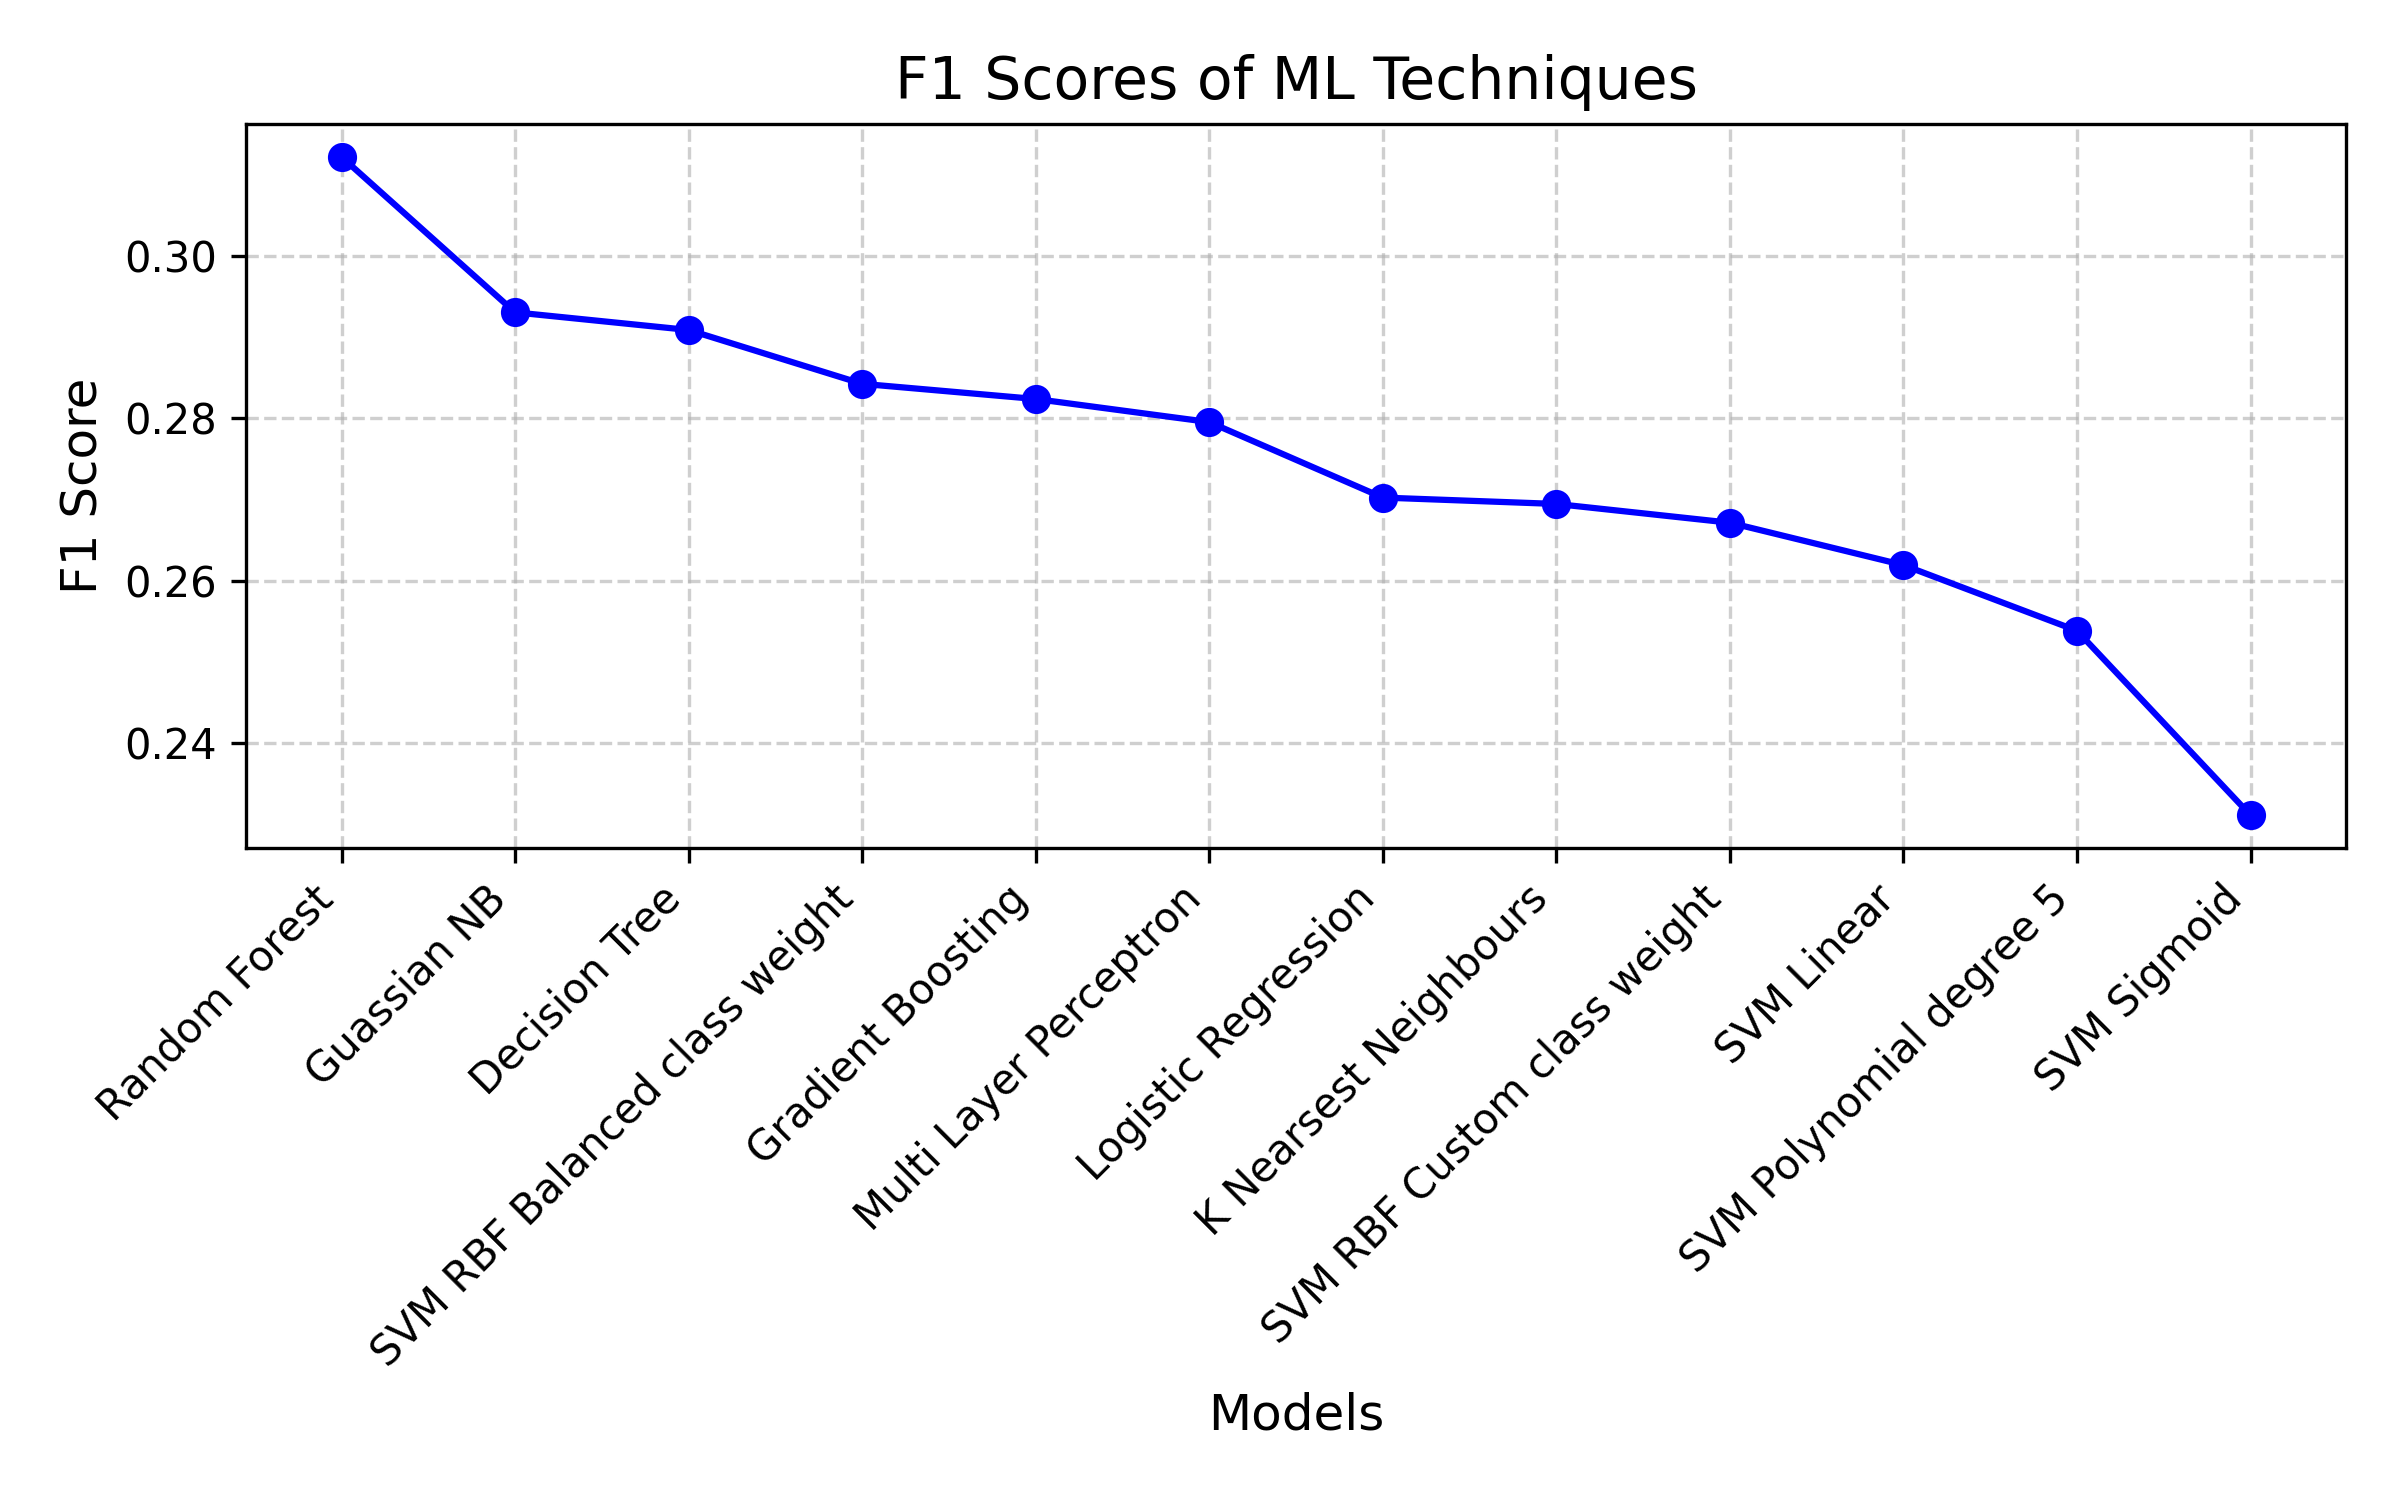 Overall model performance metrics across different approaches
 Training progress and convergence analysis
The system classifies Tamil political tweets into seven sentiment categories:
The project includes implementations for multiple transformer models:
| Model | F1 Score | Parameters | Language Coverage |
|---|---|---|---|
| Random Forest (Best) | 0.3122 | - | - |
| IndicBERT | 0.2759 | 470M | Indic languages |
| XLM-RoBERTa | 0.2027 | 278M | Multilingual |
| DistilBERT | 0.1580 | 66M | Multilingual |
| TamilBERT | 0.1037 | 389M | Tamil only |
Traditional ML models tested with extracted features:
| Model | F1 Score |
|---|---|
| Random Forest | 0.3122 |
| Gaussian Naive Bayes | 0.2930 |
| Decision Tree | 0.2909 |
| SVM (RBF Balanced) | 0.2842 |
| Gradient Boosting | 0.2824 |
| Multi-Layer Perceptron | 0.2795 |
# Tamil text preprocessing pipeline
def preprocess(text):
    text = re.sub(r"#\S+|@\S+|https?:\/\/\S+", "", text)  # Remove hashtags, mentions, URLs
    text = re.sub(r"[^அ-ஹ0-9\s]", "", text)  # Keep only Tamil script and numbers
    text = re.sub(r"[\n\r\t]+", " ", text)  # Normalize whitespace
    text = re.sub(r"\s+", " ", text).strip()  # Remove extra spaces
    text = re.sub(r"(.)\1{2,}", r"\1\1", text)  # Reduce character repetitions
    return text
class PSAModel(nn.Module):
    def __init__(self, num_classes=7):
        super(PSAModel, self).__init__()
        self.bert = AutoModelForMaskedLM.from_pretrained("ai4bharat/IndicBERTv2-MLM-Sam-TLM")
        self.final_fc = nn.Linear(in_features=250000, out_features=num_classes, bias=True)

    def forward(self, x, mask=None):
        x = self.bert(x, attention_mask=mask).logits
        x = torch.mean(x, dim=1)
        x = self.final_fc(x)
        return x
PoliticalSA/
├── Distil BERT/           # DistilBERT implementation
├── Indic BERT/            # IndicBERT implementation (best performing)
├── Tamil Bert/            # TamilBERT implementation
├── XLM-Roberta/          # XLM-RoBERTa implementation
├── Machine Learning Models/  # Traditional ML approaches
├── Trainer/              # Training utilities and logging
├── Graphs/               # Performance visualization plots
└── final_test.csv        # Feature vectors for ML models
The hybrid approach combining IndicBERT feature extraction with Random Forest classification achieved the best performance:
cd "Indic BERT"
python training_model.py
jupyter notebook vector_generation.ipynb
cd "Machine Learning Models"
jupyter notebook other_models.ipynb
Multiclass sentiment analysis of Tamil political X (Twitter) comments using transformer models and hybrid classification. Achieved F1-score of 0.3122 with IndicBERT + Random Forest approach, ranked 14th in NAACL benchmark.
Python
0
12 commits
updated Jun 3, 2025
This project implements a multiclass sentiment analysis system for Tamil political comments from X (Twitter) using transformer-based models. The system classifies Tamil text into seven sentiment categories while handling challenges like morphological richness, agglutinative structure, code-mixing, slang, and sarcasm.
Comparison of different transformer-based base models for Tamil sentiment analysis
Performance comparison of machine learning models used as classification heads
Overall model performance metrics across different approaches
Training progress and convergence analysis
The system classifies Tamil political tweets into seven sentiment categories:
The project includes implementations for multiple transformer models:
| Model | F1 Score | Parameters | Language Coverage |
|---|---|---|---|
| Random Forest (Best) | 0.3122 | - | - |
| IndicBERT | 0.2759 | 470M | Indic languages |
| XLM-RoBERTa | 0.2027 | 278M | Multilingual |
| DistilBERT | 0.1580 | 66M | Multilingual |
| TamilBERT | 0.1037 | 389M | Tamil only |
Traditional ML models tested with extracted features:
| Model | F1 Score |
|---|---|
| Random Forest | 0.3122 |
| Gaussian Naive Bayes | 0.2930 |
| Decision Tree | 0.2909 |
| SVM (RBF Balanced) | 0.2842 |
| Gradient Boosting | 0.2824 |
| Multi-Layer Perceptron | 0.2795 |
# Tamil text preprocessing pipeline
def preprocess(text):
    text = re.sub(r"#\S+|@\S+|https?:\/\/\S+", "", text)  # Remove hashtags, mentions, URLs
    text = re.sub(r"[^அ-ஹ0-9\s]", "", text)  # Keep only Tamil script and numbers
    text = re.sub(r"[\n\r\t]+", " ", text)  # Normalize whitespace
    text = re.sub(r"\s+", " ", text).strip()  # Remove extra spaces
    text = re.sub(r"(.)\1{2,}", r"\1\1", text)  # Reduce character repetitions
    return text
class PSAModel(nn.Module):
    def __init__(self, num_classes=7):
        super(PSAModel, self).__init__()
        self.bert = AutoModelForMaskedLM.from_pretrained("ai4bharat/IndicBERTv2-MLM-Sam-TLM")
        self.final_fc = nn.Linear(in_features=250000, out_features=num_classes, bias=True)

    def forward(self, x, mask=None):
        x = self.bert(x, attention_mask=mask).logits
        x = torch.mean(x, dim=1)
        x = self.final_fc(x)
        return x
PoliticalSA/
├── Distil BERT/           # DistilBERT implementation
├── Indic BERT/            # IndicBERT implementation (best performing)
├── Tamil Bert/            # TamilBERT implementation
├── XLM-Roberta/          # XLM-RoBERTa implementation
├── Machine Learning Models/  # Traditional ML approaches
├── Trainer/              # Training utilities and logging
├── Graphs/               # Performance visualization plots
└── final_test.csv        # Feature vectors for ML models
The hybrid approach combining IndicBERT feature extraction with Random Forest classification achieved the best performance:
cd "Indic BERT"
python training_model.py
jupyter notebook vector_generation.ipynb
cd "Machine Learning Models"
jupyter notebook other_models.ipynb