A ComfyUI diffusers implementation of Krea2 for the highest possible quality and most options
Python
18
15 commits
updated Oct 8, 2026
Self-contained ComfyUI custom nodes for Krea 2 - Krea AI's open-weight, from-scratch image model (single-stream MMDiT, flow matching, Qwen3-VL conditioning). Includes text-to-image, progressive multi-stage high-res generation, a 2× upscale-decode trick, natural-language prompt tooling, and an image-to-image suite (control, style, inpaint/outpaint, instruction edits) plus negative guidance that works on Turbo.
No dependency on any other node pack.
Real diffusers pipeline, not a reimplementation. Runs the genuine Hugging
Face Krea2Pipeline (single-stream MMDiT, flow matching, Qwen3-VL conditioning)
loaded straight from weights - so you inherit upstream behaviour, fixes and the
correct trained prompt templates, with no reverse-engineered sampling loop to
drift out of sync.
Easy, honest multi-stage high-res. Up to 3 progressive stages in one node, with per-stage samplers, schedules, guidance and re-noise windows, plus an on-node resolution-chain readout so you always see the real S1→S2→S3→decode sizes.
First-class img2img. A VAE Encode node feeds an init_latent input; denoise
strength is just the stage's re-noise step window - no separate float to guess.
Reference-image style/content grounding (Vision Prompt). Ground conditioning in 1-3 reference images through Krea2's own Qwen3-VL vision path - a "prompt from a picture" effect (semantic style/content grounding, not pixel editing) with no training and none of the silently-discarded-reference pitfalls of the common community pattern. Composes freely with img2img for structure + content on separate channels.
Presets everywhere. Named JSON presets per section (loader / LoRA / Ultra / sigmas) with a ★ Save button, a Merge Settings node, and Settings-from-Image for one-click reproduction of a saved image's recipe.
LoRA with per-stage settings + presets. Apply / unload / diagnose plus a Multi-LoRA Stack - both with per-stage weights (S1/S2/S3), so a LoRA can steer composition harder than final detail (or vice-versa) within a single multi-stage run, and both with named-preset save/load (★ Save) for one-click recall.
Reference-latent edit pathway. With an edit-trained LoRA loaded, a Reference Latents node feeds VAE-encoded reference images through the ai-toolkit "index_timestep_zero" method - real pixel/structure conditioning (distinct from Vision Prompt's semantic grounding), reimplemented against our diffusers transformer.
Custom flow-matching samplers, no external solver. res_2m, res_2s,
deis_3m, deis_4m re-implemented from the RES/DEIS papers, selectable per
stage, with schedule + detail_bias control.
Two high-res strategies for two checkpoints. Turbo → fast 4k via the 2× upscale-decode; Raw → controlled multi-stage re-denoise - plus optional downsample "quality-pass" VAE modes that are usually cleaner than the Wan 2.1 VAE at the same size.
A full image-to-image suite on one node. Control-LoRA ("ControlNet" depth/pose), training-free style transfer, inpaint/outpaint with the AnyPaint adapter, and instruction/identity editing with the Krea 2 Identity Edit LoRA - each a small builder node that plugs into a socket on Multi-Stage Ultra, with per-stage strengths, so the same multi-stage high-res engine serves every task.
Negative prompts that work on Turbo. NAG (Normalized Attention Guidance) and NegPiP
((phrase:-1) in the prompt) give a distilled checkpoint real negatives at guidance 0 -
no second CFG pass.
Native quantized compute. Run INT8-ConvRot / MXFP8 / NVFP4 / fp8 checkpoints on their own tensor-core kernels instead of dequantizing to bf16: ~1.45x faster and ~12 GB less VRAM at 3 MP, LoRAs included. Opt-in; bf16 stays the default.
Correctness first. A same-seed A/B found and fixed a diffusers flash_varlen bug that
silently dropped the bottom rows of every Krea 2 image (the "bottom band"); model switches
no longer leave the previous model resident in VRAM.
October 2026 - image-to-image suite, negative guidance, native quantized compute.
control socket:
depth / pose / canny ... structure control via Krea 2 Control-LoRA checkpoints (expanded
input layer + block LoRA), per-stage strengths. See Control.style socket: transfers palette / brushwork / texture from one image with no LoRA.
See Style Reference.paint socket: AnyPaint / Outpaint adapters, kept regions pinned to the source at every
stage. See Inpaint / outpaint.edit socket: the Krea 2 Identity Edit
recipe (recolor, restyle, re-pose, add / replace objects, outpaint, person-into-scene),
with the v1.2 fit reference geometry and the ref_boost fidelity dial.
See Edits.guidance
socket: NAG and NegPiP, both off by default, combinable, work at guidance 0.
See Negative guidance.compute / native_format (appended):
run quantized checkpoints on their native kernels. See
Native quantized compute.comfy_kitchen layouts) next to fp8, INT8 and
INT8-ConvRot. See Quantized checkpoints.degrid toggle on both decode nodes, and degrid on Ultra (inter-stage VAE hops and/or
the final image). See DeGrid.suggestions socket for the LoRA
Suggester. See LoRA search.flash_varlen bottom-band bug (all Krea 2 attention is now mask-safe;
existing seeds render slightly differently, edge to edge correct); VRAM pinned by LoRA
nodes and by the loader on model switches; the Reference Latents edit_frame recipe used
a stretch instead of the trained fit geometry. See Notes.Late July 2026 (cont.) - field-calibrated scoring, preset UX, er_sde.
most_typical objective (consensus render) plus a uniqueness
consensus-outlier gate. Calibrated from two full 192-cell runs.Eric Sweep Folder Scorer (in
Eric-image-classification) grades a whole sweep with Blur V7 / Noise V4 /
composition / exposure / UniPercept and writes a merged scores.csv that
Auto Pick reads via best_external: sweep -> unload -> score -> pick ->
promote in one queue.custom, and a preset_notes field (also on the
Sigmas node) keeps a saved sentence about what each preset is for.er_sde sampler + simple scheduler - a ComfyUI-faithful ER-SDE
Solver-3 port (verified step-identical): intrinsically stochastic, and
the only 1-eval/step sampler that is schedule-proof (amplification 0.048
on EVERY schedule incl. linear_quadratic). eta is ignored; the noise TYPE
shapes its churn (colored-noise er_sde is unique to this package).
simple = uniform-in-sigma, an alias of linear.Late July 2026 - parameter sweeps, hybrid samplers, inter-stage renorm.
Eric Krea2 Sweep Plan into Ultra V2's
new sweep input and one queue item runs a whole grid (or explicit combo
list) of sampler / scheduler / steps / window / eta / noise / mu / cfg /
megapixels settings against a fixed seed: per-cell PNGs with full embedded
recipes, a labeled contact sheet, sweep_summary.csv, a JSON manifest,
automatic S1-latent reuse for s2/s3-only cells, and one-click promotion of a
winning cell to a preset. See Parameter sweeps.lcm_hybrid / lcm_hybrid2 samplers + hybrid_split - lcm full-churn
entry (launders upscale damage) handing off to a trajectory-faithful tail
(deis_3m / res_2m) at a selectable fraction of the window.upscale_renorm - repairs the latent variance each upscale hop drains
(variance is contrast/saturation), stopping the progressive flattening of
multi-hop runs. per_channel recommended.July 2026 - multi-stage sampling, presets & img2img toolkit.
res_2m, res_2s, deis_3m, deis_4m
re-implemented from the RES/DEIS papers (no external solver import), selectable
per stage. Recommended: res_2s + beta57 for the Stage-1 draft, deis_3m /
deis_4m + bong_tangent for the refine passes.linear, balanced, karras,
beta57, beta, bong_tangent, exponential, with a per-stage detail_bias
control driven from a dedicated Sigmas node.init_latent input on the
Multi-Stage node; denoise strength is set by the re-noise step window.width/height/blank latent) and a latent-space
Latent Resize (bislerp, no VAE round-trip).ref_latents input on the Multi-Stage Ultra (res) node. Works only with an
edit-trained LoRA loaded (e.g. the Krea 2 Style Reference LoRA on Turbo at guidance 0);
the base model can't read reference tokens. See
Reference Latents.… with downsample modes are usually cleaner/sharper than the Wan 2.1 VAE at
the same output size and avoid the resolution blow-up. An on-node resolution-chain
readout shows the real S1→S2→S3→decode sizes and flags any field the VAE overrides.
See Upscale VAE: modes & precedence.Initial release (June 2026): Krea 2 Raw + Turbo support, multi-stage high-res, 2× upscale-decode, selectable attention backend, natural-language prompt builder + LLM Magic-Prompt expander.
These nodes drive the genuine Hugging Face Krea2Pipeline directly (see
key advantages); the only hard requirement is a
diffusers/transformers build new enough to expose it.
A diffusers build that includes Krea2Pipeline (merged after 0.39.0.dev0):
python_embeded\python.exe -m pip install --upgrade --force-reinstall --no-deps git+https://github.com/huggingface/diffusers.git
The version string stays 0.39.0.dev0, so --force-reinstall is required to
pull the newer commit.
A transformers new enough to provide Qwen3VLModel.
Krea 2 weights in diffusers layout (e.g. H:\Training\Krea-2-Raw and
H:\Training\Krea-2-Turbo).
Optional, recommended on Blackwell: FlashAttention and/or SageAttention for
the faster attention_backend paths. Kernel bench on an RTX PRO 5000 (sm120, Krea 2 shapes,
2026-10-08): flash-attn 2 = baseline; SageAttention 2 sageattn (int8 QK, fp8 PV) 1.6-1.8x
faster per attention call with ~4% relative error (cos 0.9992); its Triton varlen kernel
(what attention_backend=sage picks first) only 1.13-1.17x; xformers and cuDNN SDPA = flash.
The dense kernel is the sage_fp8 choice (last in the list). End to end on Turbo, 8 steps:
-4-6% step time at 1.5 MP, -9-12% at 3 MP, -19% at 8.4 MP (10.2 -> 8.3 s/step). Images are
equally clean (text, skin, frost detail checked at 1:1) but not seed-identical to flash - the
small per-call error steers the trajectory, so the same seed gives a sibling image, sometimes a
different framing. Edit / NAG / ref_boost runs still use flash for their split attention.
Optional: the spacepxl Wan 2× upscale VAE (auto-downloaded on first use).
Optional: flash-attn (2.8+) - also used by the edit / NAG / ref_boost attention core
(falls back to an exact but slower math path without it).
Optional: ComfyUI's comfy_kitchen (ships with recent ComfyUI) - needed for MXFP8 / NVFP4 /
W4A4 / W4A8 / W6A8 checkpoints and for compute = native.
Optional, per feature: Control-LoRA, AnyPaint and Identity Edit LoRA weights (see each section).
A single, multi-purpose graph lives in workflows/. Drag
example-workflow.png onto the ComfyUI canvas (the graph is embedded in the
PNG metadata) to load the whole pipeline at once - loaders, txt2img, img2img,
Vision Prompt, per-stage sampling, and the metadata-aware save. Flip parts on/off
with group bypass (Ctrl+B) instead of juggling separate workflows. See
workflows/README.md for the group-by-group breakdown.
| Node | Does |
|---|---|
| Eric Krea2 Loader | Loads Krea2Pipeline (Raw or Turbo), applies attention_backend, caches in VRAM. Auto-detects is_distilled. Preset dropdown. |
| Eric Krea2 Generate | Text-to-image. Emits IMAGE + a chainable KREA2_LATENT. auto_settings picks 8/0 for Turbo, 28/4.5 for Raw. |
| Eric Krea2 Multi-Stage Ultra (res) | Up to 3-stage progressive high-res with the custom RES/DEIS samplers, per-stage schedules, img2img init_latent, an optional ref_latents edit input, and width/height overrides. Sockets for control, style, paint, edit and negative guidance; degrid for the VAE lattice. Best on Raw for multi-stage re-denoise. |
| Eric Krea2 Multi-Stage Ultra V2 (presets) | Preset-driven variant of the Ultra node - serialises every widget (incl. sigmas, width/height) into one reproducible recipe. |
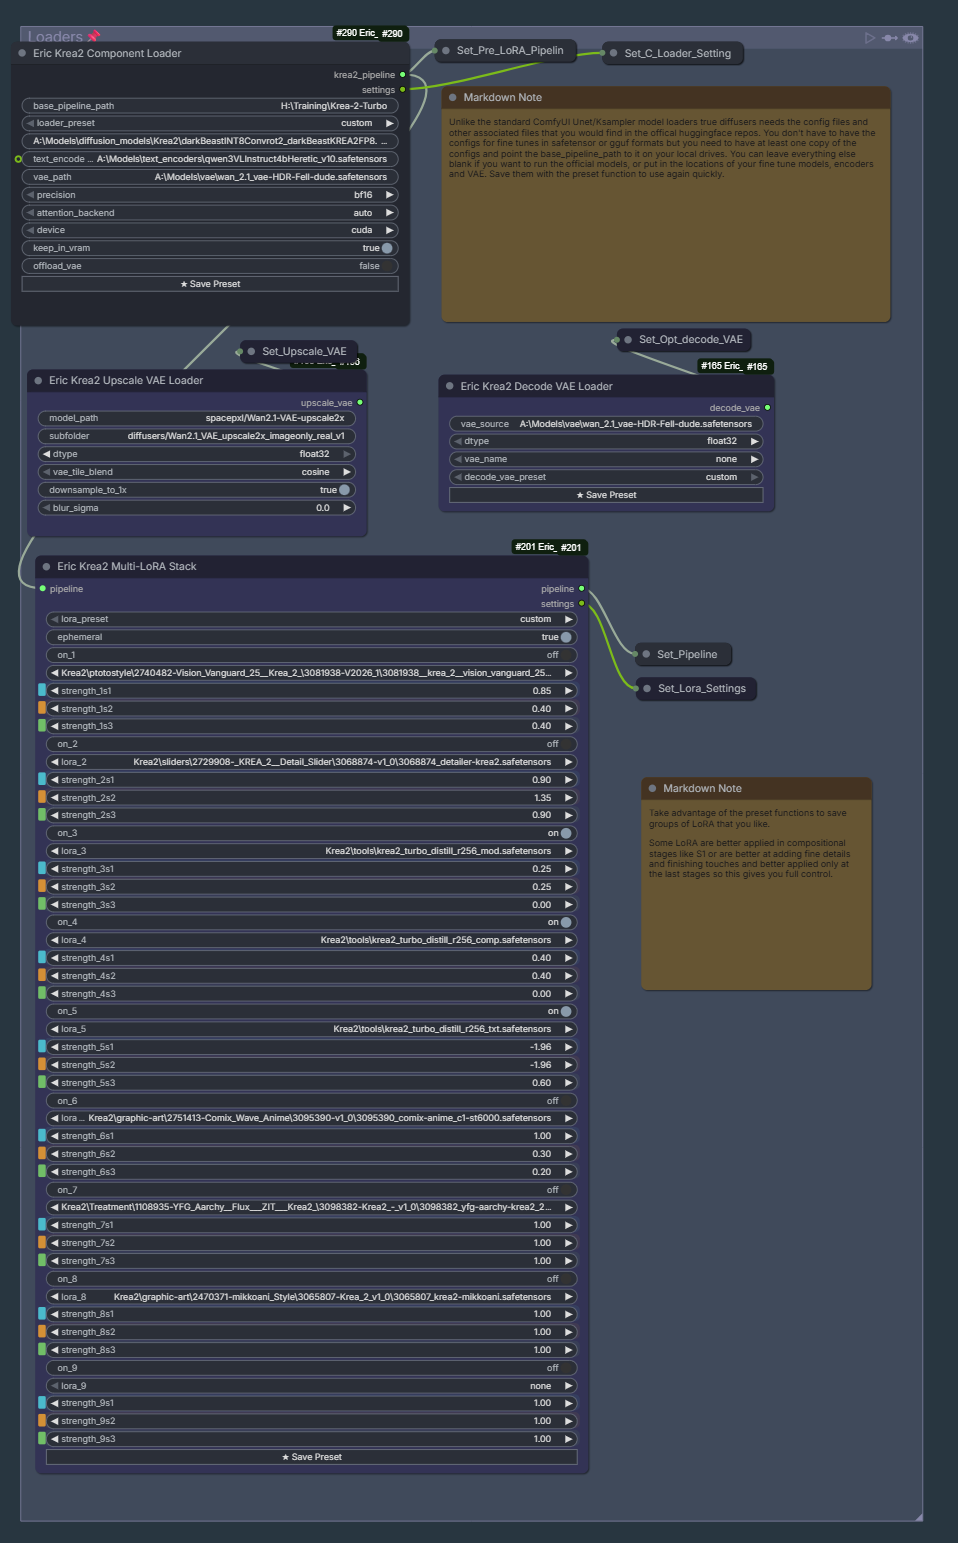
The loader group - the Component Loader (with loader_preset), the Upscale and Decode VAE loaders, and the growable Multi-LoRA Stack with per-stage strengths. Each carries its own ★ Save Preset button.
| Node | Does |
|---|---|
| Eric Krea2 Sigmas | Per-stage schedule overrides (S1/S2/S3): curve, detail_bias, Beta α/β. Emits a KREA2_SIGMAS bundle the Ultra nodes fold in. |
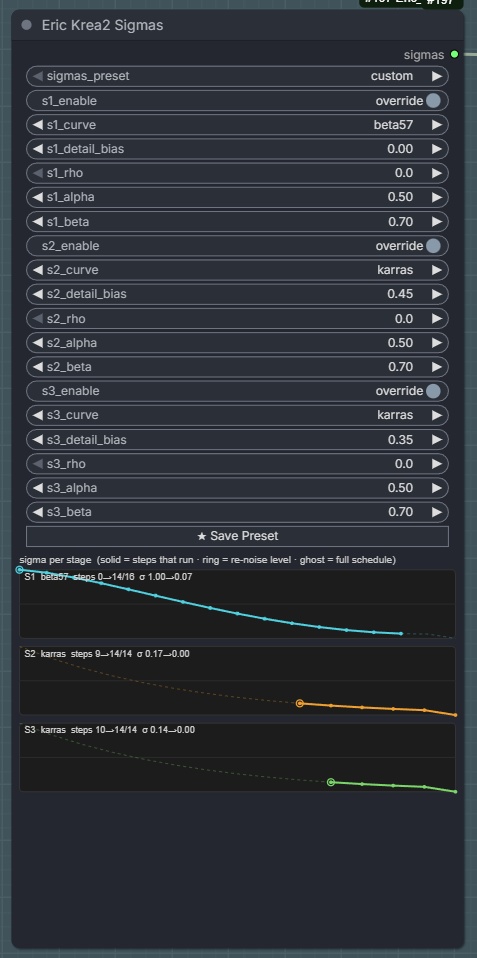
The Sigmas node: per-stage curve / detail_bias / Beta α-β overrides with a live sigma preview per stage (solid = steps that run, ring = re-noise level, ghost = full schedule).
Samplers (per stage, on the Ultra node): euler, res_2m, res_2s, deis_3m,
abnorsett_3m, abnorsett_4m, lawson4_4s, etdrk4_4s, er_sde,
rk6_7s, lcm, lcm_hybrid, lcm_hybrid2.
Schedules: linear, balanced, karras, beta57, beta,
bong_tangent, exponential, linear_quadratic, simple
(= ComfyUI's uniform-in-sigma scheduler; alias of linear here).
See Samplers & schedules.
KREA2_SWEEP plan (grid axes or
JSON-lines combos, stage scoping, quick-screen mode, output folder, hard
combo cap). Wire into Ultra V2's sweep input.ultra_presets.json, tagged with the checkpoint name.
See Parameter sweeps.| Node | Does |
|---|---|
| Eric Krea2 VAE Encode | Encodes an IMAGE → KREA2_LATENT (the img2img primitive). |
| Eric Krea2 Reference Latents (Edit) | VAE-encodes 1-3 reference images → KREA2_REF_LATENTS for the Ultra (res) node's ref_latents input (ai-toolkit "index_timestep_zero" edit method). Needs an edit-trained LoRA - without one the base model does not ignore the reference tokens, they corrupt the image into a blocky mosaic. See Reference Latents. |
| Eric Krea2 Resolution | Size from aspect_ratio + megapixels or a source image → width/height/dims + a blank KREA2_LATENT (noise or zeros). |
| Eric Krea2 Latent Resize | Resize a KREA2_LATENT in latent space (bislerp, no VAE round-trip): scale / dimensions / megapixels. |
| Eric Krea2 Latent → ComfyUI LATENT | Bridge a KREA2_LATENT to a stock ComfyUI LATENT. |
Each builds a bundle for one socket on Multi-Stage Ultra (all sockets were appended - saved workflows are untouched). Nothing loads or runs in these nodes; Ultra installs the runtime for one generation and removes it afterwards (cancel-safe).
| Node | Ultra socket | Does |
|---|---|---|
| Eric Krea2 Control (Depth/Pose ControlNet-LoRA) | control | Control image + Control-LoRA checkpoint + per-stage strengths (S1 1.0 / S2 0.5 / S3 0). See Control. |
| Eric Krea2 Style Reference (training-free) | style | Style image + recommended / custom preset + per-stage multipliers (S1 only by default). See Style Reference. |
| Eric Krea2 Paint (inpaint / outpaint) | paint | Source + mask and/or outpaint padding, adapter (anypaint / outpaint / none), per-stage restore + adapter switches. Outputs the bundle, a vlm_image for Vision Prompt, a canvas preview and the generated mask. See Inpaint / outpaint. |
| Eric Krea2 Paint Composite | - | Optional pixel-exact paste-back of the source outside the mask with a feathered edge. |
| Eric Krea2 Edit | edit | Source image (+ optional second reference), edit instruction, fit_mode, ref_boost / ref_boost_a (+ mask), grounding_px, size_from, ground_negative. See Edits. |
| Eric Krea2 Negative Guidance | guidance | NAG (own negative text, phi / tau / alpha, stages, sigma window) and NegPiP (mode, strength, block range, text-fusion option). See Negative guidance. |
Which sockets combine (one run):
| control | style | paint | edit | guidance | ref_latents | |
|---|---|---|---|---|---|---|
| control | - | yes | yes | yes | yes | yes* |
| style | yes | - | no | no | skipped | no |
| paint | yes | no | - | no | skipped | no |
| edit | yes | no | no | - | yes | no |
| guidance | yes | skipped | skipped | yes | - | skipped |
| ref_latents | yes* | no | no | no | skipped | - |
"no" raises a clear error (both wrap the transformer forward); "skipped" runs the other one and prints that guidance was ignored.
Control with edit or ref_latents: the control hint is applied to the target image tokens only; reference tokens bypass the Control-LoRA (before 2026-10-08 control was silently dropped whenever reference tokens were present). *control + ref_latents is verified to apply control on every step; a full visual run with the edit LoRA at 1.5 MP spilled VRAM on a 48 GB card shared with displays, so try 1 MP first.
| Node | Does |
|---|---|
| Eric Krea2 Upscale VAE Loader | Loads the spacepxl Wan 2× upscale decoder → UPSCALE_VAE. Optional downsample_to_1x + blur_sigma: decode at 2× then Lanczos-downsample back to native size - a supersampling-style quality pass instead of a literal resolution gain. Travels with the loaded VAE into every consumer (see Upscale VAE: modes & precedence). |
| Eric Krea2 Decode VAE Loader | Loads a plain decode VAE. |
| Eric Krea2 Upscale Decode (2×) | Decodes a KREA2_LATENT via the upscale VAE (no re-denoise). Resolution and any downsample/blur are whatever the loaded UPSCALE_VAE was configured with. |
| Eric Krea2 VAE Decode | Plain 1× decode of a KREA2_LATENT. |
| Eric Krea2 DeGrid (VAE grid remover) | Removes the VAE's 2-pixel lattice from any image (auto-calibrated notch, untouched when clean) + removed-grid preview and report. Both decode nodes also gained a degrid toggle. See DeGrid. |
| Node | Does |
|---|---|
| Eric Krea2 Merge Settings | Merges section recipe strings into one KREA2_SETTINGS (dicts updated, lora lists concatenated). |
| Eric Krea2 Settings from Image | Reads an image's embedded generation settings back into a KREA2_SETTINGS recipe. |
| Eric Krea2 Component Loader | Loads pipeline components (base folder + optional single-file transformer / VAE / text encoder) with a preset dropdown. Reads bf16, GGUF, fp8, INT8, INT8-ConvRot, MXFP8, NVFP4, ConvRot-W4A4, W4A8, W6A8 (formats); compute = bf16 or native quantized kernels (native compute); VAE tiling controls. |
| Eric Krea2 Apply LoRA / Unload LoRA / Diagnose LoRA | Apply, cleanly remove, and inspect LoRA adapters on the cached pipeline. Apply LoRA supports per-stage weights (per_stage_weights + weight_s1/weight_s2/weight_s3) so a LoRA's strength can differ across S1/S2/S3 in a multi-stage run, plus a preset dropdown (apply_lora_preset + ★ Save). |
| Eric Krea2 Multi-LoRA Stack | Stack several LoRAs in one growable node - each slot has per-stage weights (strength_Ns1/s2/s3 for S1/S2/S3) and an on/off toggle, plus a shared ephemeral switch and a preset dropdown (lora_preset + ★ Save). Unused rows auto-hide until needed. Click the middle of a LoRA dropdown for the 🔍 search popup (also on Apply / Diagnose LoRA); optional suggestions socket for the LoRA Suggester. |
| Eric Krea2 Unload Models | Free VRAM on demand. |
| Eric Krea2 Save Latent (debug) | Save/inspect a packed latent for debugging. |
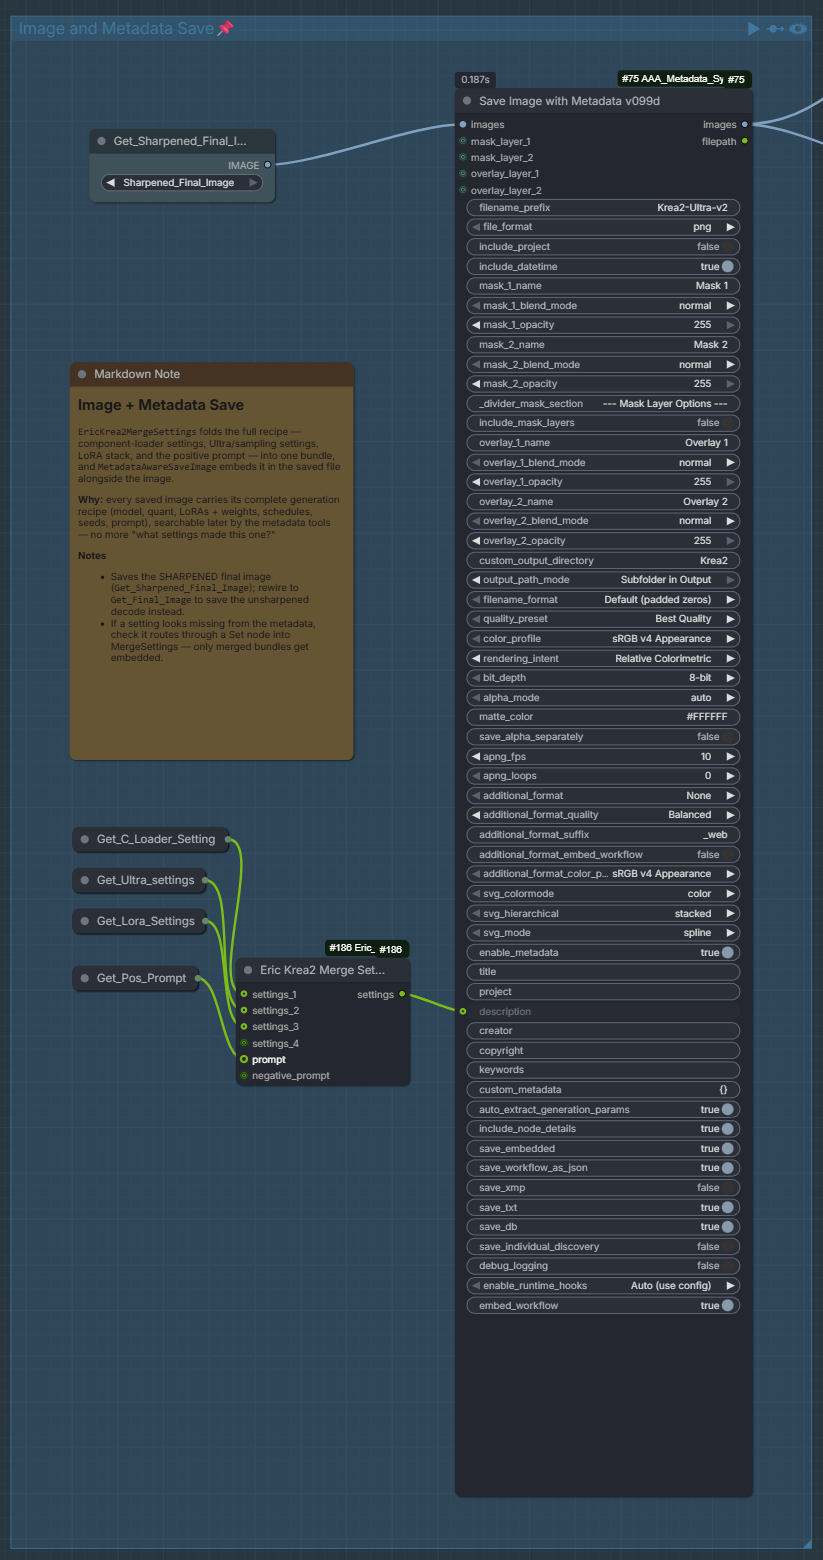
Reproducibility: Merge Settings folds the loader + Ultra + LoRA + prompt recipes into one bundle that gets embedded in the saved PNG - readable back later via Settings from Image.
| Node | Does |
|---|---|
| Eric Krea2 Prompt | Assembles structured fields into a dense, comma-joined natural-language prompt; quotes text-to-render. |
| Eric Krea2 Magic Prompt | Expands a short prompt via a local LLM (LM Studio / Ollama / any OpenAI-compatible endpoint). |
| Eric Krea2 Vision Prompt | Grounds conditioning in 1-3 reference images via Krea2's own Qwen3-VL vision path, using Krea2's trained descriptor template (not the generic Qwen-Image-Edit template). Emits KREA2_CONDITIONING → Ultra's prompt_conditioning input. See Vision Prompt below. |
Each stage of the Multi-Stage Ultra node picks a sampler (the ODE solver) and a schedule (the sigma spacing) independently.
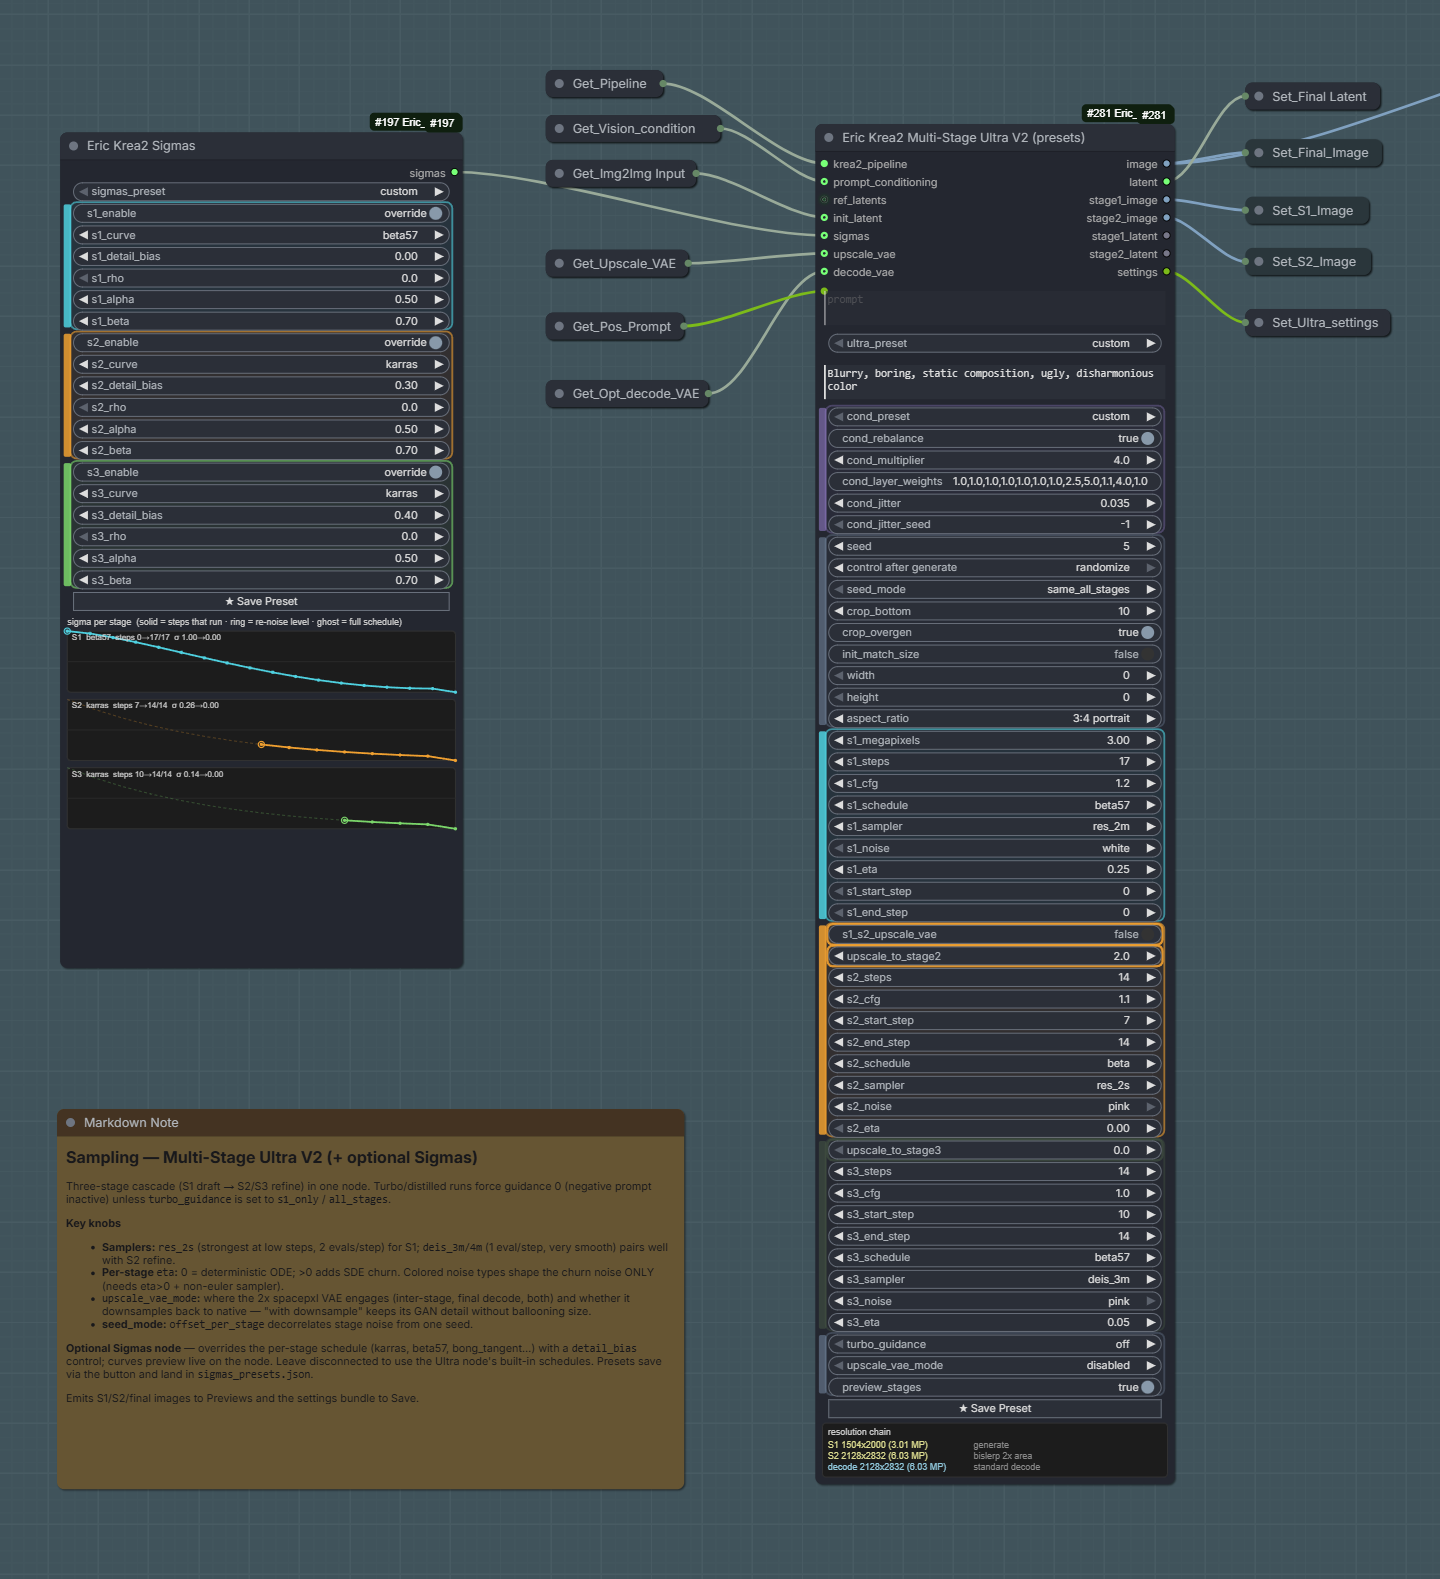
A full sampling group - the Sigmas node feeding Multi-Stage Ultra V2, with per-stage samplers/schedules, guidance, re-noise windows, and the on-node resolution-chain readout.
Samplers
| Sampler | Order | Model calls / step | Best for |
|---|---|---|---|
euler | 1 | 1 | Baseline / native parity (the comfy euler+simple twin). Honours early stop and eta (runs as a 1-stage RK). |
res_2m | 2 (multistep) | 1 | General use - sharper than Euler at the same cost. |
res_2s | 2 (single-step) | 2 | Low step counts / Stage-1 draft. Self-starting; ~2× slower. |
deis_3m | 3 (multistep) | 1 | Smooth refine passes. |
deis_4m | 4 (multistep) | 1 | Smoothest refine at higher step counts. |
rk6_7s | ~6 (7-stage RK) | 7 | Maximum solver accuracy (finetuner recipes; the Raw model). ~7x cost per step - overkill for Turbo daily use. |
abnorsett_4m | 4 (exp. multistep) | 1 | Recipe-name alias of deis_4m - identical update in this solver formulation. |
lcm | ancestral | 1 | Post-upscale refine windows: jumps to x0 and fully re-noises every step, laundering upscale artifacts. Not for Stage 1. |
Every sampler honours a noisy early-stop (end_step < steps), letting a stage
hand a partially-denoised latent to the next, and supports the ancestral eta
SDE path (lcm is inherently fully ancestral - see below). Since the 2026-07-22
shift-consistency fix, euler runs through the same solver path as every other
sampler (as a 1-stage Runge-Kutta), so the re-noise level and the stepping always
share one sigma space. The math is recreated from the RES (arXiv:2308.02157) and
DEIS (arXiv:2204.13902) papers plus standard Butcher tableaus - no external
solver code is imported.
Schedules: linear, balanced, karras, beta57, beta, bong_tangent,
linear_quadratic (ComfyUI-core slow-linear-then-quadratic descent; the kreamania pass-1 schedule),
exponential. The Sigmas node adds a detail_bias knob (biases sigma spacing
toward fine detail vs. large structure) and Beta α/β shaping.
Recommended pairings (per the RES4LYF community):
res_2s + beta57.deis_3m or deis_4m + bong_tangent.lcm + linear with a deep window - see below.Native parity note: linear + distilled_shift=fixed reproduces ComfyUI's
euler/simple spacing exactly (same uniform grid, same exponential mu=1.15
shift) - that pairing IS the native baseline, not an approximation of it.
Two independent properties decide which solver fits a stage. They often point in opposite directions, so it's worth understanding both rather than just copying the pairings above.
1. Multistep warmup (order build-up). Multistep solvers (res_2m, deis_3m,
deis_4m) reach their rated order by fitting a polynomial through past steps, so
they start low-order and ramp up:
| Step in the run | deis_3m effective order |
|---|---|
| 1st | 1 (Euler-like) |
| 2nd | 2 |
| 3rd onward | 3 (full) |
Crucially, each stage restarts the solver - the history buffer is empty at the
stage boundary and does not carry across the re-noise handoff. So the ramp is
measured from the first step of that stage's run, not the global step index. A
Stage-3 run of steps=14, start=7, end=14 is 7 sampling steps, of which the
first ~2 are below full order (full 3rd order from its 3rd step ≈ global step 9).
deis_4m ramps over ~3 steps and needs even more runway. Sub-order steps aren't
"wrong" - they're just Euler/2nd-order accurate - but at low step counts the warmup
eats most of the run and the higher order never pays off.
res_2s is self-starting (a self-contained predictor+corrector, 2 model calls
per step) - full order from step 1, no warmup - which is why it wins when steps are
scarce. Cost balances out because you use fewer of them: res_2s @ 4 steps = 8
calls ≈ deis_3m @ 7 steps = 7 calls, but cleaner at the low count.
2. Trajectory smoothness (from-noise vs from-clean). This is why Stage 1 uses a single-step solver even though it has plenty of steps to amortize warmup:
res_2s doesn't rely on history, so it's robust
on that rough start, and its corrector buys accuracy on the most consequential
steps of the whole pipeline.deis_3m's cheap high-order
extrapolation genuinely shines.Putting it together:
| Stage | Trajectory | Steps | Pick | Why |
|---|---|---|---|---|
| S1 draft | from noise | long | res_2s | robustness on the rough start > cheap order |
| S1 draft (cost-saving) | from noise | long | res_2m | multistep middle ground: 1 call/step, some early robustness given up |
| S2/S3 refine | from clean | long (≥~8-10) | deis_3m | smooth trajectory + cheap order; warmup amortized |
| S2/S3 refine | from clean | very long, smooth schedule | deis_4m | marginal extra accuracy once there's runway |
| S3 light refine / no upscale | from clean | few | res_2s | self-starting - no warmup waste when steps are scarce |
Rules of thumb: from noise → self-starting (res_2s); from clean + many steps
→ multistep (deis_3m/4m); from clean + few steps → back to res_2s (no
warmup to waste). deis_4m only over deis_3m on long, smooth, high-step runs; it's
more prone to overshoot on short or noisy-early-stop stages.
lcm fitsEvery sampler answers the same question - "given where the latent is and how noisy it should be, where does it go next?" - and they split into two philosophies.
The ODE family (euler, res_2m, res_2s, deis_*, rk6_7s) treats
denoising as following a trajectory. Each step nudges the current latent along
the flow, so information accumulates: real structure, but also upscale ridges,
interpolation error, and leftover mottling get carried forward, refined, and
sharpened into the output. The members differ only in how accurately they follow
the path (euler crudely, rk6_7s obsessively). Faithful is their virtue and their
flaw: they preserve everything, including what you wish they would not.
lcm is the other philosophy. Each step asks the model for its best guess of
the finished image (the x0 prediction), then throws the current latent away and
rebuilds the next one as that guess plus fresh noise at the next sigma (the
flow-matching mix (1 - sigma) * x0 + sigma * noise). No trajectory, no memory:
whatever damage the latent carried - contour lines from a latent upscale, seam
echo, mismatch residue - is discarded every step and replaced by the model's own
clean prior plus new noise. That is why it launders artifacts that deterministic
ODE samplers faithfully integrate. The price is symmetric: it also discards fine
detail the trajectory was carrying, drifts more from the init, and shows larger
seed-to-seed variety.
The choice rule: damaged starting latent you want repaired -> lcm. Precious
starting latent you want preserved -> an ODE sampler. In between - trajectory with
some laundering - is exactly what eta > 0 on the res/deis samplers is.
Concretely: post-upscale refine windows are lcm home turf (the latent just got stretched and is full of interpolation artifacts - the entire secret of the native euler -> lcm two-pass chains). Stage 1 is ODE territory: you are building structure from noise and want it followed faithfully, and Turbo is TDM-distilled, not LCM-distilled, so full-ancestral from pure noise reads rough and unstable. A same-resolution polish on an already-good image is a judgment call: shallow lcm freshens texture and kills residue; shallow deis/res preserves likeness.
What shapes lcm's churn (it consumes fresh noise every step, so it is the sampler most sensitive to what that noise is):
start_step/end_step): how much of the image gets rebuilt.
Deeper start = more repair, more drift.detail_bias (Sigmas node): where the re-noise ladder
concentrates. Positive bias packs churn events at low sigma (texture polish);
negative packs them high (structural repair).distilled_shift / mu: moves the whole ladder (higher mu = more time spent
churning at high sigma = smoother, deeper repaint).noise_type and eta: lcm-family re-noise draws are ALWAYS plain seeded
white - the model was trained on white noise at every sigma, and a FULL
replacement with colored noise is out-of-distribution (it decodes as
chromatic blotches over the image). noise_type shaping applies only to the
fractional SDE churn of the res/deis/rk samplers at eta > 0. For
colored-noise grain character, use deis_3m/res_2m with eta 0.5-1.0 and a
noise_type - not lcm.seed_mode): lcm windows show more seed variety than the
deterministic solvers - that is the churn, not a defect.Recommended lcm refine baseline (the native-parity chain):
lcm + linear,
distilled_shift=fixed, eta 0, white noise; upscale_to_stage2 ~1.2 (area),
S1->S2 VAE upscale OFF (plain latent hop).upscale_to_stage3 ~1.5.detail_bias +0.2..+0.3.hybrid_splitPure lcm's weakness is that its final detail is bounded by the x0 prediction
at the entry (highest-sigma) steps: the first full re-noise discards the
incoming trajectory - including the previous stage's real detail - and later
steps only polish that re-invention. The hybrids keep lcm's artifact
laundering where it works (the entry steps, where upscale damage lives) and
then develop detail trajectory-faithfully at low sigma, where detail is
actually made:
lcm_hybrid - lcm churn, then a deis_3m tail.lcm_hybrid2 - lcm churn, then a res_2m tail (added 2026-07-25;
res_2m has been testing better than deis_3m as the detail-development half
on several fine tunes - both tails cost the same per step).s1/s2/s3_hybrid_steps (Ultra widgets, default 0) - the handoff in
EXACT lcm steps at the head of that stage's window. 0 = auto (half the
window, ceil - the original behavior). At low step counts this is the
honest control: a fraction only has window-1 real values, so small %
changes were silent no-ops. Fewer lcm steps = more trajectory-faithful
detail; more = more laundering. Clamped so both halves always run; ignored
by every other sampler. Sweepable via the hybrid_steps axis or combos
JSON ({"s2_hybrid_steps": 4}).eta/noise_type apply to the tail half only; the lcm half is inherently
fully ancestral and always re-noises with plain seeded white (colored
noise as a full replacement is out-of-distribution -> rainbow blotches).eta contract: honoured by res_2m/res_2s/deis_3m/abnorsett_3m/
abnorsett_4m/lawson4_4s/etdrk4_4s/rk6_7s and the hybrid tails;
ignored by euler and lcm (euler is the deterministic baseline -
enforced in the dispatch, and the Sweep Plan automatically drops cells
that differ only by inert eta/noise on those samplers).The Norsett & exponential-RK additions (2026-07-27): abnorsett_4m is
no longer a deis alias - it is the genuine fixed-coefficient Norsett
exponential Adams-Bashforth method (RES4LYF-faithful, verified against its
phi tables), with abnorsett_3m as its 3rd-order sibling; the weights
depend only on the current step size, so they stay BOUNDED on every
schedule. deis_4m was removed: its exact variable-step weights blow up on
strongly non-uniform ladders (measured 269x on linear_quadratic) and
amplify model-prediction noise into garbage - if a saved workflow used it,
pick abnorsett_4m (stable order 4, same 1 call/step) or deis_3m.
lawson4_4s and etdrk4_4s are single-step exponential RK order 4
(4 model calls/step, no history): the most noise-robust solvers in the
package, stable everywhere, strong candidates for refine windows. Note
lawson is deliberately not phi-exact for constant forcing (classical
Lawson quadrature) - a texture character difference from etdrk4, not a bug.
Numbers = median deviation of the final state when the model's per-step predictions disagree by 2% (the solver's amplification of prediction noise; lower = more stable). Stability is necessary, not sufficient - which stable pair looks BEST for a given fine tune is what the sweep decides.
| sampler | best schedules | fine | avoid |
|---|---|---|---|
euler, res_2s | any (0.017-0.029) | - | - |
lawson4_4s, etdrk4_4s | any (0.009-0.022, noise-suppressing) | - | - |
res_2m | exponential/beta/beta57/karras (0.020-0.022) | linear (0.053) | linear_quadratic (0.152) |
deis_3m | exponential/beta57/beta/karras (0.022-0.025), OPT-DEIS12 ★ (karras +0.75 bias, 0.023) | bong_tangent/balanced (~0.03), linear (0.118) | linear_quadratic (0.834) |
abnorsett_3m | beta57/beta (0.021), exponential/karras (0.022-0.025) | linear (0.060), linear_quadratic (0.115) | - |
abnorsett_4m | beta57/beta (0.022), OPT-AB412 ★ (beta57 +0.5 bias) | exponential/karras (~0.03), linear_quadratic (0.178) | - |
er_sde | ANY - 0.048 flat on every schedule incl. linear_quadratic (stochastic contraction; schedule-proof at 1 eval/step). Community recipe: + simple @ 8 steps | - | - |
lcm_hybrid/2 | beta57/beta/karras/exponential (0.023-0.028) + the EXP ★ family | bong_tangent (~0.026) | linear (0.055-0.116), linear_quadratic (~0.15) |
Detail-bias windows (how far you can push detail_bias before conditioning
degrades, per curve): deis_3m stays clean on exponential to +0.25, on
beta57/beta from -0.75 to +0.5, and on karras it IMPROVES with positive bias
(clean -0.25 to +0.75 - positive bias straightens the karras tail in
t = -log sigma, which is why OPT-DEIS12 = karras +0.75 is both the most
detail-holding and among the most stable deis_3m curves). abnorsett_4m:
beta57/beta clean -0.75..+0.5; exponential to 0; karras never fully clean.
Single-step order-4 samplers ignore conditioning entirely - schedule choice
is pure aesthetics there. OPT-DEIS12 and OPT-AB412 ship as ★ sigma
presets (S1-only, 12-step recipes).
Field-tested Stage-1 recipe (2026-07-26, found with the sweep system):
12 total S1 steps with either hybrid (lcm_hybrid / lcm_hybrid2) over an
exponential-family custom sigma curve (authored in the Eric Krea2 Sigmas
node and saved as ★ presets - e.g. the EXP1-EXP4 set) lands among the
fastest runs while holding up across most fine tunes and curves. The
handoff sweet spot is s1_hybrid_steps = 7 of 12 for most model/curve
combinations. Treat it as a development control: 5-6 lcm steps hands
off earlier and develops more fine detail; 8 (sometimes 9) launders
longer for a cleaner, less-detailed look. The recipe re-derives itself per
fine tune in one sweep: samplers lcm_hybrid, lcm_hybrid2 x
hybrid_steps 5, 6, 7, 8 x your saved curves in sigma_profiles.
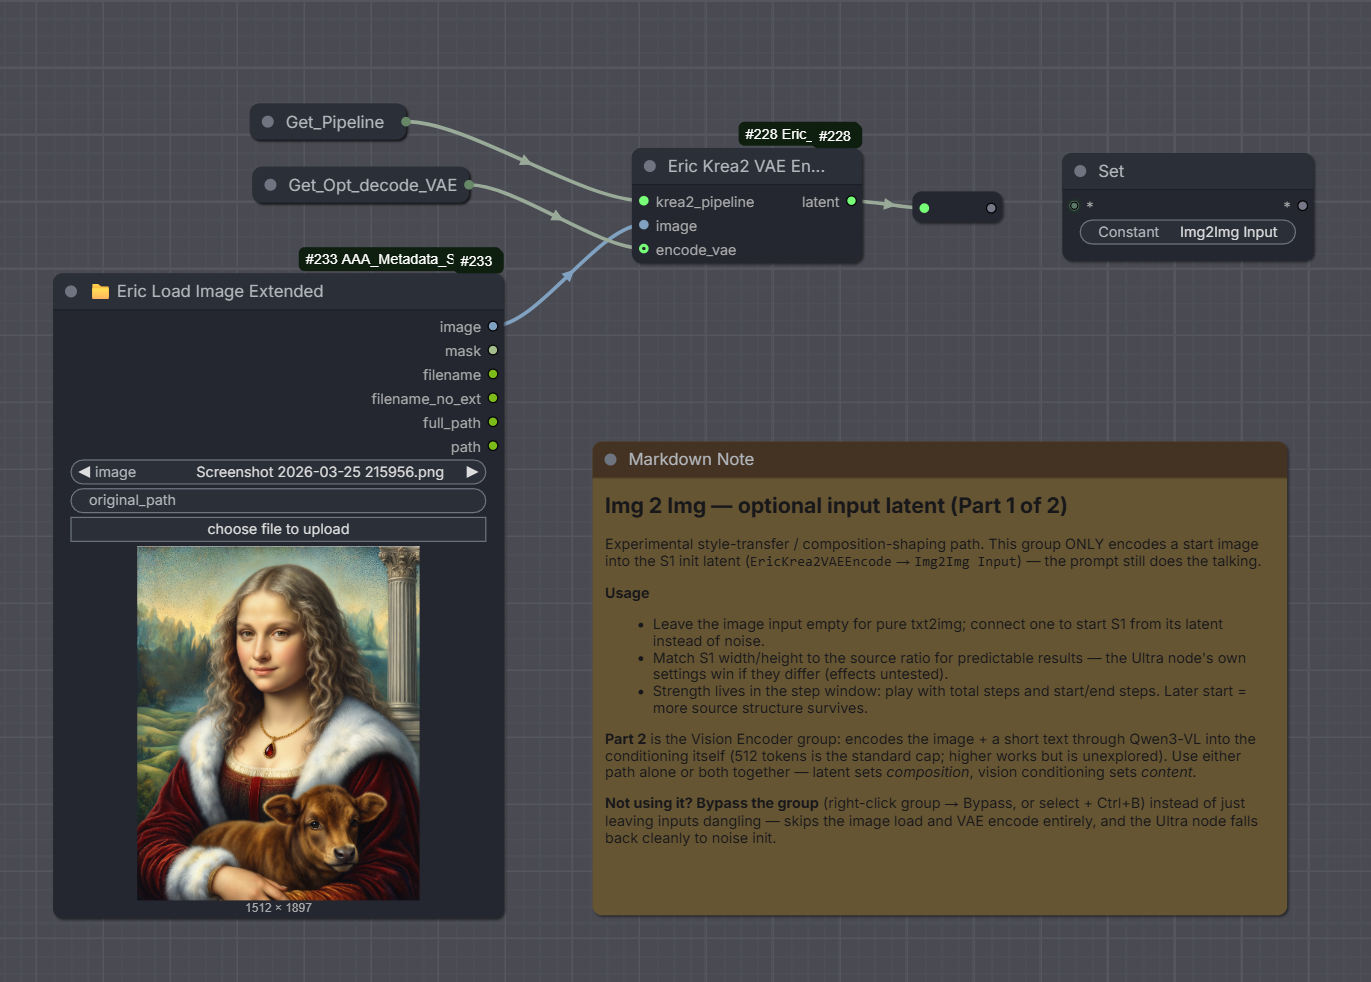
img2img (Part 1): a start image is VAE-encoded into the S1 init_latent. Denoise strength lives in the step window; the prompt still does the talking. Bypass the group for pure txt2img.
Load Image → Eric Krea2 VAE Encode → (init_latent) Multi-Stage Ultra
                     └→ Eric Krea2 Resolution (image) → width/height → Multi-Stage Ultra
Stage 1 re-noises the init_latent at s1_start_step and denoises the
[s1_start_step, s1_end_step] window - so denoise strength is the step window,
not a separate float. Feed width/height from the Resolution node (or turn on
init_match_size) to size Stage 1 to the source image.
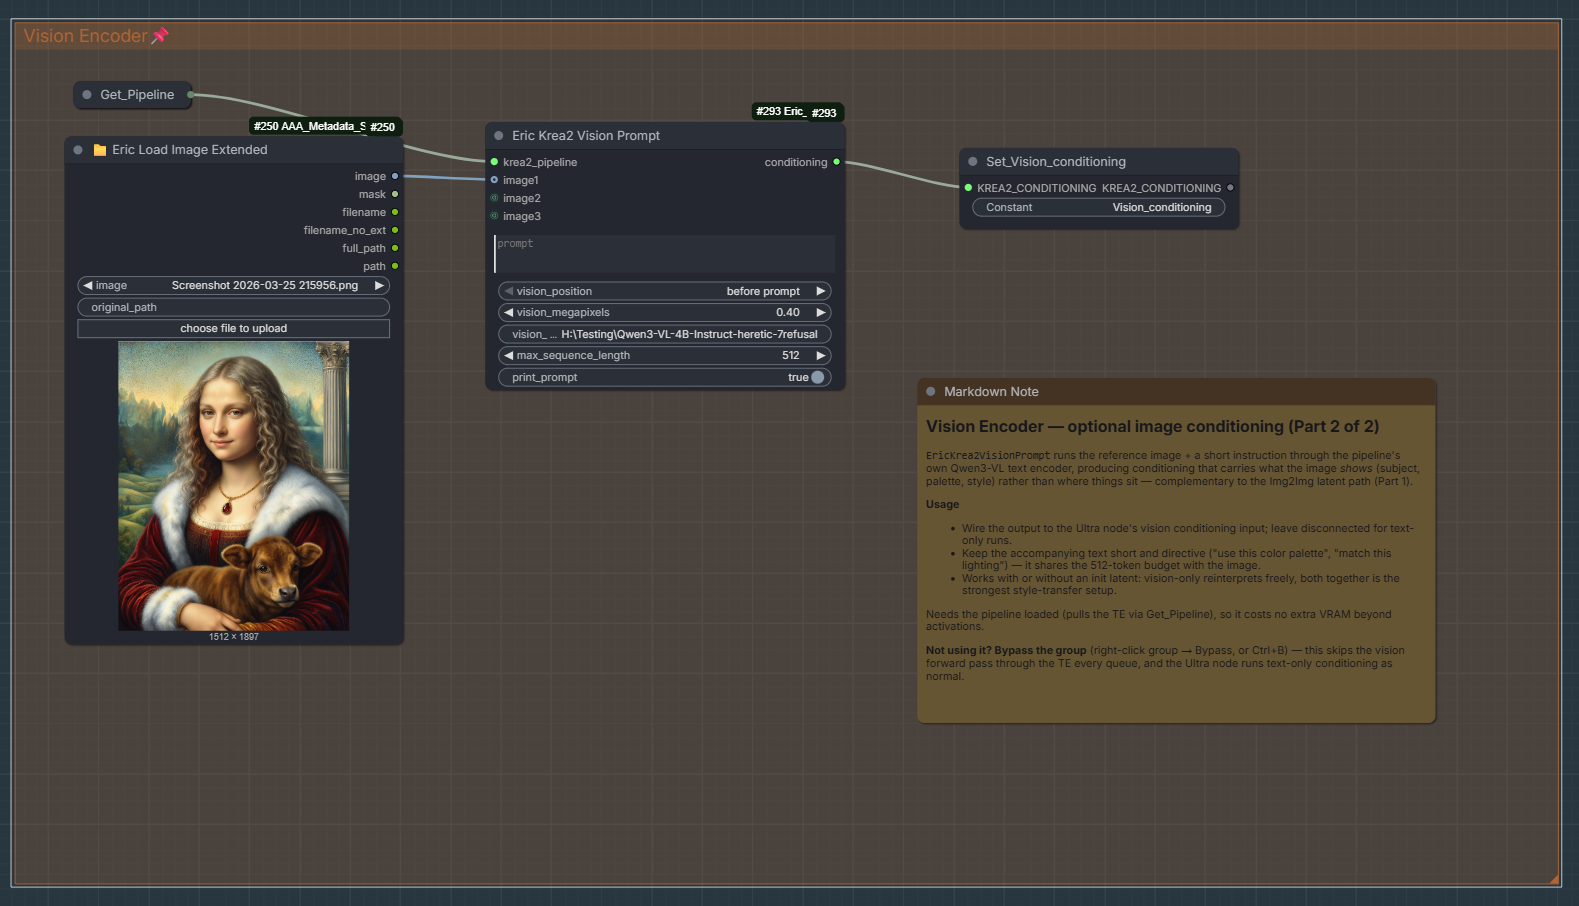
Vision Prompt (Part 2): a reference image + a short instruction run through Krea2's own Qwen3-VL vision path → KREA2_CONDITIONING. Sets content/style; pairs with img2img for structure.
Load Image(s) -> Eric Krea2 Vision Prompt -> (prompt_conditioning) Multi-Stage Ultra
Pushes 1-3 reference images through Krea2's own text encoder's vision path (it's a
Qwen3-VL VLM, not text-only), so the resulting conditioning is visually grounded by
those images - a "prompt from a picture" effect - without training anything and
without the pitfalls of the community pattern of reusing the core
TextEncodeQwenImageEditPlus node for this: that node's VAE-encoded reference goes
nowhere (the base Krea2 DiT has no reference-latent pathway - Krea2.extra_conds
never reads reference_latents, so it's silently discarded; an edit-trained LoRA is what
adds one, exposed separately via the
Reference Latents node), and it falls
back to Qwen3-VL's generic image-description template once an image is attached instead of the
descriptor template Krea2 was actually conditioned with. This node has no VAE step at
all (nothing to discard) and always uses Krea2's own prompt_template_encode_prefix/
_suffix, read straight off the loaded pipeline so it can't drift out of sync.
This is semantic grounding, not pixel editing. With no reference-latent pathway of its own it gives no structure/identity preservation from the image alone - for that, pair it with img2img (below): img2img supplies structure (what to start denoising from), Vision Prompt supplies content (what to draw toward). They're independent channels into the transformer and compose freely, including with different source images for each. (If you have an edit-trained LoRA, the Reference Latents node adds a third, pixel-level channel.)
Positive-conditioning only. Steering toward a reference makes sense; steering
away from one is a much stranger ask, and Turbo (the primary target) mostly runs
cfg=0 anyway - no negative pass to feed. When prompt_conditioning is connected,
Ultra's own prompt field is entirely inert (not used, not logged) - put your text in
the Vision Prompt node's own prompt field instead. cond_rebalance still applies to
it, identically to a text-only encode.
Token budget - the one thing to know before your first run. Krea2 was trained
with a fixed 512-token text budget (prefix + images + prompt, always padded/
truncated to exactly this length) - unlike Qwen-Image's dynamic per-batch padding,
which is why Qwen-Image tolerates a much higher max_sequence_length more gracefully.
One full-resolution (1 MP) reference image alone is ~988 tokens - nearly double the
whole budget before your prompt or even the 34-token prefix. To keep this workable
out of the box, the node auto-shares a ~0.40 MP budget across however many images you
connect (1 image ≈ 0.40 MP, 2 ≈ 0.20 MP each, 3 ≈ 0.13 MP each) and raises a clear,
specific error - with a suggested vision_megapixels value - rather than silently
truncating into the image-token block (which corrupts position ids and crashes deep
inside get_rope_index with a cryptic shape-mismatch instead). vision_megapixels is
a ceiling on top of the auto-share, not a replacement for it - lower it to reserve more
room for a long prompt.
Load Image(s) -> Eric Krea2 Reference Latents -> (ref_latents) Multi-Stage Ultra (res)
A second, pixel-level way to condition on a reference image - complementary to Vision Prompt's semantic grounding. Each reference image is VAE-encoded and flow-packed exactly like a generation latent, then its tokens are appended to the image sequence and modulated at t = 0 (clean data) - the ai-toolkit "index_timestep_zero" edit method. The velocity prediction is sliced back to the live image tokens, so the references only inform the denoise, they aren't denoised themselves.
Requires an edit-trained LoRA. The base Krea2 model was never trained to read these
tokens - this pathway only does something useful with an ai-toolkit krea2 edit LoRA
(model_kwargs.edit: true) loaded, e.g. the Civitai Krea 2 Style Reference LoRA.
Without one, the reference tokens are not ignored: the base model reads them as image
content and the output breaks up into a blocky mosaic (tested 2026-10-08, with and without
control). Cost is ~2048 extra tokens per 1 MP ref, per denoise step.
Recommended wiring (matches the Style Reference LoRA's training setup):
max_ref_megapixels 1.0) → ref_latents;vision_megapixels ≈ 0.15) → prompt_conditioning;CFG caveat. The transformer-forward wrapper can't tell a positive pass from a negative
one, so with guidance enabled the references condition both passes and partially cancel
in the CFG delta. Keep it on Turbo at g = 0 (which is what the published edit LoRAs
target anyway). This is an independent diffusers-side reimplementation of the published
mechanism (mechanism credit: ostris / ai-toolkit), not a port.
Two recipes (edit_recipe on the Reference Latents node). ostris_t0 (above) is for
style / reference LoRAs. edit_frame is the identity / instruction edit method - sources
prepended on the target grid at frame 1..N, shared timestep - placed with the krea2edit v1.2
fit geometry (Oct 2026; it previously stretched mismatched aspect ratios) and active on the
stage whose grid it was encoded for. For the Krea 2 Identity Edit LoRA use the dedicated
Edit node instead - it adds the grounded instruction encode,
ref_boost and the trained negative.
Load Image -> (depth / pose / canny preprocessor) -> Eric Krea2 Control -> (control) Multi-Stage Ultra
Krea 2 "ControlNet" checkpoints are Control-LoRAs: the DiT input projection is expanded
from 64 to 128 channels ([noisy patches ; control patches], trained weights in the
checkpoint) plus a rank-64 LoRA on every block. The control image is VAE-encoded and enters
clean at every step. Everything is forward hooks for one generation - nothing is merged
into the weights, so it composes with the LoRA stack and never leaks.
Patil/Krea-2-depth-controlnet (trained on Raw, works on Raw
and Turbo, ~1 MP buckets). Put it in your Krea2 LoRA folder; files with control in the
path are listed first. The checkpoint decides the control type - a depth LoRA needs a
depth map.channel_mode grayscale, normalize per_image_minmax, near = white
(invert if your preprocessor gives near = dark). Pose / canny / lineart: rgb, none.--lora-scale); the
expanded input layer is always full. 0 = that stage runs the stock model. Defaults
S1 1.0 / S2 0.5 / S3 0 - structure is set in S1, S3 runs far above the trained size.Load Image (style) -> Eric Krea2 Style Reference -> (style) Multi-Stage Ultra
Transfers a reference's palette, brushwork, texture and rendering language without a LoRA
(port of nkxx188/ComfyUI-Krea2-StyleTransfer). Every styled step runs the model on
[target, reference]: the reference is noised to the target's level along a model-guided
trajectory, and in blocks 7-27 the target attends to the reference's keys/values with
frequency-band reweighting - early it may align to the reference layout, late it can no
longer copy positions (no content leakage) but still pulls style statistics.
preset - recommended locks the original author's low-leakage tuning (custom
widgets ignored); custom exposes them (ref_k_strength, low_scale_end,
high_scale_start/end, adain_strength, ref_value_mix, value_adain_strength,
beta, blocks, trajectory, gamma).style_strength - overall amount; ~1.0 is strong and coherent at 3 MP; 2.0 can
overshoot. s1/s2/s3_strength multiply it per stage; S2/S3 default 0 (S2 refines S1's
styled result at full speed).trajectory - model_pc (original, ~2 x trajectory_steps extra evaluations per
styled stage) or linear (free, weaker).Load Image (+ mask) -> Eric Krea2 Paint -> (paint) Multi-Stage Ultra -> [Paint Composite]
\-> vlm_image -> Eric Krea2 Vision Prompt (image1, picture_n) -> prompt_conditioning
Implements the yijunwang2 AnyPaint / Outpaint functional adapters on our model:
Settings:
adapter - anypaint (arbitrary masks, inpaint + outpaint, one pass; put
krea2_anypaint_rank32 on the LoRA stack, S1 = 1, S2/S3 = 0), outpaint (older,
rectangular only), none (training-free: only pins the kept region - fine for small
inpaints). Krea 2 Turbo, 8 steps, guidance 0.pad_left/right/top/bottom
add outpaint canvas. seam_px (32) is regenerated around the mask so it blends.restore_s1/s2/s3 - on pins kept regions every step, structure pins while sigma >
structure_release_sigma (0.4) then frees the low-noise detail steps, auto = on when
the source has the stage's resolution else structure, off lets the stage rewrite.
Defaults on / auto / auto keep identity through S2/S3 without forcing upsampled blur.adapter_s1/s2/s3 - adapter conditioning per stage (default S1 only; trained at
<= 1024 px targets).s1_megapixels unless width/height are set;
crop_bottom is disabled for paint runs.Load Image -> Eric Krea2 Edit (instruction) -> (edit) Multi-Stage Ultra
Multi-LoRA Stack: krea2_identity_edit_v1_2 S1 = 1.0, S2 = 0, S3 = 0
Instruction editing - recolor, restyle, re-pose, add / replace / remove objects, outpaint,
try-on, person-into-scene - with the Krea 2 Identity Edit LoRA
(conradlocke/krea2-identity-edit, v1.2; full or the near-identical r128 / r64 files).
Two conditioning paths, exactly as the LoRA was trained:
[text | source (frame 1) | source_b (frame 2) | target (frame 0)], shared timestep;Settings:
fit_mode - fit (v1.2 training geometry: AR-preserving resample onto the target
grid at a fractional centered offset, any output aspect; byte-identical to krea2edit
v1.2.5) or crop (legacy) for v1 / v1.1 weights.ref_boost - reference-fidelity dial: multiplies target -> reference attention
(1 = off; ~4 strong likeness; >10 breaks removals; <1 loosens). Applies to the last
reference (the subject in two-reference edits); ref_boost_a is the scene's dial;
ref_boost_mask limits the boost to a region of the last reference (e.g. a face).
In tests ref_boost 4 kept the source's silhouette closer (a long coat stayed long when
recoloured).grounding_px - longest side the VLM sees (trained 384-768, default 768): lower =
stronger instruction adherence, higher = stronger likeness; lower it if subjects duplicate.size_from - source: Stage 1 takes the source aspect at s1_megapixels (Ultra
width/height still win); ultra settings: Ultra decides and fit handles the mismatch
(wide outpaints).ground_negative - with CFG on, the negative is the empty instruction grounded on
the same image - the trained unconditional.source_image_b - second reference (the subject) for person-into-scene; place two
people in ONE pass rather than chaining edits.Recipe notes (model card + our tests):
prompt text - describe
the edited image there; empty prompt = they reuse the grounded instruction.s1_cfg 2.0 - Krea's g, CFG = 1 + g) with ground_negative on; in our test even that
removed both people for "remove the person in the background". Word removals by what to
keep.crop_bottom is disabled for edit runs; with prompt_conditioning also connected, the
edit's grounded conditioning wins (printed).Eric Krea2 Negative Guidance -> (guidance) Multi-Stage Ultra
Both are off by default, both work at guidance 0 (Turbo), and they can be combined
with each other and with an edit. Ultra's negative_prompt stays the CFG negative.
NAG - Normalized Attention Guidance. A negative text stream (nag_negative) runs
through the blocks next to the positive one. For the image queries the attention output is
pushed away from the negative and renormalised:
z = z+ + phi (z+ - z-), L1 ratio clamped to tau, blended alpha into the positive.
Text and edit-source tokens keep their positive attention.
nag_phi 4.0, nag_tau 2.5, nag_alpha 0.25 (the published defaults),
nag_stages s1 / s1_s2 / all, nag_sigma_start/end limit it to a sigma window.NegPiP. Write (phrase:-1.0) in Ultra's prompt or the Edit instruction: that phrase's
attention values are multiplied by its weight inside the joint blocks, so a negative
weight subtracts the concept instead of adding it.
negpip_mode - in_place (default; the phrase stays where it is, its tokens are flagged -
cleanest in tests) or lifted (the phrase is removed and encoded on its own, appended).negpip_strength multiplies every negative weight; negpip_block_start/end limit the
blocks; negpip_text_fusion also flips inside the text-fusion attention (stronger).prompt_conditioning (Vision Prompt) the text can't be parsed - put the
groups in Ultra's prompt instead. Cost ~0.Using both on the same concept over-suppressed in tests (dark patches) - pick one per concept.
All three features (edit sources + ref_boost, NAG, NegPiP) share one exact attention core: keys are attended group by group and merged by log-sum-exp, so ref_boost needs no dense L x L bias (which would force slow SDPA and run out of memory at 3 MP) and NAG's positive and negative passes share the expensive image attention. Verified against dense reference implementations (docs/tools/test_edit_guidance_math.py).
Component Loader → compute (bf16 default | native) and native_format
(keep | int8 | mxfp8 | nvfp4), both appended.
bf16 dequantizes every checkpoint to bf16 (best image quality). native re-quantizes the
28 joint blocks' 224 Linear layers after loading and runs them on ComfyUI's comfy_kitchen
tensor-core kernels - the same path ComfyUI core uses; everything else stays bf16.
keep uses the checkpoint's own format (INT8 → int8-ConvRot when the file is rotated,
MXFP8, NVFP4, fp8); a bf16 / GGUF source falls back to mxfp8. Explicit int8 / mxfp8 /
nvfp4 quantize any source on load. NVFP4 uses a dynamic per-call activation scale.precision bf16 and a CUDA device.Measured, RTX PRO 5000, Ultra S1-only 3 MP, 8 steps:
checkpoint (keep →) | bf16 s/step / VRAM | native s/step / VRAM |
|---|---|---|
| INT8-ConvRot (int8_convrot) | 2.9 / 34.8 GB | 2.0 / 22.9 GB |
| same + a style LoRA | 3.1 / 35.3 GB | 2.2 / 22.9 GB |
| MXFP8 (mxfp8) | 2.9 / 35.0 GB | 2.1 / 23.3 GB |
| fp8-scaled (fp8) | 2.9 / 35.1 GB | 2.0 / 22.9 GB |
Headless bench (same card): nvfp4 1.75 s/step (1.67x). The gain shrinks at 8 MP, where attention (untouched by quantization) dominates the step.
Single-file transformers are dequantized on load (on the GPU): fp8 (bare / scaled),
INT8 and INT8-ConvRot (group-wise Hadamard un-rotation), and - through
comfy_kitchen's own layouts, mirroring comfy/ops.py - MXFP8, NVFP4,
ConvRot-W4A4, W4A8 and W6A8. GGUF loads as before (dequantize on load).
docs/tools/krea2_checkpoint_inspector.py reports any file's format and whether it loads,
without loading it. Note: a file's name is not proof of its format - one "INT8-ConvRot"
download in testing was actually bf16 (the loader logs what it found).
The Qwen-Image VAE leaves a faint fixed-phase 2-pixel grid in decoded images (strongest in
flat / dark areas), and the spacepxl 2x upscale VAE builds its output with a 2x2
pixel_shuffle. When an inter-stage VAE hop decodes, upsamples and re-encodes, that lattice
is fed into the next stage, which can develop it into a weave-like texture. DeGrid is an
exact 2-pixel notch filter (filter core from lunaaispace-eng/ComfyUI-DeGrid), amplitude-
limited so real edges pass, and an image with no detected lattice is left untouched.
mode auto / manual (limit),
skip_when_clean, and a removed_grid preview (x grid_gain) + report. Put it straight
after a decode, before sharpening / resizing.degrid toggle on Upscale Decode (2x) and VAE Decode (appended).degrid (appended): hops cleans the inter-stage VAE upscale before re-encoding
(no effect on plain latent hops - they have no pixel step), final cleans the decoded
output, hops+final both. The console prints the measured grid amplitude per pass.ERIC_LORA_CATALOG, else video_prompter's config,
else L:/Models/loras/_lora_catalog.sqlite; a missing catalog just means fewer fields.suggestions socket on the Multi-LoRA Stack - LoRAs picked by the LoRA Suggester
(video_prompter) are added after the panel's own slots with their per-stage weights and
trigger words; a file already in the stack is not added twice.Krea 2's two checkpoints suit two different paths:
Turbo → fast 4k (no re-denoise). Turbo is distilled (8 steps, guidance 0) and resists partial re-denoise, but the 2× decode sidesteps that entirely:
Loader (Krea-2-Turbo) → Generate (2048², auto) → [Upscale VAE Loader] → Upscale Decode 2× → 4096²
Raw → controlled high-res (multi-stage). Raw keeps the full-CFG, resolution-aware trajectory that partial re-denoise needs:
Loader (Krea-2-Raw) → Multi-Stage Ultra (1024² → 2× → 2×) → 4k image (+ optional Upscale Decode 2× → 8k-class)
On the Multi-Stage Ultra node, upscale_vae_mode (requires upscale_vae connected)
governs the S2→S3 jump and the final decode. Each transition can be a plain
2× VAE step (real resolution gain, 4× area) or a downsample variant that keeps the
upscale decoder's sharp/GAN-trained detail but resamples down to your chosen size:
| Mode | S2→S3 | Final image |
|---|---|---|
disabled | bislerp latent resize | decode_vae (or the base Qwen VAE if none connected) |
s2-s3 | upscale VAE 2× (4× area; ignores upscale_to_stage3) | decode_vae / base |
s2-s3 with downsample | upscale VAE 2× → downsample to upscale_to_stage3 | decode_vae / base |
final decode | bislerp latent resize | upscale VAE 2× |
final decode with downsample | bislerp latent resize | upscale VAE 2× → downsample to native |
both | upscale VAE 2× (4× area) | upscale VAE 2× |
both with downsample | upscale VAE 2× → downsample | upscale VAE 2× → downsample to native |
both with final decode downsample | upscale VAE 2× (4× area) | upscale VAE 2× → downsample to native |
Recommended: prefer the
… with downsamplevariants. In practice the upscale VAE decoded at 2× then resampled down is cleaner and sharper than the Wan 2.1 VAE at the same output size - you get its detail without the literal 4× area blow-up (and without the re-encode softening compounding across stages). The plains2-s3/bothmodes force 4× area and ignoreupscale_to_stage3, which is the usual cause of a run ballooning to 20 MP+; the downsample variants respect your numeric factor instead.
The old inter_stage / final_decode values still load (aliased to s2-s3 /
final decode) so existing graphs keep working.
S1→S2 has its own switch. s1_s2_upscale_vae (a separate boolean) routes the
first jump through the upscale VAE and forces 2× (4× area), overriding
upscale_to_stage2. It's deliberately not in the dropdown - using the VAE that early is
a specialist move (the re-encode softening gets refined away by S2/S3). Combining it
with a both … mode is what cascades to enormous final sizes - watch the on-node
resolution chain readout, which shows the real S1→S2→S3→decode sizes and flags every
field the VAE is overriding.
decode_vae is ignored outright for the final image whenever the mode does a VAE
final decode (final decode* or both*) - not blended, not overridden, simply not
passed to that call at all. It still governs the stage preview images
(preview_stages=True → stage1_image/stage2_image) regardless of what the final
image uses, since previews always go through standard_decode(..., decode_vae=decode_vae)
independent of upscale_vae_mode. So: want the upscale VAE for your final image but a
specific grain/texture VAE for previews? Keep both connected - they don't conflict.
Want the upscale VAE and don't care about previews? decode_vae can stay disconnected
with no effect either way.
Two ways to get the downsample quality pass on the final decode. The mode's
… final decode downsample variants request it per-run; the Upscale VAE Loader's own
downsample_to_1x toggle bakes it into the loaded VAE for every consumer (including
the standalone Upscale Decode node). Either enables the same thing - decode at 2× then
Lanczos-downsample back to native, a supersampling-style pass rather than a literal
resolution gain. blur_sigma=0 is a good default (Lanczos already anti-aliases); raise
it only as a taste knob. Inter-stage (S2→S3) downsampling reads the mode flags, not the
loader boolean.
upscale_renorm)Latent interpolation is a lowpass: every upscale hop shrinks latent variance,
and decoded variance is contrast/saturation - so multi-hop runs compound a
little drain per hop into progressive flattening and desaturation.
upscale_renorm repairs the statistics right after each hop:
per_channel (recommended) - re-match each latent channel's mean/std to
the pre-hop latent; strongest color + contrast hold.global - overall mean/std only.off - previous behavior.A telemetry line prints latent std pre-hop / post-hop / post-renorm in every mode, so the drain (and the repair) is measurable per run.
Turbo is distilled for guidance 0, so most wrappers give you no CFG - and therefore no
negative prompt - on the Turbo checkpoint. Multi-Stage Ultra re-enables it. The
turbo_guidance dropdown decides where classifier-free guidance (and the negative pass
it needs) is allowed on a distilled model:
turbo_guidance | S1 | S2 | S3 |
|---|---|---|---|
off (default) | g = 0 | g = 0 | g = 0 |
s1_only | uses s1_cfg | forced g = 0 | forced g = 0 |
all_stages | s1_cfg | s2_cfg | s3_cfg |
g, where standard CFG = 1 + g (g=0 → CFG 1.0,
g=0.2 → CFG 1.2). Turbo was distilled for g=0, so keep it low (~0.1-0.3); the node
warns above g=1.5 (Raw-level, over-saturates Turbo).g > 0. Under off it is inert.s1_only exists: put guidance + negatives on the composition, then let
S2/S3 refine fast and single-pass (it force-zeros s2_cfg/s3_cfg for you - you don't
set them yourself).Using a real negative prompt on a distilled/Turbo checkpoint at all is unusual - most Turbo pipelines simply can't feed one.
For negatives without a second pass, see NAG / NegPiP - both work at g = 0.
A fine tune's preferred sampler, scheduler, step count, mu and cfg tolerance are all proxies for one variable - how far its training eroded the turbo distillation. The sweep system turns that from folklore into measurement: characterize a model in one queue item, keep the evidence, promote the winners to presets.
Wiring: Eric Krea2 Sweep Plan → Ultra V2's sweep input (last socket).
The Ultra panel is the base recipe; each cell overrides only its swept keys.
All existing machinery (LoRA stack, cond rebalance, ref latents, telemetry,
renorm) runs untouched per cell.
Grid mode: fill any of the axis fields - samplers, schedulers
(pair_lock zips them into fixed pairs), steps, windows (5-12 →
start/end step), etas, noise_types, cfgs, shift_modes/mus,
hybrid_steps, megapixels - blank = not swept (panel value used). The
schedulers field takes built-in schedules AND saved sigma-shape ★ preset
names mixed freely (each entry resolves as a schedule first, then as a
sigmas preset applied as that cell's full profile; unknown names are
skipped with a console warning, never an abort), and comes pre-populated
with everything available - delete what you don't want. Full cross product,
hard-refused over max_combos with an axis-size breakdown. Cells that differ
only by inert knobs (eta/noise on euler/lcm) are deduped automatically.
Combos mode: one JSON object per line in combos_json, or a file via
combos_file (JSON array, {"combos": [...]}, or JSON-lines) - keys are the
same widget keys as presets and PNG recipes, so combos are copy-pasteable
from any stamped image. Sweep campaigns become versionable files.
Workflow intent: quick_screen forces S1-only at screen_megapixels for
cheap wide grids - perfect Stage 1 first, then sweep stage_scope=s2/s3
refinement on the short list. For s2/s3-only sweeps the post-S1 latent is
computed once and reused across cells (s1_reused in the manifest;
automatically disabled per cell for anything that changes Stage 1, and
globally under seed_mode=same_all_stages).
Outputs (to output/sweeps/<timestamp>_<finetune>/, or output_folder):
cell_NNN_<values>.png - every cell at full res with the complete resolved
recipe (ultra + loader + lora sections) embedded in a
krea2_settings chunk - each file is standalone-reproducible.contact_sheet.png - downscaled overview (tile_px tiles), captions show
only the diffs vs base, green line = per-cell generation time + scores.sweep_summary.csv - one row per cell: swept columns, gen_time_s,
rounded scores - sortable in any spreadsheet.sweep_manifest.json - full resolved recipes, timings, metrics, errors.Scores (optional, CPU, milliseconds - failure detectors, not beauty
judges): Laplacian + Tenengrad sharpness, wavelet noise sigma, flat-region
chroma variance, clip fraction. All land in the CSV/manifest; sort_by
pre-sorts the sheet; scores never hide a cell - the eye stays the judge.
Field calibration (two full 192-cell characterization runs, 2026-07-29):
clip% is the best bad-image predictor - above 3-4% suspect, above 6%
almost always bad (the sheet flags C4.2%! / C7.1%!! at exactly those
absolute thresholds, and Auto Pick's gates use them). sharp_ten
(Tenengrad) proved more trustworthy than Laplacian - it is the sharpness
shown on the sheet and gated by Auto Pick - though neither is immune to one
strong edge dominating; subject/tiled sharpness via the external scores.csv
route is the real answer there. noise sigma and splotch showed no
quality discrimination in the field - they remain CSV columns but gate
nothing and no longer appear on the sheet.
Sheet captions are stage-grouped shorthand - one line per swept stage
(s1: 2.5mp res_2m+beta57 h7 e0.3), ★profile / seed / prompt on a trailing
line - plus a compact metric line: T88s S11.3k C0.5% N1.0 U159
(T time, S sharp_ten/1000, C clip% with the !/!! flags, N noise, U
uniqueness).
Uniqueness (model-free, automatic): every cell gets a composition-uniqueness score - its mean distance from the other cells' 64x64 luma thumbnails, grouped per (prompt, S1 megapixels). READ THE DIRECTION BY EXPERIMENT TYPE: in a fixed-seed SETTINGS sweep, high uniqueness means "deviates from the consensus" and broken cells deviate hardest - the LOW end is the consensus render and the high end is an outlier list; in a SEED sweep, divergence is the point and high = more compositional variety. Auto Pick has an objective for each direction.
Promotion: Eric Krea2 Sweep → Preset reads a manifest cell into
ultra_presets.json (swept keys only, or the full recipe), auto-tagged with
the checkpoint name and an objective note - per-fine-tune preset libraries
by construction.
LoRA, prompt & sigma-profile axes (sweep v2):
lora_mode=bakeoff) - one LoRA per line in
lora_files (loras-folder names or full paths) x lora_strengths
(one value drives all three stage weights). Default: each swept LoRA runs
ALONE, so every style is measured against the bare checkpoint on equal
footing; keep_panel_stack layers it on top of your declared stack
instead. include_baseline adds the reference cell (no-LoRA, or the
panel stack alone when layering). Sweep-injected entries are ephemeral -
fused per cell, cleaned per cell, nothing persists.lora_mode=strength_ladder) - keeps the
panel-declared stack and steps only the lora_target entry (1-based
index, or a name substring) through lora_strengths.prompts; each prompt cell
re-encodes (conditioning cleared automatically, ~seconds/cell). Prompts
expand as the SLOWEST axis, so the contact sheet and CSV read in
prompt-major blocks - metric comparisons are only meaningful within a
block.sigma_profiles takes saved ★ preset NAMES from
the Eric Krea2 Sigmas node (validated at plan time); each cell rebuilds
the full bundle from that preset, overriding any wired sigmas node for
that cell.lora_triggers, default append) - each bake-off
cell merges its swept LoRA''s trigger words (from the stack node''s cached
trigger database) into that cell''s prompt, so trigger-dependent styles are
measured fully activated. Only sweep-injected entries contribute; baseline
and ladder cells are untouched; a changed prompt re-encodes automatically;
the effective prompt + triggers land in the cell''s metadata.All v2 axes cross with every classic axis, in grid mode AND on top of explicit combos, under the same cap and dedupe rules. LoRA/prompt/profile cells always run a full Stage 1 (S1-latent reuse correctly sits out). Each cell PNG records the ACTUAL stack, bundle, and prompt that cell ran - not the panel's - so every file stays a complete standalone recipe.
Failed cells never kill a sweep (red tile + manifest error), and interrupts finalize the files on disk before stopping the queue item.
Auto Pick: Eric Krea2 Sweep Auto Pick closes the loop from sweep to
preset: manifest in, cell_index + a human-readable report out. Objectives:
fastest_acceptable (fastest cell passing the field-calibrated gates:
clip% ABSOLUTE - reject above 6%, flag 4-6% as suspect-but-passing;
sharp_ten relative to the sweep median or an eye-picked reference_cell
with tolerance slack; and a uniqueness consensus-outlier gate - cells far
above the reference are rejected as deviants, with 2x tolerance so style
variation passes), most_unique (highest composition-uniqueness - the SEED
sweep objective; recomputed from cell PNGs for older manifests),
most_typical (LOWEST uniqueness - the consensus render, the right pick in
settings sweeps where high uniqueness flags broken outliers), best_metric
(any built-in column), and best_external (any column of a scores.csv in
the sweep folder, joined by filename - blank metric = first numeric column).
Wire cell_index into Sweep -> Preset (convert its widget to an input) and
one queue runs sweep -> pick -> promote. The picker proposes and explains
its choice with runners-up; promotion only happens because you queued the
preset node - metrics never silently write your preset library.
Folder scoring chain: the Eric Sweep Folder Scorer node (in the
Eric-image-classification package) consumes the manifest path and grades
every cell with the analyzer suite - Blur V7, Noise V4, composition,
exposure, UniPercept (with a device picker for the second GPU) - and
writes/merges scores.csv in the sweep folder, one column per numeric
output (comp.composition_score, blur7.variance, ...). Merging is by
filename, so multiple grading passes stack columns instead of clobbering.
The full hands-off chain is: Ultra V2 sweep_manifest -> Krea2 Unload
(frees the generator's VRAM; its wildcard passthrough keeps the ordering) ->
Sweep Folder Scorer -> Auto Pick (best_external) -> Sweep -> Preset:
one queue from characterization to a machine-proposed, human-ratified
preset.
Sweep presets, the toggle & notes: the Sweep Plan node carries an
enabled switch (off = the wired node is inert and normal generation runs)
and a sweep_preset dropdown backed by sweep_presets.json. Selecting a
preset WRITES its values into the panel - you always see exactly what will
run - and editing any field flips the dropdown back to custom; the ★ Save
Preset button saves the panel under a new name. Headless/API runs apply the
named preset as the sole source. Both the Sweep Plan and Sigmas nodes carry
a preset_notes field saved with each ★ preset - one sentence on what the
preset is FOR - written into the panel on select and printed by headless
runs, so preset libraries stay self-documenting.
Swept schedules vs a wired sigmas bundle: a cell that explicitly sweeps
a stage's schedule disables the wired bundle for that stage, cell-locally -
a swept axis is never silently inert (the bundle previously overrode swept
schedules, which produced identical cells and only a warning). Unswept
stages keep the bundle; sigma_profiles cells replace it entirely; each
cell's PNG chunk records what actually applied.
AutoencoderKLQwenImage (16-channel, f8), identical
to Qwen-Image and Wan2.1 - which is why the spacepxl 2× decoder is a drop-in.expansion.txt and point the Magic
Prompt node's system_prompt_path at it.flash_varlen backend assumes the
valid keys are a prefix; Krea 2 pads text in the middle of [text | image], so with
attention_backend=auto every generation attended to padding and dropped the bottom image
rows (the bottom band crop_bottom was hiding, plus weaker prompt adherence). All Krea 2
attention now drops padded keys explicitly before the kernel - same speed as before, matches
SDPA. Existing seeds render slightly differently (correctly to the edge); crop_bottom
is no longer needed - it now defaults to 0 and crop_overgen to off, and the shipped Ultra
presets were reset to match (saved workflows keep whatever they stored).
Side effect worth knowing: the old path diluted every prompt with ~400 padding tokens, so the
prompt (and text-side LoRAs) now act at full strength - same image quality, noticeably
stronger prompt / style adherence (e.g. a style that implies nudes now gets them more often).
For A/B comparisons, set ERIC_KREA2_MASK_SAFE=0 before ComfyUI starts restores the old
behaviour (console prints a DIAGNOSTIC line; use crop_bottom).prompt: N/507 tokens every run and a warning with the dropped words when a prompt
overflows - keep LLM-expanded prompts under ~380 English words. (Vision Prompt checks its own
budget and errors instead.)
Trigger words are protected: with add_triggers on (LoRA / Multi-LoRA Stack, and sweep cells),
the merge counts tokens and, when prompt + triggers would overflow, shortens the prompt body
(sentences just before the last one go first) so the triggers are never the part that is cut.
A trigger only counts as already present on a whole-word match (rust is not in rusted).diffusion_model.blocks.N.attn.wq...) used to load with 0
modules applied, so the LoRA silently did nothing. They are now remapped, injected with the
file's own Kronecker factor, and scaled by ComfyUI's LoKr rule (full w1/w2 = strength).TextEncodeQwenImageEditPlus for this
wastes a silently-discarded reference latent and uses the wrong prompt template.
This is an independent implementation built directly against the installed
diffusers/transformers source, not a port of that node's code.transformer_krea2.py, not a port.Patil/Krea-2-depth-controlnet) and the
facok/comfyui-krea2-controlnet port;
reimplemented for the diffusers transformer.comfy_kitchen kernels and layouts.These nodes are an independent implementation; no code is copied from Krea or spacepxl repos. Where a mechanism was ported from a permissively licensed project (Apache-2.0 / MIT, listed above), the module header carries the attribution.
A ComfyUI diffusers implementation of Krea2 for the highest possible quality and most options
Python
18
15 commits
updated Oct 8, 2026
Self-contained ComfyUI custom nodes for Krea 2 - Krea AI's open-weight, from-scratch image model (single-stream MMDiT, flow matching, Qwen3-VL conditioning). Includes text-to-image, progressive multi-stage high-res generation, a 2× upscale-decode trick, natural-language prompt tooling, and an image-to-image suite (control, style, inpaint/outpaint, instruction edits) plus negative guidance that works on Turbo.
No dependency on any other node pack.
Real diffusers pipeline, not a reimplementation. Runs the genuine Hugging
Face Krea2Pipeline (single-stream MMDiT, flow matching, Qwen3-VL conditioning)
loaded straight from weights - so you inherit upstream behaviour, fixes and the
correct trained prompt templates, with no reverse-engineered sampling loop to
drift out of sync.
Easy, honest multi-stage high-res. Up to 3 progressive stages in one node, with per-stage samplers, schedules, guidance and re-noise windows, plus an on-node resolution-chain readout so you always see the real S1→S2→S3→decode sizes.
First-class img2img. A VAE Encode node feeds an init_latent input; denoise
strength is just the stage's re-noise step window - no separate float to guess.
Reference-image style/content grounding (Vision Prompt). Ground conditioning in 1-3 reference images through Krea2's own Qwen3-VL vision path - a "prompt from a picture" effect (semantic style/content grounding, not pixel editing) with no training and none of the silently-discarded-reference pitfalls of the common community pattern. Composes freely with img2img for structure + content on separate channels.
Presets everywhere. Named JSON presets per section (loader / LoRA / Ultra / sigmas) with a ★ Save button, a Merge Settings node, and Settings-from-Image for one-click reproduction of a saved image's recipe.
LoRA with per-stage settings + presets. Apply / unload / diagnose plus a Multi-LoRA Stack - both with per-stage weights (S1/S2/S3), so a LoRA can steer composition harder than final detail (or vice-versa) within a single multi-stage run, and both with named-preset save/load (★ Save) for one-click recall.
Reference-latent edit pathway. With an edit-trained LoRA loaded, a Reference Latents node feeds VAE-encoded reference images through the ai-toolkit "index_timestep_zero" method - real pixel/structure conditioning (distinct from Vision Prompt's semantic grounding), reimplemented against our diffusers transformer.
Custom flow-matching samplers, no external solver. res_2m, res_2s,
deis_3m, deis_4m re-implemented from the RES/DEIS papers, selectable per
stage, with schedule + detail_bias control.
Two high-res strategies for two checkpoints. Turbo → fast 4k via the 2× upscale-decode; Raw → controlled multi-stage re-denoise - plus optional downsample "quality-pass" VAE modes that are usually cleaner than the Wan 2.1 VAE at the same size.
A full image-to-image suite on one node. Control-LoRA ("ControlNet" depth/pose), training-free style transfer, inpaint/outpaint with the AnyPaint adapter, and instruction/identity editing with the Krea 2 Identity Edit LoRA - each a small builder node that plugs into a socket on Multi-Stage Ultra, with per-stage strengths, so the same multi-stage high-res engine serves every task.
Negative prompts that work on Turbo. NAG (Normalized Attention Guidance) and NegPiP
((phrase:-1) in the prompt) give a distilled checkpoint real negatives at guidance 0 -
no second CFG pass.
Native quantized compute. Run INT8-ConvRot / MXFP8 / NVFP4 / fp8 checkpoints on their own tensor-core kernels instead of dequantizing to bf16: ~1.45x faster and ~12 GB less VRAM at 3 MP, LoRAs included. Opt-in; bf16 stays the default.
Correctness first. A same-seed A/B found and fixed a diffusers flash_varlen bug that
silently dropped the bottom rows of every Krea 2 image (the "bottom band"); model switches
no longer leave the previous model resident in VRAM.
October 2026 - image-to-image suite, negative guidance, native quantized compute.
control socket:
depth / pose / canny ... structure control via Krea 2 Control-LoRA checkpoints (expanded
input layer + block LoRA), per-stage strengths. See Control.style socket: transfers palette / brushwork / texture from one image with no LoRA.
See Style Reference.paint socket: AnyPaint / Outpaint adapters, kept regions pinned to the source at every
stage. See Inpaint / outpaint.edit socket: the Krea 2 Identity Edit
recipe (recolor, restyle, re-pose, add / replace objects, outpaint, person-into-scene),
with the v1.2 fit reference geometry and the ref_boost fidelity dial.
See Edits.guidance
socket: NAG and NegPiP, both off by default, combinable, work at guidance 0.
See Negative guidance.compute / native_format (appended):
run quantized checkpoints on their native kernels. See
Native quantized compute.comfy_kitchen layouts) next to fp8, INT8 and
INT8-ConvRot. See Quantized checkpoints.degrid toggle on both decode nodes, and degrid on Ultra (inter-stage VAE hops and/or
the final image). See DeGrid.suggestions socket for the LoRA
Suggester. See LoRA search.flash_varlen bottom-band bug (all Krea 2 attention is now mask-safe;
existing seeds render slightly differently, edge to edge correct); VRAM pinned by LoRA
nodes and by the loader on model switches; the Reference Latents edit_frame recipe used
a stretch instead of the trained fit geometry. See Notes.Late July 2026 (cont.) - field-calibrated scoring, preset UX, er_sde.
most_typical objective (consensus render) plus a uniqueness
consensus-outlier gate. Calibrated from two full 192-cell runs.Eric Sweep Folder Scorer (in
Eric-image-classification) grades a whole sweep with Blur V7 / Noise V4 /
composition / exposure / UniPercept and writes a merged scores.csv that
Auto Pick reads via best_external: sweep -> unload -> score -> pick ->
promote in one queue.custom, and a preset_notes field (also on the
Sigmas node) keeps a saved sentence about what each preset is for.er_sde sampler + simple scheduler - a ComfyUI-faithful ER-SDE
Solver-3 port (verified step-identical): intrinsically stochastic, and
the only 1-eval/step sampler that is schedule-proof (amplification 0.048
on EVERY schedule incl. linear_quadratic). eta is ignored; the noise TYPE
shapes its churn (colored-noise er_sde is unique to this package).
simple = uniform-in-sigma, an alias of linear.Late July 2026 - parameter sweeps, hybrid samplers, inter-stage renorm.
Eric Krea2 Sweep Plan into Ultra V2's
new sweep input and one queue item runs a whole grid (or explicit combo
list) of sampler / scheduler / steps / window / eta / noise / mu / cfg /
megapixels settings against a fixed seed: per-cell PNGs with full embedded
recipes, a labeled contact sheet, sweep_summary.csv, a JSON manifest,
automatic S1-latent reuse for s2/s3-only cells, and one-click promotion of a
winning cell to a preset. See Parameter sweeps.lcm_hybrid / lcm_hybrid2 samplers + hybrid_split - lcm full-churn
entry (launders upscale damage) handing off to a trajectory-faithful tail
(deis_3m / res_2m) at a selectable fraction of the window.upscale_renorm - repairs the latent variance each upscale hop drains
(variance is contrast/saturation), stopping the progressive flattening of
multi-hop runs. per_channel recommended.July 2026 - multi-stage sampling, presets & img2img toolkit.
res_2m, res_2s, deis_3m, deis_4m
re-implemented from the RES/DEIS papers (no external solver import), selectable
per stage. Recommended: res_2s + beta57 for the Stage-1 draft, deis_3m /
deis_4m + bong_tangent for the refine passes.linear, balanced, karras,
beta57, beta, bong_tangent, exponential, with a per-stage detail_bias
control driven from a dedicated Sigmas node.init_latent input on the
Multi-Stage node; denoise strength is set by the re-noise step window.width/height/blank latent) and a latent-space
Latent Resize (bislerp, no VAE round-trip).ref_latents input on the Multi-Stage Ultra (res) node. Works only with an
edit-trained LoRA loaded (e.g. the Krea 2 Style Reference LoRA on Turbo at guidance 0);
the base model can't read reference tokens. See
Reference Latents.… with downsample modes are usually cleaner/sharper than the Wan 2.1 VAE at
the same output size and avoid the resolution blow-up. An on-node resolution-chain
readout shows the real S1→S2→S3→decode sizes and flags any field the VAE overrides.
See Upscale VAE: modes & precedence.Initial release (June 2026): Krea 2 Raw + Turbo support, multi-stage high-res, 2× upscale-decode, selectable attention backend, natural-language prompt builder + LLM Magic-Prompt expander.
These nodes drive the genuine Hugging Face Krea2Pipeline directly (see
key advantages); the only hard requirement is a
diffusers/transformers build new enough to expose it.
A diffusers build that includes Krea2Pipeline (merged after 0.39.0.dev0):
python_embeded\python.exe -m pip install --upgrade --force-reinstall --no-deps git+https://github.com/huggingface/diffusers.git
The version string stays 0.39.0.dev0, so --force-reinstall is required to
pull the newer commit.
A transformers new enough to provide Qwen3VLModel.
Krea 2 weights in diffusers layout (e.g. H:\Training\Krea-2-Raw and
H:\Training\Krea-2-Turbo).
Optional, recommended on Blackwell: FlashAttention and/or SageAttention for
the faster attention_backend paths. Kernel bench on an RTX PRO 5000 (sm120, Krea 2 shapes,
2026-10-08): flash-attn 2 = baseline; SageAttention 2 sageattn (int8 QK, fp8 PV) 1.6-1.8x
faster per attention call with ~4% relative error (cos 0.9992); its Triton varlen kernel
(what attention_backend=sage picks first) only 1.13-1.17x; xformers and cuDNN SDPA = flash.
The dense kernel is the sage_fp8 choice (last in the list). End to end on Turbo, 8 steps:
-4-6% step time at 1.5 MP, -9-12% at 3 MP, -19% at 8.4 MP (10.2 -> 8.3 s/step). Images are
equally clean (text, skin, frost detail checked at 1:1) but not seed-identical to flash - the
small per-call error steers the trajectory, so the same seed gives a sibling image, sometimes a
different framing. Edit / NAG / ref_boost runs still use flash for their split attention.
Optional: the spacepxl Wan 2× upscale VAE (auto-downloaded on first use).
Optional: flash-attn (2.8+) - also used by the edit / NAG / ref_boost attention core
(falls back to an exact but slower math path without it).
Optional: ComfyUI's comfy_kitchen (ships with recent ComfyUI) - needed for MXFP8 / NVFP4 /
W4A4 / W4A8 / W6A8 checkpoints and for compute = native.
Optional, per feature: Control-LoRA, AnyPaint and Identity Edit LoRA weights (see each section).
A single, multi-purpose graph lives in workflows/. Drag
example-workflow.png onto the ComfyUI canvas (the graph is embedded in the
PNG metadata) to load the whole pipeline at once - loaders, txt2img, img2img,
Vision Prompt, per-stage sampling, and the metadata-aware save. Flip parts on/off
with group bypass (Ctrl+B) instead of juggling separate workflows. See
workflows/README.md for the group-by-group breakdown.
| Node | Does |
|---|---|
| Eric Krea2 Loader | Loads Krea2Pipeline (Raw or Turbo), applies attention_backend, caches in VRAM. Auto-detects is_distilled. Preset dropdown. |
| Eric Krea2 Generate | Text-to-image. Emits IMAGE + a chainable KREA2_LATENT. auto_settings picks 8/0 for Turbo, 28/4.5 for Raw. |
| Eric Krea2 Multi-Stage Ultra (res) | Up to 3-stage progressive high-res with the custom RES/DEIS samplers, per-stage schedules, img2img init_latent, an optional ref_latents edit input, and width/height overrides. Sockets for control, style, paint, edit and negative guidance; degrid for the VAE lattice. Best on Raw for multi-stage re-denoise. |
| Eric Krea2 Multi-Stage Ultra V2 (presets) | Preset-driven variant of the Ultra node - serialises every widget (incl. sigmas, width/height) into one reproducible recipe. |
The loader group - the Component Loader (with loader_preset), the Upscale and Decode VAE loaders, and the growable Multi-LoRA Stack with per-stage strengths. Each carries its own ★ Save Preset button.
| Node | Does |
|---|---|
| Eric Krea2 Sigmas | Per-stage schedule overrides (S1/S2/S3): curve, detail_bias, Beta α/β. Emits a KREA2_SIGMAS bundle the Ultra nodes fold in. |
The Sigmas node: per-stage curve / detail_bias / Beta α-β overrides with a live sigma preview per stage (solid = steps that run, ring = re-noise level, ghost = full schedule).
Samplers (per stage, on the Ultra node): euler, res_2m, res_2s, deis_3m,
abnorsett_3m, abnorsett_4m, lawson4_4s, etdrk4_4s, er_sde,
rk6_7s, lcm, lcm_hybrid, lcm_hybrid2.
Schedules: linear, balanced, karras, beta57, beta,
bong_tangent, exponential, linear_quadratic, simple
(= ComfyUI's uniform-in-sigma scheduler; alias of linear here).
See Samplers & schedules.
KREA2_SWEEP plan (grid axes or
JSON-lines combos, stage scoping, quick-screen mode, output folder, hard
combo cap). Wire into Ultra V2's sweep input.ultra_presets.json, tagged with the checkpoint name.
See Parameter sweeps.| Node | Does |
|---|---|
| Eric Krea2 VAE Encode | Encodes an IMAGE → KREA2_LATENT (the img2img primitive). |
| Eric Krea2 Reference Latents (Edit) | VAE-encodes 1-3 reference images → KREA2_REF_LATENTS for the Ultra (res) node's ref_latents input (ai-toolkit "index_timestep_zero" edit method). Needs an edit-trained LoRA - without one the base model does not ignore the reference tokens, they corrupt the image into a blocky mosaic. See Reference Latents. |
| Eric Krea2 Resolution | Size from aspect_ratio + megapixels or a source image → width/height/dims + a blank KREA2_LATENT (noise or zeros). |
| Eric Krea2 Latent Resize | Resize a KREA2_LATENT in latent space (bislerp, no VAE round-trip): scale / dimensions / megapixels. |
| Eric Krea2 Latent → ComfyUI LATENT | Bridge a KREA2_LATENT to a stock ComfyUI LATENT. |
Each builds a bundle for one socket on Multi-Stage Ultra (all sockets were appended - saved workflows are untouched). Nothing loads or runs in these nodes; Ultra installs the runtime for one generation and removes it afterwards (cancel-safe).
| Node | Ultra socket | Does |
|---|---|---|
| Eric Krea2 Control (Depth/Pose ControlNet-LoRA) | control | Control image + Control-LoRA checkpoint + per-stage strengths (S1 1.0 / S2 0.5 / S3 0). See Control. |
| Eric Krea2 Style Reference (training-free) | style | Style image + recommended / custom preset + per-stage multipliers (S1 only by default). See Style Reference. |
| Eric Krea2 Paint (inpaint / outpaint) | paint | Source + mask and/or outpaint padding, adapter (anypaint / outpaint / none), per-stage restore + adapter switches. Outputs the bundle, a vlm_image for Vision Prompt, a canvas preview and the generated mask. See Inpaint / outpaint. |
| Eric Krea2 Paint Composite | - | Optional pixel-exact paste-back of the source outside the mask with a feathered edge. |
| Eric Krea2 Edit | edit | Source image (+ optional second reference), edit instruction, fit_mode, ref_boost / ref_boost_a (+ mask), grounding_px, size_from, ground_negative. See Edits. |
| Eric Krea2 Negative Guidance | guidance | NAG (own negative text, phi / tau / alpha, stages, sigma window) and NegPiP (mode, strength, block range, text-fusion option). See Negative guidance. |
Which sockets combine (one run):
| control | style | paint | edit | guidance | ref_latents | |
|---|---|---|---|---|---|---|
| control | - | yes | yes | yes | yes | yes* |
| style | yes | - | no | no | skipped | no |
| paint | yes | no | - | no | skipped | no |
| edit | yes | no | no | - | yes | no |
| guidance | yes | skipped | skipped | yes | - | skipped |
| ref_latents | yes* | no | no | no | skipped | - |
"no" raises a clear error (both wrap the transformer forward); "skipped" runs the other one and prints that guidance was ignored.
Control with edit or ref_latents: the control hint is applied to the target image tokens only; reference tokens bypass the Control-LoRA (before 2026-10-08 control was silently dropped whenever reference tokens were present). *control + ref_latents is verified to apply control on every step; a full visual run with the edit LoRA at 1.5 MP spilled VRAM on a 48 GB card shared with displays, so try 1 MP first.
| Node | Does |
|---|---|
| Eric Krea2 Upscale VAE Loader | Loads the spacepxl Wan 2× upscale decoder → UPSCALE_VAE. Optional downsample_to_1x + blur_sigma: decode at 2× then Lanczos-downsample back to native size - a supersampling-style quality pass instead of a literal resolution gain. Travels with the loaded VAE into every consumer (see Upscale VAE: modes & precedence). |
| Eric Krea2 Decode VAE Loader | Loads a plain decode VAE. |
| Eric Krea2 Upscale Decode (2×) | Decodes a KREA2_LATENT via the upscale VAE (no re-denoise). Resolution and any downsample/blur are whatever the loaded UPSCALE_VAE was configured with. |
| Eric Krea2 VAE Decode | Plain 1× decode of a KREA2_LATENT. |
| Eric Krea2 DeGrid (VAE grid remover) | Removes the VAE's 2-pixel lattice from any image (auto-calibrated notch, untouched when clean) + removed-grid preview and report. Both decode nodes also gained a degrid toggle. See DeGrid. |
| Node | Does |
|---|---|
| Eric Krea2 Merge Settings | Merges section recipe strings into one KREA2_SETTINGS (dicts updated, lora lists concatenated). |
| Eric Krea2 Settings from Image | Reads an image's embedded generation settings back into a KREA2_SETTINGS recipe. |
| Eric Krea2 Component Loader | Loads pipeline components (base folder + optional single-file transformer / VAE / text encoder) with a preset dropdown. Reads bf16, GGUF, fp8, INT8, INT8-ConvRot, MXFP8, NVFP4, ConvRot-W4A4, W4A8, W6A8 (formats); compute = bf16 or native quantized kernels (native compute); VAE tiling controls. |
| Eric Krea2 Apply LoRA / Unload LoRA / Diagnose LoRA | Apply, cleanly remove, and inspect LoRA adapters on the cached pipeline. Apply LoRA supports per-stage weights (per_stage_weights + weight_s1/weight_s2/weight_s3) so a LoRA's strength can differ across S1/S2/S3 in a multi-stage run, plus a preset dropdown (apply_lora_preset + ★ Save). |
| Eric Krea2 Multi-LoRA Stack | Stack several LoRAs in one growable node - each slot has per-stage weights (strength_Ns1/s2/s3 for S1/S2/S3) and an on/off toggle, plus a shared ephemeral switch and a preset dropdown (lora_preset + ★ Save). Unused rows auto-hide until needed. Click the middle of a LoRA dropdown for the 🔍 search popup (also on Apply / Diagnose LoRA); optional suggestions socket for the LoRA Suggester. |
| Eric Krea2 Unload Models | Free VRAM on demand. |
| Eric Krea2 Save Latent (debug) | Save/inspect a packed latent for debugging. |
Reproducibility: Merge Settings folds the loader + Ultra + LoRA + prompt recipes into one bundle that gets embedded in the saved PNG - readable back later via Settings from Image.
| Node | Does |
|---|---|
| Eric Krea2 Prompt | Assembles structured fields into a dense, comma-joined natural-language prompt; quotes text-to-render. |
| Eric Krea2 Magic Prompt | Expands a short prompt via a local LLM (LM Studio / Ollama / any OpenAI-compatible endpoint). |
| Eric Krea2 Vision Prompt | Grounds conditioning in 1-3 reference images via Krea2's own Qwen3-VL vision path, using Krea2's trained descriptor template (not the generic Qwen-Image-Edit template). Emits KREA2_CONDITIONING → Ultra's prompt_conditioning input. See Vision Prompt below. |
Each stage of the Multi-Stage Ultra node picks a sampler (the ODE solver) and a schedule (the sigma spacing) independently.
A full sampling group - the Sigmas node feeding Multi-Stage Ultra V2, with per-stage samplers/schedules, guidance, re-noise windows, and the on-node resolution-chain readout.
Samplers
| Sampler | Order | Model calls / step | Best for |
|---|---|---|---|
euler | 1 | 1 | Baseline / native parity (the comfy euler+simple twin). Honours early stop and eta (runs as a 1-stage RK). |
res_2m | 2 (multistep) | 1 | General use - sharper than Euler at the same cost. |
res_2s | 2 (single-step) | 2 | Low step counts / Stage-1 draft. Self-starting; ~2× slower. |
deis_3m | 3 (multistep) | 1 | Smooth refine passes. |
deis_4m | 4 (multistep) | 1 | Smoothest refine at higher step counts. |
rk6_7s | ~6 (7-stage RK) | 7 | Maximum solver accuracy (finetuner recipes; the Raw model). ~7x cost per step - overkill for Turbo daily use. |
abnorsett_4m | 4 (exp. multistep) | 1 | Recipe-name alias of deis_4m - identical update in this solver formulation. |
lcm | ancestral | 1 | Post-upscale refine windows: jumps to x0 and fully re-noises every step, laundering upscale artifacts. Not for Stage 1. |
Every sampler honours a noisy early-stop (end_step < steps), letting a stage
hand a partially-denoised latent to the next, and supports the ancestral eta
SDE path (lcm is inherently fully ancestral - see below). Since the 2026-07-22
shift-consistency fix, euler runs through the same solver path as every other
sampler (as a 1-stage Runge-Kutta), so the re-noise level and the stepping always
share one sigma space. The math is recreated from the RES (arXiv:2308.02157) and
DEIS (arXiv:2204.13902) papers plus standard Butcher tableaus - no external
solver code is imported.
Schedules: linear, balanced, karras, beta57, beta, bong_tangent,
linear_quadratic (ComfyUI-core slow-linear-then-quadratic descent; the kreamania pass-1 schedule),
exponential. The Sigmas node adds a detail_bias knob (biases sigma spacing
toward fine detail vs. large structure) and Beta α/β shaping.
Recommended pairings (per the RES4LYF community):
res_2s + beta57.deis_3m or deis_4m + bong_tangent.lcm + linear with a deep window - see below.Native parity note: linear + distilled_shift=fixed reproduces ComfyUI's
euler/simple spacing exactly (same uniform grid, same exponential mu=1.15
shift) - that pairing IS the native baseline, not an approximation of it.
Two independent properties decide which solver fits a stage. They often point in opposite directions, so it's worth understanding both rather than just copying the pairings above.
1. Multistep warmup (order build-up). Multistep solvers (res_2m, deis_3m,
deis_4m) reach their rated order by fitting a polynomial through past steps, so
they start low-order and ramp up:
| Step in the run | deis_3m effective order |
|---|---|
| 1st | 1 (Euler-like) |
| 2nd | 2 |
| 3rd onward | 3 (full) |
Crucially, each stage restarts the solver - the history buffer is empty at the
stage boundary and does not carry across the re-noise handoff. So the ramp is
measured from the first step of that stage's run, not the global step index. A
Stage-3 run of steps=14, start=7, end=14 is 7 sampling steps, of which the
first ~2 are below full order (full 3rd order from its 3rd step ≈ global step 9).
deis_4m ramps over ~3 steps and needs even more runway. Sub-order steps aren't
"wrong" - they're just Euler/2nd-order accurate - but at low step counts the warmup
eats most of the run and the higher order never pays off.
res_2s is self-starting (a self-contained predictor+corrector, 2 model calls
per step) - full order from step 1, no warmup - which is why it wins when steps are
scarce. Cost balances out because you use fewer of them: res_2s @ 4 steps = 8
calls ≈ deis_3m @ 7 steps = 7 calls, but cleaner at the low count.
2. Trajectory smoothness (from-noise vs from-clean). This is why Stage 1 uses a single-step solver even though it has plenty of steps to amortize warmup:
res_2s doesn't rely on history, so it's robust
on that rough start, and its corrector buys accuracy on the most consequential
steps of the whole pipeline.deis_3m's cheap high-order
extrapolation genuinely shines.Putting it together:
| Stage | Trajectory | Steps | Pick | Why |
|---|---|---|---|---|
| S1 draft | from noise | long | res_2s | robustness on the rough start > cheap order |
| S1 draft (cost-saving) | from noise | long | res_2m | multistep middle ground: 1 call/step, some early robustness given up |
| S2/S3 refine | from clean | long (≥~8-10) | deis_3m | smooth trajectory + cheap order; warmup amortized |
| S2/S3 refine | from clean | very long, smooth schedule | deis_4m | marginal extra accuracy once there's runway |
| S3 light refine / no upscale | from clean | few | res_2s | self-starting - no warmup waste when steps are scarce |
Rules of thumb: from noise → self-starting (res_2s); from clean + many steps
→ multistep (deis_3m/4m); from clean + few steps → back to res_2s (no
warmup to waste). deis_4m only over deis_3m on long, smooth, high-step runs; it's
more prone to overshoot on short or noisy-early-stop stages.
lcm fitsEvery sampler answers the same question - "given where the latent is and how noisy it should be, where does it go next?" - and they split into two philosophies.
The ODE family (euler, res_2m, res_2s, deis_*, rk6_7s) treats
denoising as following a trajectory. Each step nudges the current latent along
the flow, so information accumulates: real structure, but also upscale ridges,
interpolation error, and leftover mottling get carried forward, refined, and
sharpened into the output. The members differ only in how accurately they follow
the path (euler crudely, rk6_7s obsessively). Faithful is their virtue and their
flaw: they preserve everything, including what you wish they would not.
lcm is the other philosophy. Each step asks the model for its best guess of
the finished image (the x0 prediction), then throws the current latent away and
rebuilds the next one as that guess plus fresh noise at the next sigma (the
flow-matching mix (1 - sigma) * x0 + sigma * noise). No trajectory, no memory:
whatever damage the latent carried - contour lines from a latent upscale, seam
echo, mismatch residue - is discarded every step and replaced by the model's own
clean prior plus new noise. That is why it launders artifacts that deterministic
ODE samplers faithfully integrate. The price is symmetric: it also discards fine
detail the trajectory was carrying, drifts more from the init, and shows larger
seed-to-seed variety.
The choice rule: damaged starting latent you want repaired -> lcm. Precious
starting latent you want preserved -> an ODE sampler. In between - trajectory with
some laundering - is exactly what eta > 0 on the res/deis samplers is.
Concretely: post-upscale refine windows are lcm home turf (the latent just got stretched and is full of interpolation artifacts - the entire secret of the native euler -> lcm two-pass chains). Stage 1 is ODE territory: you are building structure from noise and want it followed faithfully, and Turbo is TDM-distilled, not LCM-distilled, so full-ancestral from pure noise reads rough and unstable. A same-resolution polish on an already-good image is a judgment call: shallow lcm freshens texture and kills residue; shallow deis/res preserves likeness.
What shapes lcm's churn (it consumes fresh noise every step, so it is the sampler most sensitive to what that noise is):
start_step/end_step): how much of the image gets rebuilt.
Deeper start = more repair, more drift.detail_bias (Sigmas node): where the re-noise ladder
concentrates. Positive bias packs churn events at low sigma (texture polish);
negative packs them high (structural repair).distilled_shift / mu: moves the whole ladder (higher mu = more time spent
churning at high sigma = smoother, deeper repaint).noise_type and eta: lcm-family re-noise draws are ALWAYS plain seeded
white - the model was trained on white noise at every sigma, and a FULL
replacement with colored noise is out-of-distribution (it decodes as
chromatic blotches over the image). noise_type shaping applies only to the
fractional SDE churn of the res/deis/rk samplers at eta > 0. For
colored-noise grain character, use deis_3m/res_2m with eta 0.5-1.0 and a
noise_type - not lcm.seed_mode): lcm windows show more seed variety than the
deterministic solvers - that is the churn, not a defect.Recommended lcm refine baseline (the native-parity chain):
lcm + linear,
distilled_shift=fixed, eta 0, white noise; upscale_to_stage2 ~1.2 (area),
S1->S2 VAE upscale OFF (plain latent hop).upscale_to_stage3 ~1.5.detail_bias +0.2..+0.3.hybrid_splitPure lcm's weakness is that its final detail is bounded by the x0 prediction
at the entry (highest-sigma) steps: the first full re-noise discards the
incoming trajectory - including the previous stage's real detail - and later
steps only polish that re-invention. The hybrids keep lcm's artifact
laundering where it works (the entry steps, where upscale damage lives) and
then develop detail trajectory-faithfully at low sigma, where detail is
actually made:
lcm_hybrid - lcm churn, then a deis_3m tail.lcm_hybrid2 - lcm churn, then a res_2m tail (added 2026-07-25;
res_2m has been testing better than deis_3m as the detail-development half
on several fine tunes - both tails cost the same per step).s1/s2/s3_hybrid_steps (Ultra widgets, default 0) - the handoff in
EXACT lcm steps at the head of that stage's window. 0 = auto (half the
window, ceil - the original behavior). At low step counts this is the
honest control: a fraction only has window-1 real values, so small %
changes were silent no-ops. Fewer lcm steps = more trajectory-faithful
detail; more = more laundering. Clamped so both halves always run; ignored
by every other sampler. Sweepable via the hybrid_steps axis or combos
JSON ({"s2_hybrid_steps": 4}).eta/noise_type apply to the tail half only; the lcm half is inherently
fully ancestral and always re-noises with plain seeded white (colored
noise as a full replacement is out-of-distribution -> rainbow blotches).eta contract: honoured by res_2m/res_2s/deis_3m/abnorsett_3m/
abnorsett_4m/lawson4_4s/etdrk4_4s/rk6_7s and the hybrid tails;
ignored by euler and lcm (euler is the deterministic baseline -
enforced in the dispatch, and the Sweep Plan automatically drops cells
that differ only by inert eta/noise on those samplers).The Norsett & exponential-RK additions (2026-07-27): abnorsett_4m is
no longer a deis alias - it is the genuine fixed-coefficient Norsett
exponential Adams-Bashforth method (RES4LYF-faithful, verified against its
phi tables), with abnorsett_3m as its 3rd-order sibling; the weights
depend only on the current step size, so they stay BOUNDED on every
schedule. deis_4m was removed: its exact variable-step weights blow up on
strongly non-uniform ladders (measured 269x on linear_quadratic) and
amplify model-prediction noise into garbage - if a saved workflow used it,
pick abnorsett_4m (stable order 4, same 1 call/step) or deis_3m.
lawson4_4s and etdrk4_4s are single-step exponential RK order 4
(4 model calls/step, no history): the most noise-robust solvers in the
package, stable everywhere, strong candidates for refine windows. Note
lawson is deliberately not phi-exact for constant forcing (classical
Lawson quadrature) - a texture character difference from etdrk4, not a bug.
Numbers = median deviation of the final state when the model's per-step predictions disagree by 2% (the solver's amplification of prediction noise; lower = more stable). Stability is necessary, not sufficient - which stable pair looks BEST for a given fine tune is what the sweep decides.
| sampler | best schedules | fine | avoid |
|---|---|---|---|
euler, res_2s | any (0.017-0.029) | - | - |
lawson4_4s, etdrk4_4s | any (0.009-0.022, noise-suppressing) | - | - |
res_2m | exponential/beta/beta57/karras (0.020-0.022) | linear (0.053) | linear_quadratic (0.152) |
deis_3m | exponential/beta57/beta/karras (0.022-0.025), OPT-DEIS12 ★ (karras +0.75 bias, 0.023) | bong_tangent/balanced (~0.03), linear (0.118) | linear_quadratic (0.834) |
abnorsett_3m | beta57/beta (0.021), exponential/karras (0.022-0.025) | linear (0.060), linear_quadratic (0.115) | - |
abnorsett_4m | beta57/beta (0.022), OPT-AB412 ★ (beta57 +0.5 bias) | exponential/karras (~0.03), linear_quadratic (0.178) | - |
er_sde | ANY - 0.048 flat on every schedule incl. linear_quadratic (stochastic contraction; schedule-proof at 1 eval/step). Community recipe: + simple @ 8 steps | - | - |
lcm_hybrid/2 | beta57/beta/karras/exponential (0.023-0.028) + the EXP ★ family | bong_tangent (~0.026) | linear (0.055-0.116), linear_quadratic (~0.15) |
Detail-bias windows (how far you can push detail_bias before conditioning
degrades, per curve): deis_3m stays clean on exponential to +0.25, on
beta57/beta from -0.75 to +0.5, and on karras it IMPROVES with positive bias
(clean -0.25 to +0.75 - positive bias straightens the karras tail in
t = -log sigma, which is why OPT-DEIS12 = karras +0.75 is both the most
detail-holding and among the most stable deis_3m curves). abnorsett_4m:
beta57/beta clean -0.75..+0.5; exponential to 0; karras never fully clean.
Single-step order-4 samplers ignore conditioning entirely - schedule choice
is pure aesthetics there. OPT-DEIS12 and OPT-AB412 ship as ★ sigma
presets (S1-only, 12-step recipes).
Field-tested Stage-1 recipe (2026-07-26, found with the sweep system):
12 total S1 steps with either hybrid (lcm_hybrid / lcm_hybrid2) over an
exponential-family custom sigma curve (authored in the Eric Krea2 Sigmas
node and saved as ★ presets - e.g. the EXP1-EXP4 set) lands among the
fastest runs while holding up across most fine tunes and curves. The
handoff sweet spot is s1_hybrid_steps = 7 of 12 for most model/curve
combinations. Treat it as a development control: 5-6 lcm steps hands
off earlier and develops more fine detail; 8 (sometimes 9) launders
longer for a cleaner, less-detailed look. The recipe re-derives itself per
fine tune in one sweep: samplers lcm_hybrid, lcm_hybrid2 x
hybrid_steps 5, 6, 7, 8 x your saved curves in sigma_profiles.
img2img (Part 1): a start image is VAE-encoded into the S1 init_latent. Denoise strength lives in the step window; the prompt still does the talking. Bypass the group for pure txt2img.
Load Image → Eric Krea2 VAE Encode → (init_latent) Multi-Stage Ultra
                     └→ Eric Krea2 Resolution (image) → width/height → Multi-Stage Ultra
Stage 1 re-noises the init_latent at s1_start_step and denoises the
[s1_start_step, s1_end_step] window - so denoise strength is the step window,
not a separate float. Feed width/height from the Resolution node (or turn on
init_match_size) to size Stage 1 to the source image.
Vision Prompt (Part 2): a reference image + a short instruction run through Krea2's own Qwen3-VL vision path → KREA2_CONDITIONING. Sets content/style; pairs with img2img for structure.
Load Image(s) -> Eric Krea2 Vision Prompt -> (prompt_conditioning) Multi-Stage Ultra
Pushes 1-3 reference images through Krea2's own text encoder's vision path (it's a
Qwen3-VL VLM, not text-only), so the resulting conditioning is visually grounded by
those images - a "prompt from a picture" effect - without training anything and
without the pitfalls of the community pattern of reusing the core
TextEncodeQwenImageEditPlus node for this: that node's VAE-encoded reference goes
nowhere (the base Krea2 DiT has no reference-latent pathway - Krea2.extra_conds
never reads reference_latents, so it's silently discarded; an edit-trained LoRA is what
adds one, exposed separately via the
Reference Latents node), and it falls
back to Qwen3-VL's generic image-description template once an image is attached instead of the
descriptor template Krea2 was actually conditioned with. This node has no VAE step at
all (nothing to discard) and always uses Krea2's own prompt_template_encode_prefix/
_suffix, read straight off the loaded pipeline so it can't drift out of sync.
This is semantic grounding, not pixel editing. With no reference-latent pathway of its own it gives no structure/identity preservation from the image alone - for that, pair it with img2img (below): img2img supplies structure (what to start denoising from), Vision Prompt supplies content (what to draw toward). They're independent channels into the transformer and compose freely, including with different source images for each. (If you have an edit-trained LoRA, the Reference Latents node adds a third, pixel-level channel.)
Positive-conditioning only. Steering toward a reference makes sense; steering
away from one is a much stranger ask, and Turbo (the primary target) mostly runs
cfg=0 anyway - no negative pass to feed. When prompt_conditioning is connected,
Ultra's own prompt field is entirely inert (not used, not logged) - put your text in
the Vision Prompt node's own prompt field instead. cond_rebalance still applies to
it, identically to a text-only encode.
Token budget - the one thing to know before your first run. Krea2 was trained
with a fixed 512-token text budget (prefix + images + prompt, always padded/
truncated to exactly this length) - unlike Qwen-Image's dynamic per-batch padding,
which is why Qwen-Image tolerates a much higher max_sequence_length more gracefully.
One full-resolution (1 MP) reference image alone is ~988 tokens - nearly double the
whole budget before your prompt or even the 34-token prefix. To keep this workable
out of the box, the node auto-shares a ~0.40 MP budget across however many images you
connect (1 image ≈ 0.40 MP, 2 ≈ 0.20 MP each, 3 ≈ 0.13 MP each) and raises a clear,
specific error - with a suggested vision_megapixels value - rather than silently
truncating into the image-token block (which corrupts position ids and crashes deep
inside get_rope_index with a cryptic shape-mismatch instead). vision_megapixels is
a ceiling on top of the auto-share, not a replacement for it - lower it to reserve more
room for a long prompt.
Load Image(s) -> Eric Krea2 Reference Latents -> (ref_latents) Multi-Stage Ultra (res)
A second, pixel-level way to condition on a reference image - complementary to Vision Prompt's semantic grounding. Each reference image is VAE-encoded and flow-packed exactly like a generation latent, then its tokens are appended to the image sequence and modulated at t = 0 (clean data) - the ai-toolkit "index_timestep_zero" edit method. The velocity prediction is sliced back to the live image tokens, so the references only inform the denoise, they aren't denoised themselves.
Requires an edit-trained LoRA. The base Krea2 model was never trained to read these
tokens - this pathway only does something useful with an ai-toolkit krea2 edit LoRA
(model_kwargs.edit: true) loaded, e.g. the Civitai Krea 2 Style Reference LoRA.
Without one, the reference tokens are not ignored: the base model reads them as image
content and the output breaks up into a blocky mosaic (tested 2026-10-08, with and without
control). Cost is ~2048 extra tokens per 1 MP ref, per denoise step.
Recommended wiring (matches the Style Reference LoRA's training setup):
max_ref_megapixels 1.0) → ref_latents;vision_megapixels ≈ 0.15) → prompt_conditioning;CFG caveat. The transformer-forward wrapper can't tell a positive pass from a negative
one, so with guidance enabled the references condition both passes and partially cancel
in the CFG delta. Keep it on Turbo at g = 0 (which is what the published edit LoRAs
target anyway). This is an independent diffusers-side reimplementation of the published
mechanism (mechanism credit: ostris / ai-toolkit), not a port.
Two recipes (edit_recipe on the Reference Latents node). ostris_t0 (above) is for
style / reference LoRAs. edit_frame is the identity / instruction edit method - sources
prepended on the target grid at frame 1..N, shared timestep - placed with the krea2edit v1.2
fit geometry (Oct 2026; it previously stretched mismatched aspect ratios) and active on the
stage whose grid it was encoded for. For the Krea 2 Identity Edit LoRA use the dedicated
Edit node instead - it adds the grounded instruction encode,
ref_boost and the trained negative.
Load Image -> (depth / pose / canny preprocessor) -> Eric Krea2 Control -> (control) Multi-Stage Ultra
Krea 2 "ControlNet" checkpoints are Control-LoRAs: the DiT input projection is expanded
from 64 to 128 channels ([noisy patches ; control patches], trained weights in the
checkpoint) plus a rank-64 LoRA on every block. The control image is VAE-encoded and enters
clean at every step. Everything is forward hooks for one generation - nothing is merged
into the weights, so it composes with the LoRA stack and never leaks.
Patil/Krea-2-depth-controlnet (trained on Raw, works on Raw
and Turbo, ~1 MP buckets). Put it in your Krea2 LoRA folder; files with control in the
path are listed first. The checkpoint decides the control type - a depth LoRA needs a
depth map.channel_mode grayscale, normalize per_image_minmax, near = white
(invert if your preprocessor gives near = dark). Pose / canny / lineart: rgb, none.--lora-scale); the
expanded input layer is always full. 0 = that stage runs the stock model. Defaults
S1 1.0 / S2 0.5 / S3 0 - structure is set in S1, S3 runs far above the trained size.Load Image (style) -> Eric Krea2 Style Reference -> (style) Multi-Stage Ultra
Transfers a reference's palette, brushwork, texture and rendering language without a LoRA
(port of nkxx188/ComfyUI-Krea2-StyleTransfer). Every styled step runs the model on
[target, reference]: the reference is noised to the target's level along a model-guided
trajectory, and in blocks 7-27 the target attends to the reference's keys/values with
frequency-band reweighting - early it may align to the reference layout, late it can no
longer copy positions (no content leakage) but still pulls style statistics.
preset - recommended locks the original author's low-leakage tuning (custom
widgets ignored); custom exposes them (ref_k_strength, low_scale_end,
high_scale_start/end, adain_strength, ref_value_mix, value_adain_strength,
beta, blocks, trajectory, gamma).style_strength - overall amount; ~1.0 is strong and coherent at 3 MP; 2.0 can
overshoot. s1/s2/s3_strength multiply it per stage; S2/S3 default 0 (S2 refines S1's
styled result at full speed).trajectory - model_pc (original, ~2 x trajectory_steps extra evaluations per
styled stage) or linear (free, weaker).Load Image (+ mask) -> Eric Krea2 Paint -> (paint) Multi-Stage Ultra -> [Paint Composite]
\-> vlm_image -> Eric Krea2 Vision Prompt (image1, picture_n) -> prompt_conditioning
Implements the yijunwang2 AnyPaint / Outpaint functional adapters on our model:
Settings:
adapter - anypaint (arbitrary masks, inpaint + outpaint, one pass; put
krea2_anypaint_rank32 on the LoRA stack, S1 = 1, S2/S3 = 0), outpaint (older,
rectangular only), none (training-free: only pins the kept region - fine for small
inpaints). Krea 2 Turbo, 8 steps, guidance 0.pad_left/right/top/bottom
add outpaint canvas. seam_px (32) is regenerated around the mask so it blends.restore_s1/s2/s3 - on pins kept regions every step, structure pins while sigma >
structure_release_sigma (0.4) then frees the low-noise detail steps, auto = on when
the source has the stage's resolution else structure, off lets the stage rewrite.
Defaults on / auto / auto keep identity through S2/S3 without forcing upsampled blur.adapter_s1/s2/s3 - adapter conditioning per stage (default S1 only; trained at
<= 1024 px targets).s1_megapixels unless width/height are set;
crop_bottom is disabled for paint runs.Load Image -> Eric Krea2 Edit (instruction) -> (edit) Multi-Stage Ultra
Multi-LoRA Stack: krea2_identity_edit_v1_2 S1 = 1.0, S2 = 0, S3 = 0
Instruction editing - recolor, restyle, re-pose, add / replace / remove objects, outpaint,
try-on, person-into-scene - with the Krea 2 Identity Edit LoRA
(conradlocke/krea2-identity-edit, v1.2; full or the near-identical r128 / r64 files).
Two conditioning paths, exactly as the LoRA was trained:
[text | source (frame 1) | source_b (frame 2) | target (frame 0)], shared timestep;Settings:
fit_mode - fit (v1.2 training geometry: AR-preserving resample onto the target
grid at a fractional centered offset, any output aspect; byte-identical to krea2edit
v1.2.5) or crop (legacy) for v1 / v1.1 weights.ref_boost - reference-fidelity dial: multiplies target -> reference attention
(1 = off; ~4 strong likeness; >10 breaks removals; <1 loosens). Applies to the last
reference (the subject in two-reference edits); ref_boost_a is the scene's dial;
ref_boost_mask limits the boost to a region of the last reference (e.g. a face).
In tests ref_boost 4 kept the source's silhouette closer (a long coat stayed long when
recoloured).grounding_px - longest side the VLM sees (trained 384-768, default 768): lower =
stronger instruction adherence, higher = stronger likeness; lower it if subjects duplicate.size_from - source: Stage 1 takes the source aspect at s1_megapixels (Ultra
width/height still win); ultra settings: Ultra decides and fit handles the mismatch
(wide outpaints).ground_negative - with CFG on, the negative is the empty instruction grounded on
the same image - the trained unconditional.source_image_b - second reference (the subject) for person-into-scene; place two
people in ONE pass rather than chaining edits.Recipe notes (model card + our tests):
prompt text - describe
the edited image there; empty prompt = they reuse the grounded instruction.s1_cfg 2.0 - Krea's g, CFG = 1 + g) with ground_negative on; in our test even that
removed both people for "remove the person in the background". Word removals by what to
keep.crop_bottom is disabled for edit runs; with prompt_conditioning also connected, the
edit's grounded conditioning wins (printed).Eric Krea2 Negative Guidance -> (guidance) Multi-Stage Ultra
Both are off by default, both work at guidance 0 (Turbo), and they can be combined
with each other and with an edit. Ultra's negative_prompt stays the CFG negative.
NAG - Normalized Attention Guidance. A negative text stream (nag_negative) runs
through the blocks next to the positive one. For the image queries the attention output is
pushed away from the negative and renormalised:
z = z+ + phi (z+ - z-), L1 ratio clamped to tau, blended alpha into the positive.
Text and edit-source tokens keep their positive attention.
nag_phi 4.0, nag_tau 2.5, nag_alpha 0.25 (the published defaults),
nag_stages s1 / s1_s2 / all, nag_sigma_start/end limit it to a sigma window.NegPiP. Write (phrase:-1.0) in Ultra's prompt or the Edit instruction: that phrase's
attention values are multiplied by its weight inside the joint blocks, so a negative
weight subtracts the concept instead of adding it.
negpip_mode - in_place (default; the phrase stays where it is, its tokens are flagged -
cleanest in tests) or lifted (the phrase is removed and encoded on its own, appended).negpip_strength multiplies every negative weight; negpip_block_start/end limit the
blocks; negpip_text_fusion also flips inside the text-fusion attention (stronger).prompt_conditioning (Vision Prompt) the text can't be parsed - put the
groups in Ultra's prompt instead. Cost ~0.Using both on the same concept over-suppressed in tests (dark patches) - pick one per concept.
All three features (edit sources + ref_boost, NAG, NegPiP) share one exact attention core: keys are attended group by group and merged by log-sum-exp, so ref_boost needs no dense L x L bias (which would force slow SDPA and run out of memory at 3 MP) and NAG's positive and negative passes share the expensive image attention. Verified against dense reference implementations (docs/tools/test_edit_guidance_math.py).
Component Loader → compute (bf16 default | native) and native_format
(keep | int8 | mxfp8 | nvfp4), both appended.
bf16 dequantizes every checkpoint to bf16 (best image quality). native re-quantizes the
28 joint blocks' 224 Linear layers after loading and runs them on ComfyUI's comfy_kitchen
tensor-core kernels - the same path ComfyUI core uses; everything else stays bf16.
keep uses the checkpoint's own format (INT8 → int8-ConvRot when the file is rotated,
MXFP8, NVFP4, fp8); a bf16 / GGUF source falls back to mxfp8. Explicit int8 / mxfp8 /
nvfp4 quantize any source on load. NVFP4 uses a dynamic per-call activation scale.precision bf16 and a CUDA device.Measured, RTX PRO 5000, Ultra S1-only 3 MP, 8 steps:
checkpoint (keep →) | bf16 s/step / VRAM | native s/step / VRAM |
|---|---|---|
| INT8-ConvRot (int8_convrot) | 2.9 / 34.8 GB | 2.0 / 22.9 GB |
| same + a style LoRA | 3.1 / 35.3 GB | 2.2 / 22.9 GB |
| MXFP8 (mxfp8) | 2.9 / 35.0 GB | 2.1 / 23.3 GB |
| fp8-scaled (fp8) | 2.9 / 35.1 GB | 2.0 / 22.9 GB |
Headless bench (same card): nvfp4 1.75 s/step (1.67x). The gain shrinks at 8 MP, where attention (untouched by quantization) dominates the step.
Single-file transformers are dequantized on load (on the GPU): fp8 (bare / scaled),
INT8 and INT8-ConvRot (group-wise Hadamard un-rotation), and - through
comfy_kitchen's own layouts, mirroring comfy/ops.py - MXFP8, NVFP4,
ConvRot-W4A4, W4A8 and W6A8. GGUF loads as before (dequantize on load).
docs/tools/krea2_checkpoint_inspector.py reports any file's format and whether it loads,
without loading it. Note: a file's name is not proof of its format - one "INT8-ConvRot"
download in testing was actually bf16 (the loader logs what it found).
The Qwen-Image VAE leaves a faint fixed-phase 2-pixel grid in decoded images (strongest in
flat / dark areas), and the spacepxl 2x upscale VAE builds its output with a 2x2
pixel_shuffle. When an inter-stage VAE hop decodes, upsamples and re-encodes, that lattice
is fed into the next stage, which can develop it into a weave-like texture. DeGrid is an
exact 2-pixel notch filter (filter core from lunaaispace-eng/ComfyUI-DeGrid), amplitude-
limited so real edges pass, and an image with no detected lattice is left untouched.
mode auto / manual (limit),
skip_when_clean, and a removed_grid preview (x grid_gain) + report. Put it straight
after a decode, before sharpening / resizing.degrid toggle on Upscale Decode (2x) and VAE Decode (appended).degrid (appended): hops cleans the inter-stage VAE upscale before re-encoding
(no effect on plain latent hops - they have no pixel step), final cleans the decoded
output, hops+final both. The console prints the measured grid amplitude per pass.ERIC_LORA_CATALOG, else video_prompter's config,
else L:/Models/loras/_lora_catalog.sqlite; a missing catalog just means fewer fields.suggestions socket on the Multi-LoRA Stack - LoRAs picked by the LoRA Suggester
(video_prompter) are added after the panel's own slots with their per-stage weights and
trigger words; a file already in the stack is not added twice.Krea 2's two checkpoints suit two different paths:
Turbo → fast 4k (no re-denoise). Turbo is distilled (8 steps, guidance 0) and resists partial re-denoise, but the 2× decode sidesteps that entirely:
Loader (Krea-2-Turbo) → Generate (2048², auto) → [Upscale VAE Loader] → Upscale Decode 2× → 4096²
Raw → controlled high-res (multi-stage). Raw keeps the full-CFG, resolution-aware trajectory that partial re-denoise needs:
Loader (Krea-2-Raw) → Multi-Stage Ultra (1024² → 2× → 2×) → 4k image (+ optional Upscale Decode 2× → 8k-class)
On the Multi-Stage Ultra node, upscale_vae_mode (requires upscale_vae connected)
governs the S2→S3 jump and the final decode. Each transition can be a plain
2× VAE step (real resolution gain, 4× area) or a downsample variant that keeps the
upscale decoder's sharp/GAN-trained detail but resamples down to your chosen size:
| Mode | S2→S3 | Final image |
|---|---|---|
disabled | bislerp latent resize | decode_vae (or the base Qwen VAE if none connected) |
s2-s3 | upscale VAE 2× (4× area; ignores upscale_to_stage3) | decode_vae / base |
s2-s3 with downsample | upscale VAE 2× → downsample to upscale_to_stage3 | decode_vae / base |
final decode | bislerp latent resize | upscale VAE 2× |
final decode with downsample | bislerp latent resize | upscale VAE 2× → downsample to native |
both | upscale VAE 2× (4× area) | upscale VAE 2× |
both with downsample | upscale VAE 2× → downsample | upscale VAE 2× → downsample to native |
both with final decode downsample | upscale VAE 2× (4× area) | upscale VAE 2× → downsample to native |
Recommended: prefer the
… with downsamplevariants. In practice the upscale VAE decoded at 2× then resampled down is cleaner and sharper than the Wan 2.1 VAE at the same output size - you get its detail without the literal 4× area blow-up (and without the re-encode softening compounding across stages). The plains2-s3/bothmodes force 4× area and ignoreupscale_to_stage3, which is the usual cause of a run ballooning to 20 MP+; the downsample variants respect your numeric factor instead.
The old inter_stage / final_decode values still load (aliased to s2-s3 /
final decode) so existing graphs keep working.
S1→S2 has its own switch. s1_s2_upscale_vae (a separate boolean) routes the
first jump through the upscale VAE and forces 2× (4× area), overriding
upscale_to_stage2. It's deliberately not in the dropdown - using the VAE that early is
a specialist move (the re-encode softening gets refined away by S2/S3). Combining it
with a both … mode is what cascades to enormous final sizes - watch the on-node
resolution chain readout, which shows the real S1→S2→S3→decode sizes and flags every
field the VAE is overriding.
decode_vae is ignored outright for the final image whenever the mode does a VAE
final decode (final decode* or both*) - not blended, not overridden, simply not
passed to that call at all. It still governs the stage preview images
(preview_stages=True → stage1_image/stage2_image) regardless of what the final
image uses, since previews always go through standard_decode(..., decode_vae=decode_vae)
independent of upscale_vae_mode. So: want the upscale VAE for your final image but a
specific grain/texture VAE for previews? Keep both connected - they don't conflict.
Want the upscale VAE and don't care about previews? decode_vae can stay disconnected
with no effect either way.
Two ways to get the downsample quality pass on the final decode. The mode's
… final decode downsample variants request it per-run; the Upscale VAE Loader's own
downsample_to_1x toggle bakes it into the loaded VAE for every consumer (including
the standalone Upscale Decode node). Either enables the same thing - decode at 2× then
Lanczos-downsample back to native, a supersampling-style pass rather than a literal
resolution gain. blur_sigma=0 is a good default (Lanczos already anti-aliases); raise
it only as a taste knob. Inter-stage (S2→S3) downsampling reads the mode flags, not the
loader boolean.
upscale_renorm)Latent interpolation is a lowpass: every upscale hop shrinks latent variance,
and decoded variance is contrast/saturation - so multi-hop runs compound a
little drain per hop into progressive flattening and desaturation.
upscale_renorm repairs the statistics right after each hop:
per_channel (recommended) - re-match each latent channel's mean/std to
the pre-hop latent; strongest color + contrast hold.global - overall mean/std only.off - previous behavior.A telemetry line prints latent std pre-hop / post-hop / post-renorm in every mode, so the drain (and the repair) is measurable per run.
Turbo is distilled for guidance 0, so most wrappers give you no CFG - and therefore no
negative prompt - on the Turbo checkpoint. Multi-Stage Ultra re-enables it. The
turbo_guidance dropdown decides where classifier-free guidance (and the negative pass
it needs) is allowed on a distilled model:
turbo_guidance | S1 | S2 | S3 |
|---|---|---|---|
off (default) | g = 0 | g = 0 | g = 0 |
s1_only | uses s1_cfg | forced g = 0 | forced g = 0 |
all_stages | s1_cfg | s2_cfg | s3_cfg |
g, where standard CFG = 1 + g (g=0 → CFG 1.0,
g=0.2 → CFG 1.2). Turbo was distilled for g=0, so keep it low (~0.1-0.3); the node
warns above g=1.5 (Raw-level, over-saturates Turbo).g > 0. Under off it is inert.s1_only exists: put guidance + negatives on the composition, then let
S2/S3 refine fast and single-pass (it force-zeros s2_cfg/s3_cfg for you - you don't
set them yourself).Using a real negative prompt on a distilled/Turbo checkpoint at all is unusual - most Turbo pipelines simply can't feed one.
For negatives without a second pass, see NAG / NegPiP - both work at g = 0.
A fine tune's preferred sampler, scheduler, step count, mu and cfg tolerance are all proxies for one variable - how far its training eroded the turbo distillation. The sweep system turns that from folklore into measurement: characterize a model in one queue item, keep the evidence, promote the winners to presets.
Wiring: Eric Krea2 Sweep Plan → Ultra V2's sweep input (last socket).
The Ultra panel is the base recipe; each cell overrides only its swept keys.
All existing machinery (LoRA stack, cond rebalance, ref latents, telemetry,
renorm) runs untouched per cell.
Grid mode: fill any of the axis fields - samplers, schedulers
(pair_lock zips them into fixed pairs), steps, windows (5-12 →
start/end step), etas, noise_types, cfgs, shift_modes/mus,
hybrid_steps, megapixels - blank = not swept (panel value used). The
schedulers field takes built-in schedules AND saved sigma-shape ★ preset
names mixed freely (each entry resolves as a schedule first, then as a
sigmas preset applied as that cell's full profile; unknown names are
skipped with a console warning, never an abort), and comes pre-populated
with everything available - delete what you don't want. Full cross product,
hard-refused over max_combos with an axis-size breakdown. Cells that differ
only by inert knobs (eta/noise on euler/lcm) are deduped automatically.
Combos mode: one JSON object per line in combos_json, or a file via
combos_file (JSON array, {"combos": [...]}, or JSON-lines) - keys are the
same widget keys as presets and PNG recipes, so combos are copy-pasteable
from any stamped image. Sweep campaigns become versionable files.
Workflow intent: quick_screen forces S1-only at screen_megapixels for
cheap wide grids - perfect Stage 1 first, then sweep stage_scope=s2/s3
refinement on the short list. For s2/s3-only sweeps the post-S1 latent is
computed once and reused across cells (s1_reused in the manifest;
automatically disabled per cell for anything that changes Stage 1, and
globally under seed_mode=same_all_stages).
Outputs (to output/sweeps/<timestamp>_<finetune>/, or output_folder):
cell_NNN_<values>.png - every cell at full res with the complete resolved
recipe (ultra + loader + lora sections) embedded in a
krea2_settings chunk - each file is standalone-reproducible.contact_sheet.png - downscaled overview (tile_px tiles), captions show
only the diffs vs base, green line = per-cell generation time + scores.sweep_summary.csv - one row per cell: swept columns, gen_time_s,
rounded scores - sortable in any spreadsheet.sweep_manifest.json - full resolved recipes, timings, metrics, errors.Scores (optional, CPU, milliseconds - failure detectors, not beauty
judges): Laplacian + Tenengrad sharpness, wavelet noise sigma, flat-region
chroma variance, clip fraction. All land in the CSV/manifest; sort_by
pre-sorts the sheet; scores never hide a cell - the eye stays the judge.
Field calibration (two full 192-cell characterization runs, 2026-07-29):
clip% is the best bad-image predictor - above 3-4% suspect, above 6%
almost always bad (the sheet flags C4.2%! / C7.1%!! at exactly those
absolute thresholds, and Auto Pick's gates use them). sharp_ten
(Tenengrad) proved more trustworthy than Laplacian - it is the sharpness
shown on the sheet and gated by Auto Pick - though neither is immune to one
strong edge dominating; subject/tiled sharpness via the external scores.csv
route is the real answer there. noise sigma and splotch showed no
quality discrimination in the field - they remain CSV columns but gate
nothing and no longer appear on the sheet.
Sheet captions are stage-grouped shorthand - one line per swept stage
(s1: 2.5mp res_2m+beta57 h7 e0.3), ★profile / seed / prompt on a trailing
line - plus a compact metric line: T88s S11.3k C0.5% N1.0 U159
(T time, S sharp_ten/1000, C clip% with the !/!! flags, N noise, U
uniqueness).
Uniqueness (model-free, automatic): every cell gets a composition-uniqueness score - its mean distance from the other cells' 64x64 luma thumbnails, grouped per (prompt, S1 megapixels). READ THE DIRECTION BY EXPERIMENT TYPE: in a fixed-seed SETTINGS sweep, high uniqueness means "deviates from the consensus" and broken cells deviate hardest - the LOW end is the consensus render and the high end is an outlier list; in a SEED sweep, divergence is the point and high = more compositional variety. Auto Pick has an objective for each direction.
Promotion: Eric Krea2 Sweep → Preset reads a manifest cell into
ultra_presets.json (swept keys only, or the full recipe), auto-tagged with
the checkpoint name and an objective note - per-fine-tune preset libraries
by construction.
LoRA, prompt & sigma-profile axes (sweep v2):
lora_mode=bakeoff) - one LoRA per line in
lora_files (loras-folder names or full paths) x lora_strengths
(one value drives all three stage weights). Default: each swept LoRA runs
ALONE, so every style is measured against the bare checkpoint on equal
footing; keep_panel_stack layers it on top of your declared stack
instead. include_baseline adds the reference cell (no-LoRA, or the
panel stack alone when layering). Sweep-injected entries are ephemeral -
fused per cell, cleaned per cell, nothing persists.lora_mode=strength_ladder) - keeps the
panel-declared stack and steps only the lora_target entry (1-based
index, or a name substring) through lora_strengths.prompts; each prompt cell
re-encodes (conditioning cleared automatically, ~seconds/cell). Prompts
expand as the SLOWEST axis, so the contact sheet and CSV read in
prompt-major blocks - metric comparisons are only meaningful within a
block.sigma_profiles takes saved ★ preset NAMES from
the Eric Krea2 Sigmas node (validated at plan time); each cell rebuilds
the full bundle from that preset, overriding any wired sigmas node for
that cell.lora_triggers, default append) - each bake-off
cell merges its swept LoRA''s trigger words (from the stack node''s cached
trigger database) into that cell''s prompt, so trigger-dependent styles are
measured fully activated. Only sweep-injected entries contribute; baseline
and ladder cells are untouched; a changed prompt re-encodes automatically;
the effective prompt + triggers land in the cell''s metadata.All v2 axes cross with every classic axis, in grid mode AND on top of explicit combos, under the same cap and dedupe rules. LoRA/prompt/profile cells always run a full Stage 1 (S1-latent reuse correctly sits out). Each cell PNG records the ACTUAL stack, bundle, and prompt that cell ran - not the panel's - so every file stays a complete standalone recipe.
Failed cells never kill a sweep (red tile + manifest error), and interrupts finalize the files on disk before stopping the queue item.
Auto Pick: Eric Krea2 Sweep Auto Pick closes the loop from sweep to
preset: manifest in, cell_index + a human-readable report out. Objectives:
fastest_acceptable (fastest cell passing the field-calibrated gates:
clip% ABSOLUTE - reject above 6%, flag 4-6% as suspect-but-passing;
sharp_ten relative to the sweep median or an eye-picked reference_cell
with tolerance slack; and a uniqueness consensus-outlier gate - cells far
above the reference are rejected as deviants, with 2x tolerance so style
variation passes), most_unique (highest composition-uniqueness - the SEED
sweep objective; recomputed from cell PNGs for older manifests),
most_typical (LOWEST uniqueness - the consensus render, the right pick in
settings sweeps where high uniqueness flags broken outliers), best_metric
(any built-in column), and best_external (any column of a scores.csv in
the sweep folder, joined by filename - blank metric = first numeric column).
Wire cell_index into Sweep -> Preset (convert its widget to an input) and
one queue runs sweep -> pick -> promote. The picker proposes and explains
its choice with runners-up; promotion only happens because you queued the
preset node - metrics never silently write your preset library.
Folder scoring chain: the Eric Sweep Folder Scorer node (in the
Eric-image-classification package) consumes the manifest path and grades
every cell with the analyzer suite - Blur V7, Noise V4, composition,
exposure, UniPercept (with a device picker for the second GPU) - and
writes/merges scores.csv in the sweep folder, one column per numeric
output (comp.composition_score, blur7.variance, ...). Merging is by
filename, so multiple grading passes stack columns instead of clobbering.
The full hands-off chain is: Ultra V2 sweep_manifest -> Krea2 Unload
(frees the generator's VRAM; its wildcard passthrough keeps the ordering) ->
Sweep Folder Scorer -> Auto Pick (best_external) -> Sweep -> Preset:
one queue from characterization to a machine-proposed, human-ratified
preset.
Sweep presets, the toggle & notes: the Sweep Plan node carries an
enabled switch (off = the wired node is inert and normal generation runs)
and a sweep_preset dropdown backed by sweep_presets.json. Selecting a
preset WRITES its values into the panel - you always see exactly what will
run - and editing any field flips the dropdown back to custom; the ★ Save
Preset button saves the panel under a new name. Headless/API runs apply the
named preset as the sole source. Both the Sweep Plan and Sigmas nodes carry
a preset_notes field saved with each ★ preset - one sentence on what the
preset is FOR - written into the panel on select and printed by headless
runs, so preset libraries stay self-documenting.
Swept schedules vs a wired sigmas bundle: a cell that explicitly sweeps
a stage's schedule disables the wired bundle for that stage, cell-locally -
a swept axis is never silently inert (the bundle previously overrode swept
schedules, which produced identical cells and only a warning). Unswept
stages keep the bundle; sigma_profiles cells replace it entirely; each
cell's PNG chunk records what actually applied.
AutoencoderKLQwenImage (16-channel, f8), identical
to Qwen-Image and Wan2.1 - which is why the spacepxl 2× decoder is a drop-in.expansion.txt and point the Magic
Prompt node's system_prompt_path at it.flash_varlen backend assumes the
valid keys are a prefix; Krea 2 pads text in the middle of [text | image], so with
attention_backend=auto every generation attended to padding and dropped the bottom image
rows (the bottom band crop_bottom was hiding, plus weaker prompt adherence). All Krea 2
attention now drops padded keys explicitly before the kernel - same speed as before, matches
SDPA. Existing seeds render slightly differently (correctly to the edge); crop_bottom
is no longer needed - it now defaults to 0 and crop_overgen to off, and the shipped Ultra
presets were reset to match (saved workflows keep whatever they stored).
Side effect worth knowing: the old path diluted every prompt with ~400 padding tokens, so the
prompt (and text-side LoRAs) now act at full strength - same image quality, noticeably
stronger prompt / style adherence (e.g. a style that implies nudes now gets them more often).
For A/B comparisons, set ERIC_KREA2_MASK_SAFE=0 before ComfyUI starts restores the old
behaviour (console prints a DIAGNOSTIC line; use crop_bottom).prompt: N/507 tokens every run and a warning with the dropped words when a prompt
overflows - keep LLM-expanded prompts under ~380 English words. (Vision Prompt checks its own
budget and errors instead.)
Trigger words are protected: with add_triggers on (LoRA / Multi-LoRA Stack, and sweep cells),
the merge counts tokens and, when prompt + triggers would overflow, shortens the prompt body
(sentences just before the last one go first) so the triggers are never the part that is cut.
A trigger only counts as already present on a whole-word match (rust is not in rusted).diffusion_model.blocks.N.attn.wq...) used to load with 0
modules applied, so the LoRA silently did nothing. They are now remapped, injected with the
file's own Kronecker factor, and scaled by ComfyUI's LoKr rule (full w1/w2 = strength).TextEncodeQwenImageEditPlus for this
wastes a silently-discarded reference latent and uses the wrong prompt template.
This is an independent implementation built directly against the installed
diffusers/transformers source, not a port of that node's code.transformer_krea2.py, not a port.Patil/Krea-2-depth-controlnet) and the
facok/comfyui-krea2-controlnet port;
reimplemented for the diffusers transformer.comfy_kitchen kernels and layouts.These nodes are an independent implementation; no code is copied from Krea or spacepxl repos. Where a mechanism was ported from a permissively licensed project (Apache-2.0 / MIT, listed above), the module header carries the attribution.