
This repository introduce a comprehensive paper list, datasets, methods and tools for memory research.
354
53 commits
updated Dec 29, 2025
README
Memory Compass
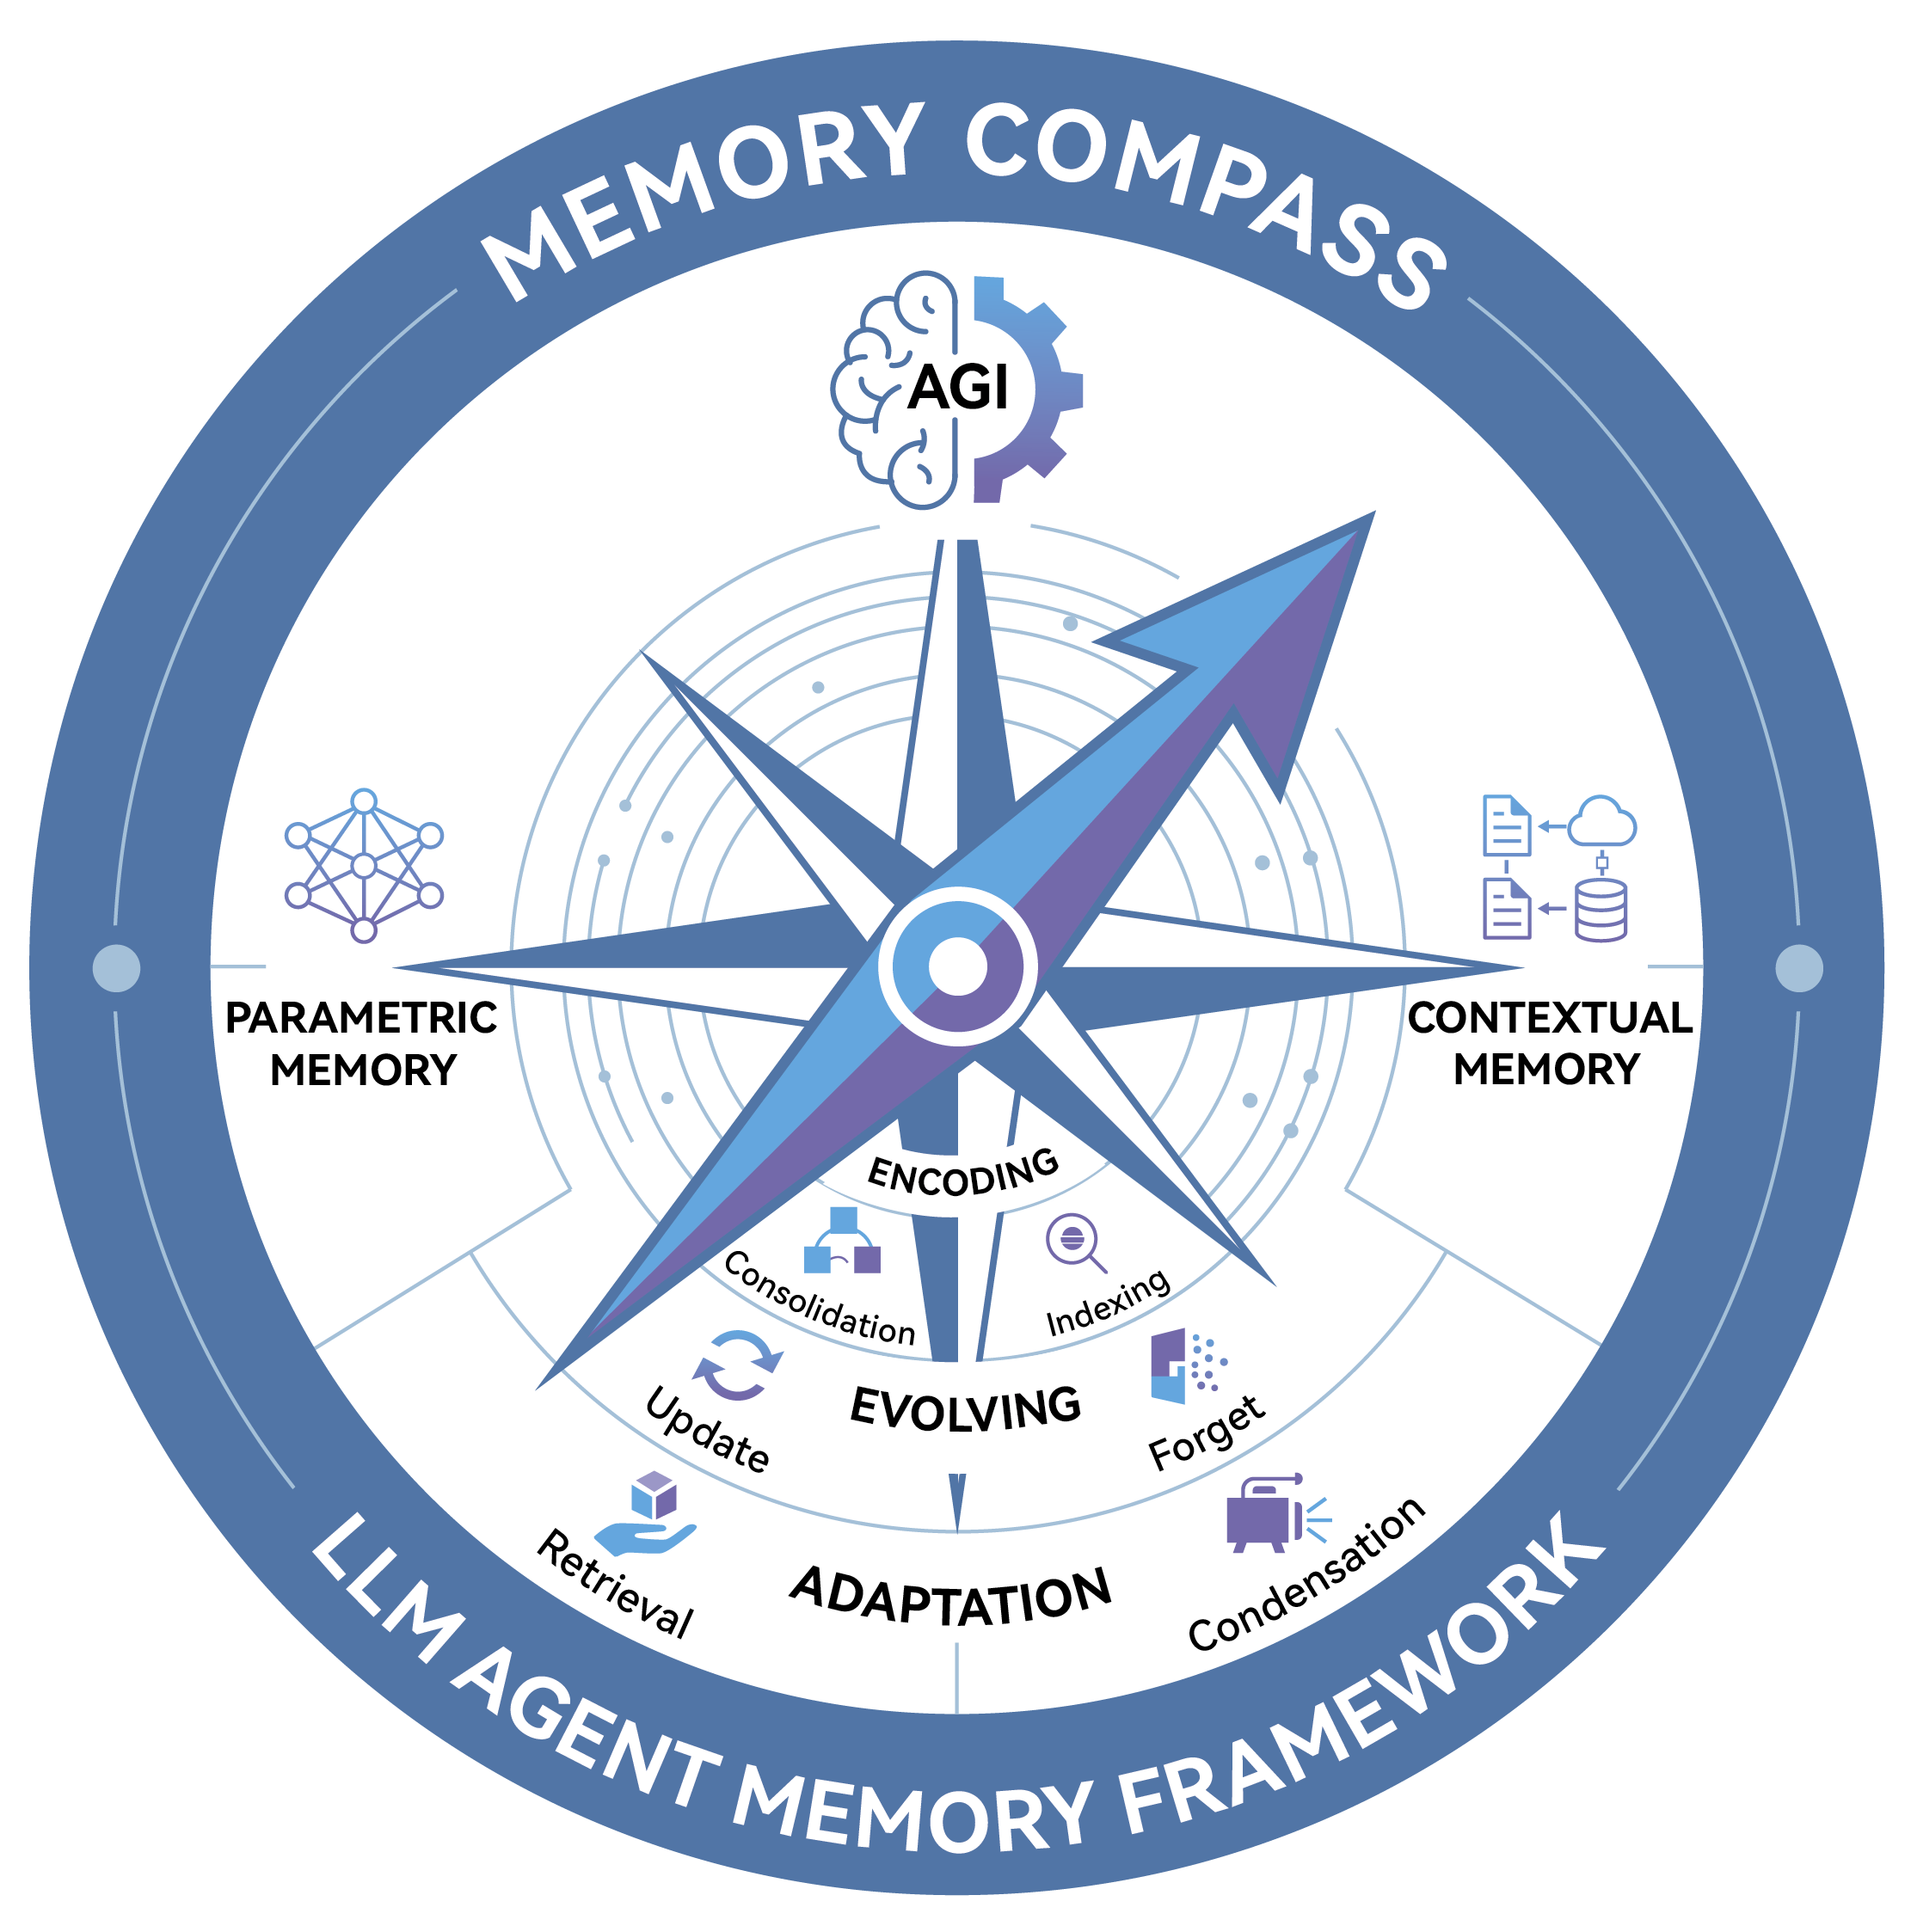
Rethinking Memory in AI: Taxonomy, Operations, Topics, and Future Directions


This repository introduce a comprehensive paper list, datasets, methods and tools for memory research.
Contents
- Rethinking Memory in AI: Taxonomy, Operations, Topics, and Future Directions
📢 News
- 🚀 Memory-T1 Released! We propose a new RL method designed for temporal reasoning and long-term memory in large language models. Memory-T1 focuses on multi-session interactions and realistic temporal dependencies, enabling systematic evaluation of memory-aware agents.
- Version 3 is availabel!
- Paper List, benchmarks and tools has been udpated.
- Version 2 of our work is now available.
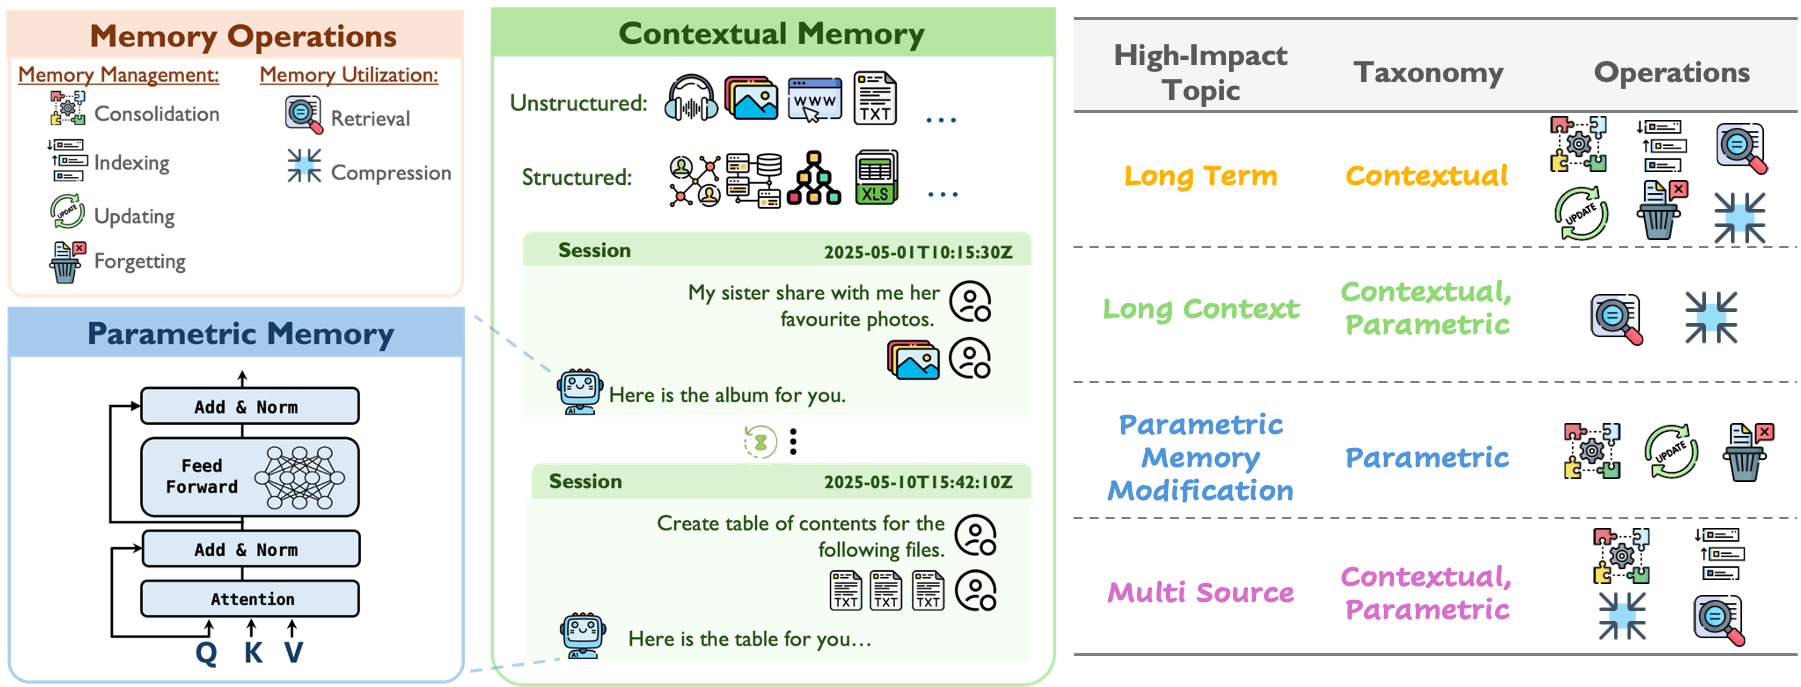
Memory Taxonomy
📜 Papers
1. Survey Papers
2025
-
Memory in the Age of AI Agents Yuyang Hu, Shichun Liu, Yanwei Yue, Guibin Zhang, Boyang Liu, Fangyi Zhu, Jiahang Lin, Honglin Guo, Shihan Dou, Zhiheng Xi, Senjie Jin, Jiejun Tan, Yanbin Yin, Jiongnan Liu, Zeyu Zhang, Zhongxiang Sun, Yutao Zhu, Hao Sun, Boci Peng, Zhenrong Cheng, Xuanbo Fan, Jiaxin Guo, Xinlei Yu, Zhenhong Zhou, Zewen Hu, Jiahao Huo, Junhao Wang, Yuwei Niu, Yu Wang, Zhenfei Yin, Xiaobin Hu, Yue Liao, Qiankun Li, Kun Wang, Wangchunshu Zhou, Yixin Liu, Dawei Cheng, Qi Zhang, Tao Gui, Shirui Pan, Yan Zhang, Philip Torr, Zhicheng Dou, Ji-Rong Wen, Xuanjing Huang, Yu-Gang Jiang, Shuicheng Yan. Arxiv 2025.
-
A Comprehensive Survey of Machine Unlearning Techniques for Large Language Models Jiahui Geng, Qing Li, Herbert Woisetschlaeger, Zongxiong Chen, Yuxia Wang, Preslav Nakov, Hans-Arno Jacobsen, Fakhri Karray. Arxiv 2025.
-
A Comprehensive Survey on Long Context Language Modeling Jiaheng Liu, Dawei Zhu, Zhiqi Bai, Yancheng He, Huanxuan Liao, Haoran Que, Zekun Wang, Chenchen Zhang, Ge Zhang, Jiebin Zhang, Yuanxing Zhang, Zhuo Chen, Hangyu Guo, Shilong Li, Ziqiang Liu, Yong Shan, Yifan Song, Jiayi Tian, Wenhao Wu, Zhejian Zhou, Ruijie Zhu, Junlan Feng, Yang Gao, Shizhu He, Zhoujun Li, Tianyu Liu, Fanyu Meng, Wenbo Su, Yingshui Tan, Zili Wang, Jian Yang, Wei Ye, Bo Zheng, Wangchunshu Zhou, Wenhao Huang, Sujian Li, Zhaoxiang Zhang Arxiv 2025.
-
A Survey of Personalized Large Language Models: Progress and Future Directions Jiahong Liu, Zexuan Qiu, Zhongyang Li, Quanyu Dai, Jieming Zhu, Minda Hu, Menglin Yang, Irwin King. Arxiv 2025.
-
Prompt Compression for Large Language Models: A Survey Zongqian Li, Yinhong Liu, Yixuan Su, Nigel Collier NAACL 2025.
-
Cognitive Memory in Large Language Models Lianlei Shan, Shixian Luo, Zezhou Zhu, Yu Yuan, Yong Wu. Arxiv 2025.
-
Human-inspired Perspectives: A Survey on AI Long-term Memory Zihong He, Weizhe Lin, Hao Zheng, Fan Zhang, Matt W. Jones, Laurence Aitchison, Xuhai Xu, Miao Liu, Per Ola Kristensson, Junxiao Shen. Arxiv 2025.
2024
-
Knowledge Conflicts for LLMs: A Survey Rongwu Xu, Zehan Qi, Zhijiang Guo, Cunxiang Wang, Hongru Wang, Yue Zhang, Wei Xu. EMNLP 2024.
-
A Survey on the Memory Mechanism of Large Language Model based Agents. Zhang, Zeyu and Bo, Xiaohe and Ma, Chen and Li, Rui and Chen, Xu and Dai, Quanyu and Zhu, Jieming and Dong, Zhenhua and Wen, Ji-Rong. Arxiv 2024.
-
Knowledge Editing for Large Language Models: A Survey Song Wang, Yaochen Zhu, Haochen Liu, Zaiyi Zheng, Chen Chen, Jundong Li. Arxiv 2024.
-
Advancing Transformer Architecture in Long-Context Large Language Models: A Comprehensive Survey Yunpeng Huang, Jingwei Xu, Junyu Lai, Zixu Jiang, Taolue Chen, Zenan Li, Yuan Yao, Xiaoxing Ma, Lijuan Yang, Hao Chen, Shupeng Li, Penghao Zhao. Arxiv 2024.
2. Memory Topics
2.1 Long Term Memory
2025
-
PersonaMem-v2: Towards Personalized Intelligence via Learning Implicit User Personas and Agentic Memory Bowen Jiang, Yuan Yuan, Maohao Shen, Zhuoqun Hao, Zhangchen Xu, Zichen Chen, Zijun Liu, Anirudh Ravi Vijjini, Jiaming He, and others. Arxiv 2025.
-
O-Mem: Omni Memory System for Personalized, Long Horizon, Self-Evolving Agents Piaohong Wang, Motong Tian, Jiaxian Li, Yuan Liang, Yuqing Wang, Qianben Chen, Tiannan Wang, Zhicong Lu, Jiawei Ma, Yuchen Eleanor Jiang, Wangchunshu Zhou. Arxiv 2025.
-
MemoryBench: A Benchmark for Memory and Continual Learning in LLM Systems Yifan Song, Weimin Xiong, Dawei Zhu, Cheng Li, Ke Wang, and others. Arxiv 2025.
-
Agent Learning via Early Experience Kai Zhang, Xiangchao Chen, Bo Liu, Tianci Xue, Zeyi Liao, Zhihan Liu, Xiyao Wang, Yuting Ning, Zhaorun Chen, Xiaohan Fu, and others. Arxiv 2025.
-
G-Memory: Tracing Hierarchical Memory for Multi-Agent Systems Guibin Zhang, Muxin Fu, Guancheng Wan, Miao Yu, Kun Wang, Shuicheng Yan. Arxiv 2025.
-
HaluMem: Evaluating Hallucinations in Memory Systems of Agents Ding Chen, Simin Niu, Kehang Li, Peng Liu, Xiangping Zheng, Bo Tang, Xinchi Li, Feiyu Xiong, Zhiyu Li. Arxiv 2025.
-
MemAgent: Reshaping Long-Context LLM with Multi-Conv RL-based Memory Agent Hongli Yu, Tinghong Chen, Jiangtao Feng, Jiangjie Chen, Weinan Dai, Qiying Yu, Ya-Qin Zhang, Wei-Ying Ma, Jingjing Liu, Mingxuan Wang, and others. Arxiv 2025.
-
Evaluating Memory in LLM Agents via Incremental Multi-Turn Interactions Yuanzhe Hu, Yu Wang, Julian McAuley. Arxiv 2025.
-
Mem0: Building production-ready ai agents with scalable long-term memory Prateek Chhikara, Dev Khant, Saket Aryan, Taranjeet Singh, Deshraj Yadav. Arxiv 2025.
-
MemOS: An Operating System for Memory-Augmented Generation (MAG) in Large Language Models Zhiyu Li, Shichao Song, Hanyu Wang, Simin Niu, Ding Chen, Jiawei Yang, Chenyang Xi, Huayi Lai, Jihao Zhao, Yezhaohui Wang, and others. Arxiv 2025.
-
LightMem: Lightweight and Efficient Memory-Augmented Generation Qingyang Zhang, Ningyu Zhang, and others. Arxiv 2025.
-
Memory OS of AI Agent Jiazheng Kang, Mingming Ji, Zhe Zhao, Ting Bai. Arxiv 2025.
-
MemU: An open-source memory framework for AI companions NevaMind-AI. GitHub 2025.
-
Hierarchical Memory for High-Efficiency Long-Term Reasoning in LLM Agents Haoran Sun, Shaoning Zeng. Arxiv 2025.
-
ReasoningBank: Scaling Agent Self-Evolving with Reasoning Memory Siru Ouyang, Jun Yan, I-Hung Hsu, Yanfei Chen, Ke Jiang, Zifeng Wang, Rujun Han, Long T. Le, Samira Daruki, Xiangru Tang, Vishy Tirumalashetty, George Lee, Mahsan Rofouei, Hangfei Lin, Jiawei Han, Chen-Yu Lee, Tomas Pfister. Arxiv 2025.
-
Agentic Context Engineering: Evolving Contexts for Self-Improving Language Models Qizheng Zhang, Changran Hu, Shubhangi Upasani, Boyuan Ma, Fenglu Hong, Vamsidhar Kamanuru, Jay Rainton, Chen Wu, Mengmeng Ji, Hanchen Li, Urmish Thakker, James Zou, Kunle Olukotun. Arxiv 2025.
-
Coarse-to-Fine Grounded Memory for LLM Agent Planning Wei Yang, Jinwei Xiao, Hongming Zhang, Qingyang Zhang, Yanna Wang, Bo Xu. Arxiv 2025.
-
Chain-of-Memory: Enhancing GUI Agents for Cross-Application Navigation Xinzge Gao, Chuanrui Hu, Bin Chen, Teng Li. Arxiv 2025.
-
MEM1: Learning to Synergize Memory and Reasoning for Efficient Long-Horizon Agents Zijian Zhou, Ao Qu, Zhaoxuan Wu, Sunghwan Kim, Alok Prakash, Daniela Rus, Jinhua Zhao, Bryan Kian Hsiang Low, Paul Pu Liang. Arxiv 2025.
-
Tremu: Towards Neuro-Symbolic Temporal Reasoning for LLM-Agents with Memory in Multi-Session Dialogues Yubin Ge, Salvatore Romeo, Jason Cai, Raphael Shu, Monica Sunkara, Yassine Benajiba, Yi Zhang. Arxiv 2025.
-
Emergence of Episodic Memory in Transformers: Characterizing Changes in Temporal Structure of Attention Scores During Training Deven Mahesh Mistry, Anooshka Bajaj, Yash Aggarwal, Sahaj Singh Maini, Zoran Tiganj. Arxiv 2025.
-
Concept-Reversed Winograd Schema Challenge: Evaluating and Improving Robust Reasoning in Large Language Models via Abstraction Kaiqiao Han, Tianqing Fang, Zhaowei Wang, Yangqiu Song, Mark Steedman. NAACL 2025.
-
Learn to Memorize: Optimizing LLM-based Agents with Adaptive Memory Framework Zeyu Zhang, Quanyu Dai, Rui Li, Xiaohe Bo, Xu Chen, Zhenhua Dong. Arxiv 2025.
-
Memory-R1: Enhancing large language model agents to manage and utilize memories via reinforcement learning Sikuan Yan, Xiufeng Yang, Zuchao Huang, Ercong Nie, Zifeng Ding, Zonggen Li, Xiaowen Ma, Hinrich Schütze, Volker Tresp, Yunpu Ma. Arxiv 2025.
-
Mem-$\alpha$: Learning Memory Construction via Reinforcement Learning Yu Wang, Ryuichi Takanobu, Zhiqi Liang, Yuzhen Mao, Yuanzhe Hu, Julian McAuley, Xiaojian Wu. Arxiv 2025.
-
AgentFly: Fine-tuning LLM Agents without Fine-tuning LLMs Huichi Zhou, Yihang Chen, Siyuan Guo, Xue Yan, Kin Hei Lee, Zihan Wang, Ka Yiu Lee, Guchun Zhang, Kun Shao, Linyi Yang, and others. Arxiv 2025.
-
MemAgent: Reshaping Long-Context LLM with Multi-Conv RL-based Memory Agent Hongli Yu, Tinghong Chen, Jiangtao Feng, Jiangjie Chen, Weinan Dai, Qiying Yu, Ya-Qin Zhang, Wei-Ying Ma, Jingjing Liu, Mingxuan Wang, and others. Arxiv 2025.
-
Evaluating Memory in LLM Agents via Incremental Multi-Turn Interactions Yuanzhe Hu, Yu Wang, Julian McAuley. Arxiv 2025.
-
MemBench: Towards More Comprehensive Evaluation on the Memory of LLM-based Agents Haoran Tan, Zeyu Zhang, Chen Ma, Xu Chen, Quanyu Dai, Zhenhua Dong. Arxiv 2025.
-
MemGuide: Intent-Driven Memory Selection for Goal-Oriented Multi-Session LLM Agents Yiming Du, Bingbing Wang, Yang He, Bin Liang, Baojun Wang, Zhongyang Li, Lin Gui, Jeff Z. Pan, Ruifeng Xu, Kam-Fai Wong. Arxiv 2025.
-
MemTool: Optimizing Short-Term Memory Management for Dynamic Tool Calling in LLM Agent Multi-Turn Conversations Elias Lumer, Anmol Gulati, Vamse Kumar Subbiah, Pradeep Honaganahalli Basavaraju, James A Burke. Arxiv 2025.
-
Memp: Exploring Agent Procedural Memory Runnan Fang, Yuan Liang, Xiaobin Wang, Jialong Wu, Shuofei Qiao, Pengjun Xie, Fei Huang, Huajun Chen, Ningyu Zhang. Arxiv 2025.
-
LongMemEval: Benchmarking Chat Assistants on Long-Term Interactive Memory Di Wu, Hongwei Wang, Wenhao Yu, Yuwei Zhang, Kai-Wei Chang, Dong Yu. ICLR 2025.
-
Compress to Impress: Unleashing the Potential of Compressive Memory in Real-World Long-Term Conversations Nuo Chen, Hongguang Li, Jia Li, Yuxuan Li, Wei Wu. COLING 2025.
-
Towards Lifelong Dialogue Agents via Timeline-based Memory Management Kai Tzu-iunn Ong, Namyoung Kim, Minju Gwak, Hyungjoo Chae, Taeyoon Kwon, Yohan Jo, Seung-won Hwang, Dongha Lee, Jinyoung Yeo. NAACL 2025.
-
Zep: A Temporal Knowledge Graph Architecture for Agent Memory Preston Rasmussen, Daniel Chalef. Arxiv 2025.
-
From RAG to Memory: Non-Parametric Continual Learning for Large Language Models Bernal Jiménez Gutiérrez, Yiheng Shu, Weijian Qi, Sizhe Zhou, Yu Su. ICML 2025.
-
Disentangling Memory and Reasoning Ability in Large Language Models Mingyu Jin, Weidi Luo, Sitao Cheng, Xinyi Wang, Wenyue Hua, Ruixiang Tang, William Yang Wang, Yongfeng Zhang. Arxiv 2025.
-
MemoRAG: Boosting Long Context Processing with Global Memory-Enhanced Retrieval Augmentation Hongjin Qian, Zheng Liu, Peitian Zhang, Kelong Mao, Defu Lian, Zhicheng Dou, Tiejun Huang. Arxiv 2025.
-
Hello Again! LLM-powered Personalized Agent for Long-term Dialogue Hao Li, Chenghao Yang, An Zhang, Yang Deng, Xiang Wang, Tat-Seng Chua. NAACL 2025.
-
MemInsight: Autonomous Memory Augmentation for LLM Agents Rana Salama, Jason Cai, Michelle Yuan, Anna Currey, Monica Sunkara, Yi Zhang, Yassine Benajiba. Arxiv 2025.
-
Interpersonal Memory Matters: A New Task for Proactive Dialogue Utilizing Conversational History Bowen Wu, Wenqing Wang, Haoran Li, Ying Li, Jingsong Yu, Baoxun Wang. Arxiv 2025.
-
Echo: A Large Language Model with Temporal Episodic Memory WenTao Liu, Ruohua Zhang, Aimin Zhou, Feng Gao, JiaLi Liu. Arxiv 2025.
-
Improving Factuality with Explicit Working Memory Mingda Chen, Yang Li, Karthik Padthe, Rulin Shao, Alicia Sun, Luke Zettlemoyer, Gargi Ghosh, Wen-tau Yih. Arxiv 2025.
-
Memorization Over Reasoning? Exposing and Mitigating Verbatim Memorization in Large Language Models' Character Understanding Evaluation Yuxuan Jiang, Francis Ferraro. Arxiv 2025.
-
Self-Memory Alignment: Mitigating Factual Hallucinations with Generalized Improvement Siyuan Zhang, Yichi Zhang, Yinpeng Dong, Hang Su. Arxiv 2025.
-
Needle in the Haystack for Memory Based Large Language Models Elliot Nelson, Georgios Kollias, Payel Das, Subhajit Chaudhury, Soham Dan. ICLR 2025.
2024
-
Evaluating Very Long-Term Conversational Memory of LLM Agents Adyasha Maharana, Dong-Ho Lee, Sergey Tulyakov, Mohit Bansal, Francesco Barbieri, Yuwei Fang. ACL 2024.
-
MemoryBank: Enhancing Large Language Models with Long-Term Memory Wanjun Zhong, Lianghong Guo, Qiqi Gao, He Ye, Yanlin Wang. AAAI 2024.
-
A-MEM: Agentic Memory for LLM Agents Wujiang Xu, Kai Mei, Hang Gao, Juntao Tan, Zujie Liang, Yongfeng Zhang. Arxiv 2024.
-
Optimus-1: Hybrid Multimodal Memory Empowered Agents Excel in Long-Horizon Tasks Zaijing Li, Yuquan Xie, Rui Shao, Gongwei Chen, Dongmei Jiang, Liqiang Nie. NeurIPS 2024.
-
HippoRAG: Neurobiologically Inspired Long-Term Memory for Large Language Models Bernal Jiménez Gutiérrez, Yiheng Shu, Yu Gu, Michihiro Yasunaga, Yu Su. NeurIPS 2024.
-
"My agent understands me better": Integrating Dynamic Human-like Memory Recall and Consolidation in LLM-Based Agents Yu Hou, Tamoto Yuta, Mayur Tikundi. Arxiv 2024.
-
Mr.Steve: Instruction-Following Agents in Minecraft with What-Where-When Memory Yu Hou, Tamoto Yuta, Mayur Tikundi. ICLR 2024.
-
StableSSM: Alleviating the Curse of Memory in State-space Models through Stable Reparameterization Shida Wang, Qianxiao Li. ICML 2024.
-
Crafting Personalized Agents through Retrieval-Augmented Generation on Editable Memory Graphs Zheng Wang, Zhongyang Li, Zeren Jiang, Dandan Tu, Wei Shi. EMNLP 2024.
-
Towards Verifiable Text Generation with Evolving Memory and Self-Reflection Hao Sun, Hengyi Cai, Bo Wang, Yingyan Hou, Xiaochi Wei, Shuaiqiang Wang, Yan Zhang, Dawei Yin. EMNLP 2024.
-
PerLTQA: A Personal Long-Term Memory Dataset for Memory Classification, Retrieval, and Synthesis in Question Answering Yiming Du, Hongru Wang, Zhengyi Zhao, Bin Liang, Baojun Wang, Wanjun Zhong, Zezhong Wang, Kam-Fai Wong. Arxiv 2024.
-
An Iterative Associative Memory Model for Empathetic Response Generation Zhou Yang, Zhaochun Ren, Yufeng Wang, Haizhou Sun, Chao Chen, Xiaofei Zhu, Xiangwen Liao. ACL 2024.
-
COCOA: CBT-based Conversational Counseling Agent Using Memory Specialized in Cognitive Distortions and Dynamic Prompt Suyeon Lee, Jieun Kang, Harim Kim, Kyoung-Mee Chung, Dongha Lee, Jinyoung Yeo. Arxiv 2024.
-
Mixed-Session Conversation with Egocentric Memory Jihyoung Jang, Taeyoung Kim, Hyounghun Kim. EMNLP 2024.
-
FragRel: Exploiting Fragment-level Relations in the External Memory of Large Language Models Xihang Yue, Linchao Zhu, Yi Yang. ACL 2024.
-
Extractive Medical Entity Disambiguation with Memory Mechanism and Memorized Entity Information Guobiao Zhang, Xueping Peng, Tao Shen, Guodong Long, Jiasheng Si, Libo Qin, Wenpeng Lu. EMNLP 2024.
-
Ever-Evolving Memory by Blending and Refining the Past Seo Hyun Kim, Keummin Ka, Yohan Jo, Seung-won Hwang, Dongha Lee, Jinyoung Yeo. Arxiv 2024.
-
Synapse: Trajectory-as-Exemplar Prompting with Memory for Computer Control Longtao Zheng, Rundong Wang, Xinrun Wang, Bo An. Arxiv 2024.
-
Moviechat: From dense token to sparse memory for long video understanding Enxin Song, Wenhao Chai, Guanhong Wang, Yucheng Zhang, Haoyang Zhou, Feiyang Wu, Haozhe Chi, Xun Guo, Tian Ye, Yanting Zhang, Yan Lu, Jenq-Neng Hwang, Gaoang Wang. CVPR 2024.
-
lamp: when large language models meet personalization Alireza Salemi, Sheshera Mysore, Michael Bendersky, Hamed Zamani. ACL 2024.
-
Evidence-Driven Retrieval Augmented Response Generation for Online Misinformation Zhenrui Yue, Huimin Zeng, Yimeng Lu, Lanyu Shang, Yang Zhang, Dong Wang. NAACL 2024.
-
IterCQR: Iterative Conversational Query Reformulation with Retrieval Guidance Yunah Jang, Kang-il Lee, Hyunkyung Bae, Hwanhee Lee, Kyomin Jung. NAACL 2024.
-
Memory Layers at Scale Vincent-Pierre Berges, Barlas Oğuz, Daniel Haziza, Wen-tau Yih, Luke Zettlemoyer, Gargi Ghosh. Arxiv 2024.
2023
-
MoT: Memory-of-Thought Enables ChatGPT to Self-Improve Sureman Lee, Yujie Qian, Yujia Xie, Yifan Hou, Xinyan Wang, Yiming Yang, Xiang Ren. EMNLP 2023.
-
Think-in-memory: Recalling and post-thinking enable llms with long-term memory Lei Liu, Xiaoyan Yang, Yue Shen, Binbin Hu, Zhiqiang Zhang, Jinjie Gu, Guannan Zhang. Arxiv 2023.
-
Recursively Summarizing Enables Long-Term Dialogue Memory in Large Language Models Qingxue Wang, Ling Ding, Yaran Cao, Zhilang Tan, Shi Wang, Dacheng Tao, Liu Qiu. Arxiv 2023.
-
LLM-based Medical Assistant Personalization with Short- and Long-Term Memory Coordination Yuwei Zhang, Yifan Hou, Xinyan Wang, Yiming Yang, Xiang Ren. Arxiv 2023.
-
SCM: Enhancing Large Language Model with Self-Controlled Memory Framework Bing Wang, Xinnian Liang, Jian Yang, Hui Huang, Shuangzhi Wu, Peihao Wu, Lu Lu, Zejun Ma, Zhoujun Li. Arxiv 2023.
-
LDM²: A Large Decision Model Imitating Human Cognition with Dynamic Memory Enhancement Xingjin Wang, Linjing Li, Dongfeng Zeng. EMMNLP 2023.
-
NarrativeXL: A Large-scale Dataset For Long-Term Memory Models Arseny Moskvichev, Ky-Vinh Mai. EMNLP 2023.
-
Who's Harry Potter? Approximate Unlearning in LLMs Ronen Eldan, Mark Russinovich. Arxiv 2023.
-
Active Retrieval Augmented Generation Zhengbao Jiang, Frank Xu, Luyu Gao, Zhiqing Sun, Qian Liu, Jane Dwivedi-Yu, Yiming Yang, Jamie Callan, Graham Neubig. EMNLP 2023.
-
Prompted LLMs as Chatbot Modules for Long Open-domain Conversation Gibbeum Lee, Volker Hartmann, Jongho Park, Dimitris Papailiopoulos, Kangwook Lee. ACL 2023.
-
MemoChat: Tuning LLMs to Use Memos for Consistent Long-Range Open-Domain Conversation Junru Lu, Siyu An, Mingbao Lin, Gabriele Pergola, Yulan He, Di Yin, Xing Sun, Yunsheng Wu. Arxiv 2023.
-
Learning Retrieval Augmentation for Personalized Dialogue Generation Qiushi Huang, Shuai Fu, Xubo Liu, Wenwu Wang, Tom Ko, Yu Zhang, Lilian Tang. EMNLP 2023.
-
Learning to Reason and Memorize with Self-Notes Jack Lanchantin, Shubham Toshniwal, Jason Weston, Arthur Szlam, Sainbayar Sukhbaatar. NeurIPS 2023.
-
RECAP: Retrieval-Enhanced Context-Aware Prefix Encoder for Personalized Dialogue Response Generation Shuai Liu, Hyundong Cho, Marjorie Freedman, Xuezhe Ma, Jonathan May. ACL 2023.
-
Enhancing Personalized Dialogue Generation with Contrastive Latent Variables: Combining Sparse and Dense Persona Yihong Tang, Bo Wang, Miao Fang, Dongming Zhao, Kun Huang, Ruifang He, Yuexian Hou. ACL 2023.
-
Transformer-based World Models Are Happy With 100k Interactions Jan Robine, Marc Höftmann, Tobias Uelwer, Stefan Harmeling. ICLR 2023.
2022 & before
-
Beyond Goldfish Memory: Long-Term Open-Domain Conversation Jing Xu, Arthur Szlam, Jason Weston. ACL 2022.
-
Long Time No See! Open-Domain Conversation with Long-Term Persona Memory Xinchao Xu, Zhibin Gou, Wenquan Wu, Zheng-Yu Niu, Hua Wu, Haifeng Wang, Shihang Wang. ACL 2022.
-
Keep Me Updated! Memory Management in Long-term Conversations Sanghwan Bae, Donghyun Kwak, Soyoung Kang, Min Young Lee, Sungdong Kim, Yuin Jeong, Hyeri Kim, Sang-Woo Lee, Woomyoung Park, Nako Sung. EMNLP 2022.
-
Towards Teachable Reasoning Systems: Using a Dynamic Memory of User Feedback for Continual System Improvement Bhavana Dalvi Mishra, Oyvind Tafjord, Peter Clark. EMNLP 2022.
-
Learning to Repair: Repairing Model Output Errors after Deployment Using a Dynamic Memory of Feedback Niket Tandon, Aman Madaan, Peter Clark, Yiming Yang. NAACL 2022.
-
There Are a Thousand Hamlets in a Thousand People's Eyes: Enhancing Knowledge-grounded Dialogue with Personal Memory Tingchen Fu, Xueliang Zhao, Chongyang Tao, Ji-Rong Wen, Rui Yan. ACL 2022.
-
Training Language Models with Memory Augmentation Zexuan Zhong, Tao Lei, Danqi Chen. EMNLP 2022.
-
Improving Multi-turn Emotional Support Dialogue Generation with Lookahead Strategy Planning Yi Cheng, Wenge Liu, Wenjie Li, Jiashuo Wang, Ruihui Zhao, Bang Liu, Xiaodan Liang, Yefeng Zheng. EMNLP 2022.
-
Less is More: Learning to Refine Dialogue History for Personalized Dialogue Generation Hanxun Zhong, Zhicheng Dou, Yutao Zhu, Hongjin Qian, Ji-Rong Wen. NAACL 2022.
-
Leveraging Similar Users for Personalized Language Modeling with Limited Data Charles Welch, Chenxi Gu, Jonathan K. Kummerfeld, Veronica Perez-Rosas, Rada Mihalcea. ACL 2022.
-
PerKGQA: Question Answering over Personalized Knowledge Graphs Ritam Dutt, Kasturi Bhattacharjee, Rashmi Gangadharaiah, Dan Roth, Carolyn Rose. NAACL 2022.
-
A Cooperative Memory Network for Personalized Task-oriented Dialogue Systems with Incomplete User Profiles Jiahuan Pei, Pengjie Ren, Maarten de Rijke. WWW 2021.
-
Episodic Memory in Lifelong Language Learning Cyprien de Masson d'Autume, Sebastian Ruder, Lingpeng Kong, Dani Yogatama. NeurIPS 2019.
2.2 Long Context Memory
2025
- Titans: Learning to Memorize at Test Time Ali Behrouz, Peilin Zhong, Vahab Mirrokni. Arxiv 2025.
- RocketKV: Accelerating Long-Context LLM Inference via Two-Stage KV Cache Compression Payman Behnam, Yaosheng Fu, Ritchie Zhao, Po-An Tsai, Zhiding Yu, Alexey Tumanov. ICML 2025.
- CateKV: On Sequential Consistency for Long-Context LLM Inference Acceleration Haoyun Jiang, Haolin Li, Jianwei Zhang, Fei Huang, Qiang Hu, Minmin Sun, Shuai Xiao, Yong Li, Junyang Lin, Jiangchao Yao. ICML 2025.
- LaCache: Ladder-Shaped KV Caching for Efficient Long-Context Modeling of Large Language Models Dachuan Shi, Yonggan Fu, Xiangchi Yuan, Zhongzhi Yu, Haoran You, Sixu Li, Xin Dong, Jan Kautz, Pavlo Molchanov, Yingyan Celine Lin. ICML 2025.
- ShadowKV: KV Cache in Shadows for High-Throughput Long-Context LLM Inference Hanshi Sun, Li-Wen Chang, Wenlei Bao, Size Zheng, Ningxin Zheng, Xin Liu, Harry Dong, Yuejie Chi, Beidi Chen. ICML 2025.
- Kelle: Co-design KV Caching and eDRAM for Efficient LLM Serving in Edge Computing Tianhua Xia, Sai Qian Zhang. Arxiv 2025.
- AgentFold: Long-Horizon Web Agents with Proactive Context Management Rui Ye, Zhongwang Zhang, Kuan Li, Huifeng Yin, Zhengwei Tao, Yida Zhao, Liangcai Su, Liwen Zhang, Zile Qiao, Xinyu Wang, Pengjun Xie, Fei Huang, Siheng Chen, Jingren Zhou, Yong Jiang. Arxiv 2025.
- Scaling Long-Horizon LLM Agent via Context-Folding Weiwei Sun, Miao Lu, Zhan Ling, Kang Liu, Xuesong Yao, Yiming Yang, Jiecao Chen. Arxiv 2025.
- Agentic Context Engineering: Evolving Contexts for Self-Improving Language Models Qizheng Zhang, Changran Hu, Shubhangi Upasani, Boyuan Ma, Fenglu Hong, Vamsidhar Kamanuru, Jay Rainton, Chen Wu, Mengmeng Ji, Hanchen Li, and others. Arxiv 2025.
- MMLongBench: Benchmarking Long-Context Vision-Language Models Effectively and Thoroughly Zhaowei Wang, Wenhao Yu, Xiyu Ren, Jipeng Zhang, Yu Zhao, Rohit Saxena, Liang Cheng, Ginny Wong, Simon See, Pasquale Minervini, and others. Neurips 2025.
- Radar: Fast Long-Context Decoding for Any Transformer Yongchang Hao, Mengyao Zhai, Hossein Hajimirsadeghi, Sepidehsadat Hosseini, Frederick Tung. ICLR 2025.
- Not All Heads Matter: A Head-Level KV Cache Compression Method with Integrated Retrieval and Reasoning Yu Fu, Zefan Cai, Abedelkadir Asi, Wayne Xiong, Yue Dong, Wen Xiao. ICLR 2025.
- Long Context Compression with Activation Beacon Peitian Zhang, Zheng Liu, Shitao Xiao, Ninglu Shao, Qiwei Ye, Zhicheng Dou. ICLR 2025.
- Selective Attention Improves Transformer Yaniv Leviathan, Matan Kalman, Yossi Matias. ICLR 2025.
- Streaming Video Question-Answering with In-context Video KV-Cache Retrieval Shangzhe Di, Zhelun Yu, Guanghao Zhang, Haoyuan Li, TaoZhong, Hao Cheng, Bolin Li, Wanggui He, Fangxun Shu, Hao Jiang. ICLR 2025.
- Accelerating Inference of Retrieval-Augmented Generation via Sparse Context Selection Yun Zhu, Jia-Chen Gu, Caitlin Sikora, Ho Ko, Yinxiao Liu, Chu-Cheng Lin, Lei Shu, Liangchen Luo, Lei Meng, Bang Liu, Jindong Chen. ICLR 2025.
- You Only Read Once (YORO): Learning to Internalize Database Knowledge for Text-to-SQL Hideo Kobayashi, Wuwei Lan, Peng Shi, Shuaichen Chang, Jiang Guo, Henghui Zhu, Zhiguo Wang, Patrick Ng. NAACL 2025.
- Masking in Multi-hop QA: An Analysis of How Language Models Perform with Context Permutation Wenyu Huang, Pavlos Vougiouklis, Mirella Lapata, Jeff Z. Pan. ACL 2025.
- Long-Context LLMs Meet RAG: Overcoming Challenges for Long Inputs in RAG Bowen Jin, Jinsung Yoon, Jiawei Han, Sercan O Arik. ICLR 2025.
2024
- Efficient Streaming Language Models with Attention Sinks Guangxuan Xiao, Yuandong Tian, Beidi Chen, Song Han, Mike Lewis. ICLR 2024.
- LM-Infinite: Zero-Shot Extreme Length Generalization for Large Language Models Chi Han, Qifan Wang, Hao Peng, Wenhan Xiong, Yu Chen, Heng Ji, Sinong Wang. NAACL 2024.
- Layer-Condensed KV Cache for Efficient Inference of Large Language Models Haoyi Wu, Kewei Tu. ACL 2024.
- Model Tells You What to Discard: Adaptive KV Cache Compression for LLMs Suyu Ge, Yunan Zhang, Liyuan Liu, Minjia Zhang, Jiawei Han, Jianfeng Gao. ICLR 2024.
- NACL: A General and Effective KV Cache Eviction Framework for LLM at Inference Time Yilong Chen, Guoxia Wang, Junyuan Shang, Shiyao Cui, Zhenyu Zhang, Tingwen Liu, Shuohuan Wang, Yu Sun, Dianhai Yu, Hua Wu. ACL 2024.
- SnapKV: LLM Knows What You Are Looking for before Generation Yuhong Li, Yingbing Huang, Bowen Yang, Bharat Venkitesh, Acyr Locatelli, Hanchen Ye, Tianle Cai, Patrick Lewis, Deming Chen. NeurIPS 2024.
- PyramidInfer: Pyramid KV Cache Compression for High-throughput LLM Inference Dongjie Yang, Xiaodong Han, Yan Gao, Yao Hu, Shilin Zhang, Hai Zhao. ACL 2024.
- A Simple and Effective L_2 Norm-Based Strategy for KV Cache Compression Alessio Devoto, Yu Zhao, Simone Scardapane, Pasquale Minervini. EMNLP 2024.
- SirLLM: Streaming Infinite Retentive LLM Yao Yao, Zuchao Li, Hai Zhao. ACL 2024.
- D-LLM: A Token Adaptive Computing Resource Allocation Strategy for Large Language Models Yikun Jiang, Huanyu Wang, Lei Xie, Hanbin Zhao, Chao Zhang, Hui Qian, John C.S. Lui. NeurIPS 2024.
- MiniCache: KV Cache Compression in Depth Dimension for Large Language Models Akide Liu, Jing Liu, Zizheng Pan, Yefei He, Gholamreza Haffari, Bohan Zhuang. NeurIPS 2024.
- InfiniPot: Infinite Context Processing on Memory-Constrained LLMs Minsoo Kim, Kyuhong Shim, Jungwook Choi, Simyung Chang. EMNLP 2024.
- CHAI: Clustered Head Attention for Efficient LLM Inference Saurabh Agarwal, Bilge Acun, Basil Hosmer, Mostafa Elhoushi, Yejin Lee, Shivaram Venkataraman, Dimitris Papailiopoulos, Carole-Jean Wu. ICML 2024.
- KVQuant: Towards 10 Million Context Length LLM Inference with KV Cache Quantization Coleman Hooper, Sehoon Kim, Hiva Mohammadzadeh, Michael W. Mahoney, Yakun Sophia Shao, Kurt Keutzer, Amir Gholami. NeurIPS 2024.
- Get More with LESS: Synthesizing Recurrence with KV Cache Compression for Efficient LLM Inference Harry Dong, Xinyu Yang, Zhenyu Zhang, Zhangyang Wang, Yuejie Chi, Beidi Chen. ICML 2024.
- Eigen Attention: Attention in Low-Rank Space for KV Cache Compression Utkarsh Saxena, Gobinda Saha, Sakshi Choudhary, Kaushik Roy. EMNLP 2024.
- Atom: Low-Bit Quantization for Efficient and Accurate LLM Serving Yilong Zhao, Chien-Yu Lin, Kan Zhu, Zihao Ye, Lequn Chen, Size Zheng, Luis Ceze, Arvind Krishnamurthy, Tianqi Chen, Baris Kasikci. MLSys 2024.
- ZipCache: Accurate and Efficient KV Cache Quantization with Salient Token Identification Yefei He, Luoming Zhang, Weijia Wu, Jing Liu, Hong Zhou, Bohan Zhuang. NeurIPS 2024.
- KIVI: A Tuning-Free Asymmetric 2bit Quantization for KV Cache Zirui Liu, Jiayi Yuan, Hongye Jin, Shaochen Zhong, Zhaozhuo Xu, Vladimir Braverman, Beidi Chen, Xia Hu. ICML 2024.
- QUEST: Query-Aware Sparsity for Efficient Long-Context LLM Inference Jiaming Tang, Yilong Zhao, Kan Zhu, Guangxuan Xiao, Baris Kasikci, Song Han. ICML 2024.
- TokenSelect: Efficient Long-Context Inference and Length Extrapolation for LLMs via Dynamic Token-Level KV Cache Selection Wei Wu, Zhuoshi Pan, Chao Wang, Liyi Chen, Yunchu Bai, Tianfu Wang, Kun Fu, Zheng Wang, Hui Xiong. Arxiv 2024.
- RetrievalAttention: Accelerating Long-Context LLM Inference via Vector Retrieval Di Liu, Meng Chen, Baotong Lu, Huiqiang Jiang, Zhenhua Han, Qianxi Zhang, Qi Chen, Chengruidong Zhang, Bailu Ding, Kai Zhang, Chen Chen, Fan Yang, Yuqing Yang, Lili Qiu. Arxiv 2024.
- ArkVale: Efficient Generative LLM Inference with Recallable Key-Value Eviction Renze Chen, Zhuofeng Wang, Beiquan Cao, Tong Wu, Size Zheng, Xiuhong Li, Xuechao Wei, Shengen Yan, Meng Li, Yun Liang. NeurIPS 2024.
- GraphReader: Building Graph-based Agent to Enhance Long-Context Abilities of Large Language Models Shilong Li, Yancheng He, Hangyu Guo, Xingyuan Bu, Ge Bai, Jie Liu, Jiaheng Liu, Xingwei Qu, Yangguang Li, Wanli Ouyang, Wenbo Su, Bo Zheng. EMNLP 2024.
- Selection-p: Self-Supervised Task-Agnostic Prompt Compression for Faithfulness and Transferability Tsz Ting Chung, Leyang Cui, Lemao Liu, Xinting Huang, Shuming Shi, Dit-Yan Yeung. EMNLP 2024.
- Tell Your Model Where to Attend: Post-hoc Attention Steering for LLMs Qingru Zhang, Chandan Singh, Liyuan Liu, Xiaodong Liu, Bin Yu, Jianfeng Gao, Tuo Zhao. ICLR 2024.
- Naive Bayes-based Context Extension for Large Language Models Jianlin Su, Murtadha Ahmed, Bo Wen, Luo Ao, Mingren Zhu, Yunfeng Liu. NAACL 2024.
- FragRel: Exploiting Fragment-level Relations in the External Memory of Large Language Models Xihang Yue, Linchao Zhu, Yi Yang. ACL 2024.
- Never Lost in the Middle: Mastering Long-Context Question Answering with Position-Agnostic Decompositional Training Junqing He, Kunhao Pan, Xiaoqun Dong, Zhuoyang Song, LiuYiBo LiuYiBo, Qianguosun Qianguosun, Yuxin Liang, Hao Wang, Enming Zhang, Jiaxing Zhang. ACL 2024.
- Make Your LLM Fully Utilize the Context Shengnan An, Zexiong Ma, Zeqi Lin, Nanning Zheng, Jian-Guang Lou. NeurIPS 2024.
- Neurocache: Efficient Vector Retrieval for Long-range Language Modeling Ali Safaya, Deniz Yuret. NAACL 2024.
- AWESOME: GPU Memory-constrained Long Document Summarization using Memory Mechanism and Global Salient Content Shuyang Cao, Lu Wang. NAACL 2024.
- xRAG: Extreme Context Compression for Retrieval-augmented Generation with One Token Xin Cheng, Xun Wang, Xingxing Zhang, Tao Ge, Si-Qing Chen, Furu Wei, Huishuai Zhang, Dongyan Zhao. NeurIPS 2024.
- Long-Context Language Modeling with Parallel Context Encoding Howard Yen, Tianyu Gao, Danqi Chen. ACL 2024.
- Hierarchical Context Merging: Better Long Context Understanding for Pre-trained LLMs Woomin Song, Seunghyuk Oh, Sangwoo Mo, Jaehyung Kim, Sukmin Yun, Jung-Woo Ha, Jinwoo Shin. ICLR 2024.
- Extending Context Window of Large Language Models via Semantic Compression Weizhi Fei, Xueyan Niu, Pingyi Zhou, Lu Hou, Bo Bai, Lei Deng, Wei Han. ACL 2024.
- RECOMP: Improving Retrieval-Augmented LMs with Context Compression and Selective Augmentation Fangyuan Xu, Weijia Shi, Eunsol Choi. ICLR 2024.
- CompAct: Compressing Retrieved Documents Actively for Question Answering Chanwoong Yoon, Taewhoo Lee, Hyeon Hwang, Minbyul Jeong, Jaewoo Kang. EMNLP 2024.
- Learning to Compress Prompt in Natural Language Formats Yu-Neng Chuang, Tianwei Xing, Chia-Yuan Chang, Zirui Liu, Xun Chen, Xia Hu. NAACL 2024.
- LongLLMLingua: Accelerating and Enhancing LLMs in Long Context Scenarios via Prompt Compression Huiqiang Jiang, Qianhui Wu, Xufang Luo, Dongsheng Li, Chin-Yew Lin, Yuqing Yang, Lili Qiu. ACL 2024.
- LLMLingua-2: Data Distillation for Efficient and Faithful Task-Agnostic Prompt Compression Zhuoshi Pan, Qianhui Wu, Huiqiang Jiang, Menglin Xia, Xufang Luo, Jue Zhang, Qingwei Lin, Victor Rühle, Yuqing Yang, Chin-Yew Lin, H. Vicky Zhao, Lili Qiu, Dongmei Zhang. ACL 2024.
- LongRoPE: Extending LLM Context Window Beyond 2 Million Tokens Yiran Ding, Li Lyna Zhang, Chengruidong Zhang, Yuanyuan Xu, Ning Shang, Jiahang Xu, Fan Yang, Mao Yang. ICML 2024.
- Lost in the Middle: How Language Models Use Long Contexts Nelson F. Liu, Kevin Lin, John Hewitt, Ashwin Paranjape, Michele Bevilacqua, Fabio Petroni, Percy Liang. TACL 2024.
- On Context Utilization in Summarization with Large Language Models Mathieu Ravaut, Aixin Sun, Nancy Chen, Shafiq Joty. ACL 2024.
- KV Cache Compression, But What Must We Give in Return? A Comprehensive Benchmark of Long Context Capable Approaches Jiayi Yuan, Hongyi Liu, Shaochen Zhong, Yu-Neng Chuang, Songchen Li, Guanchu Wang, Duy Le, Hongye Jin, Vipin Chaudhary, Zhaozhuo Xu, Zirui Liu, Xia Hu. EMNLP 2024.
- Retrieval Augmented Generation or Long-Context LLMs? A Comprehensive Study and Hybrid Approach Zhuowan Li, Cheng Li, Mingyang Zhang, Qiaozhu Mei, Michael Bendersky. EMNLP 2024.
2023
- H2O: Heavy-Hitter Oracle for Efficient Generative Inference of Large Language Models Zhenyu Zhang, Ying Sheng, Tianyi Zhou, Tianlong Chen, Lianmin Zheng, Ruisi Cai, Zhao Song, Yuandong Tian, Christopher Ré, Clark Barrett, Zhangyang "Atlas" Wang, Beidi Chen. NeurIPS 2023.
- Scissorhands: Exploiting the Persistence of Importance Hypothesis for LLM KV Cache Compression at Test Time Zichang Liu, Aditya Desai, Fangshuo Liao, Weitao Wang, Victor Xie, Zhaozhuo Xu, Anastasios Kyrillidis, Anshumali Shrivastava. NeurIPS 2023.
- FlexGen: High-Throughput Generative Inference of Large Language Models with a Single GPU Ying Sheng, Lianmin Zheng, Binhang Yuan, Zhuohan Li, Max Ryabinin, Daniel Y. Fu, Zhiqiang Xie, Beidi Chen, Clark Barrett, Joseph E. Gonzalez, Percy Liang, Christopher Ré, Ion Stoica, Ce Zhang. ICML 2023.
- Focused Transformer: Contrastive Training for Context Scaling Szymon Tworkowski, Konrad Staniszewski, Mikołaj Pacek, Yuhuai Wu, Henryk Michalewski, Piotr Miłoś. NeurIPS 2023.
- TRAMS: Training-free Memory Selection for Long-range Language Modeling Haofei Yu, Cunxiang Wang, Yue Zhang, Wei Bi. EMNLP 2023.
- MemGPT: Towards LLMs as Operating Systems Charles Packer, Sarah Wooders, Kevin Lin, Vivian Fang, Shishir G. Patil, Ion Stoica, Joseph E. Gonzalez. Arxiv 2023.
- Adapting Language Models to Compress Contexts Alexis Chevalier, Alexander Wettig, Anirudh Ajith, Danqi Chen. EMNLP 2023.
- Compressing Context to Enhance Inference Efficiency of Large Language Models Yucheng Li, Bo Dong, Frank Guerin, Chenghua Lin. EMNLP 2023.
- LLMLingua: Compressing Prompts for Accelerated Inference of Large Language Models Huiqiang Jiang, Qianhui Wu, Chin-Yew Lin, Yuqing Yang, Lili Qiu. EMNLP 2023.
- TCRA-LLM: Token Compression Retrieval Augmented Large Language Model for Inference Cost Reduction Junyi Liu, Liangzhi Li, Tong Xiang, Bowen Wang, Yiming Qian. EMNLP 2023.
- LongNet: Scaling Transformers to 1,000,000,000 Tokens Jiayu Ding, Shuming Ma, Li Dong, Xingxing Zhang, Shaohan Huang, Wenhui Wang, Nanning Zheng, Furu Wei. Arxiv 2023.
- Large Language Models Can Be Easily Distracted by Irrelevant Context Freda Shi, Xinyun Chen, Kanishka Misra, Nathan Scales, David Dohan, Ed H. Chi, Nathanael Schärli, Denny Zhou. ICML 2023.
2022
- Memorizing Transformers Yuhuai Wu, Markus Norman Rabe, DeLesley Hutchins, Christian Szegedy. ICLR 2022.
- Capturing Global Structural Information in Long Document Question Answering with Compressive Graph Selector Network Yuxiang Nie, Heyan Huang, Wei Wei, Xian-Ling Mao. EMNLP 2022.
2.3 Parametric Memory
2025
- MLP Memory: Language Modeling with Retriever-pretrained External Memory Rubin Wei, Jiaqi Cao, Jiarui Wang, Jushi Kai, Qipeng Guo, Bowen Zhou, Zhouhan Lin. Arxiv 2025.
- Memory Decoder: A Pretrained, Plug-and-Play Memory for Large Language Models Jiaqi Cao, Jiarui Wang, Rubin Wei, Qipeng Guo, Kai Chen, Bowen Zhou, Zhouhan Lin. Arxiv 2025.
- Sft memorizes, rl generalizes: A comparative study of foundation model post-training Tianzhe Chu, Yuexiang Zhai, Jihan Yang, Shengbang Tong, Saining Xie, Dale Schuurmans, Quoc V Le, Sergey Levine, Yi Ma. Arxiv 2025.
- AlphaEdit: Null-Space Constrained Knowledge Editing for Language Models Junfeng Fang, Houcheng Jiang, Kun Wang, Yunshan Ma, Shi Jie, Xiang Wang, Xiangnan He, Tat-seng Chua ICLR 2025.
- Open Problems in Machine Unlearning for AI Safety Fazl Barez, Tingchen Fu, Ameya Prabhu, Stephen Casper, Amartya Sanyal, Adel Bibi, Aidan O'Gara, Robert Kirk, Ben Bucknall, Tim Fist, Luke Ong, Philip Torr, Kwok-Yan Lam, Robert Trager, David Krueger, Sören Mindermann, José Hernandez-Orallo, Mor Geva, Yarin Gal Arxiv 2025.
- MUSE: Machine Unlearning Six-Way Evaluation for Language Models Weijia Shi, Jaechan Lee, Yangsibo Huang, Sadhika Malladi, Jieyu Zhao, Ari Holtzman, Daogao Liu, Luke Zettlemoyer, Noah A. Smith, Chiyuan Zhang ICLR 2025.
- Spurious Forgetting in Continual Learning of Language Models Junhao Zheng , Xidi Cai, Shengjie Qiu, Qianli Ma ICLR 2025.
- Precise Localization of Memories: A Fine-grained Neuron-level Knowledge Editing Technique for LLMs Haowen Pan, Xiaozhi Wang, Yixin Cao, Zenglin Shi, Xun Yang, Juanzi Li, Meng Wang ICLR 2025.
- LLM Unlearning via Loss Adjustment with Only Forget Data Yaxuan Wang, Jiaheng Wei, Chris Yuhao Liu, Jinlong Pang, Quan Liu, Ankit Shah, Yujia Bao, Yang Liu, Wei Wei ICLR 2025.
- Lifelong Learning of Large Language Model based Agents: A Roadmap Junhao Zheng, Chengming Shi, Xidi Cai, Qiuke Li, Duzhen Zhang, Chenxing Li, Dong Yu, Qianli Ma Arxiv 2025.
- Towards LifeSpan Cognitive Systems Yu Wang, Chi Han, Tongtong Wu, Xiaoxin He, Wangchunshu Zhou, Nafis Sadeq, Xiusi Chen, Zexue He, Wei Wang, Gholamreza Haffari, Heng Ji, Julian McAuley TMLR 2025.
- Self-Updatable Large Language Models by Integrating Context into Model Parameters Yu Wang, Xinshuang Liu, Xiusi Chen, Sean O'Brien, Junda Wu, Julian McAuley ICLR 2025.
- If an LLM Were a Character, Would It Know Its Own Story? Evaluating Lifelong Learning in LLMs Siqi Fan, Xiusheng Huang, Yiqun Yao, Xuezhi Fang, Kang Liu, Peng Han, Shuo Shang, Aixin Sun, Yequan Wang Arxiv 2025.
2024
- Mass-Editing Memory with Attention in Transformers: A cross-lingual exploration of knowledge Daniel Tamayo, Aitor Gonzalez-Agirre, Javier Hernando, Marta Villegas. ACL 2024.
- Memory3: Language Modeling with Explicit Memory Hongkang Yang, Zehao Lin, Wenjin Wang, Hao Wu, Zhiyu Li, Bo Tang, Wenqiang Wei, Jinbo Wang, Zeyun Tang, Shichao Song, Chenyang Xi, Yu Yu, Kai Chen, Feiyu Xiong, Linpeng Tang, Weinan E. Arxiv 2024.
- WISE: Rethinking the Knowledge Memory for Lifelong Model Editing of Large Language Models Peng Wang, Zexi Li, Ningyu Zhang, Ziwen Xu, Yunzhi Yao, Yong Jiang, Pengjun Xie, Fei Huang, Huajun Chen NeurIPS 2024.
- MEMORYLLM: Towards Self-Updatable Large Language Models Yu Wang, Yifan Gao, Xiusi Chen, Haoming Jiang, Shiyang Li, Jingfeng Yang, Qingyu Yin, Zheng Li, Xian Li, Bing Yin, Jingbo Shang, Julian McAuley Arxiv 2024.
- A Comprehensive Survey of Continual Learning: Theory, Method and Application Liyuan Wang , Xingxing Zhang , Hang Su , Jun Zhu TPAMI 2024.
- The WMDP Benchmark: Measuring and Reducing Malicious Use With Unlearning Nathaniel Li, Alexander Pan, Anjali Gopal, Summer Yue, Daniel Berrios, Alice Gatti, Justin D. Li, Ann-Kathrin Dombrowski, Shashwat Goel, Gabriel Mukobi, Nathan Helm-Burger, Rassin Lababidi, Lennart Justen, Andrew Bo Liu, Michael Chen, Isabelle Barrass, Oliver Zhang, Xiaoyuan Zhu, Rishub Tamirisa, Bhrugu Bharathi, Ariel Herbert-Voss, Cort B Breuer, Andy Zou, Mantas Mazeika, Zifan Wang, Palash Oswal, Weiran Lin, Adam Alfred Hunt, Justin Tienken-Harder, Kevin Y. Shih, Kemper Talley, John Guan, Ian Steneker, David Campbell, Brad Jokubaitis, Steven Basart, Stephen Fitz, Ponnurangam Kumaraguru, Kallol Krishna Karmakar, Uday Tupakula, Vijay Varadharajan, Yan Shoshitaishvili, Jimmy Ba, Kevin M. Esvelt, Alexandr Wang, Dan Hendrycks ICML 2024.
- TOFU: A Task of Fictitious Unlearning for LLMs Pratyush Maini, Zhili Feng, Avi Schwarzschild, Zachary Chase Lipton, J Zico Kolter COLM 2024.
- In-Context Unlearning: Language Models as Few Shot Unlearners Martin Pawelczyk, Seth Neel, Himabindu Lakkaraju ICML2024.
- Towards Safer Large Language Models through Machine Unlearning Zheyuan Liu, Guangyao Dou, Zhaoxuan Tan, Yijun Tian, Meng Jiang ACL 2024.
- A Comprehensive Study of Knowledge Editing for Large Language Models Ningyu Zhang, Yunzhi Yao, Bozhong Tian, Peng Wang, Shumin Deng, Mengru Wang, Zekun Xi, Shengyu Mao, Jintian Zhang, Yuansheng Ni, Siyuan Cheng, Ziwen Xu, Xin Xu, Jia-Chen Gu, Yong Jiang, Pengjun Xie, Fei Huang, Lei Liang, Zhiqiang Zhang, Xiaowei Zhu, Jun Zhou, Huajun Chen Arxiv 2024.
- SOUL: Unlocking the Power of Second-Order Optimization for LLM Unlearning Jinghan Jia, Yihua Zhang, Yimeng Zhang, Jiancheng Liu, Bharat Runwal, James Diffenderfer, Bhavya Kailkhura, Sijia Liu EMNLP 2024.
- Large Language Model Unlearning via Embedding-Corrupted Prompts Chris Yuhao Liu, Yaxuan Wang, Jeffrey Flanigan, Yang Liu NeurIPS 2024.
- On Memorization of Large Language Models in Logical Reasoning Chulin Xie , Yangsibo Huang, Chiyuan Zhang, Da Yu, Xinyun Chen, Bill Yuchen Lin, Bo Li, Badih Ghazi, Ravi Kumar Arxiv 2024.
- Reversing the Forget-Retain Objectives: An Efficient LLM Unlearning Framework from Logit Difference Jiabao Ji, Yujian Liu, Yang Zhang, Gaowen Liu, Ramana Rao Kompella, Sijia Liu, Shiyu Chang NeurIPS 2024.
- RWKU: Benchmarking Real-World Knowledge Unlearning for Large Language Models Zhuoran Jin, Pengfei Cao, Chenhao Wang, Zhitao He, Hongbang Yuan, Jiachun Li, Yubo Chen, Kang Liu, Jun Zhao NeurIPS 2024.
- Larimar: Large Language Models with Episodic Memory Control Payel Das, Subhajit Chaudhury, Elliot Nelson, Igor Melnyk, Sarathkrishna Swaminathan, Sihui Dai, Aurelie Lozano, Georgios Kollias, Vijil Chenthamarakshan, Jiri Navratil, Soham Dan, Pin-Yu Chen ICML 2024.
- TaSL: Continual Dialog State Tracking via Task Skill Localization and Consolidation Yujie Feng, Xu Chu, Yongxin Xu, Guangyuan Shi, Bo Liu, Xiao-Ming Wu ACL 2024
- To Forget or Not? Towards Practical Knowledge Unlearning for Large Language Models Bozhong Tian, Xiaozhuan Liang, Siyuan Cheng, Qingbin Liu, Mengru Wang, Dianbo Sui, Xi Chen, Huajun Chen, Ningyu Zhang EMNLP 2024.
- Mitigating Catastrophic Forgetting in Online Continual Learning by Modeling Previous Task Interrelations via Pareto Optimization Yichen Wu , Hong Wang, Peilin Zhao, Yefeng Zheng, Ying Wei, Long-Kai Huang ICML 2024.
- WAGLE: Strategic Weight Attribution for Effective and Modular Unlearning in Large Language Models Jinghan Jia, Jiancheng Liu, Yihua Zhang, Parikshit Ram, Nathalie Baracaldo, Sijia Liu NeurIPS 2024.
- Boosting Large Language Models with Continual Learning for Aspect-based Sentiment Analysis Xuanwen Ding, Jie Zhou, Liang Dou, Qin Chen, Yuanbin Wu, Arlene Chen, Liang He EMNLP 2024.
- DAFNet: Dynamic Auxiliary Fusion for Sequential Model Editing in Large Language Models Taolin Zhang, Qizhou Chen, Dongyang Li, Chengyu Wang, Xiaofeng He, Longtao Huang, Hui Xue’, Jun Huang ACL 2024.
2023
- Mass-Editing Memory in a Transformer Kevin Meng, Arnab Sen Sharma, Alex Andonian, Yonatan Belinkov, David Bau. ICLR 2023.
- DSI++: Updating Transformer Memory with New Documents Sanket Vaibhav Mehta, Jai Gupta, Yi Tay, Mostafa Dehghani, Vinh Q. Tran, Jinfeng Rao, Marc Najork, Emma Strubell, Donald Metzler. EMNLP 2023.
- A Unified Approach to Domain Incremental Learning with Memory: Theory and Algorithm Haizhou Shi, Hao Wang. NeurIPS 2023.
- Locating and Editing Factual Associations in GPT Kevin Meng, David Bau, Alex Andonian, Yonatan Belinkov NeurIPS 2023.
- Can We Edit Factual Knowledge by In-Context Learning? Ce Zheng, Lei Li, Qingxiu Dong, Yuxuan Fan, Zhiyong Wu, Jingjing Xu, Baobao Chang EMNLP 2023.
- Unlearn What You Want to Forget: Efficient Unlearning for LLMs Jiaao Chen, Diyi Yang EMNLP 2023.
- MQuAKE: Assessing Knowledge Editing in Language Models via Multi-Hop Questions Zexuan Zhong, Zhengxuan Wu, Christopher Manning, Christopher Potts, Danqi Chen EMNLP 2023.
- Large Language Model Unlearning Yuanshun Yao, Xiaojun Xu, Yang Liu NeurIPS SoLaR 2023.
- DEPN: Detecting and Editing Privacy Neurons in Pretrained Language Models Xinwei Wu, Junzhuo Li, Minghui Xu, Weilong Dong, Shuangzhi Wu, Chao Bian, Deyi Xiong EMNLP 2023.
2022 & Before
- Memory-Based Model Editing at Scale Eric Mitchell, Charles Lin, Antoine Bosselut, Christopher D. Manning, Chelsea Finn. ICML 2022.
- Memory-assisted prompt editing to improve GPT-3 after deployment Aman Madaan, Niket Tandon, Peter Clark, Yiming Yang. EMNLP 2022.
- Improving Task-free Continual Learning by Distributionally Robust Memory Evolution Zhenyi Wang, Li Shen, Le Fang, Qiuling Suo, Tiehang Duan, Mingchen Gao. ICML 2022.
- Memory Replay with Data Compression for Continual Learning Liyuan Wang, Xingxing Zhang, Kuo Yang, Longhui Yu, Chongxuan Li, Lanqing Hong, Shifeng Zhang, Zhenguo Li, Yi Zhong, Jun Zhu Arxiv 2022.
- Fast Model Editing at Scale Eric Mitchell, Charles Lin, Antoine Bosselut, Chelsea Finn, Christopher D Manning ICLR 2022.
- Calibrating Factual Knowledge in Pretrained Language Models Qingxiu Dong, Damai Dai, Yifan Song, Jingjing Xu, Zhifang Sui, Lei Li EMNLP 2022.
- Incremental Prompting: Episodic Memory Prompt for Lifelong Event Detection Minqian Liu, Shiyu Chang, Lifu Huang COLING 2022.
- Editing Factual Knowledge in Language Models Nicola De Cao, Wilker Aziz, Ivan Titov EMNLP 2021.
- Sequential memory improves sample and memory efficiency in Episodic Control Ismael T. Freire, Adrián F. Amil, Paul F.M.J. Verschure Arxiv 2021.
- Towards Scalable Multi-domain Conversational Agents: The Schema-Guided Dialogue Dataset Abhinav Rastogi, Xiaoxue Zang, Srinivas Sunkara, Raghav Gupta, Pranav Khaitan AAAI 2020.
- INSPIRED: Toward Sociable Recommendation Dialog Systems Shirley Anugrah Hayati, Dongyeop Kang, Qingxiaoyang Zhu, Weiyan Shi, Zhou Yu EMNLP 2020.
- Overcoming catastrophic forgetting in neural networks James Kirkpatrick, Razvan Pascanu, Neil Rabinowitz, Joel Veness, Guillaume Desjardins, Andrei A. Rusu, Kieran Milan, John Quan, Tiago Ramalho, Agnieszka Grabska-Barwinska, Demis Hassabis, Claudia Clopath, Dharshan Kumaran, Raia Hadsell PNAS 2017.
2.4 Multi-source Memory
2025
- Context as memory: Scene-consistent interactive long video generation with memory retrieval Jiwen Yu, Jianhong Bai, Yiran Qin, Quande Liu, Xintao Wang, Pengfei Wan, Di Zhang, Xihui Liu. Arxiv 2025.
- Mirix: Multi-agent memory system for llm-based agents Yu Wang, Xi Chen. Arxiv 2025.
- Seeing, Listening, Remembering, and Reasoning: A Multimodal Agent with Long-Term Memory Lin Long, Yichen He, Wentao Ye, Yiyuan Pan, Yuan Lin, Hang Li, Junbo Zhao, Wei Li. Arxiv 2025.
- Ella: Embodied Social Agents with Lifelong Memory Hongxin Zhang, Zheyuan Zhang, Zeyuan Wang, Zunzhe Zhang, Lixing Fang, Qinhong Zhou, Chuang Gan. Arxiv 2025.
- DelTA: An Online Document-Level Translation Agent Based on Multi-Level Memory Yutong Wang, Jiali Zeng, Xuebo Liu, Derek F. Wong, Fandong Meng, Jie Zhou, Min Zhang. ICLR 2025.
- StructRAG: Boosting Knowledge Intensive Reasoning of LLMs via Inference-time Hybrid Information Structurization Zhuoqun Li, Xuanang Chen, Haiyang Yu, Hongyu Lin, Yaojie Lu, Qiaoyu Tang, Fei Huang, Xianpei Han, Le Sun, Yongbin Li. ICLR 2025.
- M3: 3D-Spatial MultiModal Memory Xueyan Zou, Yuchen Song, Ri-Zhao Qiu, Xuanbin Peng, Jianglong Ye, Sifei Liu, Xiaolong Wang. ICLR 2025.
- Stable Hadamard Memory: Revitalizing Memory-Augmented Agents for Reinforcement Learning Hung Le, Dung Nguyen, Kien Do, Sunil Gupta, Svetha Venkatesh. ICLR 2025.
- A New Formula for Sticker Retrieval: Reply with Stickers in Multi-Modal and Multi-Session Conversation Bingbing Wang, Yiming Du, Bin Liang, Zhixin Bai, Min Yang, Baojun Wang, Kam-Fai Wong, Ruifeng Xu. AAAI 2025.
- LLM-Empowered Embodied Agent for Memory-Augmented Task Planning in Household Robotics Marc Glocker, Peter Hönig, Matthias Hirschmanner, Markus Vincze. Arxiv 2025.
- WORLDMEM: Long-term Consistent World Simulation with Memory Zeqi Xiao, Yushi Lan, Yifan Zhou, Wenqi Ouyang, Shuai Yang, Yanhong Zeng, Xingang Pan. Arxiv 2025.
2024
- Symbolic Working Memory Enhances Language Models for Complex Rule Application Siyuan Wang, Zhongyu Wei, Yejin Choi, Xiang Ren. EMNLP 2024.
- Memory Augmented Language Models through Mixture of Word Experts Cicero Nogueira dos Santos, James Lee-Thorp, Isaac Noble, Chung-Ching Chang, David Uthus. NAACL 2024.
- MATTER: Memory-Augmented Transformer Using Heterogeneous Knowledge Sources Dongkyu Lee, Chandana Satya Prakash, Jack FitzGerald, Jens Lehmann. ACL 2024.
- Learning Multimodal Contrast with Cross-modal Memory and Reinforced Contrast Recognition Yuanhe Tian, Fei Xia, Yan Song. ACL 2024.
- A Simple LLM Framework for Long-Range Video Question-Answering Ce Zhang, Taixi Lu, Md Mohaiminul Islam, Ziyang Wang, Shoubin Yu, Mohit Bansal, Gedas Bertasius. EMNLP 2024.
- MA-LMM: Memory-Augmented Large Multimodal Model for Long-Term Video Understanding Bo He, Hengduo Li, Young Kyun Jang, Menglin Jia, Xuefei Cao, Ashish Shah, Abhinav Shrivastava, Ser-Nam Lim. CVPR 2024.
- Chain-of-Knowledge: Grounding Large Language Models via Dynamic Knowledge Adapting over Heterogeneous Sources Xingxuan Li, Ruochen Zhao, Yew Ken Chia, Bosheng Ding, Shafiq Joty, Soujanya Poria, Lidong Bing. ICLR 2024.
- VISTA: Visualized Text Embedding For Universal Multi-Modal Retrieval Junjie Zhou, Zheng Liu, Shitao Xiao, Bo Zhao, Yongping Xiong. ACL 2024.
- Generate-on-Graph: Treat LLM as both Agent and KG in Incomplete Knowledge Graph Question Answering Yao Xu, Shizhu He, Jiabei Chen, Zihao Wang, Yangqiu Song, Hanghang Tong, Guang Liu, Kang Liu, Jun Zhao. EMNLP 2024.
- Enhancing Reasoning with Collaboration and Memory Julie Michelman, Nasrin Baratalipour, Matthew Abueg. ICLR 2024.
- Generative Cross-Modal Retrieval: Memorizing Images in Multimodal Language Models for Retrieval and Beyond Yongqi Li, Wenjie Wang, Leigang Qu, Liqiang Nie, Wenjie Li, Tat-Seng Chua. ACL 2024.
- Semi-Structured Chain-of-Thought: Integrating Multiple Sources of Knowledge for Improved Language Model Reasoning Xin Su, Tiep Le, Steven Bethard, Phillip Howard. NAACL 2024.
- Blinded by Generated Contexts: How Language Models Merge Generated and Retrieved Contexts When Knowledge Conflicts? Hexiang Tan, Fei Sun, Wanli Yang, Yuanzhuo Wang, Qi Cao, Xueqi Cheng. ACL 2024.
- Moviechat+: Question-aware sparse memory for long video question answering Enxin Song, Wenhao Chai, Tian Ye, Jenq-Neng Hwang, Xi Li, Gaoang Wang. Arxiv 2024.
- LifelongMemory: Leveraging LLMs for Answering Queries in Long-form Egocentric Videos Ying Wang, Yanlai Yang, Mengye Ren. Arxiv 2024.
- Resolving Knowledge Conflicts in Large Language Models Yike Wang, Shangbin Feng, Heng Wang, Weijia Shi, Vidhisha Balachandran, Tianxing He, Yulia Tsvetkov. Arxiv 2024.
2023
- ChatDB: Augmenting LLMs with Databases as Their Symbolic Memory Chenxu Hu, Jie Yu, Chencheng Dong, Junbo Zhao, Hang Zhao. Arxiv 2023.
- Large Language Models with Controllable Working Memory Daliang Li, Ankit Singh Rawat, Manzil Zaheer, Xin Wang, Michal Lukasik, Andreas Veit, Felix Yu, Sanjiv Kumar. ACL 2023.
- Conversation Understanding using Relational Temporal Graph Neural Networks with Auxiliary Cross-Modality Interaction Cam-Van Thi Nguyen, Anh-Tuan Mai, The-Son Le, Hai-Dang Kieu, Duc-Trong Le ACL 2023.
- Universal Vision-Language Dense Retrieval Zhenghao Liu, Chenyan Xiong, Yuanhuiyi Lv, Zhiyuan Liu, Ge Yu. ICLR 2023.
- Context-faithful Prompting for Large Language Models Wenxuan Zhou, Sheng Zhang, Hoifung Poon, Muhao Chen. EMNLP 2023.
- Open-Ended Instructable Embodied Agents with Memory-Augmented Large Language Models Gabriel Sarch, Yuxiang Wu, Yuqi Xie, Yunfan Jiang, Linxi Fan, Ajay M. Patel, Yuke Zhu, Anima Anandkumar. Arxiv 2023.
- A Framework for Inference Inspired by Human Memory Mechanisms Xiangyu Zeng, Jie Lin, Piao Hu, Ruizheng Huang, Zhicheng Zhang. Arxiv 2023.
2022 & before
- An Efficient Memory-Augmented Transformer for Knowledge-Intensive NLP Tasks Yuxiang Wu, Yu Zhao, Baotian Hu, Pasquale Minervini, Pontus Stenetorp, Sebastian Riedel. EMNLP 2022.
- There Are a Thousand Hamlets in a Thousand People's Eyes: Enhancing Knowledge-grounded Dialogue with Personal Memory Tingchen Fu, Xueliang Zhao, Chongyang Tao, Ji-Rong Wen, Rui Yan. ACL 2022.
- Prior Knowledge and Memory Enriched Transformer for Sign Language Translation Tao Jin, Zhou Zhao, Meng Zhang, Xingshan Zeng. ACL 2022.
- G-MAP: General Memory-Augmented Pre-trained Language Model for Domain Tasks Zhongwei Wan, Yichun Yin, Wei Zhang, Jiaxin Shi, Lifeng Shang, Guangyong Chen, Xin Jiang, Qun Liu. EMNLP 2022.
- Memory-aligned Knowledge Graph for Clinically Accurate Radiology Image Report Generation Sixing Yan. BioNLP 2022.
- Dynamic Global Memory for Document-level Argument Extraction Xinya Du, Sha Li, Heng Ji. ACL 2022.
- UniTranSeR: A Unified Transformer Semantic Representation Framework for Multimodal Task-Oriented Dialog System Zhiyuan Ma, Jianjun Li, Guohui Li, Yongjing Cheng. ACL 2022.
- A Cooperative Memory Network for Personalized Task-oriented Dialogue Systems with Incomplete User Profiles Jiahuan Pei, Pengjie Ren, Maarten de Rijke. WWW 2021.
📊 Datasets
Evaluation for Long Term Memroy.
Table-1: Datasets for Evaluating Long-Term Memory *(Continuously Updated)
| Dataset | Mo | Operations | DS Type | Per | TR | Metrics | Purpose | Year |
|---|---|---|---|---|---|---|---|---|
| PersonaMem-v2 | text | Updating, Retrieval | MS | ✓ | ✓ | Accuracy, Persona Score | Benchmark implicit user persona learning and agentic memory updates over long contexts. | 2025 |
| MemoryBench | text | Updating, Retrieval, Forgetting | QA | ✗ | ✓ | Accuracy, Retention Rate | Comprehensive benchmark for memory correctness, persistence, and continual learning. | 2025 |
| HaluMem | text | Retrieval | QA | ✗ | ✗ | Accuracy, Hallucination Rate, Omission Rate | Evaluate hallucinations in memory extraction, updating and retrieval. | 2025 |
| BFCL V4 | text (API/Code) | Updating, Retrieval, Reasoning | QA (API) | ✗ | ✗ | AST Accuracy, Execution Success | Benchmarking function-calling capabilities, specifically featuring a "Memory" category for CRUD tool usage. | 2025 |
| LongMemEval | text | Indexing, Retrieval, Compression | MS | ✗ | ✓ | Recall@K, NDCG@K, Accuracy | Benchmark chat assistants on long-term memory abilities, including temporal reasoning. | 2025 |
| LoCoMo | text + image | Indexing, Retrieval, Compression | MS | ✗ | ✓ | Accuracy, ROUGE, Precision, Recall, F1 | Evaluate long-term memory in LLMs across QA, event summarization, and multimodal dialogue tasks. | 2024 |
| MemoryBank | text | Updating, Retrieval | MS | ✓ | ✗ | Accuracy, Human Eval | Enhance LLMs with long-term memory capabilities, adapting to user personalities and contexts. | 2024 |
| PerLTQA | text | Retrieval | MS | ✓ | ✗ | MAP, Recall, Precision, F1, Accuracy, GPT4 score | To explore personal long-term memory question answering ability. | 2024 |
| MALP | text | Retrieval, Compression | QA | ✓ | ✗ | ROUGE, Accuracy, Win Rate | Preference-conditioned dialogue generation. Parameter-efficient fine-tuning (PEFT) for customization. | 2024 |
| DialSim | text | Retrieval | MS | ✓ | ✗ | Accuracy | To evaluate dialogue systems under realistic, real-time, and long-context multi-party conversation conditions. | 2024 |
| MovieChat-1K | text + video | question-answering + caption | QA | ✗ | ✓ | Accuracy | For long-term video understanding for Large Multimodal Models across video question-answering and video captioning tasks. | 2023 |
| CC | text | Retrieval | MS | ✗ | ✓ | BLEU, ROUGE | For long-term dialogue modeling with time and relationship context. | 2023 |
| LAMP | text | Consolidation, Retrieval, Compression | MS | ✓ | ✓ | Accuracy, F1, ROUGE | Multiple entries per user. Supports both user-based splits and time-based splits. | 2023 |
| MSC | text | Consolidation, Retrieval, Compression | MS | ✓ | ✗ | PPL | Evaluate and improve long-term dialogue models via multi-session chats with evolving knowledge. | 2022 |
| DuLeMon | text | Consolidation, Updating, Retrieval, Compression | MS | ✓ | ✗ | Accuracy, F1, Recall, Precision, PPL, BLEU, DISTINCT | For dynamic persona tracking and consistent long-term interaction. | 2022 |
| 2WikiMultiHopQA | table + knowledge base + text | Consolidation, Indexing, Retrieval, Compression | QA | ✗ | ✗ | EM, F1 | Multi-hop QA combining structured and unstructured data with reasoning paths. | 2020 |
| NQ | text | Retrieval, Compression | QA | ✗ | ✗ | EM, F1 | Open-domain QA based on real Google search queries. | 2019 |
| HotpotQA | text | Retrieval, Compression | QA | ✗ | ✗ | EM, F1 | Multi-hop QA with explainable reasoning and sentence-level supporting facts. | 2018 |
Note:
- Mo: Modality of the dataset (e.g., text, image, table).
- Ops (Operations): Memory-related operations supported or evaluated (e.g., Indexing, Retrieval, Compression, Updating, Consolidation).
- DS Type: Dataset type —
- QA = Question Answering
- MS = Multi-Session Dialogue
- Per: Persona present (✓ = Yes, ✗ = No).
- TR: Temporal reasoning required or present (✓ = Yes, ✗ = No).
Evaluation for Long Context Memory
Table-2: Datasets for Long-Context Memory Evaluation *(Continuously Updated)*
| Dataset | Modality | Operations | Metrics | Purpose | Year |
|---|---|---|---|---|---|
| MMLongBench | text + image | compression, retrieval | SubEM, Accuracy, Rouge-L, Model-Based | 5 categories and 16 datasets for vision-language long-context evaluation | 2025 |
| WikiText-103 | text | compression | PPL | 100M-token Wikipedia corpus for long-context language modeling | 2016 |
| PG-19 | text | compression | PPL | Project Gutenberg books corpus for long-context language modeling | 2019 |
| LRA | text + image | compression, retrieval | Acc | Benchmark with 6 tasks for evaluating efficient long-context language models | 2020 |
| NarrativeQA | text | retrieval | Bleu-1, Bleu-4, Meteor, Rouge-L, MRR | QA dataset for evaluating long-context QA ability | 2017 |
| TriviaQA | text | retrieval | EM, F1 | QA dataset for evaluating long-context QA ability | 2017 |
| NaturalQuestions | text | retrieval | EM, F1 | QA dataset for evaluating long-context QA ability | 2019 |
| MusiQue | text | retrieval | F1 | Multi-hop QA dataset for evaluating long-context reasoning and QA | 2021 |
| CNN/DailyMail | text | compression | Rouge-1, Rouge-2, Rouge-L | News articles dataset for long document summarization | 2016 |
| GovReport | text | compression | Rouge-1, Rouge-2, Rouge-L, Bert Score | Government agency reports for long document summarization | 2021 |
| L-Eval | text | compression, retrieval | Rouge-L, F1, GPT4 | 20-subtask benchmark for diverse long-context language model evaluation | 2023 |
| LongBench | text | compression, retrieval | F1, Rouge-L, Accuracy, EM, Edit Sim | 14 English, 5 Chinese, 2 code tasks for long-context evaluation | 2023 |
| LongBench v2 | text + table + KG | compression, retrieval | Acc | Longer, more challenging tasks with consistent multi-choice format | 2024 |
| SWE-bench | text | compression, retrieval | Resolution rate (%Resolved) | 2,294 task instances from 12 popular python repositories from GitHub | 2023 |
| SWE-bench Multimodal | text + image | compression, retrieval | Resolution rate (%Resolved), Inference cost (Avg. $ Cost) | Extending the original benchmark with image modal with 517 task instances | 2024 |
| $\infty$Bench | text | compression, retrieval | F1, Acc, ROUGE-L-Sum | 12 sub-tasks specially designed for evaluating extreme long context language models | 2024 |
| LooGLE | text | compression, retrieval | Bleu-1, Bleu-4, Rouge-1, Rouge-4, Rouge-L, Meteor score, Bert score, GPT4 score | 7 major tasks specially designed for evaluating extreme long context language models | 2023 |
Parametric Memory Modification
Table-3: Datasets for Parametric Memory Evaluation *(Continuously Updated)*
| Dataset | Modality | Operations | Metrics | Purpose | Year |
|---|---|---|---|---|---|
| KnowEdit | text | updating | Edit Success, Portability, Locality, Fluency | 6 datasets covering insertion, modification, and erasure | 2024 |
| MQUAKE-CF | text | updating | Edit-wise Success Rate, Instance-wise Accuracy, Multi-hop Accuracy | Counterfactual knowledge editing through multi-hop reasoning (up to 4 hops) | 2023 |
| MQUAKE-T | text | updating | Edit-wise Success Rate, Instance-wise Accuracy, Multi-hop Accuracy | Temporal knowledge editing with one edit per reasoning chain | 2023 |
| Counterfact | text | updating | Efficacy Score, Magnitude, Paraphrase & Neighborhood Scores | Tests substantial factual changes beyond superficial edits | 2022 |
| zsRE | text | updating | Success Rate, Retain Accuracy, Equivalence Accuracy, Perf. Deterioration | One of the earliest datasets for knowledge editing | 2021 |
| MUSE | text | forgetting | VerbMem, KnowMem, PrivLeak | Unlearning benchmark with 6 desirable properties | 2024 |
| KnowUnDo | text | forgetting | Unlearn Success, Retention Success, Perplexity, ROUGE-L | Test unlearning in copyrighted and privacy-sensitive domains | 2024 |
| RWKU | text | forgetting | ROUGE-L | Real-world unlearning under corpus-free, adversarial settings | 2024 |
| WMDP | text | forgetting | QA accuracy | Proxy for hazardous knowledge in bio/cyber/chemical domains | 2024 |
| TOFU | text | forgetting | Probability, ROUGE, Truth Ratio | Unlearning dataset of facts about 200 fictitious authors | 2024 |
| ABSA | text | consolidation | F1 | Aspect-based sentiment analysis for continual learning | 2024 |
| SGD | text | consolidation | JGA, FWT, BWT | Multi-turn task-oriented dialogue with evolving intents | 2020 |
| INSPIRED | text | consolidation | JGA, FWT, BWT | Task-oriented dialogue supporting user goal evolution | 2020 |
| Natural Question | text | consolidation | Indexing Accuracy, Hits@1 | Supports continual learning over evolving document corpora | 2019 |
Note:
- This table covers datasets for evaluating parametric memory in LLMs.
- Operations:
- updating – assessing model behavior after direct memory modification
- forgetting – evaluating unlearning/removal of specific knowledge
- consolidation – integrating new knowledge without harming prior capabilities
- Metrics include fluency, factuality, locality, transfer, edit effectiveness, and forgetting accuracy.
Evaluation for Multi-Source Memory
Table-4: Datasets for Multi-Source Memory Evaluation *(Continuously Updated)*
| Dataset | Mo | Ops | Src# | Mod# | Task | Metrics | Purpose | Year |
|---|---|---|---|---|---|---|---|---|
| MultiChat | text + image | Retrieval | 2 | 2 | Retrieval | Precision, mAP, GPT-4 | Image-grounded sticker retrieval with cross-session image-text dialogue context. | 2025 |
| Context-conflicting | text | Compression | 2 | 1 | Conflict | DiffGR, EM, Similarity | Evaluates model handling of conflicting evidence across sources. | 2024 |
| EgoSchema | video + text | Retrieval, Compression | 3 | 2 | Fusion | Accuracy | Episodic video + social schema + conversation for long-term memory QA. | 2023 |
| Ego4D NLQ | video + text | Retrieval, Compression | 2 | 2 | Fusion | Recall@K | Natural language queries over egocentric video with temporal memory. | 2022 |
| 2WikiMultihopQA | text | Indexing, Retrieval, Compression | 2 | 1 | Reasoning | EM, F1 | Multi-hop QA across Wikipedia passages with sentence-level support. | 2020 |
| HybridQA | text | Retrieval, Compression | 2 | 1 | Reasoning | EM, F1 | Reasoning across structured tables and unstructured text. | 2020 |
| CommonsenseVQA | text + image | Retrieval, Compression | 2 | 2 | Fusion | Accuracy | Commonsense QA over visual scenes requiring visual-textual fusion. | 2019 |
| NaturalQuestions | text | Retrieval, Compression | >1* | 1 | Conflict | EM, F1 | QA over Google snippets; used for contradiction analysis. | 2019 |
| ComplexWebQuestions | text | Retrieval, Compression | >1* | 1 | Reasoning | EM, F1 | Compositional QA requiring multi-step reasoning over web snippets. | 2018 |
| HotpotQA | text | Retrieval, Compression | 2 | 1 | Conflict | EM, F1, Supporting Fact Accuracy | Multi-hop QA with paragraph- and sentence-level support. | 2018 |
| TriviaQA | text | Retrieval, Compression | ≥6 | 1 | Conflict | EM, F1 | QA with noisy web sources; useful for source disagreement analysis. | 2017 |
| WebQuestionsSP | text | Indexing, Retrieval, Compression | >1* | 1 | Reasoning | F1, Accuracy | Structured QA dataset with enhanced reasoning chains. | 2016 |
| Flickr30K | text + image | Retrieval, Compression | 2 | 2 | Retrieval | Similarity | Image-caption pairs for cross-modal retrieval and alignment. | 2014 |
Note:
- Mo: Modality (e.g., text, image, video).
- Ops: Operations (e.g., Retrieval, Compression, Indexing).
- Src#: Number of sources per instance.
- Mod#: Number of modalities involved.
- Task:
- Retrieval: retrieving relevant knowledge
- Fusion: integrating multiple modalities
- Reasoning: multi-hop or logic-based inference
- Conflict: handling conflicting sources
🧠 Methods
- Overview and comparison of methods used in AI memory research.
⚙️ Tools
Components Level
Table-1: Component-Level Tools for Memory Management and Utilization. *(Continuously Updated)*
| Memory Tool | Function | Input/Output | Example Use |
|---|---|---|---|
| FAISS | Library for fast storage, indexing, and retrieval of high-dimensional vectors | Vector / Index, relevance score | Indexing large sets of text embeddings and retrieving relevant documents in RAG systems |
| Neo4j | Native graph database supporting ACID transactions and Cypher query language | Nodes and relationships with properties / Query results via Cypher | Modeling and retrieving complex relational data for use cases like fraud detection and recommendation engines |
| Chroma | AI-native embedding database for building LLM applications | Text / Embeddings | Managing knowledge, facts, and skills for LLMs |
| Milvus | Vector database for embedding similarity search and AI applications | Embeddings / Similar items | Unstructured data search and similarity matching |
| Qdrant | Vector similarity search engine and database | Embeddings / Similar items | Production-ready service with user-friendly API for vector search |
| Weaviate | Open-source vector database with built-in ML models | Data objects and vector embeddings / Search results | Scalable storage and retrieval for AI applications |
| BM25 | Probabilistic ranking function for estimating document relevance | Text queries / Ranked list of documents | Enhancing search engine results and document retrieval systems |
| Contriever | Unsupervised dense retriever trained with contrastive learning | Query text / List of similar documents | High-recall retrieval tasks in multilingual question-answering systems |
| Embedding Models (e.g., OpenAI) | Convert text, images, or audio into dense vector representations capturing semantic meaning | Raw data / Vector embeddings | Text similarity computation, recommendation systems, and clustering tasks |
Framework Level
Table-2: Framework-Level Tools for Memory Management and Utilization *(Continuously Updated)*
| Memory Tool | Function | Input/Output | Example Use | Source Type |
|---|---|---|---|---|
| Graphiti | Framework for building and querying temporally-aware knowledge graphs tailored for AI agents in dynamic environments | Multi-source data / Queryable knowledge graph | Constructing real-time knowledge graphs to enhance AI agent memory | Open |
| LlamaIndex | A flexible framework for building knowledge assistants using LLMs connected to enterprise data | Text / Context-augmented responses | Developing knowledge assistants that process complex data formats | Open |
| LangChain | Provides a framework for building context-aware, reasoning applications by connecting LLMs with external data sources | Input prompts / Multi-step reasoning outputs | Creating complex LLM applications like question-answering systems and chatbots | Open |
| LangGraph | Constructs controllable agent architectures supporting long-term memory and human-in-the-loop multi-agent systems | Graph state / State updates | Building complex task workflows with multiple AI agents | Open |
| EasyEdit | An easy-to-use knowledge editing framework for LLMs, enabling efficient behavior modification within specific domains | Edit instructions / Updated model behavior | Modifying LLM knowledge in specific domains, such as updating factual information | Open |
| CrewAI | A platform for building and deploying multi-agent systems, supporting automated workflows using any LLM and cloud platform | Multi-agent tasks / Collaborative results | Automating workflows across agents like project management and content generation | Open |
| Letta | Constructs stateful agents with long-term memory, advanced reasoning, and custom tools within a visual environment | User interactions / Improved response | Developing AI agents that learn and improve over time | Open |
| OpenHands | An open platform for autonomous software agents that maintains persistent context across file editing, command execution, and web browsing | Natural language tasks / Code patches, Terminal actions | Automating complex software engineering tasks like debugging and feature implementation with full project context | Open |
Application-Layer Level
Table-3: Application Layer-Level Tools for Memory Management and Utilization (Continuously Updated)
| Memory Tool | Function | Input/Output | Example Use | Source Type |
|---|---|---|---|---|
| Mem0 | Provides a smart memory layer for LLMs, enabling direct addition, updating, and searching of memories in models | User interactions / Personalized responses | Enhancing AI systems with persistent context for customer support and personalized recommendations | Open |
| Zep | Integrates chat messages into a knowledge graph, offering accurate and relevant user information | Chat logs, business data / Knowledge graph query results | Augmenting AI agents with knowledge through continuous learning from user interactions | Open |
| Memary | An open memory layer that emulates human memory to help AI agents manage and utilize information effectively | Agent tasks / Memory management and utilization | Building AI agents with human-like memory characteristics | Open |
| Memobase | A user profile-based long-term memory system designed to provide personalized experiences in generative AI applications | User interactions / Personalized responses | Implementing virtual assistants, educational tools, and personalized AI companions | Open |
| O-Mem | An omni-memory system enabling agents to self-evolve and maintain long-horizon consistency through recursive memory consolidation | Long-term interaction logs / Evolved memory state | Creating self-evolving personal AI assistants that adapt to user growth over time | Open |
| MemOS | An operating system-like architecture that manages memory hierarchy (working/short/long-term) to optimize Memory-Augmented Generation | Agent queries, Complex contexts / Hierarchical memory blocks | Managing complex memory resources for agents handling multi-step reasoning tasks | Open |
Product Level
Table-4: Product-Level Tools for Memory Utilization (Continuously Updated)
| Memory Tool | Function | Input/Output | Example Use | Source Type |
|---|---|---|---|---|
| Me.bot | AI-powered personal assistant that organizes notes, tasks, and memories, providing emotional support and productivity tools | User inputs (text, voice) / Organized notes, reminders, summaries | Personal productivity enhancement, emotional support, idea organization | Closed |
| ima.copilot | Intelligent workstation powered by Tencent's Mix Huang model, building a personal knowledge base for learning and work scenarios | User queries / Customized responses, knowledge retrieval | Enhancing learning efficiency, work productivity, knowledge management | Closed |
| Coze | Enables multi-agent collaboration across various platforms | User-defined workflows / Response | Deployed chatbots, AI agents | Closed |
| Grok | AI assistant developed by xAI, designed to provide truthful, useful, and curious responses, with real-time data access and image generation | Query / Informative answers, generated images | Answering questions, generating images, providing insights | Closed |
| ChatGPT | Conversational AI developed by OpenAI, capable of understanding and generating human-like text based on prompts | User prompts / Generated text responses | Answering questions, generating images, providing insights | Closed |
| Claude | AI assistant featuring "Projects" to ground answers in user-provided knowledge bases and massive context windows | Prompts, Files, Code / Text, Code, Artifacts | Analyzing large codebases, maintaining consistent style across documents via Projects | Closed |
| Doubao | A high-efficiency multimodal AI assistant capable of handling long-context interactions and diverse tasks | Text, Voice, Image / Answers, creative content | Daily conversation, writing assistance, coding, and role-playing | Closed |
| Siri | Intelligent voice assistant utilizing on-device personal semantic memory for cross-app actions and context understanding | Voice commands / Action execution, personal info retrieval | Device control, retrieving personal context ("When is Mom's flight?"), cross-app tasks | Closed |
| Xiaoyi | Huawei's smart assistant integrated into HarmonyOS, leveraging ecosystem memory for proactive services and document processing | Voice, Text, Documents / Summaries, suggestions, IoT control | Document summarization, smart home control, personalized travel planning | Closed |
| Zhixiaobao | Ant Group's financial AI agent that utilizes user financial history and market knowledge for personalized wealth management | Financial queries / Market analysis, investment advice | Financial planning, insurance analysis, market trend explanation | Closed |
🆚 Human vs. AI in Memory
Table-5: Key differences between human and agent memory across operational dimensions
| Aspect | Human Memory | Agent Memory |
|---|---|---|
| Storage | Distributed, interconnected neural systems across brain regions | Parametric, modular, and context-dependent (structured or unstructured) |
| Consolidation | Slow, biologically driven, passive | Fast, explicit, policy-driven and selective |
| Indexing | Implicit, associative, sparse codes via hippocampal circuits | Explicit, embedding-based, symbolic or key–value lookup |
| Updating | Indirect, reconsolidation-based, error-prone | Precise, programmable, supports rollback/unlearning |
| Forgetting | Passive decay or interference | Transparent, trackable, policy-controlled |
| Retrieval | Cue/context/emotion dependent, emotionally biased | Content-based, reproducible, similarity or query driven |
| Compression | Implicit, salience- and frequency-biased | Explicit, customizable (e.g., quantization, summarization) |
| Ownership | Individual and private | Shareable, replicable, and broadcastable |
| Volume | Biologically limited | Scalable, bounded only by storage and compute limits |
🌞 Future Directions
Acknowledgements
Please contact me if I miss your names in the list, I will add you back ASAP!
🤝🤝 Thanks for all the great contributors on GitHub!
If you find our repository and survey useful for your research, please consider citing the following paper:
@article{du2025rethinking,
  title={Rethinking Memory in AI: Taxonomy, Operations, Topics, and Future Directions},
  author={Du, Yiming and Huang, Wenyu and Zheng, Danna and Wang, Zhaowei and Montella, Sebastien and Lapata, Mirella and Wong, Kam-Fai and Pan, Jeff Z.},
  journal={arXiv preprint arXiv:2505.00675},
  year={2025},
  url={https://arxiv.org/abs/2505.00675}
}
Contributors
Star History
Contributors


This repository introduce a comprehensive paper list, datasets, methods and tools for memory research.
354
53 commits
updated Dec 29, 2025
README
Memory Compass
Rethinking Memory in AI: Taxonomy, Operations, Topics, and Future Directions
This repository introduce a comprehensive paper list, datasets, methods and tools for memory research.
Contents
- Rethinking Memory in AI: Taxonomy, Operations, Topics, and Future Directions
📢 News
- 🚀 Memory-T1 Released! We propose a new RL method designed for temporal reasoning and long-term memory in large language models. Memory-T1 focuses on multi-session interactions and realistic temporal dependencies, enabling systematic evaluation of memory-aware agents.
- Version 3 is availabel!
- Paper List, benchmarks and tools has been udpated.
- Version 2 of our work is now available.
Memory Taxonomy
📜 Papers
1. Survey Papers
2025
-
Memory in the Age of AI Agents Yuyang Hu, Shichun Liu, Yanwei Yue, Guibin Zhang, Boyang Liu, Fangyi Zhu, Jiahang Lin, Honglin Guo, Shihan Dou, Zhiheng Xi, Senjie Jin, Jiejun Tan, Yanbin Yin, Jiongnan Liu, Zeyu Zhang, Zhongxiang Sun, Yutao Zhu, Hao Sun, Boci Peng, Zhenrong Cheng, Xuanbo Fan, Jiaxin Guo, Xinlei Yu, Zhenhong Zhou, Zewen Hu, Jiahao Huo, Junhao Wang, Yuwei Niu, Yu Wang, Zhenfei Yin, Xiaobin Hu, Yue Liao, Qiankun Li, Kun Wang, Wangchunshu Zhou, Yixin Liu, Dawei Cheng, Qi Zhang, Tao Gui, Shirui Pan, Yan Zhang, Philip Torr, Zhicheng Dou, Ji-Rong Wen, Xuanjing Huang, Yu-Gang Jiang, Shuicheng Yan. Arxiv 2025.
-
A Comprehensive Survey of Machine Unlearning Techniques for Large Language Models Jiahui Geng, Qing Li, Herbert Woisetschlaeger, Zongxiong Chen, Yuxia Wang, Preslav Nakov, Hans-Arno Jacobsen, Fakhri Karray. Arxiv 2025.
-
A Comprehensive Survey on Long Context Language Modeling Jiaheng Liu, Dawei Zhu, Zhiqi Bai, Yancheng He, Huanxuan Liao, Haoran Que, Zekun Wang, Chenchen Zhang, Ge Zhang, Jiebin Zhang, Yuanxing Zhang, Zhuo Chen, Hangyu Guo, Shilong Li, Ziqiang Liu, Yong Shan, Yifan Song, Jiayi Tian, Wenhao Wu, Zhejian Zhou, Ruijie Zhu, Junlan Feng, Yang Gao, Shizhu He, Zhoujun Li, Tianyu Liu, Fanyu Meng, Wenbo Su, Yingshui Tan, Zili Wang, Jian Yang, Wei Ye, Bo Zheng, Wangchunshu Zhou, Wenhao Huang, Sujian Li, Zhaoxiang Zhang Arxiv 2025.
-
A Survey of Personalized Large Language Models: Progress and Future Directions Jiahong Liu, Zexuan Qiu, Zhongyang Li, Quanyu Dai, Jieming Zhu, Minda Hu, Menglin Yang, Irwin King. Arxiv 2025.
-
Prompt Compression for Large Language Models: A Survey Zongqian Li, Yinhong Liu, Yixuan Su, Nigel Collier NAACL 2025.
-
Cognitive Memory in Large Language Models Lianlei Shan, Shixian Luo, Zezhou Zhu, Yu Yuan, Yong Wu. Arxiv 2025.
-
Human-inspired Perspectives: A Survey on AI Long-term Memory Zihong He, Weizhe Lin, Hao Zheng, Fan Zhang, Matt W. Jones, Laurence Aitchison, Xuhai Xu, Miao Liu, Per Ola Kristensson, Junxiao Shen. Arxiv 2025.
2024
-
Knowledge Conflicts for LLMs: A Survey Rongwu Xu, Zehan Qi, Zhijiang Guo, Cunxiang Wang, Hongru Wang, Yue Zhang, Wei Xu. EMNLP 2024.
-
A Survey on the Memory Mechanism of Large Language Model based Agents. Zhang, Zeyu and Bo, Xiaohe and Ma, Chen and Li, Rui and Chen, Xu and Dai, Quanyu and Zhu, Jieming and Dong, Zhenhua and Wen, Ji-Rong. Arxiv 2024.
-
Knowledge Editing for Large Language Models: A Survey Song Wang, Yaochen Zhu, Haochen Liu, Zaiyi Zheng, Chen Chen, Jundong Li. Arxiv 2024.
-
Advancing Transformer Architecture in Long-Context Large Language Models: A Comprehensive Survey Yunpeng Huang, Jingwei Xu, Junyu Lai, Zixu Jiang, Taolue Chen, Zenan Li, Yuan Yao, Xiaoxing Ma, Lijuan Yang, Hao Chen, Shupeng Li, Penghao Zhao. Arxiv 2024.
2. Memory Topics
2.1 Long Term Memory
2025
-
PersonaMem-v2: Towards Personalized Intelligence via Learning Implicit User Personas and Agentic Memory Bowen Jiang, Yuan Yuan, Maohao Shen, Zhuoqun Hao, Zhangchen Xu, Zichen Chen, Zijun Liu, Anirudh Ravi Vijjini, Jiaming He, and others. Arxiv 2025.
-
O-Mem: Omni Memory System for Personalized, Long Horizon, Self-Evolving Agents Piaohong Wang, Motong Tian, Jiaxian Li, Yuan Liang, Yuqing Wang, Qianben Chen, Tiannan Wang, Zhicong Lu, Jiawei Ma, Yuchen Eleanor Jiang, Wangchunshu Zhou. Arxiv 2025.
-
MemoryBench: A Benchmark for Memory and Continual Learning in LLM Systems Yifan Song, Weimin Xiong, Dawei Zhu, Cheng Li, Ke Wang, and others. Arxiv 2025.
-
Agent Learning via Early Experience Kai Zhang, Xiangchao Chen, Bo Liu, Tianci Xue, Zeyi Liao, Zhihan Liu, Xiyao Wang, Yuting Ning, Zhaorun Chen, Xiaohan Fu, and others. Arxiv 2025.
-
G-Memory: Tracing Hierarchical Memory for Multi-Agent Systems Guibin Zhang, Muxin Fu, Guancheng Wan, Miao Yu, Kun Wang, Shuicheng Yan. Arxiv 2025.
-
HaluMem: Evaluating Hallucinations in Memory Systems of Agents Ding Chen, Simin Niu, Kehang Li, Peng Liu, Xiangping Zheng, Bo Tang, Xinchi Li, Feiyu Xiong, Zhiyu Li. Arxiv 2025.
-
MemAgent: Reshaping Long-Context LLM with Multi-Conv RL-based Memory Agent Hongli Yu, Tinghong Chen, Jiangtao Feng, Jiangjie Chen, Weinan Dai, Qiying Yu, Ya-Qin Zhang, Wei-Ying Ma, Jingjing Liu, Mingxuan Wang, and others. Arxiv 2025.
-
Evaluating Memory in LLM Agents via Incremental Multi-Turn Interactions Yuanzhe Hu, Yu Wang, Julian McAuley. Arxiv 2025.
-
Mem0: Building production-ready ai agents with scalable long-term memory Prateek Chhikara, Dev Khant, Saket Aryan, Taranjeet Singh, Deshraj Yadav. Arxiv 2025.
-
MemOS: An Operating System for Memory-Augmented Generation (MAG) in Large Language Models Zhiyu Li, Shichao Song, Hanyu Wang, Simin Niu, Ding Chen, Jiawei Yang, Chenyang Xi, Huayi Lai, Jihao Zhao, Yezhaohui Wang, and others. Arxiv 2025.
-
LightMem: Lightweight and Efficient Memory-Augmented Generation Qingyang Zhang, Ningyu Zhang, and others. Arxiv 2025.
-
Memory OS of AI Agent Jiazheng Kang, Mingming Ji, Zhe Zhao, Ting Bai. Arxiv 2025.
-
MemU: An open-source memory framework for AI companions NevaMind-AI. GitHub 2025.
-
Hierarchical Memory for High-Efficiency Long-Term Reasoning in LLM Agents Haoran Sun, Shaoning Zeng. Arxiv 2025.
-
ReasoningBank: Scaling Agent Self-Evolving with Reasoning Memory Siru Ouyang, Jun Yan, I-Hung Hsu, Yanfei Chen, Ke Jiang, Zifeng Wang, Rujun Han, Long T. Le, Samira Daruki, Xiangru Tang, Vishy Tirumalashetty, George Lee, Mahsan Rofouei, Hangfei Lin, Jiawei Han, Chen-Yu Lee, Tomas Pfister. Arxiv 2025.
-
Agentic Context Engineering: Evolving Contexts for Self-Improving Language Models Qizheng Zhang, Changran Hu, Shubhangi Upasani, Boyuan Ma, Fenglu Hong, Vamsidhar Kamanuru, Jay Rainton, Chen Wu, Mengmeng Ji, Hanchen Li, Urmish Thakker, James Zou, Kunle Olukotun. Arxiv 2025.
-
Coarse-to-Fine Grounded Memory for LLM Agent Planning Wei Yang, Jinwei Xiao, Hongming Zhang, Qingyang Zhang, Yanna Wang, Bo Xu. Arxiv 2025.
-
Chain-of-Memory: Enhancing GUI Agents for Cross-Application Navigation Xinzge Gao, Chuanrui Hu, Bin Chen, Teng Li. Arxiv 2025.
-
MEM1: Learning to Synergize Memory and Reasoning for Efficient Long-Horizon Agents Zijian Zhou, Ao Qu, Zhaoxuan Wu, Sunghwan Kim, Alok Prakash, Daniela Rus, Jinhua Zhao, Bryan Kian Hsiang Low, Paul Pu Liang. Arxiv 2025.
-
Tremu: Towards Neuro-Symbolic Temporal Reasoning for LLM-Agents with Memory in Multi-Session Dialogues Yubin Ge, Salvatore Romeo, Jason Cai, Raphael Shu, Monica Sunkara, Yassine Benajiba, Yi Zhang. Arxiv 2025.
-
Emergence of Episodic Memory in Transformers: Characterizing Changes in Temporal Structure of Attention Scores During Training Deven Mahesh Mistry, Anooshka Bajaj, Yash Aggarwal, Sahaj Singh Maini, Zoran Tiganj. Arxiv 2025.
-
Concept-Reversed Winograd Schema Challenge: Evaluating and Improving Robust Reasoning in Large Language Models via Abstraction Kaiqiao Han, Tianqing Fang, Zhaowei Wang, Yangqiu Song, Mark Steedman. NAACL 2025.
-
Learn to Memorize: Optimizing LLM-based Agents with Adaptive Memory Framework Zeyu Zhang, Quanyu Dai, Rui Li, Xiaohe Bo, Xu Chen, Zhenhua Dong. Arxiv 2025.
-
Memory-R1: Enhancing large language model agents to manage and utilize memories via reinforcement learning Sikuan Yan, Xiufeng Yang, Zuchao Huang, Ercong Nie, Zifeng Ding, Zonggen Li, Xiaowen Ma, Hinrich Schütze, Volker Tresp, Yunpu Ma. Arxiv 2025.
-
Mem-$\alpha$: Learning Memory Construction via Reinforcement Learning Yu Wang, Ryuichi Takanobu, Zhiqi Liang, Yuzhen Mao, Yuanzhe Hu, Julian McAuley, Xiaojian Wu. Arxiv 2025.
-
AgentFly: Fine-tuning LLM Agents without Fine-tuning LLMs Huichi Zhou, Yihang Chen, Siyuan Guo, Xue Yan, Kin Hei Lee, Zihan Wang, Ka Yiu Lee, Guchun Zhang, Kun Shao, Linyi Yang, and others. Arxiv 2025.
-
MemAgent: Reshaping Long-Context LLM with Multi-Conv RL-based Memory Agent Hongli Yu, Tinghong Chen, Jiangtao Feng, Jiangjie Chen, Weinan Dai, Qiying Yu, Ya-Qin Zhang, Wei-Ying Ma, Jingjing Liu, Mingxuan Wang, and others. Arxiv 2025.
-
Evaluating Memory in LLM Agents via Incremental Multi-Turn Interactions Yuanzhe Hu, Yu Wang, Julian McAuley. Arxiv 2025.
-
MemBench: Towards More Comprehensive Evaluation on the Memory of LLM-based Agents Haoran Tan, Zeyu Zhang, Chen Ma, Xu Chen, Quanyu Dai, Zhenhua Dong. Arxiv 2025.
-
MemGuide: Intent-Driven Memory Selection for Goal-Oriented Multi-Session LLM Agents Yiming Du, Bingbing Wang, Yang He, Bin Liang, Baojun Wang, Zhongyang Li, Lin Gui, Jeff Z. Pan, Ruifeng Xu, Kam-Fai Wong. Arxiv 2025.
-
MemTool: Optimizing Short-Term Memory Management for Dynamic Tool Calling in LLM Agent Multi-Turn Conversations Elias Lumer, Anmol Gulati, Vamse Kumar Subbiah, Pradeep Honaganahalli Basavaraju, James A Burke. Arxiv 2025.
-
Memp: Exploring Agent Procedural Memory Runnan Fang, Yuan Liang, Xiaobin Wang, Jialong Wu, Shuofei Qiao, Pengjun Xie, Fei Huang, Huajun Chen, Ningyu Zhang. Arxiv 2025.
-
LongMemEval: Benchmarking Chat Assistants on Long-Term Interactive Memory Di Wu, Hongwei Wang, Wenhao Yu, Yuwei Zhang, Kai-Wei Chang, Dong Yu. ICLR 2025.
-
Compress to Impress: Unleashing the Potential of Compressive Memory in Real-World Long-Term Conversations Nuo Chen, Hongguang Li, Jia Li, Yuxuan Li, Wei Wu. COLING 2025.
-
Towards Lifelong Dialogue Agents via Timeline-based Memory Management Kai Tzu-iunn Ong, Namyoung Kim, Minju Gwak, Hyungjoo Chae, Taeyoon Kwon, Yohan Jo, Seung-won Hwang, Dongha Lee, Jinyoung Yeo. NAACL 2025.
-
Zep: A Temporal Knowledge Graph Architecture for Agent Memory Preston Rasmussen, Daniel Chalef. Arxiv 2025.
-
From RAG to Memory: Non-Parametric Continual Learning for Large Language Models Bernal Jiménez Gutiérrez, Yiheng Shu, Weijian Qi, Sizhe Zhou, Yu Su. ICML 2025.
-
Disentangling Memory and Reasoning Ability in Large Language Models Mingyu Jin, Weidi Luo, Sitao Cheng, Xinyi Wang, Wenyue Hua, Ruixiang Tang, William Yang Wang, Yongfeng Zhang. Arxiv 2025.
-
MemoRAG: Boosting Long Context Processing with Global Memory-Enhanced Retrieval Augmentation Hongjin Qian, Zheng Liu, Peitian Zhang, Kelong Mao, Defu Lian, Zhicheng Dou, Tiejun Huang. Arxiv 2025.
-
Hello Again! LLM-powered Personalized Agent for Long-term Dialogue Hao Li, Chenghao Yang, An Zhang, Yang Deng, Xiang Wang, Tat-Seng Chua. NAACL 2025.
-
MemInsight: Autonomous Memory Augmentation for LLM Agents Rana Salama, Jason Cai, Michelle Yuan, Anna Currey, Monica Sunkara, Yi Zhang, Yassine Benajiba. Arxiv 2025.
-
Interpersonal Memory Matters: A New Task for Proactive Dialogue Utilizing Conversational History Bowen Wu, Wenqing Wang, Haoran Li, Ying Li, Jingsong Yu, Baoxun Wang. Arxiv 2025.
-
Echo: A Large Language Model with Temporal Episodic Memory WenTao Liu, Ruohua Zhang, Aimin Zhou, Feng Gao, JiaLi Liu. Arxiv 2025.
-
Improving Factuality with Explicit Working Memory Mingda Chen, Yang Li, Karthik Padthe, Rulin Shao, Alicia Sun, Luke Zettlemoyer, Gargi Ghosh, Wen-tau Yih. Arxiv 2025.
-
Memorization Over Reasoning? Exposing and Mitigating Verbatim Memorization in Large Language Models' Character Understanding Evaluation Yuxuan Jiang, Francis Ferraro. Arxiv 2025.
-
Self-Memory Alignment: Mitigating Factual Hallucinations with Generalized Improvement Siyuan Zhang, Yichi Zhang, Yinpeng Dong, Hang Su. Arxiv 2025.
-
Needle in the Haystack for Memory Based Large Language Models Elliot Nelson, Georgios Kollias, Payel Das, Subhajit Chaudhury, Soham Dan. ICLR 2025.
2024
-
Evaluating Very Long-Term Conversational Memory of LLM Agents Adyasha Maharana, Dong-Ho Lee, Sergey Tulyakov, Mohit Bansal, Francesco Barbieri, Yuwei Fang. ACL 2024.
-
MemoryBank: Enhancing Large Language Models with Long-Term Memory Wanjun Zhong, Lianghong Guo, Qiqi Gao, He Ye, Yanlin Wang. AAAI 2024.
-
A-MEM: Agentic Memory for LLM Agents Wujiang Xu, Kai Mei, Hang Gao, Juntao Tan, Zujie Liang, Yongfeng Zhang. Arxiv 2024.
-
Optimus-1: Hybrid Multimodal Memory Empowered Agents Excel in Long-Horizon Tasks Zaijing Li, Yuquan Xie, Rui Shao, Gongwei Chen, Dongmei Jiang, Liqiang Nie. NeurIPS 2024.
-
HippoRAG: Neurobiologically Inspired Long-Term Memory for Large Language Models Bernal Jiménez Gutiérrez, Yiheng Shu, Yu Gu, Michihiro Yasunaga, Yu Su. NeurIPS 2024.
-
"My agent understands me better": Integrating Dynamic Human-like Memory Recall and Consolidation in LLM-Based Agents Yu Hou, Tamoto Yuta, Mayur Tikundi. Arxiv 2024.
-
Mr.Steve: Instruction-Following Agents in Minecraft with What-Where-When Memory Yu Hou, Tamoto Yuta, Mayur Tikundi. ICLR 2024.
-
StableSSM: Alleviating the Curse of Memory in State-space Models through Stable Reparameterization Shida Wang, Qianxiao Li. ICML 2024.
-
Crafting Personalized Agents through Retrieval-Augmented Generation on Editable Memory Graphs Zheng Wang, Zhongyang Li, Zeren Jiang, Dandan Tu, Wei Shi. EMNLP 2024.
-
Towards Verifiable Text Generation with Evolving Memory and Self-Reflection Hao Sun, Hengyi Cai, Bo Wang, Yingyan Hou, Xiaochi Wei, Shuaiqiang Wang, Yan Zhang, Dawei Yin. EMNLP 2024.
-
PerLTQA: A Personal Long-Term Memory Dataset for Memory Classification, Retrieval, and Synthesis in Question Answering Yiming Du, Hongru Wang, Zhengyi Zhao, Bin Liang, Baojun Wang, Wanjun Zhong, Zezhong Wang, Kam-Fai Wong. Arxiv 2024.
-
An Iterative Associative Memory Model for Empathetic Response Generation Zhou Yang, Zhaochun Ren, Yufeng Wang, Haizhou Sun, Chao Chen, Xiaofei Zhu, Xiangwen Liao. ACL 2024.
-
COCOA: CBT-based Conversational Counseling Agent Using Memory Specialized in Cognitive Distortions and Dynamic Prompt Suyeon Lee, Jieun Kang, Harim Kim, Kyoung-Mee Chung, Dongha Lee, Jinyoung Yeo. Arxiv 2024.
-
Mixed-Session Conversation with Egocentric Memory Jihyoung Jang, Taeyoung Kim, Hyounghun Kim. EMNLP 2024.
-
FragRel: Exploiting Fragment-level Relations in the External Memory of Large Language Models Xihang Yue, Linchao Zhu, Yi Yang. ACL 2024.
-
Extractive Medical Entity Disambiguation with Memory Mechanism and Memorized Entity Information Guobiao Zhang, Xueping Peng, Tao Shen, Guodong Long, Jiasheng Si, Libo Qin, Wenpeng Lu. EMNLP 2024.
-
Ever-Evolving Memory by Blending and Refining the Past Seo Hyun Kim, Keummin Ka, Yohan Jo, Seung-won Hwang, Dongha Lee, Jinyoung Yeo. Arxiv 2024.
-
Synapse: Trajectory-as-Exemplar Prompting with Memory for Computer Control Longtao Zheng, Rundong Wang, Xinrun Wang, Bo An. Arxiv 2024.
-
Moviechat: From dense token to sparse memory for long video understanding Enxin Song, Wenhao Chai, Guanhong Wang, Yucheng Zhang, Haoyang Zhou, Feiyang Wu, Haozhe Chi, Xun Guo, Tian Ye, Yanting Zhang, Yan Lu, Jenq-Neng Hwang, Gaoang Wang. CVPR 2024.
-
lamp: when large language models meet personalization Alireza Salemi, Sheshera Mysore, Michael Bendersky, Hamed Zamani. ACL 2024.
-
Evidence-Driven Retrieval Augmented Response Generation for Online Misinformation Zhenrui Yue, Huimin Zeng, Yimeng Lu, Lanyu Shang, Yang Zhang, Dong Wang. NAACL 2024.
-
IterCQR: Iterative Conversational Query Reformulation with Retrieval Guidance Yunah Jang, Kang-il Lee, Hyunkyung Bae, Hwanhee Lee, Kyomin Jung. NAACL 2024.
-
Memory Layers at Scale Vincent-Pierre Berges, Barlas Oğuz, Daniel Haziza, Wen-tau Yih, Luke Zettlemoyer, Gargi Ghosh. Arxiv 2024.
2023
-
MoT: Memory-of-Thought Enables ChatGPT to Self-Improve Sureman Lee, Yujie Qian, Yujia Xie, Yifan Hou, Xinyan Wang, Yiming Yang, Xiang Ren. EMNLP 2023.
-
Think-in-memory: Recalling and post-thinking enable llms with long-term memory Lei Liu, Xiaoyan Yang, Yue Shen, Binbin Hu, Zhiqiang Zhang, Jinjie Gu, Guannan Zhang. Arxiv 2023.
-
Recursively Summarizing Enables Long-Term Dialogue Memory in Large Language Models Qingxue Wang, Ling Ding, Yaran Cao, Zhilang Tan, Shi Wang, Dacheng Tao, Liu Qiu. Arxiv 2023.
-
LLM-based Medical Assistant Personalization with Short- and Long-Term Memory Coordination Yuwei Zhang, Yifan Hou, Xinyan Wang, Yiming Yang, Xiang Ren. Arxiv 2023.
-
SCM: Enhancing Large Language Model with Self-Controlled Memory Framework Bing Wang, Xinnian Liang, Jian Yang, Hui Huang, Shuangzhi Wu, Peihao Wu, Lu Lu, Zejun Ma, Zhoujun Li. Arxiv 2023.
-
LDM²: A Large Decision Model Imitating Human Cognition with Dynamic Memory Enhancement Xingjin Wang, Linjing Li, Dongfeng Zeng. EMMNLP 2023.
-
NarrativeXL: A Large-scale Dataset For Long-Term Memory Models Arseny Moskvichev, Ky-Vinh Mai. EMNLP 2023.
-
Who's Harry Potter? Approximate Unlearning in LLMs Ronen Eldan, Mark Russinovich. Arxiv 2023.
-
Active Retrieval Augmented Generation Zhengbao Jiang, Frank Xu, Luyu Gao, Zhiqing Sun, Qian Liu, Jane Dwivedi-Yu, Yiming Yang, Jamie Callan, Graham Neubig. EMNLP 2023.
-
Prompted LLMs as Chatbot Modules for Long Open-domain Conversation Gibbeum Lee, Volker Hartmann, Jongho Park, Dimitris Papailiopoulos, Kangwook Lee. ACL 2023.
-
MemoChat: Tuning LLMs to Use Memos for Consistent Long-Range Open-Domain Conversation Junru Lu, Siyu An, Mingbao Lin, Gabriele Pergola, Yulan He, Di Yin, Xing Sun, Yunsheng Wu. Arxiv 2023.
-
Learning Retrieval Augmentation for Personalized Dialogue Generation Qiushi Huang, Shuai Fu, Xubo Liu, Wenwu Wang, Tom Ko, Yu Zhang, Lilian Tang. EMNLP 2023.
-
Learning to Reason and Memorize with Self-Notes Jack Lanchantin, Shubham Toshniwal, Jason Weston, Arthur Szlam, Sainbayar Sukhbaatar. NeurIPS 2023.
-
RECAP: Retrieval-Enhanced Context-Aware Prefix Encoder for Personalized Dialogue Response Generation Shuai Liu, Hyundong Cho, Marjorie Freedman, Xuezhe Ma, Jonathan May. ACL 2023.
-
Enhancing Personalized Dialogue Generation with Contrastive Latent Variables: Combining Sparse and Dense Persona Yihong Tang, Bo Wang, Miao Fang, Dongming Zhao, Kun Huang, Ruifang He, Yuexian Hou. ACL 2023.
-
Transformer-based World Models Are Happy With 100k Interactions Jan Robine, Marc Höftmann, Tobias Uelwer, Stefan Harmeling. ICLR 2023.
2022 & before
-
Beyond Goldfish Memory: Long-Term Open-Domain Conversation Jing Xu, Arthur Szlam, Jason Weston. ACL 2022.
-
Long Time No See! Open-Domain Conversation with Long-Term Persona Memory Xinchao Xu, Zhibin Gou, Wenquan Wu, Zheng-Yu Niu, Hua Wu, Haifeng Wang, Shihang Wang. ACL 2022.
-
Keep Me Updated! Memory Management in Long-term Conversations Sanghwan Bae, Donghyun Kwak, Soyoung Kang, Min Young Lee, Sungdong Kim, Yuin Jeong, Hyeri Kim, Sang-Woo Lee, Woomyoung Park, Nako Sung. EMNLP 2022.
-
Towards Teachable Reasoning Systems: Using a Dynamic Memory of User Feedback for Continual System Improvement Bhavana Dalvi Mishra, Oyvind Tafjord, Peter Clark. EMNLP 2022.
-
Learning to Repair: Repairing Model Output Errors after Deployment Using a Dynamic Memory of Feedback Niket Tandon, Aman Madaan, Peter Clark, Yiming Yang. NAACL 2022.
-
There Are a Thousand Hamlets in a Thousand People's Eyes: Enhancing Knowledge-grounded Dialogue with Personal Memory Tingchen Fu, Xueliang Zhao, Chongyang Tao, Ji-Rong Wen, Rui Yan. ACL 2022.
-
Training Language Models with Memory Augmentation Zexuan Zhong, Tao Lei, Danqi Chen. EMNLP 2022.
-
Improving Multi-turn Emotional Support Dialogue Generation with Lookahead Strategy Planning Yi Cheng, Wenge Liu, Wenjie Li, Jiashuo Wang, Ruihui Zhao, Bang Liu, Xiaodan Liang, Yefeng Zheng. EMNLP 2022.
-
Less is More: Learning to Refine Dialogue History for Personalized Dialogue Generation Hanxun Zhong, Zhicheng Dou, Yutao Zhu, Hongjin Qian, Ji-Rong Wen. NAACL 2022.
-
Leveraging Similar Users for Personalized Language Modeling with Limited Data Charles Welch, Chenxi Gu, Jonathan K. Kummerfeld, Veronica Perez-Rosas, Rada Mihalcea. ACL 2022.
-
PerKGQA: Question Answering over Personalized Knowledge Graphs Ritam Dutt, Kasturi Bhattacharjee, Rashmi Gangadharaiah, Dan Roth, Carolyn Rose. NAACL 2022.
-
A Cooperative Memory Network for Personalized Task-oriented Dialogue Systems with Incomplete User Profiles Jiahuan Pei, Pengjie Ren, Maarten de Rijke. WWW 2021.
-
Episodic Memory in Lifelong Language Learning Cyprien de Masson d'Autume, Sebastian Ruder, Lingpeng Kong, Dani Yogatama. NeurIPS 2019.
2.2 Long Context Memory
2025
- Titans: Learning to Memorize at Test Time Ali Behrouz, Peilin Zhong, Vahab Mirrokni. Arxiv 2025.
- RocketKV: Accelerating Long-Context LLM Inference via Two-Stage KV Cache Compression Payman Behnam, Yaosheng Fu, Ritchie Zhao, Po-An Tsai, Zhiding Yu, Alexey Tumanov. ICML 2025.
- CateKV: On Sequential Consistency for Long-Context LLM Inference Acceleration Haoyun Jiang, Haolin Li, Jianwei Zhang, Fei Huang, Qiang Hu, Minmin Sun, Shuai Xiao, Yong Li, Junyang Lin, Jiangchao Yao. ICML 2025.
- LaCache: Ladder-Shaped KV Caching for Efficient Long-Context Modeling of Large Language Models Dachuan Shi, Yonggan Fu, Xiangchi Yuan, Zhongzhi Yu, Haoran You, Sixu Li, Xin Dong, Jan Kautz, Pavlo Molchanov, Yingyan Celine Lin. ICML 2025.
- ShadowKV: KV Cache in Shadows for High-Throughput Long-Context LLM Inference Hanshi Sun, Li-Wen Chang, Wenlei Bao, Size Zheng, Ningxin Zheng, Xin Liu, Harry Dong, Yuejie Chi, Beidi Chen. ICML 2025.
- Kelle: Co-design KV Caching and eDRAM for Efficient LLM Serving in Edge Computing Tianhua Xia, Sai Qian Zhang. Arxiv 2025.
- AgentFold: Long-Horizon Web Agents with Proactive Context Management Rui Ye, Zhongwang Zhang, Kuan Li, Huifeng Yin, Zhengwei Tao, Yida Zhao, Liangcai Su, Liwen Zhang, Zile Qiao, Xinyu Wang, Pengjun Xie, Fei Huang, Siheng Chen, Jingren Zhou, Yong Jiang. Arxiv 2025.
- Scaling Long-Horizon LLM Agent via Context-Folding Weiwei Sun, Miao Lu, Zhan Ling, Kang Liu, Xuesong Yao, Yiming Yang, Jiecao Chen. Arxiv 2025.
- Agentic Context Engineering: Evolving Contexts for Self-Improving Language Models Qizheng Zhang, Changran Hu, Shubhangi Upasani, Boyuan Ma, Fenglu Hong, Vamsidhar Kamanuru, Jay Rainton, Chen Wu, Mengmeng Ji, Hanchen Li, and others. Arxiv 2025.
- MMLongBench: Benchmarking Long-Context Vision-Language Models Effectively and Thoroughly Zhaowei Wang, Wenhao Yu, Xiyu Ren, Jipeng Zhang, Yu Zhao, Rohit Saxena, Liang Cheng, Ginny Wong, Simon See, Pasquale Minervini, and others. Neurips 2025.
- Radar: Fast Long-Context Decoding for Any Transformer Yongchang Hao, Mengyao Zhai, Hossein Hajimirsadeghi, Sepidehsadat Hosseini, Frederick Tung. ICLR 2025.
- Not All Heads Matter: A Head-Level KV Cache Compression Method with Integrated Retrieval and Reasoning Yu Fu, Zefan Cai, Abedelkadir Asi, Wayne Xiong, Yue Dong, Wen Xiao. ICLR 2025.
- Long Context Compression with Activation Beacon Peitian Zhang, Zheng Liu, Shitao Xiao, Ninglu Shao, Qiwei Ye, Zhicheng Dou. ICLR 2025.
- Selective Attention Improves Transformer Yaniv Leviathan, Matan Kalman, Yossi Matias. ICLR 2025.
- Streaming Video Question-Answering with In-context Video KV-Cache Retrieval Shangzhe Di, Zhelun Yu, Guanghao Zhang, Haoyuan Li, TaoZhong, Hao Cheng, Bolin Li, Wanggui He, Fangxun Shu, Hao Jiang. ICLR 2025.
- Accelerating Inference of Retrieval-Augmented Generation via Sparse Context Selection Yun Zhu, Jia-Chen Gu, Caitlin Sikora, Ho Ko, Yinxiao Liu, Chu-Cheng Lin, Lei Shu, Liangchen Luo, Lei Meng, Bang Liu, Jindong Chen. ICLR 2025.
- You Only Read Once (YORO): Learning to Internalize Database Knowledge for Text-to-SQL Hideo Kobayashi, Wuwei Lan, Peng Shi, Shuaichen Chang, Jiang Guo, Henghui Zhu, Zhiguo Wang, Patrick Ng. NAACL 2025.
- Masking in Multi-hop QA: An Analysis of How Language Models Perform with Context Permutation Wenyu Huang, Pavlos Vougiouklis, Mirella Lapata, Jeff Z. Pan. ACL 2025.
- Long-Context LLMs Meet RAG: Overcoming Challenges for Long Inputs in RAG Bowen Jin, Jinsung Yoon, Jiawei Han, Sercan O Arik. ICLR 2025.
2024
- Efficient Streaming Language Models with Attention Sinks Guangxuan Xiao, Yuandong Tian, Beidi Chen, Song Han, Mike Lewis. ICLR 2024.
- LM-Infinite: Zero-Shot Extreme Length Generalization for Large Language Models Chi Han, Qifan Wang, Hao Peng, Wenhan Xiong, Yu Chen, Heng Ji, Sinong Wang. NAACL 2024.
- Layer-Condensed KV Cache for Efficient Inference of Large Language Models Haoyi Wu, Kewei Tu. ACL 2024.
- Model Tells You What to Discard: Adaptive KV Cache Compression for LLMs Suyu Ge, Yunan Zhang, Liyuan Liu, Minjia Zhang, Jiawei Han, Jianfeng Gao. ICLR 2024.
- NACL: A General and Effective KV Cache Eviction Framework for LLM at Inference Time Yilong Chen, Guoxia Wang, Junyuan Shang, Shiyao Cui, Zhenyu Zhang, Tingwen Liu, Shuohuan Wang, Yu Sun, Dianhai Yu, Hua Wu. ACL 2024.
- SnapKV: LLM Knows What You Are Looking for before Generation Yuhong Li, Yingbing Huang, Bowen Yang, Bharat Venkitesh, Acyr Locatelli, Hanchen Ye, Tianle Cai, Patrick Lewis, Deming Chen. NeurIPS 2024.
- PyramidInfer: Pyramid KV Cache Compression for High-throughput LLM Inference Dongjie Yang, Xiaodong Han, Yan Gao, Yao Hu, Shilin Zhang, Hai Zhao. ACL 2024.
- A Simple and Effective L_2 Norm-Based Strategy for KV Cache Compression Alessio Devoto, Yu Zhao, Simone Scardapane, Pasquale Minervini. EMNLP 2024.
- SirLLM: Streaming Infinite Retentive LLM Yao Yao, Zuchao Li, Hai Zhao. ACL 2024.
- D-LLM: A Token Adaptive Computing Resource Allocation Strategy for Large Language Models Yikun Jiang, Huanyu Wang, Lei Xie, Hanbin Zhao, Chao Zhang, Hui Qian, John C.S. Lui. NeurIPS 2024.
- MiniCache: KV Cache Compression in Depth Dimension for Large Language Models Akide Liu, Jing Liu, Zizheng Pan, Yefei He, Gholamreza Haffari, Bohan Zhuang. NeurIPS 2024.
- InfiniPot: Infinite Context Processing on Memory-Constrained LLMs Minsoo Kim, Kyuhong Shim, Jungwook Choi, Simyung Chang. EMNLP 2024.
- CHAI: Clustered Head Attention for Efficient LLM Inference Saurabh Agarwal, Bilge Acun, Basil Hosmer, Mostafa Elhoushi, Yejin Lee, Shivaram Venkataraman, Dimitris Papailiopoulos, Carole-Jean Wu. ICML 2024.
- KVQuant: Towards 10 Million Context Length LLM Inference with KV Cache Quantization Coleman Hooper, Sehoon Kim, Hiva Mohammadzadeh, Michael W. Mahoney, Yakun Sophia Shao, Kurt Keutzer, Amir Gholami. NeurIPS 2024.
- Get More with LESS: Synthesizing Recurrence with KV Cache Compression for Efficient LLM Inference Harry Dong, Xinyu Yang, Zhenyu Zhang, Zhangyang Wang, Yuejie Chi, Beidi Chen. ICML 2024.
- Eigen Attention: Attention in Low-Rank Space for KV Cache Compression Utkarsh Saxena, Gobinda Saha, Sakshi Choudhary, Kaushik Roy. EMNLP 2024.
- Atom: Low-Bit Quantization for Efficient and Accurate LLM Serving Yilong Zhao, Chien-Yu Lin, Kan Zhu, Zihao Ye, Lequn Chen, Size Zheng, Luis Ceze, Arvind Krishnamurthy, Tianqi Chen, Baris Kasikci. MLSys 2024.
- ZipCache: Accurate and Efficient KV Cache Quantization with Salient Token Identification Yefei He, Luoming Zhang, Weijia Wu, Jing Liu, Hong Zhou, Bohan Zhuang. NeurIPS 2024.
- KIVI: A Tuning-Free Asymmetric 2bit Quantization for KV Cache Zirui Liu, Jiayi Yuan, Hongye Jin, Shaochen Zhong, Zhaozhuo Xu, Vladimir Braverman, Beidi Chen, Xia Hu. ICML 2024.
- QUEST: Query-Aware Sparsity for Efficient Long-Context LLM Inference Jiaming Tang, Yilong Zhao, Kan Zhu, Guangxuan Xiao, Baris Kasikci, Song Han. ICML 2024.
- TokenSelect: Efficient Long-Context Inference and Length Extrapolation for LLMs via Dynamic Token-Level KV Cache Selection Wei Wu, Zhuoshi Pan, Chao Wang, Liyi Chen, Yunchu Bai, Tianfu Wang, Kun Fu, Zheng Wang, Hui Xiong. Arxiv 2024.
- RetrievalAttention: Accelerating Long-Context LLM Inference via Vector Retrieval Di Liu, Meng Chen, Baotong Lu, Huiqiang Jiang, Zhenhua Han, Qianxi Zhang, Qi Chen, Chengruidong Zhang, Bailu Ding, Kai Zhang, Chen Chen, Fan Yang, Yuqing Yang, Lili Qiu. Arxiv 2024.
- ArkVale: Efficient Generative LLM Inference with Recallable Key-Value Eviction Renze Chen, Zhuofeng Wang, Beiquan Cao, Tong Wu, Size Zheng, Xiuhong Li, Xuechao Wei, Shengen Yan, Meng Li, Yun Liang. NeurIPS 2024.
- GraphReader: Building Graph-based Agent to Enhance Long-Context Abilities of Large Language Models Shilong Li, Yancheng He, Hangyu Guo, Xingyuan Bu, Ge Bai, Jie Liu, Jiaheng Liu, Xingwei Qu, Yangguang Li, Wanli Ouyang, Wenbo Su, Bo Zheng. EMNLP 2024.
- Selection-p: Self-Supervised Task-Agnostic Prompt Compression for Faithfulness and Transferability Tsz Ting Chung, Leyang Cui, Lemao Liu, Xinting Huang, Shuming Shi, Dit-Yan Yeung. EMNLP 2024.
- Tell Your Model Where to Attend: Post-hoc Attention Steering for LLMs Qingru Zhang, Chandan Singh, Liyuan Liu, Xiaodong Liu, Bin Yu, Jianfeng Gao, Tuo Zhao. ICLR 2024.
- Naive Bayes-based Context Extension for Large Language Models Jianlin Su, Murtadha Ahmed, Bo Wen, Luo Ao, Mingren Zhu, Yunfeng Liu. NAACL 2024.
- FragRel: Exploiting Fragment-level Relations in the External Memory of Large Language Models Xihang Yue, Linchao Zhu, Yi Yang. ACL 2024.
- Never Lost in the Middle: Mastering Long-Context Question Answering with Position-Agnostic Decompositional Training Junqing He, Kunhao Pan, Xiaoqun Dong, Zhuoyang Song, LiuYiBo LiuYiBo, Qianguosun Qianguosun, Yuxin Liang, Hao Wang, Enming Zhang, Jiaxing Zhang. ACL 2024.
- Make Your LLM Fully Utilize the Context Shengnan An, Zexiong Ma, Zeqi Lin, Nanning Zheng, Jian-Guang Lou. NeurIPS 2024.
- Neurocache: Efficient Vector Retrieval for Long-range Language Modeling Ali Safaya, Deniz Yuret. NAACL 2024.
- AWESOME: GPU Memory-constrained Long Document Summarization using Memory Mechanism and Global Salient Content Shuyang Cao, Lu Wang. NAACL 2024.
- xRAG: Extreme Context Compression for Retrieval-augmented Generation with One Token Xin Cheng, Xun Wang, Xingxing Zhang, Tao Ge, Si-Qing Chen, Furu Wei, Huishuai Zhang, Dongyan Zhao. NeurIPS 2024.
- Long-Context Language Modeling with Parallel Context Encoding Howard Yen, Tianyu Gao, Danqi Chen. ACL 2024.
- Hierarchical Context Merging: Better Long Context Understanding for Pre-trained LLMs Woomin Song, Seunghyuk Oh, Sangwoo Mo, Jaehyung Kim, Sukmin Yun, Jung-Woo Ha, Jinwoo Shin. ICLR 2024.
- Extending Context Window of Large Language Models via Semantic Compression Weizhi Fei, Xueyan Niu, Pingyi Zhou, Lu Hou, Bo Bai, Lei Deng, Wei Han. ACL 2024.
- RECOMP: Improving Retrieval-Augmented LMs with Context Compression and Selective Augmentation Fangyuan Xu, Weijia Shi, Eunsol Choi. ICLR 2024.
- CompAct: Compressing Retrieved Documents Actively for Question Answering Chanwoong Yoon, Taewhoo Lee, Hyeon Hwang, Minbyul Jeong, Jaewoo Kang. EMNLP 2024.
- Learning to Compress Prompt in Natural Language Formats Yu-Neng Chuang, Tianwei Xing, Chia-Yuan Chang, Zirui Liu, Xun Chen, Xia Hu. NAACL 2024.
- LongLLMLingua: Accelerating and Enhancing LLMs in Long Context Scenarios via Prompt Compression Huiqiang Jiang, Qianhui Wu, Xufang Luo, Dongsheng Li, Chin-Yew Lin, Yuqing Yang, Lili Qiu. ACL 2024.
- LLMLingua-2: Data Distillation for Efficient and Faithful Task-Agnostic Prompt Compression Zhuoshi Pan, Qianhui Wu, Huiqiang Jiang, Menglin Xia, Xufang Luo, Jue Zhang, Qingwei Lin, Victor Rühle, Yuqing Yang, Chin-Yew Lin, H. Vicky Zhao, Lili Qiu, Dongmei Zhang. ACL 2024.
- LongRoPE: Extending LLM Context Window Beyond 2 Million Tokens Yiran Ding, Li Lyna Zhang, Chengruidong Zhang, Yuanyuan Xu, Ning Shang, Jiahang Xu, Fan Yang, Mao Yang. ICML 2024.
- Lost in the Middle: How Language Models Use Long Contexts Nelson F. Liu, Kevin Lin, John Hewitt, Ashwin Paranjape, Michele Bevilacqua, Fabio Petroni, Percy Liang. TACL 2024.
- On Context Utilization in Summarization with Large Language Models Mathieu Ravaut, Aixin Sun, Nancy Chen, Shafiq Joty. ACL 2024.
- KV Cache Compression, But What Must We Give in Return? A Comprehensive Benchmark of Long Context Capable Approaches Jiayi Yuan, Hongyi Liu, Shaochen Zhong, Yu-Neng Chuang, Songchen Li, Guanchu Wang, Duy Le, Hongye Jin, Vipin Chaudhary, Zhaozhuo Xu, Zirui Liu, Xia Hu. EMNLP 2024.
- Retrieval Augmented Generation or Long-Context LLMs? A Comprehensive Study and Hybrid Approach Zhuowan Li, Cheng Li, Mingyang Zhang, Qiaozhu Mei, Michael Bendersky. EMNLP 2024.
2023
- H2O: Heavy-Hitter Oracle for Efficient Generative Inference of Large Language Models Zhenyu Zhang, Ying Sheng, Tianyi Zhou, Tianlong Chen, Lianmin Zheng, Ruisi Cai, Zhao Song, Yuandong Tian, Christopher Ré, Clark Barrett, Zhangyang "Atlas" Wang, Beidi Chen. NeurIPS 2023.
- Scissorhands: Exploiting the Persistence of Importance Hypothesis for LLM KV Cache Compression at Test Time Zichang Liu, Aditya Desai, Fangshuo Liao, Weitao Wang, Victor Xie, Zhaozhuo Xu, Anastasios Kyrillidis, Anshumali Shrivastava. NeurIPS 2023.
- FlexGen: High-Throughput Generative Inference of Large Language Models with a Single GPU Ying Sheng, Lianmin Zheng, Binhang Yuan, Zhuohan Li, Max Ryabinin, Daniel Y. Fu, Zhiqiang Xie, Beidi Chen, Clark Barrett, Joseph E. Gonzalez, Percy Liang, Christopher Ré, Ion Stoica, Ce Zhang. ICML 2023.
- Focused Transformer: Contrastive Training for Context Scaling Szymon Tworkowski, Konrad Staniszewski, Mikołaj Pacek, Yuhuai Wu, Henryk Michalewski, Piotr Miłoś. NeurIPS 2023.
- TRAMS: Training-free Memory Selection for Long-range Language Modeling Haofei Yu, Cunxiang Wang, Yue Zhang, Wei Bi. EMNLP 2023.
- MemGPT: Towards LLMs as Operating Systems Charles Packer, Sarah Wooders, Kevin Lin, Vivian Fang, Shishir G. Patil, Ion Stoica, Joseph E. Gonzalez. Arxiv 2023.
- Adapting Language Models to Compress Contexts Alexis Chevalier, Alexander Wettig, Anirudh Ajith, Danqi Chen. EMNLP 2023.
- Compressing Context to Enhance Inference Efficiency of Large Language Models Yucheng Li, Bo Dong, Frank Guerin, Chenghua Lin. EMNLP 2023.
- LLMLingua: Compressing Prompts for Accelerated Inference of Large Language Models Huiqiang Jiang, Qianhui Wu, Chin-Yew Lin, Yuqing Yang, Lili Qiu. EMNLP 2023.
- TCRA-LLM: Token Compression Retrieval Augmented Large Language Model for Inference Cost Reduction Junyi Liu, Liangzhi Li, Tong Xiang, Bowen Wang, Yiming Qian. EMNLP 2023.
- LongNet: Scaling Transformers to 1,000,000,000 Tokens Jiayu Ding, Shuming Ma, Li Dong, Xingxing Zhang, Shaohan Huang, Wenhui Wang, Nanning Zheng, Furu Wei. Arxiv 2023.
- Large Language Models Can Be Easily Distracted by Irrelevant Context Freda Shi, Xinyun Chen, Kanishka Misra, Nathan Scales, David Dohan, Ed H. Chi, Nathanael Schärli, Denny Zhou. ICML 2023.
2022
- Memorizing Transformers Yuhuai Wu, Markus Norman Rabe, DeLesley Hutchins, Christian Szegedy. ICLR 2022.
- Capturing Global Structural Information in Long Document Question Answering with Compressive Graph Selector Network Yuxiang Nie, Heyan Huang, Wei Wei, Xian-Ling Mao. EMNLP 2022.
2.3 Parametric Memory
2025
- MLP Memory: Language Modeling with Retriever-pretrained External Memory Rubin Wei, Jiaqi Cao, Jiarui Wang, Jushi Kai, Qipeng Guo, Bowen Zhou, Zhouhan Lin. Arxiv 2025.
- Memory Decoder: A Pretrained, Plug-and-Play Memory for Large Language Models Jiaqi Cao, Jiarui Wang, Rubin Wei, Qipeng Guo, Kai Chen, Bowen Zhou, Zhouhan Lin. Arxiv 2025.
- Sft memorizes, rl generalizes: A comparative study of foundation model post-training Tianzhe Chu, Yuexiang Zhai, Jihan Yang, Shengbang Tong, Saining Xie, Dale Schuurmans, Quoc V Le, Sergey Levine, Yi Ma. Arxiv 2025.
- AlphaEdit: Null-Space Constrained Knowledge Editing for Language Models Junfeng Fang, Houcheng Jiang, Kun Wang, Yunshan Ma, Shi Jie, Xiang Wang, Xiangnan He, Tat-seng Chua ICLR 2025.
- Open Problems in Machine Unlearning for AI Safety Fazl Barez, Tingchen Fu, Ameya Prabhu, Stephen Casper, Amartya Sanyal, Adel Bibi, Aidan O'Gara, Robert Kirk, Ben Bucknall, Tim Fist, Luke Ong, Philip Torr, Kwok-Yan Lam, Robert Trager, David Krueger, Sören Mindermann, José Hernandez-Orallo, Mor Geva, Yarin Gal Arxiv 2025.
- MUSE: Machine Unlearning Six-Way Evaluation for Language Models Weijia Shi, Jaechan Lee, Yangsibo Huang, Sadhika Malladi, Jieyu Zhao, Ari Holtzman, Daogao Liu, Luke Zettlemoyer, Noah A. Smith, Chiyuan Zhang ICLR 2025.
- Spurious Forgetting in Continual Learning of Language Models Junhao Zheng , Xidi Cai, Shengjie Qiu, Qianli Ma ICLR 2025.
- Precise Localization of Memories: A Fine-grained Neuron-level Knowledge Editing Technique for LLMs Haowen Pan, Xiaozhi Wang, Yixin Cao, Zenglin Shi, Xun Yang, Juanzi Li, Meng Wang ICLR 2025.
- LLM Unlearning via Loss Adjustment with Only Forget Data Yaxuan Wang, Jiaheng Wei, Chris Yuhao Liu, Jinlong Pang, Quan Liu, Ankit Shah, Yujia Bao, Yang Liu, Wei Wei ICLR 2025.
- Lifelong Learning of Large Language Model based Agents: A Roadmap Junhao Zheng, Chengming Shi, Xidi Cai, Qiuke Li, Duzhen Zhang, Chenxing Li, Dong Yu, Qianli Ma Arxiv 2025.
- Towards LifeSpan Cognitive Systems Yu Wang, Chi Han, Tongtong Wu, Xiaoxin He, Wangchunshu Zhou, Nafis Sadeq, Xiusi Chen, Zexue He, Wei Wang, Gholamreza Haffari, Heng Ji, Julian McAuley TMLR 2025.
- Self-Updatable Large Language Models by Integrating Context into Model Parameters Yu Wang, Xinshuang Liu, Xiusi Chen, Sean O'Brien, Junda Wu, Julian McAuley ICLR 2025.
- If an LLM Were a Character, Would It Know Its Own Story? Evaluating Lifelong Learning in LLMs Siqi Fan, Xiusheng Huang, Yiqun Yao, Xuezhi Fang, Kang Liu, Peng Han, Shuo Shang, Aixin Sun, Yequan Wang Arxiv 2025.
2024
- Mass-Editing Memory with Attention in Transformers: A cross-lingual exploration of knowledge Daniel Tamayo, Aitor Gonzalez-Agirre, Javier Hernando, Marta Villegas. ACL 2024.
- Memory3: Language Modeling with Explicit Memory Hongkang Yang, Zehao Lin, Wenjin Wang, Hao Wu, Zhiyu Li, Bo Tang, Wenqiang Wei, Jinbo Wang, Zeyun Tang, Shichao Song, Chenyang Xi, Yu Yu, Kai Chen, Feiyu Xiong, Linpeng Tang, Weinan E. Arxiv 2024.
- WISE: Rethinking the Knowledge Memory for Lifelong Model Editing of Large Language Models Peng Wang, Zexi Li, Ningyu Zhang, Ziwen Xu, Yunzhi Yao, Yong Jiang, Pengjun Xie, Fei Huang, Huajun Chen NeurIPS 2024.
- MEMORYLLM: Towards Self-Updatable Large Language Models Yu Wang, Yifan Gao, Xiusi Chen, Haoming Jiang, Shiyang Li, Jingfeng Yang, Qingyu Yin, Zheng Li, Xian Li, Bing Yin, Jingbo Shang, Julian McAuley Arxiv 2024.
- A Comprehensive Survey of Continual Learning: Theory, Method and Application Liyuan Wang , Xingxing Zhang , Hang Su , Jun Zhu TPAMI 2024.
- The WMDP Benchmark: Measuring and Reducing Malicious Use With Unlearning Nathaniel Li, Alexander Pan, Anjali Gopal, Summer Yue, Daniel Berrios, Alice Gatti, Justin D. Li, Ann-Kathrin Dombrowski, Shashwat Goel, Gabriel Mukobi, Nathan Helm-Burger, Rassin Lababidi, Lennart Justen, Andrew Bo Liu, Michael Chen, Isabelle Barrass, Oliver Zhang, Xiaoyuan Zhu, Rishub Tamirisa, Bhrugu Bharathi, Ariel Herbert-Voss, Cort B Breuer, Andy Zou, Mantas Mazeika, Zifan Wang, Palash Oswal, Weiran Lin, Adam Alfred Hunt, Justin Tienken-Harder, Kevin Y. Shih, Kemper Talley, John Guan, Ian Steneker, David Campbell, Brad Jokubaitis, Steven Basart, Stephen Fitz, Ponnurangam Kumaraguru, Kallol Krishna Karmakar, Uday Tupakula, Vijay Varadharajan, Yan Shoshitaishvili, Jimmy Ba, Kevin M. Esvelt, Alexandr Wang, Dan Hendrycks ICML 2024.
- TOFU: A Task of Fictitious Unlearning for LLMs Pratyush Maini, Zhili Feng, Avi Schwarzschild, Zachary Chase Lipton, J Zico Kolter COLM 2024.
- In-Context Unlearning: Language Models as Few Shot Unlearners Martin Pawelczyk, Seth Neel, Himabindu Lakkaraju ICML2024.
- Towards Safer Large Language Models through Machine Unlearning Zheyuan Liu, Guangyao Dou, Zhaoxuan Tan, Yijun Tian, Meng Jiang ACL 2024.
- A Comprehensive Study of Knowledge Editing for Large Language Models Ningyu Zhang, Yunzhi Yao, Bozhong Tian, Peng Wang, Shumin Deng, Mengru Wang, Zekun Xi, Shengyu Mao, Jintian Zhang, Yuansheng Ni, Siyuan Cheng, Ziwen Xu, Xin Xu, Jia-Chen Gu, Yong Jiang, Pengjun Xie, Fei Huang, Lei Liang, Zhiqiang Zhang, Xiaowei Zhu, Jun Zhou, Huajun Chen Arxiv 2024.
- SOUL: Unlocking the Power of Second-Order Optimization for LLM Unlearning Jinghan Jia, Yihua Zhang, Yimeng Zhang, Jiancheng Liu, Bharat Runwal, James Diffenderfer, Bhavya Kailkhura, Sijia Liu EMNLP 2024.
- Large Language Model Unlearning via Embedding-Corrupted Prompts Chris Yuhao Liu, Yaxuan Wang, Jeffrey Flanigan, Yang Liu NeurIPS 2024.
- On Memorization of Large Language Models in Logical Reasoning Chulin Xie , Yangsibo Huang, Chiyuan Zhang, Da Yu, Xinyun Chen, Bill Yuchen Lin, Bo Li, Badih Ghazi, Ravi Kumar Arxiv 2024.
- Reversing the Forget-Retain Objectives: An Efficient LLM Unlearning Framework from Logit Difference Jiabao Ji, Yujian Liu, Yang Zhang, Gaowen Liu, Ramana Rao Kompella, Sijia Liu, Shiyu Chang NeurIPS 2024.
- RWKU: Benchmarking Real-World Knowledge Unlearning for Large Language Models Zhuoran Jin, Pengfei Cao, Chenhao Wang, Zhitao He, Hongbang Yuan, Jiachun Li, Yubo Chen, Kang Liu, Jun Zhao NeurIPS 2024.
- Larimar: Large Language Models with Episodic Memory Control Payel Das, Subhajit Chaudhury, Elliot Nelson, Igor Melnyk, Sarathkrishna Swaminathan, Sihui Dai, Aurelie Lozano, Georgios Kollias, Vijil Chenthamarakshan, Jiri Navratil, Soham Dan, Pin-Yu Chen ICML 2024.
- TaSL: Continual Dialog State Tracking via Task Skill Localization and Consolidation Yujie Feng, Xu Chu, Yongxin Xu, Guangyuan Shi, Bo Liu, Xiao-Ming Wu ACL 2024
- To Forget or Not? Towards Practical Knowledge Unlearning for Large Language Models Bozhong Tian, Xiaozhuan Liang, Siyuan Cheng, Qingbin Liu, Mengru Wang, Dianbo Sui, Xi Chen, Huajun Chen, Ningyu Zhang EMNLP 2024.
- Mitigating Catastrophic Forgetting in Online Continual Learning by Modeling Previous Task Interrelations via Pareto Optimization Yichen Wu , Hong Wang, Peilin Zhao, Yefeng Zheng, Ying Wei, Long-Kai Huang ICML 2024.
- WAGLE: Strategic Weight Attribution for Effective and Modular Unlearning in Large Language Models Jinghan Jia, Jiancheng Liu, Yihua Zhang, Parikshit Ram, Nathalie Baracaldo, Sijia Liu NeurIPS 2024.
- Boosting Large Language Models with Continual Learning for Aspect-based Sentiment Analysis Xuanwen Ding, Jie Zhou, Liang Dou, Qin Chen, Yuanbin Wu, Arlene Chen, Liang He EMNLP 2024.
- DAFNet: Dynamic Auxiliary Fusion for Sequential Model Editing in Large Language Models Taolin Zhang, Qizhou Chen, Dongyang Li, Chengyu Wang, Xiaofeng He, Longtao Huang, Hui Xue’, Jun Huang ACL 2024.
2023
- Mass-Editing Memory in a Transformer Kevin Meng, Arnab Sen Sharma, Alex Andonian, Yonatan Belinkov, David Bau. ICLR 2023.
- DSI++: Updating Transformer Memory with New Documents Sanket Vaibhav Mehta, Jai Gupta, Yi Tay, Mostafa Dehghani, Vinh Q. Tran, Jinfeng Rao, Marc Najork, Emma Strubell, Donald Metzler. EMNLP 2023.
- A Unified Approach to Domain Incremental Learning with Memory: Theory and Algorithm Haizhou Shi, Hao Wang. NeurIPS 2023.
- Locating and Editing Factual Associations in GPT Kevin Meng, David Bau, Alex Andonian, Yonatan Belinkov NeurIPS 2023.
- Can We Edit Factual Knowledge by In-Context Learning? Ce Zheng, Lei Li, Qingxiu Dong, Yuxuan Fan, Zhiyong Wu, Jingjing Xu, Baobao Chang EMNLP 2023.
- Unlearn What You Want to Forget: Efficient Unlearning for LLMs Jiaao Chen, Diyi Yang EMNLP 2023.
- MQuAKE: Assessing Knowledge Editing in Language Models via Multi-Hop Questions Zexuan Zhong, Zhengxuan Wu, Christopher Manning, Christopher Potts, Danqi Chen EMNLP 2023.
- Large Language Model Unlearning Yuanshun Yao, Xiaojun Xu, Yang Liu NeurIPS SoLaR 2023.
- DEPN: Detecting and Editing Privacy Neurons in Pretrained Language Models Xinwei Wu, Junzhuo Li, Minghui Xu, Weilong Dong, Shuangzhi Wu, Chao Bian, Deyi Xiong EMNLP 2023.
2022 & Before
- Memory-Based Model Editing at Scale Eric Mitchell, Charles Lin, Antoine Bosselut, Christopher D. Manning, Chelsea Finn. ICML 2022.
- Memory-assisted prompt editing to improve GPT-3 after deployment Aman Madaan, Niket Tandon, Peter Clark, Yiming Yang. EMNLP 2022.
- Improving Task-free Continual Learning by Distributionally Robust Memory Evolution Zhenyi Wang, Li Shen, Le Fang, Qiuling Suo, Tiehang Duan, Mingchen Gao. ICML 2022.
- Memory Replay with Data Compression for Continual Learning Liyuan Wang, Xingxing Zhang, Kuo Yang, Longhui Yu, Chongxuan Li, Lanqing Hong, Shifeng Zhang, Zhenguo Li, Yi Zhong, Jun Zhu Arxiv 2022.
- Fast Model Editing at Scale Eric Mitchell, Charles Lin, Antoine Bosselut, Chelsea Finn, Christopher D Manning ICLR 2022.
- Calibrating Factual Knowledge in Pretrained Language Models Qingxiu Dong, Damai Dai, Yifan Song, Jingjing Xu, Zhifang Sui, Lei Li EMNLP 2022.
- Incremental Prompting: Episodic Memory Prompt for Lifelong Event Detection Minqian Liu, Shiyu Chang, Lifu Huang COLING 2022.
- Editing Factual Knowledge in Language Models Nicola De Cao, Wilker Aziz, Ivan Titov EMNLP 2021.
- Sequential memory improves sample and memory efficiency in Episodic Control Ismael T. Freire, Adrián F. Amil, Paul F.M.J. Verschure Arxiv 2021.
- Towards Scalable Multi-domain Conversational Agents: The Schema-Guided Dialogue Dataset Abhinav Rastogi, Xiaoxue Zang, Srinivas Sunkara, Raghav Gupta, Pranav Khaitan AAAI 2020.
- INSPIRED: Toward Sociable Recommendation Dialog Systems Shirley Anugrah Hayati, Dongyeop Kang, Qingxiaoyang Zhu, Weiyan Shi, Zhou Yu EMNLP 2020.
- Overcoming catastrophic forgetting in neural networks James Kirkpatrick, Razvan Pascanu, Neil Rabinowitz, Joel Veness, Guillaume Desjardins, Andrei A. Rusu, Kieran Milan, John Quan, Tiago Ramalho, Agnieszka Grabska-Barwinska, Demis Hassabis, Claudia Clopath, Dharshan Kumaran, Raia Hadsell PNAS 2017.
2.4 Multi-source Memory
2025
- Context as memory: Scene-consistent interactive long video generation with memory retrieval Jiwen Yu, Jianhong Bai, Yiran Qin, Quande Liu, Xintao Wang, Pengfei Wan, Di Zhang, Xihui Liu. Arxiv 2025.
- Mirix: Multi-agent memory system for llm-based agents Yu Wang, Xi Chen. Arxiv 2025.
- Seeing, Listening, Remembering, and Reasoning: A Multimodal Agent with Long-Term Memory Lin Long, Yichen He, Wentao Ye, Yiyuan Pan, Yuan Lin, Hang Li, Junbo Zhao, Wei Li. Arxiv 2025.
- Ella: Embodied Social Agents with Lifelong Memory Hongxin Zhang, Zheyuan Zhang, Zeyuan Wang, Zunzhe Zhang, Lixing Fang, Qinhong Zhou, Chuang Gan. Arxiv 2025.
- DelTA: An Online Document-Level Translation Agent Based on Multi-Level Memory Yutong Wang, Jiali Zeng, Xuebo Liu, Derek F. Wong, Fandong Meng, Jie Zhou, Min Zhang. ICLR 2025.
- StructRAG: Boosting Knowledge Intensive Reasoning of LLMs via Inference-time Hybrid Information Structurization Zhuoqun Li, Xuanang Chen, Haiyang Yu, Hongyu Lin, Yaojie Lu, Qiaoyu Tang, Fei Huang, Xianpei Han, Le Sun, Yongbin Li. ICLR 2025.
- M3: 3D-Spatial MultiModal Memory Xueyan Zou, Yuchen Song, Ri-Zhao Qiu, Xuanbin Peng, Jianglong Ye, Sifei Liu, Xiaolong Wang. ICLR 2025.
- Stable Hadamard Memory: Revitalizing Memory-Augmented Agents for Reinforcement Learning Hung Le, Dung Nguyen, Kien Do, Sunil Gupta, Svetha Venkatesh. ICLR 2025.
- A New Formula for Sticker Retrieval: Reply with Stickers in Multi-Modal and Multi-Session Conversation Bingbing Wang, Yiming Du, Bin Liang, Zhixin Bai, Min Yang, Baojun Wang, Kam-Fai Wong, Ruifeng Xu. AAAI 2025.
- LLM-Empowered Embodied Agent for Memory-Augmented Task Planning in Household Robotics Marc Glocker, Peter Hönig, Matthias Hirschmanner, Markus Vincze. Arxiv 2025.
- WORLDMEM: Long-term Consistent World Simulation with Memory Zeqi Xiao, Yushi Lan, Yifan Zhou, Wenqi Ouyang, Shuai Yang, Yanhong Zeng, Xingang Pan. Arxiv 2025.
2024
- Symbolic Working Memory Enhances Language Models for Complex Rule Application Siyuan Wang, Zhongyu Wei, Yejin Choi, Xiang Ren. EMNLP 2024.
- Memory Augmented Language Models through Mixture of Word Experts Cicero Nogueira dos Santos, James Lee-Thorp, Isaac Noble, Chung-Ching Chang, David Uthus. NAACL 2024.
- MATTER: Memory-Augmented Transformer Using Heterogeneous Knowledge Sources Dongkyu Lee, Chandana Satya Prakash, Jack FitzGerald, Jens Lehmann. ACL 2024.
- Learning Multimodal Contrast with Cross-modal Memory and Reinforced Contrast Recognition Yuanhe Tian, Fei Xia, Yan Song. ACL 2024.
- A Simple LLM Framework for Long-Range Video Question-Answering Ce Zhang, Taixi Lu, Md Mohaiminul Islam, Ziyang Wang, Shoubin Yu, Mohit Bansal, Gedas Bertasius. EMNLP 2024.
- MA-LMM: Memory-Augmented Large Multimodal Model for Long-Term Video Understanding Bo He, Hengduo Li, Young Kyun Jang, Menglin Jia, Xuefei Cao, Ashish Shah, Abhinav Shrivastava, Ser-Nam Lim. CVPR 2024.
- Chain-of-Knowledge: Grounding Large Language Models via Dynamic Knowledge Adapting over Heterogeneous Sources Xingxuan Li, Ruochen Zhao, Yew Ken Chia, Bosheng Ding, Shafiq Joty, Soujanya Poria, Lidong Bing. ICLR 2024.
- VISTA: Visualized Text Embedding For Universal Multi-Modal Retrieval Junjie Zhou, Zheng Liu, Shitao Xiao, Bo Zhao, Yongping Xiong. ACL 2024.
- Generate-on-Graph: Treat LLM as both Agent and KG in Incomplete Knowledge Graph Question Answering Yao Xu, Shizhu He, Jiabei Chen, Zihao Wang, Yangqiu Song, Hanghang Tong, Guang Liu, Kang Liu, Jun Zhao. EMNLP 2024.
- Enhancing Reasoning with Collaboration and Memory Julie Michelman, Nasrin Baratalipour, Matthew Abueg. ICLR 2024.
- Generative Cross-Modal Retrieval: Memorizing Images in Multimodal Language Models for Retrieval and Beyond Yongqi Li, Wenjie Wang, Leigang Qu, Liqiang Nie, Wenjie Li, Tat-Seng Chua. ACL 2024.
- Semi-Structured Chain-of-Thought: Integrating Multiple Sources of Knowledge for Improved Language Model Reasoning Xin Su, Tiep Le, Steven Bethard, Phillip Howard. NAACL 2024.
- Blinded by Generated Contexts: How Language Models Merge Generated and Retrieved Contexts When Knowledge Conflicts? Hexiang Tan, Fei Sun, Wanli Yang, Yuanzhuo Wang, Qi Cao, Xueqi Cheng. ACL 2024.
- Moviechat+: Question-aware sparse memory for long video question answering Enxin Song, Wenhao Chai, Tian Ye, Jenq-Neng Hwang, Xi Li, Gaoang Wang. Arxiv 2024.
- LifelongMemory: Leveraging LLMs for Answering Queries in Long-form Egocentric Videos Ying Wang, Yanlai Yang, Mengye Ren. Arxiv 2024.
- Resolving Knowledge Conflicts in Large Language Models Yike Wang, Shangbin Feng, Heng Wang, Weijia Shi, Vidhisha Balachandran, Tianxing He, Yulia Tsvetkov. Arxiv 2024.
2023
- ChatDB: Augmenting LLMs with Databases as Their Symbolic Memory Chenxu Hu, Jie Yu, Chencheng Dong, Junbo Zhao, Hang Zhao. Arxiv 2023.
- Large Language Models with Controllable Working Memory Daliang Li, Ankit Singh Rawat, Manzil Zaheer, Xin Wang, Michal Lukasik, Andreas Veit, Felix Yu, Sanjiv Kumar. ACL 2023.
- Conversation Understanding using Relational Temporal Graph Neural Networks with Auxiliary Cross-Modality Interaction Cam-Van Thi Nguyen, Anh-Tuan Mai, The-Son Le, Hai-Dang Kieu, Duc-Trong Le ACL 2023.
- Universal Vision-Language Dense Retrieval Zhenghao Liu, Chenyan Xiong, Yuanhuiyi Lv, Zhiyuan Liu, Ge Yu. ICLR 2023.
- Context-faithful Prompting for Large Language Models Wenxuan Zhou, Sheng Zhang, Hoifung Poon, Muhao Chen. EMNLP 2023.
- Open-Ended Instructable Embodied Agents with Memory-Augmented Large Language Models Gabriel Sarch, Yuxiang Wu, Yuqi Xie, Yunfan Jiang, Linxi Fan, Ajay M. Patel, Yuke Zhu, Anima Anandkumar. Arxiv 2023.
- A Framework for Inference Inspired by Human Memory Mechanisms Xiangyu Zeng, Jie Lin, Piao Hu, Ruizheng Huang, Zhicheng Zhang. Arxiv 2023.
2022 & before
- An Efficient Memory-Augmented Transformer for Knowledge-Intensive NLP Tasks Yuxiang Wu, Yu Zhao, Baotian Hu, Pasquale Minervini, Pontus Stenetorp, Sebastian Riedel. EMNLP 2022.
- There Are a Thousand Hamlets in a Thousand People's Eyes: Enhancing Knowledge-grounded Dialogue with Personal Memory Tingchen Fu, Xueliang Zhao, Chongyang Tao, Ji-Rong Wen, Rui Yan. ACL 2022.
- Prior Knowledge and Memory Enriched Transformer for Sign Language Translation Tao Jin, Zhou Zhao, Meng Zhang, Xingshan Zeng. ACL 2022.
- G-MAP: General Memory-Augmented Pre-trained Language Model for Domain Tasks Zhongwei Wan, Yichun Yin, Wei Zhang, Jiaxin Shi, Lifeng Shang, Guangyong Chen, Xin Jiang, Qun Liu. EMNLP 2022.
- Memory-aligned Knowledge Graph for Clinically Accurate Radiology Image Report Generation Sixing Yan. BioNLP 2022.
- Dynamic Global Memory for Document-level Argument Extraction Xinya Du, Sha Li, Heng Ji. ACL 2022.
- UniTranSeR: A Unified Transformer Semantic Representation Framework for Multimodal Task-Oriented Dialog System Zhiyuan Ma, Jianjun Li, Guohui Li, Yongjing Cheng. ACL 2022.
- A Cooperative Memory Network for Personalized Task-oriented Dialogue Systems with Incomplete User Profiles Jiahuan Pei, Pengjie Ren, Maarten de Rijke. WWW 2021.
📊 Datasets
Evaluation for Long Term Memroy.
Table-1: Datasets for Evaluating Long-Term Memory *(Continuously Updated)
| Dataset | Mo | Operations | DS Type | Per | TR | Metrics | Purpose | Year |
|---|---|---|---|---|---|---|---|---|
| PersonaMem-v2 | text | Updating, Retrieval | MS | ✓ | ✓ | Accuracy, Persona Score | Benchmark implicit user persona learning and agentic memory updates over long contexts. | 2025 |
| MemoryBench | text | Updating, Retrieval, Forgetting | QA | ✗ | ✓ | Accuracy, Retention Rate | Comprehensive benchmark for memory correctness, persistence, and continual learning. | 2025 |
| HaluMem | text | Retrieval | QA | ✗ | ✗ | Accuracy, Hallucination Rate, Omission Rate | Evaluate hallucinations in memory extraction, updating and retrieval. | 2025 |
| BFCL V4 | text (API/Code) | Updating, Retrieval, Reasoning | QA (API) | ✗ | ✗ | AST Accuracy, Execution Success | Benchmarking function-calling capabilities, specifically featuring a "Memory" category for CRUD tool usage. | 2025 |
| LongMemEval | text | Indexing, Retrieval, Compression | MS | ✗ | ✓ | Recall@K, NDCG@K, Accuracy | Benchmark chat assistants on long-term memory abilities, including temporal reasoning. | 2025 |
| LoCoMo | text + image | Indexing, Retrieval, Compression | MS | ✗ | ✓ | Accuracy, ROUGE, Precision, Recall, F1 | Evaluate long-term memory in LLMs across QA, event summarization, and multimodal dialogue tasks. | 2024 |
| MemoryBank | text | Updating, Retrieval | MS | ✓ | ✗ | Accuracy, Human Eval | Enhance LLMs with long-term memory capabilities, adapting to user personalities and contexts. | 2024 |
| PerLTQA | text | Retrieval | MS | ✓ | ✗ | MAP, Recall, Precision, F1, Accuracy, GPT4 score | To explore personal long-term memory question answering ability. | 2024 |
| MALP | text | Retrieval, Compression | QA | ✓ | ✗ | ROUGE, Accuracy, Win Rate | Preference-conditioned dialogue generation. Parameter-efficient fine-tuning (PEFT) for customization. | 2024 |
| DialSim | text | Retrieval | MS | ✓ | ✗ | Accuracy | To evaluate dialogue systems under realistic, real-time, and long-context multi-party conversation conditions. | 2024 |
| MovieChat-1K | text + video | question-answering + caption | QA | ✗ | ✓ | Accuracy | For long-term video understanding for Large Multimodal Models across video question-answering and video captioning tasks. | 2023 |
| CC | text | Retrieval | MS | ✗ | ✓ | BLEU, ROUGE | For long-term dialogue modeling with time and relationship context. | 2023 |
| LAMP | text | Consolidation, Retrieval, Compression | MS | ✓ | ✓ | Accuracy, F1, ROUGE | Multiple entries per user. Supports both user-based splits and time-based splits. | 2023 |
| MSC | text | Consolidation, Retrieval, Compression | MS | ✓ | ✗ | PPL | Evaluate and improve long-term dialogue models via multi-session chats with evolving knowledge. | 2022 |
| DuLeMon | text | Consolidation, Updating, Retrieval, Compression | MS | ✓ | ✗ | Accuracy, F1, Recall, Precision, PPL, BLEU, DISTINCT | For dynamic persona tracking and consistent long-term interaction. | 2022 |
| 2WikiMultiHopQA | table + knowledge base + text | Consolidation, Indexing, Retrieval, Compression | QA | ✗ | ✗ | EM, F1 | Multi-hop QA combining structured and unstructured data with reasoning paths. | 2020 |
| NQ | text | Retrieval, Compression | QA | ✗ | ✗ | EM, F1 | Open-domain QA based on real Google search queries. | 2019 |
| HotpotQA | text | Retrieval, Compression | QA | ✗ | ✗ | EM, F1 | Multi-hop QA with explainable reasoning and sentence-level supporting facts. | 2018 |
Note:
- Mo: Modality of the dataset (e.g., text, image, table).
- Ops (Operations): Memory-related operations supported or evaluated (e.g., Indexing, Retrieval, Compression, Updating, Consolidation).
- DS Type: Dataset type —
- QA = Question Answering
- MS = Multi-Session Dialogue
- Per: Persona present (✓ = Yes, ✗ = No).
- TR: Temporal reasoning required or present (✓ = Yes, ✗ = No).
Evaluation for Long Context Memory
Table-2: Datasets for Long-Context Memory Evaluation *(Continuously Updated)*
| Dataset | Modality | Operations | Metrics | Purpose | Year |
|---|---|---|---|---|---|
| MMLongBench | text + image | compression, retrieval | SubEM, Accuracy, Rouge-L, Model-Based | 5 categories and 16 datasets for vision-language long-context evaluation | 2025 |
| WikiText-103 | text | compression | PPL | 100M-token Wikipedia corpus for long-context language modeling | 2016 |
| PG-19 | text | compression | PPL | Project Gutenberg books corpus for long-context language modeling | 2019 |
| LRA | text + image | compression, retrieval | Acc | Benchmark with 6 tasks for evaluating efficient long-context language models | 2020 |
| NarrativeQA | text | retrieval | Bleu-1, Bleu-4, Meteor, Rouge-L, MRR | QA dataset for evaluating long-context QA ability | 2017 |
| TriviaQA | text | retrieval | EM, F1 | QA dataset for evaluating long-context QA ability | 2017 |
| NaturalQuestions | text | retrieval | EM, F1 | QA dataset for evaluating long-context QA ability | 2019 |
| MusiQue | text | retrieval | F1 | Multi-hop QA dataset for evaluating long-context reasoning and QA | 2021 |
| CNN/DailyMail | text | compression | Rouge-1, Rouge-2, Rouge-L | News articles dataset for long document summarization | 2016 |
| GovReport | text | compression | Rouge-1, Rouge-2, Rouge-L, Bert Score | Government agency reports for long document summarization | 2021 |
| L-Eval | text | compression, retrieval | Rouge-L, F1, GPT4 | 20-subtask benchmark for diverse long-context language model evaluation | 2023 |
| LongBench | text | compression, retrieval | F1, Rouge-L, Accuracy, EM, Edit Sim | 14 English, 5 Chinese, 2 code tasks for long-context evaluation | 2023 |
| LongBench v2 | text + table + KG | compression, retrieval | Acc | Longer, more challenging tasks with consistent multi-choice format | 2024 |
| SWE-bench | text | compression, retrieval | Resolution rate (%Resolved) | 2,294 task instances from 12 popular python repositories from GitHub | 2023 |
| SWE-bench Multimodal | text + image | compression, retrieval | Resolution rate (%Resolved), Inference cost (Avg. $ Cost) | Extending the original benchmark with image modal with 517 task instances | 2024 |
| $\infty$Bench | text | compression, retrieval | F1, Acc, ROUGE-L-Sum | 12 sub-tasks specially designed for evaluating extreme long context language models | 2024 |
| LooGLE | text | compression, retrieval | Bleu-1, Bleu-4, Rouge-1, Rouge-4, Rouge-L, Meteor score, Bert score, GPT4 score | 7 major tasks specially designed for evaluating extreme long context language models | 2023 |
Parametric Memory Modification
Table-3: Datasets for Parametric Memory Evaluation *(Continuously Updated)*
| Dataset | Modality | Operations | Metrics | Purpose | Year |
|---|---|---|---|---|---|
| KnowEdit | text | updating | Edit Success, Portability, Locality, Fluency | 6 datasets covering insertion, modification, and erasure | 2024 |
| MQUAKE-CF | text | updating | Edit-wise Success Rate, Instance-wise Accuracy, Multi-hop Accuracy | Counterfactual knowledge editing through multi-hop reasoning (up to 4 hops) | 2023 |
| MQUAKE-T | text | updating | Edit-wise Success Rate, Instance-wise Accuracy, Multi-hop Accuracy | Temporal knowledge editing with one edit per reasoning chain | 2023 |
| Counterfact | text | updating | Efficacy Score, Magnitude, Paraphrase & Neighborhood Scores | Tests substantial factual changes beyond superficial edits | 2022 |
| zsRE | text | updating | Success Rate, Retain Accuracy, Equivalence Accuracy, Perf. Deterioration | One of the earliest datasets for knowledge editing | 2021 |
| MUSE | text | forgetting | VerbMem, KnowMem, PrivLeak | Unlearning benchmark with 6 desirable properties | 2024 |
| KnowUnDo | text | forgetting | Unlearn Success, Retention Success, Perplexity, ROUGE-L | Test unlearning in copyrighted and privacy-sensitive domains | 2024 |
| RWKU | text | forgetting | ROUGE-L | Real-world unlearning under corpus-free, adversarial settings | 2024 |
| WMDP | text | forgetting | QA accuracy | Proxy for hazardous knowledge in bio/cyber/chemical domains | 2024 |
| TOFU | text | forgetting | Probability, ROUGE, Truth Ratio | Unlearning dataset of facts about 200 fictitious authors | 2024 |
| ABSA | text | consolidation | F1 | Aspect-based sentiment analysis for continual learning | 2024 |
| SGD | text | consolidation | JGA, FWT, BWT | Multi-turn task-oriented dialogue with evolving intents | 2020 |
| INSPIRED | text | consolidation | JGA, FWT, BWT | Task-oriented dialogue supporting user goal evolution | 2020 |
| Natural Question | text | consolidation | Indexing Accuracy, Hits@1 | Supports continual learning over evolving document corpora | 2019 |
Note:
- This table covers datasets for evaluating parametric memory in LLMs.
- Operations:
- updating – assessing model behavior after direct memory modification
- forgetting – evaluating unlearning/removal of specific knowledge
- consolidation – integrating new knowledge without harming prior capabilities
- Metrics include fluency, factuality, locality, transfer, edit effectiveness, and forgetting accuracy.
Evaluation for Multi-Source Memory
Table-4: Datasets for Multi-Source Memory Evaluation *(Continuously Updated)*
| Dataset | Mo | Ops | Src# | Mod# | Task | Metrics | Purpose | Year |
|---|---|---|---|---|---|---|---|---|
| MultiChat | text + image | Retrieval | 2 | 2 | Retrieval | Precision, mAP, GPT-4 | Image-grounded sticker retrieval with cross-session image-text dialogue context. | 2025 |
| Context-conflicting | text | Compression | 2 | 1 | Conflict | DiffGR, EM, Similarity | Evaluates model handling of conflicting evidence across sources. | 2024 |
| EgoSchema | video + text | Retrieval, Compression | 3 | 2 | Fusion | Accuracy | Episodic video + social schema + conversation for long-term memory QA. | 2023 |
| Ego4D NLQ | video + text | Retrieval, Compression | 2 | 2 | Fusion | Recall@K | Natural language queries over egocentric video with temporal memory. | 2022 |
| 2WikiMultihopQA | text | Indexing, Retrieval, Compression | 2 | 1 | Reasoning | EM, F1 | Multi-hop QA across Wikipedia passages with sentence-level support. | 2020 |
| HybridQA | text | Retrieval, Compression | 2 | 1 | Reasoning | EM, F1 | Reasoning across structured tables and unstructured text. | 2020 |
| CommonsenseVQA | text + image | Retrieval, Compression | 2 | 2 | Fusion | Accuracy | Commonsense QA over visual scenes requiring visual-textual fusion. | 2019 |
| NaturalQuestions | text | Retrieval, Compression | >1* | 1 | Conflict | EM, F1 | QA over Google snippets; used for contradiction analysis. | 2019 |
| ComplexWebQuestions | text | Retrieval, Compression | >1* | 1 | Reasoning | EM, F1 | Compositional QA requiring multi-step reasoning over web snippets. | 2018 |
| HotpotQA | text | Retrieval, Compression | 2 | 1 | Conflict | EM, F1, Supporting Fact Accuracy | Multi-hop QA with paragraph- and sentence-level support. | 2018 |
| TriviaQA | text | Retrieval, Compression | ≥6 | 1 | Conflict | EM, F1 | QA with noisy web sources; useful for source disagreement analysis. | 2017 |
| WebQuestionsSP | text | Indexing, Retrieval, Compression | >1* | 1 | Reasoning | F1, Accuracy | Structured QA dataset with enhanced reasoning chains. | 2016 |
| Flickr30K | text + image | Retrieval, Compression | 2 | 2 | Retrieval | Similarity | Image-caption pairs for cross-modal retrieval and alignment. | 2014 |
Note:
- Mo: Modality (e.g., text, image, video).
- Ops: Operations (e.g., Retrieval, Compression, Indexing).
- Src#: Number of sources per instance.
- Mod#: Number of modalities involved.
- Task:
- Retrieval: retrieving relevant knowledge
- Fusion: integrating multiple modalities
- Reasoning: multi-hop or logic-based inference
- Conflict: handling conflicting sources
🧠 Methods
- Overview and comparison of methods used in AI memory research.
⚙️ Tools
Components Level
Table-1: Component-Level Tools for Memory Management and Utilization. *(Continuously Updated)*
| Memory Tool | Function | Input/Output | Example Use |
|---|---|---|---|
| FAISS | Library for fast storage, indexing, and retrieval of high-dimensional vectors | Vector / Index, relevance score | Indexing large sets of text embeddings and retrieving relevant documents in RAG systems |
| Neo4j | Native graph database supporting ACID transactions and Cypher query language | Nodes and relationships with properties / Query results via Cypher | Modeling and retrieving complex relational data for use cases like fraud detection and recommendation engines |
| Chroma | AI-native embedding database for building LLM applications | Text / Embeddings | Managing knowledge, facts, and skills for LLMs |
| Milvus | Vector database for embedding similarity search and AI applications | Embeddings / Similar items | Unstructured data search and similarity matching |
| Qdrant | Vector similarity search engine and database | Embeddings / Similar items | Production-ready service with user-friendly API for vector search |
| Weaviate | Open-source vector database with built-in ML models | Data objects and vector embeddings / Search results | Scalable storage and retrieval for AI applications |
| BM25 | Probabilistic ranking function for estimating document relevance | Text queries / Ranked list of documents | Enhancing search engine results and document retrieval systems |
| Contriever | Unsupervised dense retriever trained with contrastive learning | Query text / List of similar documents | High-recall retrieval tasks in multilingual question-answering systems |
| Embedding Models (e.g., OpenAI) | Convert text, images, or audio into dense vector representations capturing semantic meaning | Raw data / Vector embeddings | Text similarity computation, recommendation systems, and clustering tasks |
Framework Level
Table-2: Framework-Level Tools for Memory Management and Utilization *(Continuously Updated)*
| Memory Tool | Function | Input/Output | Example Use | Source Type |
|---|---|---|---|---|
| Graphiti | Framework for building and querying temporally-aware knowledge graphs tailored for AI agents in dynamic environments | Multi-source data / Queryable knowledge graph | Constructing real-time knowledge graphs to enhance AI agent memory | Open |
| LlamaIndex | A flexible framework for building knowledge assistants using LLMs connected to enterprise data | Text / Context-augmented responses | Developing knowledge assistants that process complex data formats | Open |
| LangChain | Provides a framework for building context-aware, reasoning applications by connecting LLMs with external data sources | Input prompts / Multi-step reasoning outputs | Creating complex LLM applications like question-answering systems and chatbots | Open |
| LangGraph | Constructs controllable agent architectures supporting long-term memory and human-in-the-loop multi-agent systems | Graph state / State updates | Building complex task workflows with multiple AI agents | Open |
| EasyEdit | An easy-to-use knowledge editing framework for LLMs, enabling efficient behavior modification within specific domains | Edit instructions / Updated model behavior | Modifying LLM knowledge in specific domains, such as updating factual information | Open |
| CrewAI | A platform for building and deploying multi-agent systems, supporting automated workflows using any LLM and cloud platform | Multi-agent tasks / Collaborative results | Automating workflows across agents like project management and content generation | Open |
| Letta | Constructs stateful agents with long-term memory, advanced reasoning, and custom tools within a visual environment | User interactions / Improved response | Developing AI agents that learn and improve over time | Open |
| OpenHands | An open platform for autonomous software agents that maintains persistent context across file editing, command execution, and web browsing | Natural language tasks / Code patches, Terminal actions | Automating complex software engineering tasks like debugging and feature implementation with full project context | Open |
Application-Layer Level
Table-3: Application Layer-Level Tools for Memory Management and Utilization (Continuously Updated)
| Memory Tool | Function | Input/Output | Example Use | Source Type |
|---|---|---|---|---|
| Mem0 | Provides a smart memory layer for LLMs, enabling direct addition, updating, and searching of memories in models | User interactions / Personalized responses | Enhancing AI systems with persistent context for customer support and personalized recommendations | Open |
| Zep | Integrates chat messages into a knowledge graph, offering accurate and relevant user information | Chat logs, business data / Knowledge graph query results | Augmenting AI agents with knowledge through continuous learning from user interactions | Open |
| Memary | An open memory layer that emulates human memory to help AI agents manage and utilize information effectively | Agent tasks / Memory management and utilization | Building AI agents with human-like memory characteristics | Open |
| Memobase | A user profile-based long-term memory system designed to provide personalized experiences in generative AI applications | User interactions / Personalized responses | Implementing virtual assistants, educational tools, and personalized AI companions | Open |
| O-Mem | An omni-memory system enabling agents to self-evolve and maintain long-horizon consistency through recursive memory consolidation | Long-term interaction logs / Evolved memory state | Creating self-evolving personal AI assistants that adapt to user growth over time | Open |
| MemOS | An operating system-like architecture that manages memory hierarchy (working/short/long-term) to optimize Memory-Augmented Generation | Agent queries, Complex contexts / Hierarchical memory blocks | Managing complex memory resources for agents handling multi-step reasoning tasks | Open |
Product Level
Table-4: Product-Level Tools for Memory Utilization (Continuously Updated)
| Memory Tool | Function | Input/Output | Example Use | Source Type |
|---|---|---|---|---|
| Me.bot | AI-powered personal assistant that organizes notes, tasks, and memories, providing emotional support and productivity tools | User inputs (text, voice) / Organized notes, reminders, summaries | Personal productivity enhancement, emotional support, idea organization | Closed |
| ima.copilot | Intelligent workstation powered by Tencent's Mix Huang model, building a personal knowledge base for learning and work scenarios | User queries / Customized responses, knowledge retrieval | Enhancing learning efficiency, work productivity, knowledge management | Closed |
| Coze | Enables multi-agent collaboration across various platforms | User-defined workflows / Response | Deployed chatbots, AI agents | Closed |
| Grok | AI assistant developed by xAI, designed to provide truthful, useful, and curious responses, with real-time data access and image generation | Query / Informative answers, generated images | Answering questions, generating images, providing insights | Closed |
| ChatGPT | Conversational AI developed by OpenAI, capable of understanding and generating human-like text based on prompts | User prompts / Generated text responses | Answering questions, generating images, providing insights | Closed |
| Claude | AI assistant featuring "Projects" to ground answers in user-provided knowledge bases and massive context windows | Prompts, Files, Code / Text, Code, Artifacts | Analyzing large codebases, maintaining consistent style across documents via Projects | Closed |
| Doubao | A high-efficiency multimodal AI assistant capable of handling long-context interactions and diverse tasks | Text, Voice, Image / Answers, creative content | Daily conversation, writing assistance, coding, and role-playing | Closed |
| Siri | Intelligent voice assistant utilizing on-device personal semantic memory for cross-app actions and context understanding | Voice commands / Action execution, personal info retrieval | Device control, retrieving personal context ("When is Mom's flight?"), cross-app tasks | Closed |
| Xiaoyi | Huawei's smart assistant integrated into HarmonyOS, leveraging ecosystem memory for proactive services and document processing | Voice, Text, Documents / Summaries, suggestions, IoT control | Document summarization, smart home control, personalized travel planning | Closed |
| Zhixiaobao | Ant Group's financial AI agent that utilizes user financial history and market knowledge for personalized wealth management | Financial queries / Market analysis, investment advice | Financial planning, insurance analysis, market trend explanation | Closed |
🆚 Human vs. AI in Memory
Table-5: Key differences between human and agent memory across operational dimensions
| Aspect | Human Memory | Agent Memory |
|---|---|---|
| Storage | Distributed, interconnected neural systems across brain regions | Parametric, modular, and context-dependent (structured or unstructured) |
| Consolidation | Slow, biologically driven, passive | Fast, explicit, policy-driven and selective |
| Indexing | Implicit, associative, sparse codes via hippocampal circuits | Explicit, embedding-based, symbolic or key–value lookup |
| Updating | Indirect, reconsolidation-based, error-prone | Precise, programmable, supports rollback/unlearning |
| Forgetting | Passive decay or interference | Transparent, trackable, policy-controlled |
| Retrieval | Cue/context/emotion dependent, emotionally biased | Content-based, reproducible, similarity or query driven |
| Compression | Implicit, salience- and frequency-biased | Explicit, customizable (e.g., quantization, summarization) |
| Ownership | Individual and private | Shareable, replicable, and broadcastable |
| Volume | Biologically limited | Scalable, bounded only by storage and compute limits |
🌞 Future Directions
Acknowledgements
Please contact me if I miss your names in the list, I will add you back ASAP!
🤝🤝 Thanks for all the great contributors on GitHub!
If you find our repository and survey useful for your research, please consider citing the following paper:
@article{du2025rethinking,
  title={Rethinking Memory in AI: Taxonomy, Operations, Topics, and Future Directions},
  author={Du, Yiming and Huang, Wenyu and Zheng, Danna and Wang, Zhaowei and Montella, Sebastien and Lapata, Mirella and Wong, Kam-Fai and Pan, Jeff Z.},
  journal={arXiv preprint arXiv:2505.00675},
  year={2025},
  url={https://arxiv.org/abs/2505.00675}
}