
[TMLR 2025] Stop Overthinking: A Survey on Efficient Reasoning for Large Language Models
See the codeREADME
Awesome-Efficient-Reasoning-LLMs

[TMLR 2025] Stop Overthinking: A Survey on Efficient Reasoning for Large Language Models
📢 Want to add related papers? Feel free to open a pull request!
📢 News
- August 21, 2025: Updated.
- July 14, 2025: "Stop Overthinking" is accepted by TMLR, Transactions on Machine Learning Research.
- April 22, 2025: Updated.
- March 20, 2025: We release the first survey for efficient reasoning of LLMs "Stop Overthinking: A Survey on Efficient Reasoning for Large Language Models".
Feel free to cite, contribute, or open a pull request to add recent related papers!
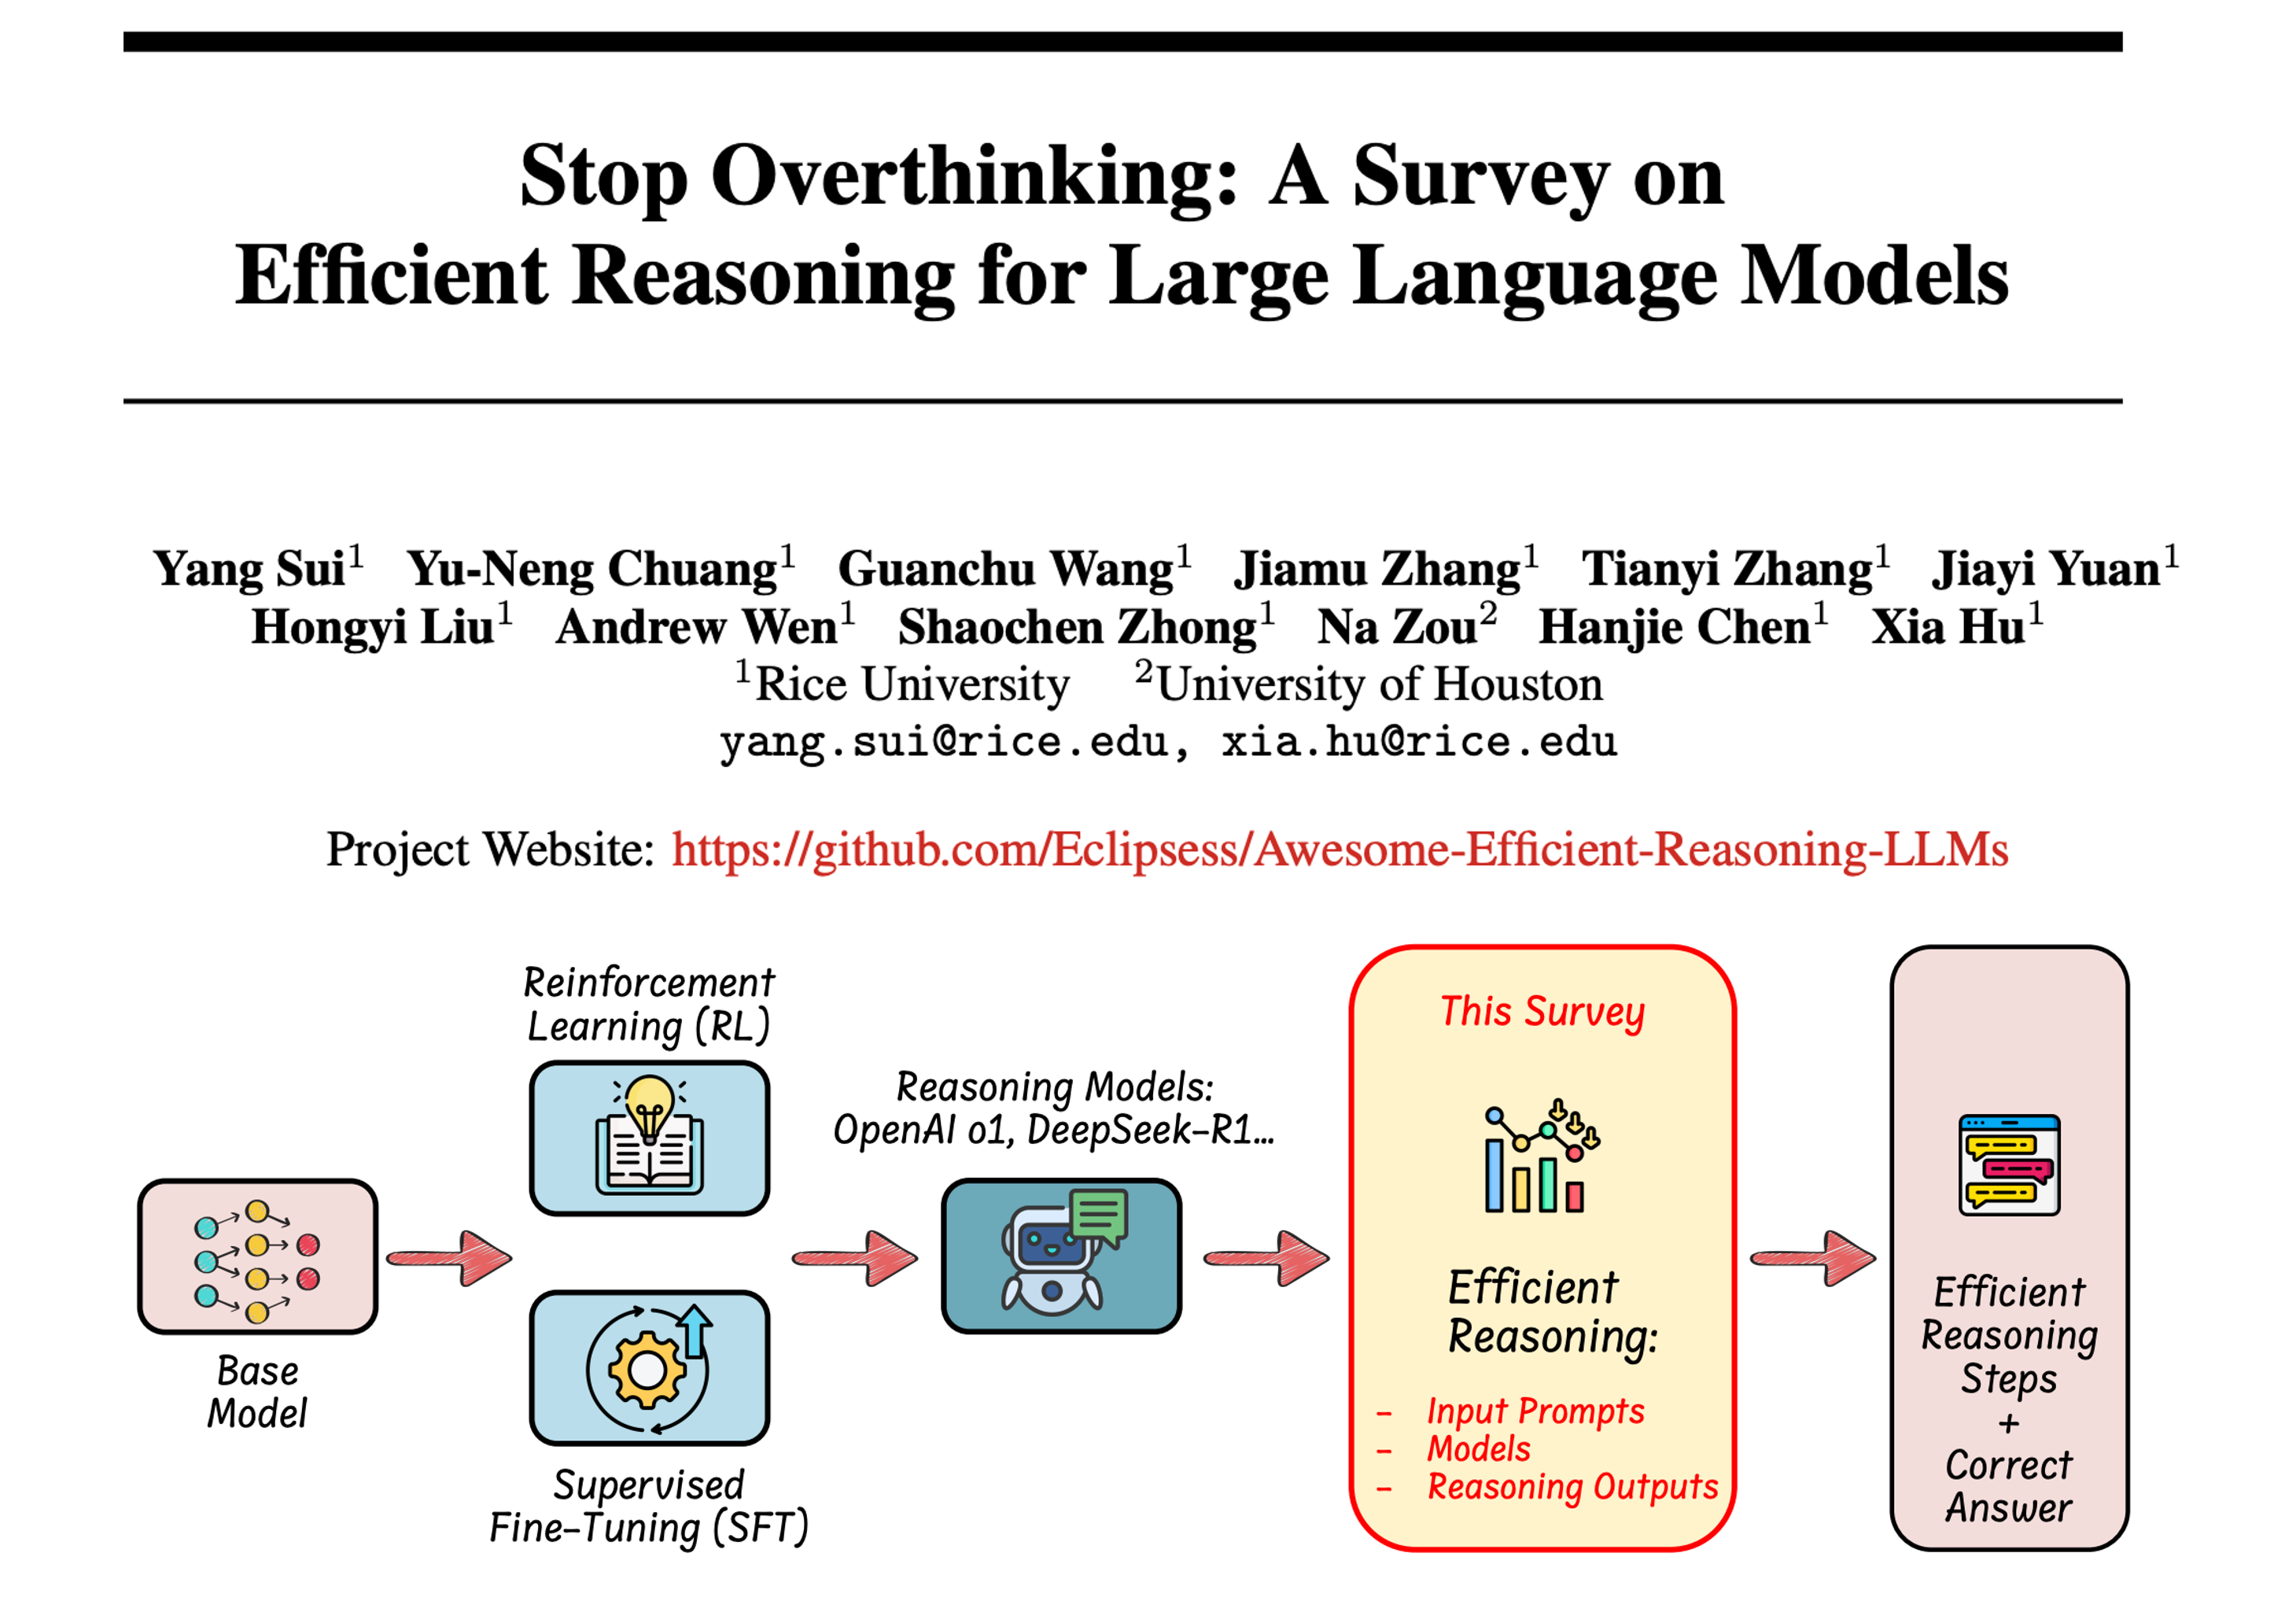
In this paper, we present the first structured survey that systematically investigates and organizes the current progress in achieving efficient reasoning in LLMs.
📊 Taxonomy
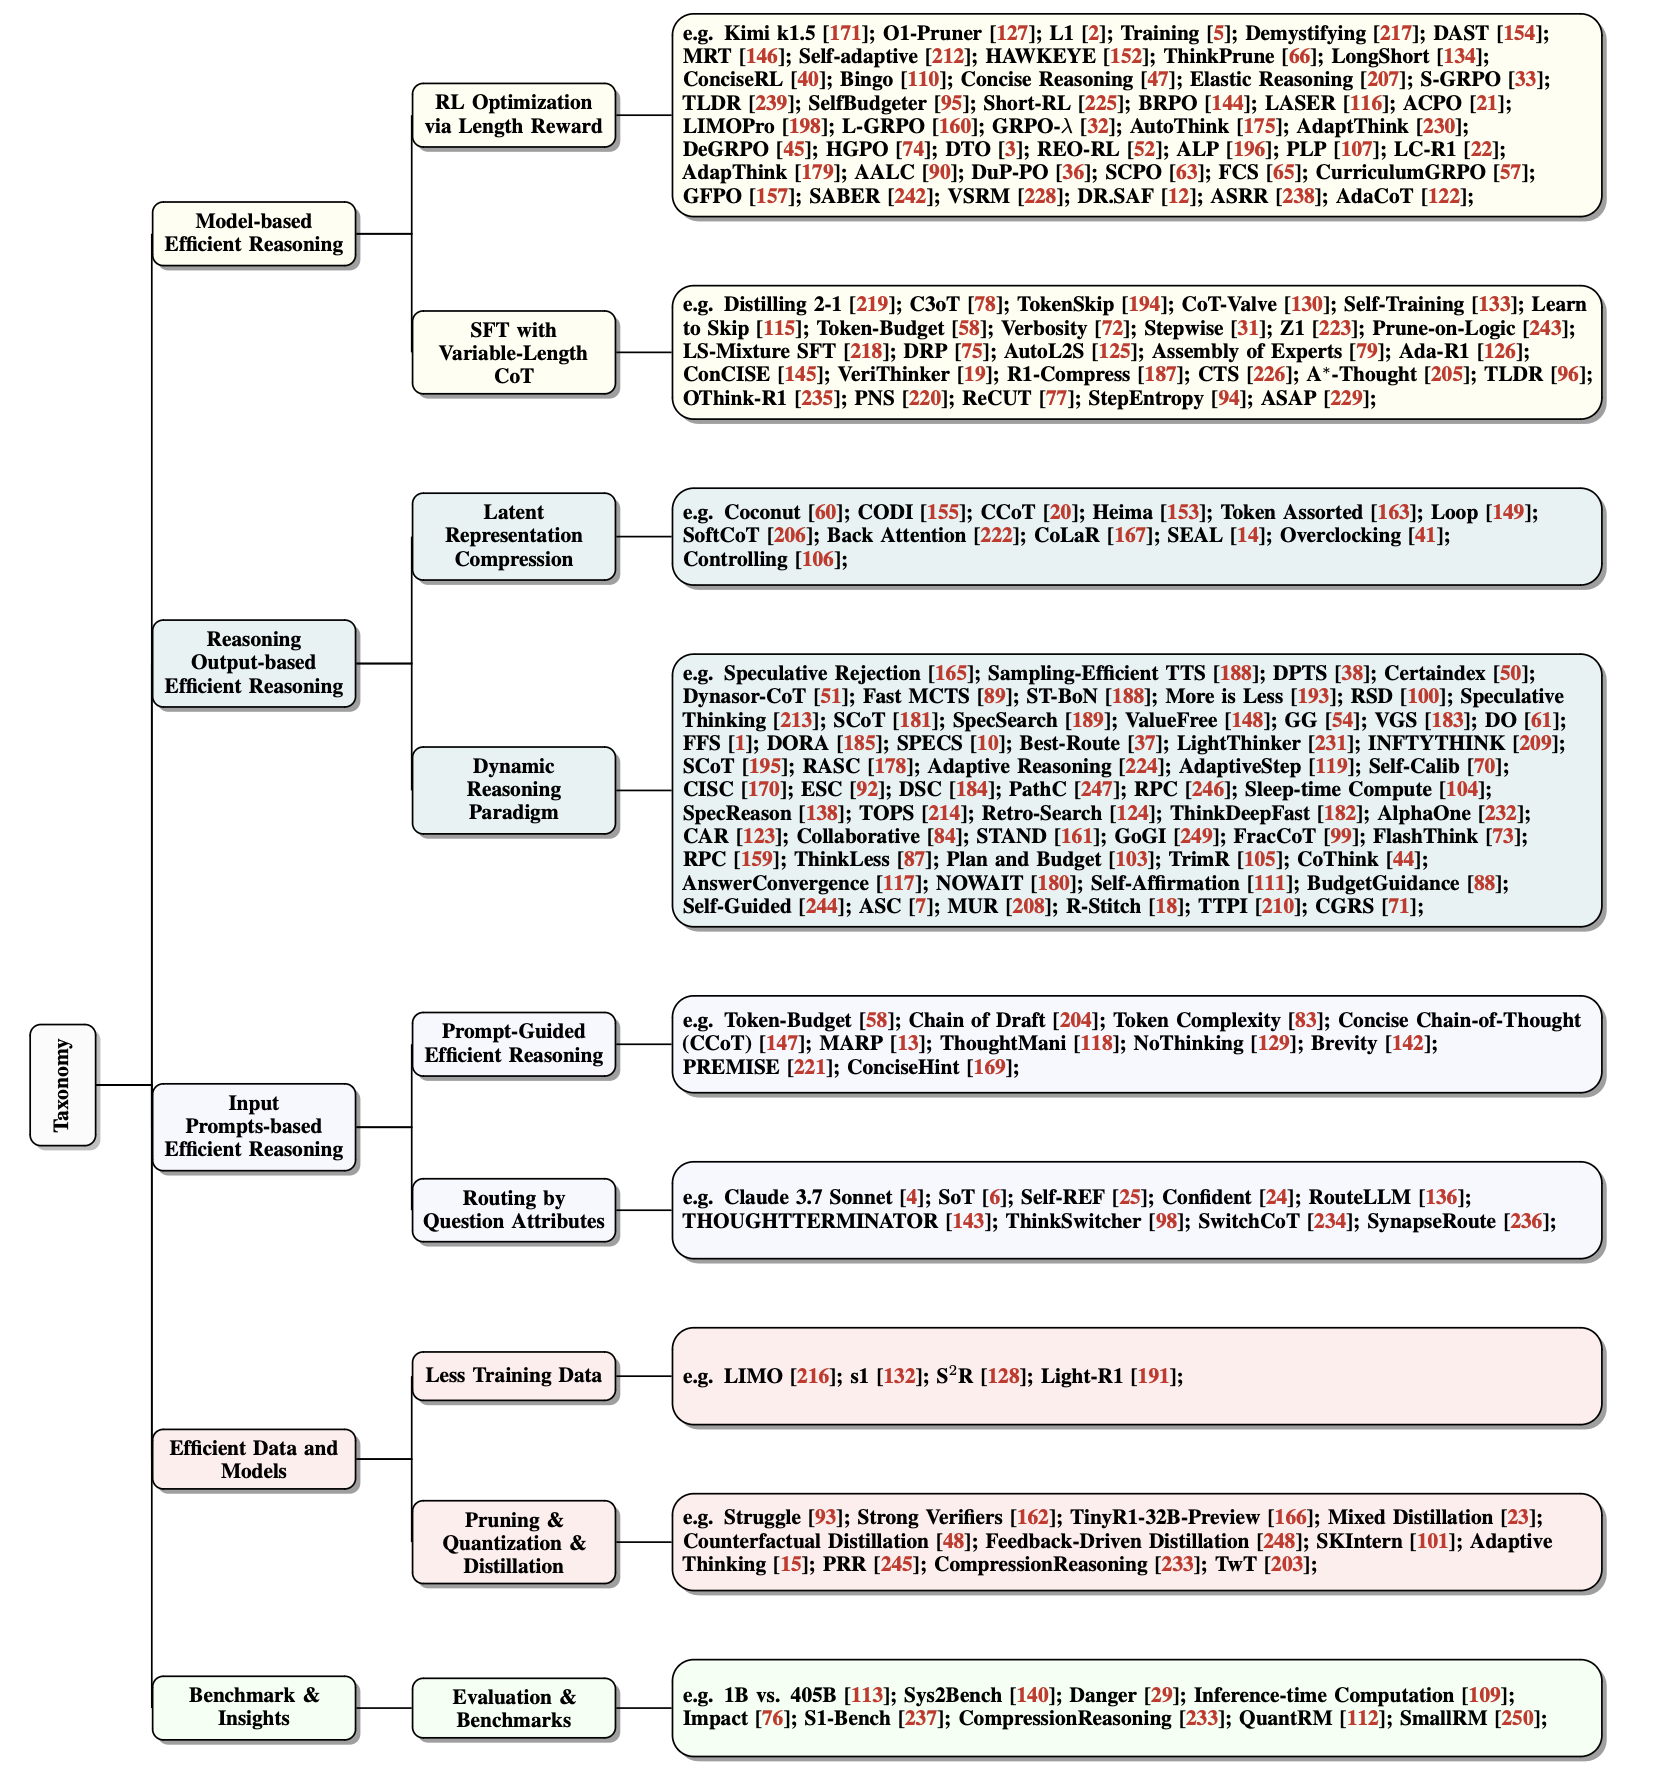
Below is a taxonomy graph summarizing the current landscape of efficient reasoning research for LLMs:
📚 Table of Contents
- Awesome-Efficient-Reasoning-LLMs
- [TMLR 2025] Stop Overthinking: A Survey on Efficient Reasoning for Large Language Models
- 📢 Want to add related papers? Feel free to open a pull request!
- 📢 News
- 📊 Taxonomy
- Section I: RL with Length Reward Design
- Section II: SFT with Variable-Length CoT Data
- Section III: Compressing Reasoning Steps into Fewer Latent Representation
- Section IV: Dynamic Reasoning Paradigm during Inference
- Section V: Prompt-Guided Efficient Reasoning
- Section VI: Prompts Attribute-Driven Reasoning Routing
- Section VII: Reasoning Abilities via Efficient Training Data and Model Compression
- Section VIII: Evaluation and Benchmark
- Citation
- Acknowledgment
"(.)" stands for "To Be Updated" in the survey paper.
Section I: RL with Length Reward Design
- Demystifying Long Chain-of-Thought Reasoning in LLMs [Paper]
- O1-Pruner: Length-Harmonizing Fine-Tuning for O1-Like Reasoning Pruning [Paper]
- Kimi k1.5: Scaling Reinforcement Learning with LLMs [Paper]
- Training Language Models to Reason Efficiently [Paper]
- L1: Controlling How Long A Reasoning Model Thinks With Reinforcement Learning [Paper]
- DAST: Difficulty-Adaptive Slow-Thinking for Large Reasoning Models [Paper]
- Optimizing Test-Time Compute via Meta Reinforcement Fine-Tuning [Paper]
- HAWKEYE: Efficient Reasoning with Model Collaboration [Paper]
- THINKPRUNE: Pruning Long Chain-of-Thought of LLMs via Reinforcement Learning [Paper]
- Think When You Need: Self-Adaptive Chain-of-Thought Learning [Paper]
- Concise Reasoning via Reinforcement Learning [Paper]
- Not All Thoughts are Generated Equal: Efficient LLM Reasoning via Multi-Turn Reinforcement Learning [Paper]
- ConciseRL: Conciseness-Guided Reinforcement Learning for Efficient Reasoning Models [Paper]
- Scalable Chain of Thoughts via Elastic Reasoning [Paper]
- S-GRPO: Early Exit via Reinforcement Learning in Reasoning Models [Paper]
- SelfBudgeter: Adaptive Token Allocation for Efficient LLM Reasoning [Paper]
- Making Small Language Models Efficient Reasoners: Intervention, Supervision, Reinforcement [Paper]
- Efficient RL Training for Reasoning Models via Length-Aware Optimization [Paper]
- Optimizing Anytime Reasoning via Budget Relative Policy Optimization [Paper]
- Learn to Reason Efficiently with Adaptive Length-based Reward Shaping [Paper]
- Incentivizing Dual Process Thinking for Efficient Large Language Model Reasoning [Paper]
- LIMOPro: Reasoning Refinement for Efficient and Effective Test-time Scaling [Paper]
- Walk Before You Run! Concise LLM Reasoning via Reinforcement Learning [Paper]
- Stable Reinforcement Learning for Efficient Reasoning [Paper]
- Don't Think Longer, Think Wisely: Optimizing Thinking Dynamics for Large Reasoning Models [Paper]
- Thinkless: LLM Learns When to Think. [Paper]
- Think Only When You Need with Large Hybrid-Reasoning Models. [Paper]
- When to Continue Thinking: Adaptive Thinking Mode Switching for Efficient Reasoning. [Paper]
- AdaCoT: Pareto-Optimal Adaptive Chain-of-Thought Triggering via Reinforcement Learning. [Paper]
- Learning When to Think: Shaping Adaptive Reasoning in R1-Style Models via Multi-Stage RL. [Paper]
- AdaptThink: Reasoning Models Can Learn When to Think. [Paper]
- Bingo: Boosting Efficient Reasoning of LLMs via Dynamic and Significance-based Reinforcement Learning [Paper]
- How Far Are We from Optimal Reasoning Efficiency? [Paper]
- Just Enough Thinking: Efficient Reasoning with Adaptive Length Penalties Reinforcement Learning. [Paper]
- Fast on the Easy, Deep on the Hard: Efficient Reasoning via Powered Length Penalty. [Paper]
- Optimizing Length Compression in Large Reasoning Models. [Paper]
- AdapThink: Adaptive Thinking Preferences for Reasoning Language Model. [Paper]
- AALC: Large Language Model Efficient Reasoning via Adaptive Accuracy-Length Control. [Paper]
- Do Thinking Tokens Help or Trap? Towards More Efficient Large Reasoning Model. [Paper]
- SmartThinker: Learning to Compress and Preserve Reasoning by Step-Level Length Control. [Paper]
- Reconsidering Overthinking: Penalizing Internal and External Redundancy in CoT Reasoning. [Paper]
- Train Long, Think Short: Curriculum Learning for Efficient Reasoning. [Paper]
- Sample More to Think Less: Group Filtered Policy Optimization for Concise Reasoning. [Paper]
- SABER: Switchable and Balanced Training for Efficient LLM Reasoning. [Paper]
- Promoting Efficient Reasoning with Verifiable Stepwise Reward. [Paper]
- Aware First, Think Less: Dynamic Boundary Self-Awareness Drives Extreme Reasoning Efficiency in Large Language Models. [Paper]
- Beyond Token Length: Step Pruner for Efficient and Accurate Reasoning in Large Language Models [Paper]


Section II: SFT with Variable-Length CoT Data
- TokenSkip: Controllable Chain-of-Thought Compression in LLMs [Paper]
- C3oT: Generating Shorter Chain-of-Thought without Compromising Effectiveness [Paper]
- CoT-Valve: Length-Compressible Chain-of-Thought Tuning [Paper]
- Self-Training Elicits Concise Reasoning in Large Language Models [Paper]
- Distilling System 2 into System 1 [Paper]
- Can Language Models Learn to Skip Steps? [Paper]
- Verbosity-Aware Rationale Reduction: Sentence-Level Rationale Reduction for Efficient and Effective Reasoning. [Paper]
- Stepwise Perplexity-Guided Refinement for Efficient Chain-of-Thought Reasoning in Large Language Models [Paper]
- Z1: Efficient Test-time Scaling with Code [Paper]
- Ada-R1: Hybrid-CoT via Bi-Level Adaptive Reasoning Optimization [Paper]
- Long-Short Chain-of-Thought Mixture Supervised Fine-Tuning Eliciting Efficient Reasoning in Large Language Models [Paper]
- DRP: Distilled Reasoning Pruning with Skill-aware Step Decomposition for Efficient Large Reasoning Models [Paper]
- AutoL2S: Auto Long-Short Reasoning for Efficient Large Language Models [Paper]
- Can Pruning Improve Reasoning? Revisiting Long-CoT Compression with Capability in Mind for Better Reasoning [Paper]
- VeriThinker: Learning to Verify Makes Reasoning Model Efficient [Paper]
- Assembly of Experts: Linear-time construction of the Chimera LLM variants with emergent and adaptable behaviors [Paper] [Model Card] [Free access via OpenRouter]
- R1-Compress: Long Chain-of-Thought Compression via Chunk Compression and Search [Paper]
- Not All Tokens Are What You Need In Thinking [Paper]
- A*-Thought: Efficient Reasoning via Bidirectional Compression for Low-Resource Settings [Paper]
- ConCISE: Confidence-guided Compression in Step-by-step Efficient Reasoning [Paper]
- TL;DR: Too Long, Do Re-weighting for Efficient LLM Reasoning Compression [Paper]
- OThink-R1: Intrinsic Fast/Slow Thinking Mode Switching for Over-Reasoning Mitigation. [Paper]
- Causal Sufficiency and Necessity Improves Chain-of-Thought Reasoning [Paper]
- ReCUT: Balancing Reasoning Length and Accuracy in LLMs via Stepwise Trails and Preference Optimization. [Paper]
- Compressing Chain-of-Thought in LLMs via Step Entropy. [Paper]
- Pruning the Unsurprising: Efficient Code Reasoning via First-Token Surprisal. [Paper]


Section III: Compressing Reasoning Steps into Fewer Latent Representation
- Training Large Language Models to Reason in a Continuous Latent Space [Paper]
- Compressed Chain of Thought: Efficient Reasoning through Dense Representations [Paper]
- Efficient Reasoning with Hidden Thinking (MLLM) [Paper]
- SoftCoT: Soft Chain-of-Thought for Efficient Reasoning with LLMs [Paper]
- Token Assorted: Mixing Latent and Text Tokens for Improved Language Model Reasoning [Paper]
- Reasoning with Latent Thoughts: On the Power of Looped Transformers [Paper]
- CODI: Compressing Chain-of-Thought into Continuous Space via Self-Distillation [Paper]
- Efficient Reasoning with Hidden Thinking [Paper]
- Token Assorted: Mixing Latent and Text Tokens for Improved Language Model Reasoning [Paper]
- Back Attention: Understanding and Enhancing Multi-Hop Reasoning in Large Language Models [Paper]
- SEAL: Steerable Reasoning Calibration of Large Language Models for Free [Paper]
- Think Silently, Think Fast: Dynamic Latent Compression of LLM Reasoning Chains [Paper]
- Overclocking LLM Reasoning: Monitoring and Controlling Thinking Path Lengths in LLMs [Paper]
- Controlling Thinking Speed in Reasoning Models. [Paper]
Section IV: Dynamic Reasoning Paradigm during Inference
- Efficiently Serving LLM Reasoning Programs with Certaindex [Paper]
- When More is Less: Understanding Chain-of-Thought Length in LLMs [Paper]
- Sketch-of-Thought: Efficient LLM Reasoning with Adaptive Cognitive-Inspired Sketching [Paper]
- Reward-Guided Speculative Decoding for Efficient LLM Reasoning [Paper]
- Fast Best-of-N Decoding via Speculative Rejection [Paper]
- FastMCTS: A Simple Sampling Strategy for Data Synthesis [Paper]
- Dynamic Parallel Tree Search for Efficient LLM Reasoning [Paper]
- Sampling-Efficient Test-Time Scaling: Self-Estimating the Best-of-N Sampling in Early Decoding [Paper]
- LightThinker: Thinking Step-by-Step Compression (training LLMs to compress thoughts into gist tokens) [Paper]
- InftyThink: Breaking the Length Limits of Long-Context Reasoning in Large Language Models [Paper]
- Reasoning Without Self-Doubt: More Efficient Chain-of-Thought Through Certainty Probing [Paper]
- SpecReason: Fast and Accurate Inference-Time Compute via Speculative Reasoning [Paper]
- AdaptiveStep: Automatically Dividing Reasoning Step through Model Confidence [Paper]
- Speculative Thinking: Enhancing Small-Model Reasoning with Large Model Guidance at Inference Time [Paper]
- Efficient Reasoning for LLMs through Speculative Chain-of-Thought. [Paper]
- Can atomic step decomposition enhance the self-structured reasoning of multimodal large models? [Paper]
- Think smarter not harder: Adaptive reasoning with inference aware optimization [Paper]
- Reasoning Aware Self-Consistency: Leveraging Reasoning Paths for Efficient LLM Sampling [Paper]
- Escape Sky-high Cost: Early-stopping Self-Consistency for Multi-step Reasoning [Paper]
- Confidence Improves Self-Consistency in LLMs [Paper]
- Make every penny count: Difficulty-adaptive self-consistency for cost-efficient reasoning [Paper]
- Path-consistency: Prefix enhancement for efficient inference in llm [Paper]
- Bridging internal probability and self-consistency for effective and efficient llm reasoning [Paper]
- Towards thinking-optimal scaling of test-time compute for llm reasoning [Paper]
- Think Deep, Think Fast: Investigating Efficiency of Verifier-free Inference-time-scaling Methods[Paper]
- Reasoning models can be effective without thinking [Paper]
- Retro-search: Exploring untaken paths for deeper and efficient reasoning [Paper]
- Thought manipulation: External thought can be efficient for large reasoning models [Paper]
- Sleep-time compute: Beyond inference scaling at test-time [Paper]
- Unlocking the capabilities of thought: A reasoning boundary framework to quantify and optimize chain-of-thought [Paper]
- THOUGHTTERMINATOR: Benchmarking, Calibrating, and Mitigating Overthinking in Reasoning Models [Paper]
- Dynamic Early Exit in Reasoning Models [Paper]
- Stop Spinning Wheels: Mitigating LLM Overthinking via Mining Patterns for Early Reasoning Exit [Paper]
- AlphaOne: Reasoning Models Thinking Slow and Fast at Test Time [Paper]
- Putting the Value Back in RL: Better Test-Time Scaling by Unifying LLM Reasoners With Verifiers. [Paper]
- Guided by Gut: Efficient Test-Time Scaling with Reinforced Intrinsic Confidence. [Paper]
- Fractured Chain-of-Thought Reasoning [Paper]
- Value-Guided Search for Efficient Chain-of-Thought Reasoning. [Paper]
- Don't Overthink it. Preferring Shorter Thinking Chains for Improved LLM Reasoning. [Paper]
- First Finish Search: Efficient Test-Time Scaling in Large Language Models [Paper]
- Accelerating Large Language Model Reasoning via Speculative Search. [Paper]
- FlashThink: An Early Exit Method For Efficient Reasoning [Paper]
- Reasoning Path Compression: Compressing Generation Trajectories for Efficient LLM Reasoning [Paper]
- Accelerating Chain-of-Thought Reasoning: When Goal-Gradient Importance Meets Dynamic Skipping [Paper]
- ThinkLess: A Training-Free Inference-Efficient Method for Reducing Reasoning Redundancy [Paper]
- Plan and Budget: Effective and Efficient Test-Time Scaling on Large Language Model Reasoning [Paper]
- TrimR: Verifier-based Training-Free Thinking Compression for Efficient Test-Time Scaling [Paper]
- CoThink: Token-Efficient Reasoning via Instruct Models Guiding Reasoning Models [Paper]
- Prolonged Reasoning Is Not All You Need: Certainty-Based Adaptive Routing for Efficient LLM/MLLM Reasoning. [Paper]
- AlphaOne: Reasoning Models Thinking Slow and Fast at Test Time. [Paper]
- Every Rollout Counts: Optimal Resource Allocation for Efficient Test-Time Scaling. [Paper]
- SPECS: Faster Test-Time Scaling through Speculative Drafts. [Paper]
- BEST-Route: Adaptive LLM Routing with Test-Time Optimal Compute. [Paper]
- Accelerated Test-Time Scaling with Model-Free Speculative Sampling [Paper]
- Answer Convergence as a Signal for Early Stopping in Reasoning [Paper]
- Collaborative LLM Inference via Planning for Efficient Reasoning. [Paper]
- Wait, We Don't Need to "Wait"! Removing Thinking Tokens Improves Reasoning Efficiency [Paper]
- Efficient Reasoning Through Suppression of Self-Affirmation Reflections in Large Reasoning Models. [Paper]
- Steering LLM Thinking with Budget Guidance. [Paper]
- Exploring and Exploiting the Inherent Efficiency within Large Reasoning Models for Self-Guided Efficiency Enhancement. [Paper]
- Activation Steering for Chain-of-Thought Compression. [Paper]
- R-Stitch: Dynamic Trajectory Stitching for Efficient Reasoning. [Paper]
- Large Reasoning Models Know How to Think Efficiently. [Paper]
- MUR: Momentum Uncertainty guided Reasoning for Large Language Models. [Paper]
- Test-time Prompt Intervention. [Paper]
- Efficient Reasoning for Large Reasoning Language Models via Certainty-Guided Reflection Suppression. [Paper]
- Entropy After
</Think>for reasoning model early exiting [Paper](.)
- Parallel-R1: Towards Parallel Thinking via Reinforcement Learning. [Paper]
- DTS: Enhancing Large Reasoning Models via Decoding Tree Sketching [Paper] [Code] [Colab]


Section V: Prompt-Guided Efficient Reasoning
- Token-Budget-Aware LLM Reasoning [Paper]
- Chain of Draft: Thinking Faster by Writing Less [Paper]
- How Well do LLMs Compress Their Own Chain-of-Thought? A Token Complexity Approach [Paper]
- The Benefits of a Concise Chain of Thought on Problem-Solving in Large Language Models [Paper]
- Brevity is the soul of sustainability: Characterizing LLM response lengths. [Paper]
- PREMISE: Scalable and Strategic Prompt Optimization for Efficient Mathematical Reasoning in Large Models. [Paper]
- ConciseHint: Boosting Efficient Reasoning via Continuous Concise Hints during Generation. [Paper]
Section VI: Prompts Attribute-Driven Reasoning Routing
- Claude 3.7 Sonnet and Claude Code [website]
- Sketch-of-Thought: Efficient LLM Reasoning with Adaptive Cognitive-Inspired Sketching [Paper]
- Learning to Route LLMs with Confidence Tokens [Paper]
- Confident or Seek Stronger: Exploring Uncertainty-Based On-device LLM Routing From Benchmarking to Generalization [Paper]
- RouteLLM: Learning to Route LLMs with Preference Data [Paper]
- ThinkSwitcher: When to Think Hard, When to Think Fast. [Paper]
- Long or short CoT? Investigating Instance-level Switch of Large Reasoning Models. [Paper]
- SynapseRoute: An Auto-Route Switching Framework on Dual-State Large Language Model. [Paper]

Section VII: Reasoning Abilities via Efficient Training Data and Model Compression
- LIMO: Less is More for Reasoning [Paper]
- s1: Simple test-time scaling [Paper]
- S2R: Teaching LLMs to Self-verify and Self-correct via Reinforcement Learning [Paper]
- Light-R1: Curriculum SFT, DPO and RL for Long COT from Scratch and Beyond [Paper]
- Small Models Struggle to Learn from Strong Reasoners [Paper]
- Towards Reasoning Ability of Small Language Models [Paper]
- Mixed Distillation Helps Smaller Language Models Reason Better [Paper]
- Small language models need strong verifiers to self-correct reasoning [Paper]
- Teaching Small Language Models Reasoning through Counterfactual Distillation [Paper]
- Improving Mathematical Reasoning Capabilities of Small Language Models via Feedback-Driven Distillation [Paper]
- Probe then retrieve and reason: Distilling probing and reasoning capabilities into smaller language models [Paper]
- Distilling Reasoning Ability from Large Language Models with Adaptive Thinking [Paper]
- SKIntern: Internalizing Symbolic Knowledge for Distilling Better CoT Capabilities into Small Language Models [Paper]
- TinyR1-32B-Preview: Boosting Accuracy with Branch-Merge Distillation [Paper]
- Improving mathematical reasoning capabilities of small language models via feedback-driven distillation [Paper]
- Probe then retrieve and reason: Distilling probing and reasoning capabilities into smaller language models [Paper]
- TwT: Thinking without Tokens by Habitual Reasoning Distillation with Multi-Teachers’ Guidance [Paper]
- When Reasoning Meets Compression: Benchmarking Compressed Large Reasoning Models on Complex Reasoning Tasks [Paper]


Section VIII: Evaluation and Benchmark
- Can 1B LLM Surpass 405B LLM? Rethinking Compute-Optimal Test-Time Scaling [Paper]
- The Danger of Overthinking: Examining the Reasoning-Action Dilemma in Agentic Tasks [Paper]
- Inference-Time Computations for LLM Reasoning and Planning: A Benchmark and Insights [Paper]
- Bag of Tricks: Benchmarking of Jailbreak Attacks on LLMs [Paper]
- The Impact of Reasoning Step Length on Large Language Models [Paper]
- S1-bench: A simple benchmark for evaluating system 1 thinking capability of large reasoning models [Paper]
- When reasoning meets compression: Benchmarking compressed large reasoning models on complex reasoning tasks. [Paper]
- Quantization Hurts Reasoning? An Empirical Study on Quantized Reasoning Models [Paper]
- A Technical Study into 0.5B Reasoning Language Models. [Paper]
- Revisiting Model Interpolation for Efficient Reasoning. [Paper]
- Do LLMs Really Need 10+ Thoughts for "Find the Time 1000 Days Later"? Towards Structural Understanding of LLM Overthinking [Paper]
Citation
If you find this work useful, please cite us.
@misc{sui2025stopoverthinkingsurveyefficient,
      title={Stop Overthinking: A Survey on Efficient Reasoning for Large Language Models},
      author={Yang Sui and Yu-Neng Chuang and Guanchu Wang and Jiamu Zhang and Tianyi Zhang and Jiayi Yuan and Hongyi Liu and Andrew Wen and Shaochen Zhong and Hanjie Chen and Xia Hu},
      year={2025},
      eprint={2503.16419},
      archivePrefix={arXiv},
      primaryClass={cs.CL},
      url={https://arxiv.org/abs/2503.16419},
}
Acknowledgment
🧩 Layout inspired by zzli2022/Awesome-System2-Reasoning-LLM and the latest works are referred to as hemingkx/Awesome-Efficient-Reasoning. Many thanks for the great structure!
Similar repos


[TMLR 2025] Stop Overthinking: A Survey on Efficient Reasoning for Large Language Models
See the codeREADME
Awesome-Efficient-Reasoning-LLMs
[TMLR 2025] Stop Overthinking: A Survey on Efficient Reasoning for Large Language Models
📢 Want to add related papers? Feel free to open a pull request!
📢 News
- August 21, 2025: Updated.
- July 14, 2025: "Stop Overthinking" is accepted by TMLR, Transactions on Machine Learning Research.
- April 22, 2025: Updated.
- March 20, 2025: We release the first survey for efficient reasoning of LLMs "Stop Overthinking: A Survey on Efficient Reasoning for Large Language Models".
Feel free to cite, contribute, or open a pull request to add recent related papers!
In this paper, we present the first structured survey that systematically investigates and organizes the current progress in achieving efficient reasoning in LLMs.
📊 Taxonomy
Below is a taxonomy graph summarizing the current landscape of efficient reasoning research for LLMs:
📚 Table of Contents
- Awesome-Efficient-Reasoning-LLMs
- [TMLR 2025] Stop Overthinking: A Survey on Efficient Reasoning for Large Language Models
- 📢 Want to add related papers? Feel free to open a pull request!
- 📢 News
- 📊 Taxonomy
- Section I: RL with Length Reward Design
- Section II: SFT with Variable-Length CoT Data
- Section III: Compressing Reasoning Steps into Fewer Latent Representation
- Section IV: Dynamic Reasoning Paradigm during Inference
- Section V: Prompt-Guided Efficient Reasoning
- Section VI: Prompts Attribute-Driven Reasoning Routing
- Section VII: Reasoning Abilities via Efficient Training Data and Model Compression
- Section VIII: Evaluation and Benchmark
- Citation
- Acknowledgment
"(.)" stands for "To Be Updated" in the survey paper.
Section I: RL with Length Reward Design
- Demystifying Long Chain-of-Thought Reasoning in LLMs [Paper]
- O1-Pruner: Length-Harmonizing Fine-Tuning for O1-Like Reasoning Pruning [Paper]
- Kimi k1.5: Scaling Reinforcement Learning with LLMs [Paper]
- Training Language Models to Reason Efficiently [Paper]
- L1: Controlling How Long A Reasoning Model Thinks With Reinforcement Learning [Paper]
- DAST: Difficulty-Adaptive Slow-Thinking for Large Reasoning Models [Paper]
- Optimizing Test-Time Compute via Meta Reinforcement Fine-Tuning [Paper]
- HAWKEYE: Efficient Reasoning with Model Collaboration [Paper]
- THINKPRUNE: Pruning Long Chain-of-Thought of LLMs via Reinforcement Learning [Paper]
- Think When You Need: Self-Adaptive Chain-of-Thought Learning [Paper]
- Concise Reasoning via Reinforcement Learning [Paper]
- Not All Thoughts are Generated Equal: Efficient LLM Reasoning via Multi-Turn Reinforcement Learning [Paper]
- ConciseRL: Conciseness-Guided Reinforcement Learning for Efficient Reasoning Models [Paper]
- Scalable Chain of Thoughts via Elastic Reasoning [Paper]
- S-GRPO: Early Exit via Reinforcement Learning in Reasoning Models [Paper]
- SelfBudgeter: Adaptive Token Allocation for Efficient LLM Reasoning [Paper]
- Making Small Language Models Efficient Reasoners: Intervention, Supervision, Reinforcement [Paper]
- Efficient RL Training for Reasoning Models via Length-Aware Optimization [Paper]
- Optimizing Anytime Reasoning via Budget Relative Policy Optimization [Paper]
- Learn to Reason Efficiently with Adaptive Length-based Reward Shaping [Paper]
- Incentivizing Dual Process Thinking for Efficient Large Language Model Reasoning [Paper]
- LIMOPro: Reasoning Refinement for Efficient and Effective Test-time Scaling [Paper]
- Walk Before You Run! Concise LLM Reasoning via Reinforcement Learning [Paper]
- Stable Reinforcement Learning for Efficient Reasoning [Paper]
- Don't Think Longer, Think Wisely: Optimizing Thinking Dynamics for Large Reasoning Models [Paper]
- Thinkless: LLM Learns When to Think. [Paper]
- Think Only When You Need with Large Hybrid-Reasoning Models. [Paper]
- When to Continue Thinking: Adaptive Thinking Mode Switching for Efficient Reasoning. [Paper]
- AdaCoT: Pareto-Optimal Adaptive Chain-of-Thought Triggering via Reinforcement Learning. [Paper]
- Learning When to Think: Shaping Adaptive Reasoning in R1-Style Models via Multi-Stage RL. [Paper]
- AdaptThink: Reasoning Models Can Learn When to Think. [Paper]
- Bingo: Boosting Efficient Reasoning of LLMs via Dynamic and Significance-based Reinforcement Learning [Paper]
- How Far Are We from Optimal Reasoning Efficiency? [Paper]
- Just Enough Thinking: Efficient Reasoning with Adaptive Length Penalties Reinforcement Learning. [Paper]
- Fast on the Easy, Deep on the Hard: Efficient Reasoning via Powered Length Penalty. [Paper]
- Optimizing Length Compression in Large Reasoning Models. [Paper]
- AdapThink: Adaptive Thinking Preferences for Reasoning Language Model. [Paper]
- AALC: Large Language Model Efficient Reasoning via Adaptive Accuracy-Length Control. [Paper]
- Do Thinking Tokens Help or Trap? Towards More Efficient Large Reasoning Model. [Paper]
- SmartThinker: Learning to Compress and Preserve Reasoning by Step-Level Length Control. [Paper]
- Reconsidering Overthinking: Penalizing Internal and External Redundancy in CoT Reasoning. [Paper]
- Train Long, Think Short: Curriculum Learning for Efficient Reasoning. [Paper]
- Sample More to Think Less: Group Filtered Policy Optimization for Concise Reasoning. [Paper]
- SABER: Switchable and Balanced Training for Efficient LLM Reasoning. [Paper]
- Promoting Efficient Reasoning with Verifiable Stepwise Reward. [Paper]
- Aware First, Think Less: Dynamic Boundary Self-Awareness Drives Extreme Reasoning Efficiency in Large Language Models. [Paper]
- Beyond Token Length: Step Pruner for Efficient and Accurate Reasoning in Large Language Models [Paper]
Section II: SFT with Variable-Length CoT Data
- TokenSkip: Controllable Chain-of-Thought Compression in LLMs [Paper]
- C3oT: Generating Shorter Chain-of-Thought without Compromising Effectiveness [Paper]
- CoT-Valve: Length-Compressible Chain-of-Thought Tuning [Paper]
- Self-Training Elicits Concise Reasoning in Large Language Models [Paper]
- Distilling System 2 into System 1 [Paper]
- Can Language Models Learn to Skip Steps? [Paper]
- Verbosity-Aware Rationale Reduction: Sentence-Level Rationale Reduction for Efficient and Effective Reasoning. [Paper]
- Stepwise Perplexity-Guided Refinement for Efficient Chain-of-Thought Reasoning in Large Language Models [Paper]
- Z1: Efficient Test-time Scaling with Code [Paper]
- Ada-R1: Hybrid-CoT via Bi-Level Adaptive Reasoning Optimization [Paper]
- Long-Short Chain-of-Thought Mixture Supervised Fine-Tuning Eliciting Efficient Reasoning in Large Language Models [Paper]
- DRP: Distilled Reasoning Pruning with Skill-aware Step Decomposition for Efficient Large Reasoning Models [Paper]
- AutoL2S: Auto Long-Short Reasoning for Efficient Large Language Models [Paper]
- Can Pruning Improve Reasoning? Revisiting Long-CoT Compression with Capability in Mind for Better Reasoning [Paper]
- VeriThinker: Learning to Verify Makes Reasoning Model Efficient [Paper]
- Assembly of Experts: Linear-time construction of the Chimera LLM variants with emergent and adaptable behaviors [Paper] [Model Card] [Free access via OpenRouter]
- R1-Compress: Long Chain-of-Thought Compression via Chunk Compression and Search [Paper]
- Not All Tokens Are What You Need In Thinking [Paper]
- A*-Thought: Efficient Reasoning via Bidirectional Compression for Low-Resource Settings [Paper]
- ConCISE: Confidence-guided Compression in Step-by-step Efficient Reasoning [Paper]
- TL;DR: Too Long, Do Re-weighting for Efficient LLM Reasoning Compression [Paper]
- OThink-R1: Intrinsic Fast/Slow Thinking Mode Switching for Over-Reasoning Mitigation. [Paper]
- Causal Sufficiency and Necessity Improves Chain-of-Thought Reasoning [Paper]
- ReCUT: Balancing Reasoning Length and Accuracy in LLMs via Stepwise Trails and Preference Optimization. [Paper]
- Compressing Chain-of-Thought in LLMs via Step Entropy. [Paper]
- Pruning the Unsurprising: Efficient Code Reasoning via First-Token Surprisal. [Paper]
Section III: Compressing Reasoning Steps into Fewer Latent Representation
- Training Large Language Models to Reason in a Continuous Latent Space [Paper]
- Compressed Chain of Thought: Efficient Reasoning through Dense Representations [Paper]
- Efficient Reasoning with Hidden Thinking (MLLM) [Paper]
- SoftCoT: Soft Chain-of-Thought for Efficient Reasoning with LLMs [Paper]
- Token Assorted: Mixing Latent and Text Tokens for Improved Language Model Reasoning [Paper]
- Reasoning with Latent Thoughts: On the Power of Looped Transformers [Paper]
- CODI: Compressing Chain-of-Thought into Continuous Space via Self-Distillation [Paper]
- Efficient Reasoning with Hidden Thinking [Paper]
- Token Assorted: Mixing Latent and Text Tokens for Improved Language Model Reasoning [Paper]
- Back Attention: Understanding and Enhancing Multi-Hop Reasoning in Large Language Models [Paper]
- SEAL: Steerable Reasoning Calibration of Large Language Models for Free [Paper]
- Think Silently, Think Fast: Dynamic Latent Compression of LLM Reasoning Chains [Paper]
- Overclocking LLM Reasoning: Monitoring and Controlling Thinking Path Lengths in LLMs [Paper]
- Controlling Thinking Speed in Reasoning Models. [Paper]
Section IV: Dynamic Reasoning Paradigm during Inference
- Efficiently Serving LLM Reasoning Programs with Certaindex [Paper]
- When More is Less: Understanding Chain-of-Thought Length in LLMs [Paper]
- Sketch-of-Thought: Efficient LLM Reasoning with Adaptive Cognitive-Inspired Sketching [Paper]
- Reward-Guided Speculative Decoding for Efficient LLM Reasoning [Paper]
- Fast Best-of-N Decoding via Speculative Rejection [Paper]
- FastMCTS: A Simple Sampling Strategy for Data Synthesis [Paper]
- Dynamic Parallel Tree Search for Efficient LLM Reasoning [Paper]
- Sampling-Efficient Test-Time Scaling: Self-Estimating the Best-of-N Sampling in Early Decoding [Paper]
- LightThinker: Thinking Step-by-Step Compression (training LLMs to compress thoughts into gist tokens) [Paper]
- InftyThink: Breaking the Length Limits of Long-Context Reasoning in Large Language Models [Paper]
- Reasoning Without Self-Doubt: More Efficient Chain-of-Thought Through Certainty Probing [Paper]
- SpecReason: Fast and Accurate Inference-Time Compute via Speculative Reasoning [Paper]
- AdaptiveStep: Automatically Dividing Reasoning Step through Model Confidence [Paper]
- Speculative Thinking: Enhancing Small-Model Reasoning with Large Model Guidance at Inference Time [Paper]
- Efficient Reasoning for LLMs through Speculative Chain-of-Thought. [Paper]
- Can atomic step decomposition enhance the self-structured reasoning of multimodal large models? [Paper]
- Think smarter not harder: Adaptive reasoning with inference aware optimization [Paper]
- Reasoning Aware Self-Consistency: Leveraging Reasoning Paths for Efficient LLM Sampling [Paper]
- Escape Sky-high Cost: Early-stopping Self-Consistency for Multi-step Reasoning [Paper]
- Confidence Improves Self-Consistency in LLMs [Paper]
- Make every penny count: Difficulty-adaptive self-consistency for cost-efficient reasoning [Paper]
- Path-consistency: Prefix enhancement for efficient inference in llm [Paper]
- Bridging internal probability and self-consistency for effective and efficient llm reasoning [Paper]
- Towards thinking-optimal scaling of test-time compute for llm reasoning [Paper]
- Think Deep, Think Fast: Investigating Efficiency of Verifier-free Inference-time-scaling Methods[Paper]
- Reasoning models can be effective without thinking [Paper]
- Retro-search: Exploring untaken paths for deeper and efficient reasoning [Paper]
- Thought manipulation: External thought can be efficient for large reasoning models [Paper]
- Sleep-time compute: Beyond inference scaling at test-time [Paper]
- Unlocking the capabilities of thought: A reasoning boundary framework to quantify and optimize chain-of-thought [Paper]
- THOUGHTTERMINATOR: Benchmarking, Calibrating, and Mitigating Overthinking in Reasoning Models [Paper]
- Dynamic Early Exit in Reasoning Models [Paper]
- Stop Spinning Wheels: Mitigating LLM Overthinking via Mining Patterns for Early Reasoning Exit [Paper]
- AlphaOne: Reasoning Models Thinking Slow and Fast at Test Time [Paper]
- Putting the Value Back in RL: Better Test-Time Scaling by Unifying LLM Reasoners With Verifiers. [Paper]
- Guided by Gut: Efficient Test-Time Scaling with Reinforced Intrinsic Confidence. [Paper]
- Fractured Chain-of-Thought Reasoning [Paper]
- Value-Guided Search for Efficient Chain-of-Thought Reasoning. [Paper]
- Don't Overthink it. Preferring Shorter Thinking Chains for Improved LLM Reasoning. [Paper]
- First Finish Search: Efficient Test-Time Scaling in Large Language Models [Paper]
- Accelerating Large Language Model Reasoning via Speculative Search. [Paper]
- FlashThink: An Early Exit Method For Efficient Reasoning [Paper]
- Reasoning Path Compression: Compressing Generation Trajectories for Efficient LLM Reasoning [Paper]
- Accelerating Chain-of-Thought Reasoning: When Goal-Gradient Importance Meets Dynamic Skipping [Paper]
- ThinkLess: A Training-Free Inference-Efficient Method for Reducing Reasoning Redundancy [Paper]
- Plan and Budget: Effective and Efficient Test-Time Scaling on Large Language Model Reasoning [Paper]
- TrimR: Verifier-based Training-Free Thinking Compression for Efficient Test-Time Scaling [Paper]
- CoThink: Token-Efficient Reasoning via Instruct Models Guiding Reasoning Models [Paper]
- Prolonged Reasoning Is Not All You Need: Certainty-Based Adaptive Routing for Efficient LLM/MLLM Reasoning. [Paper]
- AlphaOne: Reasoning Models Thinking Slow and Fast at Test Time. [Paper]
- Every Rollout Counts: Optimal Resource Allocation for Efficient Test-Time Scaling. [Paper]
- SPECS: Faster Test-Time Scaling through Speculative Drafts. [Paper]
- BEST-Route: Adaptive LLM Routing with Test-Time Optimal Compute. [Paper]
- Accelerated Test-Time Scaling with Model-Free Speculative Sampling [Paper]
- Answer Convergence as a Signal for Early Stopping in Reasoning [Paper]
- Collaborative LLM Inference via Planning for Efficient Reasoning. [Paper]
- Wait, We Don't Need to "Wait"! Removing Thinking Tokens Improves Reasoning Efficiency [Paper]
- Efficient Reasoning Through Suppression of Self-Affirmation Reflections in Large Reasoning Models. [Paper]
- Steering LLM Thinking with Budget Guidance. [Paper]
- Exploring and Exploiting the Inherent Efficiency within Large Reasoning Models for Self-Guided Efficiency Enhancement. [Paper]
- Activation Steering for Chain-of-Thought Compression. [Paper]
- R-Stitch: Dynamic Trajectory Stitching for Efficient Reasoning. [Paper]
- Large Reasoning Models Know How to Think Efficiently. [Paper]
- MUR: Momentum Uncertainty guided Reasoning for Large Language Models. [Paper]
- Test-time Prompt Intervention. [Paper]
- Efficient Reasoning for Large Reasoning Language Models via Certainty-Guided Reflection Suppression. [Paper]
- Entropy After
</Think>for reasoning model early exiting [Paper] - Parallel-R1: Towards Parallel Thinking via Reinforcement Learning. [Paper]
- DTS: Enhancing Large Reasoning Models via Decoding Tree Sketching [Paper] [Code] [Colab]
Section V: Prompt-Guided Efficient Reasoning
- Token-Budget-Aware LLM Reasoning [Paper]
- Chain of Draft: Thinking Faster by Writing Less [Paper]
- How Well do LLMs Compress Their Own Chain-of-Thought? A Token Complexity Approach [Paper]
- The Benefits of a Concise Chain of Thought on Problem-Solving in Large Language Models [Paper]
- Brevity is the soul of sustainability: Characterizing LLM response lengths. [Paper]
- PREMISE: Scalable and Strategic Prompt Optimization for Efficient Mathematical Reasoning in Large Models. [Paper]
- ConciseHint: Boosting Efficient Reasoning via Continuous Concise Hints during Generation. [Paper]
Section VI: Prompts Attribute-Driven Reasoning Routing
- Claude 3.7 Sonnet and Claude Code [website]
- Sketch-of-Thought: Efficient LLM Reasoning with Adaptive Cognitive-Inspired Sketching [Paper]
- Learning to Route LLMs with Confidence Tokens [Paper]
- Confident or Seek Stronger: Exploring Uncertainty-Based On-device LLM Routing From Benchmarking to Generalization [Paper]
- RouteLLM: Learning to Route LLMs with Preference Data [Paper]
- ThinkSwitcher: When to Think Hard, When to Think Fast. [Paper]
- Long or short CoT? Investigating Instance-level Switch of Large Reasoning Models. [Paper]
- SynapseRoute: An Auto-Route Switching Framework on Dual-State Large Language Model. [Paper]
Section VII: Reasoning Abilities via Efficient Training Data and Model Compression
- LIMO: Less is More for Reasoning [Paper]
- s1: Simple test-time scaling [Paper]
- S2R: Teaching LLMs to Self-verify and Self-correct via Reinforcement Learning [Paper]
- Light-R1: Curriculum SFT, DPO and RL for Long COT from Scratch and Beyond [Paper]
- Small Models Struggle to Learn from Strong Reasoners [Paper]
- Towards Reasoning Ability of Small Language Models [Paper]
- Mixed Distillation Helps Smaller Language Models Reason Better [Paper]
- Small language models need strong verifiers to self-correct reasoning [Paper]
- Teaching Small Language Models Reasoning through Counterfactual Distillation [Paper]
- Improving Mathematical Reasoning Capabilities of Small Language Models via Feedback-Driven Distillation [Paper]
- Probe then retrieve and reason: Distilling probing and reasoning capabilities into smaller language models [Paper]
- Distilling Reasoning Ability from Large Language Models with Adaptive Thinking [Paper]
- SKIntern: Internalizing Symbolic Knowledge for Distilling Better CoT Capabilities into Small Language Models [Paper]
- TinyR1-32B-Preview: Boosting Accuracy with Branch-Merge Distillation [Paper]
- Improving mathematical reasoning capabilities of small language models via feedback-driven distillation [Paper]
- Probe then retrieve and reason: Distilling probing and reasoning capabilities into smaller language models [Paper]
- TwT: Thinking without Tokens by Habitual Reasoning Distillation with Multi-Teachers’ Guidance [Paper]
- When Reasoning Meets Compression: Benchmarking Compressed Large Reasoning Models on Complex Reasoning Tasks [Paper]
Section VIII: Evaluation and Benchmark
- Can 1B LLM Surpass 405B LLM? Rethinking Compute-Optimal Test-Time Scaling [Paper]
- The Danger of Overthinking: Examining the Reasoning-Action Dilemma in Agentic Tasks [Paper]
- Inference-Time Computations for LLM Reasoning and Planning: A Benchmark and Insights [Paper]
- Bag of Tricks: Benchmarking of Jailbreak Attacks on LLMs [Paper]
- The Impact of Reasoning Step Length on Large Language Models [Paper]
- S1-bench: A simple benchmark for evaluating system 1 thinking capability of large reasoning models [Paper]
- When reasoning meets compression: Benchmarking compressed large reasoning models on complex reasoning tasks. [Paper]
- Quantization Hurts Reasoning? An Empirical Study on Quantized Reasoning Models [Paper]
- A Technical Study into 0.5B Reasoning Language Models. [Paper]
- Revisiting Model Interpolation for Efficient Reasoning. [Paper]
- Do LLMs Really Need 10+ Thoughts for "Find the Time 1000 Days Later"? Towards Structural Understanding of LLM Overthinking [Paper]
Citation
If you find this work useful, please cite us.
@misc{sui2025stopoverthinkingsurveyefficient,
      title={Stop Overthinking: A Survey on Efficient Reasoning for Large Language Models},
      author={Yang Sui and Yu-Neng Chuang and Guanchu Wang and Jiamu Zhang and Tianyi Zhang and Jiayi Yuan and Hongyi Liu and Andrew Wen and Shaochen Zhong and Hanjie Chen and Xia Hu},
      year={2025},
      eprint={2503.16419},
      archivePrefix={arXiv},
      primaryClass={cs.CL},
      url={https://arxiv.org/abs/2503.16419},
}
Acknowledgment
🧩 Layout inspired by zzli2022/Awesome-System2-Reasoning-LLM and the latest works are referred to as hemingkx/Awesome-Efficient-Reasoning. Many thanks for the great structure!