
[ICCV2025] Training-Free Diffusion Models for Geometric Image Editing
Jupyter Notebook
39
90 commits
updated Jan 13, 2026
README
FreeFine: Training-Free Diffusion for Geometric Image Editing


Official Implementation of ICCV 2025 Accepted Paper
🌟 Introduction
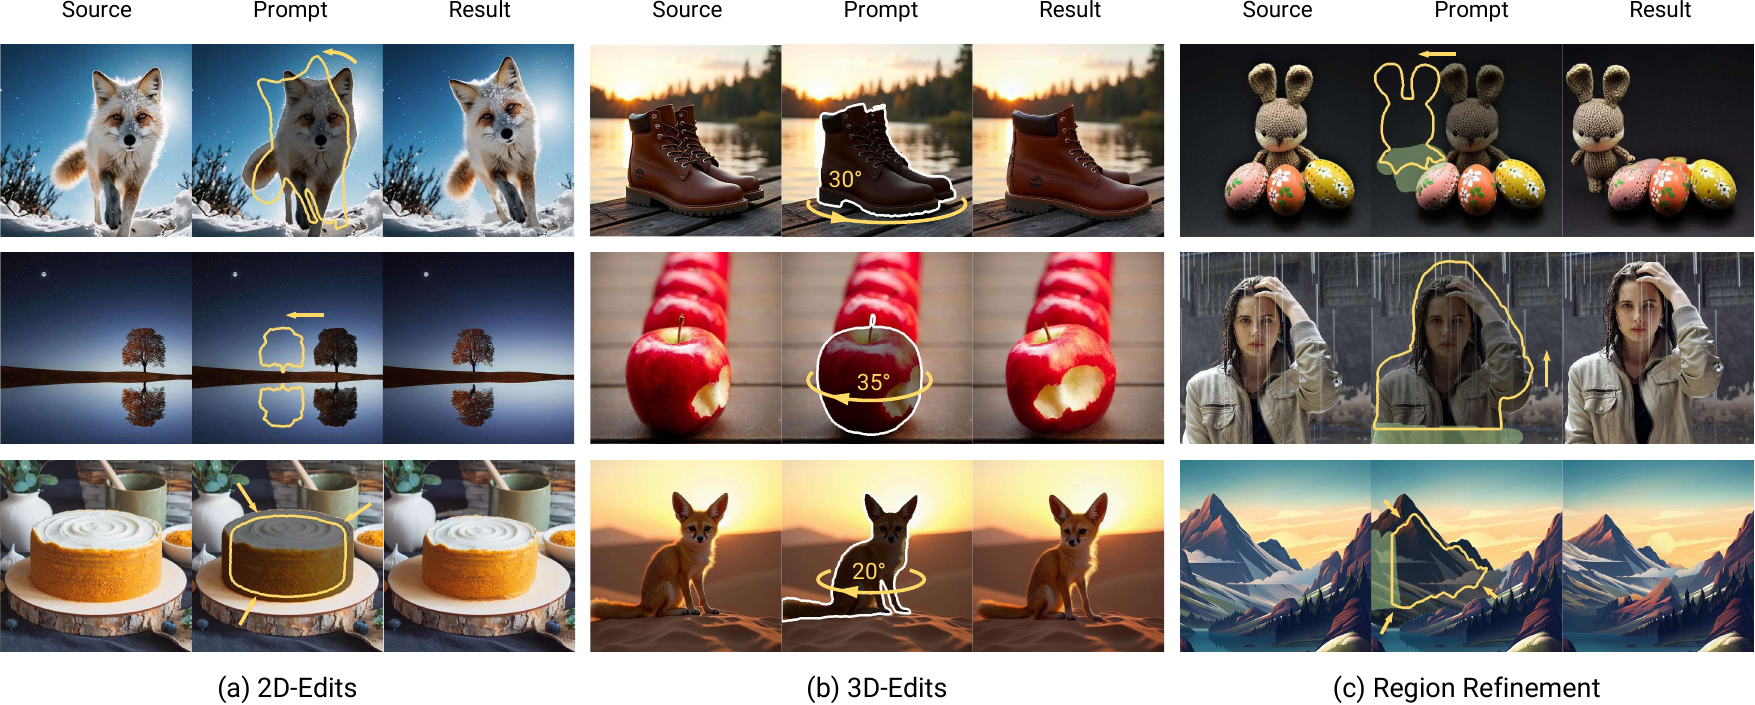
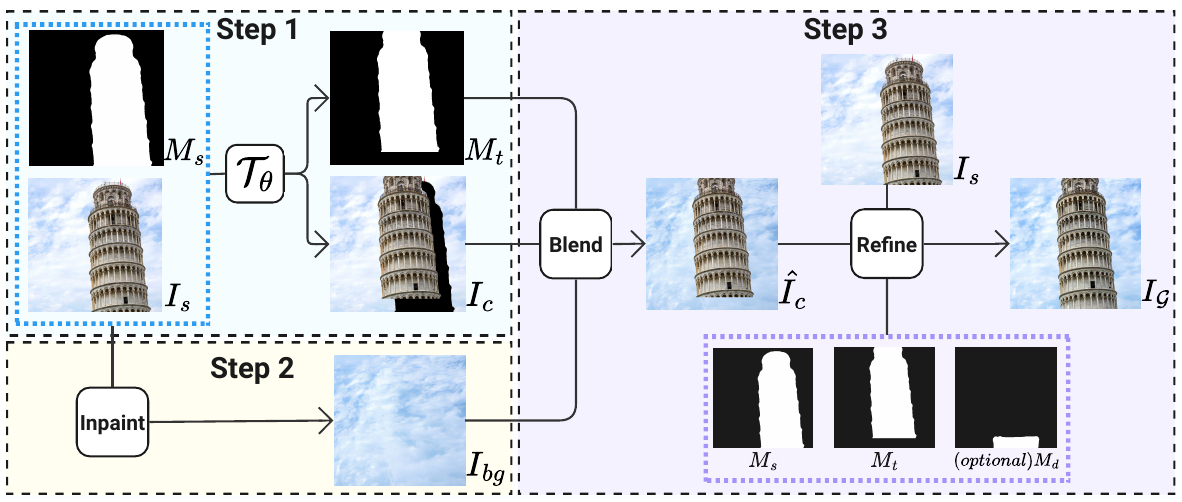
We present FreeFine, a novel framework for high-fidelity geometric image editing that enpowers users with both Object-centric Editing(such as Object Repositioning, Reorientation, and Reshaping and Fine-grained Partial Editing, all while maintaining global coherence. Remarkably, our framework simultaneously achieves Structure Completion, Object Removal, Appearance Transfer, and Multi-Image Composition within a unified pipeline - all through efficient, training-free algorithms based on diffusion models.
🔥 News
- 2025-08-26: 🚀 Scheduled Full Project Open-Source Release
We’re gearing up to release the entire FreeFine ecosystem, with these key components currently in development:- 📊 GeoBench benchmark dataset (2D/3D geometric editing scenarios)
- 📈 Evaluation code for quantitative performance testing
- ⚙️ Complete inference codebase for end-to-end editing pipelines
- 📓 Interactive Jupyter notebook demos (step-by-step tutorials)
- 2025-07-31: Our Arxiv Paper is now available!
- 2025-06-26: 🎉FreeFine has been accepted to ICCV 2025! 🎉
📌 TODO
- Arxiv Paper
- Release Code
- GeoBench benchmark dataset
- Evaluation code platform
- Jupyter notebook demos
- Gradio interface demos
- Adapt to stronger baselines such as SDXL and DIT
🛠️ Installation
git clone https://github.com/CIawevy/FreeFine.git
cd FreeFine
conda create -n FreeFine python=3.10.13 -y
conda activate FreeFine
pip install -r requirements.txt
- Install Pytorch3D (Optional for depth-based 3D-editing)
pip install iopath>=0.1.10 -i https://pypi.org/simple
pip install --no-index --no-cache-dir git+https://github.com/facebookresearch/pytorch3d.git@stable -i https://pypi.org/simple
pip install cupy-cuda12x==13.0.0
- Install SV3D (Optional for SV3D-based 3D-editing)
# Set up SV3D environment
cd generative-models
conda create -n pt2 python=3.10.0 -y
conda activate pt2
pip3 install -r requirements/pt2.txt
pip3 install . #Install sgm
⏬ Download Models
- Modify parameters (e.g., local paths, HF token) in
scripts/download_models.shas needed, then run the following command to download models:
bash scripts/download_models.sh
📊 Eval
We provide the scripts for evaluating GeoBench-2d and GeoBench-3d for FreeFine and all the Baselines. Please See EVAL for more details.
🚀 Quick Start
Run on Jupyter Notebooks
cd jupyter_demo
Run On Web Interface 🚧
⚠️ The web interface is currently under construction. Once ready, start it with:
python app.py
📚 Relate Repos
[1] DragonDiffusion: Enabling Drag-style Manipulation on Diffusion Models
[2] <a href=https://github.com/google/prompt-to-prompt>**PROMPT-TO-PROMPT IMAGE EDITING WITH CROSS-ATTENTION CONTROL** [3] <a href=https://github.com/Stability-AI/generative-models>**SV3D: Novel Multi-view Synthesis and 3D Generation from a Single Image using Latent Video Diffusion** [4] <a href=https://github.com/LiheYoung/Depth-Anything>**Depth Anything: Unleashing the Power of Large-Scale Unlabeled Data** [5] <a href=https://github.com/RahulSajnani/GeoDiffuser>**GeoDiffuser: Geometry-Based Image Editing with Diffusion Models**📜 Citation
@inproceedings{zhu2025training,
  title={Training-free Geometric Image Editing on Diffusion Models},
  author={Zhu, Hanshen and Zhu, Zhen and Zhang, Kaile and Gong, Yiming and Liu, Yuliang and Bai, Xiang},
  booktitle={Proceedings of the IEEE/CVF International Conference on Computer Vision},
  pages={19130--19140},
  year={2025}
}
Similar repos


Languages
Jupyter Notebook
81.3%
Python
18.4%
[ICCV2025] Training-Free Diffusion Models for Geometric Image Editing
Jupyter Notebook
39
90 commits
updated Jan 13, 2026
README
FreeFine: Training-Free Diffusion for Geometric Image Editing
Official Implementation of ICCV 2025 Accepted Paper
🌟 Introduction
We present FreeFine, a novel framework for high-fidelity geometric image editing that enpowers users with both Object-centric Editing(such as Object Repositioning, Reorientation, and Reshaping and Fine-grained Partial Editing, all while maintaining global coherence. Remarkably, our framework simultaneously achieves Structure Completion, Object Removal, Appearance Transfer, and Multi-Image Composition within a unified pipeline - all through efficient, training-free algorithms based on diffusion models.
🔥 News
- 2025-08-26: 🚀 Scheduled Full Project Open-Source Release
We’re gearing up to release the entire FreeFine ecosystem, with these key components currently in development:- 📊 GeoBench benchmark dataset (2D/3D geometric editing scenarios)
- 📈 Evaluation code for quantitative performance testing
- ⚙️ Complete inference codebase for end-to-end editing pipelines
- 📓 Interactive Jupyter notebook demos (step-by-step tutorials)
- 2025-07-31: Our Arxiv Paper is now available!
- 2025-06-26: 🎉FreeFine has been accepted to ICCV 2025! 🎉
📌 TODO
- Arxiv Paper
- Release Code
- GeoBench benchmark dataset
- Evaluation code platform
- Jupyter notebook demos
- Gradio interface demos
- Adapt to stronger baselines such as SDXL and DIT
🛠️ Installation
git clone https://github.com/CIawevy/FreeFine.git
cd FreeFine
conda create -n FreeFine python=3.10.13 -y
conda activate FreeFine
pip install -r requirements.txt
- Install Pytorch3D (Optional for depth-based 3D-editing)
pip install iopath>=0.1.10 -i https://pypi.org/simple
pip install --no-index --no-cache-dir git+https://github.com/facebookresearch/pytorch3d.git@stable -i https://pypi.org/simple
pip install cupy-cuda12x==13.0.0
- Install SV3D (Optional for SV3D-based 3D-editing)
# Set up SV3D environment
cd generative-models
conda create -n pt2 python=3.10.0 -y
conda activate pt2
pip3 install -r requirements/pt2.txt
pip3 install . #Install sgm
⏬ Download Models
- Modify parameters (e.g., local paths, HF token) in
scripts/download_models.shas needed, then run the following command to download models:
bash scripts/download_models.sh
📊 Eval
We provide the scripts for evaluating GeoBench-2d and GeoBench-3d for FreeFine and all the Baselines. Please See EVAL for more details.
🚀 Quick Start
Run on Jupyter Notebooks
cd jupyter_demo
Run On Web Interface 🚧
⚠️ The web interface is currently under construction. Once ready, start it with:
python app.py
📚 Relate Repos
[1] DragonDiffusion: Enabling Drag-style Manipulation on Diffusion Models
[2] <a href=https://github.com/google/prompt-to-prompt>**PROMPT-TO-PROMPT IMAGE EDITING WITH CROSS-ATTENTION CONTROL** [3] <a href=https://github.com/Stability-AI/generative-models>**SV3D: Novel Multi-view Synthesis and 3D Generation from a Single Image using Latent Video Diffusion** [4] <a href=https://github.com/LiheYoung/Depth-Anything>**Depth Anything: Unleashing the Power of Large-Scale Unlabeled Data** [5] <a href=https://github.com/RahulSajnani/GeoDiffuser>**GeoDiffuser: Geometry-Based Image Editing with Diffusion Models**📜 Citation
@inproceedings{zhu2025training,
  title={Training-free Geometric Image Editing on Diffusion Models},
  author={Zhu, Hanshen and Zhu, Zhen and Zhang, Kaile and Gong, Yiming and Liu, Yuliang and Bai, Xiang},
  booktitle={Proceedings of the IEEE/CVF International Conference on Computer Vision},
  pages={19130--19140},
  year={2025}
}
Similar repos
Languages
Jupyter Notebook
81.3%
Python
18.4%