
(ACL-2025 main conference) SurveyForge: On the Outline Heuristics, Memory-Driven Generation, and Multi-dimensional Evaluation for Automated Survey Writing
Python
334
22 commits
updated Aug 27, 2025
README
(ACL-2025) SurveyForge: On the Outline Heuristics, Memory-Driven Generation, and Multi-dimensional Evaluation for Automated Survey Writing
[ Paper 📓 ] [ SurveyBench Benchmark 🤗 ] [SurveyForge Database 🤗]
🤩 Tired of chaotic structures and inaccurate references in AI-generated survey paper? SurveyForge is here to revolutionize your research experience!🔥 News
-
Coming soon: 🎉🎉 Support the generation of comprehensive surveys in all fields on the online website.
-
2025.06: 🎉🎉 We released the code of SurveyForge.
-
2025.05: 🎉🎉 Congratulations: SurveyForge was accepted by ACL-2025 main conference.
Introduction
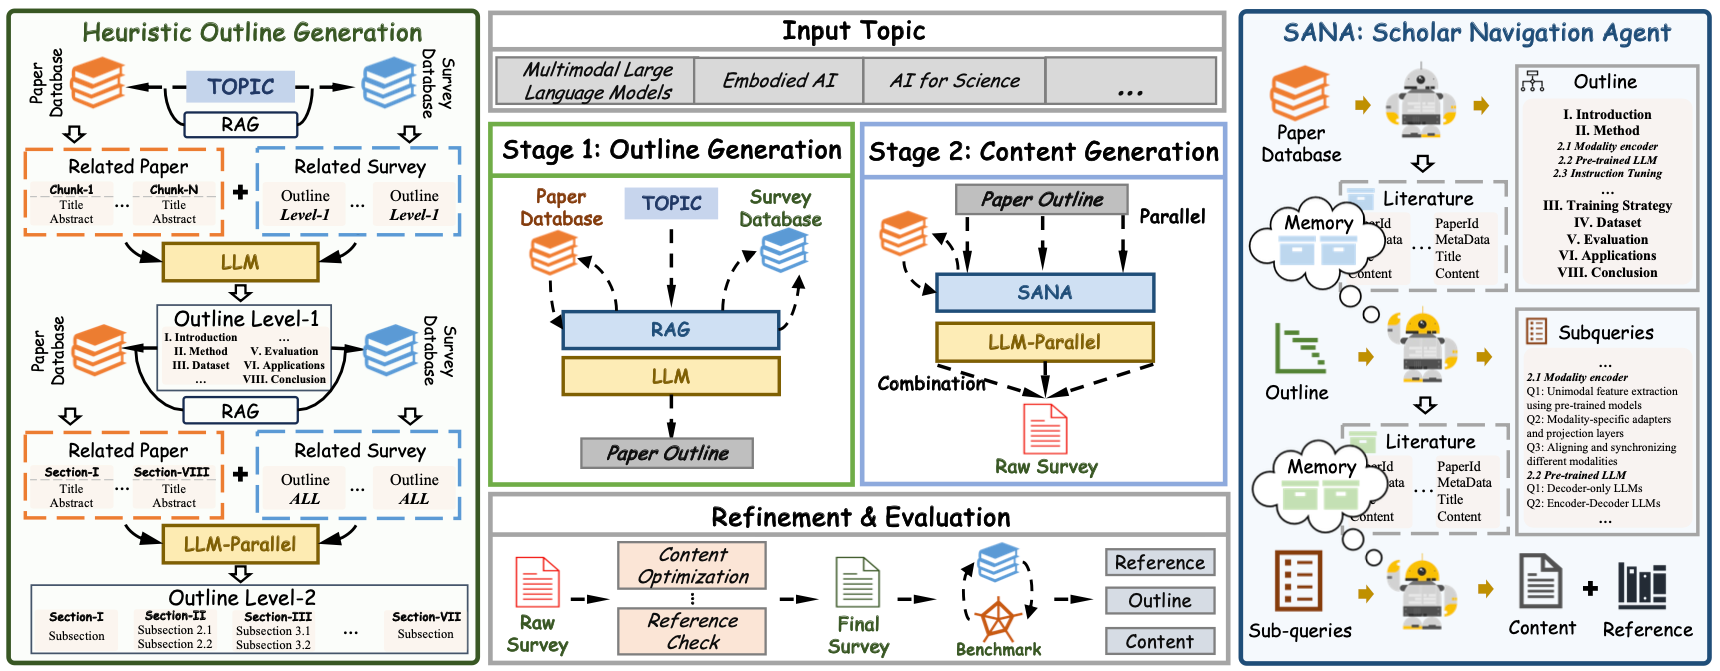
Survey papers are vital in scientific research, especially with the rapid increase in research publications. Recently, researchers have started using LLMs to automate survey creation for improved efficiency. However, LLM-generated surveys often fall short compared to human-written ones, particularly in outline quality and citation accuracy. To address this, we introduce SurveyForge, which first creates an outline by analyzing the structure of human-written outlines and consulting domain-related articles. Then, using high-quality papers retrieved by our scholar navigation agent, SurveyForge can automatically generate and refine the content of the survey.
Moreover, to achieve a comprehensive evaluation, we construct SurveyBench, which includes 100 human-written survey papers for win-rate comparison and assesses AI-generated survey papers across three dimensions: reference, outline, and content quality.
🤔How to try out SurveyForge?
-
First you need to download the database from [SurveyForge Database].
-
Then you need to download the embedding model from [gte-large-en-v1.5]
-
Finally, configure your API KEY and data path in code/run_demo.py and run the command as follows:
cd code && python run_demo.py
🕵️♂️How to evaluate the quality of the survey paper?
We offer SurveyBench, a benchmark for academic research and evaluating the quality of AI-generated surveys.
Currently , SurveyBench consists of approximately 100 human-written survey papers across 10 distinct topics, carefully curated by doctoral-level researchers to ensure thematic consistency and academic rigor. The supported topics and the core references corresponding to each topic are as follows:
| Topics | # Reference |
|---|---|
| Multimodal Large Language Models | 912 |
| Evaluation of Large Language Models | 714 |
| 3D Object Detection in Autonomous Driving | 441 |
| Vision Transformers | 563 |
| Hallucination in Large Language Models | 500 |
| Generative Diffusion Models | 994 |
| 3D Gaussian Splatting | 330 |
| LLM-based Multi-Agent | 823 |
| Graph Neural Networks | 670 |
| Retrieval-Augmented Generation for Large Language Models | 608 |
More support topics coming soon!
🧑💻You can evaluate the survey by:
cd SurveyBench && python test.py --is_human_eval
Note set is_human_eval True for human survey evaluation, False for generated surveys.
If you want to evaluate your method on SurveyBench, please follow the format:
generated_surveys
|-- 3D Gaussian Splatting
    |-- exp_1
        |-- ref.json
    |-- exp_2
        |-- ref.json
...
|-- Graph Neural Networks
...
📝Examples
| Topics | Links |
|---|---|
| Multimodal Large Language Models | Comprehensive Survey on Multimodal Large Language Models Advances, Challenges, and Future Directions.pdf |
| 3D Object Detection in Autonomous Driving | Comprehensive Survey on 3D Object Detection in Autonomous Driving.pdf |
| Vision Transformers | A Comprehensive Survey on Vision Transformers Foundations, Advances, Applications, and Future Directions.pdf |
| Generative Diffusion Models | Comprehensive Survey on Generative Diffusion Models Foundations, Innovations, and Applications.pdf |
| LLM-based Multi-Agent | Comprehensive Survey of Large Language Model-Based Multi-Agent Systems.pdf |
| Self-Supervised Learning in Computer Vision | A Comprehensive Survey on Self-Supervised Learning in Computer Vision.pdf |
| Embodied Artificial Intelligence | A Comprehensive Survey on Embodied Artificial Intelligence Foundations, Advances, and Future Directions.pdf |
| ............ |
Acknowledgements
We sincerely thank the AutoSurvey for laying the foundation in automated survey generation and analysis. SurveyForge is developed on top of the AutoSurvey framework, and we remain committed to continuous innovation and delivering ever more powerful, flexible solutions for automated survey research.
Citations
@article{yan2025surveyforge,
  title={Surveyforge: On the outline heuristics, memory-driven generation, and multi-dimensional evaluation for automated survey writing},
  author={Yan, Xiangchao and Feng, Shiyang and Yuan, Jiakang and Xia, Renqiu and Wang, Bin and Zhang, Bo and Bai, Lei},
  journal={arXiv preprint arXiv:2503.04629},
  year={2025}
}
Contributors


Similar repos


Languages
Python
100.0%
(ACL-2025 main conference) SurveyForge: On the Outline Heuristics, Memory-Driven Generation, and Multi-dimensional Evaluation for Automated Survey Writing
Python
334
22 commits
updated Aug 27, 2025
README
(ACL-2025) SurveyForge: On the Outline Heuristics, Memory-Driven Generation, and Multi-dimensional Evaluation for Automated Survey Writing
[ Paper 📓 ] [ SurveyBench Benchmark 🤗 ] [SurveyForge Database 🤗]
🤩 Tired of chaotic structures and inaccurate references in AI-generated survey paper? SurveyForge is here to revolutionize your research experience!🔥 News
-
Coming soon: 🎉🎉 Support the generation of comprehensive surveys in all fields on the online website.
-
2025.06: 🎉🎉 We released the code of SurveyForge.
-
2025.05: 🎉🎉 Congratulations: SurveyForge was accepted by ACL-2025 main conference.
Introduction
Survey papers are vital in scientific research, especially with the rapid increase in research publications. Recently, researchers have started using LLMs to automate survey creation for improved efficiency. However, LLM-generated surveys often fall short compared to human-written ones, particularly in outline quality and citation accuracy. To address this, we introduce SurveyForge, which first creates an outline by analyzing the structure of human-written outlines and consulting domain-related articles. Then, using high-quality papers retrieved by our scholar navigation agent, SurveyForge can automatically generate and refine the content of the survey.
Moreover, to achieve a comprehensive evaluation, we construct SurveyBench, which includes 100 human-written survey papers for win-rate comparison and assesses AI-generated survey papers across three dimensions: reference, outline, and content quality.
🤔How to try out SurveyForge?
-
First you need to download the database from [SurveyForge Database].
-
Then you need to download the embedding model from [gte-large-en-v1.5]
-
Finally, configure your API KEY and data path in code/run_demo.py and run the command as follows:
cd code && python run_demo.py
🕵️♂️How to evaluate the quality of the survey paper?
We offer SurveyBench, a benchmark for academic research and evaluating the quality of AI-generated surveys.
Currently , SurveyBench consists of approximately 100 human-written survey papers across 10 distinct topics, carefully curated by doctoral-level researchers to ensure thematic consistency and academic rigor. The supported topics and the core references corresponding to each topic are as follows:
| Topics | # Reference |
|---|---|
| Multimodal Large Language Models | 912 |
| Evaluation of Large Language Models | 714 |
| 3D Object Detection in Autonomous Driving | 441 |
| Vision Transformers | 563 |
| Hallucination in Large Language Models | 500 |
| Generative Diffusion Models | 994 |
| 3D Gaussian Splatting | 330 |
| LLM-based Multi-Agent | 823 |
| Graph Neural Networks | 670 |
| Retrieval-Augmented Generation for Large Language Models | 608 |
More support topics coming soon!
🧑💻You can evaluate the survey by:
cd SurveyBench && python test.py --is_human_eval
Note set is_human_eval True for human survey evaluation, False for generated surveys.
If you want to evaluate your method on SurveyBench, please follow the format:
generated_surveys
|-- 3D Gaussian Splatting
    |-- exp_1
        |-- ref.json
    |-- exp_2
        |-- ref.json
...
|-- Graph Neural Networks
...
📝Examples
| Topics | Links |
|---|---|
| Multimodal Large Language Models | Comprehensive Survey on Multimodal Large Language Models Advances, Challenges, and Future Directions.pdf |
| 3D Object Detection in Autonomous Driving | Comprehensive Survey on 3D Object Detection in Autonomous Driving.pdf |
| Vision Transformers | A Comprehensive Survey on Vision Transformers Foundations, Advances, Applications, and Future Directions.pdf |
| Generative Diffusion Models | Comprehensive Survey on Generative Diffusion Models Foundations, Innovations, and Applications.pdf |
| LLM-based Multi-Agent | Comprehensive Survey of Large Language Model-Based Multi-Agent Systems.pdf |
| Self-Supervised Learning in Computer Vision | A Comprehensive Survey on Self-Supervised Learning in Computer Vision.pdf |
| Embodied Artificial Intelligence | A Comprehensive Survey on Embodied Artificial Intelligence Foundations, Advances, and Future Directions.pdf |
| ............ |
Acknowledgements
We sincerely thank the AutoSurvey for laying the foundation in automated survey generation and analysis. SurveyForge is developed on top of the AutoSurvey framework, and we remain committed to continuous innovation and delivering ever more powerful, flexible solutions for automated survey research.
Citations
@article{yan2025surveyforge,
  title={Surveyforge: On the outline heuristics, memory-driven generation, and multi-dimensional evaluation for automated survey writing},
  author={Yan, Xiangchao and Feng, Shiyang and Yuan, Jiakang and Xia, Renqiu and Wang, Bin and Zhang, Bo and Bai, Lei},
  journal={arXiv preprint arXiv:2503.04629},
  year={2025}
}
Similar repos
Contributors
Languages
Python
100.0%