
🔥 A Survey on AI Auto-Research
See the codeREADME


:sunglasses: Awesome AI Auto-Research
 |
|---|
This repository accompanies the survey paper "AI for Auto-Research: Roadmap & User Guide" and tracks papers on AI-assisted and automated scientific research, covering the full research lifecycle.
:robot: AI Auto-Research
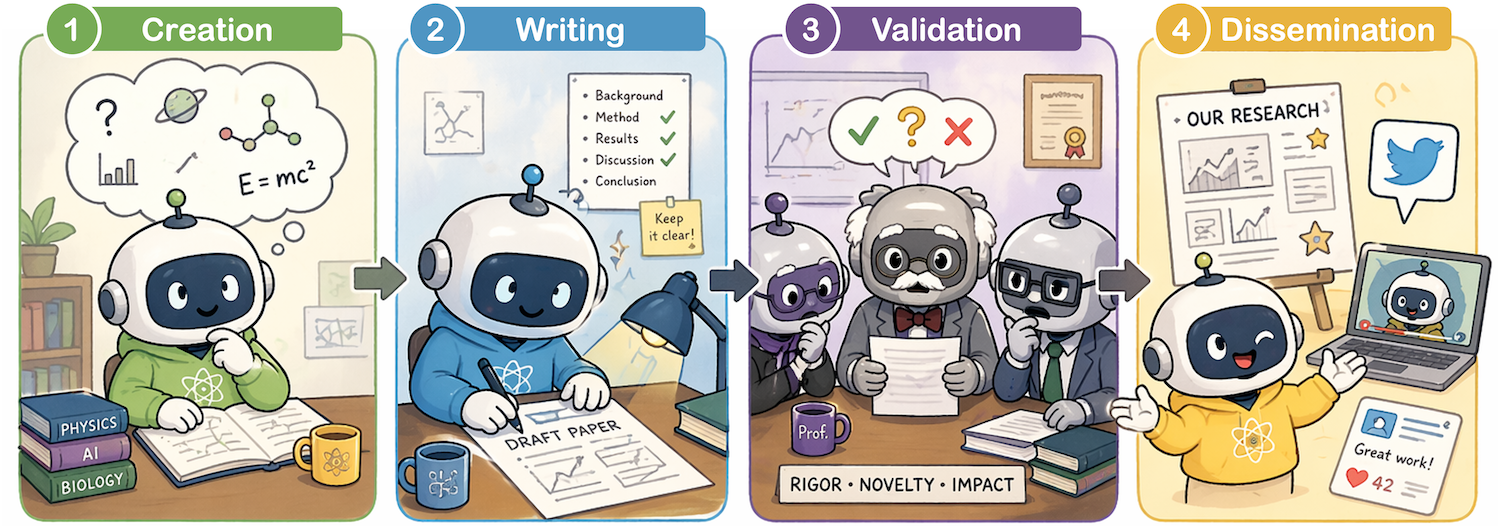
We organize the academic research lifecycle as eight interconnected stages grouped into four epistemological phases. Each phase serves a distinct function in producing, scrutinizing, and communicating scientific knowledge.
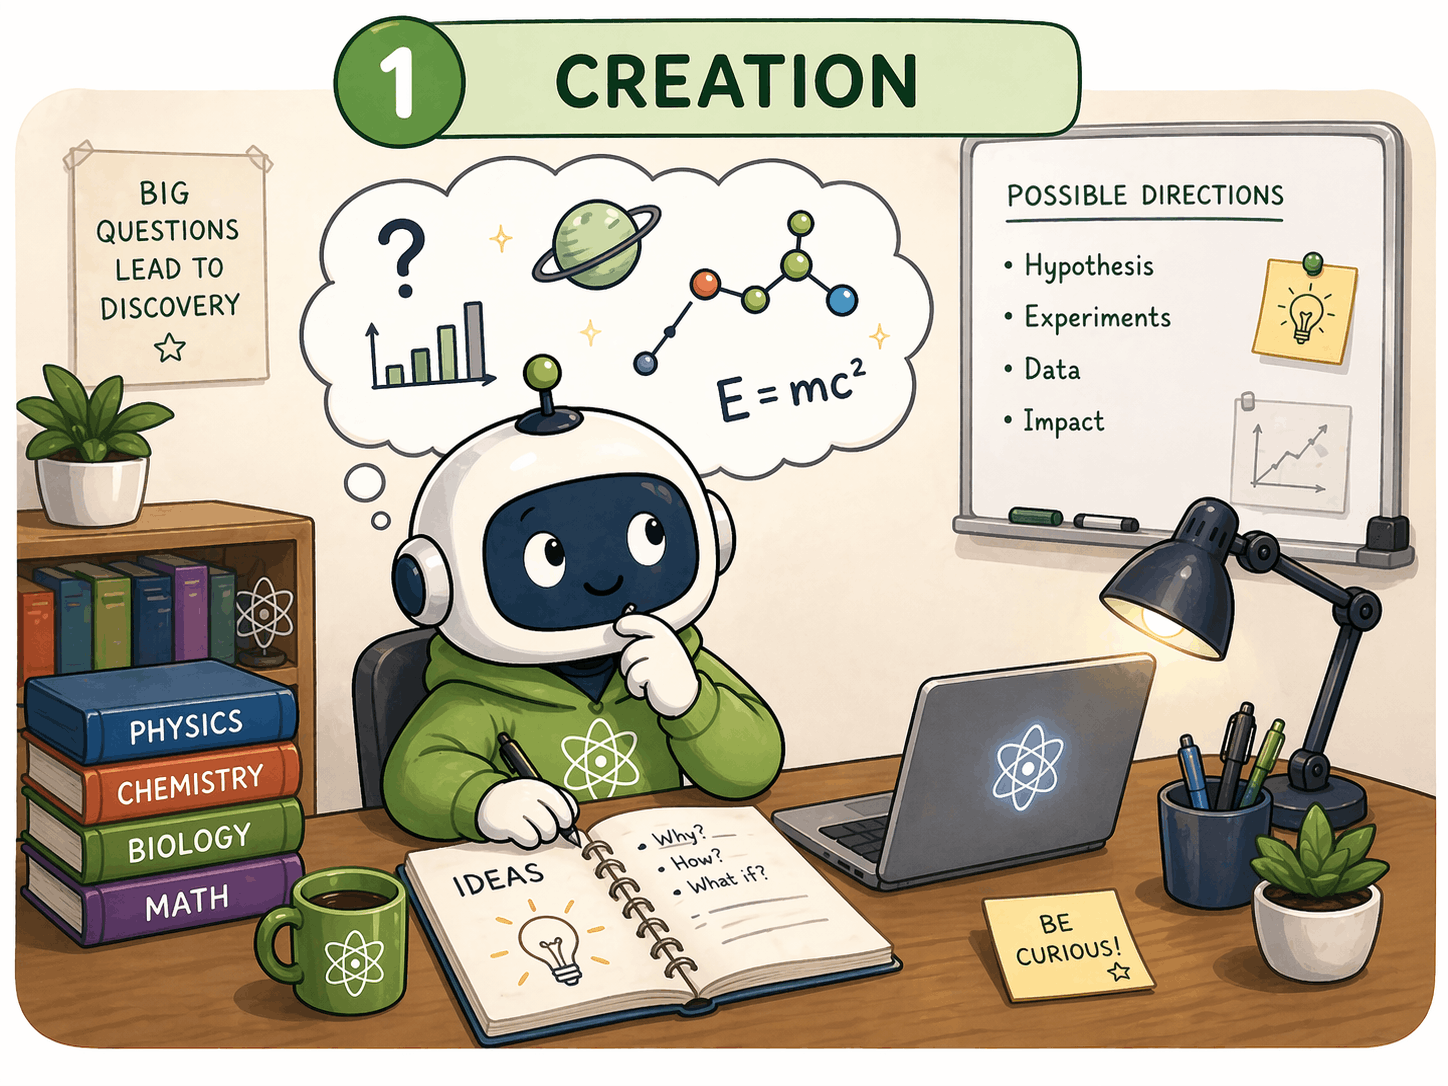
 | Phase 1: Creation Generating novel research ideas, searching and synthesizing literature, running coding experiments, and creating publication-quality tables and figures. This phase spans Idea Generation, Literature Review, Coding & Experiments, and Tables & Figures. |
 | Phase 2: Writing Drafting, editing, and polishing academic manuscripts. AI assistance ranges from semi-automated grammar and citation tools to fully automated paper generation — the most commercially mature yet ethically contested stage. |
 | Phase 3: Validation Automated peer review generation, reviewer-paper matching, review quality assessment, and AI-assisted author rebuttals. This phase covers Peer Review and Rebuttal & Revision. |
 | Phase 4: Dissemination Converting papers into slides, posters, videos, websites, and social media content. Each output format targets a different audience and demands its own design logic and AI tool chain. |
For additional details, kindly refer to our :books: Paper and :earth_asia: Project Page.
:books: Citation
If you find this work helpful for your research, please kindly consider citing our paper:
@article{survey-ai-auto-research,
  title   = {{AI} for {Auto-Research}: Roadmap \& User Guide},
  author  = {Kong, Lingdong and Sun, Xian and Chow, Wei and Li, Linfeng and Lin, Kevin Qinghong and Zhang, Xuan Billy
             and Wang, Song and Li, Rong and Wu, Qing and Gao, Wei and Wang, Yingshuo and Xie, Shaoyuan
             and Liu, Jiachen and Qu, Leigang and Li, Shijie and Ng, Lai Xing and Cottereau, Benoit R.
             and Liu, Ziwei and Chua, Tat-Seng and Ooi, Wei Tsang},
  journal = {arXiv preprint arXiv:2605.18661},
  year    = {2026}
}
Table of Contents
- 1. Idea Generation
- 2. Literature Review & Paper Search
- 3. Coding & Experimentation
- 4. Tables & Figures
- 5. Paper Writing
- 6. Peer Review
- 7. Rebuttal
- 8. Dissemination (Paper2X)
- 9. End-to-End Systems
- 10. Societal & Critical Perspectives
- 11. Surveys & Curated Lists
- 12. Tools & GitHub Repos
 |
|---|
1. Idea Generation
LLM Internal Knowledge-Based Generation
In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
Chain of Ideas |  Chain of Ideas: Revolutionizing Research Via Novel Idea Development with LLM Agents | arXiv '24 | - |  |
ResearchAgent |  ResearchAgent: Iterative Research Idea Generation over Scientific Literature with Large Language Models | NAACL '25 | - |  |
SciMON |  SciMON: Scientific Inspiration Machines Optimized for Novelty | ACL '24 | - |  |
Idea Gen Agent |  Can LLMs Generate Novel Research Ideas? A Large Scale Human Study with 100+ NLP Researchers | arXiv '24 | - | - |
IRIS | IRIS: Interactive Research Ideation System for Accelerating Scientific Discovery | ACL '25 | - |  |
Spark |  Spark: A System for Scientifically Creative Idea Generation | ICCC '25 | - | - |
Diverse Hypo. Search |  Towards Diverse Scientific Hypothesis Search with Large Language Models | arXiv '26 | - | - |
Tree-of-Ideas |  Tree-of-Ideas: Automated Research Ideation via Cross-Trajectory Reasoning over Scholarly Evolution | arXiv '26 | - | - |
IDEAgent |  IDEAgent: Agentic Quality-Diversity Search for Research Idea Generation | arXiv '26 | - | - |
External Signal-Driven Generation
In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
SGHA |  SGHA: Evidence-Grounded Research Problem Discovery with Local Language Models | arXiv '26 | - | - |
MAIL |  MAIL: Memory-driven, Adaptive, Incremental, and Literature-grounded Framework for Hypothesis Generation in Chemistry | arXiv '26 | - | - |
MOOSE-Chem | MOOSE-Chem: Large Language Models for Rediscovering Unseen Chemistry Scientific Hypotheses | ICLR '25 | - | - |
Nova |  Nova: An Iterative Planning and Search Approach to Enhance Novelty and Diversity of LLM Generated Ideas | arXiv '24 | - | - |
SciAgents |  SciAgents: Automating Scientific Discovery through Multi-Agent Intelligent Graph Reasoning | arXiv '24 | - |  |
SciPIP |  SciPIP: An LLM-based Scientific Paper Idea Proposer | arXiv '24 | - |  |
IdeaSynth |  IdeaSynth: Iterative Research Idea Development Through Evolving and Composing Idea Facets with Literature-Grounded Feedback | CHI '25 | - | - |
MOOSE-Chem2 | MOOSE-Chem2: Exploring LLM Limits in Fine-Grained Scientific Hypothesis Discovery via Hierarchical Search | NeurIPS '25 | - | - |
HALO |  HALO: Interactive Co-abductive Reasoning in Scientific Hypothesis Generation | arXiv '26 | - | - |
TCA-SIR |  TCA-SIR: Learning Target-Conditioned Abstractions for Scientific Inspiration Retrieval | arXiv '26 | - | - |
ECLAIR |  ECLAIR: A Causally-Grounded AI Framework for Scientific Discovery in Empirical Software Engineering | arXiv '26 | - | - |
Multi-Agent Collaborative Generation
In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
HypoForge |  HypoForge: A Self-Improving Multi-Agent Framework for Automated Hypothesis Generation and Testing via Scientific Skill Learning | arXiv '26 | - | - |
Combi. Creativity |  Combi. Creativity | arXiv '24 | - | - |
Deep Ideation |  Deep Ideation: Designing LLM Agents to Generate Novel Research Ideas on Scientific Concept Network | arXiv '25 | - |  |
VirSci | Many Heads Are Better Than One: Improved Scientific Idea Generation by A LLM-Based Multi-Agent System | ACL '25 | - |  |
Multi-Agent Dial. |  Multi-Agent Dial. | SIGDIAL '25 | - | - |
Artificial Hivemind |  Artificial Hivemind: The Open-Ended Homogeneity of Language Models (and Beyond) | NeurIPS '25 | - | - |
Auditable AI Sci. |  Toward Auditable AI Scientists: A Hypothesis Evolution Protocol for LLM Agents | arXiv '26 | - | - |
Diverse Personalized Ideation |  Diversifying Personalized Research Ideation against AI-Induced Homogenization | arXiv '26 | - | - |
Novelty and Feasibility Assessment
In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
RATIO |  RATIO: A Benchmark for Retrieval Across Typed Ideation Operations in Scientific Literature | arXiv '26 | - | - |
Lit2Test |  What Proves You Wrong: Benchmarking Language Models on Falsifiable Research Ideation | arXiv '26 | - | - |
Energy Scoring |  Do LLMs Know a Good Hypothesis When They See One? Logit-Based Energy Scoring Outperforms Prompted LLM-as-Judge for Scientific Hypothesis Ranking | arXiv '26 | - | - |
Think-Probe-Respond |  Think-Probe-Respond: Improving Large Language Models as Judges of Research Idea Novelty | EMNLP '26 | - | - |
IdeaBench | LiveIdeaBench: Evaluating LLMs' Scientific Creativity and Idea Generation with Minimal Context | KDD '25 | - | - |
LiveIdeaBench |  LiveIdeaBench: Evaluating LLMs' Scientific Creativity and Idea Generation with Minimal Context | arXiv '24 | - | - |
AI Idea Bench 2025 |  AI Idea Bench 2025: AI Research Idea Generation Benchmark | arXiv '25 | - |  |
HeurekaBench |  HeurekaBench: A Benchmarking Framework for AI Co-scientist | ICLR '26 | - |  |
ResearchBench |  ResearchBench: Benchmarking LLMs in Scientific Discovery via Inspiration-Based Task Decomposition | ACL '26 | - | - |
HindSight |  HindSight: Evaluating LLM-Generated Research Ideas via Future Impact | arXiv '26 | - | - |
Rubric Rewards |  Training AI Co-Scientists Using Rubric Rewards | arXiv '25 | - | - |
DeepInnovator |  DeepInnovator: Triggering the Innovative Capabilities of LLMs | arXiv '26 | - |  |
FlowPIE |  FlowPIE: Test-Time Scientific Idea Evolution with Flow-Guided Literature Exploration | arXiv '26 | - | - |
SoundnessBench |  SoundnessBench: Can Your AI Scientist Really Tell Good Research Ideas from Bad Ones? | arXiv '26 | - | - |
LLM-Judge Novelty |  On the Limits of LLM-as-Judge for Scientific Novelty Assessment | arXiv '26 | - | - |
LigBench |  LigBench: A Unified and Human-Aligned Benchmark for LLM-based Research Idea Generation | arXiv '26 | - | - |
Reconstruction |  Reconstruction: A Blind Benchmark for Recovering Research Ideas from Pre-Publication Bibliographies | arXiv '26 | - | - |
2. Literature Review & Paper Search
Literature Retrieval
In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
ITER |  ITER: Interaction-Aware Retrieval for Agentic Search | arXiv '26 | - | - |
Multi-Aspect Retrieval |  Can Retrievers Find the Same Paper from Different Aspects? A Multi-Aspect Full-Paper Scientific Retrieval Benchmark | arXiv '26 | - | - |
CiteME |  CiteME: Can Language Models Accurately Cite Scientific Claims? | arXiv '24 | - | - |
LitLLM |  LitLLM: A Toolkit for Literature Review with Large Language Models | arXiv '24 | - | - |
LitSearch |  LitSearch: A Retrieval Benchmark for Scientific Literature Search | arXiv '24 | - |  |
PaperQA2 |  Language Agents Achieve Superhuman Synthesis of Scientific Knowledge | arXiv '24 | - |  |
OpenResearcher |  OpenResearcher: Unleashing AI for Accelerated Scientific Research | EMNLP '24 | - | - |
PaSa |  PaSa: An LLM Agent for Comprehensive Academic Paper Search | arXiv '25 | - |  |
Self-Evolving Retrieval |  Towards Self-Evolving Agentic Literature Retrieval | arXiv '26 | - | - |
MasterSet |  MasterSet: A Large-Scale Benchmark for Must-Cite Citation Recommendation in the AI/ML Literature | arXiv '26 | - | - |
Search, Inspect, Fetch |  Search, Inspect, Fetch: Exploiting Structure-Aware Boolean Retrieval for Deep-Research Agents | arXiv '26 | - | - |
Rubric Reranker |  Training Documents Reranker with Search Rubrics for Deep Research Agent | arXiv '26 | - | - |
Personalized DR Refinement |  Personalized Deep Research Query Refinement with Graph-Scaffolded Evidence Grounding | arXiv '26 | - | - |
Survey & Related Work Generation
In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
DAS |  Deep Academic Survey: Stateful Agentic Closed-Loop Paradigm for Academic Survey Automation | arXiv '26 | - | - |
Tree-of-Concerns |  Tree-of-Concerns: Hierarchical Multi-Agent Debate for Unstated-Limitation Extraction in Scientific Critique | EMNLP '26 | - | - |
ChatPaper | ChatPaper: Use LLM to summarize papers | GitHub '23 | - |  |
PaperQA |  PaperQA: Retrieval-Augmented Generative Agent for Scientific Research | arXiv '23 | - | |
AutoSurvey |  AutoSurvey: Large Language Models Can Automatically Write Surveys | arXiv '24 | - |  |
GPT Researcher | GPT Researcher: Autonomous Agent for Comprehensive Online Research | GitHub '24 | - |  |
LLMs for Lit. Review |  LLMs for Lit. Review | arXiv '24 | - | - |
STORM |  Assisting in Writing Wikipedia-like Articles From Scratch with Large Language Models | arXiv '24 | - |  |
Agentic AutoSurvey |  Agentic AutoSurvey: Let LLMs Survey LLMs | arXiv '25 | - | - |
Citegeist |  Citegeist: Automated Generation of Related Work Analysis on the arXiv Corpus | arXiv '25 | - | - |
IterSurvey |  IterSurvey: Deep Literature Survey Automation with an Iterative Workflow | arXiv '25 | - |  |
LiRA |  LiRA: A Multi-Agent Framework for Reliable and Readable Literature Review Generation | arXiv '25 | - | - |
SurveyForge |  SurveyForge: On the Outline Heuristics, Memory-Driven Generation, and Multi-dimensional Evaluation for Automated Survey Writing | arXiv '25 | - |  |
SurveyG |  SurveyG: A Multi-Agent LLM Framework with Hierarchical Citation Graph for Automated Survey Generation | arXiv '25 | - | - |
SurveyX |  SurveyX: Academic Survey Automation via Large Language Models | arXiv '25 | - | - |
InteractiveSurvey |  InteractiveSurvey: An LLM-based Personalized and Interactive Survey Paper Generation System | arXiv '25 | - |  |
CiteLLM |  CiteLLM: An Agentic Platform for Trustworthy Scientific Reference Discovery | arXiv '26 | - | - |
DeepSurvey |  DeepSurvey: Enhancing Analytical Depth and Citation Reliability in Automated Survey Generation | arXiv '26 | - | - |
STRUCTSURVEY |  STRUCTSURVEY: Structured Agentic Retrieval for Automated Survey Paper Generation | arXiv '26 | - | - |
Deep Research Agents
In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
Crase |  Structurally-bounded Agentic Graph Exploration for Evidence-Grounded Scholarly DeepSearch | arXiv '26 | - | - |
DeepWeaver |  DeepWeaver: Bridging the Evidence Synthesis Gap in Open-Ended Question Answering | arXiv '26 | - | - |
AgentR |  AgentR A Stateful and Recovery-Aware Software Architecture for LLM-based Auditable Workflows | arXiv '26 | - | - |
ASReview | An Open Source Machine Learning Framework for Efficient and Transparent Systematic Reviews | Nature MI '21 | - |  |
CHIME |  CHIME: LLM-Assisted Hierarchical Organization of Scientific Studies for Literature Review Support | arXiv '24 | - | - |
DeepResearch-Agent | DeepResearchAgent: A Hierarchical Multi-Agent System for Deep Research | GitHub '25 | - |  |
DeerFlow | DeerFlow: A Deep Research Framework Orchestrating Sub-Agents, Memory, and Sandboxes | GitHub '25 | - |  |
OpenScholar | OpenScholar: Synthesizing Scientific Literature with Retrieval-Augmented LMs | Nature '26 | - | - |
AutoAgent |  AutoAgent | arXiv '25 | - | - |
Tongyi DeepResearch | Tongyi DeepResearch | GitHub '25 | - |  |
O-Researcher |  O-Researcher: An Open Ended Deep Research Model via Multi-Agent Distillation and Agentic RL | arXiv '26 | - | - |
OpenResearcher |  OpenResearcher: Unleashing AI for Accelerated Scientific Research | arXiv '26 | - |  |
AREX |  AREX: Towards a Recursively Self-Improving Agent for Deep Research | arXiv '26 | - | - |
Predictive Navigation |  Deep Research Pretraining via Predictive Navigation | arXiv '26 | - | - |
On-Device DR (4B) |  On-Device Deep Research at 4B: Exposure Bounds Faithfulness, Retrieval Bounds Coverage | arXiv '26 | - | - |
Carnot |  Carnot: Interpretable, Interactive, and Optimized Execution of Deep Research Queries | VLDB '26 | - | - |
Marginal Value Est. |  Not Worth Another Token: Marginal Value Estimation for Efficient Deep Research Agents | arXiv '26 | - | - |
Retrieval-Aware Control |  When Deep Research Agents Stagnate: Enhancing Reasoning with Retrieval-Aware Agent Control | arXiv '26 | - | - |
Analogical Deep Research |  Analogical Deep Research: Retrieving and Integrating Historical Analogies for Foresight Analysis | arXiv '26 | - | - |
Plato-Bio |  Plato-Bio: verification-first biological novelty screening with temporal rediscovery and structural benchmarks | arXiv '26 | - | - |
Albilich |  Albilich: Steerable Proof-State Orchestration for LLM-Based Mathematical Research with CAS Integration | arXiv '26 | - | - |
Retrieval and Synthesis Quality Assessment
In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
IBIS |  From Inertia to Objectivity: Improving Deep Research Agents with Noise Isolation | EMNLP '26 | - | - |
Agent to Blame |  Who is the Agent to Blame? Localizing Faithfulness and Citation Mistakes in Agentic Deep Research | EMNLP '26 | - | - |
DeepScholar-Bench |  DeepScholar-Bench: A Live Benchmark and Automated Evaluation for Generative Research Synthesis | arXiv '25 | - |  |
ReportBench |  ReportBench: Evaluating Deep Research Agents via Academic Survey Tasks | arXiv '25 | - |  |
IDRBench |  IDRBench: Interactive Deep Research Benchmark | arXiv '26 | - | - |
ScholarGym |  ScholarGym: Benchmarking Large Language Model Capabilities in the Information-Gathering Stage of Deep Research | arXiv '26 | - | - |
SciNetBench |  SciNetBench: A Relation-Aware Benchmark for Scientific Literature Retrieval Agents | arXiv '26 | - | - |
AutoResearchBench |  AutoResearchBench: Benchmarking AI Agents on Complex Scientific Literature Discovery | arXiv '26 | - | - |
PaperMind |  PaperMind: Benchmarking Agentic Reasoning and Critique over Scientific Papers in Multimodal LLMs | arXiv '26 | - | - |
DRNOISE |  DRNOISE: Benchmarking Deep Research Agents in Misleading Evidence Environments | arXiv '26 | - | - |
HiEviDR-Bench |  HiEviDR-Bench: A Benchmark for Hierarchical Evidence Aggregation in Deep Research | arXiv '26 | - | - |
SciExplore |  SciExplore: Evaluating Autonomous Agents from Scientific Navigation to Information Integration | arXiv '26 | - | - |
WANDR |  WANDR: A Benchmark for Wide and Deep Research | arXiv '26 | - | - |
QA-to-DR Bench |  From Simple QA to Deep Research: A Verifiable Benchmark Constructed through Iterative Task Evolution | arXiv '26 | - | - |
3. Coding & Experimentation
Code Generation
In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
SWE-bench |  SWE-bench: Can Language Models Resolve Real-World GitHub Issues? | ICLR '24 | - |  |
SWE-agent |  SWE-agent: Agent-Computer Interfaces Enable Automated Software Engineering | arXiv '24 | - |  |
OpenHands |  OpenHands: An Open Platform for AI Software Developers as Generalist Agents | ICLR '25 | - |  |
SWE-bench Pro |  SWE-Bench Pro: Can AI Agents Solve Long-Horizon Software Engineering Tasks? | arXiv '25 | - | - |
SWE-EVO |  SWE-EVO: Benchmarking Coding Agents in Long-Horizon Software Evolution Scenarios | arXiv '25 | - | - |
Paper-to-Code
In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
ReproAgent |  ReproAgent: Contract-Guided Paper-to-Code Reproduction | EMNLP '26 | - | - |
DeepRepro |  DeepRepro: State-Aware Subplanning for Paper-to-Code Reproduction in Evolving Repositories | CIKM '26 | - | - |
FunSearch | Mathematical Discoveries from Program Search with Large Language Models | Nature '24 | - |  |
SciCode |  SciCode: A Research Coding Benchmark Curated by Scientists | arXiv '24 | - |  |
PaperBench |  PaperBench: Evaluating AI's Ability to Replicate AI Research | arXiv '25 | - |  |
PaperCoder |  Paper2Code: Automating Code Generation from Scientific Papers in Machine Learning | arXiv '25 | - |  |
ResearchCodeBench |  ResearchCodeBench: Benchmarking LLMs on Implementing Novel ML Research Code | arXiv '25 | - | - |
SciReplicate-Bench |  SciReplicate-Bench: Benchmarking LLMs in Agent-driven Algorithmic Reproduction from Research Papers | arXiv '25 | - |  |
Experiment Execution & Orchestration
In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
Praxist |  Praxist: From Experimental Artifacts to Solution Lineages | arXiv '26 | - | - |
Skill-Based Baselines |  Can Coding Agents Build Robust Baselines? A Skill-Based Approach for Automating the Medical Imaging Model-Development Pipeline | MICCAI '26 | - | - |
BioPlanner |  BioPlanner: Automatic Evaluation of LLMs on Protocol Planning | arXiv '23 | - |  |
CRISPR-GPT |  CRISPR-GPT for Agentic Automation of Gene-Editing Experiments | arXiv '24 | - | - |
DS-Agent |  DS-Agent: Automated Data Science by Empowering Large Language Models with Case-Based Reasoning | arXiv '24 | - |  |
MLE-Bench |  MLE-Bench: Evaluating Machine Learning Agents on Machine Learning Engineering | arXiv '24 | - | - |
MLAgentBench |  MLAgentBench: Evaluating Language Agents on Machine Learning Experimentation | arXiv '24 | - |  |
MLR-Copilot |  MLR-Copilot: Autonomous Machine Learning Research based on Large Language Models Agents | arXiv '24 | - | - |
AIDE |  AIDE: AI-Driven Exploration in the Space of Code | arXiv '25 | - | - |
AlphaEvolve |  AlphaEvolve: A Coding Agent for Scientific and Algorithmic Discovery | arXiv '25 | - | - |
AutoReproduce |  AutoReproduce: Automatic AI Experiment Reproduction with Paper Lineage | arXiv '25 | - |  |
CURIE |  Curie: Toward Rigorous and Automated Scientific Experimentation with AI Agents | arXiv '25 | - |  |
MLGym |  MLGym: A New Framework and Benchmark for Advancing AI Research Agents | arXiv '25 | - | - |
MLR-Bench |  MLR-Bench: Evaluating AI Agents on Open-Ended Machine Learning Research | arXiv '25 | - | - |
Execution-Grounded |  Towards Execution-Grounded Automated AI Research | arXiv '26 | - | - |
Learn to Discover |  Learning to Discover at Test Time | arXiv '26 | - | - |
AutoNumerics |  AutoNumerics: An Autonomous, PDE-Agnostic Multi-Agent Pipeline for Scientific Computing | arXiv '26 | - |  |
SciNav |  SciNav: A General Agent Framework for Scientific Coding Tasks | arXiv '26 | - | - |
FrontierScience |  FrontierScience: Evaluating AI's Ability to Perform Expert-Level Scientific Tasks | arXiv '26 | - | - |
EvoDS |  EvoDS: Self-Evolving Autonomous Data Science Agent with Skill Learning and Context Management | arXiv '26 | - | - |
AutoTTS |  LLMs Improving LLMs: Agentic Discovery for Test-Time Scaling | arXiv '26 | - |  |
AutoScientists |  AutoScientists: Self-Organizing Agent Teams for Long-Running Scientific Experimentation | arXiv '26 | - | - |
EurekAgent |  EurekAgent: Agent Environment Engineering is All You Need For Autonomous Scientific Discovery | arXiv '26 | - | - |
Code Correctness and Reproducibility Assessment
In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
Experimental Fidelity |  Beyond Execution: Auditing Experimental Fidelity in LLM-Driven Scientific Research | arXiv '26 | - | - |
DiscoveryBench |  DiscoveryBench: Towards Data-Driven Discovery with Large Language Models | arXiv '24 | - |  |
DiscoveryWorld |  DiscoveryWorld: A Virtual Environment for Developing and Evaluating Automated Scientific Discovery Agents | arXiv '24 | - |  |
InfiAgent-DABench |  InfiAgent-DABench: Evaluating Agents on Data Analysis Tasks | arXiv '24 | - | - |
ScienceAgentBench |  ScienceAgentBench: Toward Rigorous Assessment of Language Agents for Data-Driven Scientific Discovery | arXiv '24 | - | - |
LAB-Bench |  Lab-Bench: Measuring Capabilities of Language Models for Biology Research | arXiv '24 | - |  |
KernelBench |  KernelBench: Can LLMs Write Efficient GPU Kernels? | arXiv '25 | - |  |
TritonBench |  TritonBench: Benchmarking Large Language Model Capabilities for Generating Triton Operators | arXiv '25 | - |  |
AstaBench |  AstaBench: Rigorous Benchmarking of AI Agents with a Scientific Research Suite | arXiv '25 | - |  |
ResearchClawBench |  Probing Scientific General Intelligence of LLMs with Scientist-Aligned Workflows | arXiv '25 | - |  |
EXP-Bench | EXP-Bench: Can AI Conduct AI Research Experiments? | ICLR '26 | - | |
PostTrainBench |  PostTrainBench: Can LLM Agents Automate LLM Post-Training? | arXiv '26 | - |  |
MLReplicate |  MLReplicate: Benchmarking Autonomous Research Systems for Machine Learning Reproducibility | arXiv '26 | - | - |
BeyondSWE |  BeyondSWE: Can Current Code Agent Survive Beyond Single-Repo Bug Fixing? | arXiv '26 | |  |
NatureBench |  NatureBench: Can Coding Agents Match the Published SOTA of Nature-Family Papers? | arXiv '26 | - | - |
SciCoQA |  SciCoQA: Quality Assurance for Scientific Paper--Code Alignment | ACL '26 | |  |
4. Tables & Figures
Scientific Figure Generation
In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
ChartGPT |  ChartGPT: Leveraging LLMs to Generate Charts from Abstract Natural Language | arXiv '23 | - | - |
MatPlotAgent |  MatPlotAgent: Method and Evaluation for LLM-Based Agentic Scientific Data Visualization | arXiv '24 | - | - |
CoDA |  CoDA: Agentic Systems for Collaborative Data Visualization | arXiv '25 | - | - |
PlotGen |  PlotGen: Multi-Agent LLM-based Scientific Data Visualization via Multimodal Feedback | arXiv '25 | - | - |
VIS-Shepherd |  VIS-Shepherd: Constructing Critic for LLM-based Data Visualization Generation | arXiv '25 | - | - |
DiagramAgent |  From Words to Structured Visuals: A Benchmark and Framework for Text-to-Diagram Generation and Editing | CVPR '25 | - | - |
StarVector |  StarVector: Generating Scalable Vector Graphics Code from Images and Text | CVPR '25 | - | - |
VisCoder |  VisCoder: Fine-Tuning LLMs for Executable Python Visualization Code Generation | EMNLP '25 | - | - |
AI-Generated Figures |  AI-Generated Figures | arXiv '26 | - | - |
AutoFigure-Edit |  AutoFigure-Edit: Generating Editable Scientific Illustration | arXiv '26 | - |  |
AutoFigure |  AutoFigure-Edit: Generating Editable Scientific Illustration | ICLR '26 | - |  |
PaperBanana |  PaperBanana: Automating Academic Illustration for AI Scientists | arXiv '26 | - | - |
SAIL |  Setting SAIL: Leveraging Scientist-AI-Loops for Rigorous Visualization Tools | arXiv '26 | - | - |
Crafter |  Crafter: A Multi-Agent Harness for Editable Scientific Figure Generation from Diverse Inputs | arXiv '26 | - | - |
DiagramRAG |  DiagramRAG: A Lightweight Framework to Retrieve Scientific Diagram for Figure Generation | arXiv '26 | - | - |
GeoSVG-RL |  GeoSVG-RL: Geometry-Aware Reinforcement Learning for Layout-Constrained Text-to-SVG Diagram Generation | arXiv '26 | - | - |
Can AI Draw Sci. |  Can AI Draw Science? A Benchmark for Evaluating Scientific Figure Generation by Text-to-Image and Multimodal Models | arXiv '26 | - | - |
SciDiagramEdit |  SciDiagramEdit: Learning to Edit Scientific Diagrams from Paper Revisions | arXiv '26 | - | - |
GenGA |  GenGA: Editable and Data-Grounded Graphical Abstract Generation for Academic Papers | arXiv '26 | - | - |
Table Understanding & Generation
In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
ArxivDIGESTables |  ArxivDIGESTables: Synthesizing Scientific Literature into Tables using Language Models | EMNLP '24 | - | - |
Chain-of-Table |  Chain-of-Table: Evolving Tables in Reasoning Chain for Table Understanding | ICLR '24 | - | - |
ShowTable |  ShowTable: Unlocking Creative Table Visualization with Collaborative Reflection and Refinement | CVPR '26 | - | - |
Table2LaTeX-RL |  Table2LaTeX-RL: Converting Table Images to High-Fidelity LaTeX Code Using Reinforced Multimodal Language Models | arXiv '25 | - | - |
CSPO |  CSPO: Alleviating Reward Ambiguity for Structured Table-to-LaTeX Generation | arXiv '26 | - | - |
Mathematical Formulas & TikZ
In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
AutomaTikZ |  AutomaTikZ: Text-Guided Synthesis of Scientific Vector Graphics with TikZ | ICLR '24 | - | - |
DeTikZify |  DeTikZify: Synthesizing Graphics Programs for Scientific Figures and Sketches with TikZ | NeurIPS '24 | - | - |
TikZilla |  TikZilla: Scaling Text-to-TikZ with High-Quality Data and Reinforcement Learning | arXiv '26 | - | - |
Edit2TikZ |  Edit2TikZ: A Comprehensive and Challenging Benchmark for Scientific Figure Editing with TikZ | arXiv '26 | - | - |
Visual Fidelity and Scientific Accuracy Assessment
In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
StructEval | StructEval: Benchmarking LLMs' Capabilities to Generate Structural Outputs | TMLR '25 | |  |
PlotCraft |  PlotCraft: Pushing the Limits of LLMs for Complex and Interactive Data Visualization | arXiv '25 | - | - |
TeXpert | TeXpert: Multi-Level Benchmark for LaTeX Code Generation | SDP '25 | - | - |
AbGen |  AbGen: Evaluating Large Language Models in Ablation Study Design and Evaluation for Scientific Research | ACL '25 | - | - |
SciFig |  SciFig: Towards Automating Scientific Figure Generation | arXiv '26 | - | - |
SciFlow-Bench |  SciFlow-Bench: Evaluating Structure-Aware Scientific Diagram Generation via Inverse Parsing | arXiv '26 | - | - |
FigureBench | AutoFigure: Generating and Refining Publication-Ready Scientific Illustrations | ICLR '26 | - | |
SciFigQual-Bench |  SciFigQual-Bench: A Benchmark for Scientific Figure Quality Assessment with Full-Manuscript Context | arXiv '26 | - | - |
SciFigAlign |  SciFigAlign: Scoring Scientific Figures by Fine-tuned Alignment of Visuals with Manuscript Evidence | arXiv '26 | - | - |
SciFigPlag-Bench |  SciFigPlag-Bench: A Benchmark for Provenance-Aware Scientific Figure Plagiarism Detection | arXiv '26 | - | - |
VLM Blind/Misled |  How Do VLMs Behave When Blind or Misled? Behavioral Evaluation of VLMs on Scientific Figures | arXiv '26 | - | - |
5. Paper Writing
Semi-Automated Writing Assistance
In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
CoAuthor |  CoAuthor: Human-AI Collaborative Writing with Language Models | arXiv '22 | - | - |
AI Writing Study |  AI Writing Study | AIED '25 | - | - |
DraftMarks |  DraftMarks: Enhancing Transparency in Human-AI Co-Writing Through Interactive Skeuomorphic Process Traces | arXiv '25 | - | - |
PaperDebugger |  PaperDebugger: A Plugin-Based Multi-Agent System for In-Editor Academic Writing, Review, and Editing | arXiv '25 | - |  |
ScholarCopilot |  ScholarCopilot: Training LLMs for Academic Writing with Integrated Citation | arXiv '25 | - | - |
XtraGPT |  XtraGPT: Context-Aware and Controllable Academic Paper Revision | arXiv '25 | - | - |
LimAgents |  Multi-Agent LLMs for Generating Research Limitations | arXiv '26 | - | - |
PaperMentor |  PaperMentor: A Human-Centered Multi-Agent Writing Tutor for AI Research Papers on Overleaf | arXiv '26 | - | - |
AutoSupervision |  AutoSupervision: Closing the Feedback Loop in Scientific Workflows with Grounded Revision Verification | arXiv '26 | - | - |
ReasFlow |  ReasFlow: Assisting Reasoning-Centric Scientific Discovery in Applied Mathematics via a Knowledge-Based Multi-Agent System | arXiv '26 | - | - |
Fully Automated Paper Generation
In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
CycleResearcher |  CycleResearcher: Improving Automated Research via Automated Review | ICLR '25 | - | - |
Agent Laboratory | Agent Laboratory: Using LLM Agents as Research Assistants | EMNLP '25 | - | - |
FutureGen |  FutureGen: A RAG-based Approach to Generate the Future Work of Scientific Article | arXiv '25 | - | - |
AI Scientist |  The AI Scientist: Towards Fully Automated Open-Ended Scientific Discovery | Nature '26 | - |  |
APRES |  APRES: An Agentic Paper Revision and Evaluation System | arXiv '26 | - | - |
LECTOR |  LECTOR: Joint Optimization of Scientific Reasoning Graphs and Introduction Generation | arXiv '26 | - | - |
RWGBench |  RWGBench: Evaluating Scholarly Positioning in Related Work Generation | arXiv '26 | - | - |
Societal Analysis
In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
AI Writing Adoption | AI Writing Adoption | Nature '26 | - | - |
Nature AI Survey | More than Half of Researchers Now Use AI for Peer Review | Nature '26 | - | - |
Denial of Science |  Distributed Denial of Science: How Indirect Data Poisoning of AI Systems Can Industrialize Scientific Fraud | arXiv '26 | - | - |
AI Slop OSS |  "AI Slop is DDoSing Open Source": Understanding the Impact of AI-Generated Contributions on Open Source Sustainability | arXiv '26 | - | - |
Writing Quality and AI Detection Assessment
In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
Mapping LLM Use |  Mapping the Increasing Use of LLMs in Scientific Papers | arXiv '24 | - | - |
CycleReviewer | CycleResearcher: Improving Automated Research via Automated Review | ICLR '25 | - | - |
Stanford Agentic | Stanford Agentic | Web '25 | - | - |
SciIG |  Let's Use ChatGPT To Write Our Paper! Benchmarking LLMs To Write the Introduction of a Research Paper | arXiv '25 | - | - |
Watermarking |  Detecting LLM-Generated Peer Reviews | arXiv '25 | - | - |
PaperWritingBench |  PaperOrchestra: A Multi-Agent Framework for Automated AI Research Paper Writing | arXiv '26 | - | - |
CiteTracer |  Source or It Didn't Happen: A Multi-Agent Framework for Citation Hallucination Detection | arXiv '26 | - | - |
Process Eval |  Process-Oriented Evaluation of AI-Assisted Scientific Writing | arXiv '26 | - | - |
6. Peer Review
Automated Review Generation
In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
ChatReviewer | ChatReviewer: ChatGPT-based Paper Reviewing and Response Generation | GitHub '23 | - |  |
AI-Peer-Review | AI-Peer-Review | GitHub '24 | - |  |
MARG |  MARG: Multi-Agent Review Generation for Scientific Papers | arXiv '24 | - | - |
Reviewer2 |  Reviewer2: Optimizing Review Generation Through Prompt Generation | arXiv '24 | - | - |
ReviewRL | ReviewRL: Towards Automated Scientific Review with RL | EMNLP '25 | - | - |
DeepReviewer |  DeepReview: Improving LLM-based Paper Review with Human-like Deep Thinking Process | arXiv '25 | - | - |
OpenReviewer | OpenReviewer: A Specialized Large Language Model for Generating Critical Scientific Paper Reviews | NAACL '25 | - | - |
REMOR |  REMOR: Automated Peer Review Generation with LLM Reasoning and Multi-Objective Reinforcement Learning | arXiv '25 | - | - |
ScholarPeer |  ScholarPeer: A Context-Aware Multi-Agent Framework for Automated Peer Review | arXiv '26 | - | - |
ProReviewer |  From Passive Generation to Investigation: A Proactive Scientific Peer Review Agent | arXiv '26 | - | - |
PeerCheck |  PeerCheck: Enhancing LLM-Generated Academic Reviews Towards Human-Level Quality | arXiv '26 | - | - |
Local Pre-Screening |  Local AI pre-screening for human triple-blind peer review in health sciences | arXiv '26 | - | - |
ReVoicer |  ReVoicer: Conversational Voice Annotation for Human-Centered, LLM-Assisted Peer Review | arXiv '26 | - | - |
Meta-Review & Reviewer Matching
In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
Metag |  Metag: A dataset to build agentic meta-reviewing capabilities | arXiv '26 | - | - |
AgentReview | AgentReview: Exploring Peer Review Dynamics with LLM Agents | EMNLP '24 | - | - |
Meta-Review LLMs | Meta-Review LLMs | NAACL '25 | - | - |
RATE |  RATE: Reviewer Profiling and Annotation-free Training for Expertise Ranking in Peer Review Systems | arXiv '26 | - | - |
MERIT |  MERIT: Matching Expertise via Rubric-Informed Training for Reviewer Assignment | arXiv '26 | - | - |
Adversarial Attacks & Bias Analysis
In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
Raina etal |  Raina etal | EMNLP '24 | - | - |
AI Review Lottery |  The AI Review Lottery: Widespread AI-Assisted Peer Reviews Boost Paper Scores and Acceptance Rates | arXiv '24 | - | - |
Ye etal |  Ye etal | arXiv '24 | - | - |
Breaking the Reviewer |  Breaking the Reviewer: Assessing the Vulnerability of Large Language Models in Automated Peer Review Under Textual Adversarial Attacks | arXiv '25 | - | - |
LLM Reviewer Bias |  LLM Reviewer Bias | arXiv '25 | - | - |
Prompt Injection |  Prompt Injection Attacks on LLM Generated Reviews of Scientific Publications | arXiv '25 | - | - |
Sahoo etal |  Sahoo etal | arXiv '25 | - | - |
Zhou etal |  Zhou etal | arXiv '25 | - | - |
Presentation Gaming |  No Hidden Prompts Needed! You Can Game AI Peer Review with Presentation-Only Revisions | arXiv '26 | - | - |
LLMs Favor LLMs? |  Do LLMs Favor LLMs? Quantifying Interaction Effects in Peer Review | arXiv '26 | - | - |
Gaming AI Reviews |  Gaming AI-Assisted Peer Reviews Poses New Risks to the Scientific Community | arXiv '26 | - | - |
Phantom Refs |  Phantom References: Hallucinated Citations That Survive Peer Review at Top-Tier Conferences | arXiv '26 | - | - |
Rhetorical Reward-Hacking |  How Can Rhetoric Reward-Hack AI Reviewers? Dissecting Rhetorical Sensitivity in AI-Based Peer Review | arXiv '26 | - | - |
Detection & Policy
In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
AI Detection |  Is Your Paper Being Reviewed by an LLM? Benchmarking AI Text Detection in Peer Review | arXiv '25 | - | - |
AI Use Rejects | Major Conference Catches Illicit AI Use — and Rejects Hundreds of Papers | Nature '26 | - | - |
Nature AI Survey | More than Half of Researchers Now Use AI for Peer Review | Nature '26 | - | - |
Policy Enforcement |  Policy Enforcement | arXiv '26 | - | - |
Reviewer Feedback | What Happens When Reviewers Receive AI Feedback in Their Reviews? | CHI '26 | - | - |
AAAI-26 Pilot |  AI-Assisted Peer Review at Scale: The AAAI-26 AI Review Pilot | arXiv '26 | - | - |
Reviewer AI Policies |  AI-Assisted Peer Review Across Research Communities: From Reviewer AI Policies to LLM Review Quality | arXiv '26 | - | - |
Review Consistency and Bias Assessment
In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
VERA-RL |  Not Just Reason, Not Just Scan: Reinforcement Learning for Proactive Scientific Error Verification over Academic Paper | EMNLP '26 | - | - |
Review Survey | More than Half of Researchers Now Use AI for Peer Review — often Against Guidance | IF '25 | - | - |
Stanford Agentic | Stanford Agentic | Web '25 | - | - |
ClaimCheck | ClaimCheck: How Grounded are LLM Critiques of Scientific Papers? | EMNLP '25 | - | - |
REFUTE | REFUTE: A Benchmark for Scientific Critique and Epistemic Calibration in Language Models | HF '26 | Website | - |
ReViewGraph |  Automatic Paper Reviewing with Heterogeneous Graph Reasoning over LLM-Simulated Reviewer-Author Debates | AAAI '26 | - | - |
ReviewAgents |  ReviewAgents: Bridging the Gap Between Human and AI-Generated Paper Reviews | arXiv '25 | - | - |
ICLR 2025 Study | ICLR 2025 Study | NMI '26 | - | - |
AI Reviewer Limits |  On the limits and opportunities of AI reviewers: Reviewing the reviews of Nature-family papers with 45 expert scientists | arXiv '26 | - | - |
PRISM |  PRISM: A Multi-Dimensional Benchmark for Evaluating LLM Peer Reviewers | arXiv '26 | - | - |
LLM-Human Alignment |  How Closely Do LLM Reviews Align with Human Peer Review? | arXiv '26 | - | - |
Epistemic Reliability |  Articulate Intuition or Genuine Analysis? Benchmarking Epistemic Reliability in LLM-as-a-Judge Peer Reviews | arXiv '26 | - | - |
SurveyReview |  SurveyReview: A Reviewer-Aligned Benchmark for Survey Evaluators | arXiv '26 | - | - |
7. Rebuttal
Reviewer Comment Analysis
In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
ReviewMT |  Peer Review as A Multi-Turn and Long-Context Dialogue with Role-Based Interactions | arXiv '24 | - | - |
ICLR Rebuttal Study |  ICLR Rebuttal Study | arXiv '25 | - | - |
RbtAct |  RbtAct: Rebuttal as Supervision for Actionable Review Feedback Generation | arXiv '26 | - | - |
GoodPoint |  GoodPoint: Learning Constructive Scientific Paper Feedback from Author Responses | arXiv '26 | - | - |
Automated Rebuttal Generation
In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
ReviewerToo |  ReviewerToo: Should AI Join The Program Committee? A Look At The Future of Peer Review | arXiv '25 | - | - |
RebuttalAgent |  RebuttalAgent: Strategic Persuasion in Academic Rebuttal via Theory of Mind | ICLR '26 | - |  |
Author-in-the-Loop |  Author-in-the-Loop Response Generation and Evaluation: Integrating Author Expertise and Intent in Responses to Peer Review | ACL '26 | - | - |
DRPG |  DRPG: An Agentic Framework for Academic Rebuttal | arXiv '26 | - |  |
Paper2Rebuttal |  Paper2Rebuttal: A Multi-Agent Framework for Transparent Author Response Assistance | arXiv '26 | - | - |
Defend |  Defend: Automated Rebuttals for Peer Review with Minimal Author Guidance | arXiv '26 | - | - |
Rebuttal Effectiveness Assessment
In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
Re$^2$ |  Re$^2$ | arXiv '25 | - | - |
Commitment Checklist |  Commitment Checklist: Auditing Author Commitments in Peer Review | arXiv '26 | - | - |
Re$^3$Align | Re$^3$Align | ACL '26 | - | - |
Rebuttals Move |  Rebuttals Move Peer-Review Scores, but Initial-Review Structure Bounds the Movement | arXiv '26 | - | - |
Trust AI Reviews |  To Trust or Not to Trust: Authors' Response to AI-based Reviews | arXiv '26 | - | - |
8. Dissemination (Paper2X)
Paper2Poster
In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
P2P | P2P: Automated Paper-to-Poster Generation and Fine-Grained Benchmark | ICLR '26 | - | - |
Paper2Poster | Paper2Poster: Towards Multimodal Poster Automation from Scientific Papers | NeurIPS '25 | - |  |
PosterForest |  PosterForest: Hierarchical Multi-Agent Collaboration for Scientific Poster Generation | arXiv '25 | - | - |
PosterGen |  PosterGen: Aesthetic-Aware Paper-to-Poster Generation via Multi-Agent LLMs | arXiv '25 | - | - |
APEX |  APEX: Academic Poster Editing Agentic Expert | arXiv '26 | - |  |
PosterOmni |  PosterOmni: Generalized Artistic Poster Creation via Task Distillation and Unified Reward Feedback | arXiv '26 | - | - |
Any2Poster |  Any2Poster: Any-Source Poster Generation Across Modalities and Domains | arXiv '26 | - | - |
PosterMELD |  PosterMELD: Multi-Agent Paper-to-Poster Generation for Controllable Design Diversity with Editable Print-Ready Outputs | arXiv '26 | - | - |
Paper2Slides
In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
DOC2PPT | DOC2PPT: Automatic Presentation Slides Generation from Scientific Documents | AAAI '22 | - | - |
PPTAgent |  PPTAgent: Generating and Evaluating Presentations Beyond Text-to-Slides | EMNLP '25 | - |  |
AutoPresent |  AutoPresent: Designing Structured Visuals from Scratch | CVPR '25 | - | - |
Paper2Slides | Paper2Slides: From Paper to Presentation in One Click | GitHub '25 | - |  |
Auto-Slides |  Auto-Slides: An Interactive Multi-Agent System for Creating and Customizing Research Presentations | arXiv '25 | - | - |
PASS |  PASS: Presentation Automation for Slide Generation and Speech | arXiv '25 | - | - |
SlideGen |  SlideGen: Collaborative Multimodal Agents for Scientific Slide Generation | arXiv '25 | - | - |
Talk to Your Slides |  Talk to Your Slides: Efficient Slide Editing Agent | arXiv '25 | - | - |
SlideTailor |  SlideTailor: Personalized Presentation Slide Generation for Scientific Papers | AAAI '26 | - |  |
DeepPresenter |  DeepPresenter: Environment-Grounded Reflection for Agentic Presentation Generation | arXiv '26 | - | |
Office Raccoon | Office Raccoon | Web '26 | - | - |
X+Slides |  X+Slides: Benchmarking Audience-Conditioned Slide Generation | arXiv '26 | - | - |
SeaSlides |  SeaSlides: Semantic Abstraction Layer for Agentic Slide Generation | arXiv '26 | - | - |
Paper2Video
In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
Preacher | Preacher: Paper-to-Video Agentic System | ICCV '25 | - |  |
Paper2Video |  Paper2Video: Automatic Video Generation from Scientific Papers | arXiv '25 | - |  |
PresentAgent | PresentAgent: Multimodal Agent for Presentation Video Generation | EMNLP '25 | - |  |
PresentAgent-2 |  PresentAgent-2: Towards Generalist Multimodal Presentation Agents | arXiv '26 | - | - |
Paper2Video Talks |  A Good Talk Does not Look Like a Summary, It Teaches You! Measuring Takeaways from Paper-to-Video Talks | arXiv '26 | - | - |
Paper2Web & Social Media
In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
Paper2Web |  Paper2Web: Let's Make Your Paper Alive! | arXiv '25 | - |  |
ResearchStudio-Reel |  ResearchStudio-Reel: Automate the Last Mile of Research from Paper to Poster, Video, and Blog | arXiv '26 | - | - |
I-WebGenBench |  I-WebGenBench: Evaluating Interactivity in LLM-Generated Scientific Web Applications | arXiv '26 | - | - |
SciForge |  SciForge: An AI-Native, Multimodal Workbench for Scientific Discovery | arXiv '26 | - | - |
Fidelity and Adoption Assessment
In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
PPTEval | PPTAgent: Generating and Evaluating Presentations Beyond Text-to-Slides | EMNLP '25 | - | |
PresentQuiz | Paper2Video: Automatic Video Generation from Scientific Papers | arXiv '25 | - | |
PresentEval | PresentAgent: Multimodal Agent for Presentation Video Generation | EMNLP '25 | - | |
Sci. Comm. Correspondence |  Unifying Scientific Communication: Fine-Grained Correspondence Across Scientific Media | arXiv '26 | - | - |
9. End-to-End Systems
Fully Automated Research Systems
In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
Gemini Co-Scientist |  Accelerating Scientific Research with Gemini in the Real-World | arXiv 2026 | - | - |
AutoResearch |  AutoResearch: Insight In, Hallucination Out | arXiv 2026 | - | - |
Eureka |  Eureka: Task-Conditioned Meta-Agent Orchestration for Scientific Discovery | arXiv 2026 | - | - |
AutoResearch Diagnosis |  How Do Agents Fail on AutoResearch: End-to-End Diagnostic Evaluation on 100 Real-World Frontier Research Tasks | arXiv 2026 | - | - |
ResearchTown |  ResearchTown: Simulator of Human Research Community | ICML 2025 | |  |
Agent Laboratory |  Agent Laboratory: Using LLM Agents as Research Assistants | arXiv 2025 | - | - |
AgentRxiv |  AgentRxiv: Towards Collaborative Autonomous Research | arXiv 2025 | - | - |
ARIS | - | GitHub 2025 | - |  |
freephdlabor |  Build Your Personalized Research Group: A Multiagent Framework for Continual and Interactive Science Automation | arXiv 2025 | - | - |
SciMaster |  SciMaster: Towards General-Purpose Scientific AI Agents | arXiv 2025 | - |  |
| - |  Towards End-to-End Automation of AI Research | Nature 2026 | | |
Idea2Story |  Idea2Story: An Automated Pipeline for Transforming Research Concepts into Complete Scientific Narratives | arXiv 2026 | - | - |
UniScientist | - | Web 2026 | - | - |
ASI-Evolve | - | GitHub 2026 | - |  |
FARS | - | Web 2026 | - | - |
AutoResearchClaw | - | GitHub 2026 | - |  |
CORAL |  CORAL: Towards Autonomous Multi-Agent Evolution for Open-Ended Discovery | arXiv 2026 | - |  |
AutoSOTA |  AutoSOTA: An End-to-End Automated Research System for State-of-the-Art AI Model Discovery | arXiv 2026 | - |  |
AiScientist-LH |  Toward Autonomous Long-Horizon Engineering for ML Research | arXiv 2026 | - |  |
OpenResearcher (2026) | OpenResearcher: A Fully Open Pipeline for Long-Horizon Deep Research Trajectory Synthesis | arXiv 2026 | - | |
Aletheia |  Towards Autonomous Mathematics Research | arXiv 2026 | - |  |
AutoSci |  AutoSci: A Memory-Centric Agentic System for the Full Scientific Research Lifecycle | arXiv 2026 | - | - |
ScientistOne |  ScientistOne: Towards Human-Level Autonomous Research via Chain-of-Evidence | arXiv 2026 | - | - |
Arbor |  Toward Generalist Autonomous Research via Hypothesis-Tree Refinement | arXiv 2026 | - | - |
Agon |  Agon: An Autonomous Large-Scale Omnidisciplinary Research System Built on Prompt Economy | arXiv 2026 | - |  |
ResearchClawBench |  ResearchClawBench: A Benchmark for End-to-End Autonomous Scientific Research | arXiv 2026 | - | - |
Act as Real Researcher |  Act As a Real Researcher: A Suite of Benchmarks Evaluating Frontier LLMs and Agentic Harnesses in Research Lifecycle | arXiv 2026 | - | - |
ResearchArena |  How Far Are We From True Auto-Research? | arXiv 2026 | - | - |
NVAITC AI Sci. |  NVAITC AI Scientist: A Governed End-to-End Research System -- A Hypertension GWAS Case Study | arXiv '26 | - | - |
DeepResearch Agent Sys. |  DeepResearch Agent System | arXiv '26 | - | - |
ScienceFlow |  ScienceFlow: A long-horizon agent for ML research, scientific discovery and beyond | arXiv '26 | - | - |
Spark-to-Paper |  Spark-to-Paper: End-to-End Research Paper Generation as a Composable Skill | arXiv '26 | - | - |
OmniScientist |  OmniScientist: An Omni-Modal Omni-Discipline AI Scientist | arXiv '26 | - | - |
Domain-Specific Systems
In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
AutoSR |  AutoSR: Automatic Symbolic Regression by Searching Research States | arXiv 2026 | - | - |
The AI Engineer |  Closed-loop AI achieves certifiable engineering design | arXiv 2026 | - | - |
AlphaFold 3 |  Accurate Structure Prediction of Biomolecular Interactions with AlphaFold 3 | Nature 2024 | | - |
Medical AI Scientist |  Towards a Medical AI Scientist | arXiv 2026 | - | - |
Cognitive Scientist |  Closing the Loop to Discover Psychological Theories with an Automated Cognitive Scientist | arXiv '26 | - | - |
Molecular Closed-Loop |  Closed-loop Auto Research for Molecular Property Prediction: Discovering and Certifying Generalizable Improvements | arXiv '26 | - | - |
Auto Research (Materials) |  Auto Research for Materials: Auditable AI-Scientist Workflows with Held-Out Transfer | arXiv '26 | - | - |
OmniQEC |  OmniQEC: discovering practical quantum error-correcting codes by an AI scientist | arXiv '26 | - | - |
Andy |  Andy: A Mathematical Agent for Rigorous Proof and Autonomous Research | arXiv '26 | - | - |
BaT |  BaT: Towards Self-Evolving Medical Research Agent with Stage Rubrics | arXiv '26 | - | - |
Agentic Sci. Community |  An Agentic AI Scientific Community for Automated Neural Operator Discovery | arXiv '26 | - | - |
WARA |  WARA: A Closed-Loop Multi-Agent Framework for Wireless Optimization Autoresearch | ICCC '26 | - | - |
Evolutionary & Self-Improving Systems
In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
ShinkaEvolve |  ShinkaEvolve: Towards Open-Ended and Sample-Efficient Program Evolution | arXiv 2025 | - |  |
Darwin Godel Machine |  Darwin Godel Machine: Open-Ended Evolution of Self-Improving Agents | arXiv 2025 | - |  |
EvoMaster |  EvoMaster: A Foundational Evolving Agent Framework for Agentic Science at Scale | arXiv 2026 | - | - |
Self-Driving Lab |  Compressing the Validation Bottleneck: An Agentic Self-Driving Lab for Scientific Discovery | arXiv '26 | - | - |
Meta-Reflection |  Autonomous Scientific Discovery via Iterative Meta-Reflection | arXiv '26 | - | - |
Project2Task |  Project2Task: Graph-Guided Project-Level Planning for Autonomous Research | arXiv '26 | - | - |
Adaptive Inquiry |  Beyond Solution-Centric Search: Adaptive Inquiry and Knowledge Revision for Autonomous ML Engineering | arXiv '26 | - | - |
CausalForge |  CausalForge: A Formally Grounded, Self-Improving Agentic Framework for Automated Research in Causal Inference | arXiv '26 | - | - |
World-Model Scaling |  Scaling Automatic Research Agents via World Models | arXiv '26 | - | - |
Research Preference Models |  AI Research Preference Models | arXiv '26 | - | - |
Research Platforms & Infrastructure
In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
Symposium |  Symposium: Trust via Auditable Records for Communities of AI Scientist Agents | arXiv 2026 | - | - |
Towards an AI co-scientist |  Towards an AI co-scientist | arXiv 2025 | - | - |
PiFlow |  PiFlow: Principle-aware Scientific Discovery with Multi-Agent Collaboration | arXiv 2025 | - | - |
LabClaw | - | Web 2026 | - | - |
| - | OpenAI Is Throwing Everything into Building a Fully Automated Researcher | MIT TR 2026 | | - |
XScientist |  XScientist: A Git-Like Research Protocol for Long-Running Autonomous Scientific Discovery | arXiv '26 | - | - |
Auditable Records |  From Trajectories to Evidence: Auditable Experimental Records for Industrial Research Agents | arXiv '26 | - | - |
PEARL |  PEARL: Auditable Repair for Scientific Reasoning Graph Extraction | arXiv '26 | - | - |
IdeaTrail |  IdeaTrail: Full-Process Agent Trajectories for Scientific Ideation | arXiv '26 | - | - |
EviGraph |  EviGraph: Evidence-Guided Autonomous Research Agents | arXiv '26 | - | - |
Discovery Environments |  Scaling Scientific Discovery Environments for Turn-Level Agentic RL | arXiv '26 | - | - |
Quantum Theorem Bench |  Benchmarking Agents for Proving Theorems in Quantum Algorithms and Quantum Information | arXiv '26 | - | - |
SciDiscovery Readiness |  Are LLMs Ready for Scientific Discovery? A Capability-Oriented Benchmark for AI Scientists | arXiv '26 | - | - |
ARAC |  ARAC: Benchmarking Auto-Research's Alignment and Completeness on End-to-End Researchs | arXiv '26 | - | - |
Beyond Final Scores |  Beyond Final Scores: A Systematic Evaluation of Agents for Long-Horizon AI Research and Development | arXiv '26 | - | - |
Replication Training |  Training AI Scientists to Replicate Research | arXiv '26 | - | - |
Rubric Meta-Eval |  Can LLMs Write Reliable Rubrics? A Meta-Evaluation for Experiment Reproduction | arXiv '26 | - | - |
Fast-Moving Domains |  Adversarial Fast-Moving Real-World Domains as Test Beds for Benchmarking AI Scientist Capabilities | arXiv '26 | - | - |
AutoWorldModel-Bench |  AutoWorldModel-Bench: A State-Centric Benchmark for Automated World-Model Research | arXiv '26 | - | - |
Scientific Memory |  Beyond Memory Leaderboards: Evaluating Scientific Memory as Budgeted Context Restoration | arXiv '26 | - | - |
SciHazard |  SciHazard: A Benchmark for Measuring Scientific Safety Risks with Decomposed Harm Scoring | arXiv '26 | - | - |
Science Edge Eval. |  Science Edge Evaluation: SEE the Missing Step Toward Real Scientific Discovery | arXiv '26 | - | - |
10. Societal & Critical Perspectives
:timer_clock: In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
| - |  Science Done on a Machine by a Machine: AI Agents in Computational Chemistry | arXiv 2026 | - | - |
| - |  Bayesian Optimization for Self-Driving Materials Laboratories: From Algorithms to Physics-Informed Workflows | arXiv 2026 | - | - |
| - |  LLM assisted writing deserves empirical evaluation | arXiv 2026 | - | - |
| - |  A Metric with Positive Sectional Curvature on $S^2\times S^3$ | arXiv 2026 | - | - |
| - |  Weak-Type Bounds for Convolution on the Boolean Hypercube | arXiv 2026 | - | - |
| - |  Quo Vadis? Scientific Discovery in the Age of Artificial Intelligence | Theory of Science | - | - |
| - |  Are LLMs becoming similarly creative? Evidence from three years of models | arXiv 2026 | - | - |
| - | Navigating the Jagged Technological Frontier | Org. Sci. 2025 | | - |
| - | Reassessing Academic Integrity in the Age of AI | SSH Open 2025 | | - |
The AI Deskilling Paradox | The AI Deskilling Paradox | CACM 2025 | | - |
Hidden Pitfalls of AI Scientist Systems |  The More You Automate, the Less You See: Hidden Pitfalls of AI Scientist Systems | arXiv 2025 | - | - |
Rethinking Science in the Age of AI |  Rethinking Science in the Age of Artificial Intelligence | arXiv 2025 | - | - |
| - | Measuring AI Ability to Complete Long Tasks | METR 2025 | | - |
| - |  Towards a Science of Scaling Agent Systems | arXiv 2025 | - | - |
| - | Artificial Intelligence Tools Expand Scientists' Impact but Contract Science's Focus | Nature 2026 | | - |
| - | [](https://www.cell.com/patterns/fulltext/S2666-3899(25) AI for Scientific Discovery is a Social Problem | Patterns 2026 | [](https://www.cell.com/patterns/fulltext/S2666-3899(25) | - |
Research Integrity in the Age of AI |  Research Integrity and Academic Authority in the Age of Artificial Intelligence: From Discovery to Curation? | arXiv 2026 | - | - |
SciSciGPT | SciSciGPT: Advancing Human-AI Collaboration in the Science of Science | Nature CS 2026 | | - |
SimStep |  SimStep: Chain-of-Abstractions for Incremental Specification and Debugging of AI-Generated Interactive Simulations | arXiv 2025 | - | - |
ConvoLearn |  ConvoLearn: A Learning Sciences Grounded Dataset for Fine-Tuning Dialogic AI Tutors | arXiv 2026 | - | - |
AFIM: Academic Fraud Inclination Metric | AFIM: Academic Fraud Inclination Metric | Web 2026 | | - |
| - |  AI Researchers' Views on Automating AI R&D and Intelligence Explosions | arXiv 2026 | - | - |
| - | AI Scientists Are Changing Research | Nature 2026 | | - |
Learning by Creating (Talk) | Learning by Creating: A Human-Centered Vision for AI in Education | Talk 2026 | | - |
AI Sci. No Reasoning |  AI scientists produce results without reasoning scientifically | arXiv 2026 | - | - |
Not Built for Autonomy |  Agentic AI Scientists Are Not Built For Autonomous Scientific Discovery | arXiv 2026 | - | - |
Workflow != Closure |  Workflow Closure Is Not Scientific Closure in Auto-Research Systems | arXiv 2026 | - | - |
PseudoBench |  PseudoBench: Measuring How Agentic Auto-Research Fuels Pseudoscience | arXiv 2026 | - | - |
SciIntegrity-Bench |  SciIntegrity-Bench: A Benchmark for Evaluating Academic Integrity in AI Scientist Systems | arXiv 2026 | - | - |
| - |  Abduction Without a Body? Representational Grounding and the Abduction Loop for Scientific Hypothesis Generation | arXiv '26 | - | - |
| - |  Visualizing Graph-to-Answer Mechanism Recovery in Materials-Science Hypothesis Generation | arXiv '26 | - | - |
| - |  Generative AI use in Statistical Research: A Literature Review and Code Generation Case Study | arXiv '26 | - | - |
| - |  AI's Capability in Assisting Scientific Research in Physics, Astrophysics, and Cosmology I: Literature Review | arXiv '26 | - | - |
| - |  Scientific Knowledge Discovery in the Age of Large Language Models | arXiv '26 | - | - |
| - |  Is Deep Research Reliable? Misleading Knowledge Induces False Conclusions | arXiv '26 | - | - |
| - |  Diagnosing Search Behavior and Failure Modes in Long-Horizon Search Agents | arXiv '26 | - | - |
| - |  A Pathway to General-Purpose Scientific AI: Multimodal Comprehension of Scientific Images | arXiv '26 | - | - |
| - |  Position: AI Agents in Scientific Teams Should Be Studied as Human-Agent Systems | arXiv '26 | - | - |
| - |  The Past and Future of AI Scientists | arXiv '26 | - | - |
| - |  Efficiency Matters in Autonomous Research | arXiv '26 | - | - |
| - |  Agentic Auto-Research is Fuzz Testing | arXiv '26 | - | - |
| - |  Mechanist: AI as a Scientific Instrument for Discovering the Mechanisms of Intelligence | arXiv '26 | - | - |
| - |  An AI Scientist that Doesn't Drift: Taste, Structure, and Falsifiable Findings in a Quadruped Navigation Research Loop | arXiv '26 | - | - |
| - |  Long-Horizon Autonomous Architecture Research with a Language-Model Agent: A Behavioural Case Study | arXiv '26 | - | - |
| - |  Stress-testing large language model agents in a robotic chemistry laboratory | arXiv '26 | - | - |
11. Surveys & Curated Lists
:timer_clock: In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
LLM4SR |  LLM4SR: A Survey on Large Language Models for Scientific Research | arXiv 2025 | - | - |
From Automation to Autonomy |  From Automation to Autonomy: A Survey on Large Language Models for Scientific Discovery | arXiv 2025 | - | - |
AI4Research |  AI4Research: A Survey of Artificial Intelligence for Scientific Research | arXiv 2025 | - | - |
A Survey of AI Scientists |  A Survey of AI Scientists | arXiv 2025 | - | - |
| - |  Large Language Models for Scientific Idea Generation: A Creativity-Centered Survey | arXiv 2025 | - | - |
| - | Large Language Models for Automated Scholarly Paper Review: A Survey | Inf. Fusion 2025 | | - |
AutoResearch Survey | What's Missing in Autonomous Research? A Systematization of Systems, Benchmarks, and Verification | Web 2026 | | - |
12. Tools & GitHub Repos
Open-source tools, frameworks, and curated resource lists for AI-assisted research (not directly tied to a single paper).
Curated Lists
| Repository | Stars | Description |
|---|---|---|
| Awesome-Deep-Research |  | Up-to-date collection of agentic deep research resources |
| Awesome-Scientific-Language-Models |  | Survey of scientific LLMs (EMNLP'24) |
| Awesome-LLM-Scientific-Discovery |  | Three-level autonomy framework (EMNLP'25) |
| Awesome-AI-Scientist-Papers |  | Resources on AI Scientist systems |
| Awesome-Auto-Research-Tools |  | Automated research tools catalog |
| awesome-autoresearch |  | Autonomous improvement loops and research agents |
| awesome-ai-research-writing |  | Prompt templates and agent skills for AI-assisted writing |
Idea Generation
| Repository | Stars | Description |
|---|---|---|
| Virtual-Scientists |  | VirSci: multi-agent collaborative idea generation (ACL'25) |
| ResearchAgent | | Iterative idea proposal with reviewing agents |
Literature Review
| Repository | Stars | Description |
|---|---|---|
| paper-qa | | PaperQA2: superhuman RAG for scientific Q&A |
| local-deep-research |  | Fully local deep research |
| researchgpt |  | Conversational interaction with research papers |
| gpt-researcher | | Autonomous agent for comprehensive online research |
| AutoSurvey | | Automated comprehensive literature surveys |
| storm | | Wikipedia-style article generation (STORM) |
| lune-mcp-server |  | MCP client for the hosted Lune Research corpus: paper search, citation traversal, evidence extraction, quote-backed claim verification (API key required) |
Coding & Experiments
| Repository | Stars | Description |
|---|---|---|
| autoresearch (Karpathy) |  | Autonomous ML experiments, ~12 exp/hour overnight |
| Paper2Code | | Multi-agent ML paper to code transformation |
| RD-Agent |  | Microsoft's LLM framework for autonomous data science |
| MLAgentBench | | 13 end-to-end ML experimentation tasks |
| SWE-bench | | Real-world GitHub issue resolution benchmark |
| Thoth |  | Dashboard-first Claude Code and Codex runtime for durable autoresearch runs, work-item locks, ledgers, and reviewable verdicts |
Peer Review
| Repository | Stars | Description |
|---|---|---|
| paper-reviewer |  | arXiv paper reviews + blog posts |
| ai-peer-review | | Multi-LLM reviews + meta-review synthesis |
| openreviewer |  | Llama-8B fine-tuned on 79K expert reviews |
Last updated: 2026-08-31 · Maintained by WorldBench
Contributors


Similar repos


Languages
HTML
100.0%
🔥 A Survey on AI Auto-Research
See the codeREADME
:sunglasses: Awesome AI Auto-Research
|
|---|
This repository accompanies the survey paper "AI for Auto-Research: Roadmap & User Guide" and tracks papers on AI-assisted and automated scientific research, covering the full research lifecycle.
:robot: AI Auto-Research
We organize the academic research lifecycle as eight interconnected stages grouped into four epistemological phases. Each phase serves a distinct function in producing, scrutinizing, and communicating scientific knowledge.
| Phase 1: Creation Generating novel research ideas, searching and synthesizing literature, running coding experiments, and creating publication-quality tables and figures. This phase spans Idea Generation, Literature Review, Coding & Experiments, and Tables & Figures. |
| Phase 2: Writing Drafting, editing, and polishing academic manuscripts. AI assistance ranges from semi-automated grammar and citation tools to fully automated paper generation — the most commercially mature yet ethically contested stage. |
| Phase 3: Validation Automated peer review generation, reviewer-paper matching, review quality assessment, and AI-assisted author rebuttals. This phase covers Peer Review and Rebuttal & Revision. |
| Phase 4: Dissemination Converting papers into slides, posters, videos, websites, and social media content. Each output format targets a different audience and demands its own design logic and AI tool chain. |
For additional details, kindly refer to our :books: Paper and :earth_asia: Project Page.
:books: Citation
If you find this work helpful for your research, please kindly consider citing our paper:
@article{survey-ai-auto-research,
  title   = {{AI} for {Auto-Research}: Roadmap \& User Guide},
  author  = {Kong, Lingdong and Sun, Xian and Chow, Wei and Li, Linfeng and Lin, Kevin Qinghong and Zhang, Xuan Billy
             and Wang, Song and Li, Rong and Wu, Qing and Gao, Wei and Wang, Yingshuo and Xie, Shaoyuan
             and Liu, Jiachen and Qu, Leigang and Li, Shijie and Ng, Lai Xing and Cottereau, Benoit R.
             and Liu, Ziwei and Chua, Tat-Seng and Ooi, Wei Tsang},
  journal = {arXiv preprint arXiv:2605.18661},
  year    = {2026}
}
Table of Contents
- 1. Idea Generation
- 2. Literature Review & Paper Search
- 3. Coding & Experimentation
- 4. Tables & Figures
- 5. Paper Writing
- 6. Peer Review
- 7. Rebuttal
- 8. Dissemination (Paper2X)
- 9. End-to-End Systems
- 10. Societal & Critical Perspectives
- 11. Surveys & Curated Lists
- 12. Tools & GitHub Repos
|
|---|
1. Idea Generation
LLM Internal Knowledge-Based Generation
In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
Chain of Ideas | Chain of Ideas: Revolutionizing Research Via Novel Idea Development with LLM Agents | arXiv '24 | - | |
ResearchAgent | ResearchAgent: Iterative Research Idea Generation over Scientific Literature with Large Language Models | NAACL '25 | - | |
SciMON | SciMON: Scientific Inspiration Machines Optimized for Novelty | ACL '24 | - | |
Idea Gen Agent | Can LLMs Generate Novel Research Ideas? A Large Scale Human Study with 100+ NLP Researchers | arXiv '24 | - | - |
IRIS | IRIS: Interactive Research Ideation System for Accelerating Scientific Discovery | ACL '25 | - | |
Spark | Spark: A System for Scientifically Creative Idea Generation | ICCC '25 | - | - |
Diverse Hypo. Search | Towards Diverse Scientific Hypothesis Search with Large Language Models | arXiv '26 | - | - |
Tree-of-Ideas | Tree-of-Ideas: Automated Research Ideation via Cross-Trajectory Reasoning over Scholarly Evolution | arXiv '26 | - | - |
IDEAgent | IDEAgent: Agentic Quality-Diversity Search for Research Idea Generation | arXiv '26 | - | - |
External Signal-Driven Generation
In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
SGHA | SGHA: Evidence-Grounded Research Problem Discovery with Local Language Models | arXiv '26 | - | - |
MAIL | MAIL: Memory-driven, Adaptive, Incremental, and Literature-grounded Framework for Hypothesis Generation in Chemistry | arXiv '26 | - | - |
MOOSE-Chem | MOOSE-Chem: Large Language Models for Rediscovering Unseen Chemistry Scientific Hypotheses | ICLR '25 | - | - |
Nova | Nova: An Iterative Planning and Search Approach to Enhance Novelty and Diversity of LLM Generated Ideas | arXiv '24 | - | - |
SciAgents | SciAgents: Automating Scientific Discovery through Multi-Agent Intelligent Graph Reasoning | arXiv '24 | - | |
SciPIP | SciPIP: An LLM-based Scientific Paper Idea Proposer | arXiv '24 | - | |
IdeaSynth | IdeaSynth: Iterative Research Idea Development Through Evolving and Composing Idea Facets with Literature-Grounded Feedback | CHI '25 | - | - |
MOOSE-Chem2 | MOOSE-Chem2: Exploring LLM Limits in Fine-Grained Scientific Hypothesis Discovery via Hierarchical Search | NeurIPS '25 | - | - |
HALO | HALO: Interactive Co-abductive Reasoning in Scientific Hypothesis Generation | arXiv '26 | - | - |
TCA-SIR | TCA-SIR: Learning Target-Conditioned Abstractions for Scientific Inspiration Retrieval | arXiv '26 | - | - |
ECLAIR | ECLAIR: A Causally-Grounded AI Framework for Scientific Discovery in Empirical Software Engineering | arXiv '26 | - | - |
Multi-Agent Collaborative Generation
In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
HypoForge | HypoForge: A Self-Improving Multi-Agent Framework for Automated Hypothesis Generation and Testing via Scientific Skill Learning | arXiv '26 | - | - |
Combi. Creativity | Combi. Creativity | arXiv '24 | - | - |
Deep Ideation | Deep Ideation: Designing LLM Agents to Generate Novel Research Ideas on Scientific Concept Network | arXiv '25 | - | |
VirSci | Many Heads Are Better Than One: Improved Scientific Idea Generation by A LLM-Based Multi-Agent System | ACL '25 | - | |
Multi-Agent Dial. | Multi-Agent Dial. | SIGDIAL '25 | - | - |
Artificial Hivemind | Artificial Hivemind: The Open-Ended Homogeneity of Language Models (and Beyond) | NeurIPS '25 | - | - |
Auditable AI Sci. | Toward Auditable AI Scientists: A Hypothesis Evolution Protocol for LLM Agents | arXiv '26 | - | - |
Diverse Personalized Ideation | Diversifying Personalized Research Ideation against AI-Induced Homogenization | arXiv '26 | - | - |
Novelty and Feasibility Assessment
In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
RATIO | RATIO: A Benchmark for Retrieval Across Typed Ideation Operations in Scientific Literature | arXiv '26 | - | - |
Lit2Test | What Proves You Wrong: Benchmarking Language Models on Falsifiable Research Ideation | arXiv '26 | - | - |
Energy Scoring | Do LLMs Know a Good Hypothesis When They See One? Logit-Based Energy Scoring Outperforms Prompted LLM-as-Judge for Scientific Hypothesis Ranking | arXiv '26 | - | - |
Think-Probe-Respond | Think-Probe-Respond: Improving Large Language Models as Judges of Research Idea Novelty | EMNLP '26 | - | - |
IdeaBench | LiveIdeaBench: Evaluating LLMs' Scientific Creativity and Idea Generation with Minimal Context | KDD '25 | - | - |
LiveIdeaBench | LiveIdeaBench: Evaluating LLMs' Scientific Creativity and Idea Generation with Minimal Context | arXiv '24 | - | - |
AI Idea Bench 2025 | AI Idea Bench 2025: AI Research Idea Generation Benchmark | arXiv '25 | - | |
HeurekaBench | HeurekaBench: A Benchmarking Framework for AI Co-scientist | ICLR '26 | - | |
ResearchBench | ResearchBench: Benchmarking LLMs in Scientific Discovery via Inspiration-Based Task Decomposition | ACL '26 | - | - |
HindSight | HindSight: Evaluating LLM-Generated Research Ideas via Future Impact | arXiv '26 | - | - |
Rubric Rewards | Training AI Co-Scientists Using Rubric Rewards | arXiv '25 | - | - |
DeepInnovator | DeepInnovator: Triggering the Innovative Capabilities of LLMs | arXiv '26 | - | |
FlowPIE | FlowPIE: Test-Time Scientific Idea Evolution with Flow-Guided Literature Exploration | arXiv '26 | - | - |
SoundnessBench | SoundnessBench: Can Your AI Scientist Really Tell Good Research Ideas from Bad Ones? | arXiv '26 | - | - |
LLM-Judge Novelty | On the Limits of LLM-as-Judge for Scientific Novelty Assessment | arXiv '26 | - | - |
LigBench | LigBench: A Unified and Human-Aligned Benchmark for LLM-based Research Idea Generation | arXiv '26 | - | - |
Reconstruction | Reconstruction: A Blind Benchmark for Recovering Research Ideas from Pre-Publication Bibliographies | arXiv '26 | - | - |
2. Literature Review & Paper Search
Literature Retrieval
In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
ITER | ITER: Interaction-Aware Retrieval for Agentic Search | arXiv '26 | - | - |
Multi-Aspect Retrieval | Can Retrievers Find the Same Paper from Different Aspects? A Multi-Aspect Full-Paper Scientific Retrieval Benchmark | arXiv '26 | - | - |
CiteME | CiteME: Can Language Models Accurately Cite Scientific Claims? | arXiv '24 | - | - |
LitLLM | LitLLM: A Toolkit for Literature Review with Large Language Models | arXiv '24 | - | - |
LitSearch | LitSearch: A Retrieval Benchmark for Scientific Literature Search | arXiv '24 | - | |
PaperQA2 | Language Agents Achieve Superhuman Synthesis of Scientific Knowledge | arXiv '24 | - | |
OpenResearcher | OpenResearcher: Unleashing AI for Accelerated Scientific Research | EMNLP '24 | - | - |
PaSa | PaSa: An LLM Agent for Comprehensive Academic Paper Search | arXiv '25 | - | |
Self-Evolving Retrieval | Towards Self-Evolving Agentic Literature Retrieval | arXiv '26 | - | - |
MasterSet | MasterSet: A Large-Scale Benchmark for Must-Cite Citation Recommendation in the AI/ML Literature | arXiv '26 | - | - |
Search, Inspect, Fetch | Search, Inspect, Fetch: Exploiting Structure-Aware Boolean Retrieval for Deep-Research Agents | arXiv '26 | - | - |
Rubric Reranker | Training Documents Reranker with Search Rubrics for Deep Research Agent | arXiv '26 | - | - |
Personalized DR Refinement | Personalized Deep Research Query Refinement with Graph-Scaffolded Evidence Grounding | arXiv '26 | - | - |
Survey & Related Work Generation
In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
DAS | Deep Academic Survey: Stateful Agentic Closed-Loop Paradigm for Academic Survey Automation | arXiv '26 | - | - |
Tree-of-Concerns | Tree-of-Concerns: Hierarchical Multi-Agent Debate for Unstated-Limitation Extraction in Scientific Critique | EMNLP '26 | - | - |
ChatPaper | ChatPaper: Use LLM to summarize papers | GitHub '23 | - | |
PaperQA | PaperQA: Retrieval-Augmented Generative Agent for Scientific Research | arXiv '23 | - | |
AutoSurvey | AutoSurvey: Large Language Models Can Automatically Write Surveys | arXiv '24 | - | |
GPT Researcher | GPT Researcher: Autonomous Agent for Comprehensive Online Research | GitHub '24 | - | |
LLMs for Lit. Review | LLMs for Lit. Review | arXiv '24 | - | - |
STORM | Assisting in Writing Wikipedia-like Articles From Scratch with Large Language Models | arXiv '24 | - | |
Agentic AutoSurvey | Agentic AutoSurvey: Let LLMs Survey LLMs | arXiv '25 | - | - |
Citegeist | Citegeist: Automated Generation of Related Work Analysis on the arXiv Corpus | arXiv '25 | - | - |
IterSurvey | IterSurvey: Deep Literature Survey Automation with an Iterative Workflow | arXiv '25 | - | |
LiRA | LiRA: A Multi-Agent Framework for Reliable and Readable Literature Review Generation | arXiv '25 | - | - |
SurveyForge | SurveyForge: On the Outline Heuristics, Memory-Driven Generation, and Multi-dimensional Evaluation for Automated Survey Writing | arXiv '25 | - | |
SurveyG | SurveyG: A Multi-Agent LLM Framework with Hierarchical Citation Graph for Automated Survey Generation | arXiv '25 | - | - |
SurveyX | SurveyX: Academic Survey Automation via Large Language Models | arXiv '25 | - | - |
InteractiveSurvey | InteractiveSurvey: An LLM-based Personalized and Interactive Survey Paper Generation System | arXiv '25 | - | |
CiteLLM | CiteLLM: An Agentic Platform for Trustworthy Scientific Reference Discovery | arXiv '26 | - | - |
DeepSurvey | DeepSurvey: Enhancing Analytical Depth and Citation Reliability in Automated Survey Generation | arXiv '26 | - | - |
STRUCTSURVEY | STRUCTSURVEY: Structured Agentic Retrieval for Automated Survey Paper Generation | arXiv '26 | - | - |
Deep Research Agents
In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
Crase | Structurally-bounded Agentic Graph Exploration for Evidence-Grounded Scholarly DeepSearch | arXiv '26 | - | - |
DeepWeaver | DeepWeaver: Bridging the Evidence Synthesis Gap in Open-Ended Question Answering | arXiv '26 | - | - |
AgentR | AgentR A Stateful and Recovery-Aware Software Architecture for LLM-based Auditable Workflows | arXiv '26 | - | - |
ASReview | An Open Source Machine Learning Framework for Efficient and Transparent Systematic Reviews | Nature MI '21 | - | |
CHIME | CHIME: LLM-Assisted Hierarchical Organization of Scientific Studies for Literature Review Support | arXiv '24 | - | - |
DeepResearch-Agent | DeepResearchAgent: A Hierarchical Multi-Agent System for Deep Research | GitHub '25 | - | |
DeerFlow | DeerFlow: A Deep Research Framework Orchestrating Sub-Agents, Memory, and Sandboxes | GitHub '25 | - | |
OpenScholar | OpenScholar: Synthesizing Scientific Literature with Retrieval-Augmented LMs | Nature '26 | - | - |
AutoAgent | AutoAgent | arXiv '25 | - | - |
Tongyi DeepResearch | Tongyi DeepResearch | GitHub '25 | - | |
O-Researcher | O-Researcher: An Open Ended Deep Research Model via Multi-Agent Distillation and Agentic RL | arXiv '26 | - | - |
OpenResearcher | OpenResearcher: Unleashing AI for Accelerated Scientific Research | arXiv '26 | - | |
AREX | AREX: Towards a Recursively Self-Improving Agent for Deep Research | arXiv '26 | - | - |
Predictive Navigation | Deep Research Pretraining via Predictive Navigation | arXiv '26 | - | - |
On-Device DR (4B) | On-Device Deep Research at 4B: Exposure Bounds Faithfulness, Retrieval Bounds Coverage | arXiv '26 | - | - |
Carnot | Carnot: Interpretable, Interactive, and Optimized Execution of Deep Research Queries | VLDB '26 | - | - |
Marginal Value Est. | Not Worth Another Token: Marginal Value Estimation for Efficient Deep Research Agents | arXiv '26 | - | - |
Retrieval-Aware Control | When Deep Research Agents Stagnate: Enhancing Reasoning with Retrieval-Aware Agent Control | arXiv '26 | - | - |
Analogical Deep Research | Analogical Deep Research: Retrieving and Integrating Historical Analogies for Foresight Analysis | arXiv '26 | - | - |
Plato-Bio | Plato-Bio: verification-first biological novelty screening with temporal rediscovery and structural benchmarks | arXiv '26 | - | - |
Albilich | Albilich: Steerable Proof-State Orchestration for LLM-Based Mathematical Research with CAS Integration | arXiv '26 | - | - |
Retrieval and Synthesis Quality Assessment
In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
IBIS | From Inertia to Objectivity: Improving Deep Research Agents with Noise Isolation | EMNLP '26 | - | - |
Agent to Blame | Who is the Agent to Blame? Localizing Faithfulness and Citation Mistakes in Agentic Deep Research | EMNLP '26 | - | - |
DeepScholar-Bench | DeepScholar-Bench: A Live Benchmark and Automated Evaluation for Generative Research Synthesis | arXiv '25 | - | |
ReportBench | ReportBench: Evaluating Deep Research Agents via Academic Survey Tasks | arXiv '25 | - | |
IDRBench | IDRBench: Interactive Deep Research Benchmark | arXiv '26 | - | - |
ScholarGym | ScholarGym: Benchmarking Large Language Model Capabilities in the Information-Gathering Stage of Deep Research | arXiv '26 | - | - |
SciNetBench | SciNetBench: A Relation-Aware Benchmark for Scientific Literature Retrieval Agents | arXiv '26 | - | - |
AutoResearchBench | AutoResearchBench: Benchmarking AI Agents on Complex Scientific Literature Discovery | arXiv '26 | - | - |
PaperMind | PaperMind: Benchmarking Agentic Reasoning and Critique over Scientific Papers in Multimodal LLMs | arXiv '26 | - | - |
DRNOISE | DRNOISE: Benchmarking Deep Research Agents in Misleading Evidence Environments | arXiv '26 | - | - |
HiEviDR-Bench | HiEviDR-Bench: A Benchmark for Hierarchical Evidence Aggregation in Deep Research | arXiv '26 | - | - |
SciExplore | SciExplore: Evaluating Autonomous Agents from Scientific Navigation to Information Integration | arXiv '26 | - | - |
WANDR | WANDR: A Benchmark for Wide and Deep Research | arXiv '26 | - | - |
QA-to-DR Bench | From Simple QA to Deep Research: A Verifiable Benchmark Constructed through Iterative Task Evolution | arXiv '26 | - | - |
3. Coding & Experimentation
Code Generation
In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
SWE-bench | SWE-bench: Can Language Models Resolve Real-World GitHub Issues? | ICLR '24 | - | |
SWE-agent | SWE-agent: Agent-Computer Interfaces Enable Automated Software Engineering | arXiv '24 | - | |
OpenHands | OpenHands: An Open Platform for AI Software Developers as Generalist Agents | ICLR '25 | - | |
SWE-bench Pro | SWE-Bench Pro: Can AI Agents Solve Long-Horizon Software Engineering Tasks? | arXiv '25 | - | - |
SWE-EVO | SWE-EVO: Benchmarking Coding Agents in Long-Horizon Software Evolution Scenarios | arXiv '25 | - | - |
Paper-to-Code
In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
ReproAgent | ReproAgent: Contract-Guided Paper-to-Code Reproduction | EMNLP '26 | - | - |
DeepRepro | DeepRepro: State-Aware Subplanning for Paper-to-Code Reproduction in Evolving Repositories | CIKM '26 | - | - |
FunSearch | Mathematical Discoveries from Program Search with Large Language Models | Nature '24 | - | |
SciCode | SciCode: A Research Coding Benchmark Curated by Scientists | arXiv '24 | - | |
PaperBench | PaperBench: Evaluating AI's Ability to Replicate AI Research | arXiv '25 | - | |
PaperCoder | Paper2Code: Automating Code Generation from Scientific Papers in Machine Learning | arXiv '25 | - | |
ResearchCodeBench | ResearchCodeBench: Benchmarking LLMs on Implementing Novel ML Research Code | arXiv '25 | - | - |
SciReplicate-Bench | SciReplicate-Bench: Benchmarking LLMs in Agent-driven Algorithmic Reproduction from Research Papers | arXiv '25 | - | |
Experiment Execution & Orchestration
In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
Praxist | Praxist: From Experimental Artifacts to Solution Lineages | arXiv '26 | - | - |
Skill-Based Baselines | Can Coding Agents Build Robust Baselines? A Skill-Based Approach for Automating the Medical Imaging Model-Development Pipeline | MICCAI '26 | - | - |
BioPlanner | BioPlanner: Automatic Evaluation of LLMs on Protocol Planning | arXiv '23 | - | |
CRISPR-GPT | CRISPR-GPT for Agentic Automation of Gene-Editing Experiments | arXiv '24 | - | - |
DS-Agent | DS-Agent: Automated Data Science by Empowering Large Language Models with Case-Based Reasoning | arXiv '24 | - | |
MLE-Bench | MLE-Bench: Evaluating Machine Learning Agents on Machine Learning Engineering | arXiv '24 | - | - |
MLAgentBench | MLAgentBench: Evaluating Language Agents on Machine Learning Experimentation | arXiv '24 | - | |
MLR-Copilot | MLR-Copilot: Autonomous Machine Learning Research based on Large Language Models Agents | arXiv '24 | - | - |
AIDE | AIDE: AI-Driven Exploration in the Space of Code | arXiv '25 | - | - |
AlphaEvolve | AlphaEvolve: A Coding Agent for Scientific and Algorithmic Discovery | arXiv '25 | - | - |
AutoReproduce | AutoReproduce: Automatic AI Experiment Reproduction with Paper Lineage | arXiv '25 | - | |
CURIE | Curie: Toward Rigorous and Automated Scientific Experimentation with AI Agents | arXiv '25 | - | |
MLGym | MLGym: A New Framework and Benchmark for Advancing AI Research Agents | arXiv '25 | - | - |
MLR-Bench | MLR-Bench: Evaluating AI Agents on Open-Ended Machine Learning Research | arXiv '25 | - | - |
Execution-Grounded | Towards Execution-Grounded Automated AI Research | arXiv '26 | - | - |
Learn to Discover | Learning to Discover at Test Time | arXiv '26 | - | - |
AutoNumerics | AutoNumerics: An Autonomous, PDE-Agnostic Multi-Agent Pipeline for Scientific Computing | arXiv '26 | - | |
SciNav | SciNav: A General Agent Framework for Scientific Coding Tasks | arXiv '26 | - | - |
FrontierScience | FrontierScience: Evaluating AI's Ability to Perform Expert-Level Scientific Tasks | arXiv '26 | - | - |
EvoDS | EvoDS: Self-Evolving Autonomous Data Science Agent with Skill Learning and Context Management | arXiv '26 | - | - |
AutoTTS | LLMs Improving LLMs: Agentic Discovery for Test-Time Scaling | arXiv '26 | - | |
AutoScientists | AutoScientists: Self-Organizing Agent Teams for Long-Running Scientific Experimentation | arXiv '26 | - | - |
EurekAgent | EurekAgent: Agent Environment Engineering is All You Need For Autonomous Scientific Discovery | arXiv '26 | - | - |
Code Correctness and Reproducibility Assessment
In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
Experimental Fidelity | Beyond Execution: Auditing Experimental Fidelity in LLM-Driven Scientific Research | arXiv '26 | - | - |
DiscoveryBench | DiscoveryBench: Towards Data-Driven Discovery with Large Language Models | arXiv '24 | - | |
DiscoveryWorld | DiscoveryWorld: A Virtual Environment for Developing and Evaluating Automated Scientific Discovery Agents | arXiv '24 | - | |
InfiAgent-DABench | InfiAgent-DABench: Evaluating Agents on Data Analysis Tasks | arXiv '24 | - | - |
ScienceAgentBench | ScienceAgentBench: Toward Rigorous Assessment of Language Agents for Data-Driven Scientific Discovery | arXiv '24 | - | - |
LAB-Bench | Lab-Bench: Measuring Capabilities of Language Models for Biology Research | arXiv '24 | - | |
KernelBench | KernelBench: Can LLMs Write Efficient GPU Kernels? | arXiv '25 | - | |
TritonBench | TritonBench: Benchmarking Large Language Model Capabilities for Generating Triton Operators | arXiv '25 | - | |
AstaBench | AstaBench: Rigorous Benchmarking of AI Agents with a Scientific Research Suite | arXiv '25 | - | |
ResearchClawBench | Probing Scientific General Intelligence of LLMs with Scientist-Aligned Workflows | arXiv '25 | - | |
EXP-Bench | EXP-Bench: Can AI Conduct AI Research Experiments? | ICLR '26 | - | |
PostTrainBench | PostTrainBench: Can LLM Agents Automate LLM Post-Training? | arXiv '26 | - | |
MLReplicate | MLReplicate: Benchmarking Autonomous Research Systems for Machine Learning Reproducibility | arXiv '26 | - | - |
BeyondSWE | BeyondSWE: Can Current Code Agent Survive Beyond Single-Repo Bug Fixing? | arXiv '26 | | |
NatureBench | NatureBench: Can Coding Agents Match the Published SOTA of Nature-Family Papers? | arXiv '26 | - | - |
SciCoQA | SciCoQA: Quality Assurance for Scientific Paper--Code Alignment | ACL '26 | | |
4. Tables & Figures
Scientific Figure Generation
In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
ChartGPT | ChartGPT: Leveraging LLMs to Generate Charts from Abstract Natural Language | arXiv '23 | - | - |
MatPlotAgent | MatPlotAgent: Method and Evaluation for LLM-Based Agentic Scientific Data Visualization | arXiv '24 | - | - |
CoDA | CoDA: Agentic Systems for Collaborative Data Visualization | arXiv '25 | - | - |
PlotGen | PlotGen: Multi-Agent LLM-based Scientific Data Visualization via Multimodal Feedback | arXiv '25 | - | - |
VIS-Shepherd | VIS-Shepherd: Constructing Critic for LLM-based Data Visualization Generation | arXiv '25 | - | - |
DiagramAgent | From Words to Structured Visuals: A Benchmark and Framework for Text-to-Diagram Generation and Editing | CVPR '25 | - | - |
StarVector | StarVector: Generating Scalable Vector Graphics Code from Images and Text | CVPR '25 | - | - |
VisCoder | VisCoder: Fine-Tuning LLMs for Executable Python Visualization Code Generation | EMNLP '25 | - | - |
AI-Generated Figures | AI-Generated Figures | arXiv '26 | - | - |
AutoFigure-Edit | AutoFigure-Edit: Generating Editable Scientific Illustration | arXiv '26 | - | |
AutoFigure | AutoFigure-Edit: Generating Editable Scientific Illustration | ICLR '26 | - | |
PaperBanana | PaperBanana: Automating Academic Illustration for AI Scientists | arXiv '26 | - | - |
SAIL | Setting SAIL: Leveraging Scientist-AI-Loops for Rigorous Visualization Tools | arXiv '26 | - | - |
Crafter | Crafter: A Multi-Agent Harness for Editable Scientific Figure Generation from Diverse Inputs | arXiv '26 | - | - |
DiagramRAG | DiagramRAG: A Lightweight Framework to Retrieve Scientific Diagram for Figure Generation | arXiv '26 | - | - |
GeoSVG-RL | GeoSVG-RL: Geometry-Aware Reinforcement Learning for Layout-Constrained Text-to-SVG Diagram Generation | arXiv '26 | - | - |
Can AI Draw Sci. | Can AI Draw Science? A Benchmark for Evaluating Scientific Figure Generation by Text-to-Image and Multimodal Models | arXiv '26 | - | - |
SciDiagramEdit | SciDiagramEdit: Learning to Edit Scientific Diagrams from Paper Revisions | arXiv '26 | - | - |
GenGA | GenGA: Editable and Data-Grounded Graphical Abstract Generation for Academic Papers | arXiv '26 | - | - |
Table Understanding & Generation
In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
ArxivDIGESTables | ArxivDIGESTables: Synthesizing Scientific Literature into Tables using Language Models | EMNLP '24 | - | - |
Chain-of-Table | Chain-of-Table: Evolving Tables in Reasoning Chain for Table Understanding | ICLR '24 | - | - |
ShowTable | ShowTable: Unlocking Creative Table Visualization with Collaborative Reflection and Refinement | CVPR '26 | - | - |
Table2LaTeX-RL | Table2LaTeX-RL: Converting Table Images to High-Fidelity LaTeX Code Using Reinforced Multimodal Language Models | arXiv '25 | - | - |
CSPO | CSPO: Alleviating Reward Ambiguity for Structured Table-to-LaTeX Generation | arXiv '26 | - | - |
Mathematical Formulas & TikZ
In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
AutomaTikZ | AutomaTikZ: Text-Guided Synthesis of Scientific Vector Graphics with TikZ | ICLR '24 | - | - |
DeTikZify | DeTikZify: Synthesizing Graphics Programs for Scientific Figures and Sketches with TikZ | NeurIPS '24 | - | - |
TikZilla | TikZilla: Scaling Text-to-TikZ with High-Quality Data and Reinforcement Learning | arXiv '26 | - | - |
Edit2TikZ | Edit2TikZ: A Comprehensive and Challenging Benchmark for Scientific Figure Editing with TikZ | arXiv '26 | - | - |
Visual Fidelity and Scientific Accuracy Assessment
In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
StructEval | StructEval: Benchmarking LLMs' Capabilities to Generate Structural Outputs | TMLR '25 | | |
PlotCraft | PlotCraft: Pushing the Limits of LLMs for Complex and Interactive Data Visualization | arXiv '25 | - | - |
TeXpert | TeXpert: Multi-Level Benchmark for LaTeX Code Generation | SDP '25 | - | - |
AbGen | AbGen: Evaluating Large Language Models in Ablation Study Design and Evaluation for Scientific Research | ACL '25 | - | - |
SciFig | SciFig: Towards Automating Scientific Figure Generation | arXiv '26 | - | - |
SciFlow-Bench | SciFlow-Bench: Evaluating Structure-Aware Scientific Diagram Generation via Inverse Parsing | arXiv '26 | - | - |
FigureBench | AutoFigure: Generating and Refining Publication-Ready Scientific Illustrations | ICLR '26 | - | |
SciFigQual-Bench | SciFigQual-Bench: A Benchmark for Scientific Figure Quality Assessment with Full-Manuscript Context | arXiv '26 | - | - |
SciFigAlign | SciFigAlign: Scoring Scientific Figures by Fine-tuned Alignment of Visuals with Manuscript Evidence | arXiv '26 | - | - |
SciFigPlag-Bench | SciFigPlag-Bench: A Benchmark for Provenance-Aware Scientific Figure Plagiarism Detection | arXiv '26 | - | - |
VLM Blind/Misled | How Do VLMs Behave When Blind or Misled? Behavioral Evaluation of VLMs on Scientific Figures | arXiv '26 | - | - |
5. Paper Writing
Semi-Automated Writing Assistance
In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
CoAuthor | CoAuthor: Human-AI Collaborative Writing with Language Models | arXiv '22 | - | - |
AI Writing Study | AI Writing Study | AIED '25 | - | - |
DraftMarks | DraftMarks: Enhancing Transparency in Human-AI Co-Writing Through Interactive Skeuomorphic Process Traces | arXiv '25 | - | - |
PaperDebugger | PaperDebugger: A Plugin-Based Multi-Agent System for In-Editor Academic Writing, Review, and Editing | arXiv '25 | - | |
ScholarCopilot | ScholarCopilot: Training LLMs for Academic Writing with Integrated Citation | arXiv '25 | - | - |
XtraGPT | XtraGPT: Context-Aware and Controllable Academic Paper Revision | arXiv '25 | - | - |
LimAgents | Multi-Agent LLMs for Generating Research Limitations | arXiv '26 | - | - |
PaperMentor | PaperMentor: A Human-Centered Multi-Agent Writing Tutor for AI Research Papers on Overleaf | arXiv '26 | - | - |
AutoSupervision | AutoSupervision: Closing the Feedback Loop in Scientific Workflows with Grounded Revision Verification | arXiv '26 | - | - |
ReasFlow | ReasFlow: Assisting Reasoning-Centric Scientific Discovery in Applied Mathematics via a Knowledge-Based Multi-Agent System | arXiv '26 | - | - |
Fully Automated Paper Generation
In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
CycleResearcher | CycleResearcher: Improving Automated Research via Automated Review | ICLR '25 | - | - |
Agent Laboratory | Agent Laboratory: Using LLM Agents as Research Assistants | EMNLP '25 | - | - |
FutureGen | FutureGen: A RAG-based Approach to Generate the Future Work of Scientific Article | arXiv '25 | - | - |
AI Scientist | The AI Scientist: Towards Fully Automated Open-Ended Scientific Discovery | Nature '26 | - | |
APRES | APRES: An Agentic Paper Revision and Evaluation System | arXiv '26 | - | - |
LECTOR | LECTOR: Joint Optimization of Scientific Reasoning Graphs and Introduction Generation | arXiv '26 | - | - |
RWGBench | RWGBench: Evaluating Scholarly Positioning in Related Work Generation | arXiv '26 | - | - |
Societal Analysis
In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
AI Writing Adoption | AI Writing Adoption | Nature '26 | - | - |
Nature AI Survey | More than Half of Researchers Now Use AI for Peer Review | Nature '26 | - | - |
Denial of Science | Distributed Denial of Science: How Indirect Data Poisoning of AI Systems Can Industrialize Scientific Fraud | arXiv '26 | - | - |
AI Slop OSS | "AI Slop is DDoSing Open Source": Understanding the Impact of AI-Generated Contributions on Open Source Sustainability | arXiv '26 | - | - |
Writing Quality and AI Detection Assessment
In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
Mapping LLM Use | Mapping the Increasing Use of LLMs in Scientific Papers | arXiv '24 | - | - |
CycleReviewer | CycleResearcher: Improving Automated Research via Automated Review | ICLR '25 | - | - |
Stanford Agentic | Stanford Agentic | Web '25 | - | - |
SciIG | Let's Use ChatGPT To Write Our Paper! Benchmarking LLMs To Write the Introduction of a Research Paper | arXiv '25 | - | - |
Watermarking | Detecting LLM-Generated Peer Reviews | arXiv '25 | - | - |
PaperWritingBench | PaperOrchestra: A Multi-Agent Framework for Automated AI Research Paper Writing | arXiv '26 | - | - |
CiteTracer | Source or It Didn't Happen: A Multi-Agent Framework for Citation Hallucination Detection | arXiv '26 | - | - |
Process Eval | Process-Oriented Evaluation of AI-Assisted Scientific Writing | arXiv '26 | - | - |
6. Peer Review
Automated Review Generation
In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
ChatReviewer | ChatReviewer: ChatGPT-based Paper Reviewing and Response Generation | GitHub '23 | - | |
AI-Peer-Review | AI-Peer-Review | GitHub '24 | - | |
MARG | MARG: Multi-Agent Review Generation for Scientific Papers | arXiv '24 | - | - |
Reviewer2 | Reviewer2: Optimizing Review Generation Through Prompt Generation | arXiv '24 | - | - |
ReviewRL | ReviewRL: Towards Automated Scientific Review with RL | EMNLP '25 | - | - |
DeepReviewer | DeepReview: Improving LLM-based Paper Review with Human-like Deep Thinking Process | arXiv '25 | - | - |
OpenReviewer | OpenReviewer: A Specialized Large Language Model for Generating Critical Scientific Paper Reviews | NAACL '25 | - | - |
REMOR | REMOR: Automated Peer Review Generation with LLM Reasoning and Multi-Objective Reinforcement Learning | arXiv '25 | - | - |
ScholarPeer | ScholarPeer: A Context-Aware Multi-Agent Framework for Automated Peer Review | arXiv '26 | - | - |
ProReviewer | From Passive Generation to Investigation: A Proactive Scientific Peer Review Agent | arXiv '26 | - | - |
PeerCheck | PeerCheck: Enhancing LLM-Generated Academic Reviews Towards Human-Level Quality | arXiv '26 | - | - |
Local Pre-Screening | Local AI pre-screening for human triple-blind peer review in health sciences | arXiv '26 | - | - |
ReVoicer | ReVoicer: Conversational Voice Annotation for Human-Centered, LLM-Assisted Peer Review | arXiv '26 | - | - |
Meta-Review & Reviewer Matching
In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
Metag | Metag: A dataset to build agentic meta-reviewing capabilities | arXiv '26 | - | - |
AgentReview | AgentReview: Exploring Peer Review Dynamics with LLM Agents | EMNLP '24 | - | - |
Meta-Review LLMs | Meta-Review LLMs | NAACL '25 | - | - |
RATE | RATE: Reviewer Profiling and Annotation-free Training for Expertise Ranking in Peer Review Systems | arXiv '26 | - | - |
MERIT | MERIT: Matching Expertise via Rubric-Informed Training for Reviewer Assignment | arXiv '26 | - | - |
Adversarial Attacks & Bias Analysis
In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
Raina etal | Raina etal | EMNLP '24 | - | - |
AI Review Lottery | The AI Review Lottery: Widespread AI-Assisted Peer Reviews Boost Paper Scores and Acceptance Rates | arXiv '24 | - | - |
Ye etal | Ye etal | arXiv '24 | - | - |
Breaking the Reviewer | Breaking the Reviewer: Assessing the Vulnerability of Large Language Models in Automated Peer Review Under Textual Adversarial Attacks | arXiv '25 | - | - |
LLM Reviewer Bias | LLM Reviewer Bias | arXiv '25 | - | - |
Prompt Injection | Prompt Injection Attacks on LLM Generated Reviews of Scientific Publications | arXiv '25 | - | - |
Sahoo etal | Sahoo etal | arXiv '25 | - | - |
Zhou etal | Zhou etal | arXiv '25 | - | - |
Presentation Gaming | No Hidden Prompts Needed! You Can Game AI Peer Review with Presentation-Only Revisions | arXiv '26 | - | - |
LLMs Favor LLMs? | Do LLMs Favor LLMs? Quantifying Interaction Effects in Peer Review | arXiv '26 | - | - |
Gaming AI Reviews | Gaming AI-Assisted Peer Reviews Poses New Risks to the Scientific Community | arXiv '26 | - | - |
Phantom Refs | Phantom References: Hallucinated Citations That Survive Peer Review at Top-Tier Conferences | arXiv '26 | - | - |
Rhetorical Reward-Hacking | How Can Rhetoric Reward-Hack AI Reviewers? Dissecting Rhetorical Sensitivity in AI-Based Peer Review | arXiv '26 | - | - |
Detection & Policy
In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
AI Detection | Is Your Paper Being Reviewed by an LLM? Benchmarking AI Text Detection in Peer Review | arXiv '25 | - | - |
AI Use Rejects | Major Conference Catches Illicit AI Use — and Rejects Hundreds of Papers | Nature '26 | - | - |
Nature AI Survey | More than Half of Researchers Now Use AI for Peer Review | Nature '26 | - | - |
Policy Enforcement | Policy Enforcement | arXiv '26 | - | - |
Reviewer Feedback | What Happens When Reviewers Receive AI Feedback in Their Reviews? | CHI '26 | - | - |
AAAI-26 Pilot | AI-Assisted Peer Review at Scale: The AAAI-26 AI Review Pilot | arXiv '26 | - | - |
Reviewer AI Policies | AI-Assisted Peer Review Across Research Communities: From Reviewer AI Policies to LLM Review Quality | arXiv '26 | - | - |
Review Consistency and Bias Assessment
In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
VERA-RL | Not Just Reason, Not Just Scan: Reinforcement Learning for Proactive Scientific Error Verification over Academic Paper | EMNLP '26 | - | - |
Review Survey | More than Half of Researchers Now Use AI for Peer Review — often Against Guidance | IF '25 | - | - |
Stanford Agentic | Stanford Agentic | Web '25 | - | - |
ClaimCheck | ClaimCheck: How Grounded are LLM Critiques of Scientific Papers? | EMNLP '25 | - | - |
REFUTE | REFUTE: A Benchmark for Scientific Critique and Epistemic Calibration in Language Models | HF '26 | Website | - |
ReViewGraph | Automatic Paper Reviewing with Heterogeneous Graph Reasoning over LLM-Simulated Reviewer-Author Debates | AAAI '26 | - | - |
ReviewAgents | ReviewAgents: Bridging the Gap Between Human and AI-Generated Paper Reviews | arXiv '25 | - | - |
ICLR 2025 Study | ICLR 2025 Study | NMI '26 | - | - |
AI Reviewer Limits | On the limits and opportunities of AI reviewers: Reviewing the reviews of Nature-family papers with 45 expert scientists | arXiv '26 | - | - |
PRISM | PRISM: A Multi-Dimensional Benchmark for Evaluating LLM Peer Reviewers | arXiv '26 | - | - |
LLM-Human Alignment | How Closely Do LLM Reviews Align with Human Peer Review? | arXiv '26 | - | - |
Epistemic Reliability | Articulate Intuition or Genuine Analysis? Benchmarking Epistemic Reliability in LLM-as-a-Judge Peer Reviews | arXiv '26 | - | - |
SurveyReview | SurveyReview: A Reviewer-Aligned Benchmark for Survey Evaluators | arXiv '26 | - | - |
7. Rebuttal
Reviewer Comment Analysis
In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
ReviewMT | Peer Review as A Multi-Turn and Long-Context Dialogue with Role-Based Interactions | arXiv '24 | - | - |
ICLR Rebuttal Study | ICLR Rebuttal Study | arXiv '25 | - | - |
RbtAct | RbtAct: Rebuttal as Supervision for Actionable Review Feedback Generation | arXiv '26 | - | - |
GoodPoint | GoodPoint: Learning Constructive Scientific Paper Feedback from Author Responses | arXiv '26 | - | - |
Automated Rebuttal Generation
In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
ReviewerToo | ReviewerToo: Should AI Join The Program Committee? A Look At The Future of Peer Review | arXiv '25 | - | - |
RebuttalAgent | RebuttalAgent: Strategic Persuasion in Academic Rebuttal via Theory of Mind | ICLR '26 | - | |
Author-in-the-Loop | Author-in-the-Loop Response Generation and Evaluation: Integrating Author Expertise and Intent in Responses to Peer Review | ACL '26 | - | - |
DRPG | DRPG: An Agentic Framework for Academic Rebuttal | arXiv '26 | - | |
Paper2Rebuttal | Paper2Rebuttal: A Multi-Agent Framework for Transparent Author Response Assistance | arXiv '26 | - | - |
Defend | Defend: Automated Rebuttals for Peer Review with Minimal Author Guidance | arXiv '26 | - | - |
Rebuttal Effectiveness Assessment
In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
Re$^2$ | Re$^2$ | arXiv '25 | - | - |
Commitment Checklist | Commitment Checklist: Auditing Author Commitments in Peer Review | arXiv '26 | - | - |
Re$^3$Align | Re$^3$Align | ACL '26 | - | - |
Rebuttals Move | Rebuttals Move Peer-Review Scores, but Initial-Review Structure Bounds the Movement | arXiv '26 | - | - |
Trust AI Reviews | To Trust or Not to Trust: Authors' Response to AI-based Reviews | arXiv '26 | - | - |
8. Dissemination (Paper2X)
Paper2Poster
In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
P2P | P2P: Automated Paper-to-Poster Generation and Fine-Grained Benchmark | ICLR '26 | - | - |
Paper2Poster | Paper2Poster: Towards Multimodal Poster Automation from Scientific Papers | NeurIPS '25 | - | |
PosterForest | PosterForest: Hierarchical Multi-Agent Collaboration for Scientific Poster Generation | arXiv '25 | - | - |
PosterGen | PosterGen: Aesthetic-Aware Paper-to-Poster Generation via Multi-Agent LLMs | arXiv '25 | - | - |
APEX | APEX: Academic Poster Editing Agentic Expert | arXiv '26 | - | |
PosterOmni | PosterOmni: Generalized Artistic Poster Creation via Task Distillation and Unified Reward Feedback | arXiv '26 | - | - |
Any2Poster | Any2Poster: Any-Source Poster Generation Across Modalities and Domains | arXiv '26 | - | - |
PosterMELD | PosterMELD: Multi-Agent Paper-to-Poster Generation for Controllable Design Diversity with Editable Print-Ready Outputs | arXiv '26 | - | - |
Paper2Slides
In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
DOC2PPT | DOC2PPT: Automatic Presentation Slides Generation from Scientific Documents | AAAI '22 | - | - |
PPTAgent | PPTAgent: Generating and Evaluating Presentations Beyond Text-to-Slides | EMNLP '25 | - | |
AutoPresent | AutoPresent: Designing Structured Visuals from Scratch | CVPR '25 | - | - |
Paper2Slides | Paper2Slides: From Paper to Presentation in One Click | GitHub '25 | - | |
Auto-Slides | Auto-Slides: An Interactive Multi-Agent System for Creating and Customizing Research Presentations | arXiv '25 | - | - |
PASS | PASS: Presentation Automation for Slide Generation and Speech | arXiv '25 | - | - |
SlideGen | SlideGen: Collaborative Multimodal Agents for Scientific Slide Generation | arXiv '25 | - | - |
Talk to Your Slides | Talk to Your Slides: Efficient Slide Editing Agent | arXiv '25 | - | - |
SlideTailor | SlideTailor: Personalized Presentation Slide Generation for Scientific Papers | AAAI '26 | - | |
DeepPresenter | DeepPresenter: Environment-Grounded Reflection for Agentic Presentation Generation | arXiv '26 | - | |
Office Raccoon | Office Raccoon | Web '26 | - | - |
X+Slides | X+Slides: Benchmarking Audience-Conditioned Slide Generation | arXiv '26 | - | - |
SeaSlides | SeaSlides: Semantic Abstraction Layer for Agentic Slide Generation | arXiv '26 | - | - |
Paper2Video
In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
Preacher | Preacher: Paper-to-Video Agentic System | ICCV '25 | - | |
Paper2Video | Paper2Video: Automatic Video Generation from Scientific Papers | arXiv '25 | - | |
PresentAgent | PresentAgent: Multimodal Agent for Presentation Video Generation | EMNLP '25 | - | |
PresentAgent-2 | PresentAgent-2: Towards Generalist Multimodal Presentation Agents | arXiv '26 | - | - |
Paper2Video Talks | A Good Talk Does not Look Like a Summary, It Teaches You! Measuring Takeaways from Paper-to-Video Talks | arXiv '26 | - | - |
Paper2Web & Social Media
In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
Paper2Web | Paper2Web: Let's Make Your Paper Alive! | arXiv '25 | - | |
ResearchStudio-Reel | ResearchStudio-Reel: Automate the Last Mile of Research from Paper to Poster, Video, and Blog | arXiv '26 | - | - |
I-WebGenBench | I-WebGenBench: Evaluating Interactivity in LLM-Generated Scientific Web Applications | arXiv '26 | - | - |
SciForge | SciForge: An AI-Native, Multimodal Workbench for Scientific Discovery | arXiv '26 | - | - |
Fidelity and Adoption Assessment
In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
PPTEval | PPTAgent: Generating and Evaluating Presentations Beyond Text-to-Slides | EMNLP '25 | - | |
PresentQuiz | Paper2Video: Automatic Video Generation from Scientific Papers | arXiv '25 | - | |
PresentEval | PresentAgent: Multimodal Agent for Presentation Video Generation | EMNLP '25 | - | |
Sci. Comm. Correspondence | Unifying Scientific Communication: Fine-Grained Correspondence Across Scientific Media | arXiv '26 | - | - |
9. End-to-End Systems
Fully Automated Research Systems
In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
Gemini Co-Scientist | Accelerating Scientific Research with Gemini in the Real-World | arXiv 2026 | - | - |
AutoResearch | AutoResearch: Insight In, Hallucination Out | arXiv 2026 | - | - |
Eureka | Eureka: Task-Conditioned Meta-Agent Orchestration for Scientific Discovery | arXiv 2026 | - | - |
AutoResearch Diagnosis | How Do Agents Fail on AutoResearch: End-to-End Diagnostic Evaluation on 100 Real-World Frontier Research Tasks | arXiv 2026 | - | - |
ResearchTown | ResearchTown: Simulator of Human Research Community | ICML 2025 | | |
Agent Laboratory | Agent Laboratory: Using LLM Agents as Research Assistants | arXiv 2025 | - | - |
AgentRxiv | AgentRxiv: Towards Collaborative Autonomous Research | arXiv 2025 | - | - |
ARIS | - | GitHub 2025 | - | |
freephdlabor | Build Your Personalized Research Group: A Multiagent Framework for Continual and Interactive Science Automation | arXiv 2025 | - | - |
SciMaster | SciMaster: Towards General-Purpose Scientific AI Agents | arXiv 2025 | - | |
| - | Towards End-to-End Automation of AI Research | Nature 2026 | | |
Idea2Story | Idea2Story: An Automated Pipeline for Transforming Research Concepts into Complete Scientific Narratives | arXiv 2026 | - | - |
UniScientist | - | Web 2026 | - | - |
ASI-Evolve | - | GitHub 2026 | - | |
FARS | - | Web 2026 | - | - |
AutoResearchClaw | - | GitHub 2026 | - | |
CORAL | CORAL: Towards Autonomous Multi-Agent Evolution for Open-Ended Discovery | arXiv 2026 | - | |
AutoSOTA | AutoSOTA: An End-to-End Automated Research System for State-of-the-Art AI Model Discovery | arXiv 2026 | - | |
AiScientist-LH | Toward Autonomous Long-Horizon Engineering for ML Research | arXiv 2026 | - | |
OpenResearcher (2026) | OpenResearcher: A Fully Open Pipeline for Long-Horizon Deep Research Trajectory Synthesis | arXiv 2026 | - | |
Aletheia | Towards Autonomous Mathematics Research | arXiv 2026 | - | |
AutoSci | AutoSci: A Memory-Centric Agentic System for the Full Scientific Research Lifecycle | arXiv 2026 | - | - |
ScientistOne | ScientistOne: Towards Human-Level Autonomous Research via Chain-of-Evidence | arXiv 2026 | - | - |
Arbor | Toward Generalist Autonomous Research via Hypothesis-Tree Refinement | arXiv 2026 | - | - |
Agon | Agon: An Autonomous Large-Scale Omnidisciplinary Research System Built on Prompt Economy | arXiv 2026 | - | |
ResearchClawBench | ResearchClawBench: A Benchmark for End-to-End Autonomous Scientific Research | arXiv 2026 | - | - |
Act as Real Researcher | Act As a Real Researcher: A Suite of Benchmarks Evaluating Frontier LLMs and Agentic Harnesses in Research Lifecycle | arXiv 2026 | - | - |
ResearchArena | How Far Are We From True Auto-Research? | arXiv 2026 | - | - |
NVAITC AI Sci. | NVAITC AI Scientist: A Governed End-to-End Research System -- A Hypertension GWAS Case Study | arXiv '26 | - | - |
DeepResearch Agent Sys. | DeepResearch Agent System | arXiv '26 | - | - |
ScienceFlow | ScienceFlow: A long-horizon agent for ML research, scientific discovery and beyond | arXiv '26 | - | - |
Spark-to-Paper | Spark-to-Paper: End-to-End Research Paper Generation as a Composable Skill | arXiv '26 | - | - |
OmniScientist | OmniScientist: An Omni-Modal Omni-Discipline AI Scientist | arXiv '26 | - | - |
Domain-Specific Systems
In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
AutoSR | AutoSR: Automatic Symbolic Regression by Searching Research States | arXiv 2026 | - | - |
The AI Engineer | Closed-loop AI achieves certifiable engineering design | arXiv 2026 | - | - |
AlphaFold 3 | Accurate Structure Prediction of Biomolecular Interactions with AlphaFold 3 | Nature 2024 | | - |
Medical AI Scientist | Towards a Medical AI Scientist | arXiv 2026 | - | - |
Cognitive Scientist | Closing the Loop to Discover Psychological Theories with an Automated Cognitive Scientist | arXiv '26 | - | - |
Molecular Closed-Loop | Closed-loop Auto Research for Molecular Property Prediction: Discovering and Certifying Generalizable Improvements | arXiv '26 | - | - |
Auto Research (Materials) | Auto Research for Materials: Auditable AI-Scientist Workflows with Held-Out Transfer | arXiv '26 | - | - |
OmniQEC | OmniQEC: discovering practical quantum error-correcting codes by an AI scientist | arXiv '26 | - | - |
Andy | Andy: A Mathematical Agent for Rigorous Proof and Autonomous Research | arXiv '26 | - | - |
BaT | BaT: Towards Self-Evolving Medical Research Agent with Stage Rubrics | arXiv '26 | - | - |
Agentic Sci. Community | An Agentic AI Scientific Community for Automated Neural Operator Discovery | arXiv '26 | - | - |
WARA | WARA: A Closed-Loop Multi-Agent Framework for Wireless Optimization Autoresearch | ICCC '26 | - | - |
Evolutionary & Self-Improving Systems
In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
ShinkaEvolve | ShinkaEvolve: Towards Open-Ended and Sample-Efficient Program Evolution | arXiv 2025 | - | |
Darwin Godel Machine | Darwin Godel Machine: Open-Ended Evolution of Self-Improving Agents | arXiv 2025 | - | |
EvoMaster | EvoMaster: A Foundational Evolving Agent Framework for Agentic Science at Scale | arXiv 2026 | - | - |
Self-Driving Lab | Compressing the Validation Bottleneck: An Agentic Self-Driving Lab for Scientific Discovery | arXiv '26 | - | - |
Meta-Reflection | Autonomous Scientific Discovery via Iterative Meta-Reflection | arXiv '26 | - | - |
Project2Task | Project2Task: Graph-Guided Project-Level Planning for Autonomous Research | arXiv '26 | - | - |
Adaptive Inquiry | Beyond Solution-Centric Search: Adaptive Inquiry and Knowledge Revision for Autonomous ML Engineering | arXiv '26 | - | - |
CausalForge | CausalForge: A Formally Grounded, Self-Improving Agentic Framework for Automated Research in Causal Inference | arXiv '26 | - | - |
World-Model Scaling | Scaling Automatic Research Agents via World Models | arXiv '26 | - | - |
Research Preference Models | AI Research Preference Models | arXiv '26 | - | - |
Research Platforms & Infrastructure
In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
Symposium | Symposium: Trust via Auditable Records for Communities of AI Scientist Agents | arXiv 2026 | - | - |
Towards an AI co-scientist | Towards an AI co-scientist | arXiv 2025 | - | - |
PiFlow | PiFlow: Principle-aware Scientific Discovery with Multi-Agent Collaboration | arXiv 2025 | - | - |
LabClaw | - | Web 2026 | - | - |
| - | OpenAI Is Throwing Everything into Building a Fully Automated Researcher | MIT TR 2026 | | - |
XScientist | XScientist: A Git-Like Research Protocol for Long-Running Autonomous Scientific Discovery | arXiv '26 | - | - |
Auditable Records | From Trajectories to Evidence: Auditable Experimental Records for Industrial Research Agents | arXiv '26 | - | - |
PEARL | PEARL: Auditable Repair for Scientific Reasoning Graph Extraction | arXiv '26 | - | - |
IdeaTrail | IdeaTrail: Full-Process Agent Trajectories for Scientific Ideation | arXiv '26 | - | - |
EviGraph | EviGraph: Evidence-Guided Autonomous Research Agents | arXiv '26 | - | - |
Discovery Environments | Scaling Scientific Discovery Environments for Turn-Level Agentic RL | arXiv '26 | - | - |
Quantum Theorem Bench | Benchmarking Agents for Proving Theorems in Quantum Algorithms and Quantum Information | arXiv '26 | - | - |
SciDiscovery Readiness | Are LLMs Ready for Scientific Discovery? A Capability-Oriented Benchmark for AI Scientists | arXiv '26 | - | - |
ARAC | ARAC: Benchmarking Auto-Research's Alignment and Completeness on End-to-End Researchs | arXiv '26 | - | - |
Beyond Final Scores | Beyond Final Scores: A Systematic Evaluation of Agents for Long-Horizon AI Research and Development | arXiv '26 | - | - |
Replication Training | Training AI Scientists to Replicate Research | arXiv '26 | - | - |
Rubric Meta-Eval | Can LLMs Write Reliable Rubrics? A Meta-Evaluation for Experiment Reproduction | arXiv '26 | - | - |
Fast-Moving Domains | Adversarial Fast-Moving Real-World Domains as Test Beds for Benchmarking AI Scientist Capabilities | arXiv '26 | - | - |
AutoWorldModel-Bench | AutoWorldModel-Bench: A State-Centric Benchmark for Automated World-Model Research | arXiv '26 | - | - |
Scientific Memory | Beyond Memory Leaderboards: Evaluating Scientific Memory as Budgeted Context Restoration | arXiv '26 | - | - |
SciHazard | SciHazard: A Benchmark for Measuring Scientific Safety Risks with Decomposed Harm Scoring | arXiv '26 | - | - |
Science Edge Eval. | Science Edge Evaluation: SEE the Missing Step Toward Real Scientific Discovery | arXiv '26 | - | - |
10. Societal & Critical Perspectives
:timer_clock: In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
| - | Science Done on a Machine by a Machine: AI Agents in Computational Chemistry | arXiv 2026 | - | - |
| - | Bayesian Optimization for Self-Driving Materials Laboratories: From Algorithms to Physics-Informed Workflows | arXiv 2026 | - | - |
| - | LLM assisted writing deserves empirical evaluation | arXiv 2026 | - | - |
| - | A Metric with Positive Sectional Curvature on $S^2\times S^3$ | arXiv 2026 | - | - |
| - | Weak-Type Bounds for Convolution on the Boolean Hypercube | arXiv 2026 | - | - |
| - | Quo Vadis? Scientific Discovery in the Age of Artificial Intelligence | Theory of Science | - | - |
| - | Are LLMs becoming similarly creative? Evidence from three years of models | arXiv 2026 | - | - |
| - | Navigating the Jagged Technological Frontier | Org. Sci. 2025 | | - |
| - | Reassessing Academic Integrity in the Age of AI | SSH Open 2025 | | - |
The AI Deskilling Paradox | The AI Deskilling Paradox | CACM 2025 | | - |
Hidden Pitfalls of AI Scientist Systems | The More You Automate, the Less You See: Hidden Pitfalls of AI Scientist Systems | arXiv 2025 | - | - |
Rethinking Science in the Age of AI | Rethinking Science in the Age of Artificial Intelligence | arXiv 2025 | - | - |
| - | Measuring AI Ability to Complete Long Tasks | METR 2025 | | - |
| - | Towards a Science of Scaling Agent Systems | arXiv 2025 | - | - |
| - | Artificial Intelligence Tools Expand Scientists' Impact but Contract Science's Focus | Nature 2026 | | - |
| - | [](https://www.cell.com/patterns/fulltext/S2666-3899(25) AI for Scientific Discovery is a Social Problem | Patterns 2026 | [](https://www.cell.com/patterns/fulltext/S2666-3899(25) | - |
Research Integrity in the Age of AI | Research Integrity and Academic Authority in the Age of Artificial Intelligence: From Discovery to Curation? | arXiv 2026 | - | - |
SciSciGPT | SciSciGPT: Advancing Human-AI Collaboration in the Science of Science | Nature CS 2026 | | - |
SimStep | SimStep: Chain-of-Abstractions for Incremental Specification and Debugging of AI-Generated Interactive Simulations | arXiv 2025 | - | - |
ConvoLearn | ConvoLearn: A Learning Sciences Grounded Dataset for Fine-Tuning Dialogic AI Tutors | arXiv 2026 | - | - |
AFIM: Academic Fraud Inclination Metric | AFIM: Academic Fraud Inclination Metric | Web 2026 | | - |
| - | AI Researchers' Views on Automating AI R&D and Intelligence Explosions | arXiv 2026 | - | - |
| - | AI Scientists Are Changing Research | Nature 2026 | | - |
Learning by Creating (Talk) | Learning by Creating: A Human-Centered Vision for AI in Education | Talk 2026 | | - |
AI Sci. No Reasoning | AI scientists produce results without reasoning scientifically | arXiv 2026 | - | - |
Not Built for Autonomy | Agentic AI Scientists Are Not Built For Autonomous Scientific Discovery | arXiv 2026 | - | - |
Workflow != Closure | Workflow Closure Is Not Scientific Closure in Auto-Research Systems | arXiv 2026 | - | - |
PseudoBench | PseudoBench: Measuring How Agentic Auto-Research Fuels Pseudoscience | arXiv 2026 | - | - |
SciIntegrity-Bench | SciIntegrity-Bench: A Benchmark for Evaluating Academic Integrity in AI Scientist Systems | arXiv 2026 | - | - |
| - | Abduction Without a Body? Representational Grounding and the Abduction Loop for Scientific Hypothesis Generation | arXiv '26 | - | - |
| - | Visualizing Graph-to-Answer Mechanism Recovery in Materials-Science Hypothesis Generation | arXiv '26 | - | - |
| - | Generative AI use in Statistical Research: A Literature Review and Code Generation Case Study | arXiv '26 | - | - |
| - | AI's Capability in Assisting Scientific Research in Physics, Astrophysics, and Cosmology I: Literature Review | arXiv '26 | - | - |
| - | Scientific Knowledge Discovery in the Age of Large Language Models | arXiv '26 | - | - |
| - | Is Deep Research Reliable? Misleading Knowledge Induces False Conclusions | arXiv '26 | - | - |
| - | Diagnosing Search Behavior and Failure Modes in Long-Horizon Search Agents | arXiv '26 | - | - |
| - | A Pathway to General-Purpose Scientific AI: Multimodal Comprehension of Scientific Images | arXiv '26 | - | - |
| - | Position: AI Agents in Scientific Teams Should Be Studied as Human-Agent Systems | arXiv '26 | - | - |
| - | The Past and Future of AI Scientists | arXiv '26 | - | - |
| - | Efficiency Matters in Autonomous Research | arXiv '26 | - | - |
| - | Agentic Auto-Research is Fuzz Testing | arXiv '26 | - | - |
| - | Mechanist: AI as a Scientific Instrument for Discovering the Mechanisms of Intelligence | arXiv '26 | - | - |
| - | An AI Scientist that Doesn't Drift: Taste, Structure, and Falsifiable Findings in a Quadruped Navigation Research Loop | arXiv '26 | - | - |
| - | Long-Horizon Autonomous Architecture Research with a Language-Model Agent: A Behavioural Case Study | arXiv '26 | - | - |
| - | Stress-testing large language model agents in a robotic chemistry laboratory | arXiv '26 | - | - |
11. Surveys & Curated Lists
:timer_clock: In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
LLM4SR | LLM4SR: A Survey on Large Language Models for Scientific Research | arXiv 2025 | - | - |
From Automation to Autonomy | From Automation to Autonomy: A Survey on Large Language Models for Scientific Discovery | arXiv 2025 | - | - |
AI4Research | AI4Research: A Survey of Artificial Intelligence for Scientific Research | arXiv 2025 | - | - |
A Survey of AI Scientists | A Survey of AI Scientists | arXiv 2025 | - | - |
| - | Large Language Models for Scientific Idea Generation: A Creativity-Centered Survey | arXiv 2025 | - | - |
| - | Large Language Models for Automated Scholarly Paper Review: A Survey | Inf. Fusion 2025 | | - |
AutoResearch Survey | What's Missing in Autonomous Research? A Systematization of Systems, Benchmarks, and Verification | Web 2026 | | - |
12. Tools & GitHub Repos
Open-source tools, frameworks, and curated resource lists for AI-assisted research (not directly tied to a single paper).
Curated Lists
| Repository | Stars | Description |
|---|---|---|
| Awesome-Deep-Research | | Up-to-date collection of agentic deep research resources |
| Awesome-Scientific-Language-Models | | Survey of scientific LLMs (EMNLP'24) |
| Awesome-LLM-Scientific-Discovery | | Three-level autonomy framework (EMNLP'25) |
| Awesome-AI-Scientist-Papers | | Resources on AI Scientist systems |
| Awesome-Auto-Research-Tools | | Automated research tools catalog |
| awesome-autoresearch | | Autonomous improvement loops and research agents |
| awesome-ai-research-writing | | Prompt templates and agent skills for AI-assisted writing |
Idea Generation
| Repository | Stars | Description |
|---|---|---|
| Virtual-Scientists | | VirSci: multi-agent collaborative idea generation (ACL'25) |
| ResearchAgent | | Iterative idea proposal with reviewing agents |
Literature Review
| Repository | Stars | Description |
|---|---|---|
| paper-qa | | PaperQA2: superhuman RAG for scientific Q&A |
| local-deep-research | | Fully local deep research |
| researchgpt | | Conversational interaction with research papers |
| gpt-researcher | | Autonomous agent for comprehensive online research |
| AutoSurvey | | Automated comprehensive literature surveys |
| storm | | Wikipedia-style article generation (STORM) |
| lune-mcp-server | | MCP client for the hosted Lune Research corpus: paper search, citation traversal, evidence extraction, quote-backed claim verification (API key required) |
Coding & Experiments
| Repository | Stars | Description |
|---|---|---|
| autoresearch (Karpathy) | | Autonomous ML experiments, ~12 exp/hour overnight |
| Paper2Code | | Multi-agent ML paper to code transformation |
| RD-Agent | | Microsoft's LLM framework for autonomous data science |
| MLAgentBench | | 13 end-to-end ML experimentation tasks |
| SWE-bench | | Real-world GitHub issue resolution benchmark |
| Thoth | | Dashboard-first Claude Code and Codex runtime for durable autoresearch runs, work-item locks, ledgers, and reviewable verdicts |
Peer Review
| Repository | Stars | Description |
|---|---|---|
| paper-reviewer | | arXiv paper reviews + blog posts |
| ai-peer-review | | Multi-LLM reviews + meta-review synthesis |
| openreviewer | | Llama-8B fine-tuned on 79K expert reviews |
Last updated: 2026-08-31 · Maintained by WorldBench
Similar repos
Contributors
Languages
HTML
100.0%