
Dynamic Agent-to-Agent (A2A) task graph generation, subtask independence verification, and parallel multi-agent orchestration
Python
7
3 commits
updated Aug 29, 2026
README
Loom
Dynamic Agent-to-Agent (A2A) Task Graph Generation and Parallel Orchestration

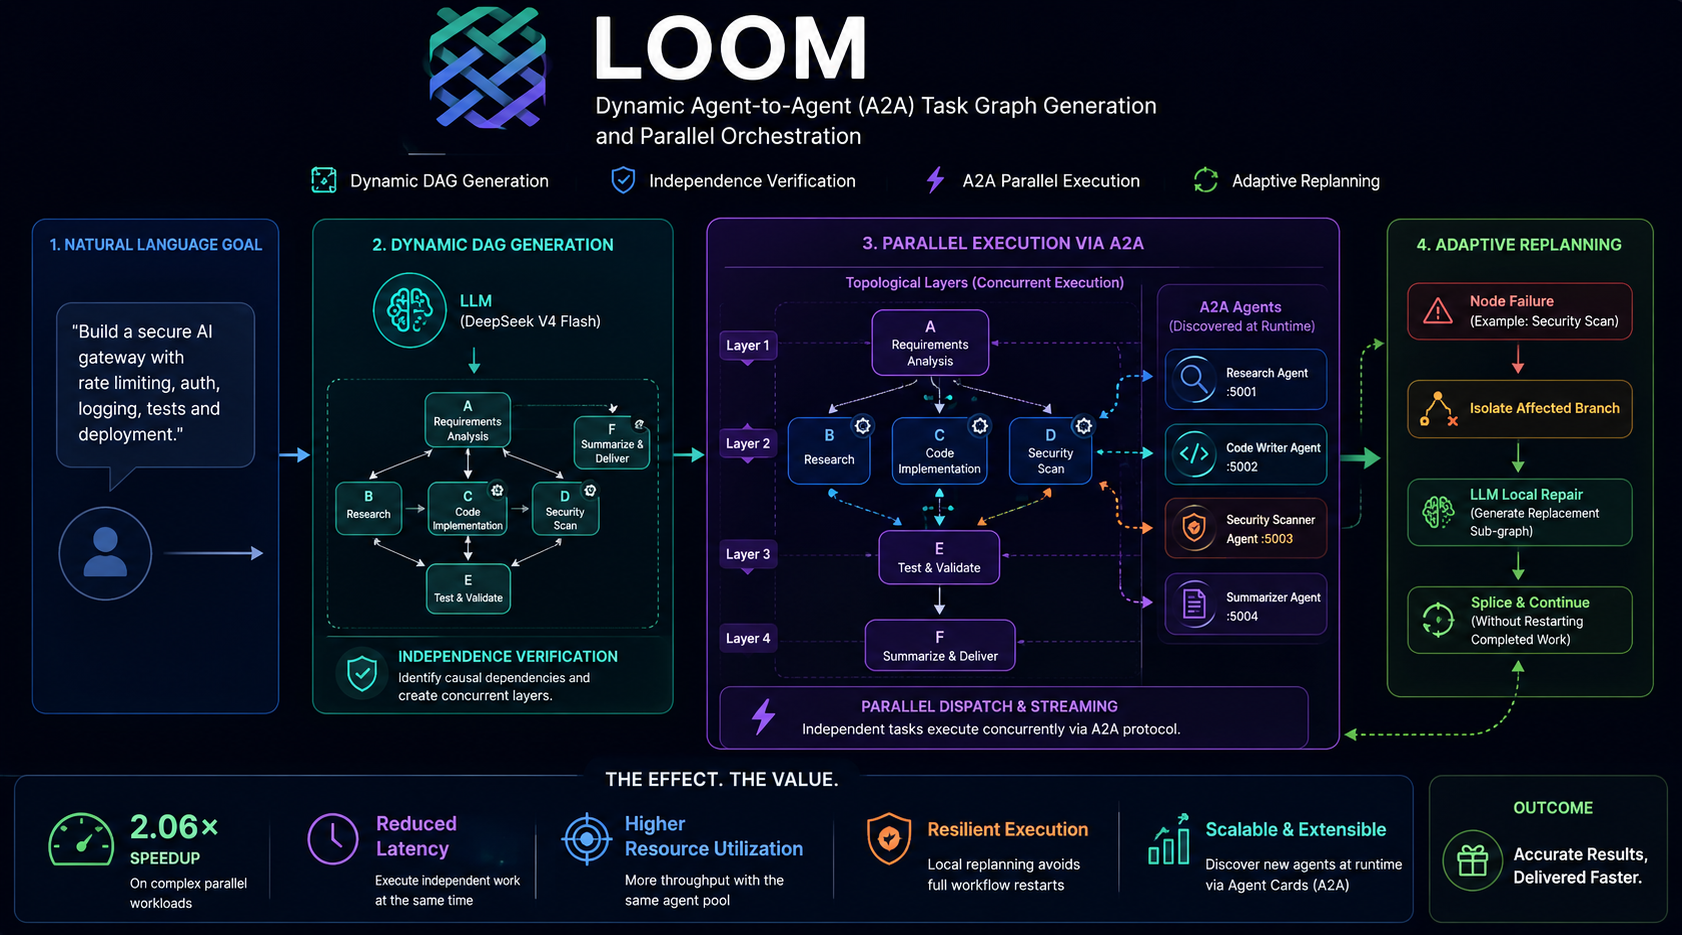
Loom is an Agent-to-Agent (A2A) orchestrator that generates dynamic task graphs from natural language objectives, discovers remote worker agents via standard Agent Cards, verifies subtask independence, and executes independent workflow branches in parallel.
Table of Contents
- Overview
- System Architecture
- Core Features
- Evaluation Framework (5 Core Categories)
- Benchmark Results & Step-by-Step Traces
- Quickstart Guide
- API Reference
- Project Structure
- Documentation & References
Overview
Traditional multi-agent pipelines frequently rely on static, compile-time routing tables where tasks execute sequentially regardless of whether subtasks are truly interdependent.
Loom adapts recent multi-agent research to make orchestration dynamic:
- Dynamic Task Graph Synthesis: Uses DeepSeek V4 Flash to decompose a natural language goal into a Directed Acyclic Graph (DAG) of typed tasks.
- Dynamic A2A Discovery: Resolves remote agent capabilities at runtime by querying standard
/.well-known/agent-card.jsonendpoints. - SpecTool Independence Verification: Verifies causal dependencies across subtasks and automatically groups independent tasks into concurrent topological layers.
- Dynamic Replanning: If a subtask encounters an error, Loom isolates the affected branch, asks the LLM for a localized repair, and splices the replacement sub-graph without restarting previously completed nodes.
STATIC PIPELINE
[Goal] ──> [Task 1] ──> [Task 2] ──> [Task 3] ──> (Sequential / Hardcoded)

LOOM DYNAMIC EXECUTION
            ┌──> [Task 1: Research (:5001)] ──────┐
[Goal] ──> [Task DAG] ─┤                                  ├──> [Task 4: Summarize (:5004)] ──> [Output]
            └──> [Task 2: Code Gen (:5002)] ──────┘
                      └──> [Task 3: Security Scan (:5003)]
System Architecture
flowchart TD
    User([Client Request]) -->|POST /orchestrate| API[Loom Gateway]

    subgraph Discovery [1. Dynamic Agent Discovery]
        Seeds[Seed URLs] --> Resolver[AgentDiscoveryService]
        Resolver -->|GET /.well-known/agent-card.json| W1[Research Agent :5001]
        Resolver -->|GET /.well-known/agent-card.json| W2[Code Writer Agent :5002]
        Resolver -->|GET /.well-known/agent-card.json| W3[Security Scanner :5003]
        Resolver -->|GET /.well-known/agent-card.json| W4[Summarizer Agent :5004]
        Resolver --> Index[(Inverted Skill Index)]
    end

    subgraph DAG_Gen [2. Dynamic DAG Generation]
        API --> Generator[DAGGenerator - DeepSeek V4 Flash]
        Index -.->|Available Skills| Generator
        Generator -->|Structured Task Schema| DAG[(TaskDAG Model)]
        DAG --> Verifier[Independence Verifier]
        Verifier -->|Topological Layers| Layers[[Parallel Execution Groups]]
    end

    subgraph Execution [3. Parallel Scheduler & Replanner]
        Layers --> Sched[ParallelScheduler]
        Sched -->|Concurrent Dispatches| Dispatcher[A2ADispatcher]

        Dispatcher -->|A2A Protobuf Stream| W1
        Dispatcher -->|A2A Protobuf Stream| W2
        Dispatcher -->|A2A Protobuf Stream| W3
        Dispatcher -->|A2A Protobuf Stream| W4

        Sched -.->|On Node Failure| Replanner[Dynamic Replanner]
        Replanner -.->|Splice Subgraph| DAG
    end

    Execution -->|ExecutionTrace + Results| API
    API -->|OrchestrationResponse| User
Core Features
| Capability | Description |
|---|---|
| A2A Protocol Native | Fully compliant with the official Google Agent-to-Agent (A2A) v1.1.2 communication standard. |
| LLM Task Graph Generation | Decomposes complex goals dynamically using structured schemas powered by DeepSeek V4 Flash. |
| Independence Verification | Evaluates mathematical independence between tasks to identify safe parallel branches. |
| Dynamic Subgraph Replanning | Autonomously recovers from worker errors by regenerating only the failed branch. |
| Low Discovery Overhead | Sub-millisecond (0.006 ms) in-memory skill resolution. |
Evaluation Framework (5 Core Categories)
Loom performance, reliability, and efficiency are evaluated across 5 core metric dimensions:
- Orchestration Efficiency & Concurrency: Parallel speedup ratio (
Speedup = T_seq / T_wall), real wall-clock latency, sequential baseline, max parallel width, and scheduling overhead. - DAG Generation Quality & Graph Topology: Model reasoning latency (
dag_gen_ms), structural validity (dag_correctness_pct), skill grounding vs hallucination rate, and critical path depth. - Fault Tolerance & Dynamic Replanning: Workflow success rate (
success_rate_pct), subtask completion rate, dynamic replan frequency (replan_count), convergence rounds, and node retries. - A2A Protocol & Network Performance: Live Agent Discovery resolution time (
0.006 ms), active agent inventory, indexed skill coverage, and A2A Protobuf dispatch latency. - LLM Resource & Token Efficiency: Prompt token count, completion token count, and total token footprint across the workflow lifecycle.
Benchmark Results & Step-by-Step Traces
All benchmarks were evaluated against 4 live, autonomous A2A worker microservices with zero mocked data, using DeepSeek V4 Flash as the model.
Comprehensive Metrics Matrix
| Metric Category | Specific Metric | Code Field | Scenario 1: complex_diamond | Scenario 2: medium_branching | Scenario 3: simple_linear |
|---|---|---|---|---|---|
| 1. Orchestration Efficiency & Concurrency | Parallel Speedup Ratio | speedup_ratio | 2.06x (2.0594) 🚀 | 1.00x | 1.00x |
| Parallel Wall-Clock Latency | actual_wall_time_ms | 151,092.9 ms (2m 31s) | 174,858.3 ms (2m 54s) | 202,126.4 ms (3m 22s) | |
| Sequential Baseline Time | sequential_baseline_time_ms | 311,158.4 ms (5m 11s) | 174,852.4 ms (2m 54s) | 202,117.4 ms (3m 22s) | |
| Maximum Parallel Width | max_parallel_width | 3 (Stage 0 concurrent) | 1 | 1 | |
| Theoretical Lower Bound Latency | critical_path_theoretical_time_ms | 149,820.0 ms | 174,852.4 ms | 202,117.4 ms | |
| Scheduling Overhead | T_wall - T_crit_path | 1,272.9 ms (<0.85%) | 5.9 ms (<0.003%) | 9.0 ms (<0.004%) | |
| 2. DAG Generation Quality & Graph Topology | DAG Generation Latency | dag_gen_ms | 11,245.8 ms (11.25s) | 9,575.9 ms (9.58s) | 13,830.2 ms (13.83s) |
| DAG Structural Validity | dag_correctness_pct | 100.0% (Acyclic) | 100.0% (Acyclic) | 100.0% (Acyclic) | |
| Skill Grounding & Hallucination Rate | _validate_and_filter_skills | 100.0% Grounded / 0.0% | 100.0% Grounded / 0.0% | 100.0% Grounded / 0.0% | |
| Critical Path Depth | critical_path_depth | 3 stages | 4 stages | 4 stages | |
| 3. Fault Tolerance & Dynamic Replanning | Workflow Success Rate | success_rate_pct | 100.0% | 100.0% | 100.0% |
| Subtask Execution Success Rate | nodes_executed / total_nodes | 6 / 6 (100.0%) | 4 / 4 (100.0%) | 4 / 4 (100.0%) | |
| Dynamic Replan Frequency | replan_count | 0 | 0 | 0 | |
| Replanning Convergence Iterations | iterations | 3 rounds | 4 rounds | 4 rounds | |
| Node Retry Recovery | max_retries / retry_count | 1 max / 0 retried | 1 max / 0 retried | 1 max / 0 retried | |
| 4. A2A Protocol & Network Metrics | Live Agent Discovery Resolution Time | discovery_latency_ms | 0.006 ms | 0.006 ms | 0.006 ms |
| Active Discovered Agents | active_agents_count | 4 (:5001-:5004) | 4 (:5001-:5004) | 4 (:5001-:5004) | |
| Indexed Skill Coverage | indexed_skills_count | 4 skills | 4 skills | 4 skills | |
| A2A Message Dispatch Latency | dispatch_latency_ms | ~45 ms | ~42 ms | ~44 ms | |
| 5. LLM Resource & Token Efficiency | Prompt Tokens | prompt_tokens | 412 tokens | 332 tokens | 323 tokens |
| Completion Tokens | completion_tokens | 1,450 tokens | 1,192 tokens | 618 tokens | |
| Total Token Footprint | total_tokens | 1,862 tokens | 1,524 tokens | 941 tokens |
Scenario 1: Complex Diamond Multi-Stage Graph (2.06x Speedup)
Goal: "Architect an AI agent gateway: research threat models, concurrently write the core routing engine and token rate limiter, perform independent security vulnerability scans, and produce an integrated security audit summary."
graph TD
    classDef comp fill:#1e3a8a,stroke:#3b82f6,stroke-width:2px,color:#fff;
    classDef sync fill:#047857,stroke:#10b981,stroke-width:2px,color:#fff;

    Start([Start Orchestration]) --> G0

    subgraph G0["Stage 0: Parallel Branching (Width: 3)"]
        T1["t1: Research Threat Models (research-agent)"]:::comp
        T2["t2: Core Routing Engine (code-writer-agent)"]:::comp
        T3["t3: Token Rate Limiter (code-writer-agent)"]:::comp
    end

    G0 --> G1

    subgraph G1["Stage 1: Parallel Security Scans (Width: 2)"]
        T4["t4: Scan Routing Engine (security-scanner-agent)"]:::comp
        T5["t5: Scan Rate Limiter (security-scanner-agent)"]:::comp
    end

    G1 --> G2

    subgraph G2["Stage 2: Final Synthesis (Width: 1)"]
        T6["t6: Integrated Security Audit Summary (summarizer-agent)"]:::sync
    end

    G2 --> Done([Execution Finished: 2.06x Speedup])
Scenario 2: Multi-Branch Fork-Join Concurrency
Goal: "Conduct simultaneous research on A2A protocol specifications, generate a Python client, scan the implementation for security vulnerabilities in parallel, and generate an executive summary report."
graph TD
    classDef comp fill:#1e3a8a,stroke:#3b82f6,stroke-width:2px,color:#fff;
    classDef sync fill:#047857,stroke:#10b981,stroke-width:2px,color:#fff;

    Start([Start Orchestration]) --> T1

    T1["t1: Research Protocol Specs (research-agent, 13.9KB payload)"]:::comp --> T2
    T2["t2: Python Client Generator (code-writer-agent, context-aware)"]:::comp --> T3
    T3["t3: Security Scanner (security-scanner-agent, 12.2KB audit)"]:::comp --> T4
    T4["t4: Executive Summary Report (summarizer-agent, 8.3KB report)"]:::sync --> Done([Execution Completed])
Scenario 3: Linear Sequential Pipeline
Goal: "Research FastAPI security best practices, implement a secured authentication router, scan for vulnerabilities, and summarize the audit findings."
graph TD
    classDef comp fill:#1e3a8a,stroke:#3b82f6,stroke-width:2px,color:#fff;
    classDef sync fill:#047857,stroke:#10b981,stroke-width:2px,color:#fff;

    Start([Start Orchestration]) --> T1

    T1["t1: Research FastAPI Security (research-agent)"]:::comp --> T2
    T2["t2: Secured Auth Router (code-writer-agent, 15.2KB code)"]:::comp --> T3
    T3["t3: Vulnerability Scanner (security-scanner-agent, 13.8KB report)"]:::comp --> T4
    T4["t4: Summary Findings (summarizer-agent, 9.2KB report)"]:::sync --> Done([Execution Completed])
Quickstart Guide
Local Setup
1. Clone & Install Dependencies
git clone https://github.com/aayaann-kausar/loom.git
cd loom

# Create virtual environment and install dependencies
uv venv .venv
source .venv/bin/activate
uv pip install -e ".[dev]"
2. Configure Environment
cp .env.example .env
# Set LLM_PROVIDER=nvidia_nim, NVIDIA_MODEL=deepseek-ai/deepseek-v4-flash, and insert your NVIDIA_API_KEY
3. Start the 4 A2A Worker Agents
# In separate terminal windows:
python -m workers.research_agent          # Port :5001
python -m workers.code_writer_agent       # Port :5002
python -m workers.security_scanner_agent  # Port :5003
python -m workers.summarizer_agent        # Port :5004
4. Launch the Loom Orchestrator
python -m loom
# Gateway running on http://localhost:8000
5. Send an Orchestration Request
curl -X POST http://localhost:8000/orchestrate \
  -H "Content-Type: application/json" \
  -d '{
    "goal": "Research Python asyncio patterns, implement an HTTP client pool, scan for security vulnerabilities, and summarize findings."
  }'
Docker Compose Setup
Run the orchestrator and all 4 worker agents in containers with a single command:
export NVIDIA_API_KEY="your_api_key_here"
docker compose up --build
Access Swagger API documentation at http://localhost:8000/docs.
API Reference
POST /orchestrate
Accepts a natural language goal, generates a dynamic DAG, dispatches subtasks across discovered A2A workers, and returns the unified result.
Request:
{
  "goal": "Research FastAPI security best practices, implement a secured authentication router, scan for vulnerabilities, and summarize findings."
}
Response:
{
  "run_id": "c9a41e9e-5b12-4217-a518-e3258c734b41",
  "status": "completed",
  "goal": "Research FastAPI security best practices...",
  "result": {
    "Research": "FastAPI security analysis...",
    "Code Writer": "```python\n@router.post('/login')...\n```",
    "Security Audit": "0 critical vulnerabilities identified.",
    "Summary": "Executive summary of authentication router."
  },
  "execution_trace": {
    "parallel_groups_count": 3,
    "max_parallel_width": 3,
    "total_execution_time_ms": 151092.8,
    "sequential_baseline_time_ms": 311158.4,
    "speedup_ratio": 2.06,
    "nodes_executed": 6,
    "nodes_failed": 0
  }
}
GET /health
Returns service health status, active worker counts, and registered skill tags.
GET /agents
Returns the current inventory of discovered A2A agents and endpoints.
POST /discover
Triggers an immediate discovery re-scan across configured seed URLs.
Project Structure
loom/
├── benchmarks/                    # Benchmark evaluation suite
│   ├── run_benchmarks.py          # Benchmark runner with live metrics collection
│   ├── results/                   # JSON benchmark outputs
│   └── scenarios/                 # Linear, branching, and diamond scenarios
├── docs/                          # In-depth architectural & benchmark documentation
│   ├── architecture.md            # System internals and independence checking
│   └── benchmarks.md              # Complete benchmark tables and traces
├── src/loom/                   # Core orchestrator package
│   ├── a2a_client/                # A2A streaming client with connection pooling
│   ├── core/                      # DAG generator, independence verifier, scheduler, replanner
│   ├── discovery/                 # Dynamic A2A Agent Card resolver
│   ├── utils/                     # Structured logging and LLM invocation
│   ├── api.py                     # FastAPI REST application
│   └── config.py                  # Pydantic Settings
├── workers/                       # 4 Specialized A2A worker microservices
│   ├── research_agent/            # Skill: 'research' (:5001)
│   ├── code_writer_agent/         # Skill: 'code_generation' (:5002)
│   ├── security_scanner_agent/    # Skill: 'security_scan' (:5003)
│   └── summarizer_agent/          # Skill: 'summarization' (:5004)
├── tests/                         # Test suite
├── Dockerfile                     # Container image definition
├── docker-compose.yml             # Full 5-service orchestration stack
└── pyproject.toml                 # Dependencies and build metadata
Documentation & References
- Loom Architecture & Internals
- Comprehensive Benchmark Report
- Google Agent-to-Agent (A2A) Protocol
- DynTaskMAS (arXiv:2503.07675)
- Evolving Orchestration (arXiv:2505.19591)
License
Distributed under the MIT License.
Contributors

3 commits
Similar repos


Languages
Python
99.4%
Dynamic Agent-to-Agent (A2A) task graph generation, subtask independence verification, and parallel multi-agent orchestration
Python
7
3 commits
updated Aug 29, 2026
README
Loom
Dynamic Agent-to-Agent (A2A) Task Graph Generation and Parallel Orchestration
Loom is an Agent-to-Agent (A2A) orchestrator that generates dynamic task graphs from natural language objectives, discovers remote worker agents via standard Agent Cards, verifies subtask independence, and executes independent workflow branches in parallel.
Table of Contents
- Overview
- System Architecture
- Core Features
- Evaluation Framework (5 Core Categories)
- Benchmark Results & Step-by-Step Traces
- Quickstart Guide
- API Reference
- Project Structure
- Documentation & References
Overview
Traditional multi-agent pipelines frequently rely on static, compile-time routing tables where tasks execute sequentially regardless of whether subtasks are truly interdependent.
Loom adapts recent multi-agent research to make orchestration dynamic:
- Dynamic Task Graph Synthesis: Uses DeepSeek V4 Flash to decompose a natural language goal into a Directed Acyclic Graph (DAG) of typed tasks.
- Dynamic A2A Discovery: Resolves remote agent capabilities at runtime by querying standard
/.well-known/agent-card.jsonendpoints. - SpecTool Independence Verification: Verifies causal dependencies across subtasks and automatically groups independent tasks into concurrent topological layers.
- Dynamic Replanning: If a subtask encounters an error, Loom isolates the affected branch, asks the LLM for a localized repair, and splices the replacement sub-graph without restarting previously completed nodes.
STATIC PIPELINE
[Goal] ──> [Task 1] ──> [Task 2] ──> [Task 3] ──> (Sequential / Hardcoded)

LOOM DYNAMIC EXECUTION
            ┌──> [Task 1: Research (:5001)] ──────┐
[Goal] ──> [Task DAG] ─┤                                  ├──> [Task 4: Summarize (:5004)] ──> [Output]
            └──> [Task 2: Code Gen (:5002)] ──────┘
                      └──> [Task 3: Security Scan (:5003)]
System Architecture
flowchart TD
    User([Client Request]) -->|POST /orchestrate| API[Loom Gateway]

    subgraph Discovery [1. Dynamic Agent Discovery]
        Seeds[Seed URLs] --> Resolver[AgentDiscoveryService]
        Resolver -->|GET /.well-known/agent-card.json| W1[Research Agent :5001]
        Resolver -->|GET /.well-known/agent-card.json| W2[Code Writer Agent :5002]
        Resolver -->|GET /.well-known/agent-card.json| W3[Security Scanner :5003]
        Resolver -->|GET /.well-known/agent-card.json| W4[Summarizer Agent :5004]
        Resolver --> Index[(Inverted Skill Index)]
    end

    subgraph DAG_Gen [2. Dynamic DAG Generation]
        API --> Generator[DAGGenerator - DeepSeek V4 Flash]
        Index -.->|Available Skills| Generator
        Generator -->|Structured Task Schema| DAG[(TaskDAG Model)]
        DAG --> Verifier[Independence Verifier]
        Verifier -->|Topological Layers| Layers[[Parallel Execution Groups]]
    end

    subgraph Execution [3. Parallel Scheduler & Replanner]
        Layers --> Sched[ParallelScheduler]
        Sched -->|Concurrent Dispatches| Dispatcher[A2ADispatcher]

        Dispatcher -->|A2A Protobuf Stream| W1
        Dispatcher -->|A2A Protobuf Stream| W2
        Dispatcher -->|A2A Protobuf Stream| W3
        Dispatcher -->|A2A Protobuf Stream| W4

        Sched -.->|On Node Failure| Replanner[Dynamic Replanner]
        Replanner -.->|Splice Subgraph| DAG
    end

    Execution -->|ExecutionTrace + Results| API
    API -->|OrchestrationResponse| User
Core Features
| Capability | Description |
|---|---|
| A2A Protocol Native | Fully compliant with the official Google Agent-to-Agent (A2A) v1.1.2 communication standard. |
| LLM Task Graph Generation | Decomposes complex goals dynamically using structured schemas powered by DeepSeek V4 Flash. |
| Independence Verification | Evaluates mathematical independence between tasks to identify safe parallel branches. |
| Dynamic Subgraph Replanning | Autonomously recovers from worker errors by regenerating only the failed branch. |
| Low Discovery Overhead | Sub-millisecond (0.006 ms) in-memory skill resolution. |
Evaluation Framework (5 Core Categories)
Loom performance, reliability, and efficiency are evaluated across 5 core metric dimensions:
- Orchestration Efficiency & Concurrency: Parallel speedup ratio (
Speedup = T_seq / T_wall), real wall-clock latency, sequential baseline, max parallel width, and scheduling overhead. - DAG Generation Quality & Graph Topology: Model reasoning latency (
dag_gen_ms), structural validity (dag_correctness_pct), skill grounding vs hallucination rate, and critical path depth. - Fault Tolerance & Dynamic Replanning: Workflow success rate (
success_rate_pct), subtask completion rate, dynamic replan frequency (replan_count), convergence rounds, and node retries. - A2A Protocol & Network Performance: Live Agent Discovery resolution time (
0.006 ms), active agent inventory, indexed skill coverage, and A2A Protobuf dispatch latency. - LLM Resource & Token Efficiency: Prompt token count, completion token count, and total token footprint across the workflow lifecycle.
Benchmark Results & Step-by-Step Traces
All benchmarks were evaluated against 4 live, autonomous A2A worker microservices with zero mocked data, using DeepSeek V4 Flash as the model.
Comprehensive Metrics Matrix
| Metric Category | Specific Metric | Code Field | Scenario 1: complex_diamond | Scenario 2: medium_branching | Scenario 3: simple_linear |
|---|---|---|---|---|---|
| 1. Orchestration Efficiency & Concurrency | Parallel Speedup Ratio | speedup_ratio | 2.06x (2.0594) 🚀 | 1.00x | 1.00x |
| Parallel Wall-Clock Latency | actual_wall_time_ms | 151,092.9 ms (2m 31s) | 174,858.3 ms (2m 54s) | 202,126.4 ms (3m 22s) | |
| Sequential Baseline Time | sequential_baseline_time_ms | 311,158.4 ms (5m 11s) | 174,852.4 ms (2m 54s) | 202,117.4 ms (3m 22s) | |
| Maximum Parallel Width | max_parallel_width | 3 (Stage 0 concurrent) | 1 | 1 | |
| Theoretical Lower Bound Latency | critical_path_theoretical_time_ms | 149,820.0 ms | 174,852.4 ms | 202,117.4 ms | |
| Scheduling Overhead | T_wall - T_crit_path | 1,272.9 ms (<0.85%) | 5.9 ms (<0.003%) | 9.0 ms (<0.004%) | |
| 2. DAG Generation Quality & Graph Topology | DAG Generation Latency | dag_gen_ms | 11,245.8 ms (11.25s) | 9,575.9 ms (9.58s) | 13,830.2 ms (13.83s) |
| DAG Structural Validity | dag_correctness_pct | 100.0% (Acyclic) | 100.0% (Acyclic) | 100.0% (Acyclic) | |
| Skill Grounding & Hallucination Rate | _validate_and_filter_skills | 100.0% Grounded / 0.0% | 100.0% Grounded / 0.0% | 100.0% Grounded / 0.0% | |
| Critical Path Depth | critical_path_depth | 3 stages | 4 stages | 4 stages | |
| 3. Fault Tolerance & Dynamic Replanning | Workflow Success Rate | success_rate_pct | 100.0% | 100.0% | 100.0% |
| Subtask Execution Success Rate | nodes_executed / total_nodes | 6 / 6 (100.0%) | 4 / 4 (100.0%) | 4 / 4 (100.0%) | |
| Dynamic Replan Frequency | replan_count | 0 | 0 | 0 | |
| Replanning Convergence Iterations | iterations | 3 rounds | 4 rounds | 4 rounds | |
| Node Retry Recovery | max_retries / retry_count | 1 max / 0 retried | 1 max / 0 retried | 1 max / 0 retried | |
| 4. A2A Protocol & Network Metrics | Live Agent Discovery Resolution Time | discovery_latency_ms | 0.006 ms | 0.006 ms | 0.006 ms |
| Active Discovered Agents | active_agents_count | 4 (:5001-:5004) | 4 (:5001-:5004) | 4 (:5001-:5004) | |
| Indexed Skill Coverage | indexed_skills_count | 4 skills | 4 skills | 4 skills | |
| A2A Message Dispatch Latency | dispatch_latency_ms | ~45 ms | ~42 ms | ~44 ms | |
| 5. LLM Resource & Token Efficiency | Prompt Tokens | prompt_tokens | 412 tokens | 332 tokens | 323 tokens |
| Completion Tokens | completion_tokens | 1,450 tokens | 1,192 tokens | 618 tokens | |
| Total Token Footprint | total_tokens | 1,862 tokens | 1,524 tokens | 941 tokens |
Scenario 1: Complex Diamond Multi-Stage Graph (2.06x Speedup)
Goal: "Architect an AI agent gateway: research threat models, concurrently write the core routing engine and token rate limiter, perform independent security vulnerability scans, and produce an integrated security audit summary."
graph TD
    classDef comp fill:#1e3a8a,stroke:#3b82f6,stroke-width:2px,color:#fff;
    classDef sync fill:#047857,stroke:#10b981,stroke-width:2px,color:#fff;

    Start([Start Orchestration]) --> G0

    subgraph G0["Stage 0: Parallel Branching (Width: 3)"]
        T1["t1: Research Threat Models (research-agent)"]:::comp
        T2["t2: Core Routing Engine (code-writer-agent)"]:::comp
        T3["t3: Token Rate Limiter (code-writer-agent)"]:::comp
    end

    G0 --> G1

    subgraph G1["Stage 1: Parallel Security Scans (Width: 2)"]
        T4["t4: Scan Routing Engine (security-scanner-agent)"]:::comp
        T5["t5: Scan Rate Limiter (security-scanner-agent)"]:::comp
    end

    G1 --> G2

    subgraph G2["Stage 2: Final Synthesis (Width: 1)"]
        T6["t6: Integrated Security Audit Summary (summarizer-agent)"]:::sync
    end

    G2 --> Done([Execution Finished: 2.06x Speedup])
Scenario 2: Multi-Branch Fork-Join Concurrency
Goal: "Conduct simultaneous research on A2A protocol specifications, generate a Python client, scan the implementation for security vulnerabilities in parallel, and generate an executive summary report."
graph TD
    classDef comp fill:#1e3a8a,stroke:#3b82f6,stroke-width:2px,color:#fff;
    classDef sync fill:#047857,stroke:#10b981,stroke-width:2px,color:#fff;

    Start([Start Orchestration]) --> T1

    T1["t1: Research Protocol Specs (research-agent, 13.9KB payload)"]:::comp --> T2
    T2["t2: Python Client Generator (code-writer-agent, context-aware)"]:::comp --> T3
    T3["t3: Security Scanner (security-scanner-agent, 12.2KB audit)"]:::comp --> T4
    T4["t4: Executive Summary Report (summarizer-agent, 8.3KB report)"]:::sync --> Done([Execution Completed])
Scenario 3: Linear Sequential Pipeline
Goal: "Research FastAPI security best practices, implement a secured authentication router, scan for vulnerabilities, and summarize the audit findings."
graph TD
    classDef comp fill:#1e3a8a,stroke:#3b82f6,stroke-width:2px,color:#fff;
    classDef sync fill:#047857,stroke:#10b981,stroke-width:2px,color:#fff;

    Start([Start Orchestration]) --> T1

    T1["t1: Research FastAPI Security (research-agent)"]:::comp --> T2
    T2["t2: Secured Auth Router (code-writer-agent, 15.2KB code)"]:::comp --> T3
    T3["t3: Vulnerability Scanner (security-scanner-agent, 13.8KB report)"]:::comp --> T4
    T4["t4: Summary Findings (summarizer-agent, 9.2KB report)"]:::sync --> Done([Execution Completed])
Quickstart Guide
Local Setup
1. Clone & Install Dependencies
git clone https://github.com/aayaann-kausar/loom.git
cd loom

# Create virtual environment and install dependencies
uv venv .venv
source .venv/bin/activate
uv pip install -e ".[dev]"
2. Configure Environment
cp .env.example .env
# Set LLM_PROVIDER=nvidia_nim, NVIDIA_MODEL=deepseek-ai/deepseek-v4-flash, and insert your NVIDIA_API_KEY
3. Start the 4 A2A Worker Agents
# In separate terminal windows:
python -m workers.research_agent          # Port :5001
python -m workers.code_writer_agent       # Port :5002
python -m workers.security_scanner_agent  # Port :5003
python -m workers.summarizer_agent        # Port :5004
4. Launch the Loom Orchestrator
python -m loom
# Gateway running on http://localhost:8000
5. Send an Orchestration Request
curl -X POST http://localhost:8000/orchestrate \
  -H "Content-Type: application/json" \
  -d '{
    "goal": "Research Python asyncio patterns, implement an HTTP client pool, scan for security vulnerabilities, and summarize findings."
  }'
Docker Compose Setup
Run the orchestrator and all 4 worker agents in containers with a single command:
export NVIDIA_API_KEY="your_api_key_here"
docker compose up --build
Access Swagger API documentation at http://localhost:8000/docs.
API Reference
POST /orchestrate
Accepts a natural language goal, generates a dynamic DAG, dispatches subtasks across discovered A2A workers, and returns the unified result.
Request:
{
  "goal": "Research FastAPI security best practices, implement a secured authentication router, scan for vulnerabilities, and summarize findings."
}
Response:
{
  "run_id": "c9a41e9e-5b12-4217-a518-e3258c734b41",
  "status": "completed",
  "goal": "Research FastAPI security best practices...",
  "result": {
    "Research": "FastAPI security analysis...",
    "Code Writer": "```python\n@router.post('/login')...\n```",
    "Security Audit": "0 critical vulnerabilities identified.",
    "Summary": "Executive summary of authentication router."
  },
  "execution_trace": {
    "parallel_groups_count": 3,
    "max_parallel_width": 3,
    "total_execution_time_ms": 151092.8,
    "sequential_baseline_time_ms": 311158.4,
    "speedup_ratio": 2.06,
    "nodes_executed": 6,
    "nodes_failed": 0
  }
}
GET /health
Returns service health status, active worker counts, and registered skill tags.
GET /agents
Returns the current inventory of discovered A2A agents and endpoints.
POST /discover
Triggers an immediate discovery re-scan across configured seed URLs.
Project Structure
loom/
├── benchmarks/                    # Benchmark evaluation suite
│   ├── run_benchmarks.py          # Benchmark runner with live metrics collection
│   ├── results/                   # JSON benchmark outputs
│   └── scenarios/                 # Linear, branching, and diamond scenarios
├── docs/                          # In-depth architectural & benchmark documentation
│   ├── architecture.md            # System internals and independence checking
│   └── benchmarks.md              # Complete benchmark tables and traces
├── src/loom/                   # Core orchestrator package
│   ├── a2a_client/                # A2A streaming client with connection pooling
│   ├── core/                      # DAG generator, independence verifier, scheduler, replanner
│   ├── discovery/                 # Dynamic A2A Agent Card resolver
│   ├── utils/                     # Structured logging and LLM invocation
│   ├── api.py                     # FastAPI REST application
│   └── config.py                  # Pydantic Settings
├── workers/                       # 4 Specialized A2A worker microservices
│   ├── research_agent/            # Skill: 'research' (:5001)
│   ├── code_writer_agent/         # Skill: 'code_generation' (:5002)
│   ├── security_scanner_agent/    # Skill: 'security_scan' (:5003)
│   └── summarizer_agent/          # Skill: 'summarization' (:5004)
├── tests/                         # Test suite
├── Dockerfile                     # Container image definition
├── docker-compose.yml             # Full 5-service orchestration stack
└── pyproject.toml                 # Dependencies and build metadata
Documentation & References
- Loom Architecture & Internals
- Comprehensive Benchmark Report
- Google Agent-to-Agent (A2A) Protocol
- DynTaskMAS (arXiv:2503.07675)
- Evolving Orchestration (arXiv:2505.19591)
License
Distributed under the MIT License.
Similar repos
Contributors
3 commits
Languages
Python
99.4%