
Implementation of "FLUX-Text: A Simple and Advanced Diffusion Transformer Baseline for Scene Text Editing"
Python
923
0 commits
updated Nov 24, 2025
README
Implementation of FLUX-Text
FLUX-Text: A Simple and Advanced Diffusion Transformer Baseline for Scene Text Editing


Rui Lan1, Yancheng Bai1, Xu Duan1, Mingxing Li1, Dongyang Jin1, Ryan Xu1, Dong Nie2, Lei Sun1, Xiangxiang Chu1
1ALibaba Group 2University of North Carolina at Chapel Hill
📖 Overview
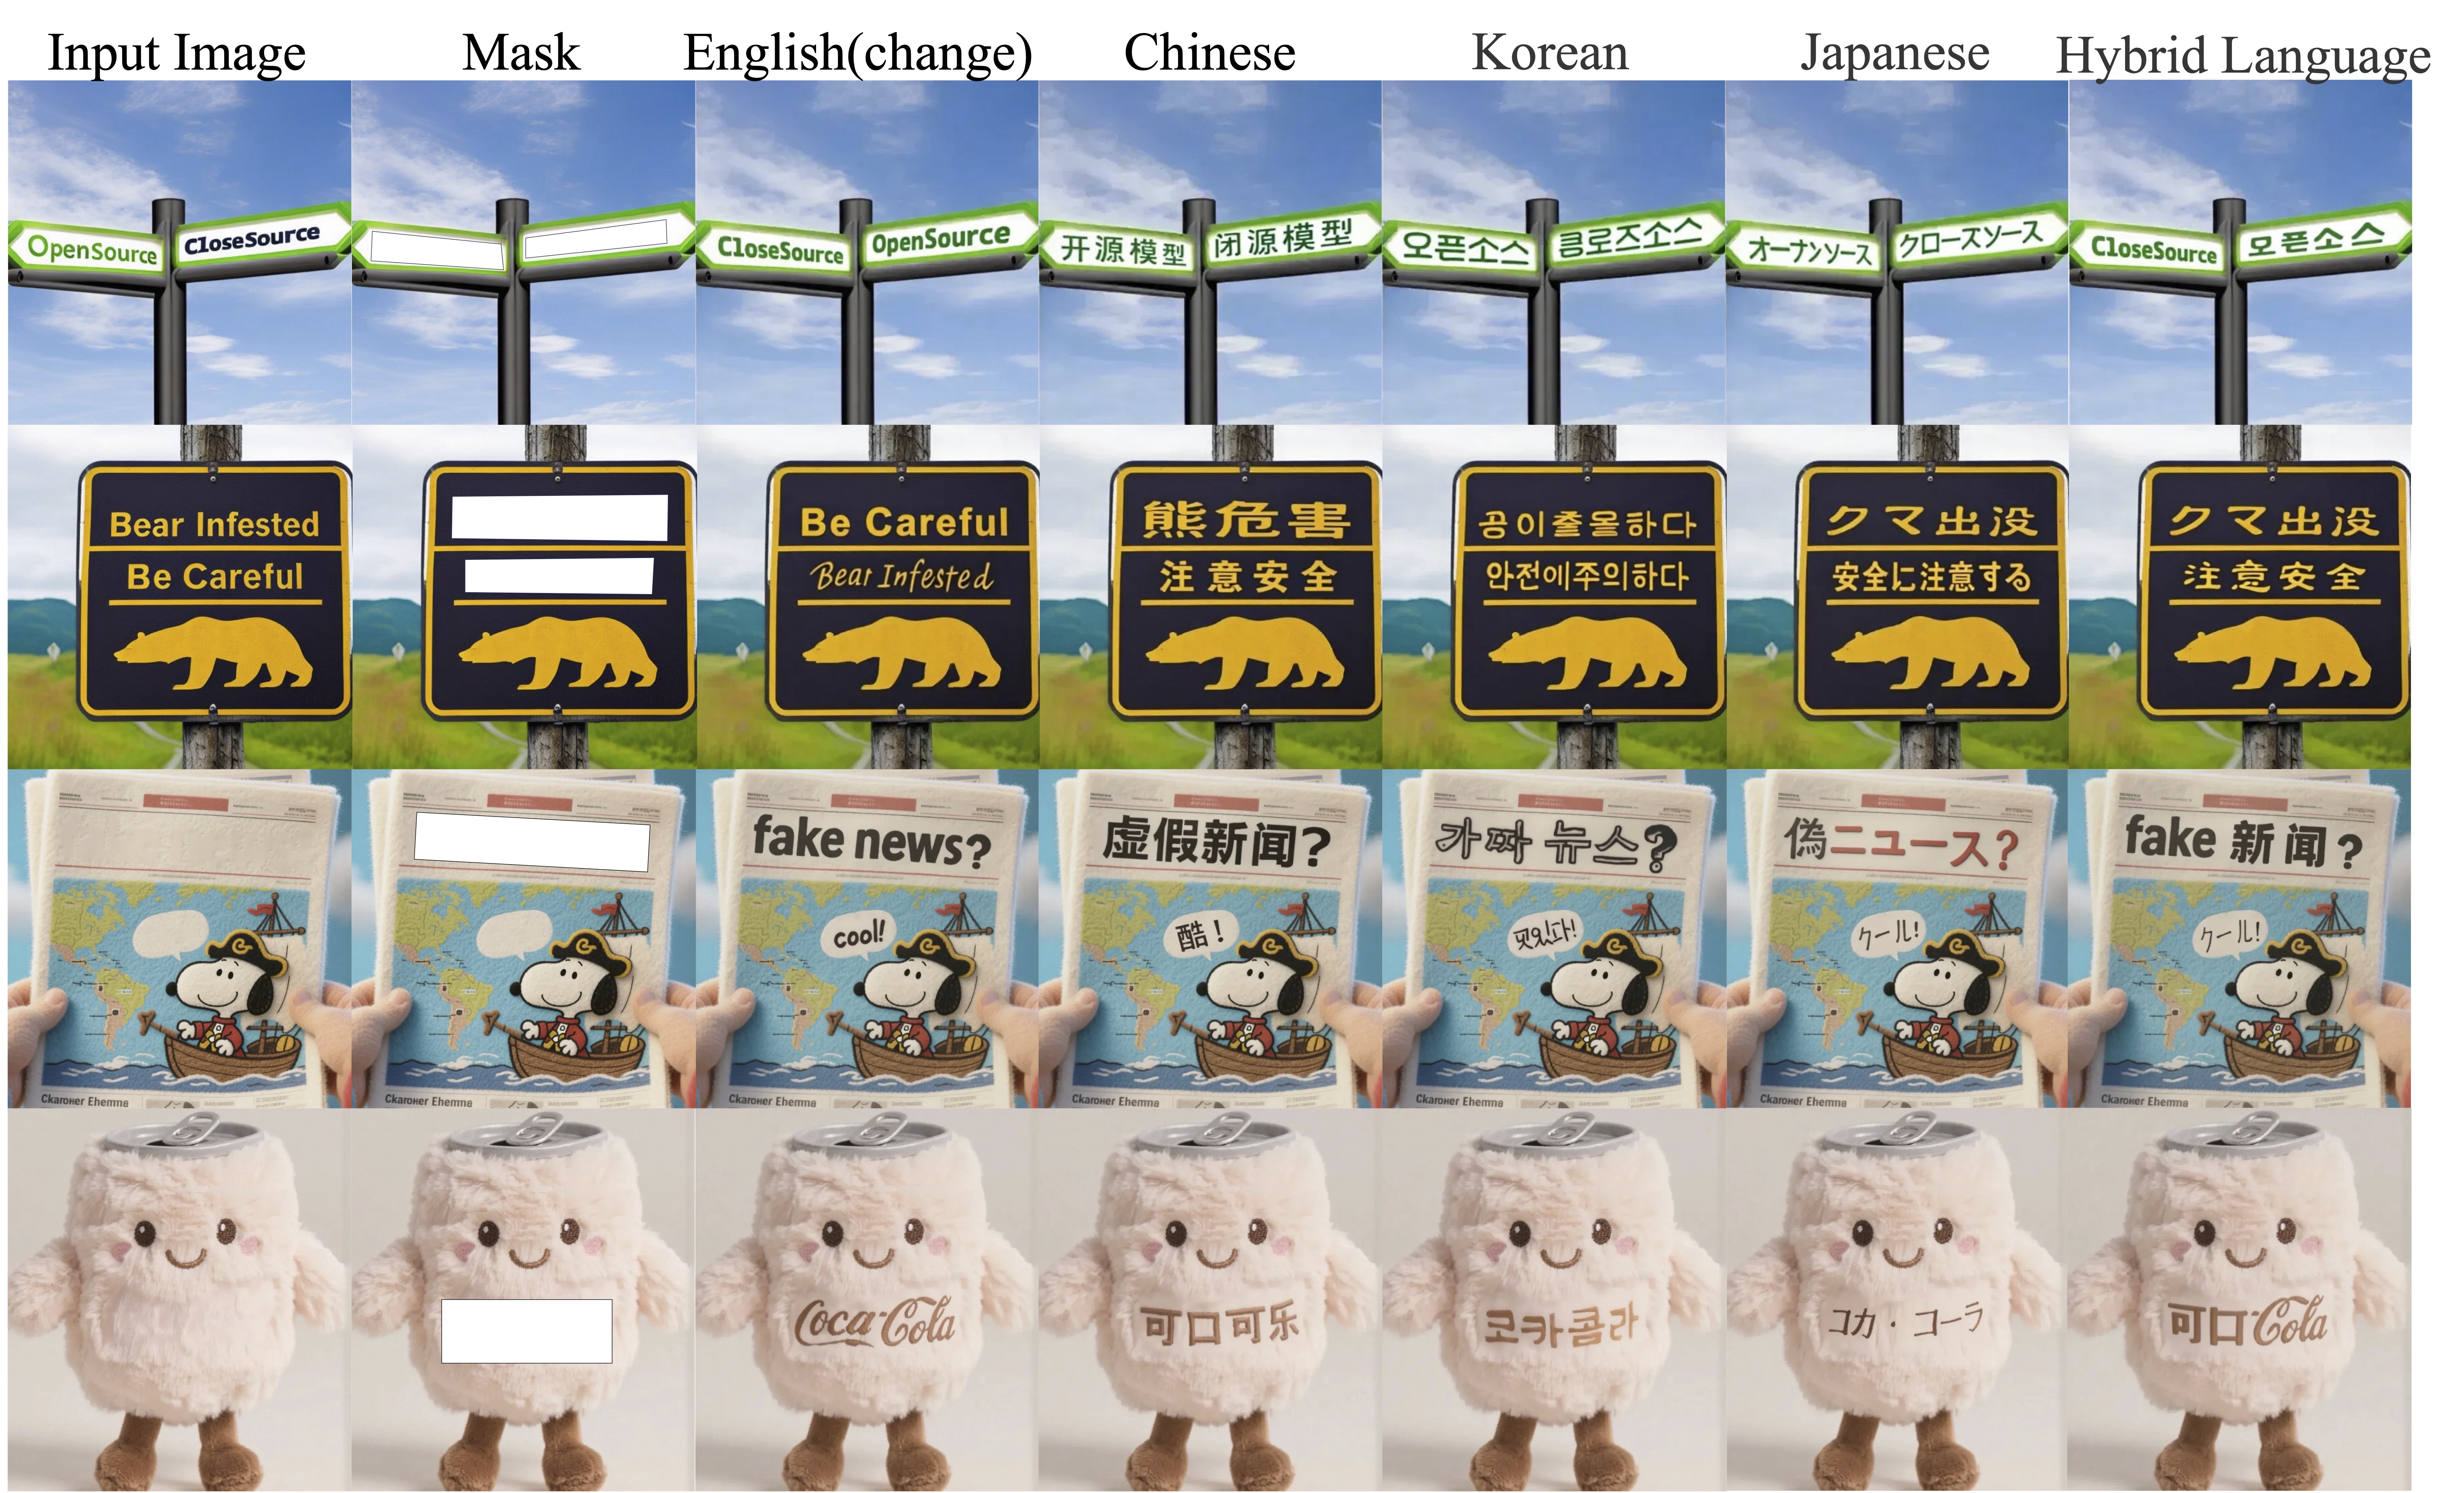
- Motivation: Scene text editing is a challenging task that aims to modify or add text in images while maintaining the fidelity of newly generated text and visual coherence with the background. The main challenge of this task is that we need to edit multiple line texts with diverse language attributes (e.g., fonts, sizes, and styles), language types (e.g., English, Chinese), and visual scenarios (e.g., poster, advertising, gaming).
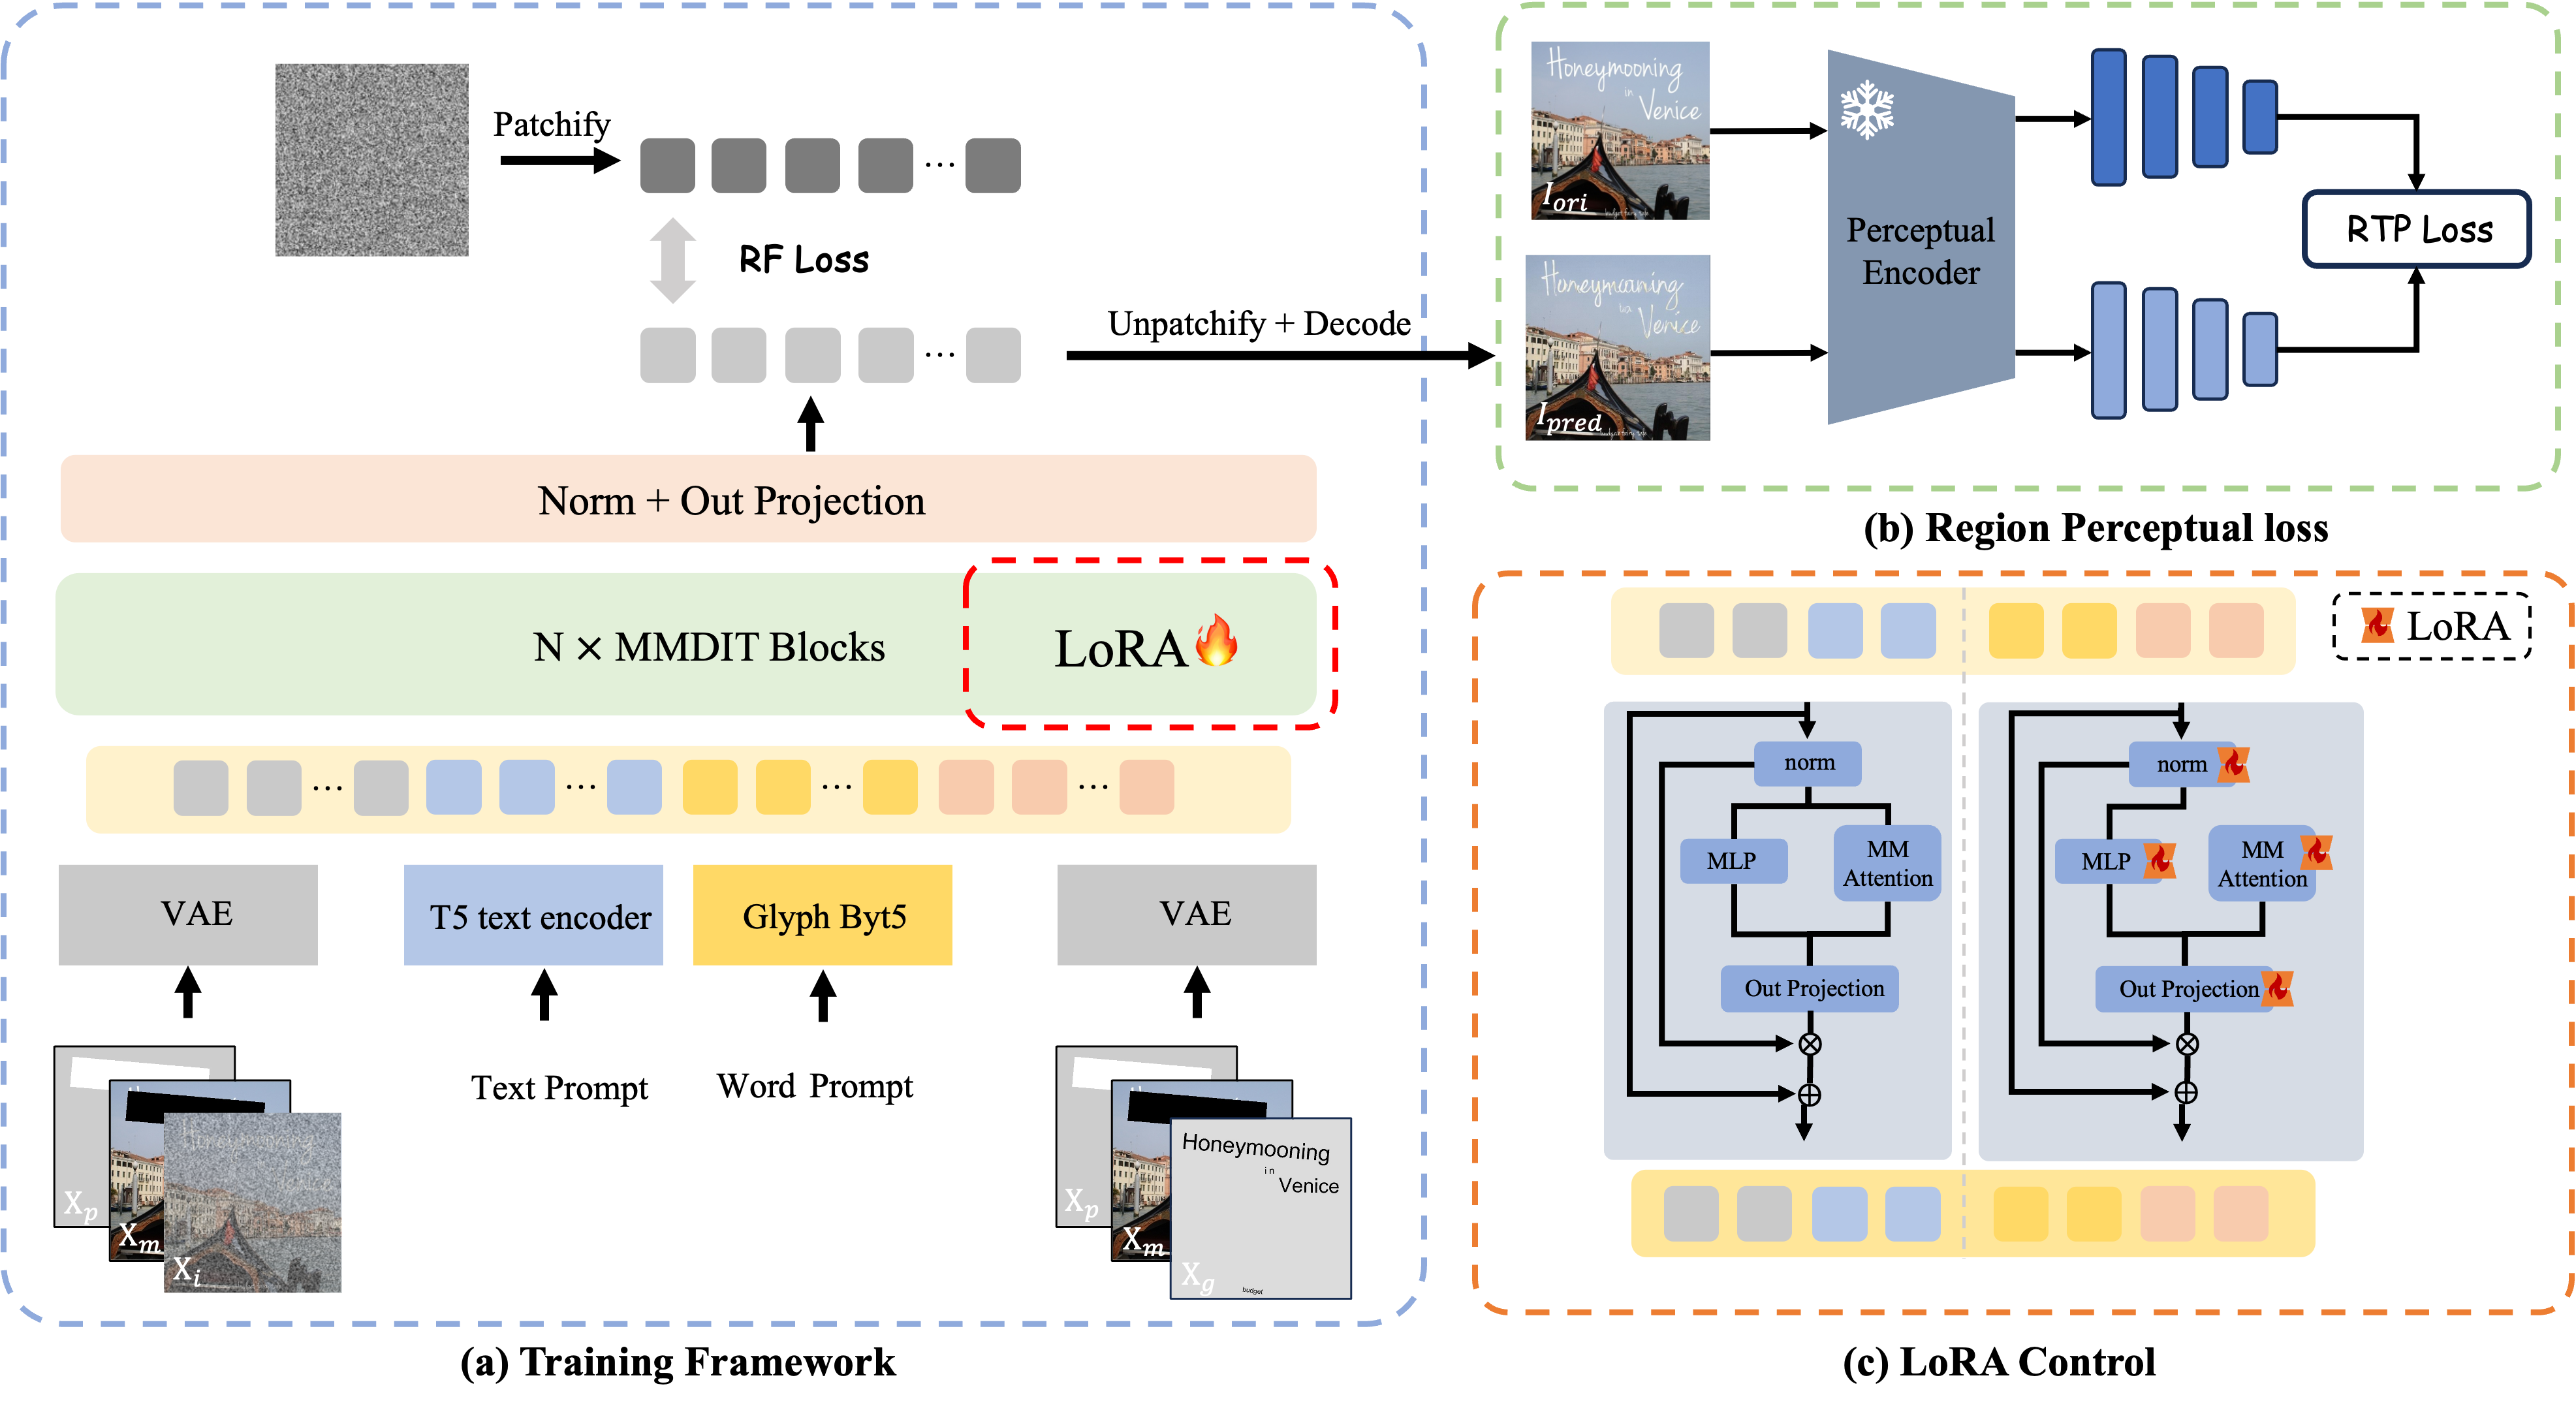
- Contribution: We propose FLUX-Text, a novel text editing framework for editing multi-line texts in complex visual scenes. By incorporating a lightweight Condition Injection LoRA module, Regional text perceptual loss, and two-stage training strategy, we significantly significant improvements on both Chinese and English benchmarks.
News
- 2025-07-16: 🔥 Update comfyui node. We have decoupled the FLUX-Text node to support the use of more basic nodes. Due to differences in node computation in ComfyUI, if you need more consistent results, you should set min_length to 512 in the code.
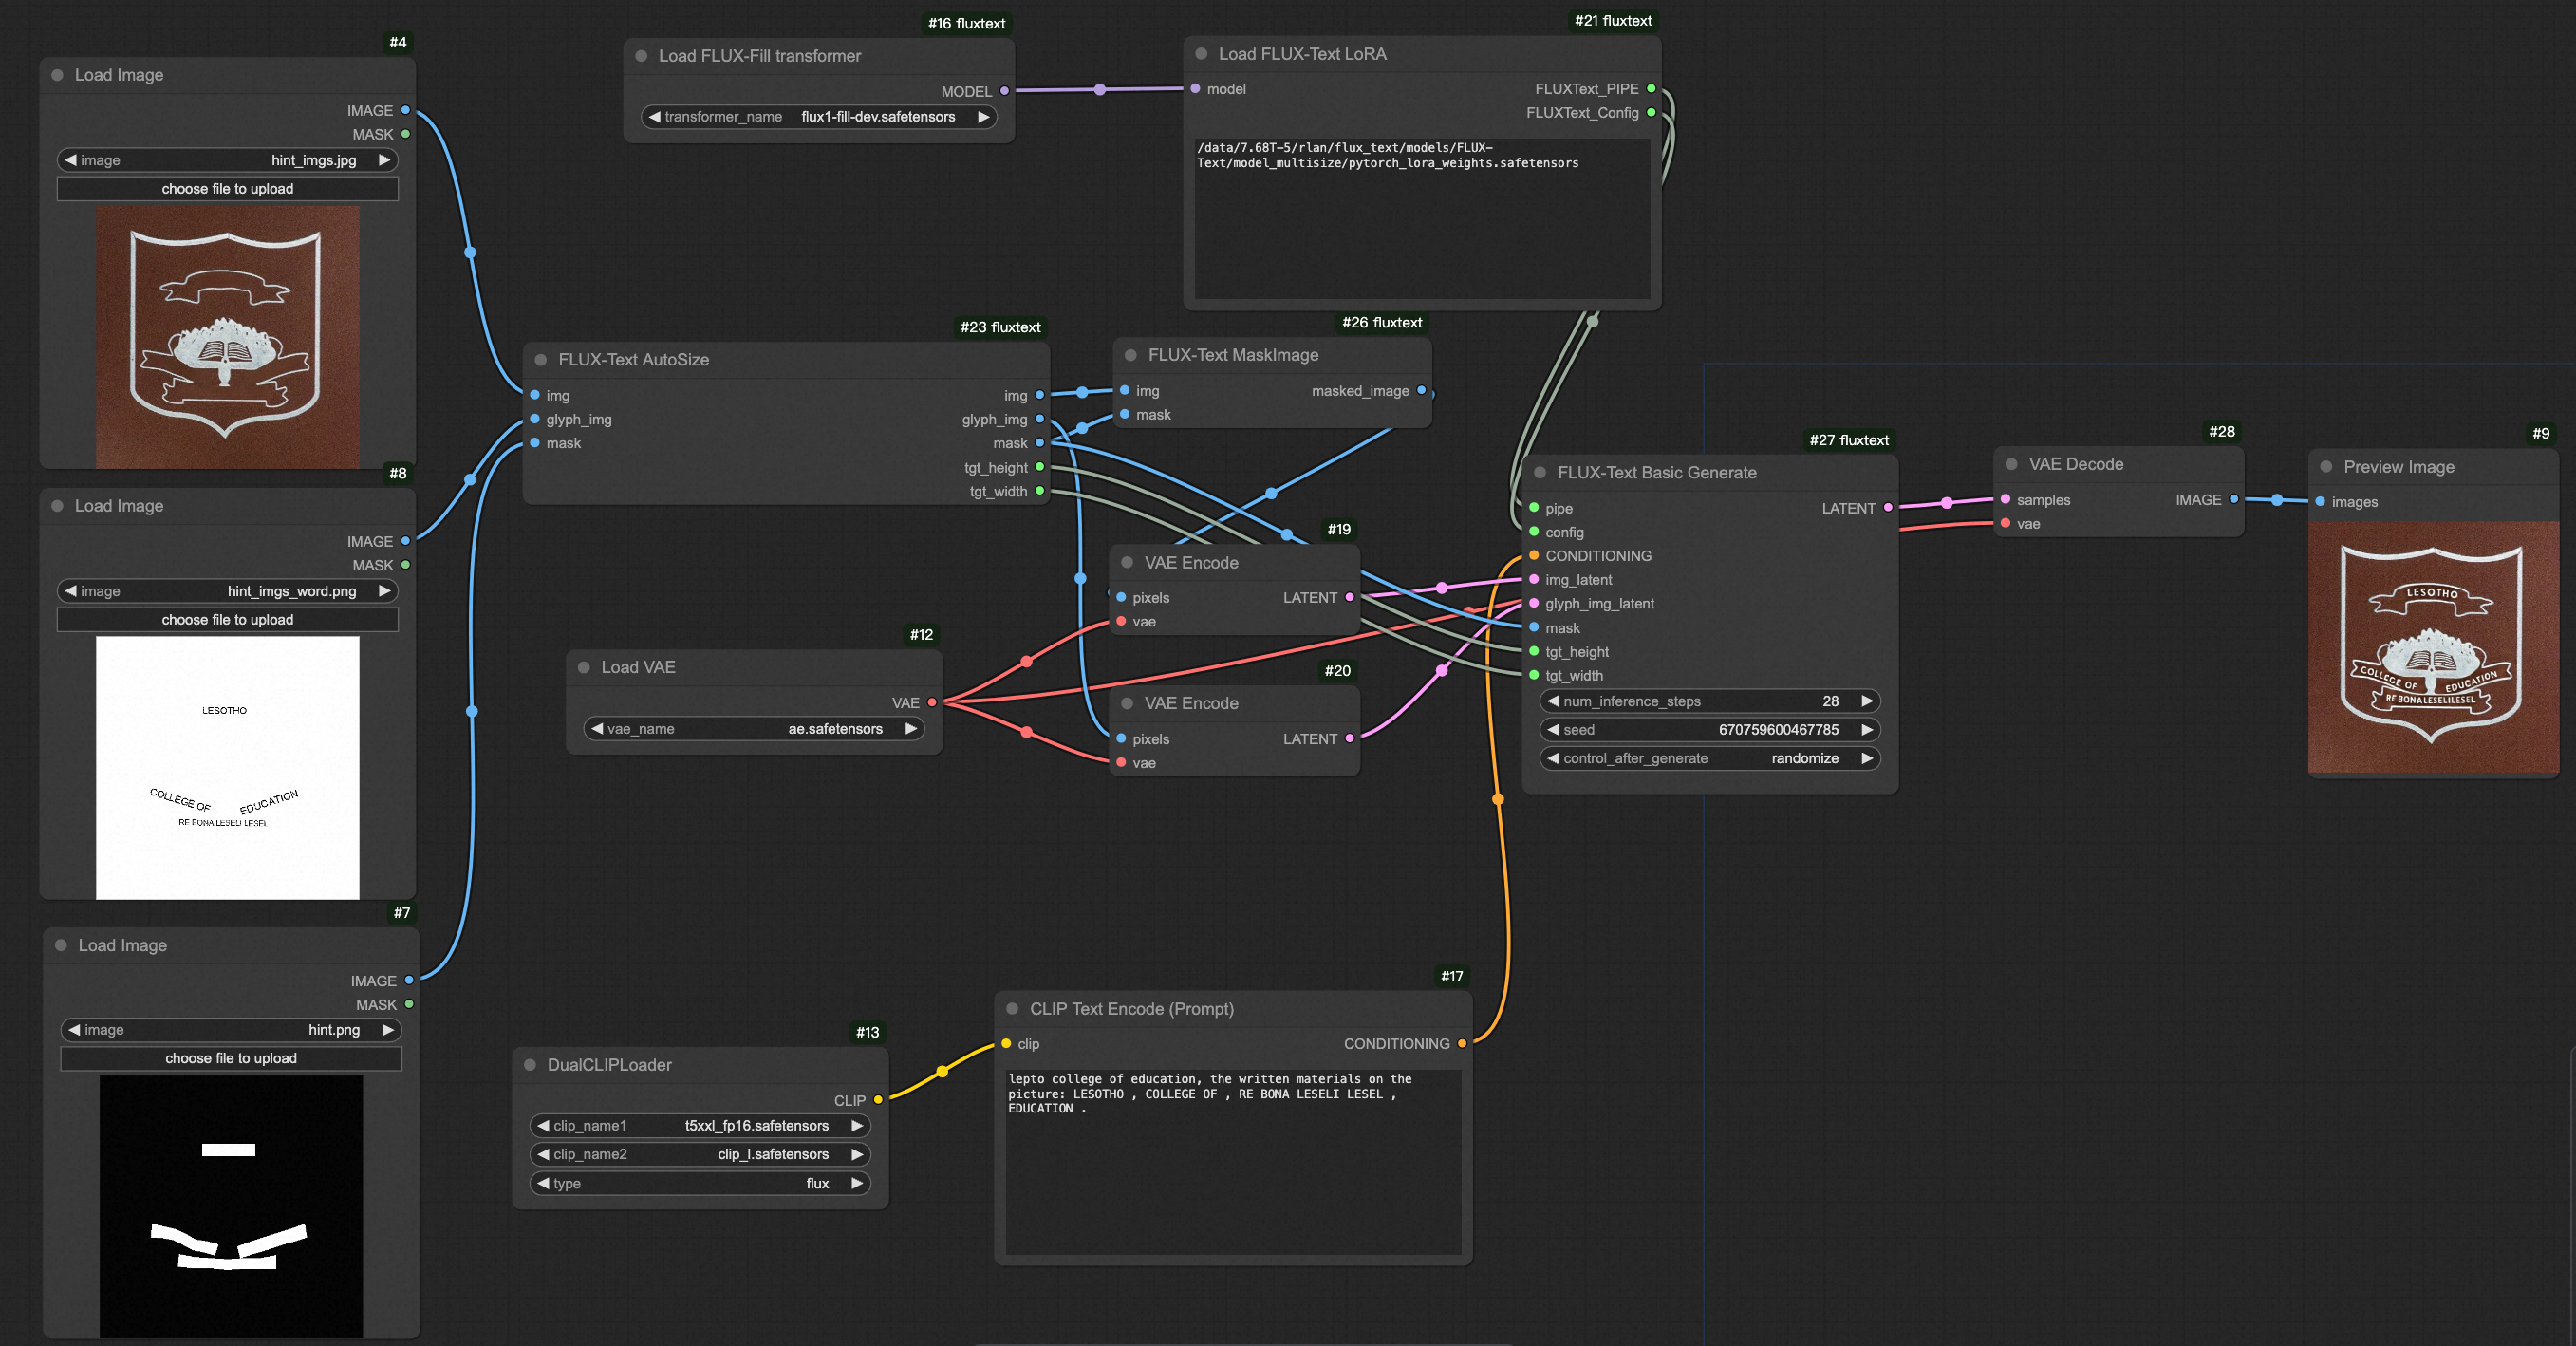 |
| workflow/FLUX-Text-Basic-Workflow.json |
-
2025-07-13: 🔥 The training code has been updated. The code now supports multi-scale training.
-
2025-07-13: 🔥 Update the low-VRAM version of the Gradio demo, which It currently requires 25GB of VRAM to run. Looking forward to more efficient, lower-memory solutions from the community.
-
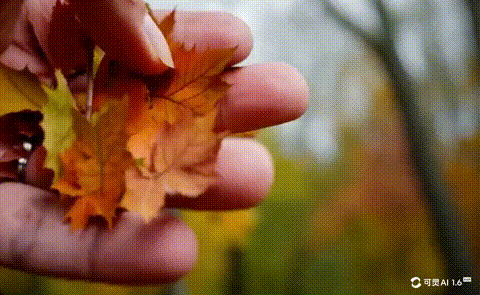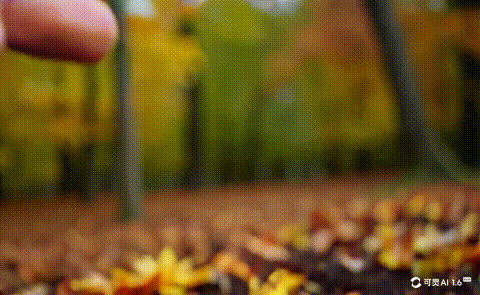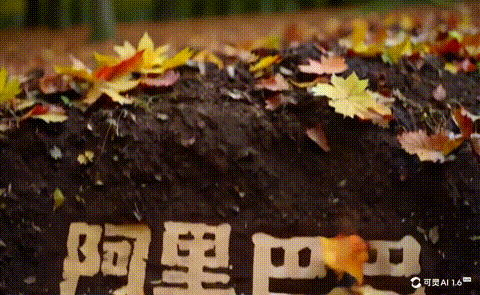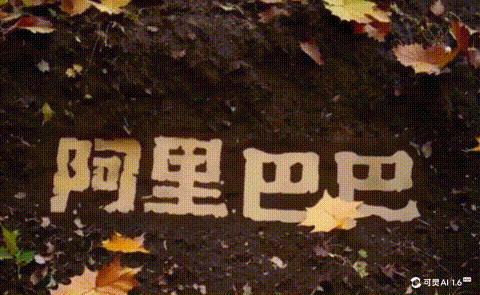
2025-07-08: 🔥 ComfyUI Node is supported! You can now build an workflow based on FLUX-Text for editing posters. It is definitely worth trying to set up a workflow to automatically enhance product image service information and service scope. Meanwhile, utilizing the first and last frames enables the creation of video data with text effects. Thanks to the community work, FLUX-Text was run on 8GB VRAM.
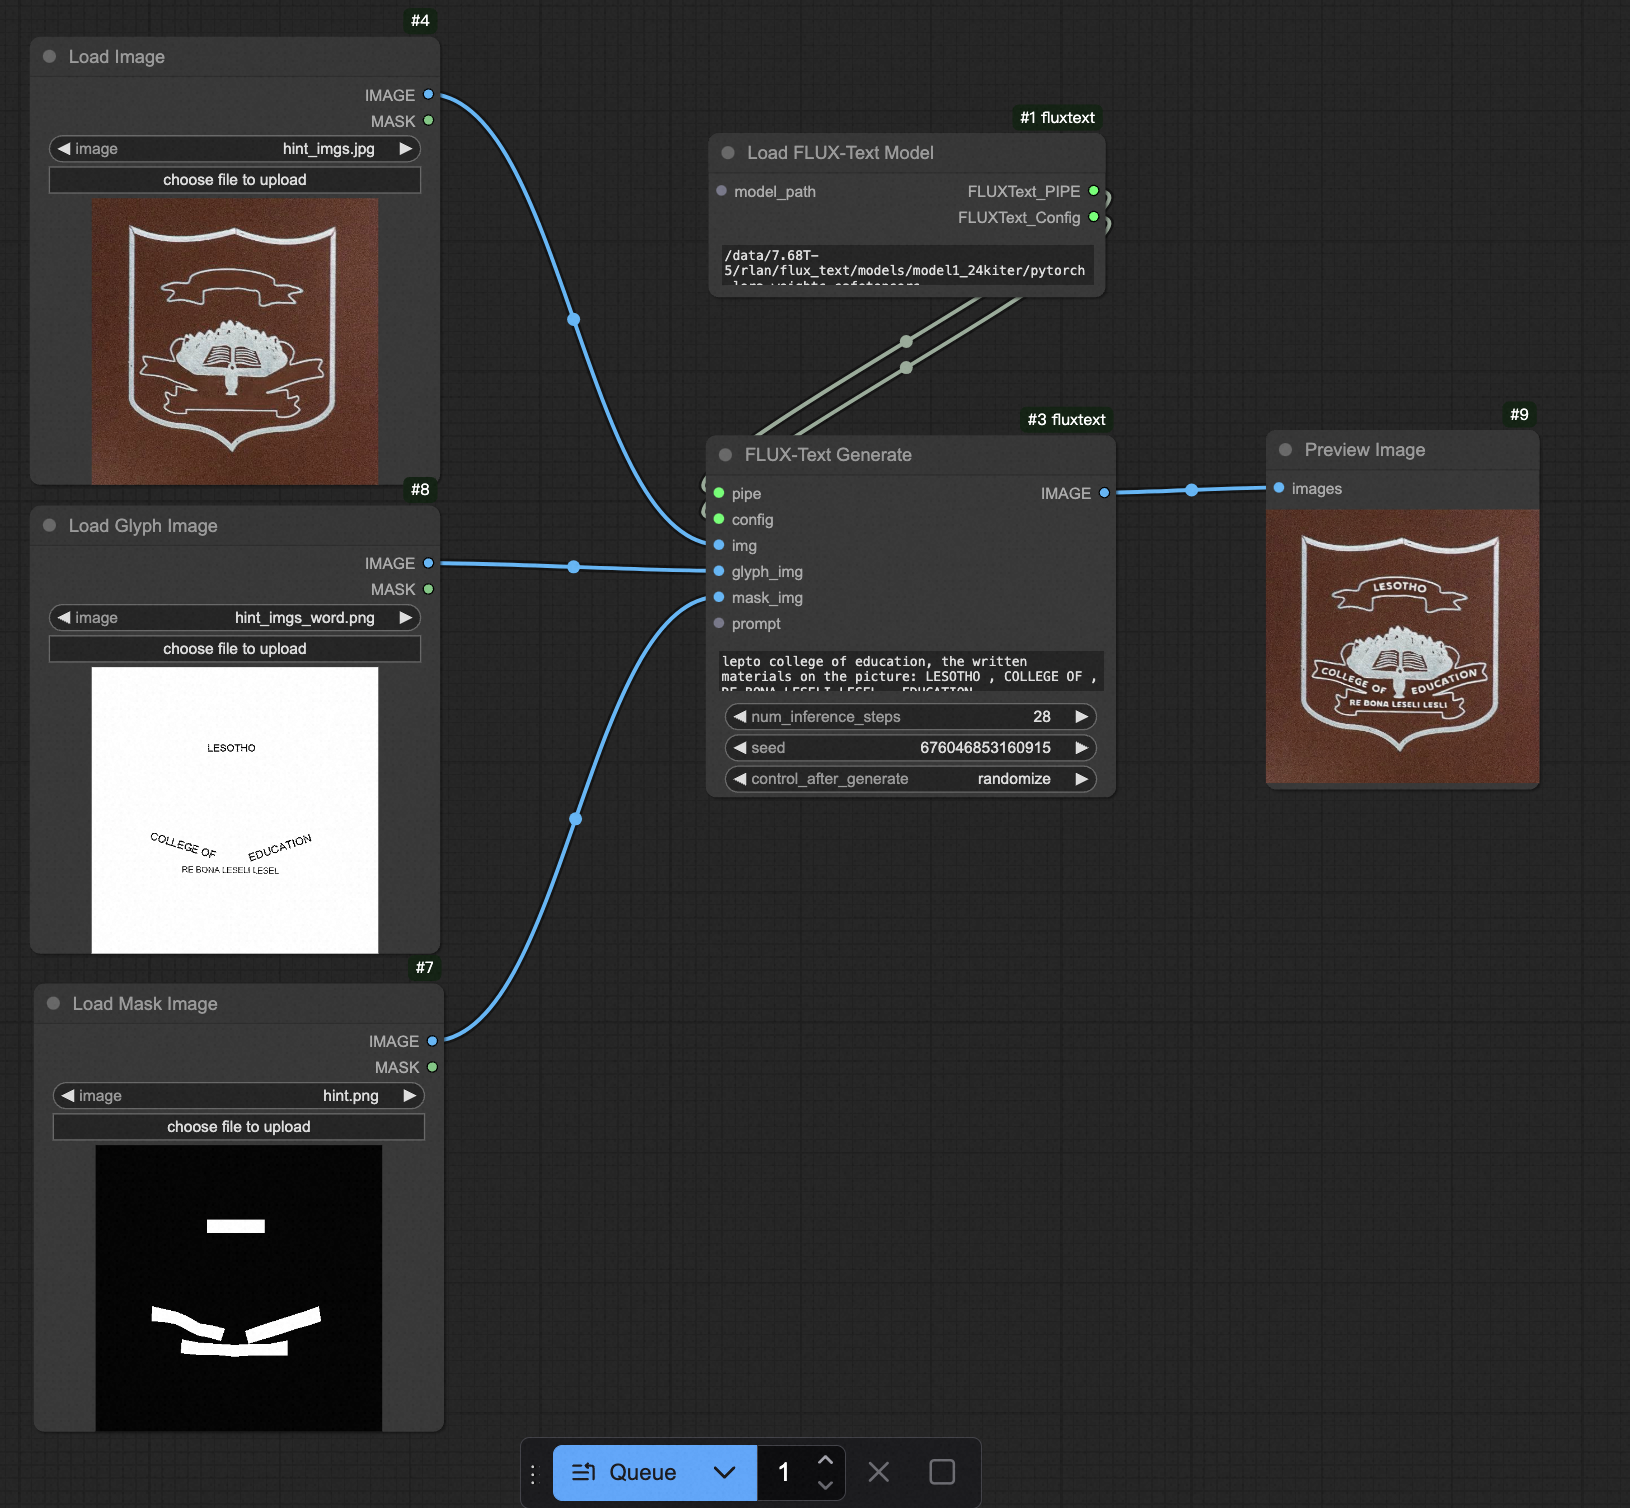 |
| workflow/FLUX-Text-Workflow.json |
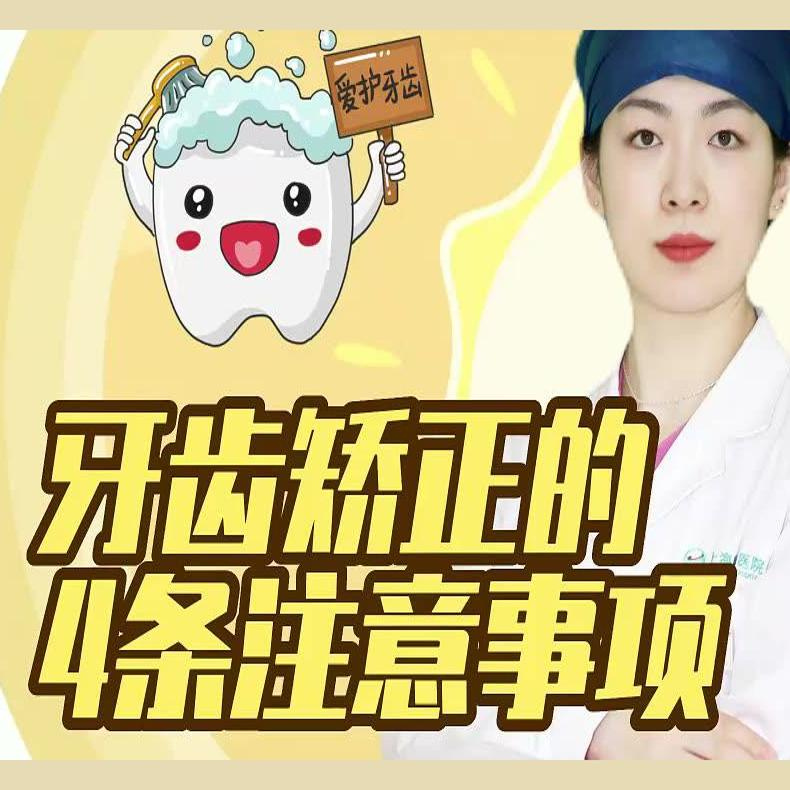 | 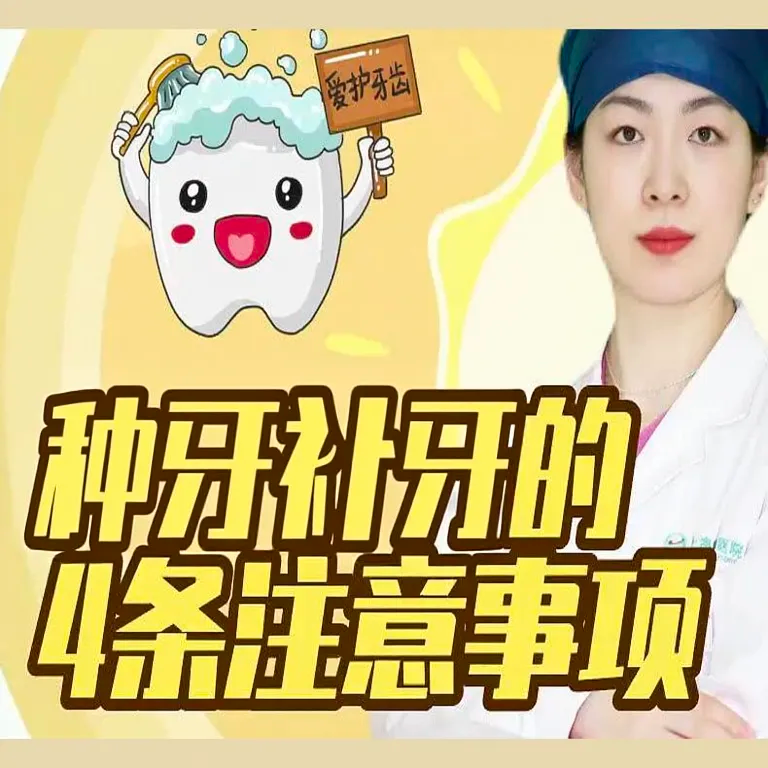 | 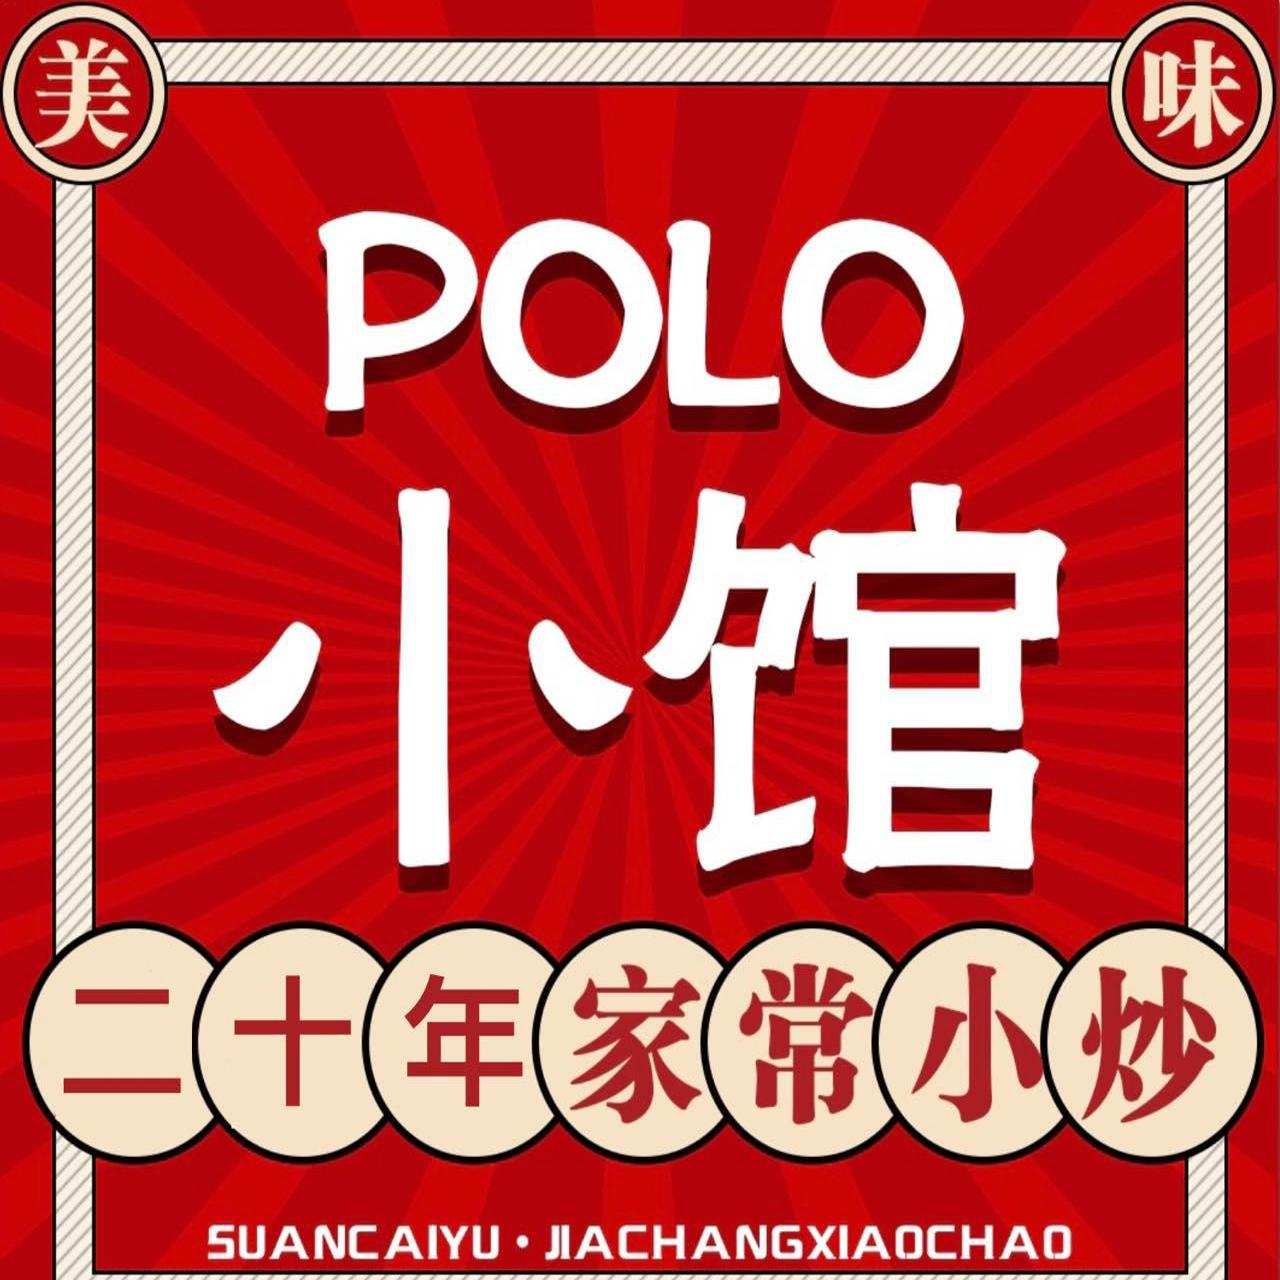 | 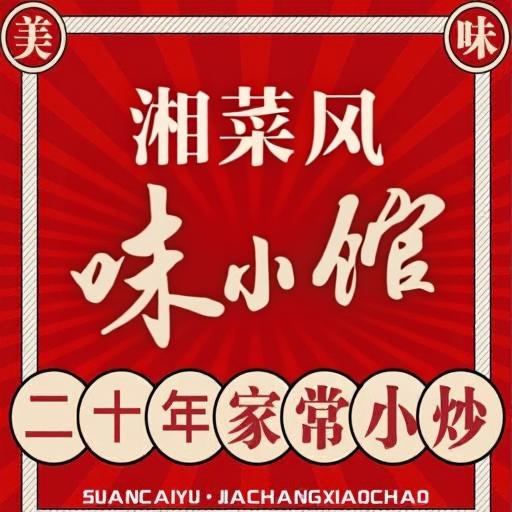 |
| original image | edited image | original image | edited image |
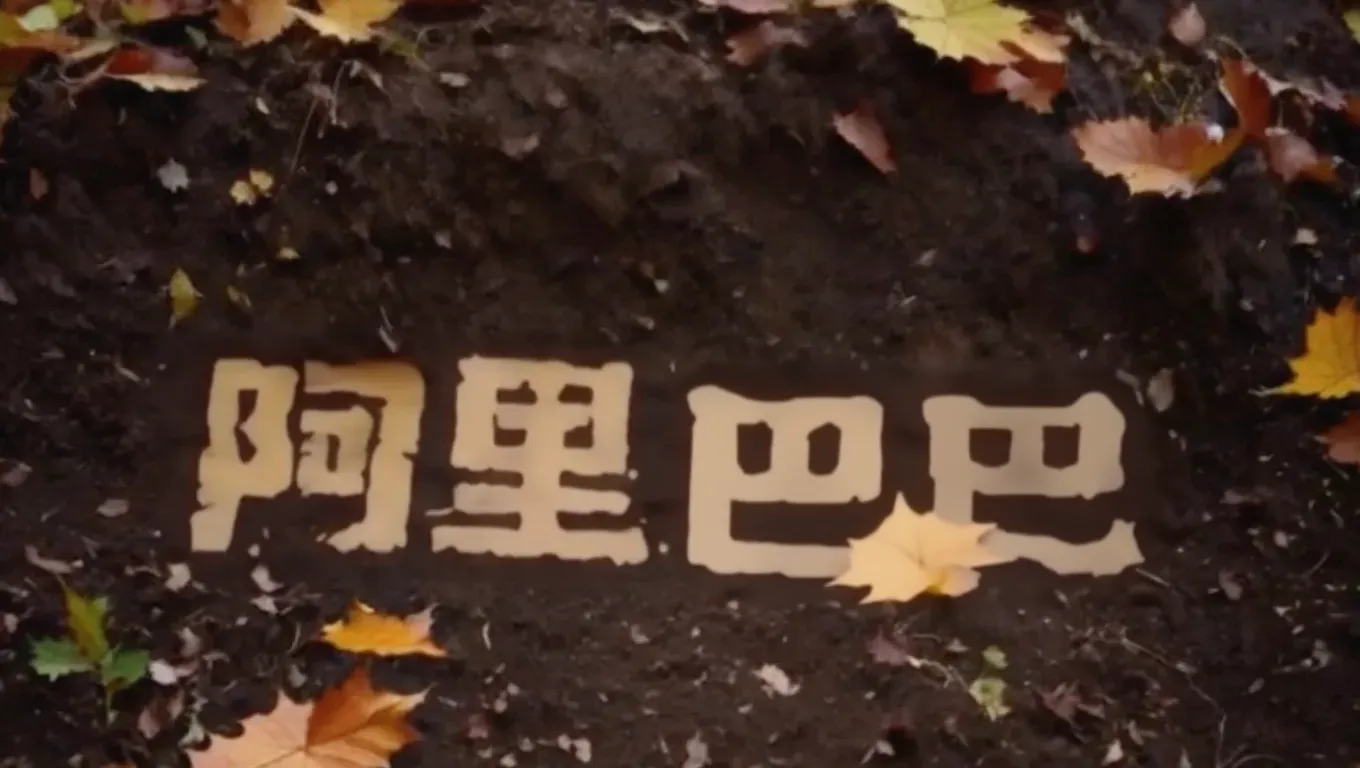 |  |
 | 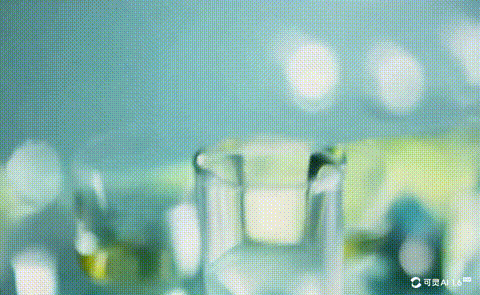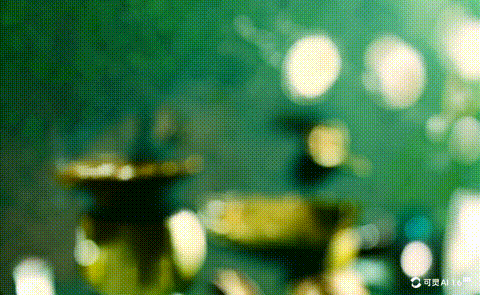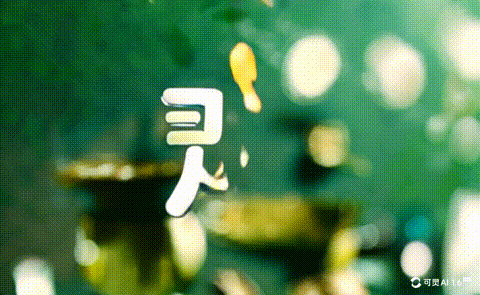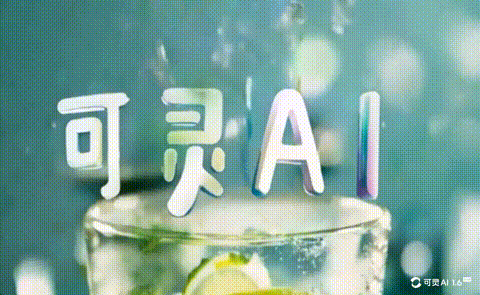 |
| last frame | video |
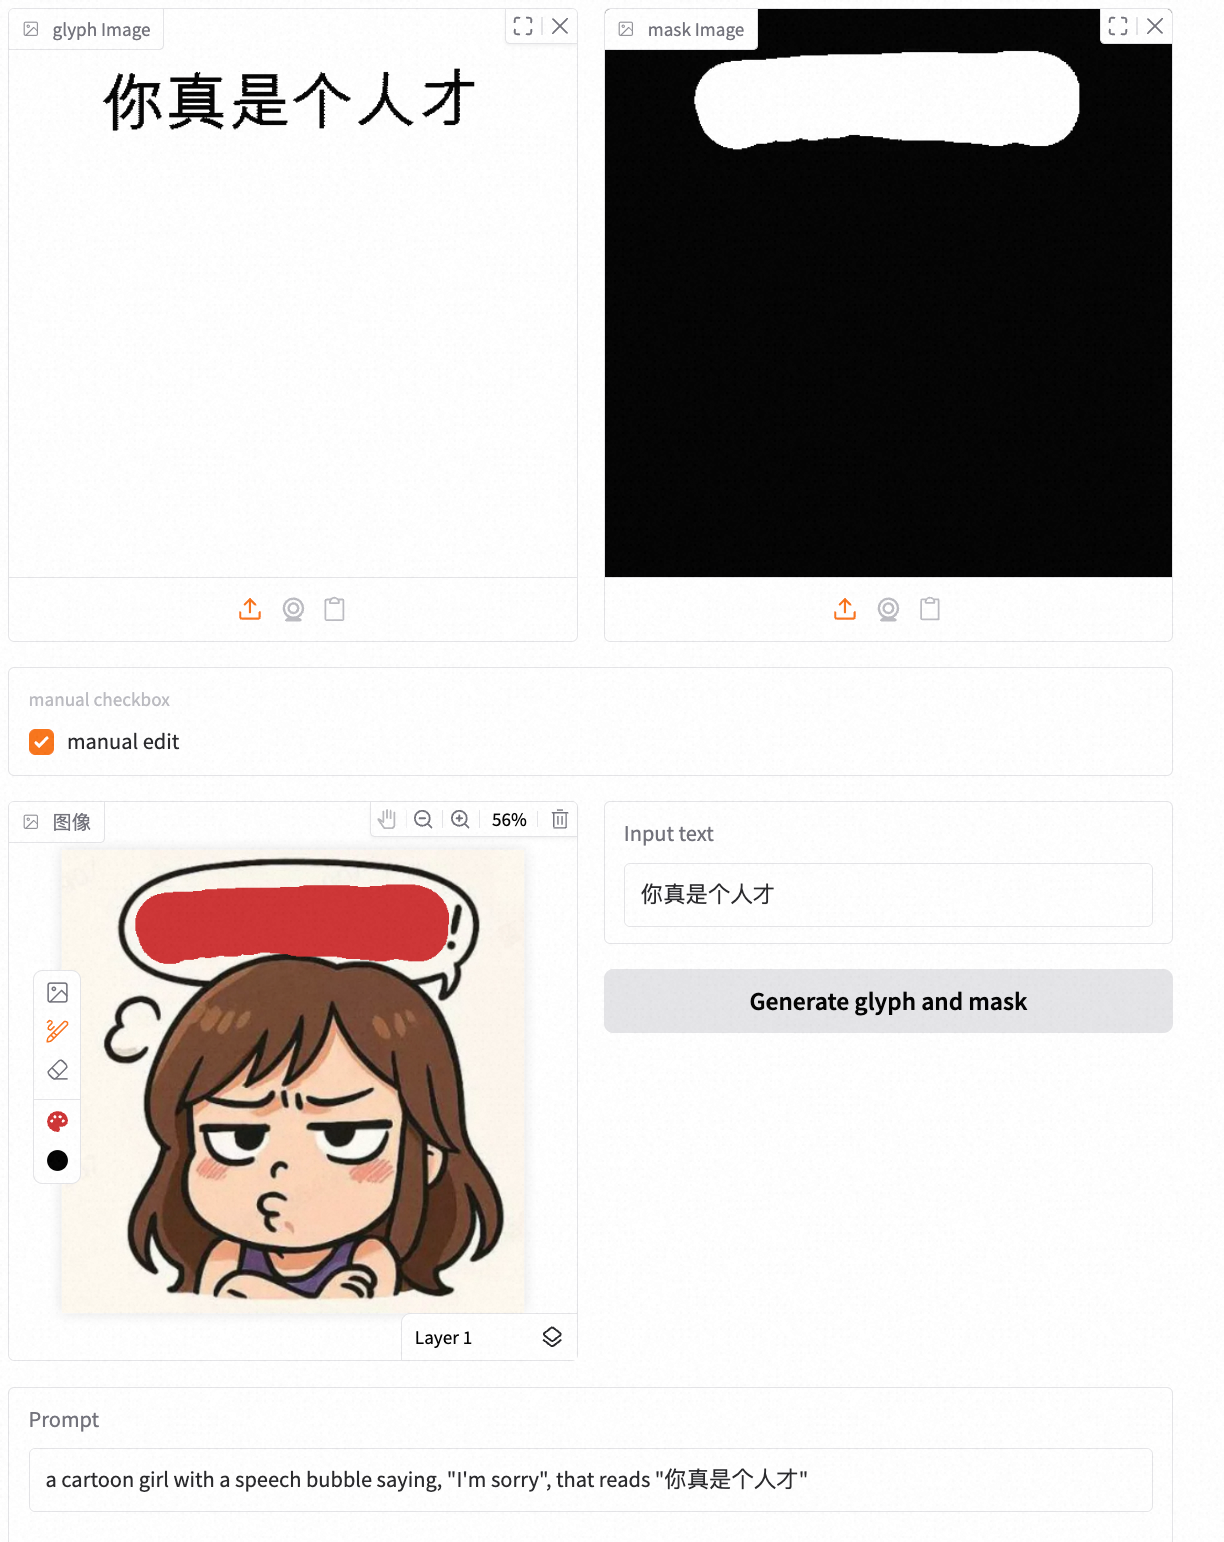
- 2025-07-04: 🔥 We have released gradio demo! You can now try out FLUX-Text.
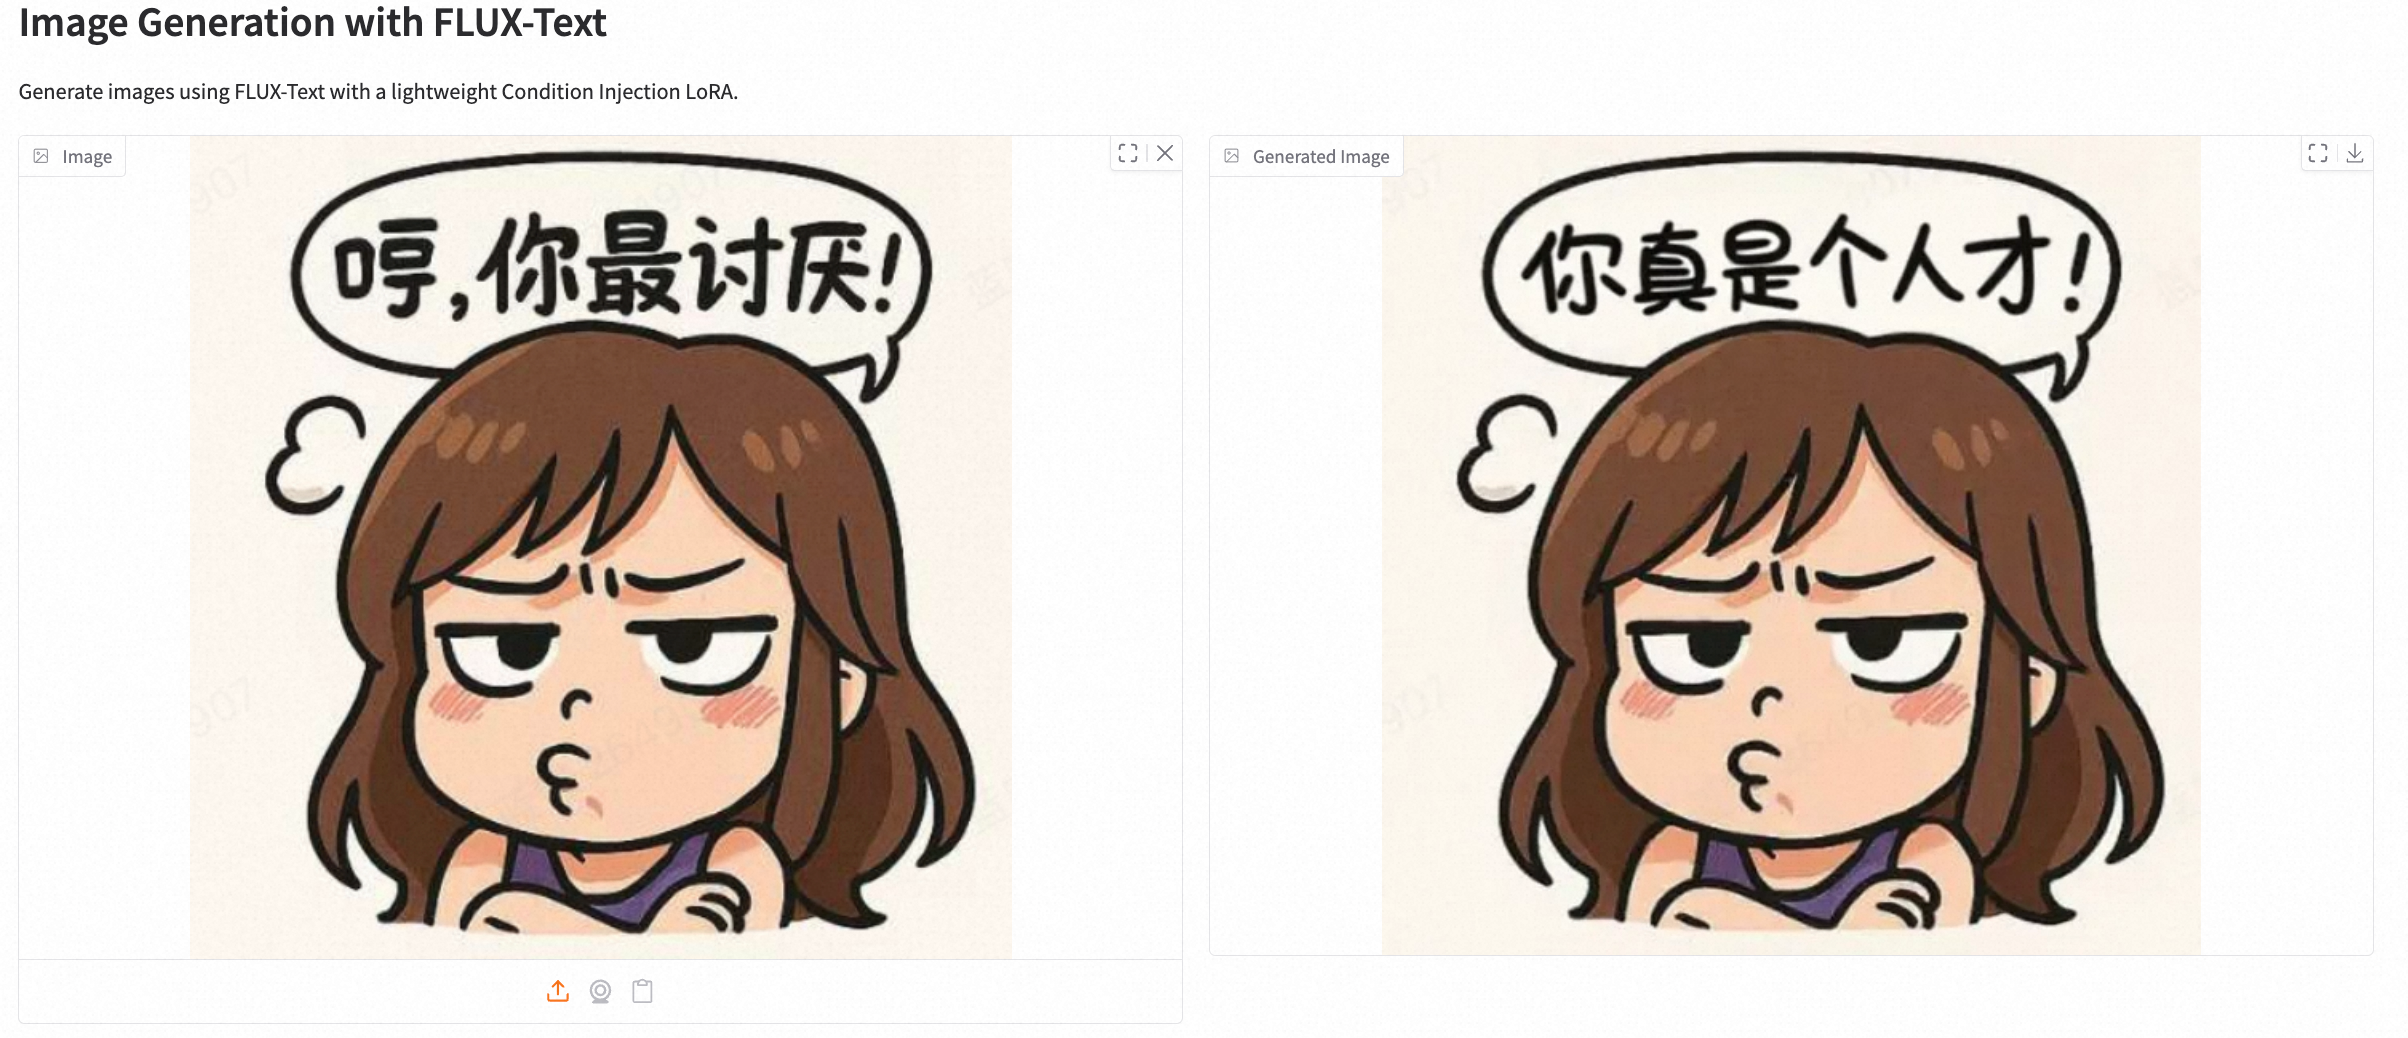 |  |
| Example 1 | Example 2 |
-
2025-07-03: 🔥 We have released our pre-trained checkpoints on Hugging Face! You can now try out FLUX-Text with the official weights.
-
2025-06-26: ⭐️ Inference and evaluate code are released. Once we have ensured that everything is functioning correctly, the new model will be merged into this repository.
Todo List
-
- Inference code
-
- Pre-trained weights
-
- Gradio demo
-
- ComfyUI
-
- Training code
🛠️ Installation
We recommend using Python 3.10 and PyTorch with CUDA support. To set up the environment:
# Create a new conda environment
conda create -n flux_text python=3.10
conda activate flux_text

# Install other dependencies
pip install -r requirements.txt
pip install flash_attn --no-build-isolation
pip install Pillow==9.5.0
🤗 Model Introduction
FLUX-Text is an open-source version of the scene text editing model. FLUX-Text can be used for editing posters, emotions, and more. The table below displays the list of text editing models we currently offer, along with their foundational information.
| Model Name | Image Resolution | Memory Usage | English Sen.Acc | Chinese Sen.Acc | Download Link |
|---|---|---|---|---|---|
| FLUX-Text-512 | 512*512 | 34G | 0.8419 | 0.7132 | 🤗 HuggingFace |
| FLUX-Text | Multi Resolution | 34G for (512*512) | 0.8228 | 0.7161 | 🤗 HuggingFace |
🔥 ComfyUI
Installing via GitHub
First, install and set up ComfyUI, and then follow these steps:
-
Clone FLUXText Repository:
git clone https://github.com/AMAP-ML/FluxText.git -
Install FluxText:
cd FluxText && pip install -r requirements.txt -
Integrate FluxText Comfy Nodes with ComfyUI:
- Symbolic Link (Recommended):
ln -s $(pwd)/ComfyUI-fluxtext path/to/ComfyUI/custom_nodes/ - Copy Directory:
cp -r ComfyUI-fluxtext path/to/ComfyUI/custom_nodes/
- Symbolic Link (Recommended):
🔥 Quick Start
Here's a basic example of using FLUX-Text:
import numpy as np
from PIL import Image
import torch
import yaml

from src.flux.condition import Condition
from src.flux.generate_fill import generate_fill
from src.train.model import OminiModelFIll
from safetensors.torch import load_file

config_path = ""
lora_path = ""
with open(config_path, "r") as f:
    config = yaml.safe_load(f)
model = OminiModelFIll(
        flux_pipe_id=config["flux_path"],
        lora_config=config["train"]["lora_config"],
        device=f"cuda",
        dtype=getattr(torch, config["dtype"]),
        optimizer_config=config["train"]["optimizer"],
        model_config=config.get("model", {}),
        gradient_checkpointing=True,
        byt5_encoder_config=None,
    )

state_dict = load_file(lora_path)
state_dict_new = {x.replace('lora_A', 'lora_A.default').replace('lora_B', 'lora_B.default').replace('transformer.', ''): v for x, v in state_dict.items()}
model.transformer.load_state_dict(state_dict_new, strict=False)
pipe = model.flux_pipe

prompt = "lepto college of education, the written materials on the picture: LESOTHO , COLLEGE OF , RE BONA LESELI LESEL , EDUCATION ."
hint = Image.open("assets/hint.png").resize((512, 512)).convert('RGB')
img = Image.open("assets/hint_imgs.jpg").resize((512, 512))
condition_img = Image.open("assets/hint_imgs_word.png").resize((512, 512)).convert('RGB')
hint = np.array(hint) / 255
condition_img = np.array(condition_img)
condition_img = (255 - condition_img) / 255
condition_img = [condition_img, hint, img]
position_delta = [0, 0]
condition = Condition(
                condition_type='word_fill',
                condition=condition_img,
                position_delta=position_delta,
            )
generator = torch.Generator(device="cuda")
res = generate_fill(
    pipe,
    prompt=prompt,
    conditions=[condition],
    height=512,
    width=512,
    generator=generator,
    model_config=config.get("model", {}),
    default_lora=True,
)
res.images[0].save('flux_fill.png')
🤗 gradio
You can upload the glyph image and mask image to edit text region. Or you can use manual edit to obtain glyph image and mask image.
first, download the model weight and config in HuggingFace
python app.py --model_path xx.safetensors --config_path config.yaml
💪🏻 Training
-
Download training dataset AnyWord-3M from ModelScope, unzip all *.zip files in each subfolder, then open *.json and modify the
data_rootwith your own path of imgs folder for each sub dataset. -
Replace the old annotations in AnyWord with the new annotations. Change the dataset annotations path and image_root in src/train/data_word.py.
json_paths = [
        ['dataset/Anyword/data_text_recog_glyph/Art/data-info.json', 'AnyWord-3M/ocr_data/Art/imgs/'],
        ['dataset/Anyword/data_text_recog_glyph/COCO_Text/data-info.json', 'AnyWord-3M/ocr_data/COCO_Text/imgs/'],
        ['dataset/Anyword/data_text_recog_glyph/icdar2017rctw/data-info.json', 'AnyWord-3M/ocr_data/icdar2017rctw/imgs'],
        ['dataset/Anyword/data_text_recog_glyph/LSVT/data-info.json', 'AnyWord-3M/ocr_data/LSVT/imgs'],
        ['dataset/Anyword/data_text_recog_glyph/mlt2019/data-info.json', 'AnyWord-3M/ocr_data/mlt2019/imgs/'],
        ['dataset/Anyword/data_text_recog_glyph/MTWI2018/data-info.json', 'AnyWord-3M/ocr_data/MTWI2018/imgs'],
        ['dataset/Anyword/data_text_recog_glyph/ReCTS/data-info.json', 'AnyWord-3M/ocr_data/ReCTS/imgs'],
        ['dataset/Anyword/data_text_recog_glyph/laion/data_v1.1-info.json', 'AnyWord-3M/laion/imgs'],
        ['dataset/Anyword/data_text_recog_glyph/wukong_1of5/data_v1.1-info.json', 'AnyWord-3M/wukong_1of5/imgs'],
        ['dataset/Anyword/data_text_recog_glyph/wukong_2of5/data_v1.1-info.json', 'AnyWord-3M/wukong_2of5/imgs'],
        ['dataset/Anyword/data_text_recog_glyph/wukong_3of5/data_v1.1-info.json', 'AnyWord-3M/wukong_3of5/imgs'],
        ['dataset/Anyword/data_text_recog_glyph/wukong_4of5/data_v1.1-info.json', 'AnyWord-3M/wukong_4of5/imgs'],
        ['dataset/Anyword/data_text_recog_glyph/wukong_5of5/data_v1.1-info.json', 'AnyWord-3M/wukong_5of5/imgs'],
        ]
-
Download the ODM weights in HuggingFace and change
odm_loss/modelpathin the config file. -
(Optional) Download the pretrained weight in HuggingFace and change
reuse_lora_pathin the config file. -
Run the training scripts. With 48GB of VRAM, you can train at 512×512 resolution with a batch size of 2 in LoRA rank 8.
bash train/script/train_word.sh
📊 Evaluation
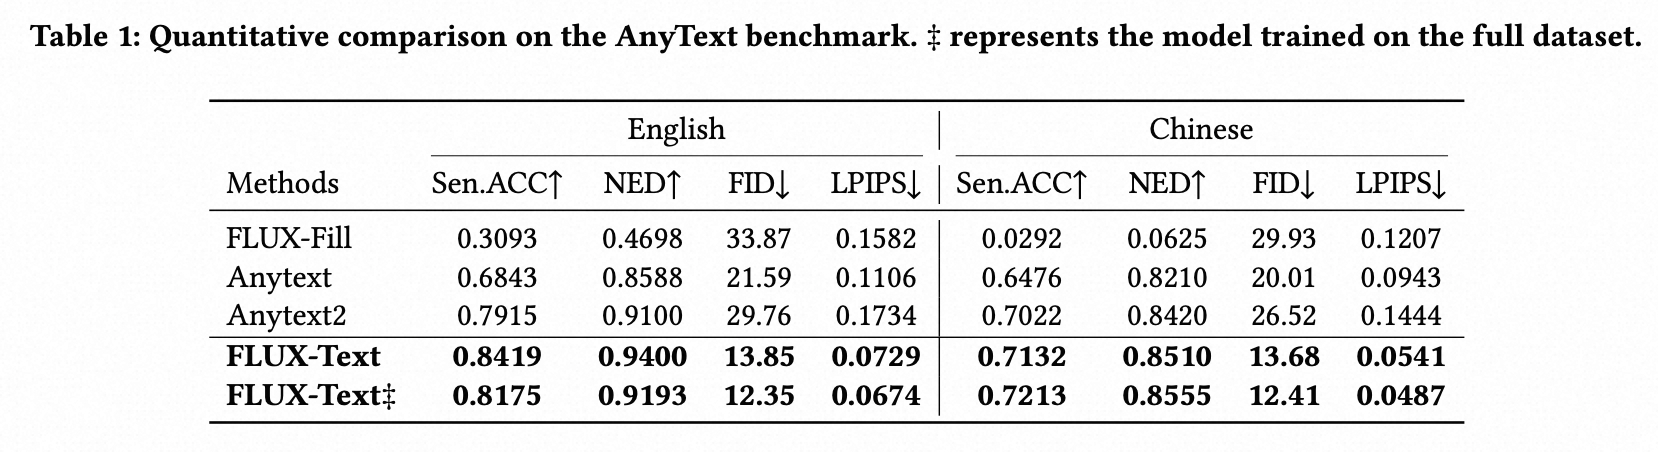
For Anytext-benchmark, please set the config_path, model_path, json_path, output_dir in the eval/gen_imgs_anytext.sh and generate the text editing results.
bash eval/gen_imgs_anytext.sh
For Sen.ACC, NED, FID and LPIPS evaluation, use the scripts in the eval folder.
bash eval/eval_ocr.sh
bash eval/eval_fid.sh
bash eval/eval_lpips.sh
📈 Results
🌹 Acknowledgement
Our work is primarily based on OminiControl, AnyText, Open-Sora, Phantom. We are sincerely grateful for their excellent works.
📚 Citation
If you find our paper and code helpful for your research, please consider starring our repository ⭐ and citing our work ✏️.
@article{lan2025flux,
  title={Flux-text: A simple and advanced diffusion transformer baseline for scene text editing},
  author={Lan, Rui and Bai, Yancheng and Duan, Xu and Li, Mingxing and Jin, Dongyang and Xu, Ryan and Nie, Dong and Sun, Lei and Chu, Xiangxiang},
  journal={arXiv preprint arXiv:2505.03329},
  year={2025}
}
Similar repos


Languages
Python
99.8%
Implementation of "FLUX-Text: A Simple and Advanced Diffusion Transformer Baseline for Scene Text Editing"
Python
923
0 commits
updated Nov 24, 2025
README
Implementation of FLUX-Text
FLUX-Text: A Simple and Advanced Diffusion Transformer Baseline for Scene Text Editing
Rui Lan1, Yancheng Bai1, Xu Duan1, Mingxing Li1, Dongyang Jin1, Ryan Xu1, Dong Nie2, Lei Sun1, Xiangxiang Chu1
1ALibaba Group 2University of North Carolina at Chapel Hill
📖 Overview
- Motivation: Scene text editing is a challenging task that aims to modify or add text in images while maintaining the fidelity of newly generated text and visual coherence with the background. The main challenge of this task is that we need to edit multiple line texts with diverse language attributes (e.g., fonts, sizes, and styles), language types (e.g., English, Chinese), and visual scenarios (e.g., poster, advertising, gaming).
- Contribution: We propose FLUX-Text, a novel text editing framework for editing multi-line texts in complex visual scenes. By incorporating a lightweight Condition Injection LoRA module, Regional text perceptual loss, and two-stage training strategy, we significantly significant improvements on both Chinese and English benchmarks.
News
- 2025-07-16: 🔥 Update comfyui node. We have decoupled the FLUX-Text node to support the use of more basic nodes. Due to differences in node computation in ComfyUI, if you need more consistent results, you should set min_length to 512 in the code.
|
| workflow/FLUX-Text-Basic-Workflow.json |
-
2025-07-13: 🔥 The training code has been updated. The code now supports multi-scale training.
-
2025-07-13: 🔥 Update the low-VRAM version of the Gradio demo, which It currently requires 25GB of VRAM to run. Looking forward to more efficient, lower-memory solutions from the community.
-
2025-07-08: 🔥 ComfyUI Node is supported! You can now build an workflow based on FLUX-Text for editing posters. It is definitely worth trying to set up a workflow to automatically enhance product image service information and service scope. Meanwhile, utilizing the first and last frames enables the creation of video data with text effects. Thanks to the community work, FLUX-Text was run on 8GB VRAM.
|
| workflow/FLUX-Text-Workflow.json |
| | | |
| original image | edited image | original image | edited image |
| |
| |
| last frame | video |
- 2025-07-04: 🔥 We have released gradio demo! You can now try out FLUX-Text.
| |
| Example 1 | Example 2 |
-
2025-07-03: 🔥 We have released our pre-trained checkpoints on Hugging Face! You can now try out FLUX-Text with the official weights.
-
2025-06-26: ⭐️ Inference and evaluate code are released. Once we have ensured that everything is functioning correctly, the new model will be merged into this repository.
Todo List
-
- Inference code
-
- Pre-trained weights
-
- Gradio demo
-
- ComfyUI
-
- Training code
🛠️ Installation
We recommend using Python 3.10 and PyTorch with CUDA support. To set up the environment:
# Create a new conda environment
conda create -n flux_text python=3.10
conda activate flux_text

# Install other dependencies
pip install -r requirements.txt
pip install flash_attn --no-build-isolation
pip install Pillow==9.5.0
🤗 Model Introduction
FLUX-Text is an open-source version of the scene text editing model. FLUX-Text can be used for editing posters, emotions, and more. The table below displays the list of text editing models we currently offer, along with their foundational information.
| Model Name | Image Resolution | Memory Usage | English Sen.Acc | Chinese Sen.Acc | Download Link |
|---|---|---|---|---|---|
| FLUX-Text-512 | 512*512 | 34G | 0.8419 | 0.7132 | 🤗 HuggingFace |
| FLUX-Text | Multi Resolution | 34G for (512*512) | 0.8228 | 0.7161 | 🤗 HuggingFace |
🔥 ComfyUI
Installing via GitHub
First, install and set up ComfyUI, and then follow these steps:
-
Clone FLUXText Repository:
git clone https://github.com/AMAP-ML/FluxText.git -
Install FluxText:
cd FluxText && pip install -r requirements.txt -
Integrate FluxText Comfy Nodes with ComfyUI:
- Symbolic Link (Recommended):
ln -s $(pwd)/ComfyUI-fluxtext path/to/ComfyUI/custom_nodes/ - Copy Directory:
cp -r ComfyUI-fluxtext path/to/ComfyUI/custom_nodes/
- Symbolic Link (Recommended):
🔥 Quick Start
Here's a basic example of using FLUX-Text:
import numpy as np
from PIL import Image
import torch
import yaml

from src.flux.condition import Condition
from src.flux.generate_fill import generate_fill
from src.train.model import OminiModelFIll
from safetensors.torch import load_file

config_path = ""
lora_path = ""
with open(config_path, "r") as f:
    config = yaml.safe_load(f)
model = OminiModelFIll(
        flux_pipe_id=config["flux_path"],
        lora_config=config["train"]["lora_config"],
        device=f"cuda",
        dtype=getattr(torch, config["dtype"]),
        optimizer_config=config["train"]["optimizer"],
        model_config=config.get("model", {}),
        gradient_checkpointing=True,
        byt5_encoder_config=None,
    )

state_dict = load_file(lora_path)
state_dict_new = {x.replace('lora_A', 'lora_A.default').replace('lora_B', 'lora_B.default').replace('transformer.', ''): v for x, v in state_dict.items()}
model.transformer.load_state_dict(state_dict_new, strict=False)
pipe = model.flux_pipe

prompt = "lepto college of education, the written materials on the picture: LESOTHO , COLLEGE OF , RE BONA LESELI LESEL , EDUCATION ."
hint = Image.open("assets/hint.png").resize((512, 512)).convert('RGB')
img = Image.open("assets/hint_imgs.jpg").resize((512, 512))
condition_img = Image.open("assets/hint_imgs_word.png").resize((512, 512)).convert('RGB')
hint = np.array(hint) / 255
condition_img = np.array(condition_img)
condition_img = (255 - condition_img) / 255
condition_img = [condition_img, hint, img]
position_delta = [0, 0]
condition = Condition(
                condition_type='word_fill',
                condition=condition_img,
                position_delta=position_delta,
            )
generator = torch.Generator(device="cuda")
res = generate_fill(
    pipe,
    prompt=prompt,
    conditions=[condition],
    height=512,
    width=512,
    generator=generator,
    model_config=config.get("model", {}),
    default_lora=True,
)
res.images[0].save('flux_fill.png')
🤗 gradio
You can upload the glyph image and mask image to edit text region. Or you can use manual edit to obtain glyph image and mask image.
first, download the model weight and config in HuggingFace
python app.py --model_path xx.safetensors --config_path config.yaml
💪🏻 Training
-
Download training dataset AnyWord-3M from ModelScope, unzip all *.zip files in each subfolder, then open *.json and modify the
data_rootwith your own path of imgs folder for each sub dataset. -
Replace the old annotations in AnyWord with the new annotations. Change the dataset annotations path and image_root in src/train/data_word.py.
json_paths = [
        ['dataset/Anyword/data_text_recog_glyph/Art/data-info.json', 'AnyWord-3M/ocr_data/Art/imgs/'],
        ['dataset/Anyword/data_text_recog_glyph/COCO_Text/data-info.json', 'AnyWord-3M/ocr_data/COCO_Text/imgs/'],
        ['dataset/Anyword/data_text_recog_glyph/icdar2017rctw/data-info.json', 'AnyWord-3M/ocr_data/icdar2017rctw/imgs'],
        ['dataset/Anyword/data_text_recog_glyph/LSVT/data-info.json', 'AnyWord-3M/ocr_data/LSVT/imgs'],
        ['dataset/Anyword/data_text_recog_glyph/mlt2019/data-info.json', 'AnyWord-3M/ocr_data/mlt2019/imgs/'],
        ['dataset/Anyword/data_text_recog_glyph/MTWI2018/data-info.json', 'AnyWord-3M/ocr_data/MTWI2018/imgs'],
        ['dataset/Anyword/data_text_recog_glyph/ReCTS/data-info.json', 'AnyWord-3M/ocr_data/ReCTS/imgs'],
        ['dataset/Anyword/data_text_recog_glyph/laion/data_v1.1-info.json', 'AnyWord-3M/laion/imgs'],
        ['dataset/Anyword/data_text_recog_glyph/wukong_1of5/data_v1.1-info.json', 'AnyWord-3M/wukong_1of5/imgs'],
        ['dataset/Anyword/data_text_recog_glyph/wukong_2of5/data_v1.1-info.json', 'AnyWord-3M/wukong_2of5/imgs'],
        ['dataset/Anyword/data_text_recog_glyph/wukong_3of5/data_v1.1-info.json', 'AnyWord-3M/wukong_3of5/imgs'],
        ['dataset/Anyword/data_text_recog_glyph/wukong_4of5/data_v1.1-info.json', 'AnyWord-3M/wukong_4of5/imgs'],
        ['dataset/Anyword/data_text_recog_glyph/wukong_5of5/data_v1.1-info.json', 'AnyWord-3M/wukong_5of5/imgs'],
        ]
-
Download the ODM weights in HuggingFace and change
odm_loss/modelpathin the config file. -
(Optional) Download the pretrained weight in HuggingFace and change
reuse_lora_pathin the config file. -
Run the training scripts. With 48GB of VRAM, you can train at 512×512 resolution with a batch size of 2 in LoRA rank 8.
bash train/script/train_word.sh
📊 Evaluation
For Anytext-benchmark, please set the config_path, model_path, json_path, output_dir in the eval/gen_imgs_anytext.sh and generate the text editing results.
bash eval/gen_imgs_anytext.sh
For Sen.ACC, NED, FID and LPIPS evaluation, use the scripts in the eval folder.
bash eval/eval_ocr.sh
bash eval/eval_fid.sh
bash eval/eval_lpips.sh
📈 Results
🌹 Acknowledgement
Our work is primarily based on OminiControl, AnyText, Open-Sora, Phantom. We are sincerely grateful for their excellent works.
📚 Citation
If you find our paper and code helpful for your research, please consider starring our repository ⭐ and citing our work ✏️.
@article{lan2025flux,
  title={Flux-text: A simple and advanced diffusion transformer baseline for scene text editing},
  author={Lan, Rui and Bai, Yancheng and Duan, Xu and Li, Mingxing and Jin, Dongyang and Xu, Ryan and Nie, Dong and Sun, Lei and Chu, Xiangxiang},
  journal={arXiv preprint arXiv:2505.03329},
  year={2025}
}
Similar repos
Languages
Python
99.8%