ADaM-BJTU/model-native-agentic-ai

Our survey's paper list on Agentic AI, continuously updated with the latest research.

100

58 commits

updated Oct 28, 2025

See the code

README

🧠 model-native-agentic-ai

Logo

Agentic AI: From Pipelines to Model-native

This repository contains a curated list of papers referenced in our survey:
Beyond Pipelines: A Survey of the Paradigm Shift toward Model-Native Agentic AI
We will continuously update this list with new, relevant papers.

Awesome

🙏 Citation

If you find our survey useful for your research, please consider citing our work:

@misc{sang2025pipelinessurveyparadigmshift,
      title={Beyond Pipelines: A Survey of the Paradigm Shift toward Model-Native Agentic AI}, 
      author={Jitao Sang and Jinlin Xiao and Jiarun Han and Jilin Chen and Xiaoyi Chen and Shuyu Wei and Yongjie Sun and Yuhang Wang},
      year={2025},
      eprint={2510.16720},
      archivePrefix={arXiv},
      primaryClass={cs.AI},
      url={https://arxiv.org/abs/2510.16720}, 
}

🌟 Abstract

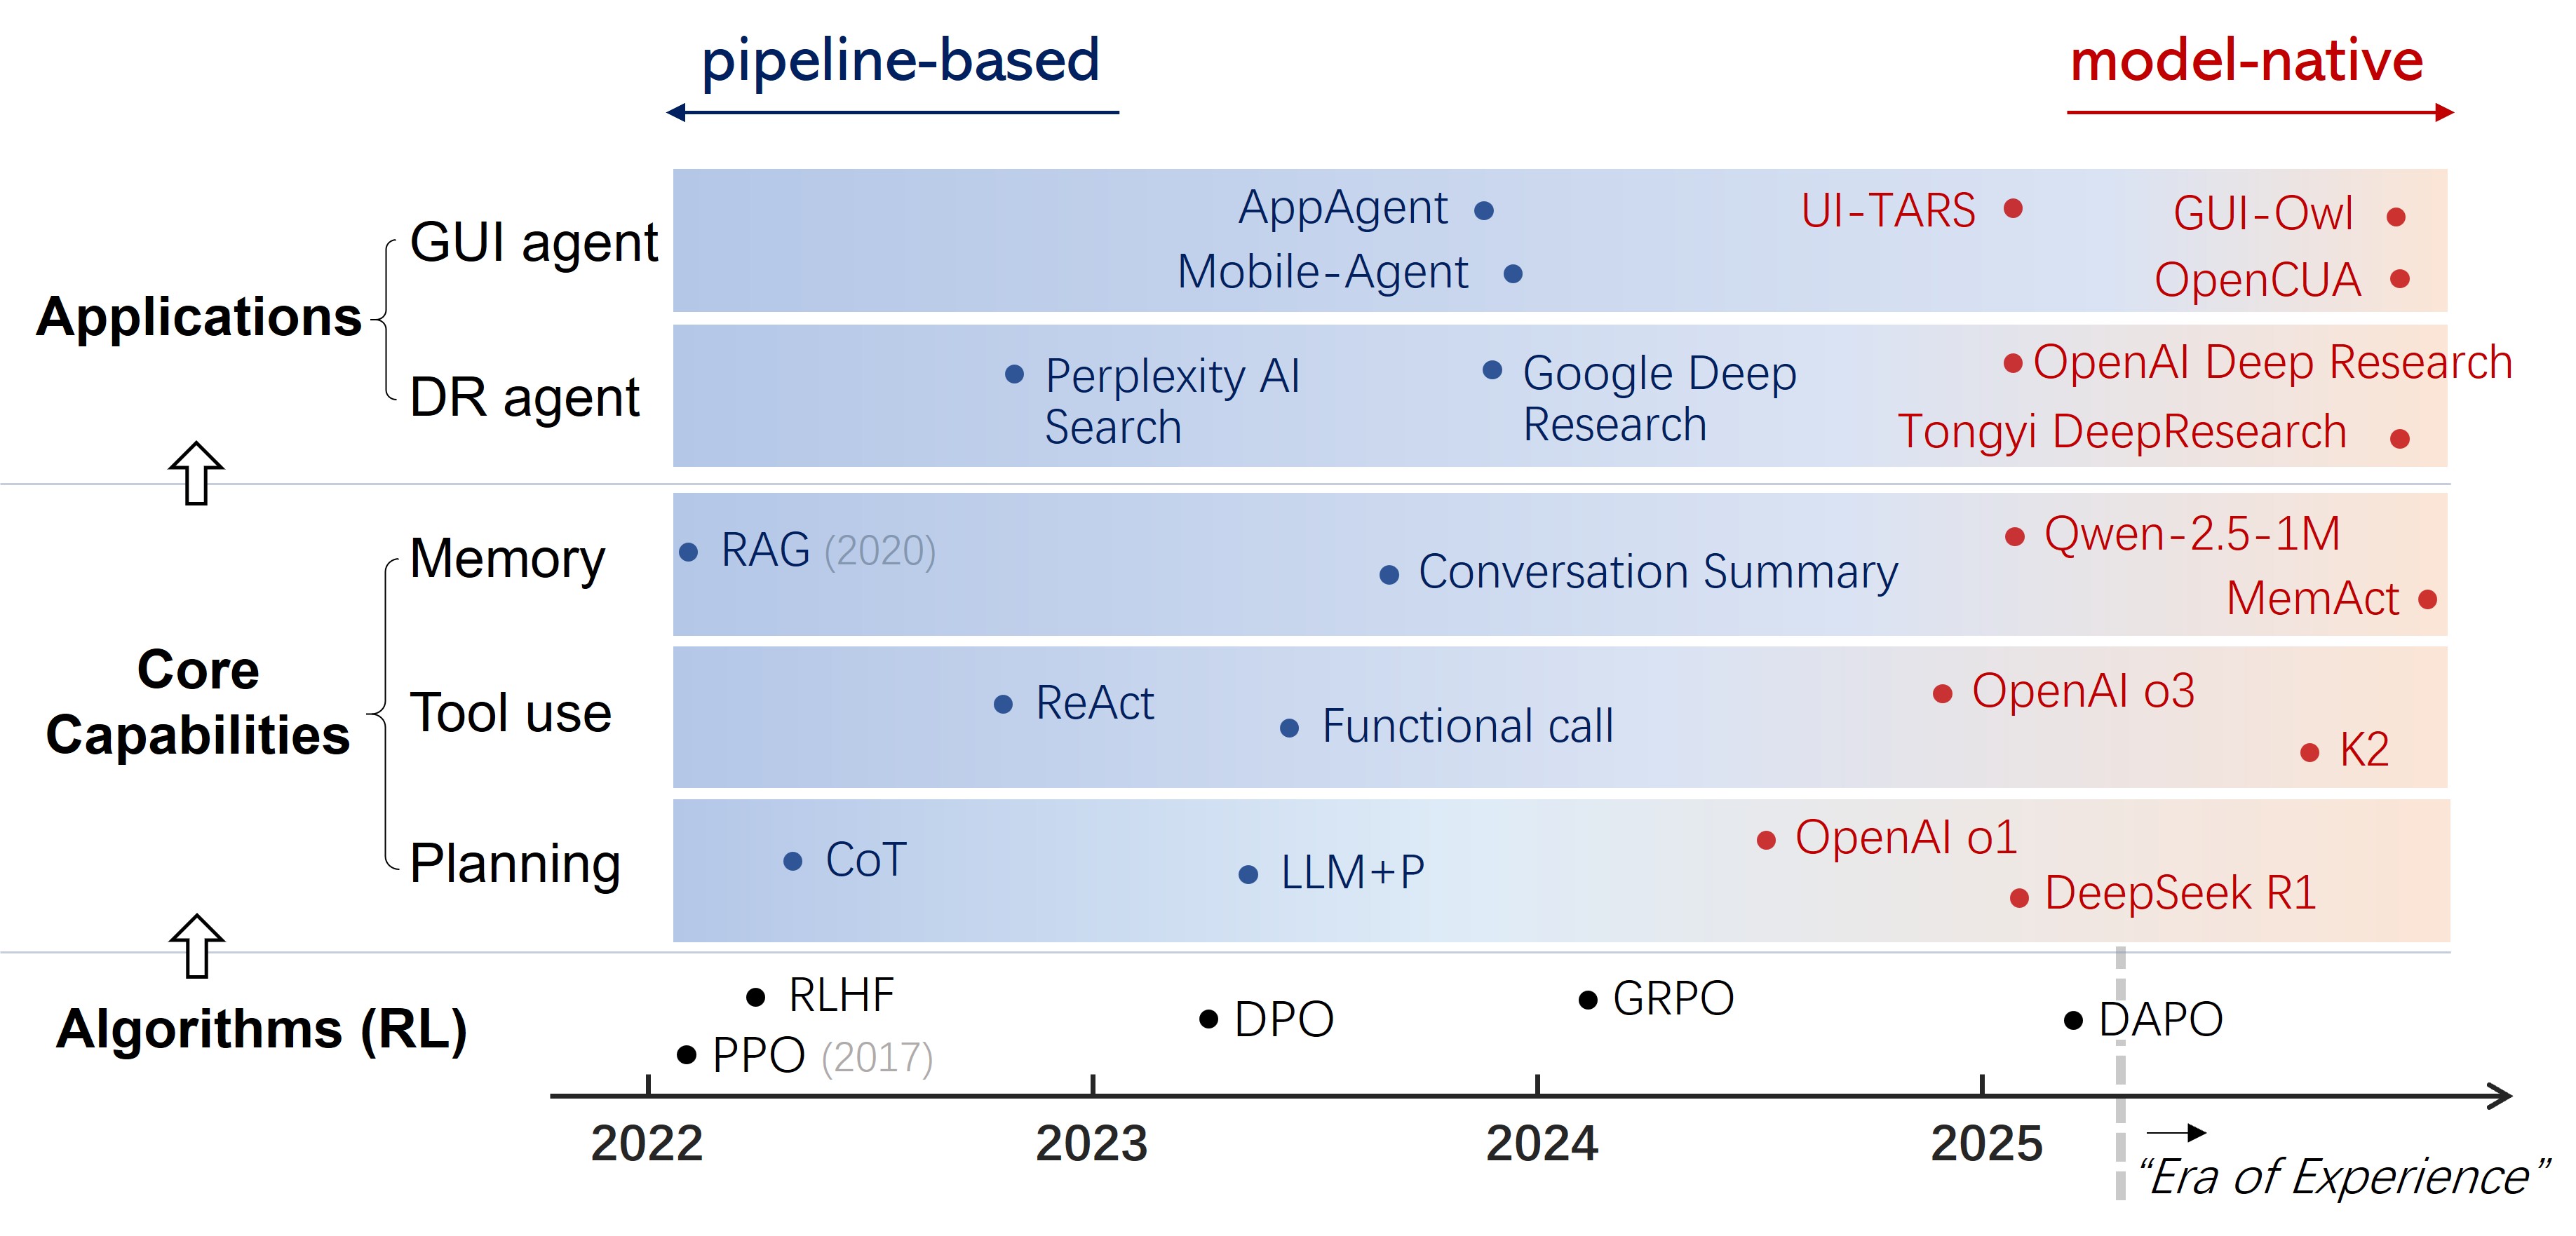
The rapid evolution of agentic AI marks a new phase in artificial intelligence, where Large Language Models (LLMs) no longer merely respond but act, reason, and adapt. This survey traces the paradigm shift in building agentic AI: from Pipeline-based systems, where planning, tool use, and memory are orchestrated by external logic, to the emerging Model-native paradigm, where these capabilities are internalized within the model’s parameters.

We first position Reinforcement Learning (RL) as the algorithmic engine enabling this paradigm shift. By reframing learning from imitating static data to outcome-driven exploration, RL underpins a unified solution of LLM + RL + Task across language, vision and embodied domains. Building on this, the survey systematically reviews how each capability—Planning, Tool use, and Memory—has evolved from externally scripted modules to end-to-end learned behaviors. Furthermore, it examines how this paradigm shift has reshaped major agent applications, specifically the Deep Research agent emphasizing long-horizon reasoning and the GUI agent emphasizing embodied interaction.

We conclude by discussing the continued internalization of agentic capabilities like Multi-agent collaboration and Reflection, alongside the evolving roles of the system and model layers in future agentic AI. Together, these developments outline a coherent trajectory toward model-native agentic AI as an integrated learning and interaction framework, marking the transition from constructing systems that apply intelligence to developing models that grow intelligence through experience.

📒 Table of Contents

📜 Papers

➤ 3  Core Capabilities: Planning

3.2  Pipeline-based Paradigm

3.3  Model-native Paradigm

Short NamePaperDateCode/Project Link
ReST-MCTS*ReST-MCTS*: LLM Self-Training via Process Reward Guided Tree Search2024-06GitHub Stars
Marco-o1Marco-o1: Towards Open Reasoning Models for Open-Ended Solutions2024-11GitHub Stars
HuatuoGPT-o1HuatuoGPT-o1, Towards Medical Complex Reasoning with LLMs2024-12GitHub Stars
Bespoke-StratosBespoke-Stratos: The unreasonable effectiveness of reasoning distillation2024-12Dataset
s1s1: Simple test-time scaling2025-01GitHub Stars
R1-Distill-SFTMillions scale dataset distilled from R1-32b2025-01Dataset
LIMOLIMO: Less is More for Reasoning2025-02GitHub Stars
BOLTBOLT: Bootstrap Long Chain-of-Thought in Language Models without Distillation2025-02-
AStarBoosting Multimodal Reasoning with Automated Structured Thinking2025-02-
FastMCTSFastMCTS: A Simple Sampling Strategy for Data Synthesis2025-02-
OpenThoughtsOpenThoughts: Data Recipes for Reasoning Models2025-06GitHub Stars
OpenR1-Math-220kOpen R1: A fully open reproduction of DeepSeek-R12025-02GitHub Stars
SYNTHETIC-1SYNTHETIC-1: Two Million Collaboratively Generated Reasoning Traces from Deepseek-R12025-02Dataset
WebSynthesisWebSynthesis: World-Model-Guided MCTS for Efficient WebUI-Trajectory Synthesis2025-07GitHub Stars
Math-ShepherdMath-Shepherd: Verify and Reinforce LLMs Step-by-step without Human Annotations2023-12Project
ReFTReFT: Reasoning with Reinforced Fine-Tuning2024-01GitHub Stars
OmegaPRMImprove Mathematical Reasoning in Language Models by Automated Process Supervision2024-06-
OpenAI o1Learning to reason with LLMs2024-09-
RLEFRLEF: Grounding Code LLMs in Execution Feedback with Reinforcement Learning2024-10-
o1-Codero1-Coder: an o1 Replication for Coding2024-01GitHub Stars
Implicit PRMFree Process Rewards without Process Labels2024-12-
ORPSReasoning Through Execution: Unifying Process and Outcome Rewards for Code Generation2024-12GitHub Stars
OpenRFTOpenRFT: Adapting Reasoning Foundation Model for Domain-specific Tasks with Reinforcement Fine-Tuning2024-12GitHub Stars
DeepSeek R1DeepSeek-R1: Incentivizing Reasoning Capability in LLMs via Reinforcement Learning2025-01GitHub Stars
Qwen-2.5-Math-PRMThe Lessons of Developing Process Reward Models in Mathematical Reasoning2025-01Model
Kimi k1.5Kimi k1.5: Scaling Reinforcement Learning with LLMs2025-01-
O1-PrunerO1-Pruner: Length-Harmonizing Fine-Tuning for O1-Like Reasoning Pruning2025-01GitHub Stars
PRIMEProcess Reinforcement through Implicit Rewards2025-02-
DeepScaleRDeepScaleR: Surpassing O1-Preview with a 1.5B Model by Scaling RL2025-02GitHub Stars
PRLCoderProcess-Supervised Reinforcement Learning for Code Generation2025-02-
L1L1: Controlling How Long A Reasoning Model Thinks With Reinforcement Learning2025.03GitHub Stars
DASTDAST: Difficulty-Adaptive Slow-Thinking for Large Reasoning Models2025.03GitHub Stars
QwQQwQ-32B: Embracing the Power of Reinforcement Learning2025-03HuggingFace
Skywork or1Skywork Open Reasoner Series2025-03GitHub Stars
Demystify-long-cotDemystifying Long Chain-of-Thought Reasoning in LLMs2025-02GitHub Stars
LLM-as-JudgeWho's Your Judge? On the Detectability of LLM-Generated Judgments2025-09-

➤ 4  Core Capabilities: Tool Use

4.2  Pipeline-based Paradigm

4.3  Model-native Paradigm

Short NamePaperDateCode/Project Link
Agent-as-ToolAgent-as-Tool: A Study on the Hierarchical Decision Making with Reinforcement Learning2025-07-
AI-SearchPlannerAI-SearchPlanner: Modular Agentic Search via Pareto-Optimal Multi-Objective Reinforcement Learning2025-08-
RLTREncouraging Good Processes Without the Need for Good Answers: Reinforcement Learning for LLM Agent Planning2025-08-
R1-SearcherR1-searcher: Incentivizing the search capability in llms via reinforcement learning2025-03GitHub Stars
ReSearchReSearch: Learning to Reason with Search for LLMs via Reinforcement Learning2025-03GitHub Stars
ToRLToRL: Tool-integrated Reinforcement Learning for LLM Agents2025-03GitHub Stars
Search-R1Search-R1: Training LLMs to Reason and Leverage Search Engines with Reinforcement Learning2025-03GitHub Stars
AutoCoAAgent models: Internalizing Chain-of-Action Generation into Reasoning models2025-03GitHub Stars
ReToolReTool: Reinforcement Learning for Strategic Tool Use in LLMs2025-04GitHub Stars
ToolRLToolRL: Reinforcement Learning for Tool-Use in Large Reasoning Models2025-04GitHub Stars
OTCActing Less is Reasoning More: Teaching Models Optimal Tool Calls via Reinforcement Learning2025-04-
DeepResearcherDeepResearcher: Scaling Deep Research via Reinforcement Learning in Real-world Environments2025-04GitHub Stars
ARTISTAgentic Reasoning and Tool Integration for LLMs via Reinforcement Learning2025-04-
WebThinkerWebthinker: Empowering large reasoning models with deep research capability2025-04GitHub Stars
RAGENRAGEN: Understanding Self-Evolution in LLM Agents via Multi-Turn Reinforcement Learning2025-04GitHub Stars
WebDancerWebDancer: Towards Autonomous Information Seeking Agency2025-05GitHub Stars
Tool-N1Tool-N1: Training General Tool-Use in Large Reasoning Models2025-05GitHub Stars
Satori-SWESatori-SWE: Evolutionary Test-Time Scaling for Sample-Efficient Software Engineering2025-05GitHub Stars
MaskSearchMaskSearch: A Universal Pre-Training Framework to Enhance Agentic Search Capability2025-05GitHub Stars
SkyRLSkyRL-v0: Train Real-World Long-Horizon Agents via Reinforcement Learning2025-05GitHub Stars
ZeroSearchZeroSearch: Incentivize the Search Capability of LLMs without Searching2025-05GitHub Stars
Agent RL ScalingAgent RL Scaling Law: Agent RL with Spontaneous Code Execution for Mathematical Problem Solving2025-05GitHub Stars
GIGPOGroup-in-Group Policy Optimization for LLM Agent Training2025-05GitHub Stars
VTool-R1VTool-R1: VLMs Learn to Think with Images via Reinforcement Learning on Multimodal Tool Use2025-05GitHub Stars
DeepEyesDeepEyes: Incentivizing "Thinking with Images" via Reinforcement Learning2025-05GitHub Stars
Multi-Turn-RLReinforcing Multi-Turn Reasoning in LLM Agents via Turn-Level Credit Assignment2025-05GitHub Stars
StepSearchStepSearch: Igniting LLMs Search Ability via Step-Wise Proximal Policy Optimization2025-05GitHub Stars
Spa-RLSPA-RL: Reinforcing LLM Agents via Stepwise Progress Attribution2025-05GitHub Stars
O^2-SearcherO^2-Searcher: A Searching-based Agent Model for Open-domain QA via Reinforcement Learning2025-05GitHub Stars
MMSearch-R1MMSearch-R1: Incentivizing LMMs to Search2025-06GitHub Stars
Agent-RLVRAgent-RLVR: Training Software Engineering Agents via Guidance and Environment Rewards2025-06-
AutoTIRAutoTIR: Autonomous Tools Integrated Reasoning via Reinforcement Learning2025-07GitHub Stars
Agent LightningAgent Lightning: Train ANY AI Agents with Reinforcement Learning2025-08GitHub Stars
FunRLExploring Superior Function Calls via Reinforcement Learning2025-08GitHub Stars
rStar2-AgentrStar2-Agent: Agentic Reasoning Technical Report2025-08GitHub Stars
ASearcherUnlocking Long-Horizon Agentic Search with Large-Scale Asynchronous Reinforcement Learning2025-08GitHub Stars

➤ 5  Core Capabilities: Memory

5.2  Short-Term Memory: Long Context

Pipeline-based paradigm

Model-native Paradigm

5.3  Short-Term Memory: Context Management

Pipeline-based paradigm

Model-native Paradigm

Short NamePaperDateCode/Project Link
G-MEMG-Memory: Tracing Hierarchical Memory for Multi-Agent Systems2024-12GitHub Stars
A-MemA-MEM: Agentic Memory for LLM Agents2025-02GitHub Stars
Intrinsic Memory AgentsIntrinsic Memory Agents: Heterogeneous Multi-Agent LLM Systems through Structured Contextual Memory2025-08-
EMUEfficient Episodic Memory Utilization of Cooperative Multi-Agent Reinforcement Learning2024-03GitHub Stars
Optimus-1Optimus-1: On-device Data of Task Execution and Decision Making for LLM-based Agents2025-06GitHub Stars
NemoriNemori: Self-Organizing Agent Memory Inspired by Cognitive Science2025-08-
RAPRAP: Retrieval-Augmented Planning with Contextual Memory for Multimodal LLM Agents2024-02GitHub Stars
TWMTemporal Working Memory: Query-Guided Segment Refinement for Enhanced Multimodal Understanding2025-02GitHub Stars
RCR-RouterRCR-Router: Efficient Role-Aware Context Routing for Multi-Agent LLM Systems with Structured Memory2025-08-
Learn-to-MemorizeLearn to Memorize: Optimizing LLM-based Agents with Adaptive Memory Framework2025-08GitHub Stars
Self-RAGSelf-RAG: Learning to Retrieve, Generate, and Critique through Self-Reflection2023-10GitHub Stars
TiMThink-in-Memory: Recalling and Post-thinking Enable LLMs with Long-Term Memory2023-11-
HippoRAGHippoRAG: Neurobiologically Inspired Long-Term Memory for Large Language Models2024-05GitHub Stars
MemAgentMemAgent: Reshaping Long-Context LLM with Multi-Conversation Memory and Reinforcement Learning2025-07GitHub Stars
Memory-R1Memory-R1: Enhancing Large Language Model Agents to Manage and Utilize Memories via Reinforcement Learning2025-08-

5.4  Long-Term Memory

➤ 6  Applications

6.1  Deep Research Agent

Pipeline-based paradigm

Model-native Paradigm

Short NamePaperDateCode/Project Link
R1-SearcherR1-searcher: Incentivizing the search capability in llms via reinforcement learning2025-03GitHub Stars
Search-R1Search-R1: Training LLMs to Reason and Leverage Search Engines with Reinforcement Learning2025-03GitHub Stars
ReSearchReSearch: Learning to Reason with Search for LLMs via Reinforcement Learning2025-03GitHub Stars
R1-Searcher++R1-Searcher++: Incentivizing the Dynamic Knowledge Acquisition of LLMs via Reinforcement Learning2025-05GitHub Stars
R-SearchR-Search: Empowering LLM Reasoning with Search via Multi-Reward Reinforcement Learning2025-06GitHub Stars
M2IO-R1M2IO-R1: An Efficient RL-Enhanced Reasoning Framework for Multimodal Retrieval Augmented Multimodal Generation2025-08-
DeepResearcherDeepResearcher: Scaling Deep Research via Reinforcement Learning in Real-world Environments2025-04GitHub Stars
WebThinkerWebthinker: Empowering large reasoning models with deep research capability2025-04GitHub Stars
ZeroSearchZeroSearch: Incentivize the Search Capability of LLMs without Searching2025-05GitHub Stars
MMSearch-R1MMSearch-R1: Incentivizing LMMs to Search2025-06GitHub Stars
WebWatcherWebWatcher: Breaking New Frontier of Vision-Language Deep Research Agent2025-09GitHub Stars
SFR-DeepResearchSfr-deepresearch: Towards effective reinforcement learning for autonomously reasoning single agents2025-09-
DeepDiveDeepdive: Advancing deep search agents with knowledge graphs and multi-turn rl2025-09GitHub Stars
WebResearcherWebResearcher: Unleashing unbounded reasoning capability in Long-Horizon Agents2025-09GitHub Stars

6.2  GUI Agent

Pipeline-based paradigm

Model-native Paradigm

Short NamePaperDateCode/Project Link
CogAgentCogAgent: A Visual Language Model for GUI Agents2023-12GitHub Stars
UGroundUGround: Towards Unified Visual Grounding with Unrolled Transformers2024-10GitHub Stars
CoATAndroid in the Zoo: Chain-of-Action-Thought for GUI Agents2024-03GitHub Stars
WEPOWEPO: web element preference optimization for LLM-based web navigation2024-12GitHub Stars
STEVESTEVE: A Step Verification Pipeline for Computer-use Agent Training2025-03GitHub Stars
ExplorerExplorer: Scaling Exploration-driven Web Trajectory Synthesis for Multimodal Web Agents2025-05GitHub Stars
OS-GenesisOS-Genesis: Automating GUI Agent Trajectory Construction via Reverse Task Synthesis2025-06GitHub Stars
Aria-UIAria-UI: Visual Grounding for GUI Instructions2024-12GitHub Stars
V-DroidAdvancing Mobile GUI Agents: A Verifier-Driven Approach to Practical Deployment2025-03GitHub Stars
SeeClickSeeClick: Harnessing GUI Grounding for Advanced Visual GUI Agents2024-02GitHub Stars
MobileFlowMobileFlow: A Multimodal LLM For Mobile GUI Agent2024-07-
UI-TARSUI-TARS: Pioneering Automated GUI Interaction with Native Agents2025-01GitHub Stars
GUICourseGUICourse: From General Vision Language Models to Versatile GUI Agents2025-05GitHub Stars
ZeroGUIZeroGUI: Automating Online GUI Learning at Zero Human Cost2025-05GitHub Stars
ARPOARPO:End-to-End Policy Optimization for GUI Agents with Experience Replay2025-05GitHub Stars
UItronUItron: Foundational GUI Agent with Advanced Perception and Planning2025-08GitHub Stars
GUI-OwlMobile-Agent-v3: Foundamental Agents for GUI Automation2025-08GitHub Stars
DARTEfficient Multi-turn RL for GUI Agents via Decoupled Training and Adaptive Data Curation2025-09GitHub Stars
GUI-R1GUI-R1: A Generalist R1-Style Vision-Language Action Model For GUI Agents2025-10GitHub Stars
OpenCUAOpenCUA: Open Foundations for Computer-Use Agents2025-10GitHub Stars

➤ 7  Future Direction and Discussion

7.1.1  Emerging Model-native Capabilities: Multi-agent Collaboration

Short NamePaperDateCode/Project Link
CAMELCAMEL: Communicative Agents for “Mind” Exploration of Large Language Model Society2023-03GitHub Stars Project
MetaGPTMetaGPT: Meta Programming for A Multi-Agent Collaborative Framework2023-08GitHub Stars
MADEncouraging Divergent Thinking in Large Language Models through Multi-Agent Debate2023-05GitHub Stars
MoAMixture-of-Agents Enhances Large Language Model Capabilities2024-06GitHub Stars
AFlowAFlow: Automating Agentic Workflow Generation2024-10GitHub Stars
MALTMALT: Improving Reasoning with Multi-Agent LLM Training2024-12-
CORYCoevolving with the Other You: Fine-Tuning LLM with Sequential Cooperative Multi-Agent Reinforcement Learning2024-10GitHub Stars
MARFTMARFT: Multi-Agent Reinforcement Fine-Tuning2025-04GitHub Stars
MAGRPOLLM Collaboration With Multi-Agent Reinforcement Learning2025-08-
RLCCFWisdom of the Crowd: Reinforcement Learning from Coevolutionary Collective Feedback2025-08-
MATPOMulti-Agent Tool-Integrated Policy Optimization2025-10GitHub Stars
MasHostMasHost Builds It All: Autonomous Multi-Agent System Directed by Reinforcement Learning2025-06-
G-DesignerG-Designer: Architecting Multi-agent Communication Topologies via Graph Neural Networks2024-10GitHub Stars
ARG-DesignerAssemble Your Crew: Automatic Multi-agent Communication Topology Design via Autoregressive Graph Generation2025-07GitHub Stars
MAGDiMAGDi: Structured Distillation of Multi-Agent Interaction Graphs Improves Reasoning in Smaller Language Models2024-02GitHub Stars
CoAChain-of-Agents: End-to-End Agent Foundation Models via Multi-Agent Distillation and Agentic RL2025-08GitHub Stars

7.1.2  Emerging Model-native Capabilities: Reflection

Contributors

ADaM-BJTU

39 commits

FairyLinya

16 commits

Weizhena

2 commits

ADaM-BJTU/model-native-agentic-ai

Our survey's paper list on Agentic AI, continuously updated with the latest research.

100

58 commits

updated Oct 28, 2025

See the code

README

🧠 model-native-agentic-ai

Logo

Agentic AI: From Pipelines to Model-native

This repository contains a curated list of papers referenced in our survey:
Beyond Pipelines: A Survey of the Paradigm Shift toward Model-Native Agentic AI
We will continuously update this list with new, relevant papers.

Awesome

🙏 Citation

If you find our survey useful for your research, please consider citing our work:

@misc{sang2025pipelinessurveyparadigmshift,
      title={Beyond Pipelines: A Survey of the Paradigm Shift toward Model-Native Agentic AI}, 
      author={Jitao Sang and Jinlin Xiao and Jiarun Han and Jilin Chen and Xiaoyi Chen and Shuyu Wei and Yongjie Sun and Yuhang Wang},
      year={2025},
      eprint={2510.16720},
      archivePrefix={arXiv},
      primaryClass={cs.AI},
      url={https://arxiv.org/abs/2510.16720}, 
}

🌟 Abstract

The rapid evolution of agentic AI marks a new phase in artificial intelligence, where Large Language Models (LLMs) no longer merely respond but act, reason, and adapt. This survey traces the paradigm shift in building agentic AI: from Pipeline-based systems, where planning, tool use, and memory are orchestrated by external logic, to the emerging Model-native paradigm, where these capabilities are internalized within the model’s parameters.

We first position Reinforcement Learning (RL) as the algorithmic engine enabling this paradigm shift. By reframing learning from imitating static data to outcome-driven exploration, RL underpins a unified solution of LLM + RL + Task across language, vision and embodied domains. Building on this, the survey systematically reviews how each capability—Planning, Tool use, and Memory—has evolved from externally scripted modules to end-to-end learned behaviors. Furthermore, it examines how this paradigm shift has reshaped major agent applications, specifically the Deep Research agent emphasizing long-horizon reasoning and the GUI agent emphasizing embodied interaction.

We conclude by discussing the continued internalization of agentic capabilities like Multi-agent collaboration and Reflection, alongside the evolving roles of the system and model layers in future agentic AI. Together, these developments outline a coherent trajectory toward model-native agentic AI as an integrated learning and interaction framework, marking the transition from constructing systems that apply intelligence to developing models that grow intelligence through experience.

📒 Table of Contents

📜 Papers

➤ 3  Core Capabilities: Planning

3.2  Pipeline-based Paradigm

3.3  Model-native Paradigm

Short NamePaperDateCode/Project Link
ReST-MCTS*ReST-MCTS*: LLM Self-Training via Process Reward Guided Tree Search2024-06GitHub Stars
Marco-o1Marco-o1: Towards Open Reasoning Models for Open-Ended Solutions2024-11GitHub Stars
HuatuoGPT-o1HuatuoGPT-o1, Towards Medical Complex Reasoning with LLMs2024-12GitHub Stars
Bespoke-StratosBespoke-Stratos: The unreasonable effectiveness of reasoning distillation2024-12Dataset
s1s1: Simple test-time scaling2025-01GitHub Stars
R1-Distill-SFTMillions scale dataset distilled from R1-32b2025-01Dataset
LIMOLIMO: Less is More for Reasoning2025-02GitHub Stars
BOLTBOLT: Bootstrap Long Chain-of-Thought in Language Models without Distillation2025-02-
AStarBoosting Multimodal Reasoning with Automated Structured Thinking2025-02-
FastMCTSFastMCTS: A Simple Sampling Strategy for Data Synthesis2025-02-
OpenThoughtsOpenThoughts: Data Recipes for Reasoning Models2025-06GitHub Stars
OpenR1-Math-220kOpen R1: A fully open reproduction of DeepSeek-R12025-02GitHub Stars
SYNTHETIC-1SYNTHETIC-1: Two Million Collaboratively Generated Reasoning Traces from Deepseek-R12025-02Dataset
WebSynthesisWebSynthesis: World-Model-Guided MCTS for Efficient WebUI-Trajectory Synthesis2025-07GitHub Stars
Math-ShepherdMath-Shepherd: Verify and Reinforce LLMs Step-by-step without Human Annotations2023-12Project
ReFTReFT: Reasoning with Reinforced Fine-Tuning2024-01GitHub Stars
OmegaPRMImprove Mathematical Reasoning in Language Models by Automated Process Supervision2024-06-
OpenAI o1Learning to reason with LLMs2024-09-
RLEFRLEF: Grounding Code LLMs in Execution Feedback with Reinforcement Learning2024-10-
o1-Codero1-Coder: an o1 Replication for Coding2024-01GitHub Stars
Implicit PRMFree Process Rewards without Process Labels2024-12-
ORPSReasoning Through Execution: Unifying Process and Outcome Rewards for Code Generation2024-12GitHub Stars
OpenRFTOpenRFT: Adapting Reasoning Foundation Model for Domain-specific Tasks with Reinforcement Fine-Tuning2024-12GitHub Stars
DeepSeek R1DeepSeek-R1: Incentivizing Reasoning Capability in LLMs via Reinforcement Learning2025-01GitHub Stars
Qwen-2.5-Math-PRMThe Lessons of Developing Process Reward Models in Mathematical Reasoning2025-01Model
Kimi k1.5Kimi k1.5: Scaling Reinforcement Learning with LLMs2025-01-
O1-PrunerO1-Pruner: Length-Harmonizing Fine-Tuning for O1-Like Reasoning Pruning2025-01GitHub Stars
PRIMEProcess Reinforcement through Implicit Rewards2025-02-
DeepScaleRDeepScaleR: Surpassing O1-Preview with a 1.5B Model by Scaling RL2025-02GitHub Stars
PRLCoderProcess-Supervised Reinforcement Learning for Code Generation2025-02-
L1L1: Controlling How Long A Reasoning Model Thinks With Reinforcement Learning2025.03GitHub Stars
DASTDAST: Difficulty-Adaptive Slow-Thinking for Large Reasoning Models2025.03GitHub Stars
QwQQwQ-32B: Embracing the Power of Reinforcement Learning2025-03HuggingFace
Skywork or1Skywork Open Reasoner Series2025-03GitHub Stars
Demystify-long-cotDemystifying Long Chain-of-Thought Reasoning in LLMs2025-02GitHub Stars
LLM-as-JudgeWho's Your Judge? On the Detectability of LLM-Generated Judgments2025-09-

➤ 4  Core Capabilities: Tool Use

4.2  Pipeline-based Paradigm

4.3  Model-native Paradigm

Short NamePaperDateCode/Project Link
Agent-as-ToolAgent-as-Tool: A Study on the Hierarchical Decision Making with Reinforcement Learning2025-07-
AI-SearchPlannerAI-SearchPlanner: Modular Agentic Search via Pareto-Optimal Multi-Objective Reinforcement Learning2025-08-
RLTREncouraging Good Processes Without the Need for Good Answers: Reinforcement Learning for LLM Agent Planning2025-08-
R1-SearcherR1-searcher: Incentivizing the search capability in llms via reinforcement learning2025-03GitHub Stars
ReSearchReSearch: Learning to Reason with Search for LLMs via Reinforcement Learning2025-03GitHub Stars
ToRLToRL: Tool-integrated Reinforcement Learning for LLM Agents2025-03GitHub Stars
Search-R1Search-R1: Training LLMs to Reason and Leverage Search Engines with Reinforcement Learning2025-03GitHub Stars
AutoCoAAgent models: Internalizing Chain-of-Action Generation into Reasoning models2025-03GitHub Stars
ReToolReTool: Reinforcement Learning for Strategic Tool Use in LLMs2025-04GitHub Stars
ToolRLToolRL: Reinforcement Learning for Tool-Use in Large Reasoning Models2025-04GitHub Stars
OTCActing Less is Reasoning More: Teaching Models Optimal Tool Calls via Reinforcement Learning2025-04-
DeepResearcherDeepResearcher: Scaling Deep Research via Reinforcement Learning in Real-world Environments2025-04GitHub Stars
ARTISTAgentic Reasoning and Tool Integration for LLMs via Reinforcement Learning2025-04-
WebThinkerWebthinker: Empowering large reasoning models with deep research capability2025-04GitHub Stars
RAGENRAGEN: Understanding Self-Evolution in LLM Agents via Multi-Turn Reinforcement Learning2025-04GitHub Stars
WebDancerWebDancer: Towards Autonomous Information Seeking Agency2025-05GitHub Stars
Tool-N1Tool-N1: Training General Tool-Use in Large Reasoning Models2025-05GitHub Stars
Satori-SWESatori-SWE: Evolutionary Test-Time Scaling for Sample-Efficient Software Engineering2025-05GitHub Stars
MaskSearchMaskSearch: A Universal Pre-Training Framework to Enhance Agentic Search Capability2025-05GitHub Stars
SkyRLSkyRL-v0: Train Real-World Long-Horizon Agents via Reinforcement Learning2025-05GitHub Stars
ZeroSearchZeroSearch: Incentivize the Search Capability of LLMs without Searching2025-05GitHub Stars
Agent RL ScalingAgent RL Scaling Law: Agent RL with Spontaneous Code Execution for Mathematical Problem Solving2025-05GitHub Stars
GIGPOGroup-in-Group Policy Optimization for LLM Agent Training2025-05GitHub Stars
VTool-R1VTool-R1: VLMs Learn to Think with Images via Reinforcement Learning on Multimodal Tool Use2025-05GitHub Stars
DeepEyesDeepEyes: Incentivizing "Thinking with Images" via Reinforcement Learning2025-05GitHub Stars
Multi-Turn-RLReinforcing Multi-Turn Reasoning in LLM Agents via Turn-Level Credit Assignment2025-05GitHub Stars
StepSearchStepSearch: Igniting LLMs Search Ability via Step-Wise Proximal Policy Optimization2025-05GitHub Stars
Spa-RLSPA-RL: Reinforcing LLM Agents via Stepwise Progress Attribution2025-05GitHub Stars
O^2-SearcherO^2-Searcher: A Searching-based Agent Model for Open-domain QA via Reinforcement Learning2025-05GitHub Stars
MMSearch-R1MMSearch-R1: Incentivizing LMMs to Search2025-06GitHub Stars
Agent-RLVRAgent-RLVR: Training Software Engineering Agents via Guidance and Environment Rewards2025-06-
AutoTIRAutoTIR: Autonomous Tools Integrated Reasoning via Reinforcement Learning2025-07GitHub Stars
Agent LightningAgent Lightning: Train ANY AI Agents with Reinforcement Learning2025-08GitHub Stars
FunRLExploring Superior Function Calls via Reinforcement Learning2025-08GitHub Stars
rStar2-AgentrStar2-Agent: Agentic Reasoning Technical Report2025-08GitHub Stars
ASearcherUnlocking Long-Horizon Agentic Search with Large-Scale Asynchronous Reinforcement Learning2025-08GitHub Stars

➤ 5  Core Capabilities: Memory

5.2  Short-Term Memory: Long Context

Pipeline-based paradigm

Model-native Paradigm

5.3  Short-Term Memory: Context Management

Pipeline-based paradigm

Model-native Paradigm

Short NamePaperDateCode/Project Link
G-MEMG-Memory: Tracing Hierarchical Memory for Multi-Agent Systems2024-12GitHub Stars
A-MemA-MEM: Agentic Memory for LLM Agents2025-02GitHub Stars
Intrinsic Memory AgentsIntrinsic Memory Agents: Heterogeneous Multi-Agent LLM Systems through Structured Contextual Memory2025-08-
EMUEfficient Episodic Memory Utilization of Cooperative Multi-Agent Reinforcement Learning2024-03GitHub Stars
Optimus-1Optimus-1: On-device Data of Task Execution and Decision Making for LLM-based Agents2025-06GitHub Stars
NemoriNemori: Self-Organizing Agent Memory Inspired by Cognitive Science2025-08-
RAPRAP: Retrieval-Augmented Planning with Contextual Memory for Multimodal LLM Agents2024-02GitHub Stars
TWMTemporal Working Memory: Query-Guided Segment Refinement for Enhanced Multimodal Understanding2025-02GitHub Stars
RCR-RouterRCR-Router: Efficient Role-Aware Context Routing for Multi-Agent LLM Systems with Structured Memory2025-08-
Learn-to-MemorizeLearn to Memorize: Optimizing LLM-based Agents with Adaptive Memory Framework2025-08GitHub Stars
Self-RAGSelf-RAG: Learning to Retrieve, Generate, and Critique through Self-Reflection2023-10GitHub Stars
TiMThink-in-Memory: Recalling and Post-thinking Enable LLMs with Long-Term Memory2023-11-
HippoRAGHippoRAG: Neurobiologically Inspired Long-Term Memory for Large Language Models2024-05GitHub Stars
MemAgentMemAgent: Reshaping Long-Context LLM with Multi-Conversation Memory and Reinforcement Learning2025-07GitHub Stars
Memory-R1Memory-R1: Enhancing Large Language Model Agents to Manage and Utilize Memories via Reinforcement Learning2025-08-

5.4  Long-Term Memory

➤ 6  Applications

6.1  Deep Research Agent

Pipeline-based paradigm

Model-native Paradigm

Short NamePaperDateCode/Project Link
R1-SearcherR1-searcher: Incentivizing the search capability in llms via reinforcement learning2025-03GitHub Stars
Search-R1Search-R1: Training LLMs to Reason and Leverage Search Engines with Reinforcement Learning2025-03GitHub Stars
ReSearchReSearch: Learning to Reason with Search for LLMs via Reinforcement Learning2025-03GitHub Stars
R1-Searcher++R1-Searcher++: Incentivizing the Dynamic Knowledge Acquisition of LLMs via Reinforcement Learning2025-05GitHub Stars
R-SearchR-Search: Empowering LLM Reasoning with Search via Multi-Reward Reinforcement Learning2025-06GitHub Stars
M2IO-R1M2IO-R1: An Efficient RL-Enhanced Reasoning Framework for Multimodal Retrieval Augmented Multimodal Generation2025-08-
DeepResearcherDeepResearcher: Scaling Deep Research via Reinforcement Learning in Real-world Environments2025-04GitHub Stars
WebThinkerWebthinker: Empowering large reasoning models with deep research capability2025-04GitHub Stars
ZeroSearchZeroSearch: Incentivize the Search Capability of LLMs without Searching2025-05GitHub Stars
MMSearch-R1MMSearch-R1: Incentivizing LMMs to Search2025-06GitHub Stars
WebWatcherWebWatcher: Breaking New Frontier of Vision-Language Deep Research Agent2025-09GitHub Stars
SFR-DeepResearchSfr-deepresearch: Towards effective reinforcement learning for autonomously reasoning single agents2025-09-
DeepDiveDeepdive: Advancing deep search agents with knowledge graphs and multi-turn rl2025-09GitHub Stars
WebResearcherWebResearcher: Unleashing unbounded reasoning capability in Long-Horizon Agents2025-09GitHub Stars

6.2  GUI Agent

Pipeline-based paradigm

Model-native Paradigm

Short NamePaperDateCode/Project Link
CogAgentCogAgent: A Visual Language Model for GUI Agents2023-12GitHub Stars
UGroundUGround: Towards Unified Visual Grounding with Unrolled Transformers2024-10GitHub Stars
CoATAndroid in the Zoo: Chain-of-Action-Thought for GUI Agents2024-03GitHub Stars
WEPOWEPO: web element preference optimization for LLM-based web navigation2024-12GitHub Stars
STEVESTEVE: A Step Verification Pipeline for Computer-use Agent Training2025-03GitHub Stars
ExplorerExplorer: Scaling Exploration-driven Web Trajectory Synthesis for Multimodal Web Agents2025-05GitHub Stars
OS-GenesisOS-Genesis: Automating GUI Agent Trajectory Construction via Reverse Task Synthesis2025-06GitHub Stars
Aria-UIAria-UI: Visual Grounding for GUI Instructions2024-12GitHub Stars
V-DroidAdvancing Mobile GUI Agents: A Verifier-Driven Approach to Practical Deployment2025-03GitHub Stars
SeeClickSeeClick: Harnessing GUI Grounding for Advanced Visual GUI Agents2024-02GitHub Stars
MobileFlowMobileFlow: A Multimodal LLM For Mobile GUI Agent2024-07-
UI-TARSUI-TARS: Pioneering Automated GUI Interaction with Native Agents2025-01GitHub Stars
GUICourseGUICourse: From General Vision Language Models to Versatile GUI Agents2025-05GitHub Stars
ZeroGUIZeroGUI: Automating Online GUI Learning at Zero Human Cost2025-05GitHub Stars
ARPOARPO:End-to-End Policy Optimization for GUI Agents with Experience Replay2025-05GitHub Stars
UItronUItron: Foundational GUI Agent with Advanced Perception and Planning2025-08GitHub Stars
GUI-OwlMobile-Agent-v3: Foundamental Agents for GUI Automation2025-08GitHub Stars
DARTEfficient Multi-turn RL for GUI Agents via Decoupled Training and Adaptive Data Curation2025-09GitHub Stars
GUI-R1GUI-R1: A Generalist R1-Style Vision-Language Action Model For GUI Agents2025-10GitHub Stars
OpenCUAOpenCUA: Open Foundations for Computer-Use Agents2025-10GitHub Stars

➤ 7  Future Direction and Discussion

7.1.1  Emerging Model-native Capabilities: Multi-agent Collaboration

Short NamePaperDateCode/Project Link
CAMELCAMEL: Communicative Agents for “Mind” Exploration of Large Language Model Society2023-03GitHub Stars Project
MetaGPTMetaGPT: Meta Programming for A Multi-Agent Collaborative Framework2023-08GitHub Stars
MADEncouraging Divergent Thinking in Large Language Models through Multi-Agent Debate2023-05GitHub Stars
MoAMixture-of-Agents Enhances Large Language Model Capabilities2024-06GitHub Stars
AFlowAFlow: Automating Agentic Workflow Generation2024-10GitHub Stars
MALTMALT: Improving Reasoning with Multi-Agent LLM Training2024-12-
CORYCoevolving with the Other You: Fine-Tuning LLM with Sequential Cooperative Multi-Agent Reinforcement Learning2024-10GitHub Stars
MARFTMARFT: Multi-Agent Reinforcement Fine-Tuning2025-04GitHub Stars
MAGRPOLLM Collaboration With Multi-Agent Reinforcement Learning2025-08-
RLCCFWisdom of the Crowd: Reinforcement Learning from Coevolutionary Collective Feedback2025-08-
MATPOMulti-Agent Tool-Integrated Policy Optimization2025-10GitHub Stars
MasHostMasHost Builds It All: Autonomous Multi-Agent System Directed by Reinforcement Learning2025-06-
G-DesignerG-Designer: Architecting Multi-agent Communication Topologies via Graph Neural Networks2024-10GitHub Stars
ARG-DesignerAssemble Your Crew: Automatic Multi-agent Communication Topology Design via Autoregressive Graph Generation2025-07GitHub Stars
MAGDiMAGDi: Structured Distillation of Multi-Agent Interaction Graphs Improves Reasoning in Smaller Language Models2024-02GitHub Stars
CoAChain-of-Agents: End-to-End Agent Foundation Models via Multi-Agent Distillation and Agentic RL2025-08GitHub Stars

7.1.2  Emerging Model-native Capabilities: Reflection

Contributors

ADaM-BJTU

39 commits

FairyLinya

16 commits

Weizhena

2 commits