
This repository will continuously update the latest papers, technical reports, benchmarks about multimodal reasoning!
56
13 commits
updated Mar 21, 2025
README
Mind with Eyes: From Language Reasoning to Multimodal Reasoning
This repository will continuously update the latest Papers, technical reports, benchmarks about multimodal reasoning!
🎇 Introduction
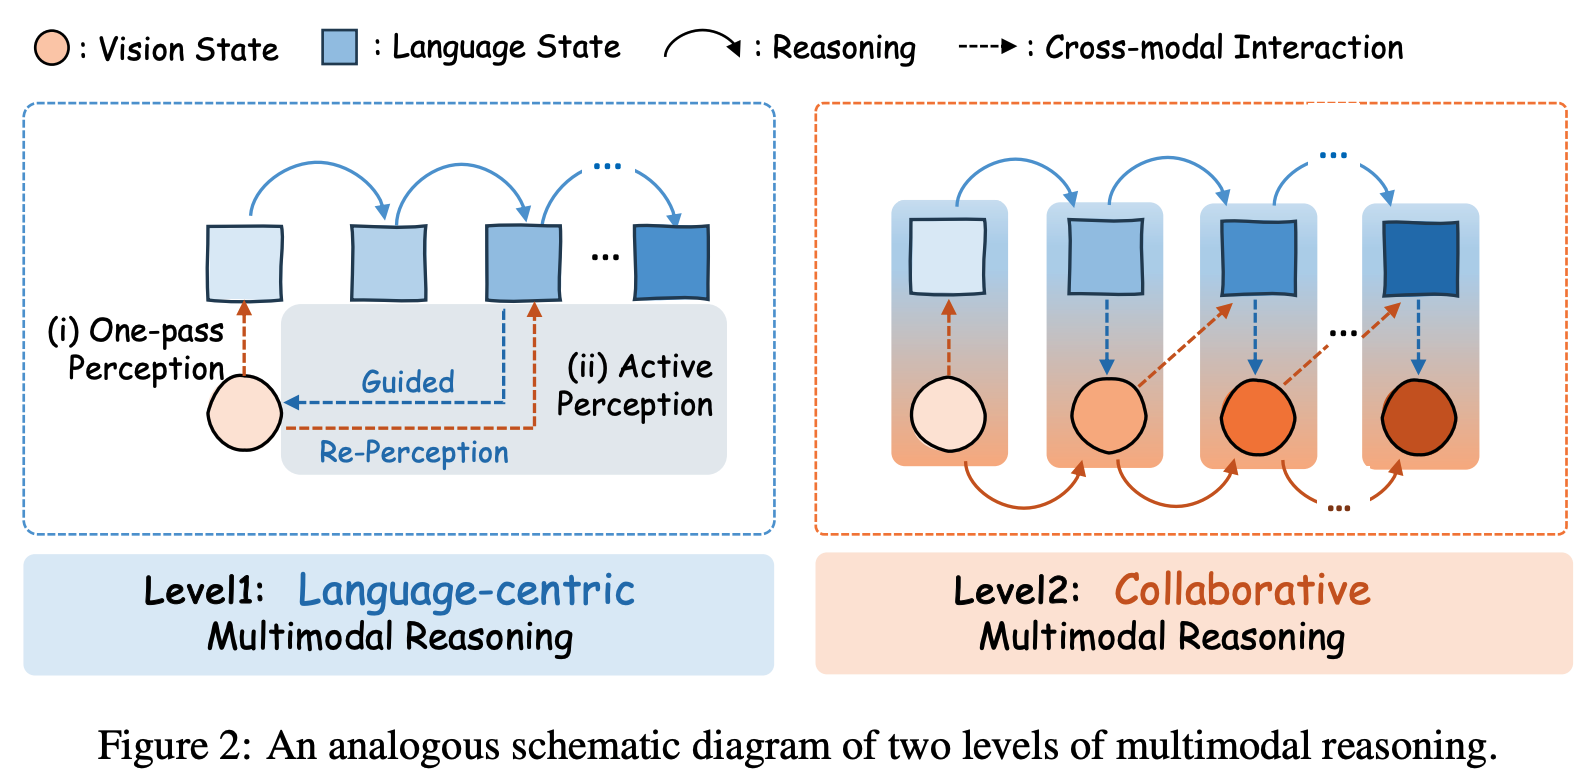 Language models have recently advanced into the realm of reasoning, yet it is through multimodal reasoning that we can fully unlock the potential to achieve more comprehensive, human-like cognitive capabilities. This survey provides a systematic overview of the recent multimodal reasoning approaches, categorizing them into two levels: language-centric multimodal reasoning and collaborative multimodal reasoning. The former encompasses one-pass visual perception and active visual perception, where vision primarily serves a supporting role in language reasoning. The latter involves action generation and state update within reasoning process, enabling a more dynamic interaction between modalities. Furthermore, we analyze the technical evolution of these methods, discuss their inherent challenges, and introduce key benchmark tasks and evaluation metrics for assessing multimodal reasoning performance. Finally, we provide insights into future research directions from the following two perspectives: (i) from visual-language reasoning to omnimodal reasoning and (ii) from multimodal reasoning to multimodal agents. This survey aims to provide a structured overview that will inspire further advancements in multimodal reasoning research.
📢 Updates
- ✨ 2025.03.21: The paper is now available in here.
- 🚀 2025.03.15: We released this repo.
📚 Table of Contents
- 1. Language-centric Multimodal Reasoning
- 2. Collaborative Multimodal Reasoning
- 3. Benchmarks on Multimodal Reasoning
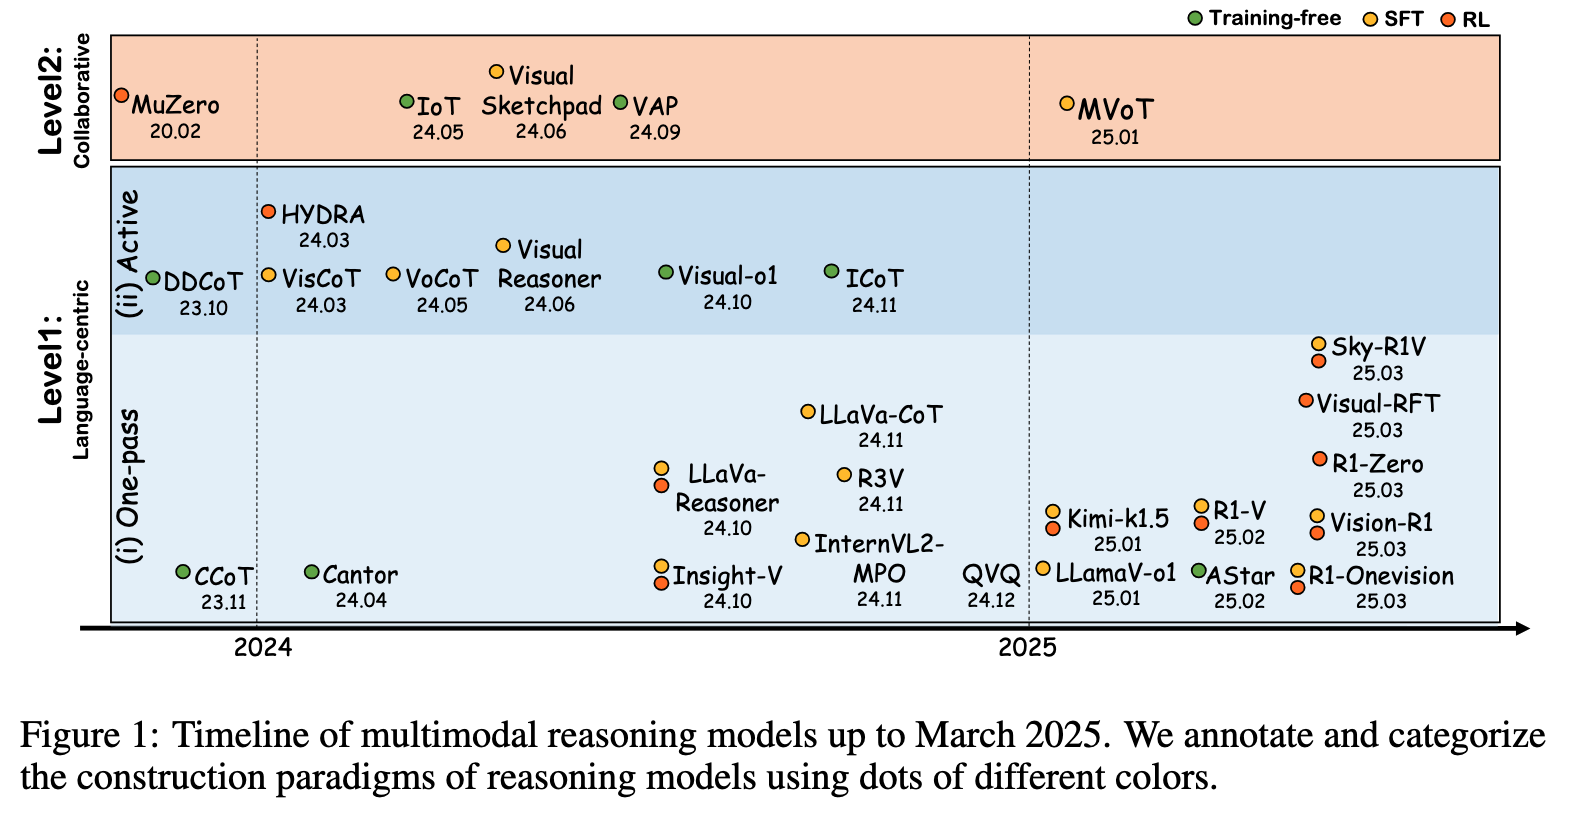
📖 1. Language-centric Multimodal Reasoning
📝 One-pass Visual Perception
- [2502] [R1-Onevision:An Open-Source Multimodal Large Language Model Capable of Deep Reasoning] (R1-Onevision) [Paper] [Code]
- [2502] [R1-V: Reinforcing Super Generalization Ability in Vision Language Models with Less Than $3] (R1-V) [Code]
- [2502] [Boosting Multimodal Reasoning with MCTS-Automated Structured Thinking] [Paper]
- [2501] [LlamaV-o1: Rethinking Step-by-step Visual Reasoning in LLM] (LlamaV-o1) [Paper] [Code]
- [2501] [Kimi k1.5: Scaling Reinforcement Learning with Large Language Models] (Kimi k1.5) [Paper] [Code]
- [2412] [Mulberry: Empowering MLLM with o1-like Reasoning and Reflection via Collective Monte Carlo Tree Search] (Mulberry) [Paper] [Code]
- [2411] [LLaVA-CoT: Let Vision Language Models Reason Step-by-Step] (LLaVA-CoT) [Paper] [Code]
- [2411] [Insight-V: Exploring Long-Chain Visual Reasoning with Multimodal Large Language Models] (Insight-V) [Paper] [Code]
- [2411] [Enhancing the Reasoning Ability of Multimodal Large Language Models via Mixed Preference Optimization] [Paper] [Code]
- [2411] [Vision-Language Models Can Self-Improve Reasoning via Reflection] () [Paper] [Code]
- [2410] [Improve Vision Language Model Chain-of-thought Reasoning] [Paper] [Code]
- [2404] [Cantor:Inspiring Multimodal Chain-of-Thought of MLLM] (Cantor) [Paper] [Code]
- [2403] [Visual CoT: Advancing Multi-Modal Language Models with a Comprehensive Dataset and Benchmark for Chain-of-Thought Reasoning] (Visual CoT) [Paper] [Code]
- [2311] [Compositional Chain-of-Thought Prompting for Large Multimodal Models] [Paper] [Code]
📝 Active Visual Perception
- [2411] [Interleaved-Modal Chain-of-Thought] [Paper]
- [2410] [Visual-o1: Understanding ambiguous instructions via multi-modal multi-turn chain-of-thoughts reasoning] (Visual-o1) [Paper]
- [2408] [Visual Agents As Fast And Slow Thinkers] (sys2-llava) [Paper] [Code]
- [2406] [From the Least to the Most: Building a Plug-and-Play Visual Reasoner via Data Synthesis] (VisualReasoner) [Paper] [Code]
- [2405] [VoCoT: Unleashing Visually Grounded Multi-Step Reasoning in Large Multi-Modal Models] (VoCoT) [Paper] [Code]
- [2403] [HYDRA: A Hyper Agent for Dynamic Compositional Visual Reasoning] (HYDRA) [Paper] [Code]
- [2310] [DDCoT: Duty-Distinct Chain-of-Thought Prompting for Multimodal Reasoning in Language Models] (DDCoT) [Paper] [Code]
🚀 2. Collaborative Multimodal Reasoning
- [2502] [Investigating Inference-time Scaling for Chain of Multi-modal Thought: A Preliminary Study] [Paper]
- [2501] [Imagine while Reasoning in Space: Multimodal Visualization-of-Thought] (MVoT) [Paper]
- [2409] [Enhancing LLM Reasoning via Vision-Augmented Prompting] [Paper] [Code]
- [2406] [Visual SKETCHPAD: Sketching as a Visual Chain of Thought for Multimodal Language Models] (Visual SKETCHPAD) [Paper] [Code]
- [2405] [Image-of-Thought Prompting for Visual Reasoning Refinement in Multimodal Large Language Models] (IoT) [Paper]
📊 3. Benchmarks on Multimodal Reasoning
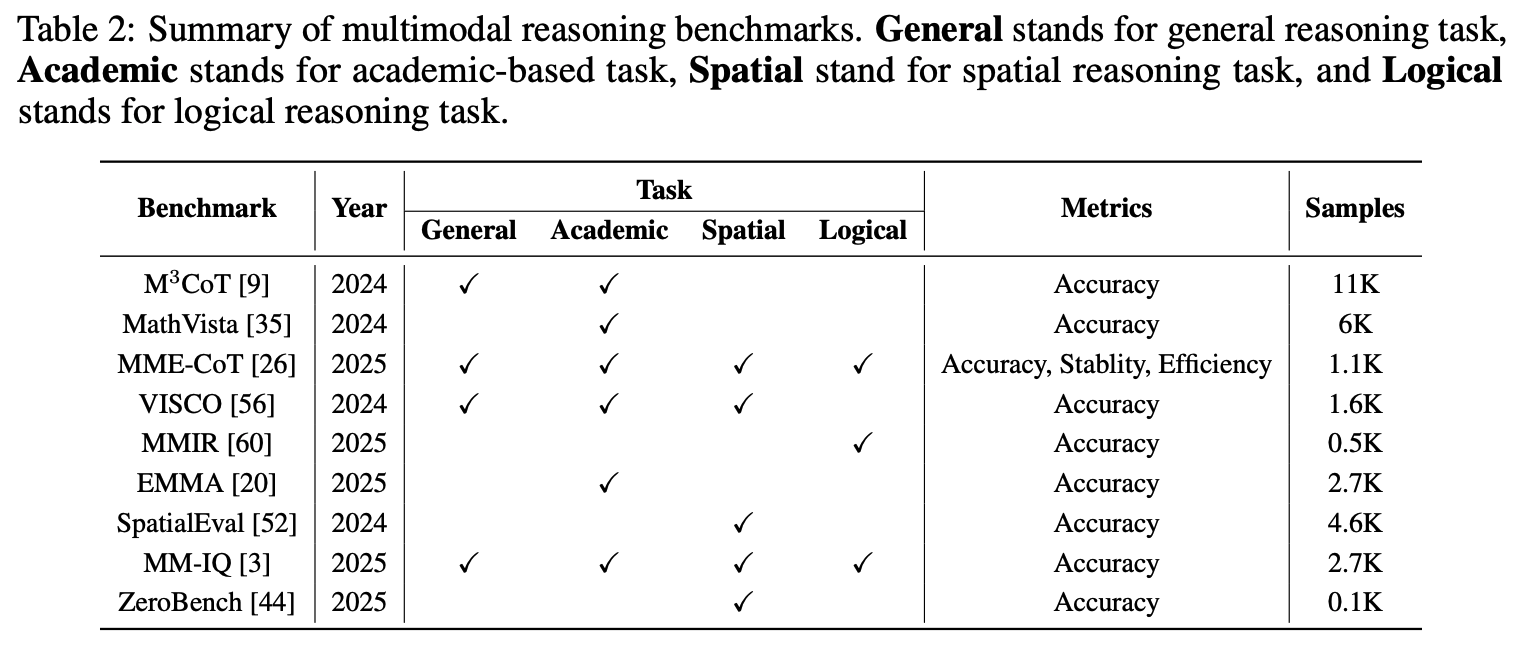
- [2502] [Multimodal Inconsistency Reasoning (MMIR): A New Benchmark for Multimodal Reasoning Models] (MMIR) [Paper] [Code]
- [2502] [ZeroBench: An Impossible Visual Benchmark for Contemporary Large Multimodal Models] (ZeroBench) [Paper] [Code]
- [2502] [MME-CoT: Benchmarking Chain-of-Thought in Large Multimodal Models for Reasoning Quality, Robustness, and Efficiency] (MME-CoT) [Paper] [Code]
- [2502] [MM-IQ: Benchmarking Human-Like Abstraction and Reasoning in Multimodal Models] (MM-IQ) [Paper] [Code]
- [2501] [Can MLLMs Reason in Multimodality? EMMA: An Enhanced MultiModal ReAsoning Benchmark] (EMMA) [Paper] [Code]
- [2501] [URSA: Understanding and Verifying Chain-of-thought Reasoning in Multimodal Mathematics] (URSA) [Paper] [Code]
- [2412] [VISCO: Benchmarking Fine-Grained Critique and Correction Towards Self-Improvement in Visual Reasoning] (VISCO) [Paper] [Code]
- [2406] [Is A Picture Worth A Thousand Words? Delving Into Spatial Reasoning for Vision Language Models] [Paper] [Code]
- [2405] [M3CoT: A Novel Benchmark for Multi-Domain Multi-step Multi-modal Chain-of-Thought] (M3CoT) [Paper] [Code]
- [2310] [MathVista: Evaluating Math Reasoning in Visual Contexts] (MathVista) [Paper] [Code]
🔗 Other useful links
Survey
- Multimodal Chain-of-Thought Reasoning: A Comprehensive Survey [Paper]
- From System 1 to System 2: A Survey of Reasoning Large Language Models [Paper]
- Rethinking External Slow-Thinking: From Snowball Errors to Probability of Correct Reasoning[Paper]
- Towards Reasoning Era: A Survey of Long Chain-of-Thought for Reasoning Large Language Models [Paper]
Contributors

10 commits

3 commits
Similar repos


This repository will continuously update the latest papers, technical reports, benchmarks about multimodal reasoning!
56
13 commits
updated Mar 21, 2025
README
Mind with Eyes: From Language Reasoning to Multimodal Reasoning
This repository will continuously update the latest Papers, technical reports, benchmarks about multimodal reasoning!
🎇 Introduction
Language models have recently advanced into the realm of reasoning, yet it is through multimodal reasoning that we can fully unlock the potential to achieve more comprehensive, human-like cognitive capabilities. This survey provides a systematic overview of the recent multimodal reasoning approaches, categorizing them into two levels: language-centric multimodal reasoning and collaborative multimodal reasoning. The former encompasses one-pass visual perception and active visual perception, where vision primarily serves a supporting role in language reasoning. The latter involves action generation and state update within reasoning process, enabling a more dynamic interaction between modalities. Furthermore, we analyze the technical evolution of these methods, discuss their inherent challenges, and introduce key benchmark tasks and evaluation metrics for assessing multimodal reasoning performance. Finally, we provide insights into future research directions from the following two perspectives: (i) from visual-language reasoning to omnimodal reasoning and (ii) from multimodal reasoning to multimodal agents. This survey aims to provide a structured overview that will inspire further advancements in multimodal reasoning research.
📢 Updates
- ✨ 2025.03.21: The paper is now available in here.
- 🚀 2025.03.15: We released this repo.
📚 Table of Contents
- 1. Language-centric Multimodal Reasoning
- 2. Collaborative Multimodal Reasoning
- 3. Benchmarks on Multimodal Reasoning
📖 1. Language-centric Multimodal Reasoning
📝 One-pass Visual Perception
- [2502] [R1-Onevision:An Open-Source Multimodal Large Language Model Capable of Deep Reasoning] (R1-Onevision) [Paper] [Code]
- [2502] [R1-V: Reinforcing Super Generalization Ability in Vision Language Models with Less Than $3] (R1-V) [Code]
- [2502] [Boosting Multimodal Reasoning with MCTS-Automated Structured Thinking] [Paper]
- [2501] [LlamaV-o1: Rethinking Step-by-step Visual Reasoning in LLM] (LlamaV-o1) [Paper] [Code]
- [2501] [Kimi k1.5: Scaling Reinforcement Learning with Large Language Models] (Kimi k1.5) [Paper] [Code]
- [2412] [Mulberry: Empowering MLLM with o1-like Reasoning and Reflection via Collective Monte Carlo Tree Search] (Mulberry) [Paper] [Code]
- [2411] [LLaVA-CoT: Let Vision Language Models Reason Step-by-Step] (LLaVA-CoT) [Paper] [Code]
- [2411] [Insight-V: Exploring Long-Chain Visual Reasoning with Multimodal Large Language Models] (Insight-V) [Paper] [Code]
- [2411] [Enhancing the Reasoning Ability of Multimodal Large Language Models via Mixed Preference Optimization] [Paper] [Code]
- [2411] [Vision-Language Models Can Self-Improve Reasoning via Reflection] () [Paper] [Code]
- [2410] [Improve Vision Language Model Chain-of-thought Reasoning] [Paper] [Code]
- [2404] [Cantor:Inspiring Multimodal Chain-of-Thought of MLLM] (Cantor) [Paper] [Code]
- [2403] [Visual CoT: Advancing Multi-Modal Language Models with a Comprehensive Dataset and Benchmark for Chain-of-Thought Reasoning] (Visual CoT) [Paper] [Code]
- [2311] [Compositional Chain-of-Thought Prompting for Large Multimodal Models] [Paper] [Code]
📝 Active Visual Perception
- [2411] [Interleaved-Modal Chain-of-Thought] [Paper]
- [2410] [Visual-o1: Understanding ambiguous instructions via multi-modal multi-turn chain-of-thoughts reasoning] (Visual-o1) [Paper]
- [2408] [Visual Agents As Fast And Slow Thinkers] (sys2-llava) [Paper] [Code]
- [2406] [From the Least to the Most: Building a Plug-and-Play Visual Reasoner via Data Synthesis] (VisualReasoner) [Paper] [Code]
- [2405] [VoCoT: Unleashing Visually Grounded Multi-Step Reasoning in Large Multi-Modal Models] (VoCoT) [Paper] [Code]
- [2403] [HYDRA: A Hyper Agent for Dynamic Compositional Visual Reasoning] (HYDRA) [Paper] [Code]
- [2310] [DDCoT: Duty-Distinct Chain-of-Thought Prompting for Multimodal Reasoning in Language Models] (DDCoT) [Paper] [Code]
🚀 2. Collaborative Multimodal Reasoning
- [2502] [Investigating Inference-time Scaling for Chain of Multi-modal Thought: A Preliminary Study] [Paper]
- [2501] [Imagine while Reasoning in Space: Multimodal Visualization-of-Thought] (MVoT) [Paper]
- [2409] [Enhancing LLM Reasoning via Vision-Augmented Prompting] [Paper] [Code]
- [2406] [Visual SKETCHPAD: Sketching as a Visual Chain of Thought for Multimodal Language Models] (Visual SKETCHPAD) [Paper] [Code]
- [2405] [Image-of-Thought Prompting for Visual Reasoning Refinement in Multimodal Large Language Models] (IoT) [Paper]
📊 3. Benchmarks on Multimodal Reasoning
- [2502] [Multimodal Inconsistency Reasoning (MMIR): A New Benchmark for Multimodal Reasoning Models] (MMIR) [Paper] [Code]
- [2502] [ZeroBench: An Impossible Visual Benchmark for Contemporary Large Multimodal Models] (ZeroBench) [Paper] [Code]
- [2502] [MME-CoT: Benchmarking Chain-of-Thought in Large Multimodal Models for Reasoning Quality, Robustness, and Efficiency] (MME-CoT) [Paper] [Code]
- [2502] [MM-IQ: Benchmarking Human-Like Abstraction and Reasoning in Multimodal Models] (MM-IQ) [Paper] [Code]
- [2501] [Can MLLMs Reason in Multimodality? EMMA: An Enhanced MultiModal ReAsoning Benchmark] (EMMA) [Paper] [Code]
- [2501] [URSA: Understanding and Verifying Chain-of-thought Reasoning in Multimodal Mathematics] (URSA) [Paper] [Code]
- [2412] [VISCO: Benchmarking Fine-Grained Critique and Correction Towards Self-Improvement in Visual Reasoning] (VISCO) [Paper] [Code]
- [2406] [Is A Picture Worth A Thousand Words? Delving Into Spatial Reasoning for Vision Language Models] [Paper] [Code]
- [2405] [M3CoT: A Novel Benchmark for Multi-Domain Multi-step Multi-modal Chain-of-Thought] (M3CoT) [Paper] [Code]
- [2310] [MathVista: Evaluating Math Reasoning in Visual Contexts] (MathVista) [Paper] [Code]
🔗 Other useful links
Survey
- Multimodal Chain-of-Thought Reasoning: A Comprehensive Survey [Paper]
- From System 1 to System 2: A Survey of Reasoning Large Language Models [Paper]
- Rethinking External Slow-Thinking: From Snowball Errors to Probability of Correct Reasoning[Paper]
- Towards Reasoning Era: A Survey of Long Chain-of-Thought for Reasoning Large Language Models [Paper]
Similar repos
Contributors
10 commits
3 commits