🤗 Hugging Models
| 📑 Paper
| 🤗 Spaces Demo
| 🕹️ OpenBayes贝式计算
🤗 Datasets | 💬 X (Twitter)
| 🖥️ Computer Use
| 📖 GUI Paper List
ShowUI: One Vision-Language-Action Model for GUI Visual Agent
Kevin Qinghong Lin, Linjie Li, Difei Gao, Zhengyuan Yang, Shiwei Wu, Zechen Bai, Weixian Lei, Lijuan Wang, Mike Zheng Shou
Show Lab @ National University of Singapore, Microsoft
showui for UI-guided token selection implementation.ShowUI-desktop-8K.showlab/ShowUI-2B is available at huggingface.See Computer Use OOTB for using ShowUI to control your PC.
https://github.com/user-attachments/assets/f50b7611-2350-4712-af9e-3d31e30020ee
Our Training codebases supports:
See Train for training set up.
Try test.ipynb, which seamless support for Qwen2VL models.
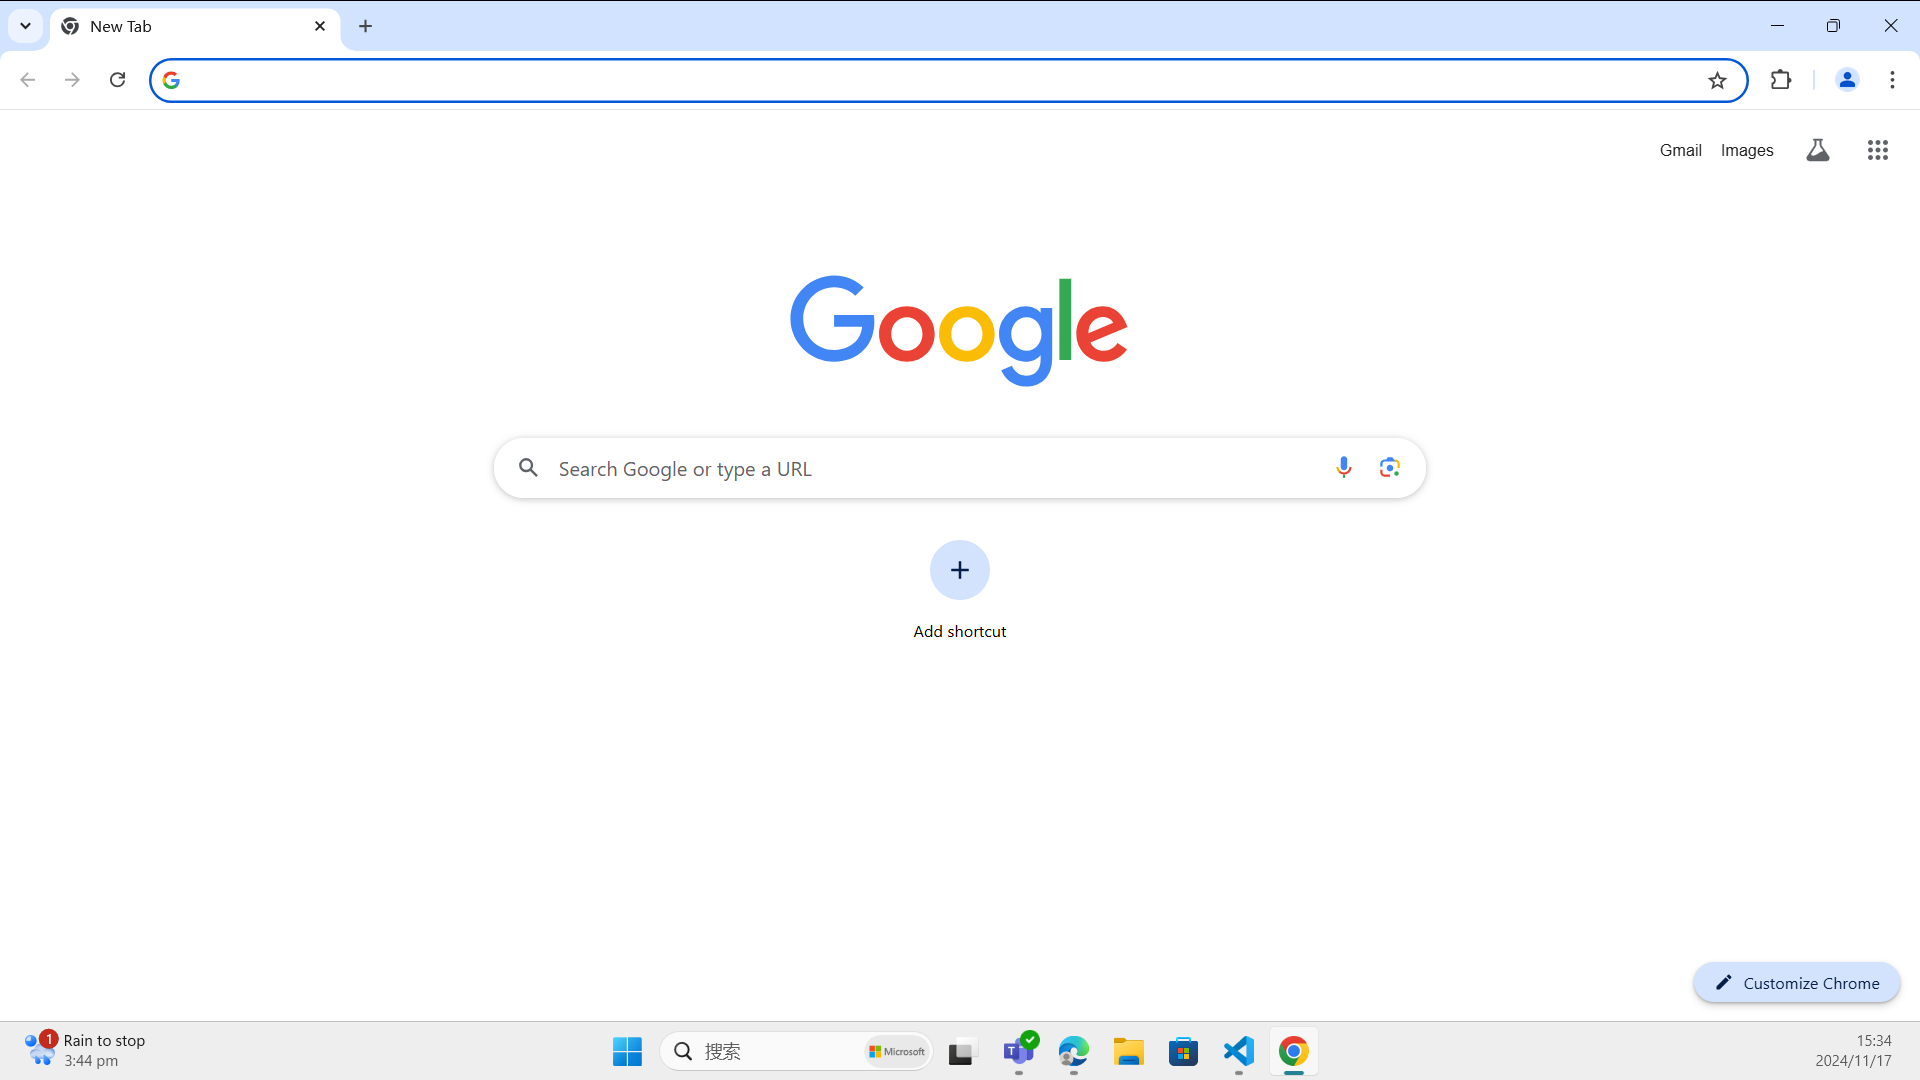
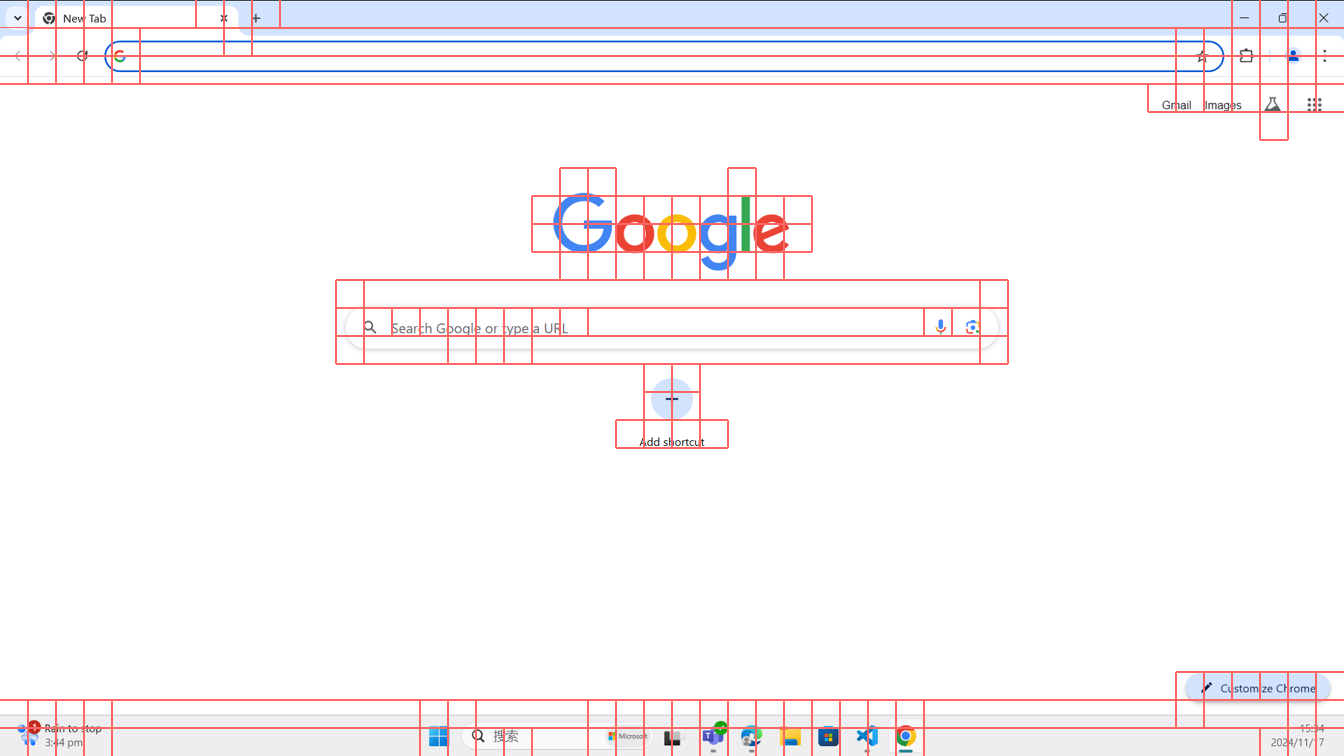
See Quick Start for model usage.
See Gradio for installation.
If you find our work helpful, please consider citing our paper.
@misc{lin2024showui,
      title={ShowUI: One Vision-Language-Action Model for GUI Visual Agent},
      author={Kevin Qinghong Lin and Linjie Li and Difei Gao and Zhengyuan Yang and Shiwei Wu and Zechen Bai and Weixian Lei and Lijuan Wang and Mike Zheng Shou},
      year={2024},
      eprint={2411.17465},
      archivePrefix={arXiv},
      primaryClass={cs.CV},
      url={https://arxiv.org/abs/2411.17465},
}
🤗 Hugging Models
| 📑 Paper
| 🤗 Spaces Demo
| 🕹️ OpenBayes贝式计算
🤗 Datasets | 💬 X (Twitter)
| 🖥️ Computer Use
| 📖 GUI Paper List
ShowUI: One Vision-Language-Action Model for GUI Visual Agent
Kevin Qinghong Lin, Linjie Li, Difei Gao, Zhengyuan Yang, Shiwei Wu, Zechen Bai, Weixian Lei, Lijuan Wang, Mike Zheng Shou
Show Lab @ National University of Singapore, Microsoft
showui for UI-guided token selection implementation.ShowUI-desktop-8K.showlab/ShowUI-2B is available at huggingface.See Computer Use OOTB for using ShowUI to control your PC.
https://github.com/user-attachments/assets/f50b7611-2350-4712-af9e-3d31e30020ee
Our Training codebases supports:
See Train for training set up.
Try test.ipynb, which seamless support for Qwen2VL models.
See Quick Start for model usage.
See Gradio for installation.
If you find our work helpful, please consider citing our paper.
@misc{lin2024showui,
      title={ShowUI: One Vision-Language-Action Model for GUI Visual Agent},
      author={Kevin Qinghong Lin and Linjie Li and Difei Gao and Zhengyuan Yang and Shiwei Wu and Zechen Bai and Weixian Lei and Lijuan Wang and Mike Zheng Shou},
      year={2024},
      eprint={2411.17465},
      archivePrefix={arXiv},
      primaryClass={cs.CV},
      url={https://arxiv.org/abs/2411.17465},
}






