
[CVPR 2026] FocusUI: Efficient UI Grounding via Position-Preserving Visual Token Selection
See the codeREADME
TL;DR: FocusUI teaches VLMs where to look in UI screenshots. 🔍


Mingyu Ouyang1, Kevin Qinghong Lin2, Mike Zheng Shou1†, Hwee Tou Ng1†
1National University of Singapore 2University of Oxford
†Corresponding authors
Overview ✨
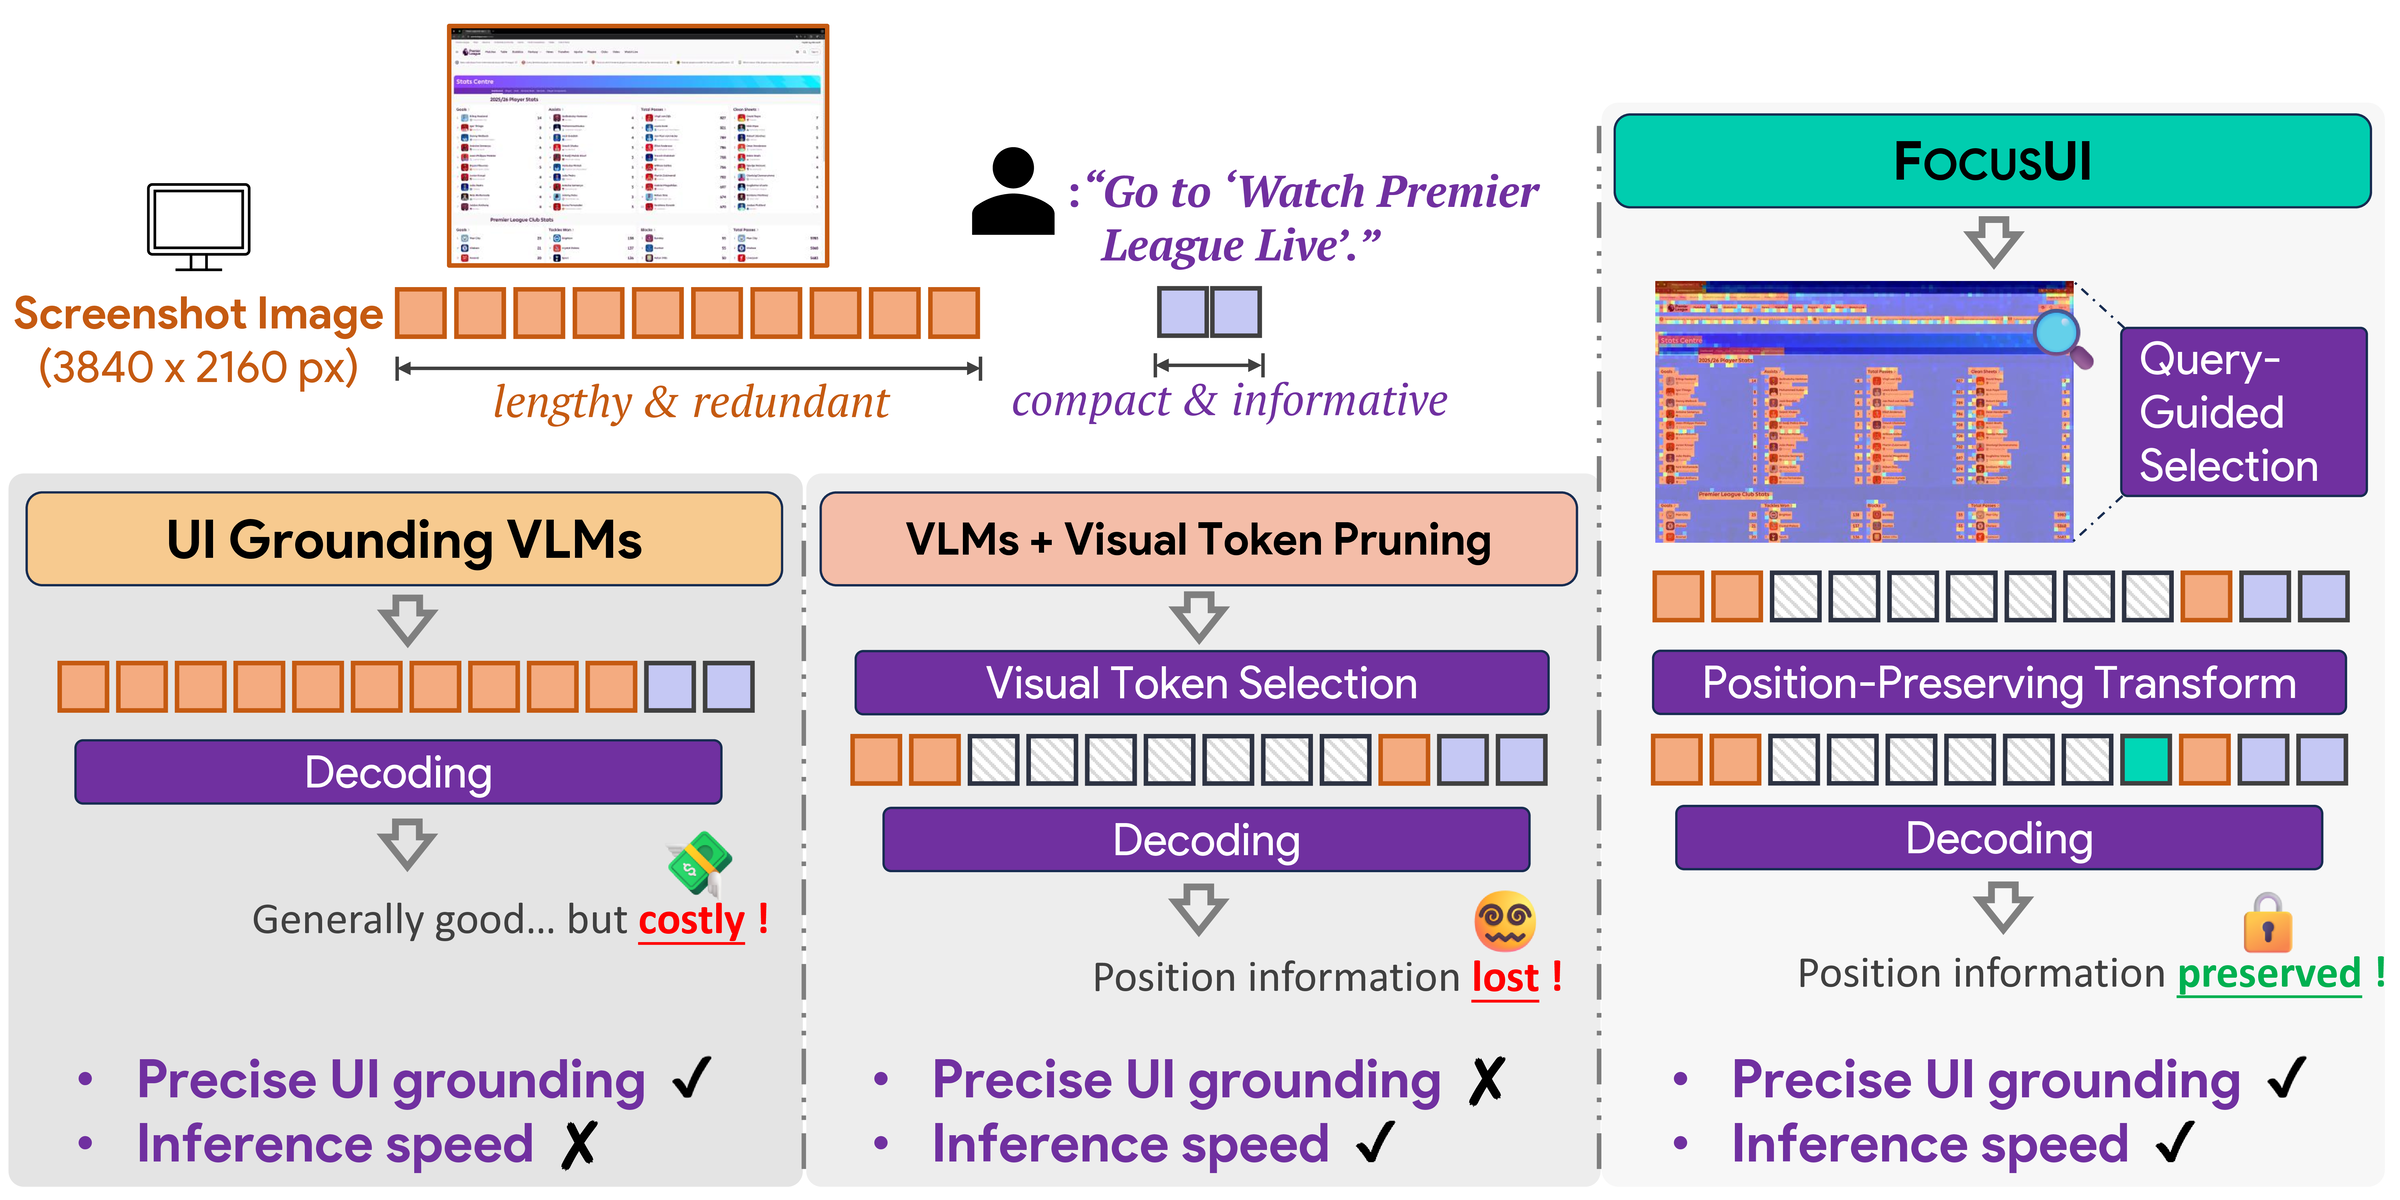
Vision-Language Models (VLMs) have shown remarkable performance in UI grounding tasks, but high-resolution screenshots are tokenized into thousands of visual tokens (e.g., ~4700 for 2K resolution), causing significant computational overhead. In contrast, humans naturally focus on regions of interest when interacting with UI. FocusUI is an efficient UI grounding framework that selects patches most relevant to the instruction while preserving positional continuity for precise grounding.
Key Innovations
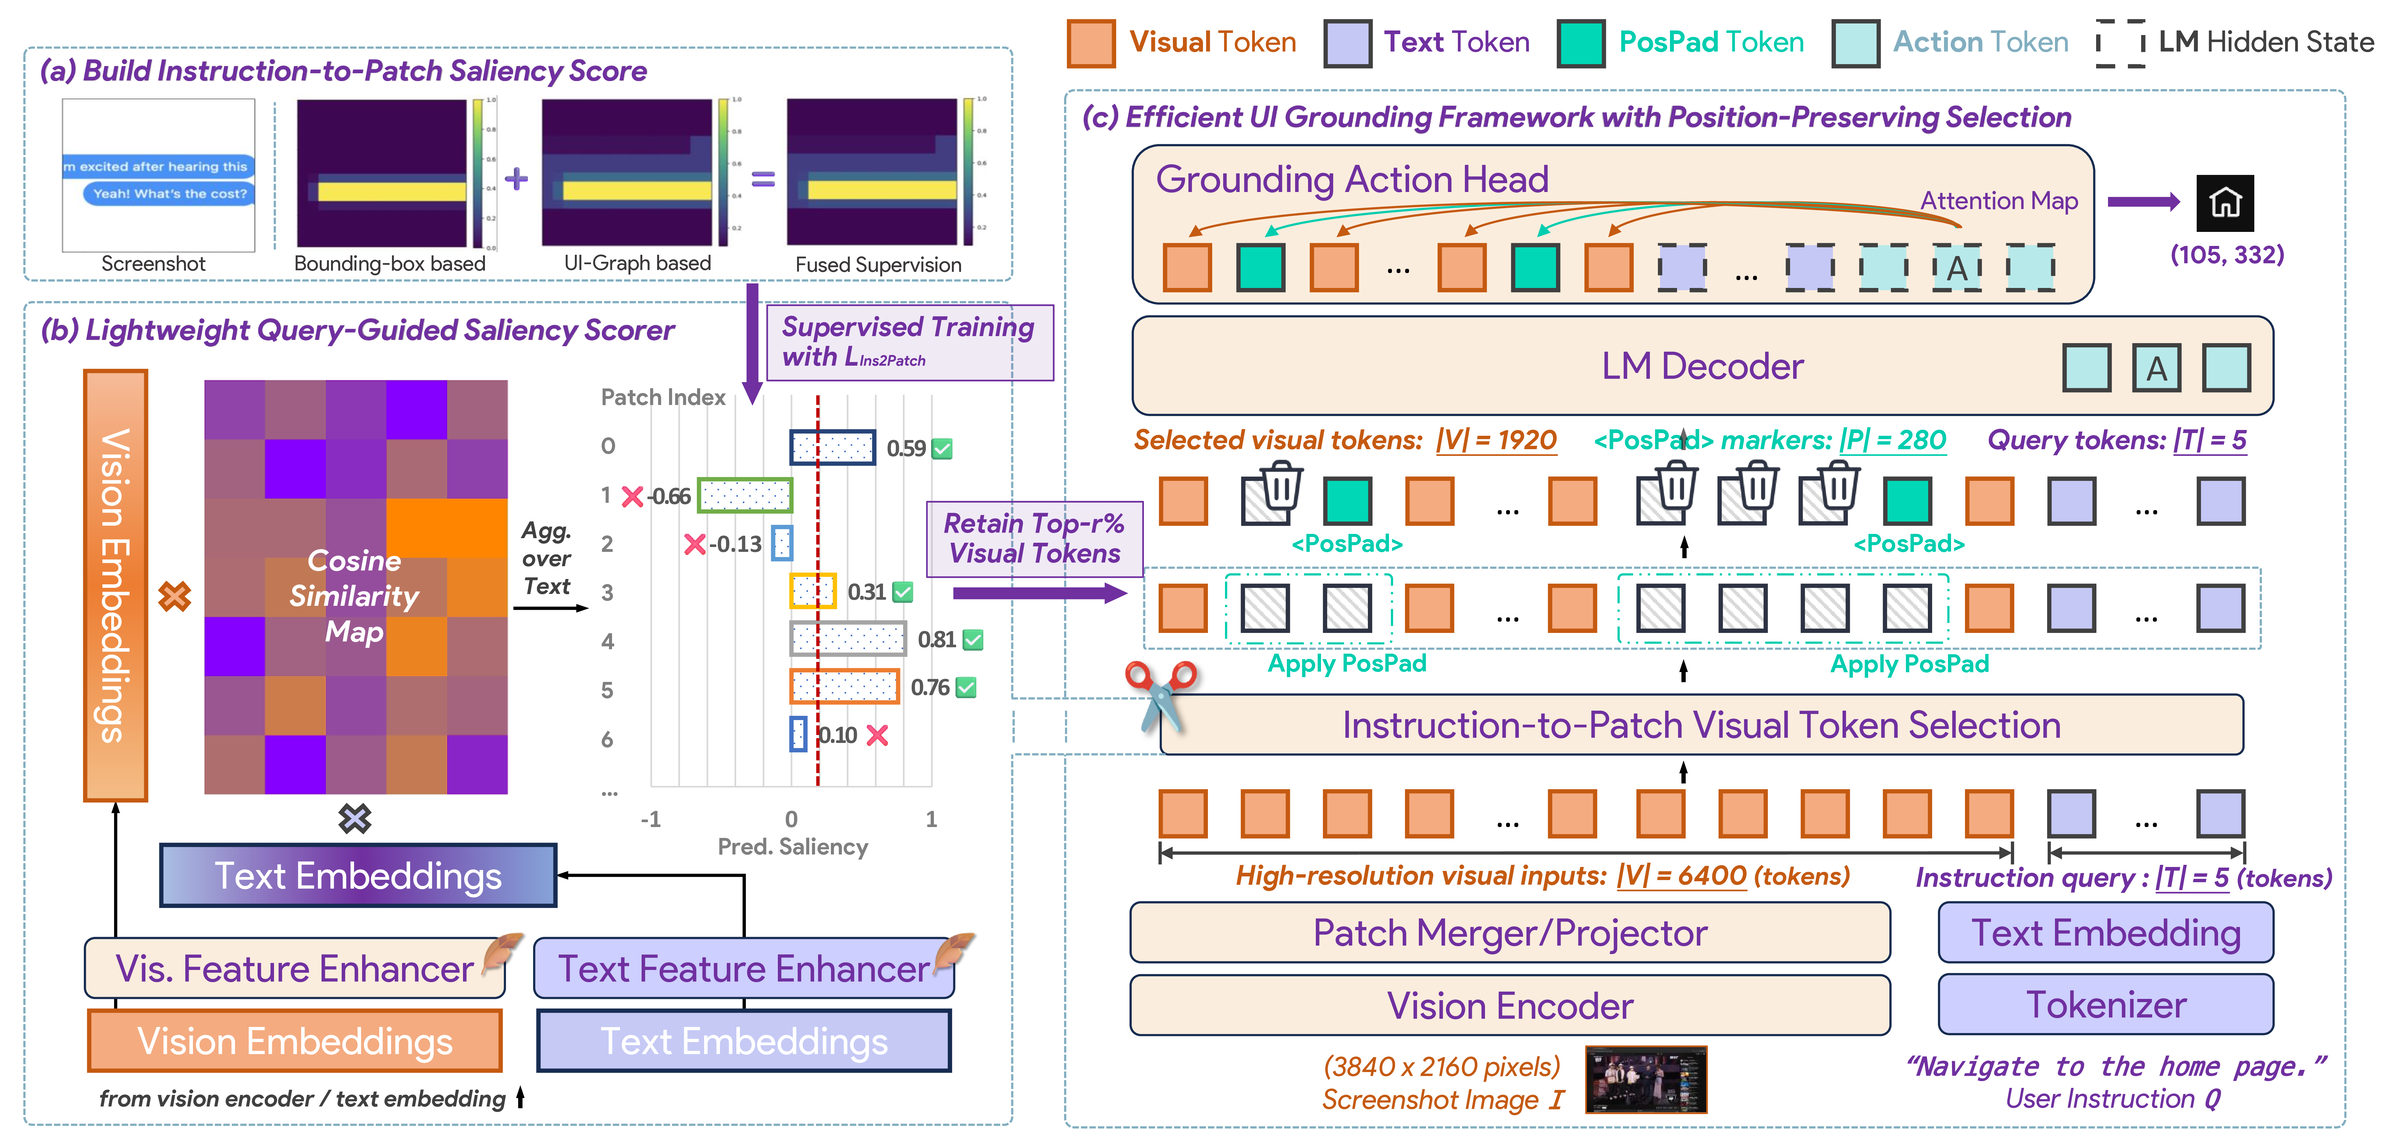
- Query-Guided Visual Token Selection: Constructs patch-level supervision by fusing instruction-conditioned scores with rule-based UI-graph scores that down-weight large homogeneous regions.
- POSPAD (Position-Preserving Padding): A novel strategy that compresses each contiguous sequence of dropped visual tokens into a single special marker placed at the sequence's last index, preserving positional continuity crucial for UI grounding.
Updates 📣
- [2026/06/07] FocusUI is reproduced by AutoSOTA.
- [2026/02/20] FocusUI is accepted by CVPR 2026.
- [2026/02/08] 🤗 Models, dataset and benchmarks are available on HuggingFace.
- [2025/12/29] Project page and code base released.
Quick Start 🚀
Installation
# Clone the repository
git clone https://github.com/showlab/FocusUI.git
cd FocusUI

# Install dependencies
conda create -n focusui python=3.12 -y
conda activate focusui
pip install -r requirements.txt
To download checkpoints:
# download FocusUI-3B
hf download yyyang/focusui_3b_ft_final --repo-type model --local-dir ./checkpoints/focusui-3b
(Optional) To download benchmarks and training datasets:
# download benchmarks
hf download yyyang/UI-Grounding-Benchmarks --repo-type dataset --local-dir ./datasets/UI-Grounding-Benchmarks/

# download training datasets
hf download yyyang/FocusUI-Training-Data --repo-type dataset --local-dir ./datasets/FocusUI-Training-Data/
Quick Start: Inference with FocusUI
See inference_focusui.py for an example of how to use FocusUI for inference.
Training 🧠
FocusUI uses a two-stage training process:
Stage 1: Train Patch Scorer Only. This stage trains only the PatchScorer module while freezing the base VLM.
bash scripts/train/stage_1_ft_focusui_scorer.sh
Stage 2: Full Fine-tuning. This stage fine-tunes the entire model with the trained PatchScorer.
bash scripts/train/stage_2_ft_focusui.sh
Evaluation 📊
Run evaluation on grounding benchmarks:
# ScreenSpot-Pro
python -m evaluation.ss_pro_eval \
    --model_type focusui_3b \
    --model_name_or_path checkpoints/FocusUI-3B \
    --data_path ./datasets/UI-Grounding-Benchmarks/ScreenSpot-Pro \
    --save_path ./results/ss_pro \
    --visual_reduct_ratio 0.5

# ScreenSpot-V2
python -m evaluation.ss_v2_eval \
    --model_type focusui_3b \
    --model_name_or_path checkpoints/FocusUI-3B \
    --data_path ./datasets/UI-Grounding-Benchmarks/ScreenSpot-V2 \
    --save_path ./results/ss_v2 \
    --visual_reduct_ratio 0.5

# ScreenSpot-V2
python -m evaluation.ss_v2_eval \
    --model_type focusui_qwen3vl_2b \
    --model_name_or_path checkpoints/FocusUI-Qwen3-VL-2B \
    --data_path ./datasets/UI-Grounding-Benchmarks/ScreenSpot-V2 \
    --save_path ./results/ss_v2_2b \
    --visual_reduct_ratio 0.5

# UI-Vision
python -m evaluation.ui_vision_eval \
    --model_type focusui_3b \
    --model_name_or_path checkpoints/FocusUI-3B \
    --data_path ./datasets/UI-Grounding-Benchmarks/UI-Vision \
    --save_path ./results/ui_vision \
    --visual_reduct_ratio 0.5


# OSWorld-G
python -m evaluation.os_world_g_eval \
    --model_type focusui_3b \
    --model_name_or_path checkpoints/FocusUI-3B \
    --data_path ./datasets/UI-Grounding-Benchmarks/OSWorld-G \
    --save_path ./results/osworld_g \
    --visual_reduct_ratio 0.5
Key Evaluation Options
| Argument | Description | Default |
|---|---|---|
--apply_visual_token_select | Enable visual token selection | True |
--visual_reduct_ratio | Token retention ratio (1.0 = keep all) | 0.5 |
Model Zoo 🧩
| Model | Backbone | Parameters | HuggingFace |
|---|---|---|---|
| FocusUI-3B | Qwen2.5-VL-3B | 3B | FocusUI-3B |
| FocusUI-7B | Qwen2.5-VL-7B | 7B | FocusUI-7B |
| FocusUI-2B | Qwen3-VL-2B | 2B | FocusUI-Qwen3-VL-2B |
Citation 📝
If you find FocusUI useful for your research, please cite:
@article{ouyang2025focusui,
  title   = {FocusUI: Efficient UI Grounding via Position-Preserving Visual Token Selection},
  author  = {Ouyang, Mingyu and Lin, Kevin Qinghong and Shou, Mike Zheng and Ng, Hwee Tou},
  year    = {2025},
  journal = {arXiv preprint},
}
Acknowledgements 🙏
FocusUI builds upon Qwen2.5/3-VL and GUI-Actor as backbone models. We thank the open-source community for their valuable contributions.
Similar repos



Languages
Python
97.8%
Shell
2.2%
[CVPR 2026] FocusUI: Efficient UI Grounding via Position-Preserving Visual Token Selection
See the codeREADME
TL;DR: FocusUI teaches VLMs where to look in UI screenshots. 🔍
Mingyu Ouyang1, Kevin Qinghong Lin2, Mike Zheng Shou1†, Hwee Tou Ng1†
1National University of Singapore 2University of Oxford
†Corresponding authors
Overview ✨
Vision-Language Models (VLMs) have shown remarkable performance in UI grounding tasks, but high-resolution screenshots are tokenized into thousands of visual tokens (e.g., ~4700 for 2K resolution), causing significant computational overhead. In contrast, humans naturally focus on regions of interest when interacting with UI. FocusUI is an efficient UI grounding framework that selects patches most relevant to the instruction while preserving positional continuity for precise grounding.
Key Innovations
- Query-Guided Visual Token Selection: Constructs patch-level supervision by fusing instruction-conditioned scores with rule-based UI-graph scores that down-weight large homogeneous regions.
- POSPAD (Position-Preserving Padding): A novel strategy that compresses each contiguous sequence of dropped visual tokens into a single special marker placed at the sequence's last index, preserving positional continuity crucial for UI grounding.
Updates 📣
- [2026/06/07] FocusUI is reproduced by AutoSOTA.
- [2026/02/20] FocusUI is accepted by CVPR 2026.
- [2026/02/08] 🤗 Models, dataset and benchmarks are available on HuggingFace.
- [2025/12/29] Project page and code base released.
Quick Start 🚀
Installation
# Clone the repository
git clone https://github.com/showlab/FocusUI.git
cd FocusUI

# Install dependencies
conda create -n focusui python=3.12 -y
conda activate focusui
pip install -r requirements.txt
To download checkpoints:
# download FocusUI-3B
hf download yyyang/focusui_3b_ft_final --repo-type model --local-dir ./checkpoints/focusui-3b
(Optional) To download benchmarks and training datasets:
# download benchmarks
hf download yyyang/UI-Grounding-Benchmarks --repo-type dataset --local-dir ./datasets/UI-Grounding-Benchmarks/

# download training datasets
hf download yyyang/FocusUI-Training-Data --repo-type dataset --local-dir ./datasets/FocusUI-Training-Data/
Quick Start: Inference with FocusUI
See inference_focusui.py for an example of how to use FocusUI for inference.
Training 🧠
FocusUI uses a two-stage training process:
Stage 1: Train Patch Scorer Only. This stage trains only the PatchScorer module while freezing the base VLM.
bash scripts/train/stage_1_ft_focusui_scorer.sh
Stage 2: Full Fine-tuning. This stage fine-tunes the entire model with the trained PatchScorer.
bash scripts/train/stage_2_ft_focusui.sh
Evaluation 📊
Run evaluation on grounding benchmarks:
# ScreenSpot-Pro
python -m evaluation.ss_pro_eval \
    --model_type focusui_3b \
    --model_name_or_path checkpoints/FocusUI-3B \
    --data_path ./datasets/UI-Grounding-Benchmarks/ScreenSpot-Pro \
    --save_path ./results/ss_pro \
    --visual_reduct_ratio 0.5

# ScreenSpot-V2
python -m evaluation.ss_v2_eval \
    --model_type focusui_3b \
    --model_name_or_path checkpoints/FocusUI-3B \
    --data_path ./datasets/UI-Grounding-Benchmarks/ScreenSpot-V2 \
    --save_path ./results/ss_v2 \
    --visual_reduct_ratio 0.5

# ScreenSpot-V2
python -m evaluation.ss_v2_eval \
    --model_type focusui_qwen3vl_2b \
    --model_name_or_path checkpoints/FocusUI-Qwen3-VL-2B \
    --data_path ./datasets/UI-Grounding-Benchmarks/ScreenSpot-V2 \
    --save_path ./results/ss_v2_2b \
    --visual_reduct_ratio 0.5

# UI-Vision
python -m evaluation.ui_vision_eval \
    --model_type focusui_3b \
    --model_name_or_path checkpoints/FocusUI-3B \
    --data_path ./datasets/UI-Grounding-Benchmarks/UI-Vision \
    --save_path ./results/ui_vision \
    --visual_reduct_ratio 0.5


# OSWorld-G
python -m evaluation.os_world_g_eval \
    --model_type focusui_3b \
    --model_name_or_path checkpoints/FocusUI-3B \
    --data_path ./datasets/UI-Grounding-Benchmarks/OSWorld-G \
    --save_path ./results/osworld_g \
    --visual_reduct_ratio 0.5
Key Evaluation Options
| Argument | Description | Default |
|---|---|---|
--apply_visual_token_select | Enable visual token selection | True |
--visual_reduct_ratio | Token retention ratio (1.0 = keep all) | 0.5 |
Model Zoo 🧩
| Model | Backbone | Parameters | HuggingFace |
|---|---|---|---|
| FocusUI-3B | Qwen2.5-VL-3B | 3B | FocusUI-3B |
| FocusUI-7B | Qwen2.5-VL-7B | 7B | FocusUI-7B |
| FocusUI-2B | Qwen3-VL-2B | 2B | FocusUI-Qwen3-VL-2B |
Citation 📝
If you find FocusUI useful for your research, please cite:
@article{ouyang2025focusui,
  title   = {FocusUI: Efficient UI Grounding via Position-Preserving Visual Token Selection},
  author  = {Ouyang, Mingyu and Lin, Kevin Qinghong and Shou, Mike Zheng and Ng, Hwee Tou},
  year    = {2025},
  journal = {arXiv preprint},
}
Acknowledgements 🙏
FocusUI builds upon Qwen2.5/3-VL and GUI-Actor as backbone models. We thank the open-source community for their valuable contributions.
Similar repos
Languages
Python
97.8%
Shell
2.2%