Code Implementation for Paper: "One Token per Multimodel Evidence: Latent Memory for Resource-Constrained QA"
Python
10
10 commits
updated Jun 10, 2026
Code for One Token per Multimodal Evidence: Latent Memory for Resource-Constrained QA. Arxiv
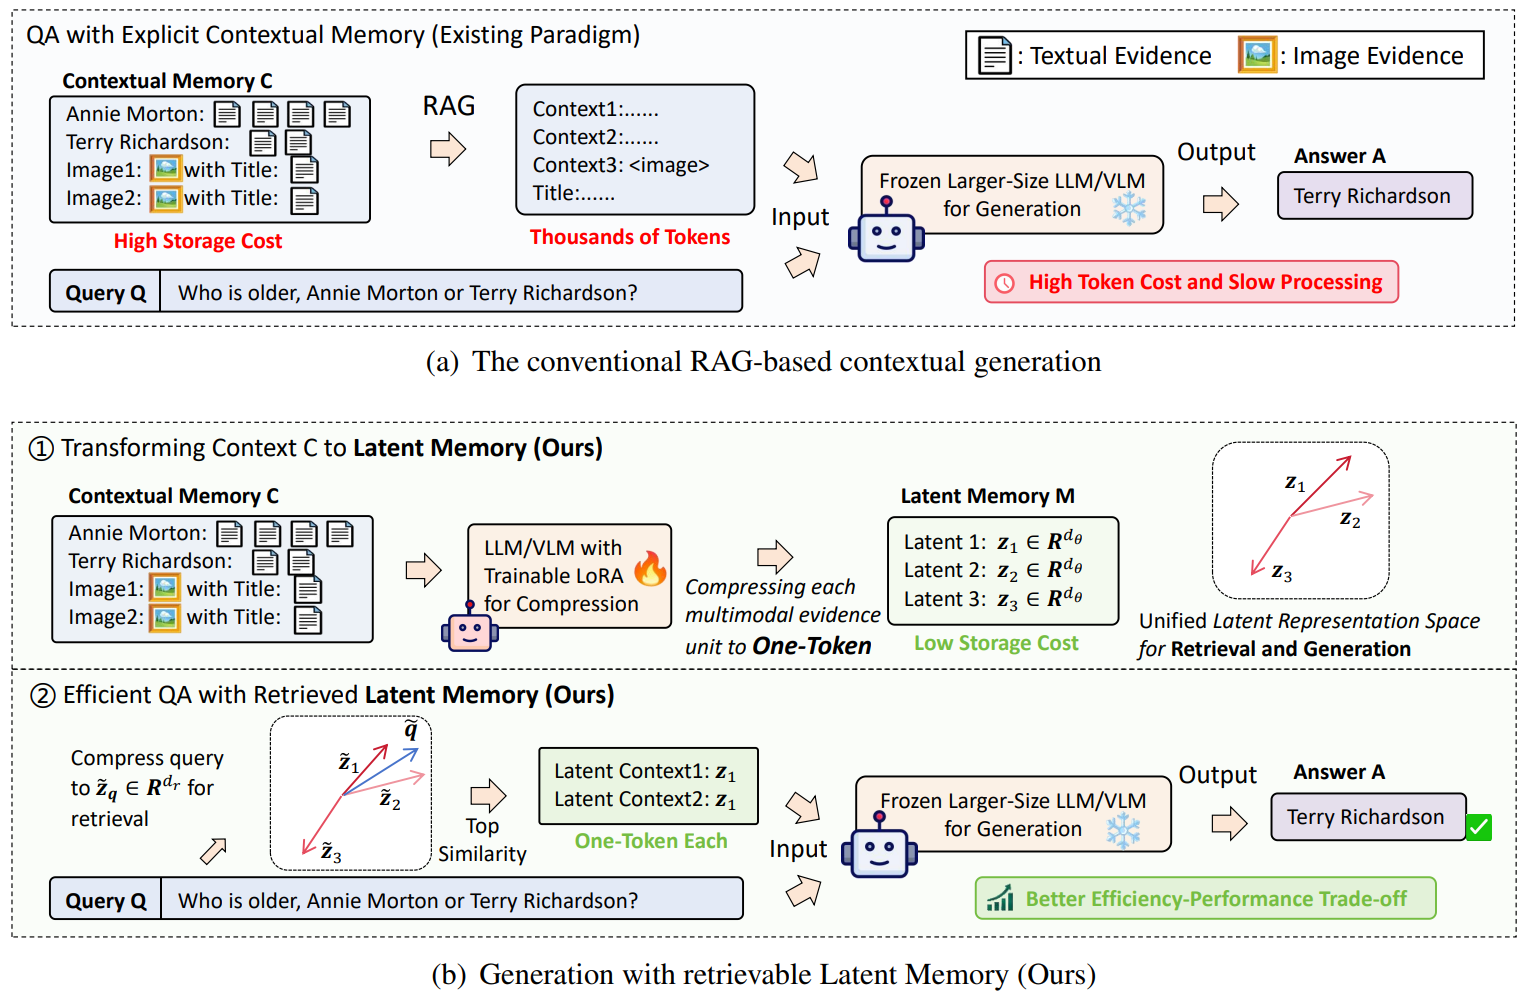
This repository contains the core src/ modules and executable scripts/ for four experiment families:
src/        Core model, compressor, retrieval, and evaluation modules.
scripts/    Public train/eval entry points.
configs/    Main YAML configs for text-only, LLaVA multimodal, and Gemma multimodal runs.
runs/       Ready-to-edit YAML and shell launchers for the main experiments.
pip install -r requirements.txt
Download the released data and checkpoints from zz1358m/Latent-Memory-Master before running the examples. 📦
The default release workflow is intentionally simple:
train -> eval
Memory-bank construction is optional and only needed for offline indexing over a fixed corpus. The multimodal evaluation scripts build per-sample candidate pools online and do not require a separate compile step.
bash runs/run_text_llama.sh
bash runs/run_text_llama_mistral.sh
bash runs/run_llava_multimodal.sh
bash runs/run_gemma_multimodal.sh
Each run file calls the unified public entry points:
python scripts/train_release.py --task text  --config configs/config.yaml
python scripts/train_release.py --task llava --config configs/config_llava.yaml
python scripts/train_release.py --task gemma --config configs/config_gemma3_4B_12B.yaml

python scripts/eval_release.py --task text  --config configs/config.yaml --checkpoint checkpoints/text_llama/model.pt --output results/text_llama --top_k 5
python scripts/eval_release.py --task text  --config configs/config_llama1b_mistral7b.yaml --checkpoint checkpoints/text_llama_mistral/model_best.pt --output results/text_llama_mistral --dataset hotpotqa --ood_datasets 2wikimultihopqa,musique --k_list 1,2,5 --skip_baselines
python scripts/eval_release.py --task llava --config configs/config_llava.yaml --checkpoint checkpoints/llava/model.pt --top_k_values 5 --output results/llava_webqa/baselines_llava.json
python scripts/eval_release.py --task gemma --config configs/config_gemma3_4B_12B.yaml --checkpoint checkpoints/gemma_multimodal/model.pt --top_k_values 5 --output results/gemma_webqa/baselines_gemma.json
Place the trained autoencoder/LoRA checkpoint at:
checkpoints/text_llama_mistral/model_best.pt
Then run latent retrieval with raw-text generation by Mistral:
bash runs/run_text_llama_mistral.sh
The launcher uses:
configs/config_llama1b_mistral7b.yaml
runs/text_llama_mistral.yaml
By default it evaluates HotpotQA plus 2wikimultihopqa,musique at k=1,2,5 and writes results to results/text_llama_mistral/. Override paths without editing files:
CKPT=/path/to/model_best.pt \
OUT_DIR=results/my_mistral_run \
MAX_SAMPLES=1000 \
bash runs/run_text_llama_mistral.sh
If your models are stored locally, edit model.compressor_name and model.generator_name in configs/config_llama1b_mistral7b.yaml. The public defaults are meta-llama/Llama-3.2-1B-Instruct for the compressor and mistralai/Mistral-7B-Instruct-v0.3 for the generator.
To continue training from an existing Llama encoder LoRA checkpoint:
python scripts/train_release.py --task text \
  --config configs/config_llama1b_mistral7b.yaml \
  --data data/hotpotqa_train.json \
  --val_data data/hotpotqa_val.json \
  --init_checkpoint checkpoints/text_llama_mistral/model_best.pt \
  --output checkpoints/text_llama_mistral/model_continued.pt
scripts/train_release.py
scripts/eval_release.py
Task-specific implementations live in scripts/internal/ so the release remains easy to navigate while preserving the original training and evaluation logic.
Code Implementation for Paper: "One Token per Multimodel Evidence: Latent Memory for Resource-Constrained QA"
Python
10
10 commits
updated Jun 10, 2026
Code for One Token per Multimodal Evidence: Latent Memory for Resource-Constrained QA. Arxiv
This repository contains the core src/ modules and executable scripts/ for four experiment families:
src/        Core model, compressor, retrieval, and evaluation modules.
scripts/    Public train/eval entry points.
configs/    Main YAML configs for text-only, LLaVA multimodal, and Gemma multimodal runs.
runs/       Ready-to-edit YAML and shell launchers for the main experiments.
pip install -r requirements.txt
Download the released data and checkpoints from zz1358m/Latent-Memory-Master before running the examples. 📦
The default release workflow is intentionally simple:
train -> eval
Memory-bank construction is optional and only needed for offline indexing over a fixed corpus. The multimodal evaluation scripts build per-sample candidate pools online and do not require a separate compile step.
bash runs/run_text_llama.sh
bash runs/run_text_llama_mistral.sh
bash runs/run_llava_multimodal.sh
bash runs/run_gemma_multimodal.sh
Each run file calls the unified public entry points:
python scripts/train_release.py --task text  --config configs/config.yaml
python scripts/train_release.py --task llava --config configs/config_llava.yaml
python scripts/train_release.py --task gemma --config configs/config_gemma3_4B_12B.yaml

python scripts/eval_release.py --task text  --config configs/config.yaml --checkpoint checkpoints/text_llama/model.pt --output results/text_llama --top_k 5
python scripts/eval_release.py --task text  --config configs/config_llama1b_mistral7b.yaml --checkpoint checkpoints/text_llama_mistral/model_best.pt --output results/text_llama_mistral --dataset hotpotqa --ood_datasets 2wikimultihopqa,musique --k_list 1,2,5 --skip_baselines
python scripts/eval_release.py --task llava --config configs/config_llava.yaml --checkpoint checkpoints/llava/model.pt --top_k_values 5 --output results/llava_webqa/baselines_llava.json
python scripts/eval_release.py --task gemma --config configs/config_gemma3_4B_12B.yaml --checkpoint checkpoints/gemma_multimodal/model.pt --top_k_values 5 --output results/gemma_webqa/baselines_gemma.json
Place the trained autoencoder/LoRA checkpoint at:
checkpoints/text_llama_mistral/model_best.pt
Then run latent retrieval with raw-text generation by Mistral:
bash runs/run_text_llama_mistral.sh
The launcher uses:
configs/config_llama1b_mistral7b.yaml
runs/text_llama_mistral.yaml
By default it evaluates HotpotQA plus 2wikimultihopqa,musique at k=1,2,5 and writes results to results/text_llama_mistral/. Override paths without editing files:
CKPT=/path/to/model_best.pt \
OUT_DIR=results/my_mistral_run \
MAX_SAMPLES=1000 \
bash runs/run_text_llama_mistral.sh
If your models are stored locally, edit model.compressor_name and model.generator_name in configs/config_llama1b_mistral7b.yaml. The public defaults are meta-llama/Llama-3.2-1B-Instruct for the compressor and mistralai/Mistral-7B-Instruct-v0.3 for the generator.
To continue training from an existing Llama encoder LoRA checkpoint:
python scripts/train_release.py --task text \
  --config configs/config_llama1b_mistral7b.yaml \
  --data data/hotpotqa_train.json \
  --val_data data/hotpotqa_val.json \
  --init_checkpoint checkpoints/text_llama_mistral/model_best.pt \
  --output checkpoints/text_llama_mistral/model_continued.pt
scripts/train_release.py
scripts/eval_release.py
Task-specific implementations live in scripts/internal/ so the release remains easy to navigate while preserving the original training and evaluation logic.



