
A collection of various llm pruning implementations, training code for GPUs & TPUs, and evaluation script.
Python
75
43 commits
updated Apr 20, 2026
README
Small LLMs: Pruning vs Training from Scratch
Yufeng Xu1, Taiming Lu1, Jiachen Zhu2, Mingjie Sun3, Kunjun Li1, and Zhuang Liu1
1 Princeton. 2 NYU. 3 CMU.
This is a Jax-based repo for LLM Prunning, It contains:
- the implementations of various LLM pruning methods of different granularity.
- pretraining and fine-tuning code for both GPU and TPU platforms.
- evaluation scripts for assessing model performance.
We gratefully acknowledge the generous support of the Google TPU Research Cloud (TRC), which provided the computational resources used to build this repository.
The repo is organized as follows:
├── pruning
│   ├── FLAP # including Wanda-sp and FLAP
│   ├── LLM-Pruner
│   ├── llmshearing # sheared llama
│   ├── minitron # including shortgpt
│   ├── SLEB # including sleb
│   ├── SliceGPT # including slicegpt
│   └── wanda # including sparsegpt and magnitude pruning
├── training
│   ├── fms_fsdp
│   └── maxtext
└── eval
where pruning is the collection of the pruning methods we experimented; training contains the LLM training frameworks we used, and we provided options for both TPU and GPU; eval contains JAX-compatible eval scripts we used to evaluate the pruned models.
Supported Features
Pruning Methods
Training Frameworks
Evaluation
- accelerate lm-eval-harness for maxtext. (by 2-4x times!)
Get Started
Pruning
In order to reproduce the results of the different pruning methods, we need to set up separate environments for different methods. The installation and command guide can be found at pruning/<method>/README.md. Below is an overview:
Minitron
cd pruning/minitron
bash scripts/install.sh
bash scripts/prune_llama3.1-8b.sh # contains minitron depth and width for llama3.1-8b
ShortGPT
cd pruning/minitron
bash scripts/install.sh
bash scripts/prune_llama2-7b.sh
Wanda, SparseGPT, Magnitude
cd pruning/wanda
bash scripts/install.sh
bash scripts/prune_llama3.1-8b.sh # contains wanda, sparsegpt, and magnitude for llama3.1-8b
bash scripts/prune_llama2-7b.sh
bash scripts/prune_llama-7b.sh
LLM-Pruner
cd pruning/LLM-Pruner
bash scripts/install.sh
bash scripts/prune_llama-7b.sh
bash scripts/prune_llama2-7b.sh
bash scripts/prune_llama3.1-8b.sh
Sheared Llama
cd pruning/llmshearing
bash scripts/install.sh

mkdir -p llmshearing/data/red_pajama && cd llmshearing/data/red_pajama
huggingface-cli download Zephyr271828/redpajama-for-prune --repo-type dataset --local-dir for_prune
cd -

bash scripts/hf2composer.sh
bash scripts/prune_llama2-2.7b.sh
bash scripts/prune_llama2-1.3b.sh
bash scripts/prune_llama2-370m.sh
bash scripts/composer2hf.sh
Training
GPU To train on GPUs, please refer to the guide of fms-fsdp for details.
TPU To train on TPUs, please refer to guide of MaxText for details.
Evaluation
GPU
For evaluation on GPUS, you may run the following evaluation script on your HF checkpoint:
cd training/fms_fsdp
bash scripts/install.sh

cd ../../eval
bash scripts/eval.sh
Note for LLM-Pruner and Wanda, they have specified a specific version of lm-eval to use, which is included in their respective directory, and the evaluation code is included in the pruning process.
For all other methods, you may eval with the script provided.
TPU Please refer to the guide of MaxText for details.
Reproduction Results
In this section, we show some of our results to verify that we can reproduce the results from the original pruning papers.
- For Minitron, the original papers did not report evaluation results after pruning and before retraining, so we attempt to reproduce the plots from LLM Pruning and Distillation in Practice: The Minitron Approach.
- For ShortGPT, although evaluation results are provided, yet we noticed there are inconsistencies between results in the table (also see ShortGPT: Layers in Large Language Models are More Redundant Than You Expect). Therefore, we choose to reproduce the block importance plot from the paper, which implies the correctness of our implementation.
- For all other methods, both official implementation and evaluation results are provided, so we simply provide comparison with the reported results in paper.
Minitron-Winogrande
Left: plot from the paper; Right: plot made by us.
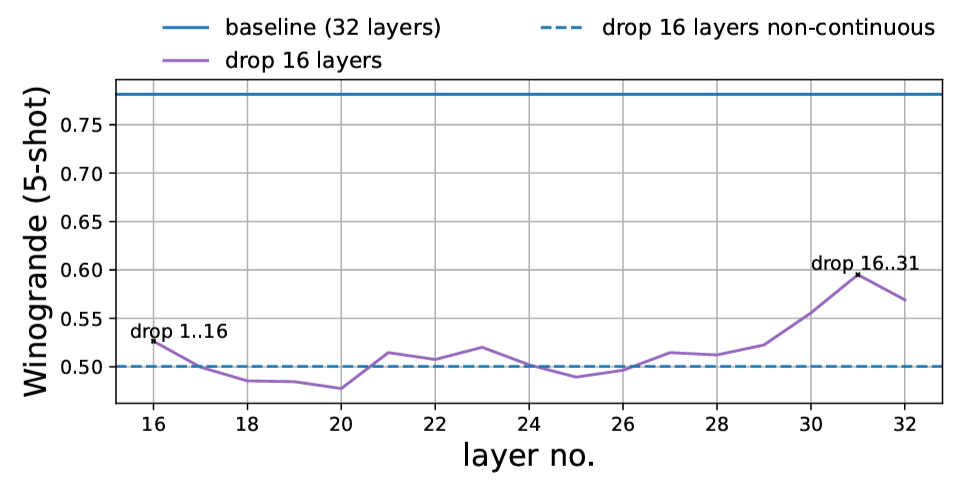
Paper (Sreenivas et al.)
|
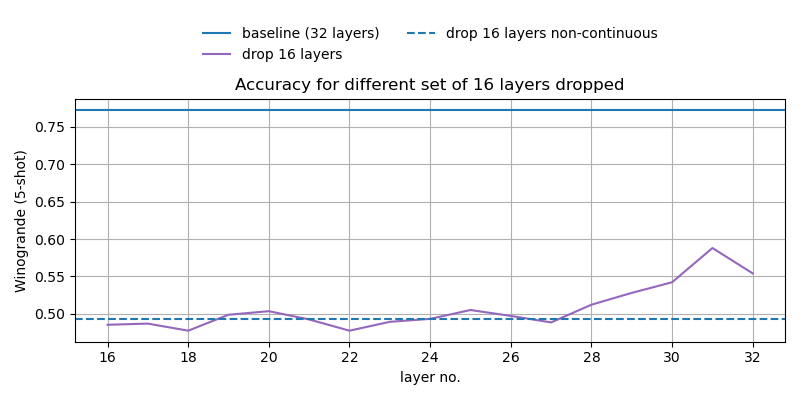
Ours
|
Minitron-Wikitext
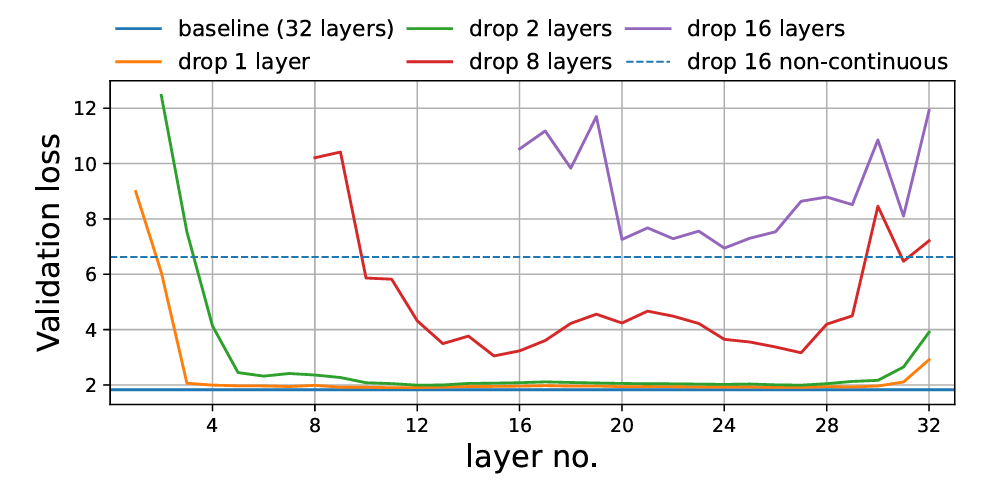 Paper (Sreenivas et al.) |
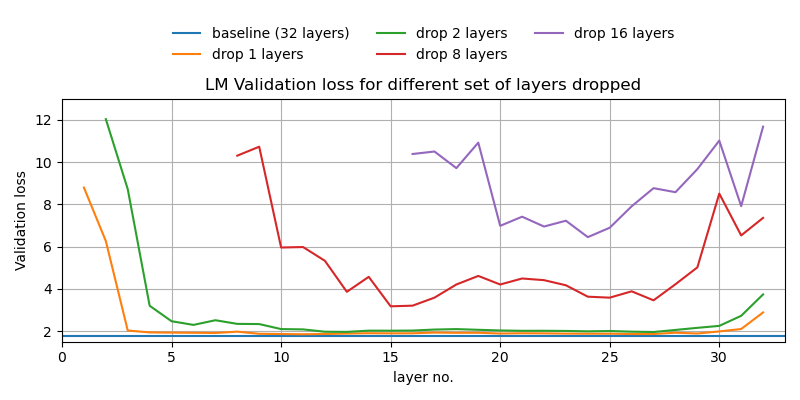 Ours |
ShortGPT
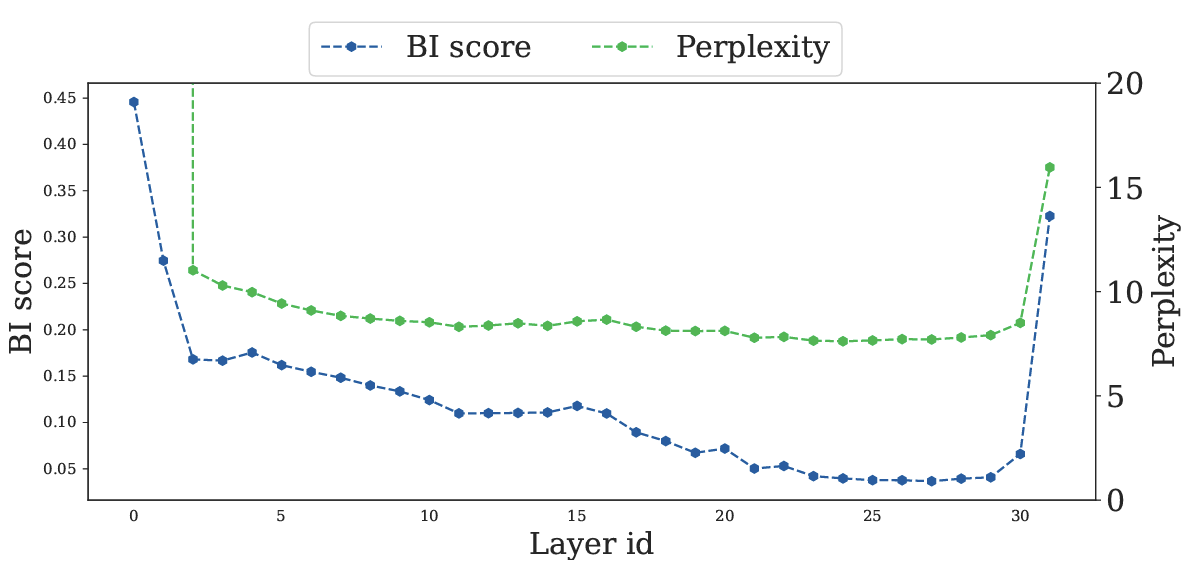 Paper (Men et al.) |
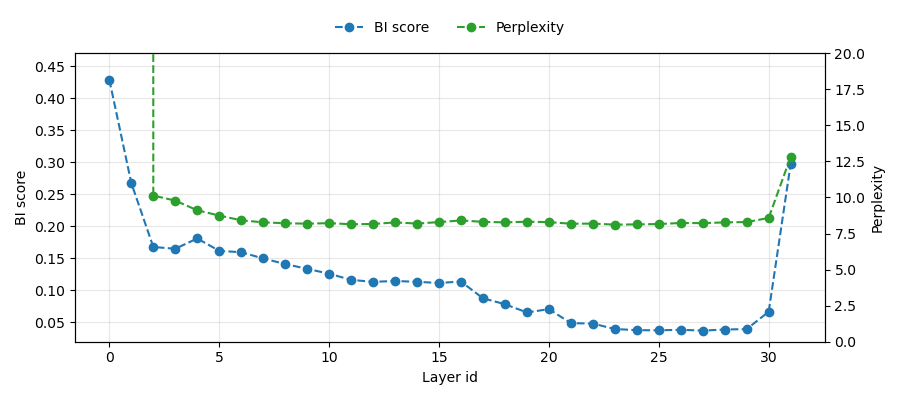 Ours |
Wanda
Llama-2-7b-hf:
| Sparsity | Ratio | Source | BoolQ | RTE | Hellaswag | Winogrande | ARC-E | ARC-C | OBQA |
|---|---|---|---|---|---|---|---|---|---|
| unstructured | 0.5 | Paper | 75.0 | 53.4 | 52.5 | 68.2 | 72.8 | 39.9 | 31.2 |
| unstructured | 0.5 | Ours | 76.7 | 53.4 | 52.5 | 68.7 | 72.4 | 39.4 | 30.8 |
| 4:8 | 0.5 | Paper | 72.7 | 53.8 | 46.5 | 66.6 | 66.7 | 34.1 | 25.8 |
| 4:8 | 0.5 | Ours | 73.0 | 53.8 | 46.9 | 66.9 | 67.0 | 34.0 | 26.2 |
| 2:4 | 0.5 | Paper | 67.7 | 53.0 | 40.9 | 62.4 | 61.8 | 31.2 | 24.2 |
| 2:4 | 0.5 | Ours | 68.0 | 53.4 | 41.2 | 62.6 | 62.6 | 30.9 | 23.8 |
SparseGPT
Llama-2-7b-hf:
| Sparsity | Ratio | Source | BoolQ | RTE | Hellaswag | Winogrande | ARC-E | ARC-C | OBQA |
|---|---|---|---|---|---|---|---|---|---|
| unstructured | 0.5 | Paper | 75.0 | 54.2 | 52.4 | 69.9 | 73.3 | 39.9 | 29.2 |
| unstructured | 0.5 | Ours | 73.7 | 53.8 | 52.8 | 70.0 | 72.0 | 38.5 | 29.2 |
| 4:8 | 0.5 | Paper | 72.7 | 55.2 | 48.2 | 68.1 | 69.2 | 35.8 | 27.4 |
| 4:8 | 0.5 | Ours | 72.5 | 56.7 | 48.2 | 67.3 | 69.0 | 35.2 | 27.6 |
| 2:4 | 0.5 | Paper | 70.5 | 58.8 | 43.3 | 66.7 | 64.1 | 30.0 | 23.2 |
| 2:4 | 0.5 | Ours | 70.3 | 58.5 | 43.3 | 64.7 | 64.0 | 31.6 | 24.0 |
Magnitude
Llama-2-7b-hf:
| Sparsity | Ratio | Source | BoolQ | RTE | Hellaswag | Winogrande | ARC-E | ARC-C | OBQA |
|---|---|---|---|---|---|---|---|---|---|
| unstructured | 0.5 | Paper | 63.0 | 57.0 | 49.1 | 63.3 | 64.1 | 34.6 | 26.8 |
| unstructured | 0.5 | Ours | 62.9 | 57.0 | 49.1 | 63.2 | 64.1 | 34.6 | 26.8 |
| 4:8 | 0.5 | Paper | 63.0 | 52.4 | 50.1 | 62.4 | 64.7 | 35.9 | 26.0 |
| 4:8 | 0.5 | Ours | 63.0 | 52.4 | 50.1 | 62.4 | 64.8 | 35.9 | 26.0 |
| 2:4 | 0.5 | Paper | 56.2 | 51.4 | 42.3 | 60.9 | 59.2 | 27.3 | 21.8 |
| 2:4 | 0.5 | Ours | 59.8 | 52.4 | 45.4 | 61.1 | 61.9 | 30.2 | 21.8 |
Sheared Llama
| Size | Source | BoolQ | PIQA | Winogrande | ARC-C | ARC-E | Hellaswag |
|---|---|---|---|---|---|---|---|
| 2.7B | Released | 84.5 | 66.4 | 53.2 | 26.5 | 49.9 | 47.1 |
| 2.7B | Tested | 84.2 | 66.2 | 55.9 | 28.2 | 52.8 | 46.9 |
| 1.3B | Released | 77.5 | 62.6 | 50.3 | 19.5 | 41.0 | 34.8 |
| 1.3B | Tested | 77.8 | 60.5 | 51.0 | 18.4 | 41.8 | 34.1 |
LLM-Pruner
| Source | Method | Importance Estimation | WikiText2 | BoolQ | PIQA | Hellaswag | Winogrande | ARC-E | ARC-C | OBQA |
|---|---|---|---|---|---|---|---|---|---|---|
| Paper | - | - | 12.6 | 73.2 | 78.4 | 73.0 | 67.0 | 67.5 | 41.4 | 42.4 |
| Ours | - | - | 12.7 | 73.1 | 78.4 | 73.0 | 67.1 | 67.5 | 41.4 | 42.4 |
| Paper | Block | Element 1 | 19.1 | 57.1 | 75.7 | 66.8 | 59.8 | 60.9 | 36.5 | 40.0 |
| Ours | Block | Element 1 | 20.1 | 59.1 | 75.9 | 66.5 | 59.1 | 61.8 | 37.0 | 40.6 |
| Paper | L2 | - | 582 | 59.8 | 58.0 | 37.0 | 52.4 | 33.1 | 28.6 | 29.8 |
| Ours | L2 | - | 457 | 60.2 | 58.7 | 37.1 | 53.2 | 32.9 | 27.8 | 29.8 |
| Paper | Random | - | 27.5 | 61.8 | 71.3 | 58.3 | 54.5 | 57.1 | 32.9 | 35.0 |
| Ours | Random | - | 25.8 | 62.0 | 70.8 | 57.9 | 58.1 | 52.3 | 32.4 | 38.0 |
| Paper | Block | Element 2 | 19.8 | 59.4 | 75.6 | 65.3 | 61.3 | 59.2 | 37.1 | 39.8 |
| Ours | Block | Element 2 | 20.4 | 63.9 | 75.0 | 63.9 | 57.5 | 60.5 | 37.1 | 39.6 |
| Paper | Block | Vector | 22.3 | 61.4 | 71.7 | 57.3 | 54.2 | 55.8 | 34.0 | 38.4 |
| Ours | Block | Vector | 20.4 | 62.2 | 74.1 | 64.4 | 62.6 | 58.8 | 35.7 | 40.8 |
Note: The results are obtained by running the exact pruning and evaluation scripts from the LLM-Pruner repo. Still, some results differ the reported results in the paper. My conjecture is that only 10 samples are randomly selected from the bookcorpus dataset for importance estimation, and this caused some randomness, even though we fixed the random seed.
Contributors

34 commits

9 commits
Similar repos


Languages
Python
96.7%
Jupyter Notebook
1.7%
Shell
1.2%
A collection of various llm pruning implementations, training code for GPUs & TPUs, and evaluation script.
Python
75
43 commits
updated Apr 20, 2026
README
Small LLMs: Pruning vs Training from Scratch
Yufeng Xu1, Taiming Lu1, Jiachen Zhu2, Mingjie Sun3, Kunjun Li1, and Zhuang Liu1
1 Princeton. 2 NYU. 3 CMU.
This is a Jax-based repo for LLM Prunning, It contains:
- the implementations of various LLM pruning methods of different granularity.
- pretraining and fine-tuning code for both GPU and TPU platforms.
- evaluation scripts for assessing model performance.
We gratefully acknowledge the generous support of the Google TPU Research Cloud (TRC), which provided the computational resources used to build this repository.
The repo is organized as follows:
├── pruning
│   ├── FLAP # including Wanda-sp and FLAP
│   ├── LLM-Pruner
│   ├── llmshearing # sheared llama
│   ├── minitron # including shortgpt
│   ├── SLEB # including sleb
│   ├── SliceGPT # including slicegpt
│   └── wanda # including sparsegpt and magnitude pruning
├── training
│   ├── fms_fsdp
│   └── maxtext
└── eval
where pruning is the collection of the pruning methods we experimented; training contains the LLM training frameworks we used, and we provided options for both TPU and GPU; eval contains JAX-compatible eval scripts we used to evaluate the pruned models.
Supported Features
Pruning Methods
Training Frameworks
Evaluation
- accelerate lm-eval-harness for maxtext. (by 2-4x times!)
Get Started
Pruning
In order to reproduce the results of the different pruning methods, we need to set up separate environments for different methods. The installation and command guide can be found at pruning/<method>/README.md. Below is an overview:
Minitron
cd pruning/minitron
bash scripts/install.sh
bash scripts/prune_llama3.1-8b.sh # contains minitron depth and width for llama3.1-8b
ShortGPT
cd pruning/minitron
bash scripts/install.sh
bash scripts/prune_llama2-7b.sh
Wanda, SparseGPT, Magnitude
cd pruning/wanda
bash scripts/install.sh
bash scripts/prune_llama3.1-8b.sh # contains wanda, sparsegpt, and magnitude for llama3.1-8b
bash scripts/prune_llama2-7b.sh
bash scripts/prune_llama-7b.sh
LLM-Pruner
cd pruning/LLM-Pruner
bash scripts/install.sh
bash scripts/prune_llama-7b.sh
bash scripts/prune_llama2-7b.sh
bash scripts/prune_llama3.1-8b.sh
Sheared Llama
cd pruning/llmshearing
bash scripts/install.sh

mkdir -p llmshearing/data/red_pajama && cd llmshearing/data/red_pajama
huggingface-cli download Zephyr271828/redpajama-for-prune --repo-type dataset --local-dir for_prune
cd -

bash scripts/hf2composer.sh
bash scripts/prune_llama2-2.7b.sh
bash scripts/prune_llama2-1.3b.sh
bash scripts/prune_llama2-370m.sh
bash scripts/composer2hf.sh
Training
GPU To train on GPUs, please refer to the guide of fms-fsdp for details.
TPU To train on TPUs, please refer to guide of MaxText for details.
Evaluation
GPU
For evaluation on GPUS, you may run the following evaluation script on your HF checkpoint:
cd training/fms_fsdp
bash scripts/install.sh

cd ../../eval
bash scripts/eval.sh
Note for LLM-Pruner and Wanda, they have specified a specific version of lm-eval to use, which is included in their respective directory, and the evaluation code is included in the pruning process.
For all other methods, you may eval with the script provided.
TPU Please refer to the guide of MaxText for details.
Reproduction Results
In this section, we show some of our results to verify that we can reproduce the results from the original pruning papers.
- For Minitron, the original papers did not report evaluation results after pruning and before retraining, so we attempt to reproduce the plots from LLM Pruning and Distillation in Practice: The Minitron Approach.
- For ShortGPT, although evaluation results are provided, yet we noticed there are inconsistencies between results in the table (also see ShortGPT: Layers in Large Language Models are More Redundant Than You Expect). Therefore, we choose to reproduce the block importance plot from the paper, which implies the correctness of our implementation.
- For all other methods, both official implementation and evaluation results are provided, so we simply provide comparison with the reported results in paper.
Minitron-Winogrande
Left: plot from the paper; Right: plot made by us.
|
Paper (Sreenivas et al.)
|
Ours
|
Minitron-Wikitext
|
Paper (Sreenivas et al.) |
Ours |
ShortGPT
|
Paper (Men et al.) |
Ours |
Wanda
Llama-2-7b-hf:
| Sparsity | Ratio | Source | BoolQ | RTE | Hellaswag | Winogrande | ARC-E | ARC-C | OBQA |
|---|---|---|---|---|---|---|---|---|---|
| unstructured | 0.5 | Paper | 75.0 | 53.4 | 52.5 | 68.2 | 72.8 | 39.9 | 31.2 |
| unstructured | 0.5 | Ours | 76.7 | 53.4 | 52.5 | 68.7 | 72.4 | 39.4 | 30.8 |
| 4:8 | 0.5 | Paper | 72.7 | 53.8 | 46.5 | 66.6 | 66.7 | 34.1 | 25.8 |
| 4:8 | 0.5 | Ours | 73.0 | 53.8 | 46.9 | 66.9 | 67.0 | 34.0 | 26.2 |
| 2:4 | 0.5 | Paper | 67.7 | 53.0 | 40.9 | 62.4 | 61.8 | 31.2 | 24.2 |
| 2:4 | 0.5 | Ours | 68.0 | 53.4 | 41.2 | 62.6 | 62.6 | 30.9 | 23.8 |
SparseGPT
Llama-2-7b-hf:
| Sparsity | Ratio | Source | BoolQ | RTE | Hellaswag | Winogrande | ARC-E | ARC-C | OBQA |
|---|---|---|---|---|---|---|---|---|---|
| unstructured | 0.5 | Paper | 75.0 | 54.2 | 52.4 | 69.9 | 73.3 | 39.9 | 29.2 |
| unstructured | 0.5 | Ours | 73.7 | 53.8 | 52.8 | 70.0 | 72.0 | 38.5 | 29.2 |
| 4:8 | 0.5 | Paper | 72.7 | 55.2 | 48.2 | 68.1 | 69.2 | 35.8 | 27.4 |
| 4:8 | 0.5 | Ours | 72.5 | 56.7 | 48.2 | 67.3 | 69.0 | 35.2 | 27.6 |
| 2:4 | 0.5 | Paper | 70.5 | 58.8 | 43.3 | 66.7 | 64.1 | 30.0 | 23.2 |
| 2:4 | 0.5 | Ours | 70.3 | 58.5 | 43.3 | 64.7 | 64.0 | 31.6 | 24.0 |
Magnitude
Llama-2-7b-hf:
| Sparsity | Ratio | Source | BoolQ | RTE | Hellaswag | Winogrande | ARC-E | ARC-C | OBQA |
|---|---|---|---|---|---|---|---|---|---|
| unstructured | 0.5 | Paper | 63.0 | 57.0 | 49.1 | 63.3 | 64.1 | 34.6 | 26.8 |
| unstructured | 0.5 | Ours | 62.9 | 57.0 | 49.1 | 63.2 | 64.1 | 34.6 | 26.8 |
| 4:8 | 0.5 | Paper | 63.0 | 52.4 | 50.1 | 62.4 | 64.7 | 35.9 | 26.0 |
| 4:8 | 0.5 | Ours | 63.0 | 52.4 | 50.1 | 62.4 | 64.8 | 35.9 | 26.0 |
| 2:4 | 0.5 | Paper | 56.2 | 51.4 | 42.3 | 60.9 | 59.2 | 27.3 | 21.8 |
| 2:4 | 0.5 | Ours | 59.8 | 52.4 | 45.4 | 61.1 | 61.9 | 30.2 | 21.8 |
Sheared Llama
| Size | Source | BoolQ | PIQA | Winogrande | ARC-C | ARC-E | Hellaswag |
|---|---|---|---|---|---|---|---|
| 2.7B | Released | 84.5 | 66.4 | 53.2 | 26.5 | 49.9 | 47.1 |
| 2.7B | Tested | 84.2 | 66.2 | 55.9 | 28.2 | 52.8 | 46.9 |
| 1.3B | Released | 77.5 | 62.6 | 50.3 | 19.5 | 41.0 | 34.8 |
| 1.3B | Tested | 77.8 | 60.5 | 51.0 | 18.4 | 41.8 | 34.1 |
LLM-Pruner
| Source | Method | Importance Estimation | WikiText2 | BoolQ | PIQA | Hellaswag | Winogrande | ARC-E | ARC-C | OBQA |
|---|---|---|---|---|---|---|---|---|---|---|
| Paper | - | - | 12.6 | 73.2 | 78.4 | 73.0 | 67.0 | 67.5 | 41.4 | 42.4 |
| Ours | - | - | 12.7 | 73.1 | 78.4 | 73.0 | 67.1 | 67.5 | 41.4 | 42.4 |
| Paper | Block | Element 1 | 19.1 | 57.1 | 75.7 | 66.8 | 59.8 | 60.9 | 36.5 | 40.0 |
| Ours | Block | Element 1 | 20.1 | 59.1 | 75.9 | 66.5 | 59.1 | 61.8 | 37.0 | 40.6 |
| Paper | L2 | - | 582 | 59.8 | 58.0 | 37.0 | 52.4 | 33.1 | 28.6 | 29.8 |
| Ours | L2 | - | 457 | 60.2 | 58.7 | 37.1 | 53.2 | 32.9 | 27.8 | 29.8 |
| Paper | Random | - | 27.5 | 61.8 | 71.3 | 58.3 | 54.5 | 57.1 | 32.9 | 35.0 |
| Ours | Random | - | 25.8 | 62.0 | 70.8 | 57.9 | 58.1 | 52.3 | 32.4 | 38.0 |
| Paper | Block | Element 2 | 19.8 | 59.4 | 75.6 | 65.3 | 61.3 | 59.2 | 37.1 | 39.8 |
| Ours | Block | Element 2 | 20.4 | 63.9 | 75.0 | 63.9 | 57.5 | 60.5 | 37.1 | 39.6 |
| Paper | Block | Vector | 22.3 | 61.4 | 71.7 | 57.3 | 54.2 | 55.8 | 34.0 | 38.4 |
| Ours | Block | Vector | 20.4 | 62.2 | 74.1 | 64.4 | 62.6 | 58.8 | 35.7 | 40.8 |
Note: The results are obtained by running the exact pruning and evaluation scripts from the LLM-Pruner repo. Still, some results differ the reported results in the paper. My conjecture is that only 10 samples are randomly selected from the bookcorpus dataset for importance estimation, and this caused some randomness, even though we fixed the random seed.
Similar repos
Contributors
34 commits
9 commits
Languages
Python
96.7%
Jupyter Notebook
1.7%
Shell
1.2%