
README
Awesome-TableReasoning-LLM-Survey


This repository contains a list of papers, datasets and leaderboards of the table reasoning task based on the Large Language Models (LLMs), which is carefully and comprehensively organized. If you found any error, please open an issue or pull request.
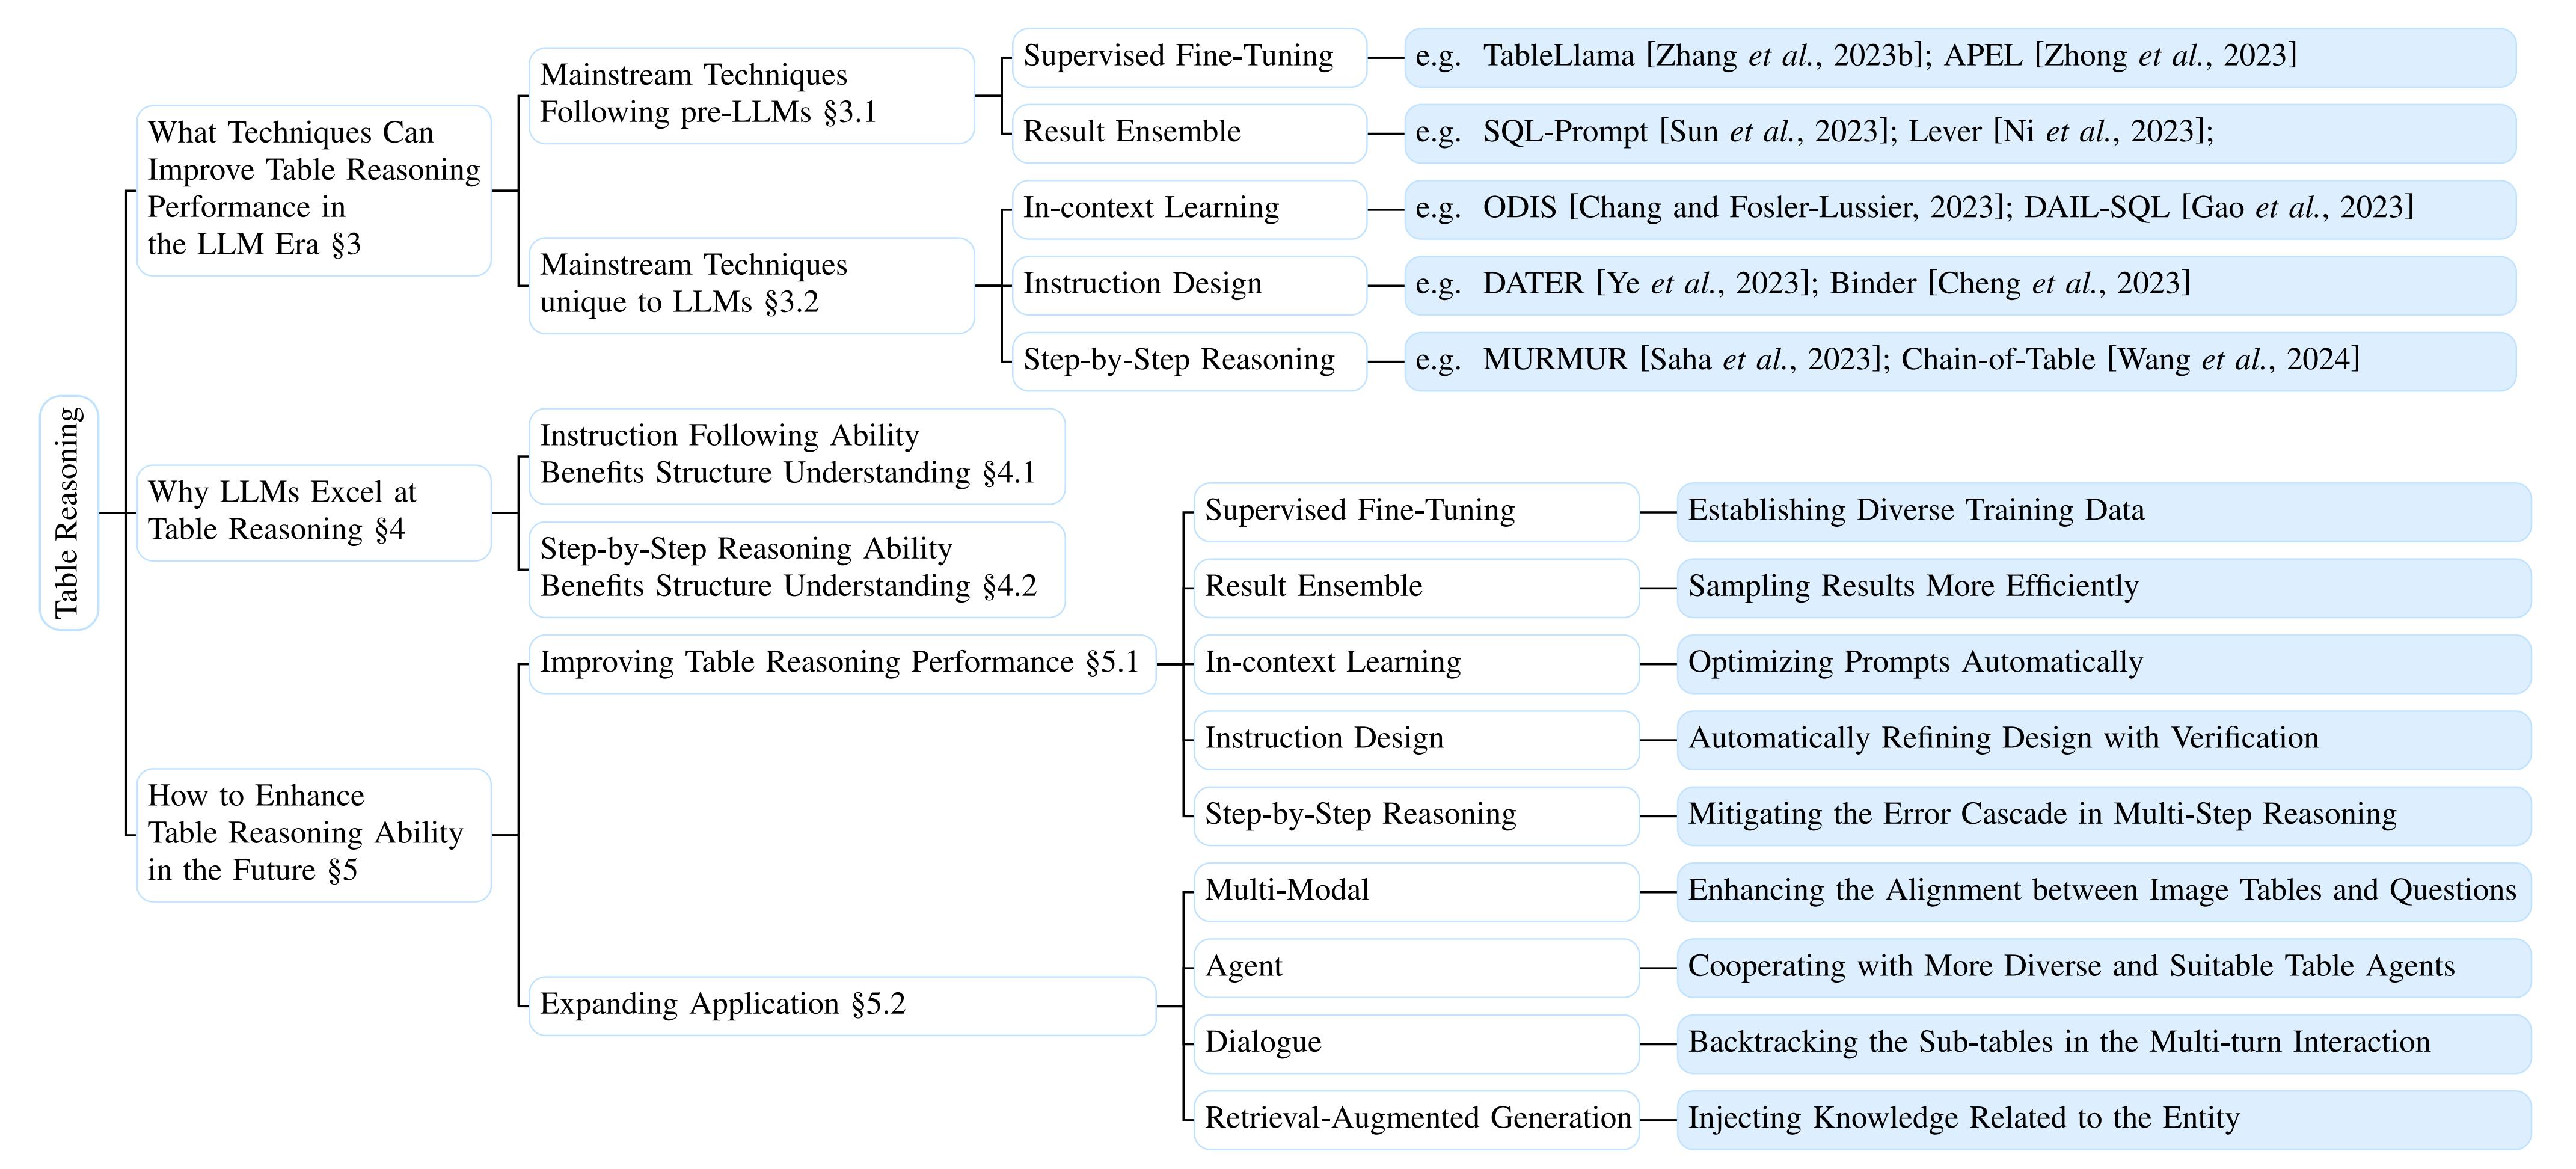
For more details, please refer to the paper: A Survey of Table Reasoning with Large Language Models, the overview of which is shown in the figure below.
Introduction
In a table reasoning task, the inputs to the model include the table, optionally a text description of the table, and the user question that corresponds to variable tasks (e.g., table QA, table fact verification, table-to-text, and text-to-SQL), and the outputs are the answers of the task. Recent research has shown that LLMs exhibit compelling performance across NLP tasks, in particular, the ability of in-context learning without large-scale data fine-tuning dramatically reduces annotation requirements, which we call the LLM era. Considering the high annotation and training overheads of table reasoning, there has been a lot of work on applying LLMs to table reasoning tasks to reduce the overheads, which has become the current mainstream method.
Benchmarks and Leaderboard
In this part, we present leadboards of currect mainstream benchmarks of table reasoning with LLMs. Each benchmark is ordered by the performance. Type denotes the reasoning types:
- PLM-SOTA: the best performance of small-scale PLMs;
- LLM-fine-tuned: fine-tuning LLMs;
- LLM-few-shot: inference using LLMs with few-shot.
WikiTableQuestions
WikiTableQuestions serves as the initial benchmark in the table QA task, which has open-domain tables accompanied by complex questions.
| Type | Method | Organization | Model | Setting | Dev-EM | Test-EM | Published Date |
|---|---|---|---|---|---|---|---|
| PLM-SOTA | OmniTab | CMU + Microsoft Azure AI | TAPEX (BART) | In-Domain | - | 62.8 | 2022.07 |
| LLM-fine-tuned | TableLlama | OSU | LongLoRA-7B(Llama-2-7B) | In-Domain | - | 31.6 | 2023.11 |
| LLM-few-shot | ReAcTable | Microsoft | code-davinci-002 | In-Domain | - | 68.0 | 2023.10 |
| Chain-of-Table | PaLM 2-S | In-Domain | - | 67.3 | 2024.01 | ||
| Dater | USTC & Alibaba Group | code-davinci-002 | In-Domain | 64.8 | 65.9 | 2023.01 | |
| Lever | Yale & Meta AI | code-davinci-002 | In-Domain | 64.6 | 65.8 | 2023.02 | |
| Binder | HKU | code-davinci-002 | In-Domain | 65.0 | 64.6 | 2022.10 | |
| OpenTab | UMD | gpt-3.5-turbo-16k | Open-Domain | - | 64.1 | 2024.01 | |
| IRR | RUC | text-davinci-003 | In-Domain | - | 57.0 | 2023.05 | |
| Chen [2023] | UW | code-davinci-002 | In-Domain | - | 48.8 | 2022.10 | |
| Cao et al. [2023] | CMU | code-davinci-002 | In-Domain | - | 42.4 | 2023.10 |
TabFact
TabFact, as the first benchmark in the table fact verification task, features large-scale cross-domain table data and complex reasoning requirements.
| Type | Method | Organization | Model | Test-Acc | Published Date |
|---|---|---|---|---|---|
| PLM-SOTA | LKA | SEU | DeBERTaV1 | 84.9 | 2022.04 |
| LLM-fine-tuned | TableLlama | OSU | LongLoRA-7B(Llama-2-7B) | 82.6 | 2023.11 |
| LLM-few-shot | Dater | USTC & Alibaba Group | code-davinci-002 | 93.0 | 2023.01 |
| IRR | RUC | gpt-3.5-turbo | 87.6 | 2023.05 | |
| Chain-of-Table | PaLM 2-S | 86.6 | 2024.01 | ||
| ReAcTable | Microsoft | code-davinci-002 | 86.1 | 2023.10 | |
| Binder | HKU | code-davinci-002 | 86.0 | 2022.10 | |
| Chen [2023] | UW | code-davinci-002 | 78.8 | 2022.10 | |
| TAP4LLM | Microsoft | gpt-3.5-turbo | 62.7 | 2023.12 |
FeTaQA
FeTaQA requires the model to generate a free-form answer to the question, with large-scale and high-quality data.
| Type | Method | Organization | Model | Dev-BLEU | Test-BLEU | Test-ROUGE-1 | Test-ROUGE-2 | Test-ROUGE-3 | Test-ROUGE-L | Published Date |
|---|---|---|---|---|---|---|---|---|---|---|
| PLM-SOTA | UNIFIEDSKG | HKU & CMU | T5-3B | - | 33.44 | 0.65 | 0.43 | - | 0.55 | 2022.01 |
| LLM-fine-tuned | TableLlama | OSU | LongLoRA-7B(Llama-2-7B) | - | 39.05 | - | - | - | - | 2023.11 |
| HELLaMA | FDU | Llama-2-13B | - | 34.18 | 0.67 | 0.45 | 0.57 | - | 2023.11 | |
| LLM-few-shot | ReAcTable | Microsoft | code-davinci-002 | - | - | 0.71 | 0.46 | - | 0.61 | 2023.10 |
| Chain-of-Table | PaLM 2-S | - | 32.61 | 0.66 | 0.44 | 0.56 | - | 2024.01 | ||
| Dater | USTC & Alibaba Group | code-davinci-002 | - | 30.92 | 0.66 | 0.45 | 0.56 | 0.56 | 2023.01 |
Spider
Spider is the first multi-domain, multi-table benchmark on the text-to-SQL task.
| Type | Method | Organization | Model | Setting | Dev-EM | Dev-EX | Test-EM | Test-EX | Published Date |
|---|---|---|---|---|---|---|---|---|---|
| PLM-SOTA | RESDSQL | RUC | RESDSQL-3B (T503B) + NatSQL | In-Domain | 80.5 | 84.1 | 72.0 | 79.9 | 2023.02 |
| LLM-fine-tuned | DB-GPT | Ant Group | QWEN-14B-CHAT-SFT | In-Domain | - | 70.1 | - | - | 2023.12 |
| DBCopilot | CAS | T5-base + gpt-3.5-turbo-16k-0613 | Open-Domain @5 | - | - | - | 72.8 | 2023.12 | |
| LLM-few-shot | DAIL-SQL | Alibaba Group | GPT-4 | In-Domain | - | 83.5 | - | 86.6 | 2023.08 |
| DIN-SQL | UofA | GPT-4 | In-Domain | 60.1 | 74.2 | 60.0 | 85.3 | 2023.04 | |
| MAC-SQL | BUAA | GPT4 | In-Domain | - | 86.8 | - | 82.8 | 2023.12 | |
| CRUSH | IIT Bombay | text-davinci-003 + RESDSQL-3B | Open-Domain @10 | - | - | 46.? | 53.? | 2023.11 | |
| ODIS | OSU | code-davinci-002 | In-Domain | - | 85.2 | - | - | 2023.10 | |
| Re-rank | PKU | gpt-4-turbo | In-Domain | 64.5 | 84.5 | - | - | 2024.01 | |
| Auto-CoT | SJTU | GPT-4 | In-Domain | 61.7 | 82.9 | - | - | 2023.10 | |
| Lever | Yale & Meta AI | code-davinci-002 | In-Domain | - | 81.9 | - | - | 2023.02 | |
| IRR | RUC | gpt-3.5-turbo | In-Domain | - | 77.8 | - | - | 2023.05 | |
| SQLPrompt | Cloud AI Research Team | PaLM FLAN 540B + PaLM62B + PaLM FLAN 62B | In-Domain | 68.6 | 77.1 | - | - | 2023.11 | |
| Cao et al. [2023] | CMU | code-davinci-002 | In-Domain | - | 63.8 | - | - | 2023.10 | |
| TAP4LLM | Microsoft | gpt-3.5-turbo | In-Domain | 82.5 | - | - | - | 2023.12 |
Citation
If you find our survey helpful, please cite as following:
@article{zhang2024survey,
  title={A Survey of Table Reasoning with Large Language Models},
  author={Zhang, Xuanliang and Wang, Dingzirui and Dou, Longxu and Zhu, Qingfu and Che, Wanxiang},
  journal={arXiv preprint arXiv:2402.08259},
  year={2024}
}
Contributors

13 commits
Similar repos


README
Awesome-TableReasoning-LLM-Survey
This repository contains a list of papers, datasets and leaderboards of the table reasoning task based on the Large Language Models (LLMs), which is carefully and comprehensively organized. If you found any error, please open an issue or pull request.
For more details, please refer to the paper: A Survey of Table Reasoning with Large Language Models, the overview of which is shown in the figure below.
Introduction
In a table reasoning task, the inputs to the model include the table, optionally a text description of the table, and the user question that corresponds to variable tasks (e.g., table QA, table fact verification, table-to-text, and text-to-SQL), and the outputs are the answers of the task. Recent research has shown that LLMs exhibit compelling performance across NLP tasks, in particular, the ability of in-context learning without large-scale data fine-tuning dramatically reduces annotation requirements, which we call the LLM era. Considering the high annotation and training overheads of table reasoning, there has been a lot of work on applying LLMs to table reasoning tasks to reduce the overheads, which has become the current mainstream method.
Benchmarks and Leaderboard
In this part, we present leadboards of currect mainstream benchmarks of table reasoning with LLMs. Each benchmark is ordered by the performance. Type denotes the reasoning types:
- PLM-SOTA: the best performance of small-scale PLMs;
- LLM-fine-tuned: fine-tuning LLMs;
- LLM-few-shot: inference using LLMs with few-shot.
WikiTableQuestions
WikiTableQuestions serves as the initial benchmark in the table QA task, which has open-domain tables accompanied by complex questions.
| Type | Method | Organization | Model | Setting | Dev-EM | Test-EM | Published Date |
|---|---|---|---|---|---|---|---|
| PLM-SOTA | OmniTab | CMU + Microsoft Azure AI | TAPEX (BART) | In-Domain | - | 62.8 | 2022.07 |
| LLM-fine-tuned | TableLlama | OSU | LongLoRA-7B(Llama-2-7B) | In-Domain | - | 31.6 | 2023.11 |
| LLM-few-shot | ReAcTable | Microsoft | code-davinci-002 | In-Domain | - | 68.0 | 2023.10 |
| Chain-of-Table | PaLM 2-S | In-Domain | - | 67.3 | 2024.01 | ||
| Dater | USTC & Alibaba Group | code-davinci-002 | In-Domain | 64.8 | 65.9 | 2023.01 | |
| Lever | Yale & Meta AI | code-davinci-002 | In-Domain | 64.6 | 65.8 | 2023.02 | |
| Binder | HKU | code-davinci-002 | In-Domain | 65.0 | 64.6 | 2022.10 | |
| OpenTab | UMD | gpt-3.5-turbo-16k | Open-Domain | - | 64.1 | 2024.01 | |
| IRR | RUC | text-davinci-003 | In-Domain | - | 57.0 | 2023.05 | |
| Chen [2023] | UW | code-davinci-002 | In-Domain | - | 48.8 | 2022.10 | |
| Cao et al. [2023] | CMU | code-davinci-002 | In-Domain | - | 42.4 | 2023.10 |
TabFact
TabFact, as the first benchmark in the table fact verification task, features large-scale cross-domain table data and complex reasoning requirements.
| Type | Method | Organization | Model | Test-Acc | Published Date |
|---|---|---|---|---|---|
| PLM-SOTA | LKA | SEU | DeBERTaV1 | 84.9 | 2022.04 |
| LLM-fine-tuned | TableLlama | OSU | LongLoRA-7B(Llama-2-7B) | 82.6 | 2023.11 |
| LLM-few-shot | Dater | USTC & Alibaba Group | code-davinci-002 | 93.0 | 2023.01 |
| IRR | RUC | gpt-3.5-turbo | 87.6 | 2023.05 | |
| Chain-of-Table | PaLM 2-S | 86.6 | 2024.01 | ||
| ReAcTable | Microsoft | code-davinci-002 | 86.1 | 2023.10 | |
| Binder | HKU | code-davinci-002 | 86.0 | 2022.10 | |
| Chen [2023] | UW | code-davinci-002 | 78.8 | 2022.10 | |
| TAP4LLM | Microsoft | gpt-3.5-turbo | 62.7 | 2023.12 |
FeTaQA
FeTaQA requires the model to generate a free-form answer to the question, with large-scale and high-quality data.
| Type | Method | Organization | Model | Dev-BLEU | Test-BLEU | Test-ROUGE-1 | Test-ROUGE-2 | Test-ROUGE-3 | Test-ROUGE-L | Published Date |
|---|---|---|---|---|---|---|---|---|---|---|
| PLM-SOTA | UNIFIEDSKG | HKU & CMU | T5-3B | - | 33.44 | 0.65 | 0.43 | - | 0.55 | 2022.01 |
| LLM-fine-tuned | TableLlama | OSU | LongLoRA-7B(Llama-2-7B) | - | 39.05 | - | - | - | - | 2023.11 |
| HELLaMA | FDU | Llama-2-13B | - | 34.18 | 0.67 | 0.45 | 0.57 | - | 2023.11 | |
| LLM-few-shot | ReAcTable | Microsoft | code-davinci-002 | - | - | 0.71 | 0.46 | - | 0.61 | 2023.10 |
| Chain-of-Table | PaLM 2-S | - | 32.61 | 0.66 | 0.44 | 0.56 | - | 2024.01 | ||
| Dater | USTC & Alibaba Group | code-davinci-002 | - | 30.92 | 0.66 | 0.45 | 0.56 | 0.56 | 2023.01 |
Spider
Spider is the first multi-domain, multi-table benchmark on the text-to-SQL task.
| Type | Method | Organization | Model | Setting | Dev-EM | Dev-EX | Test-EM | Test-EX | Published Date |
|---|---|---|---|---|---|---|---|---|---|
| PLM-SOTA | RESDSQL | RUC | RESDSQL-3B (T503B) + NatSQL | In-Domain | 80.5 | 84.1 | 72.0 | 79.9 | 2023.02 |
| LLM-fine-tuned | DB-GPT | Ant Group | QWEN-14B-CHAT-SFT | In-Domain | - | 70.1 | - | - | 2023.12 |
| DBCopilot | CAS | T5-base + gpt-3.5-turbo-16k-0613 | Open-Domain @5 | - | - | - | 72.8 | 2023.12 | |
| LLM-few-shot | DAIL-SQL | Alibaba Group | GPT-4 | In-Domain | - | 83.5 | - | 86.6 | 2023.08 |
| DIN-SQL | UofA | GPT-4 | In-Domain | 60.1 | 74.2 | 60.0 | 85.3 | 2023.04 | |
| MAC-SQL | BUAA | GPT4 | In-Domain | - | 86.8 | - | 82.8 | 2023.12 | |
| CRUSH | IIT Bombay | text-davinci-003 + RESDSQL-3B | Open-Domain @10 | - | - | 46.? | 53.? | 2023.11 | |
| ODIS | OSU | code-davinci-002 | In-Domain | - | 85.2 | - | - | 2023.10 | |
| Re-rank | PKU | gpt-4-turbo | In-Domain | 64.5 | 84.5 | - | - | 2024.01 | |
| Auto-CoT | SJTU | GPT-4 | In-Domain | 61.7 | 82.9 | - | - | 2023.10 | |
| Lever | Yale & Meta AI | code-davinci-002 | In-Domain | - | 81.9 | - | - | 2023.02 | |
| IRR | RUC | gpt-3.5-turbo | In-Domain | - | 77.8 | - | - | 2023.05 | |
| SQLPrompt | Cloud AI Research Team | PaLM FLAN 540B + PaLM62B + PaLM FLAN 62B | In-Domain | 68.6 | 77.1 | - | - | 2023.11 | |
| Cao et al. [2023] | CMU | code-davinci-002 | In-Domain | - | 63.8 | - | - | 2023.10 | |
| TAP4LLM | Microsoft | gpt-3.5-turbo | In-Domain | 82.5 | - | - | - | 2023.12 |
Citation
If you find our survey helpful, please cite as following:
@article{zhang2024survey,
  title={A Survey of Table Reasoning with Large Language Models},
  author={Zhang, Xuanliang and Wang, Dingzirui and Dou, Longxu and Zhu, Qingfu and Che, Wanxiang},
  journal={arXiv preprint arXiv:2402.08259},
  year={2024}
}
Similar repos
Contributors
13 commits