
PureDocBench: source-traceable benchmark for document parsing across clean, degraded, and real-world settings
See the codeREADME
PureDocBench
How far is document parsing from solved?
A source-traceable benchmark for OCR and document parsing across clean, digitally degraded, and real-degraded document settings.



中文说明 | Dataset | Paper | GT Review & Corrections
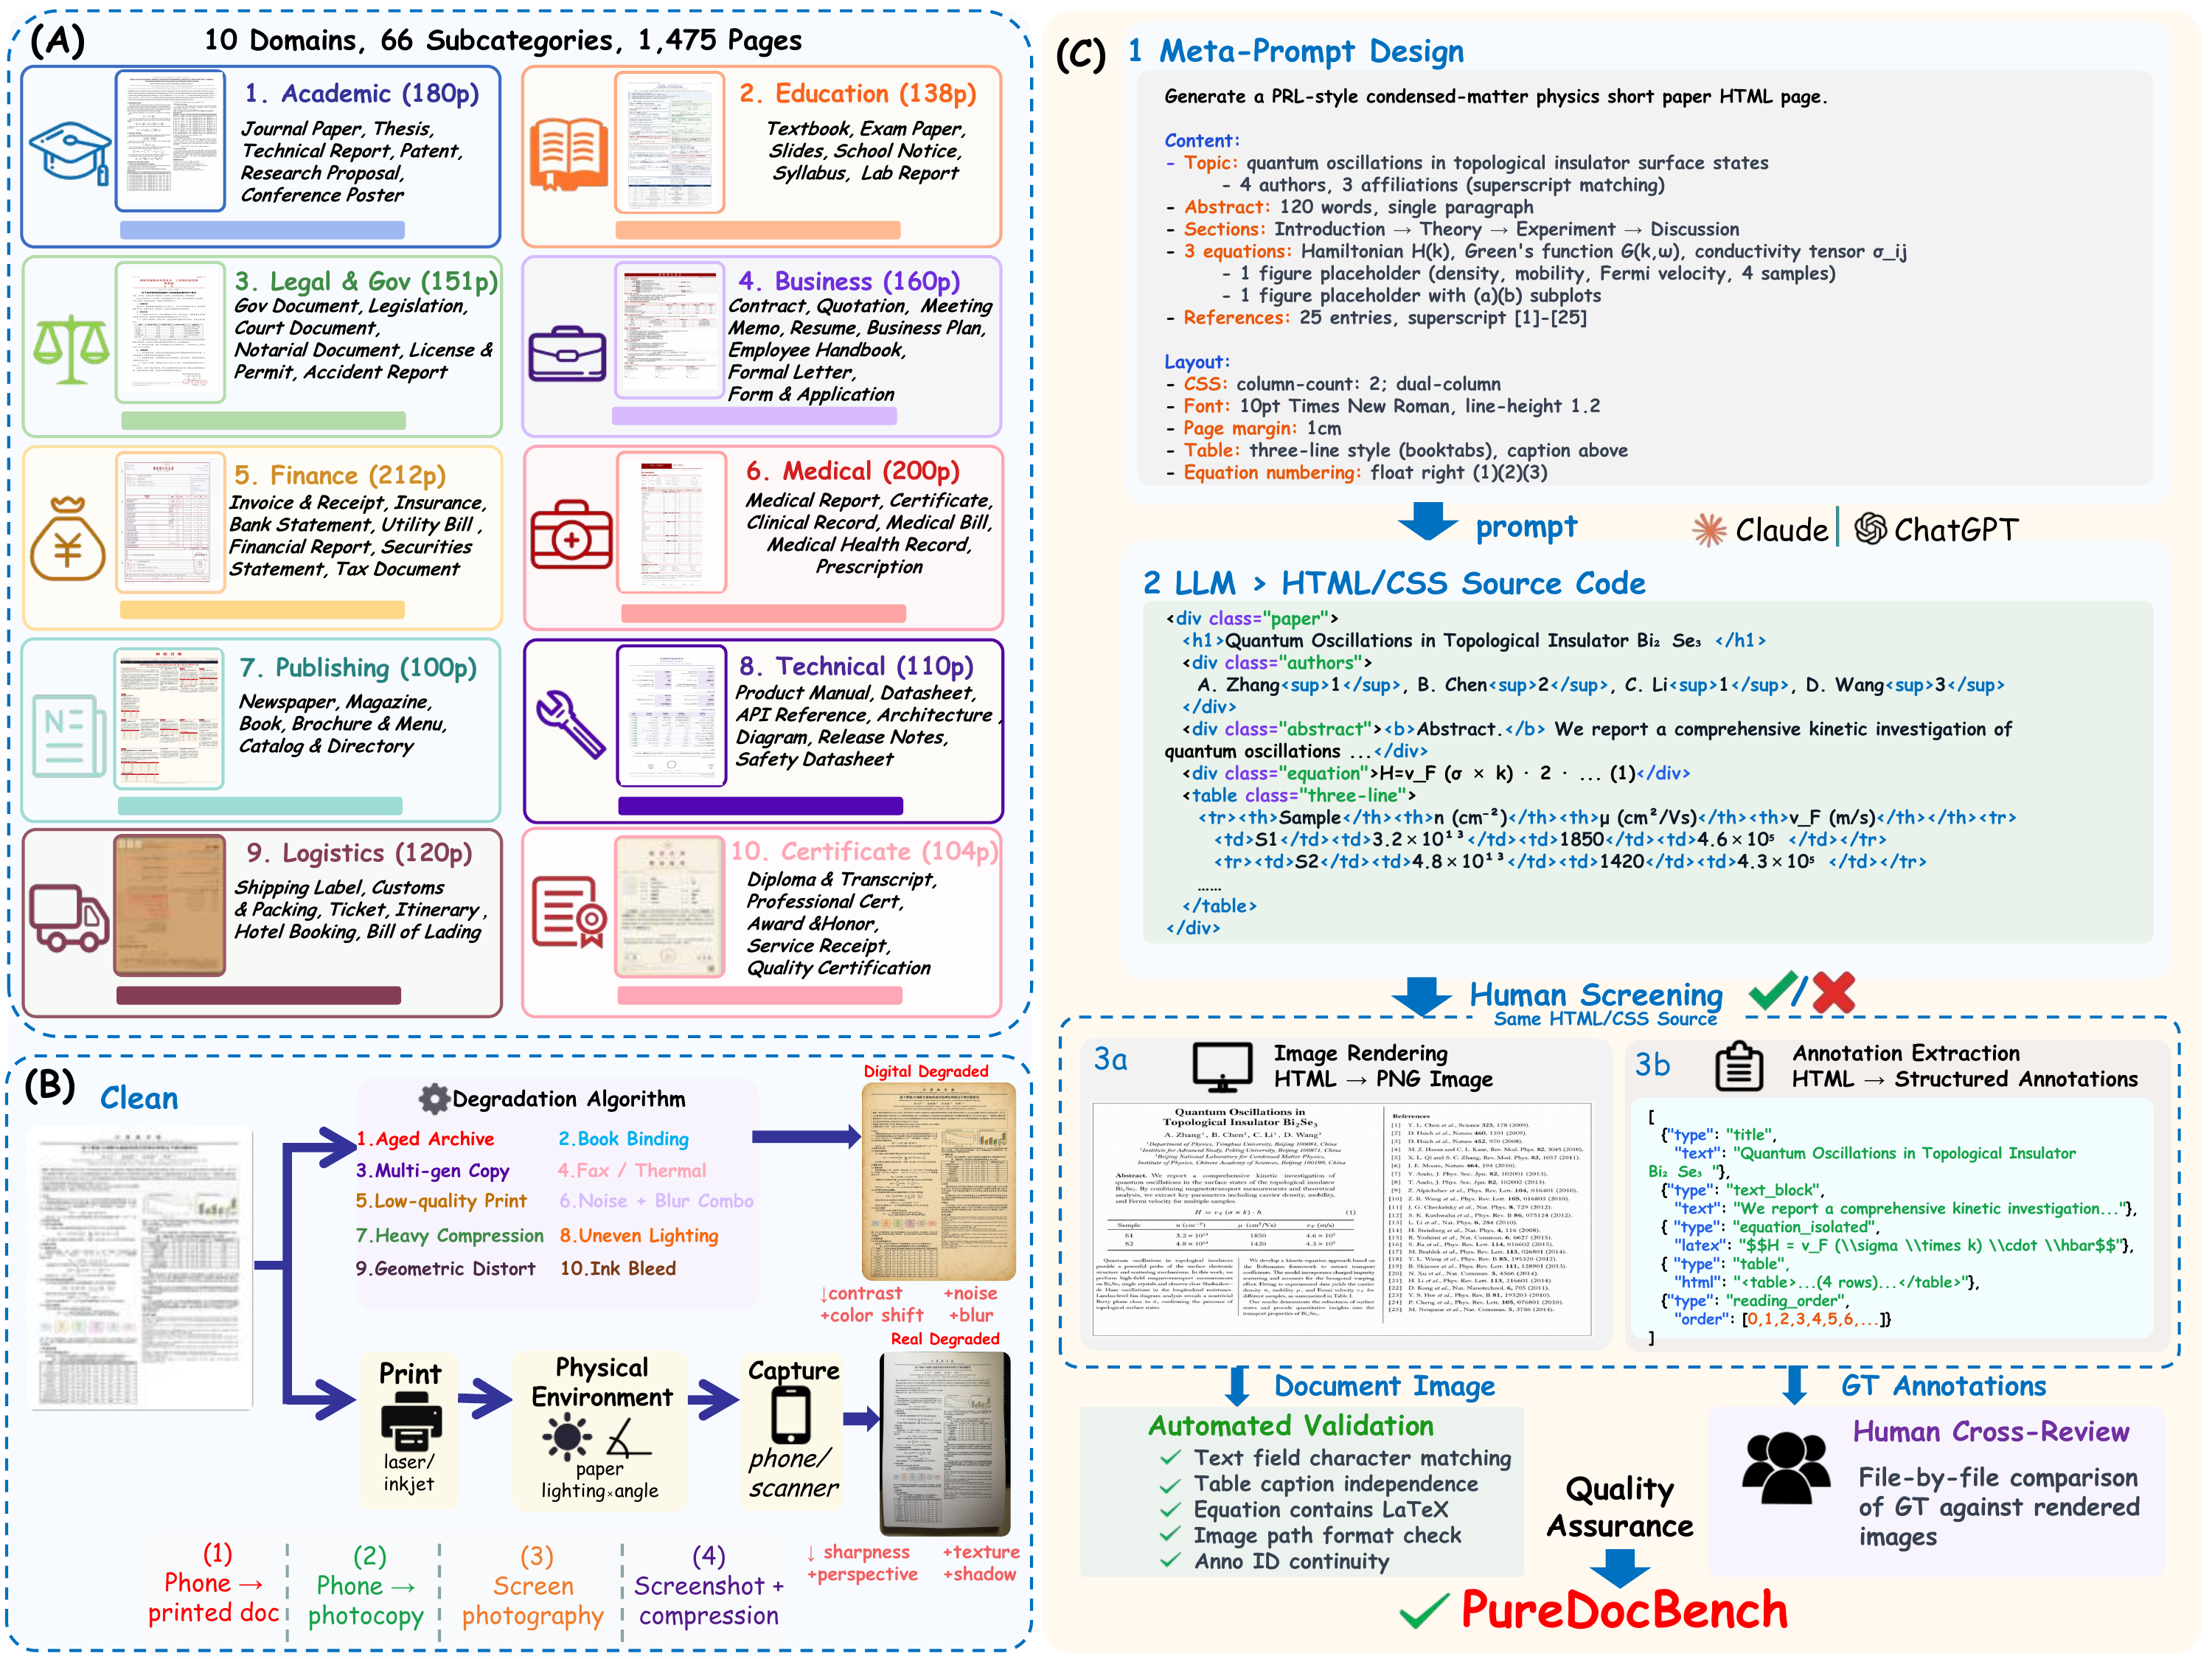
PureDocBench uses HTML/CSS document sources as hidden anchors: each page is rendered into images and annotated from the same structured source. This gives a benchmark where text, tables, formulas, captions, and reading order can be scored with less post-hoc annotation noise.
PureDocBench 是一个源可追踪的 OCR / 文档解析 benchmark。数据由 HTML/CSS 源文件渲染而来,GT 标注从同源结构中抽取,覆盖 clean、digital-degraded、real-degraded 三条图像轨道。
Updates
- Current GT: The stable alias is
puredocbench-gt-latest; the exact revision and timestamp are recorded in Hugging Facegt/latest.json. - 2026-06-14: Updated GT annotations and opened a GT Review app for community corrections.
- 2026-05-08: Initial public release of PureDocBench, including the paper PDF and full dataset on Hugging Face.
GT Annotation Examples
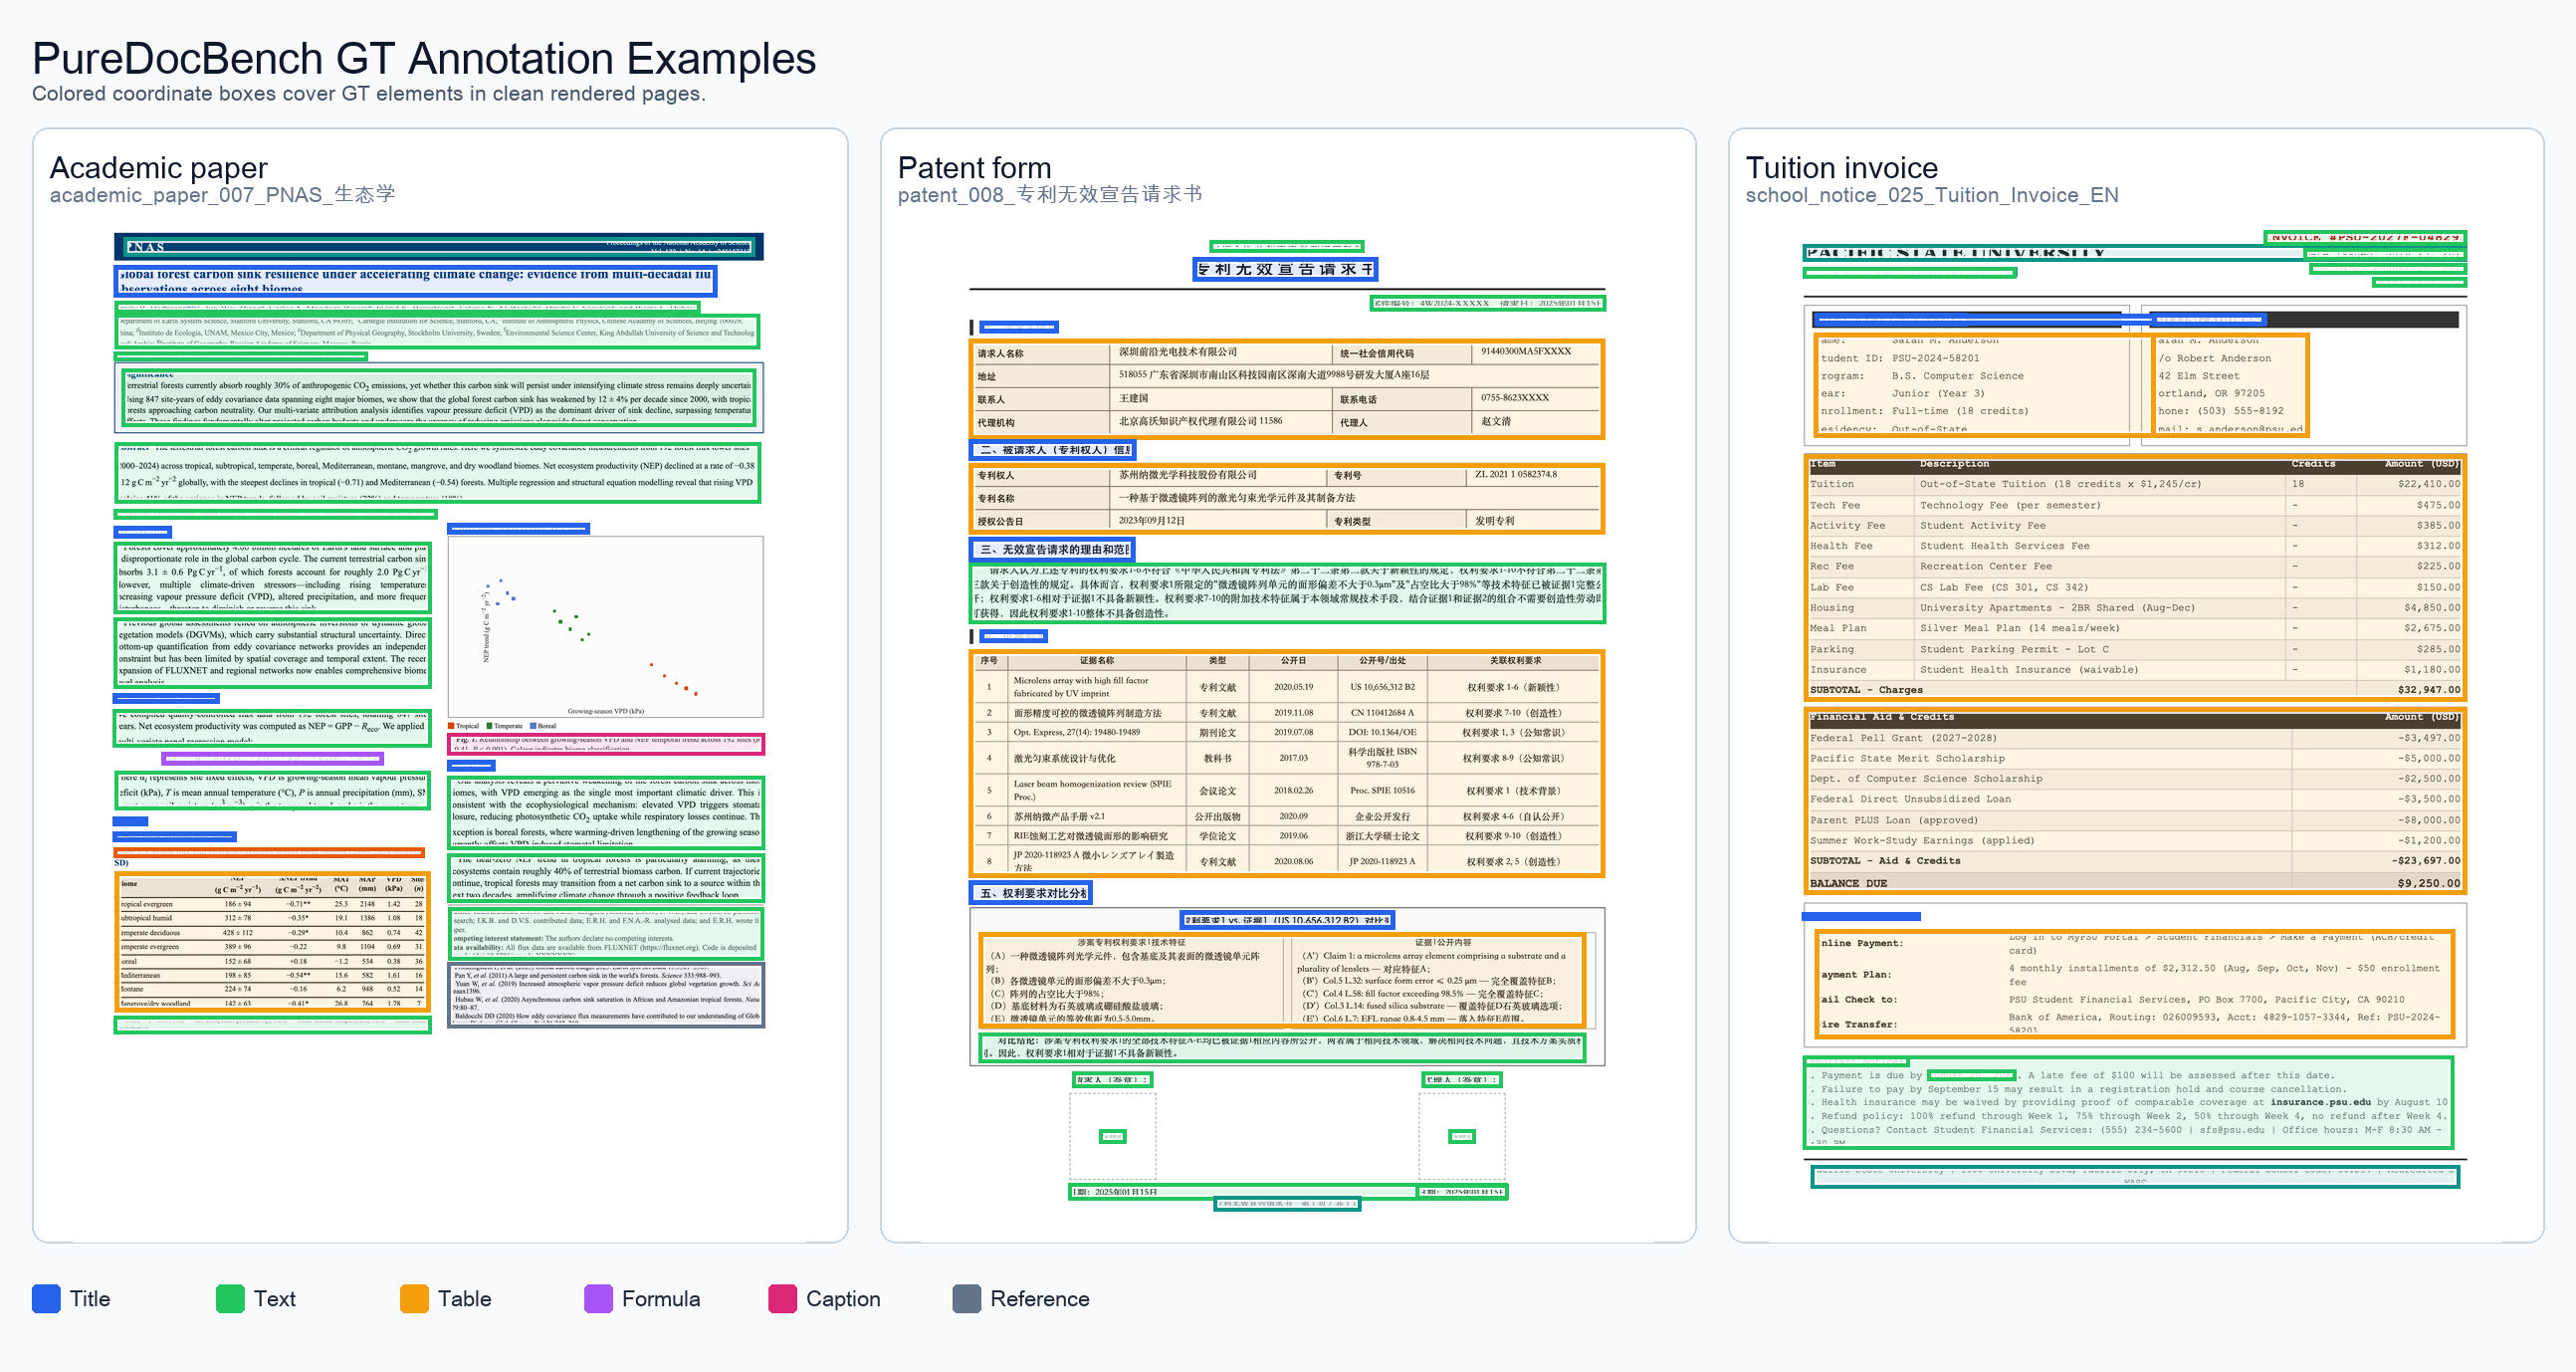
The examples below show colored coordinate boxes over clean rendered pages from an academic paper, a patent form, and a tuition invoice.
At A Glance
| Item | Count |
|---|---|
| Official pages | 1,475 |
| Official images | 4,425 |
| Top-level domains | 10 |
| Fine-grained subcategories | 66 |
| Image tracks | clean, digital-degraded, real-degraded |
| Scored structures | text, formulas, tables, reading order |
Main Leaderboard
The paper evaluates 40 systems across pipeline specialists, end-to-end document parsers, and general-purpose VLMs. The live leaderboard additionally tracks public post-publication results. Each track reports Overall, TextEdit, FormulaCDM, TableTEDS, and ROEdit; Avg3 averages the three track Overall scores.
Open the interactive sortable leaderboard ↗
| Model | Params | Clean | Digital Degraded | Real Degraded | Avg3↑ | ||||||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Overall↑ | TextEdit↓ | FormulaCDM↑ | TableTEDS↑ | ROEdit↓ | Overall↑ | TextEdit↓ | FormulaCDM↑ | TableTEDS↑ | ROEdit↓ | Overall↑ | TextEdit↓ | FormulaCDM↑ | TableTEDS↑ | ROEdit↓ | |||
| Pipeline / Multi-stage Specialists | |||||||||||||||||
| NaviDC-OCR† | 1.2B | 86.90 | 0.111 | 81.01 | 91.09 | — | 77.47 | 0.206 | 72.59 | 80.45 | — | 70.85 | 0.302 | 65.11 | 77.66 | — | 78.41 |
| DotsMOCR | 3B | 76.27 | 0.151 | 66.23 | 77.65 | 0.273 | 73.16 | 0.198 | 64.32 | 74.95 | 0.309 | 61.73 | 0.312 | 54.39 | 61.97 | 0.393 | 70.39 |
| Dolphin-v2 | 3B | 65.90 | 0.342 | 59.80 | 72.12 | 0.429 | 60.24 | 0.393 | 52.20 | 67.86 | 0.461 | 44.92 | 0.553 | 39.98 | 50.04 | 0.558 | 57.02 |
| MonkeyOCR-pro-3B | 3B | 62.23 | 0.346 | 48.46 | 72.83 | 0.492 | 57.40 | 0.397 | 45.57 | 66.32 | 0.526 | 46.49 | 0.511 | 38.18 | 52.43 | 0.600 | 55.37 |
| YouTu-Parsing | 2B | 75.02 | 0.230 | 67.34 | 80.74 | 0.358 | 69.66 | 0.270 | 61.44 | 74.49 | 0.388 | 60.29 | 0.360 | 52.20 | 64.69 | 0.430 | 68.32 |
| MinerU2.5-Pro | 1.2B | 75.87 | 0.222 | 65.14 | 84.68 | 0.346 | 71.77 | 0.272 | 61.79 | 80.73 | 0.378 | 62.56 | 0.375 | 52.70 | 72.47 | 0.446 | 70.07 |
| MinerU2.5 | 1.2B | 74.90 | 0.184 | 62.08 | 81.04 | 0.327 | 68.92 | 0.245 | 56.99 | 74.24 | 0.374 | 59.15 | 0.370 | 49.01 | 65.41 | 0.446 | 67.66 |
| MonkeyOCR-pro-1.2B | 1.2B | 61.09 | 0.358 | 47.43 | 71.60 | 0.498 | 55.72 | 0.416 | 43.91 | 64.83 | 0.529 | 43.82 | 0.556 | 36.94 | 50.07 | 0.609 | 53.54 |
| PaddleOCR-VL-1.5 | 0.9B | 73.01 | 0.266 | 63.53 | 82.12 | 0.428 | 66.73 | 0.339 | 58.03 | 76.07 | 0.478 | 60.50 | 0.398 | 54.00 | 67.33 | 0.510 | 66.75 |
| GLM-OCR | 0.9B | 68.65 | 0.314 | 57.89 | 79.44 | 0.470 | 63.06 | 0.383 | 53.23 | 74.21 | 0.520 | 58.31 | 0.433 | 50.34 | 67.83 | 0.543 | 63.34 |
| OpenOCR | 0.1B | 32.70 | 0.354 | 33.50 | 0.00 | 0.507 | 30.03 | 0.410 | 31.09 | 0.00 | 0.541 | 25.73 | 0.486 | 25.81 | 0.00 | 0.591 | 29.49 |
| End-to-End Specialists | |||||||||||||||||
| OvisOCR2* | 0.8B | 81.55 | — | — | — | — | 77.09 | — | — | — | — | 66.56 | — | — | — | — | 75.06 |
| olmOCR-2-7B | 7B | 69.36 | 0.284 | 56.89 | 79.59 | 0.358 | 65.87 | 0.318 | 54.57 | 74.81 | 0.378 | 56.10 | 0.417 | 48.79 | 61.25 | 0.439 | 63.78 |
| olmOCR-7B | 7B | 62.56 | 0.388 | 58.69 | 67.77 | 0.466 | 57.84 | 0.436 | 55.44 | 61.66 | 0.499 | 47.30 | 0.542 | 46.26 | 49.80 | 0.568 | 55.90 |
| FD-RL | 4B | 78.38 | 0.193 | 68.21 | 86.22 | 0.334 | 76.33 | 0.214 | 67.16 | 83.22 | 0.350 | 67.04 | 0.298 | 58.82 | 72.08 | 0.391 | 73.92 |
| Logics-Parsing-v2 | 4B | 76.35 | 0.213 | 67.67 | 82.67 | 0.342 | 73.85 | 0.248 | 67.33 | 79.02 | 0.375 | 67.64 | 0.304 | 61.65 | 71.64 | 0.416 | 72.61 |
| OCRVerse | 4B | 73.18 | 0.273 | 63.78 | 83.09 | 0.393 | 71.36 | 0.302 | 63.95 | 80.36 | 0.415 | 63.66 | 0.363 | 57.03 | 70.30 | 0.452 | 69.40 |
| Qianfan-OCR | 4B | 57.22 | 0.370 | 49.79 | 58.83 | 0.443 | 50.85 | 0.438 | 44.41 | 51.96 | 0.485 | 45.06 | 0.494 | 39.08 | 45.53 | 0.509 | 51.04 |
| Nanonets-OCR2 | 3B | 64.83 | 0.254 | 44.98 | 74.94 | 0.377 | 61.23 | 0.307 | 45.40 | 68.97 | 0.408 | 49.03 | 0.435 | 35.50 | 55.09 | 0.468 | 58.36 |
| DeepSeek-OCR-2 | 3B | 55.53 | 0.354 | 46.00 | 56.01 | 0.466 | 49.41 | 0.412 | 40.78 | 48.67 | 0.493 | 43.60 | 0.486 | 37.30 | 42.06 | 0.533 | 49.51 |
| OCRFlux-3B | 3B | 47.14 | 0.454 | 38.35 | 48.46 | 0.424 | 41.82 | 0.486 | 31.90 | 42.17 | 0.437 | 37.21 | 0.559 | 32.65 | 34.87 | 0.491 | 42.06 |
| DeepSeek-OCR | 3B | 53.50 | 0.419 | 45.39 | 57.06 | 0.514 | 46.95 | 0.478 | 39.99 | 48.64 | 0.548 | 40.48 | 0.537 | 34.04 | 41.12 | 0.575 | 46.98 |
| dots.ocr | 2.9B | 72.01 | 0.248 | 61.37 | 79.51 | 0.379 | 65.95 | 0.307 | 56.67 | 71.86 | 0.417 | 55.68 | 0.403 | 47.70 | 59.63 | 0.467 | 64.55 |
| FireRed-OCR | 2B | 70.81 | 0.287 | 63.86 | 77.23 | 0.396 | 68.49 | 0.319 | 62.64 | 74.77 | 0.422 | 57.42 | 0.415 | 51.60 | 62.16 | 0.474 | 65.57 |
| HunyuanOCR | 1B | 65.61 | 0.269 | 55.74 | 68.02 | 0.382 | 61.49 | 0.308 | 51.62 | 63.68 | 0.400 | 54.58 | 0.421 | 48.30 | 57.54 | 0.459 | 60.56 |
| UniRec-0.1B | 0.1B | 58.91 | 0.422 | 51.31 | 67.60 | 0.526 | 52.42 | 0.501 | 48.37 | 59.04 | 0.578 | 34.44 | 0.658 | 30.97 | 38.16 | 0.685 | 48.59 |
| OpenDoc-0.1B | 0.1B | 60.28 | 0.411 | 53.09 | 68.86 | 0.519 | 52.46 | 0.501 | 48.41 | 59.04 | 0.577 | 44.27 | 0.547 | 38.46 | 49.06 | 0.603 | 52.00 |
| General VLMs: Qwen3.5 | |||||||||||||||||
| Qwen3.5-397B-A17B | 397B/17B | 69.12 | 0.233 | 65.26 | 65.40 | 0.366 | 68.34 | 0.244 | 63.91 | 65.53 | 0.376 | 62.70 | 0.287 | 60.70 | 56.12 | 0.399 | 66.72 |
| Qwen3.5-122B-A10B | 122B/10B | 76.14 | 0.226 | 67.96 | 83.03 | 0.375 | 76.34 | 0.220 | 67.82 | 83.21 | 0.366 | 69.85 | 0.281 | 62.19 | 75.44 | 0.401 | 74.11 |
| Qwen3.5-35B-A3B | 35B/3B | 68.40 | 0.232 | 64.94 | 63.45 | 0.374 | 68.04 | 0.245 | 64.78 | 63.86 | 0.379 | 60.59 | 0.310 | 59.68 | 53.07 | 0.419 | 65.68 |
| Qwen3.5-27B | 27B | 72.07 | 0.227 | 66.36 | 72.51 | 0.362 | 70.73 | 0.236 | 64.61 | 71.17 | 0.367 | 65.92 | 0.283 | 61.23 | 64.82 | 0.390 | 69.57 |
| Qwen3.5-9B | 9B | 73.87 | 0.254 | 67.60 | 79.39 | 0.388 | 73.34 | 0.260 | 67.00 | 79.01 | 0.396 | 65.45 | 0.332 | 60.91 | 68.59 | 0.437 | 70.89 |
| Qwen3.5-4B | 4B | 73.45 | 0.276 | 69.96 | 78.02 | 0.410 | 72.53 | 0.281 | 68.88 | 76.78 | 0.412 | 63.47 | 0.380 | 61.27 | 67.17 | 0.477 | 69.82 |
| Qwen3.5-2B | 2B | 66.24 | 0.348 | 62.84 | 70.70 | 0.473 | 65.22 | 0.350 | 58.30 | 72.36 | 0.477 | 55.92 | 0.440 | 50.99 | 60.79 | 0.521 | 62.46 |
| Qwen3.5-0.8B | 0.8B | 60.77 | 0.376 | 54.39 | 65.54 | 0.500 | 59.28 | 0.386 | 54.22 | 62.22 | 0.510 | 47.93 | 0.498 | 44.60 | 48.98 | 0.557 | 55.99 |
| General VLMs: Qwen3-VL | |||||||||||||||||
| Qwen3-VL-8B | 8B | 72.44 | 0.261 | 65.10 | 78.35 | 0.411 | 72.03 | 0.266 | 64.88 | 77.82 | 0.409 | 62.73 | 0.342 | 55.55 | 66.81 | 0.448 | 69.07 |
| Qwen3-VL-4B | 4B | 72.04 | 0.262 | 65.10 | 77.17 | 0.418 | 70.84 | 0.272 | 63.54 | 76.13 | 0.425 | 59.61 | 0.378 | 55.15 | 61.47 | 0.480 | 67.50 |
| Qwen3-VL-2B | 2B | 66.37 | 0.300 | 59.04 | 70.03 | 0.439 | 65.81 | 0.314 | 60.25 | 68.52 | 0.448 | 54.09 | 0.428 | 51.05 | 53.99 | 0.511 | 62.09 |
| General VLMs: Other | |||||||||||||||||
| Kimi K2.6 | 1T/32B | 72.32 | 0.303 | 66.93 | 80.30 | 0.466 | 69.95 | 0.322 | 64.69 | 77.31 | 0.475 | 68.02 | 0.335 | 62.44 | 75.14 | 0.481 | 70.10 |
| Step3-VL | 10B | 53.65 | 0.496 | 53.41 | 57.16 | 0.509 | 52.74 | 0.516 | 53.62 | 56.15 | 0.529 | 45.06 | 0.579 | 45.42 | 47.66 | 0.573 | 50.48 |
| MiniCPM-V-4.5 | 8B | 51.81 | 0.439 | 45.97 | 53.36 | 0.481 | 49.38 | 0.461 | 42.79 | 51.50 | 0.489 | 37.59 | 0.583 | 32.01 | 39.06 | 0.552 | 46.26 |
| Gemini-3.1-Pro | --- | 70.04 | 0.306 | 65.63 | 75.08 | 0.409 | 69.28 | 0.322 | 65.81 | 74.24 | 0.417 | 71.98 | 0.300 | 68.62 | 77.26 | 0.386 | 70.43 |
* OvisOCR2 scores are author-reported post-publication results from its official model card. Only per-track Overall and Avg3 were published; unreported component metrics are shown as —.
† NaviDC-OCR scores are author-reported post-publication results from its official repository. The source reports TextEdit, FormulaCDM, and TableTEDS for each track, but not ROEdit; unreported ROEdit metrics are shown as —.
Bold marks the best reported score in each column; underlined marks the runner-up. GitHub README tables cannot run sorting scripts, so use the interactive leaderboard to sort any metric in either direction.
Diagnostics
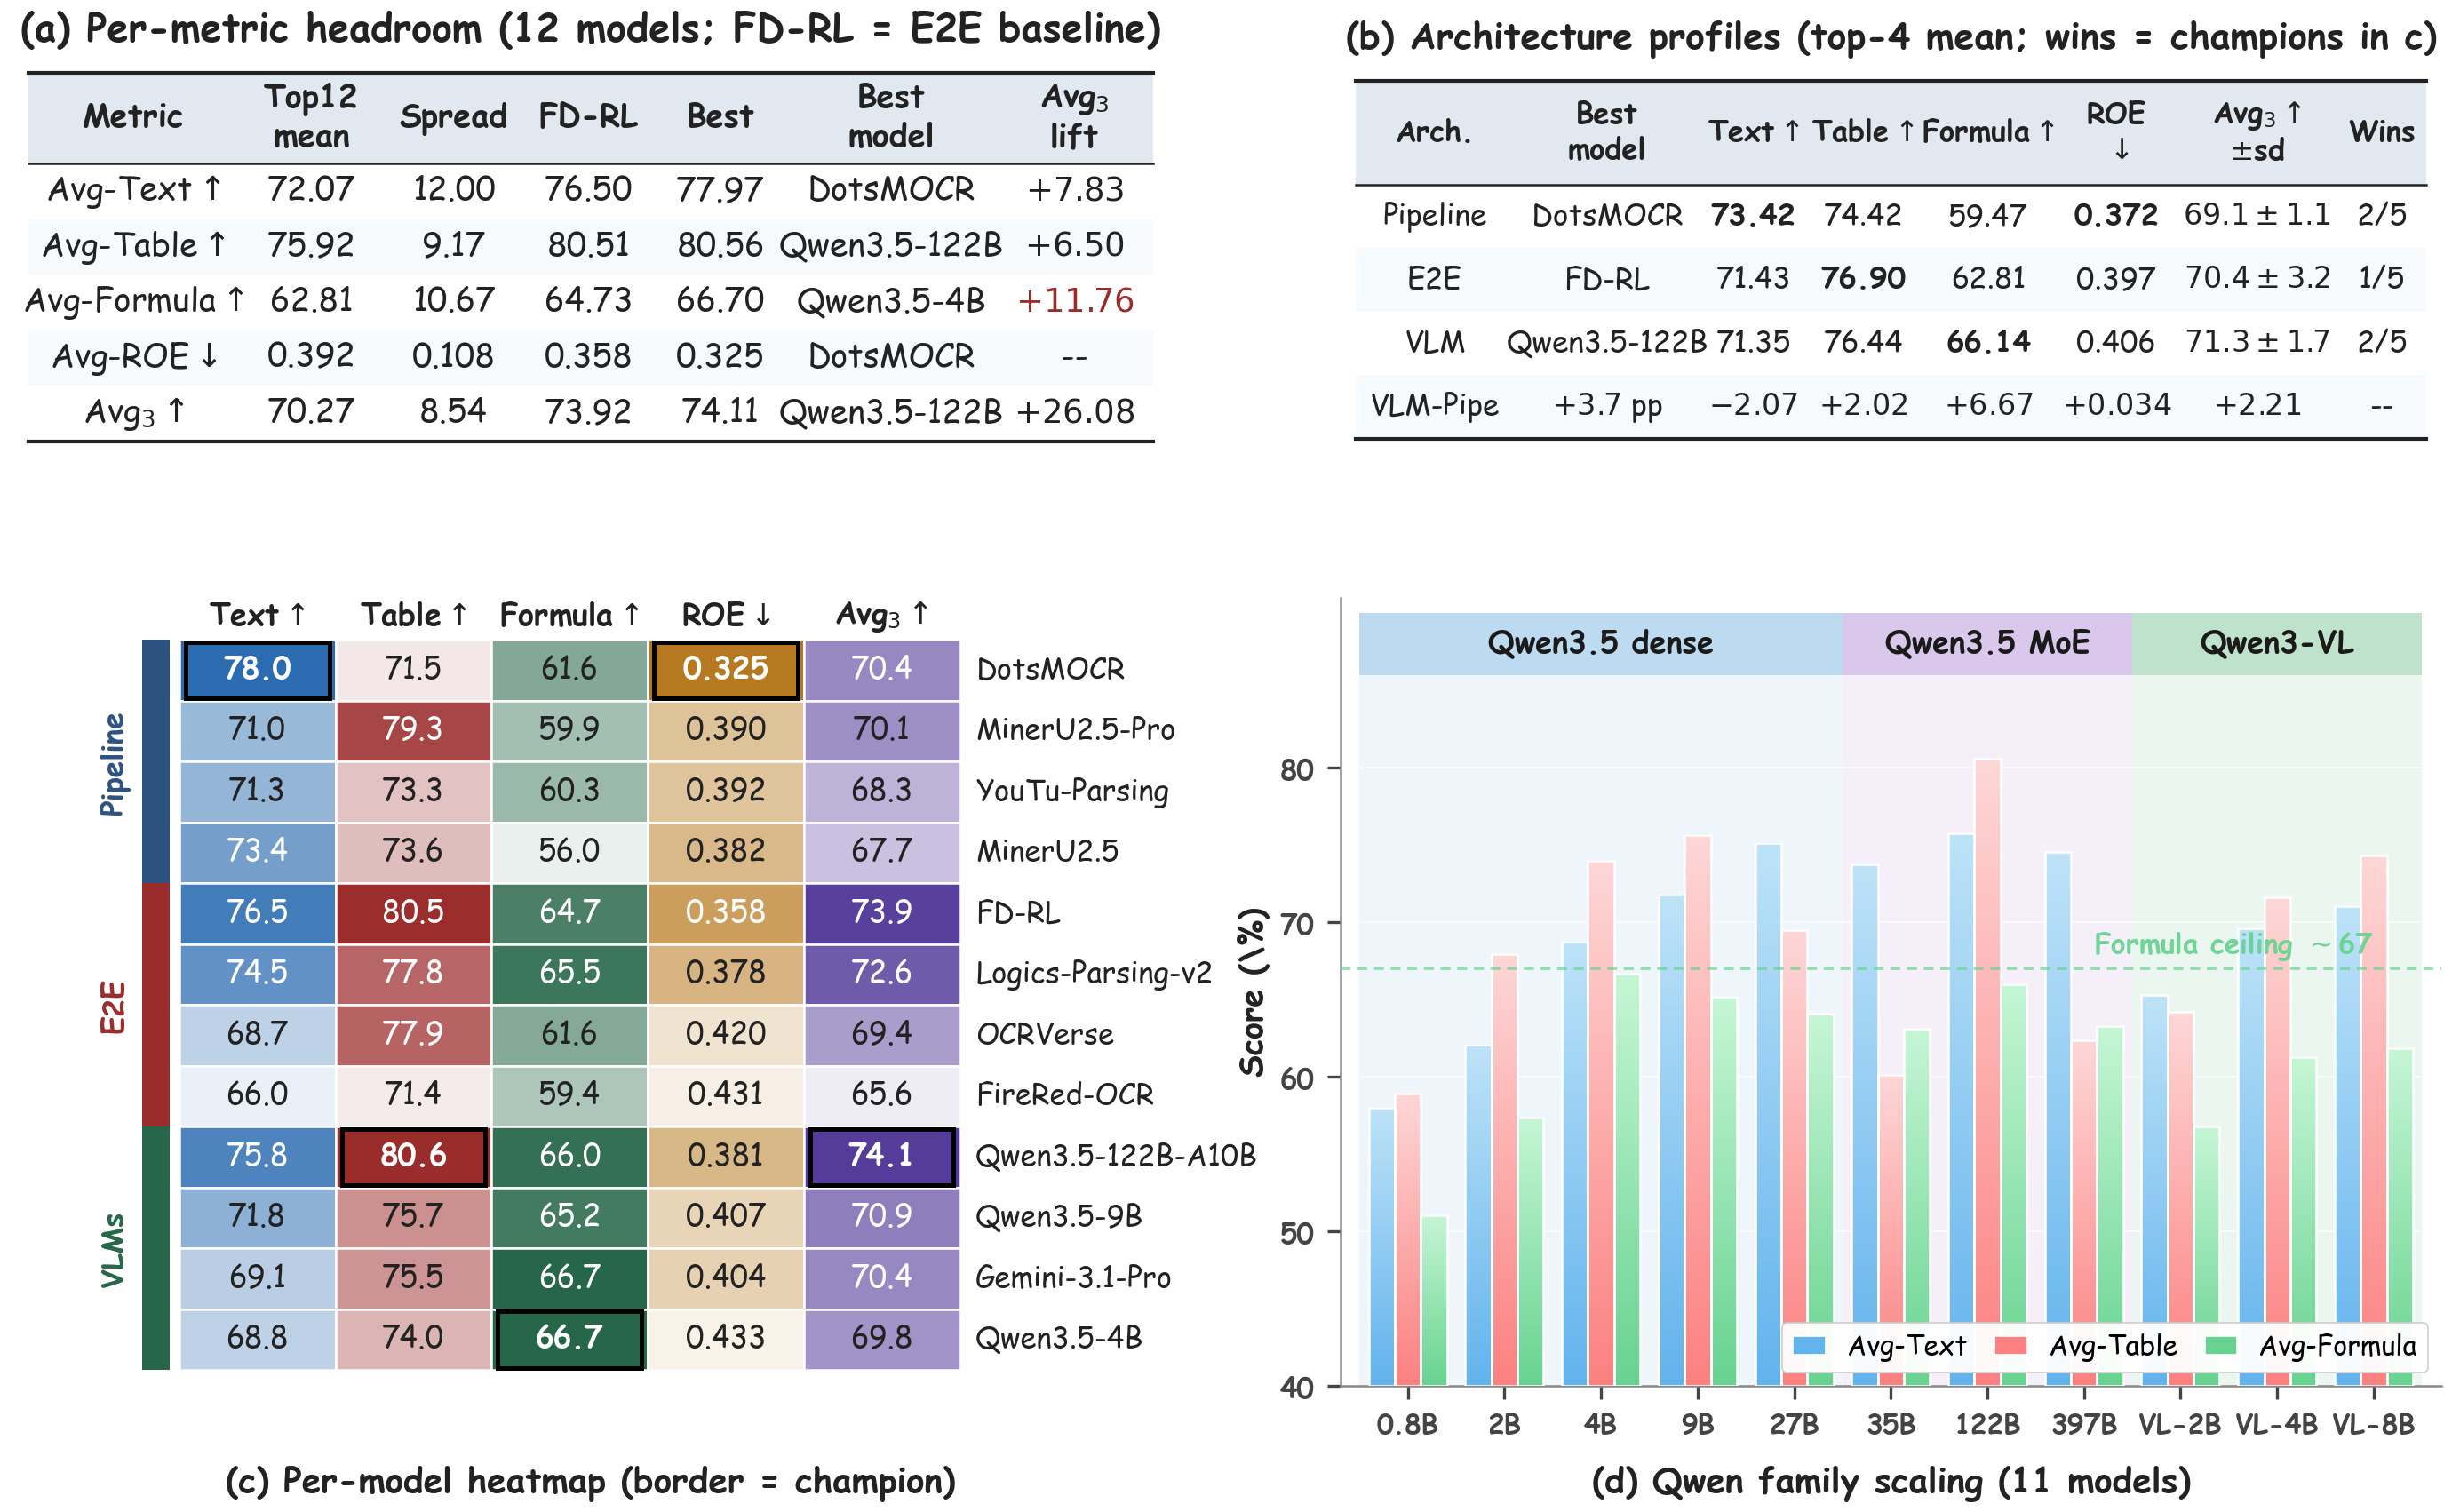
The diagnostic panel shows where current systems still have headroom. Formula recognition is the largest single bottleneck, and real degradation changes rankings more sharply than digital degradation.
Case Studies
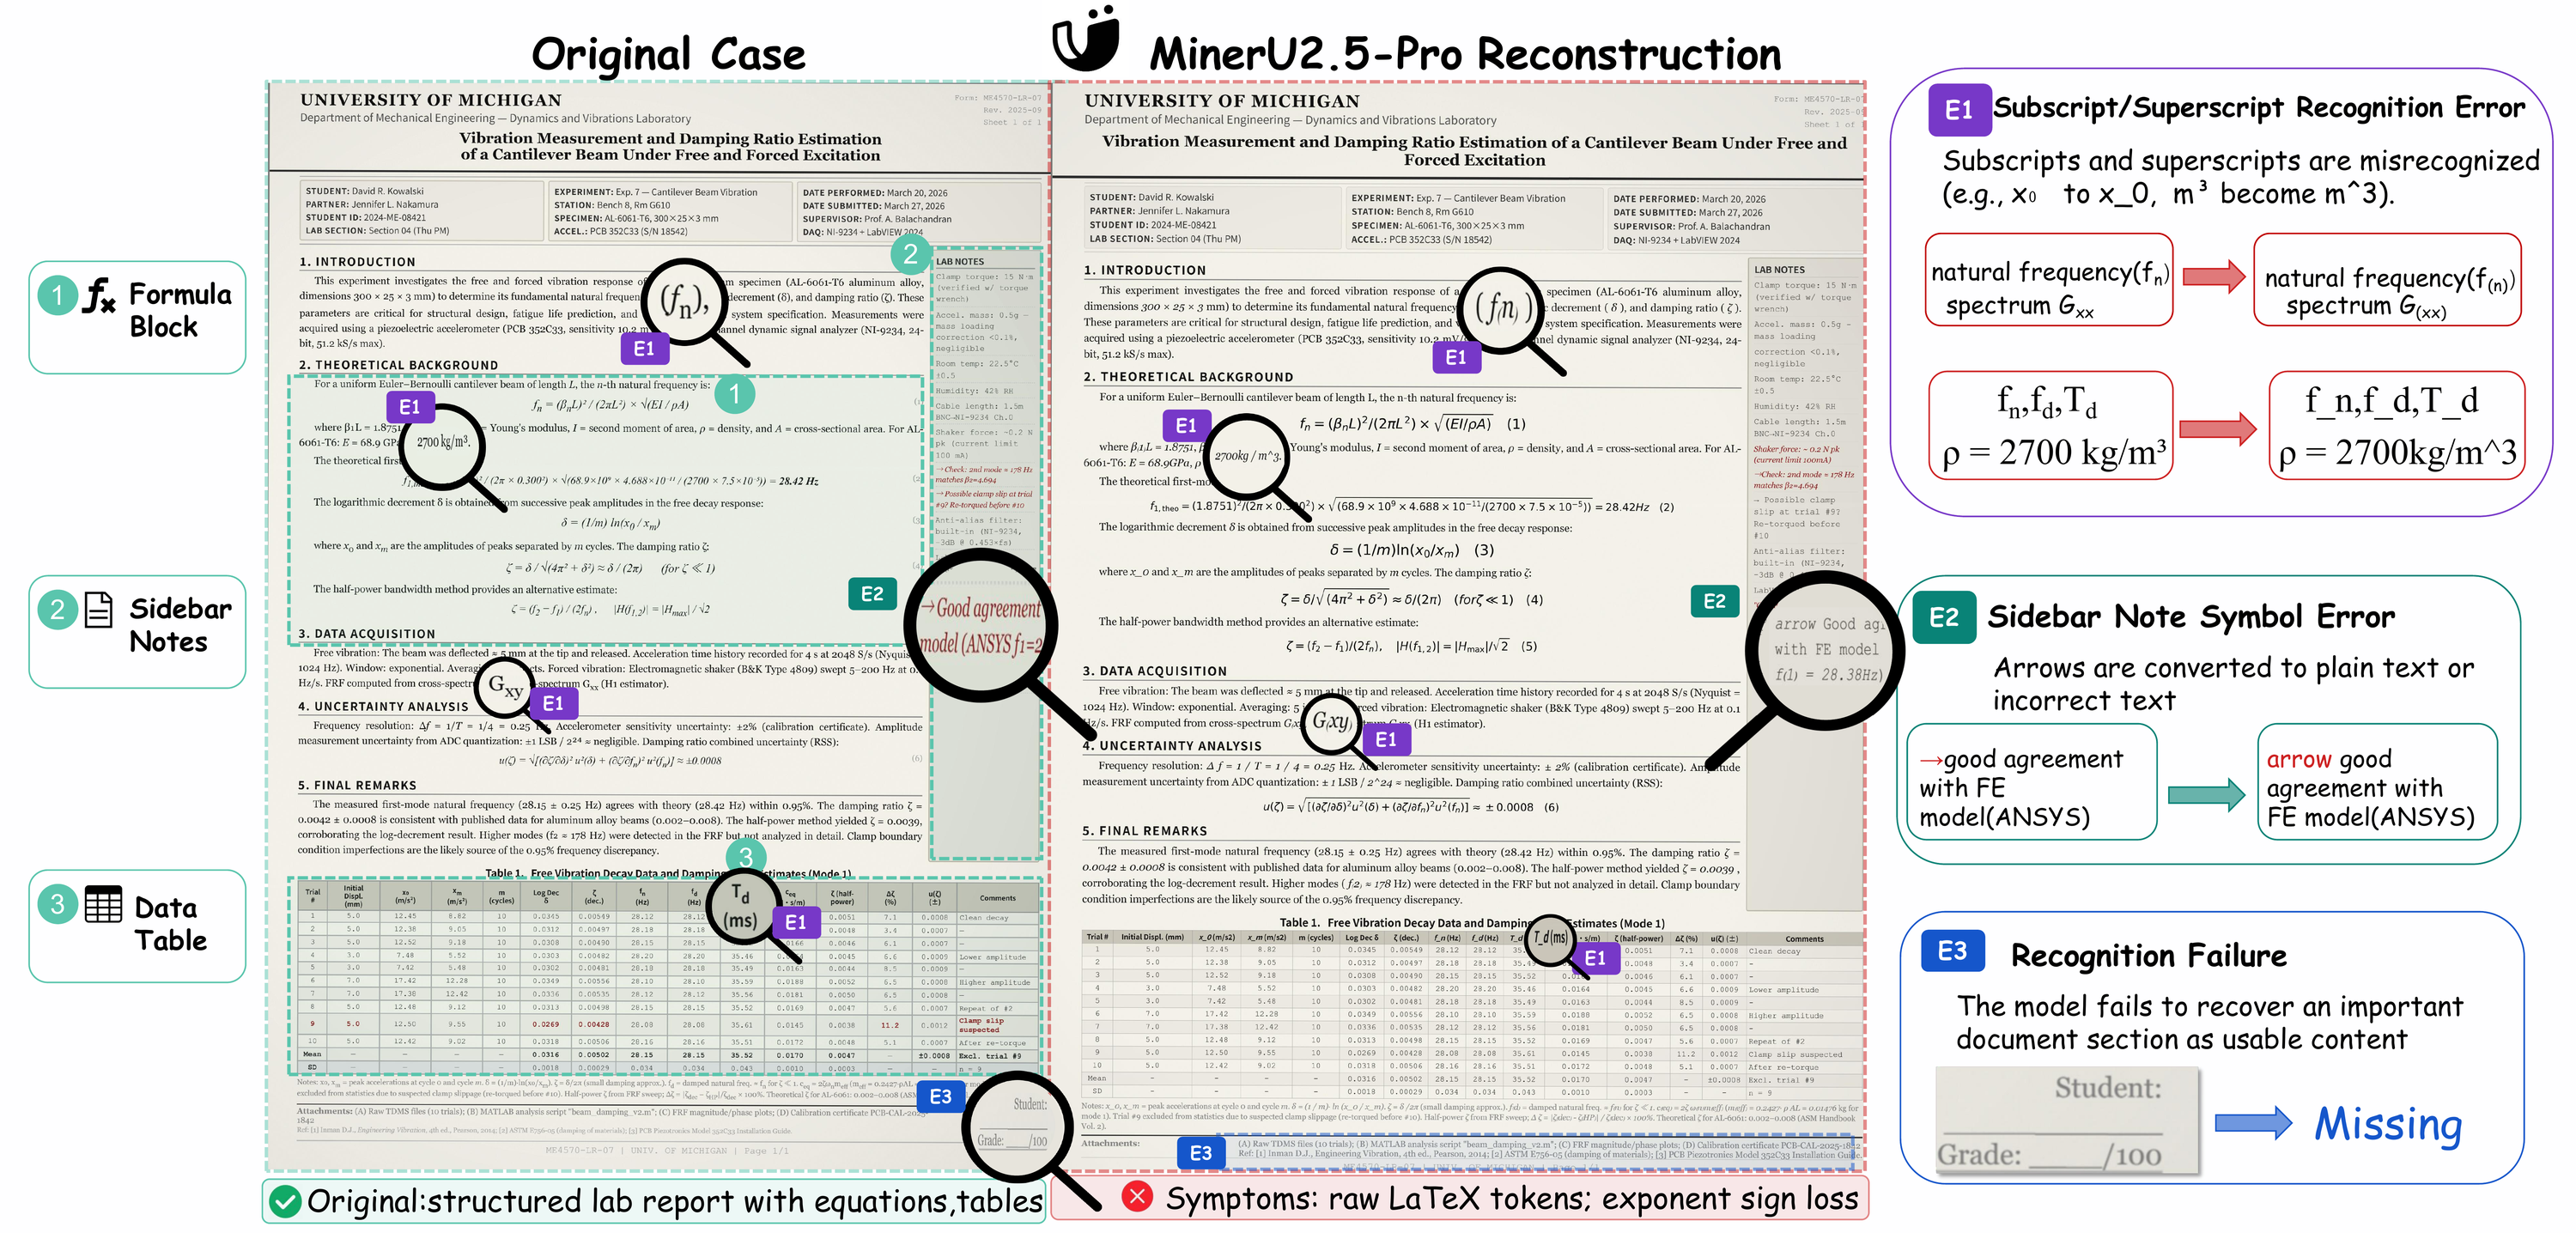
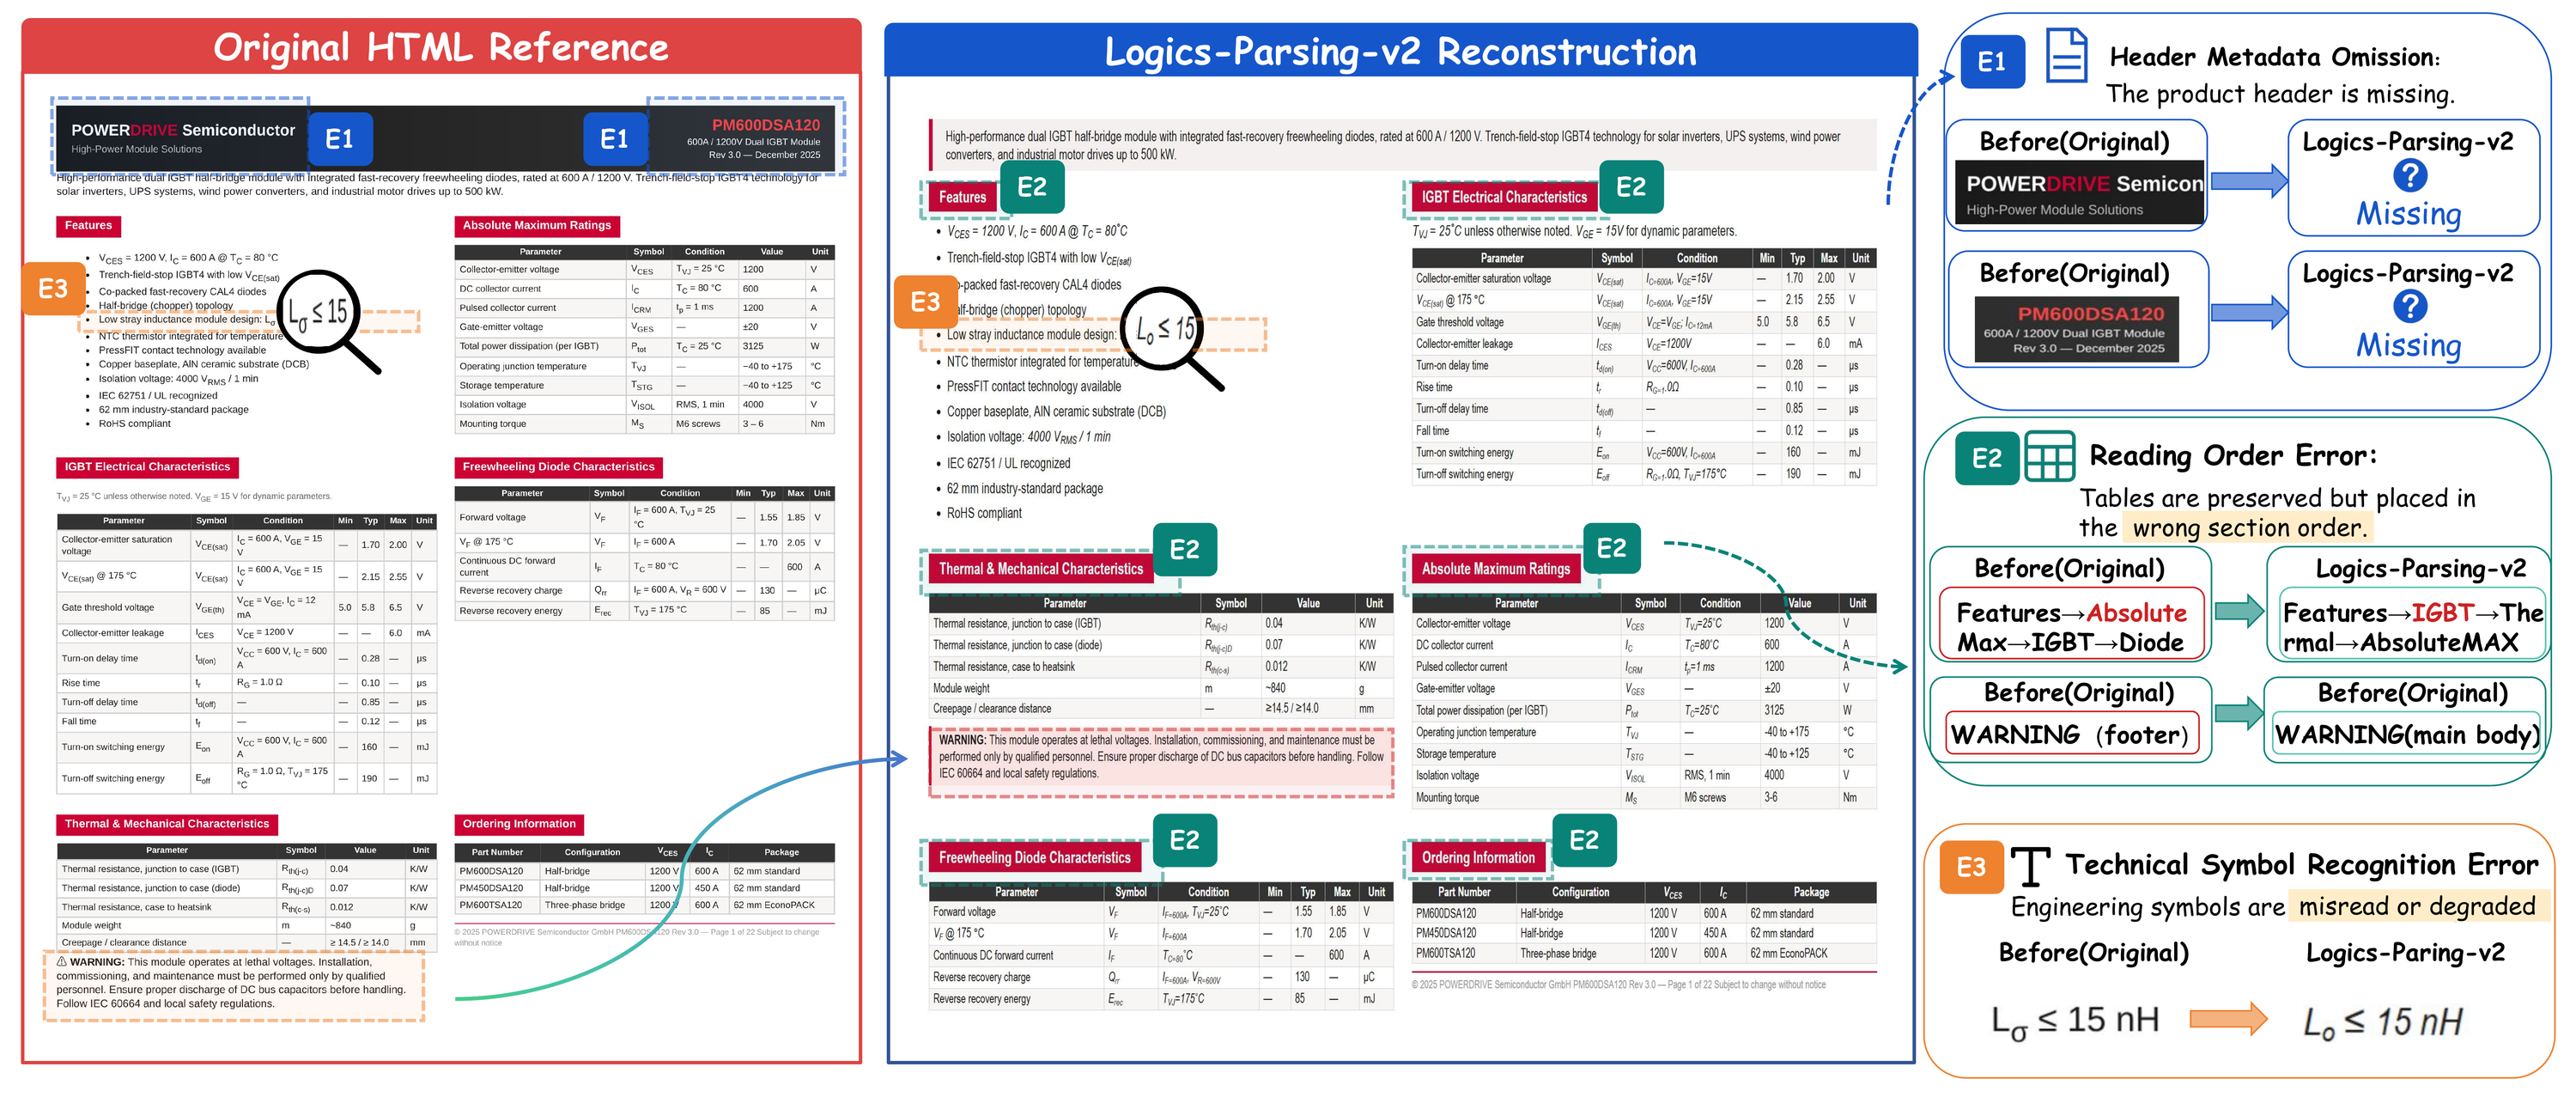
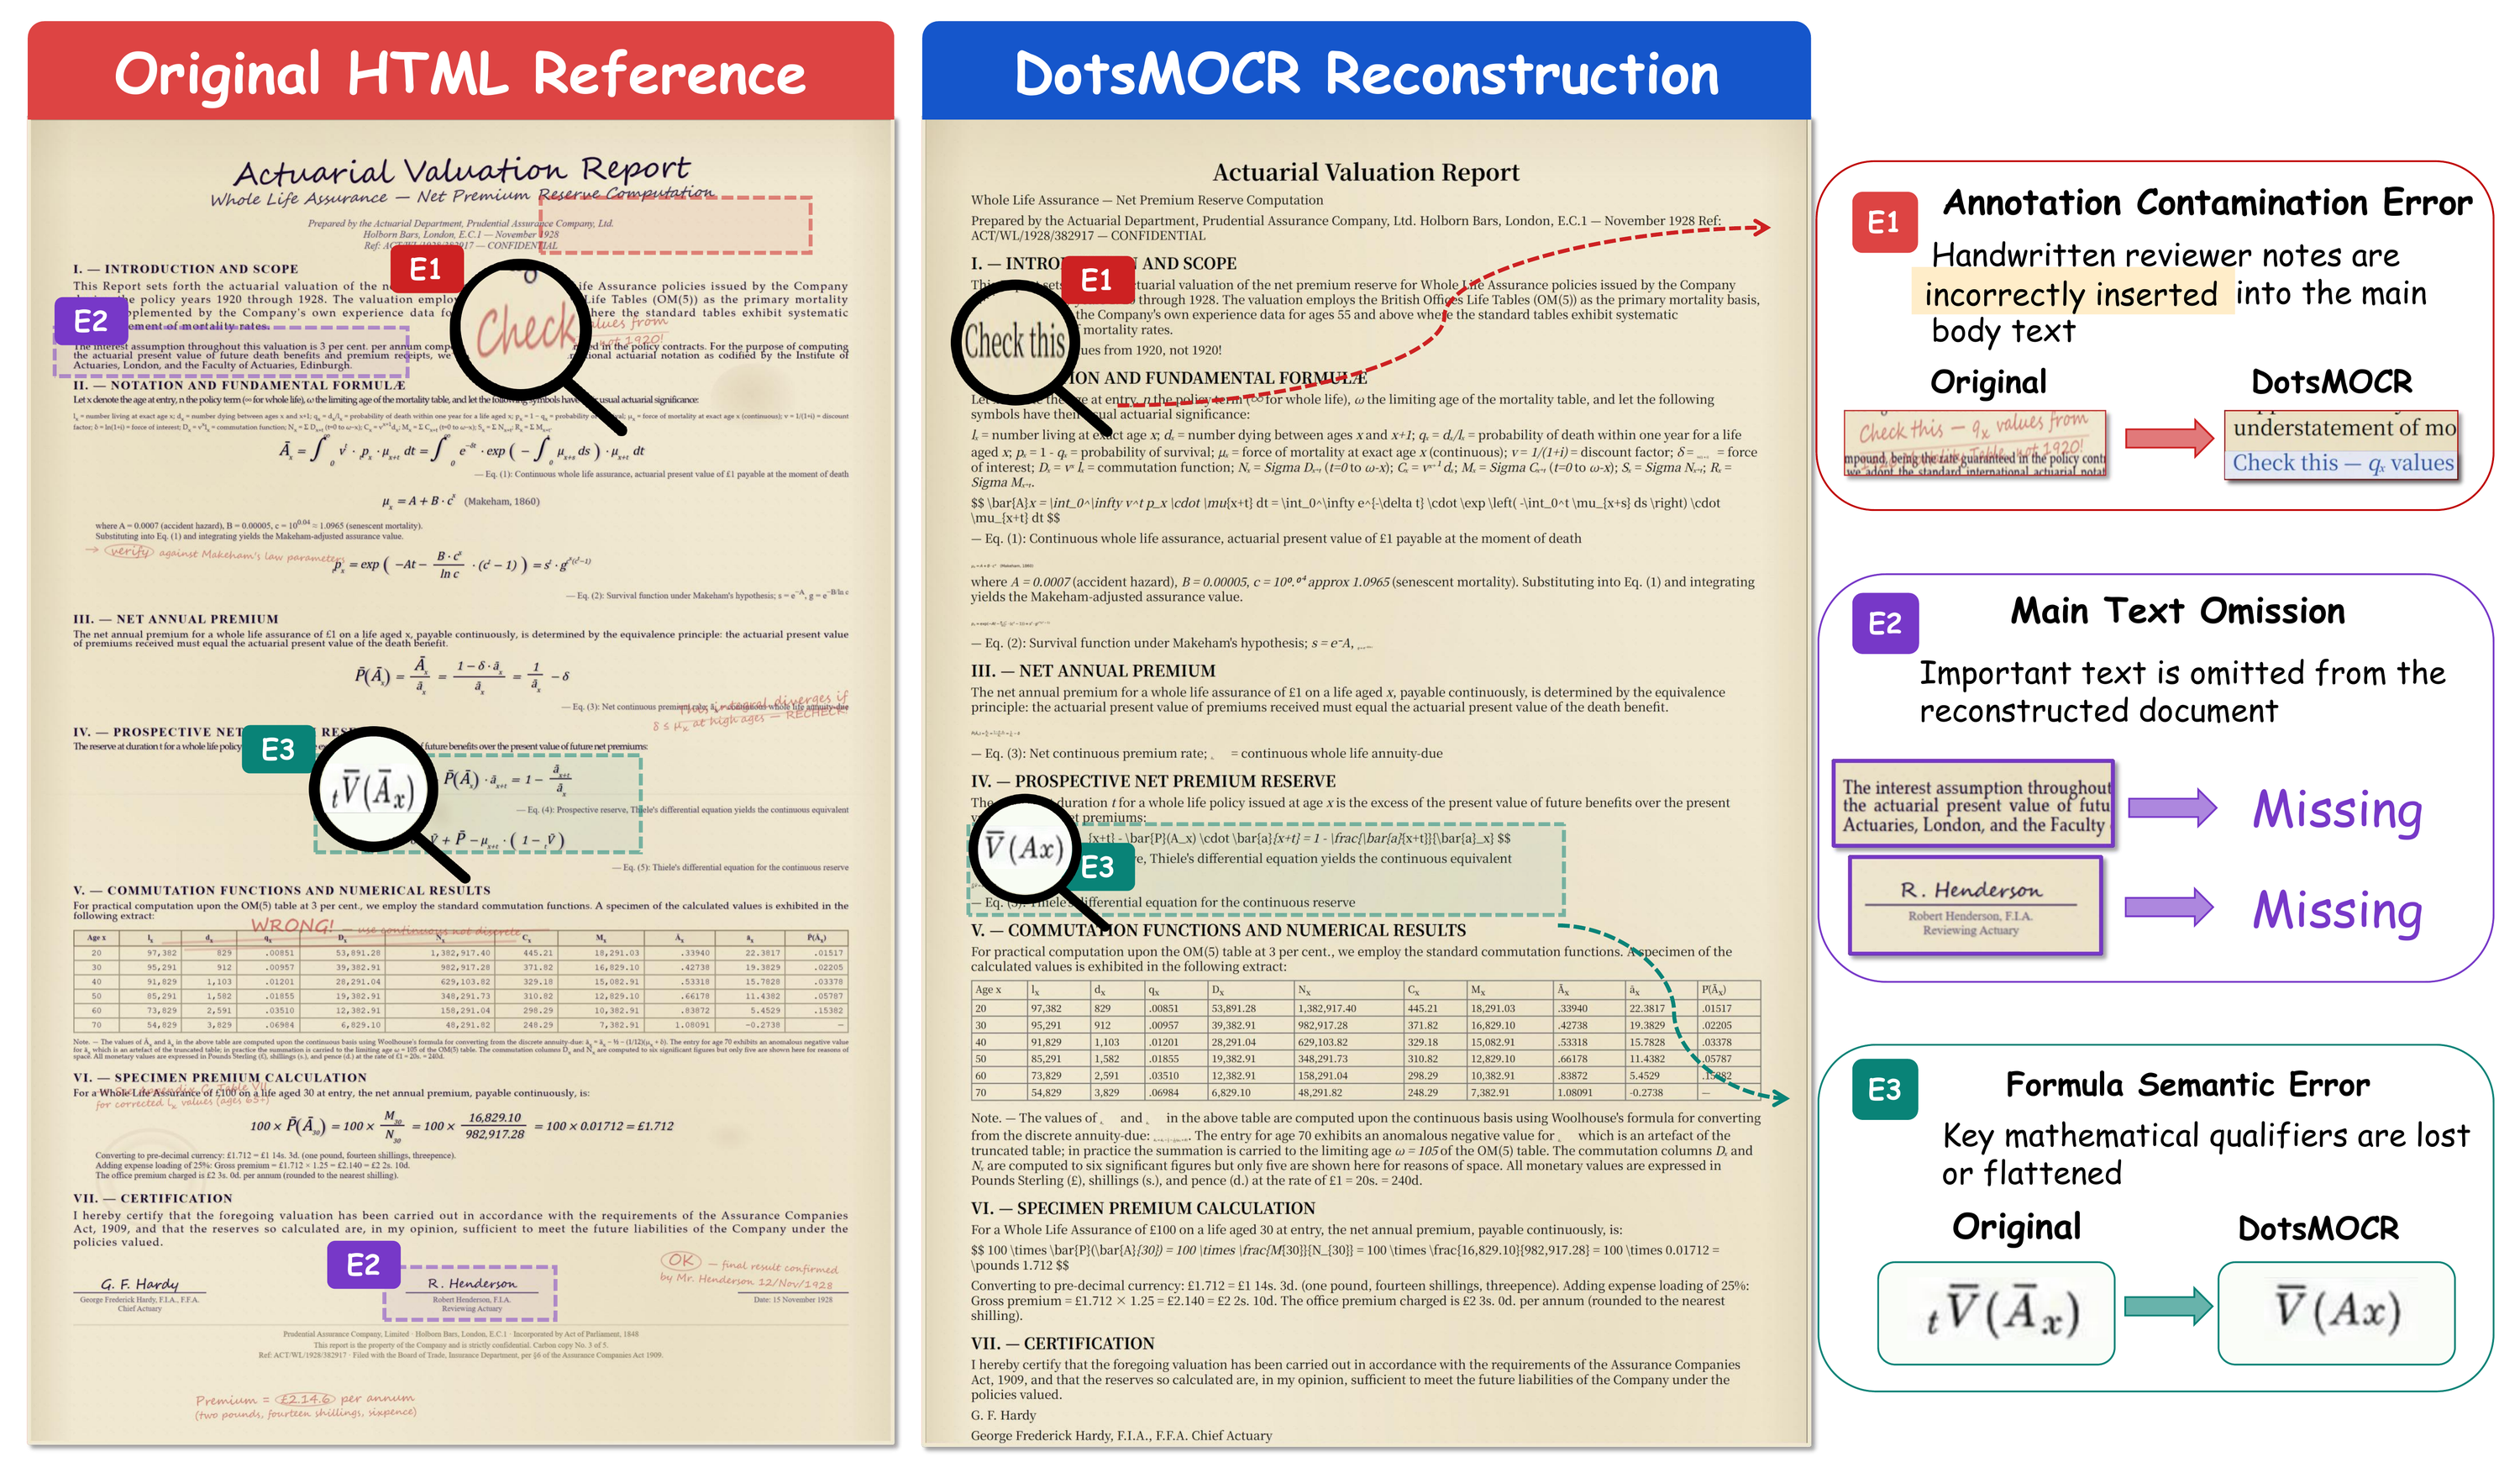
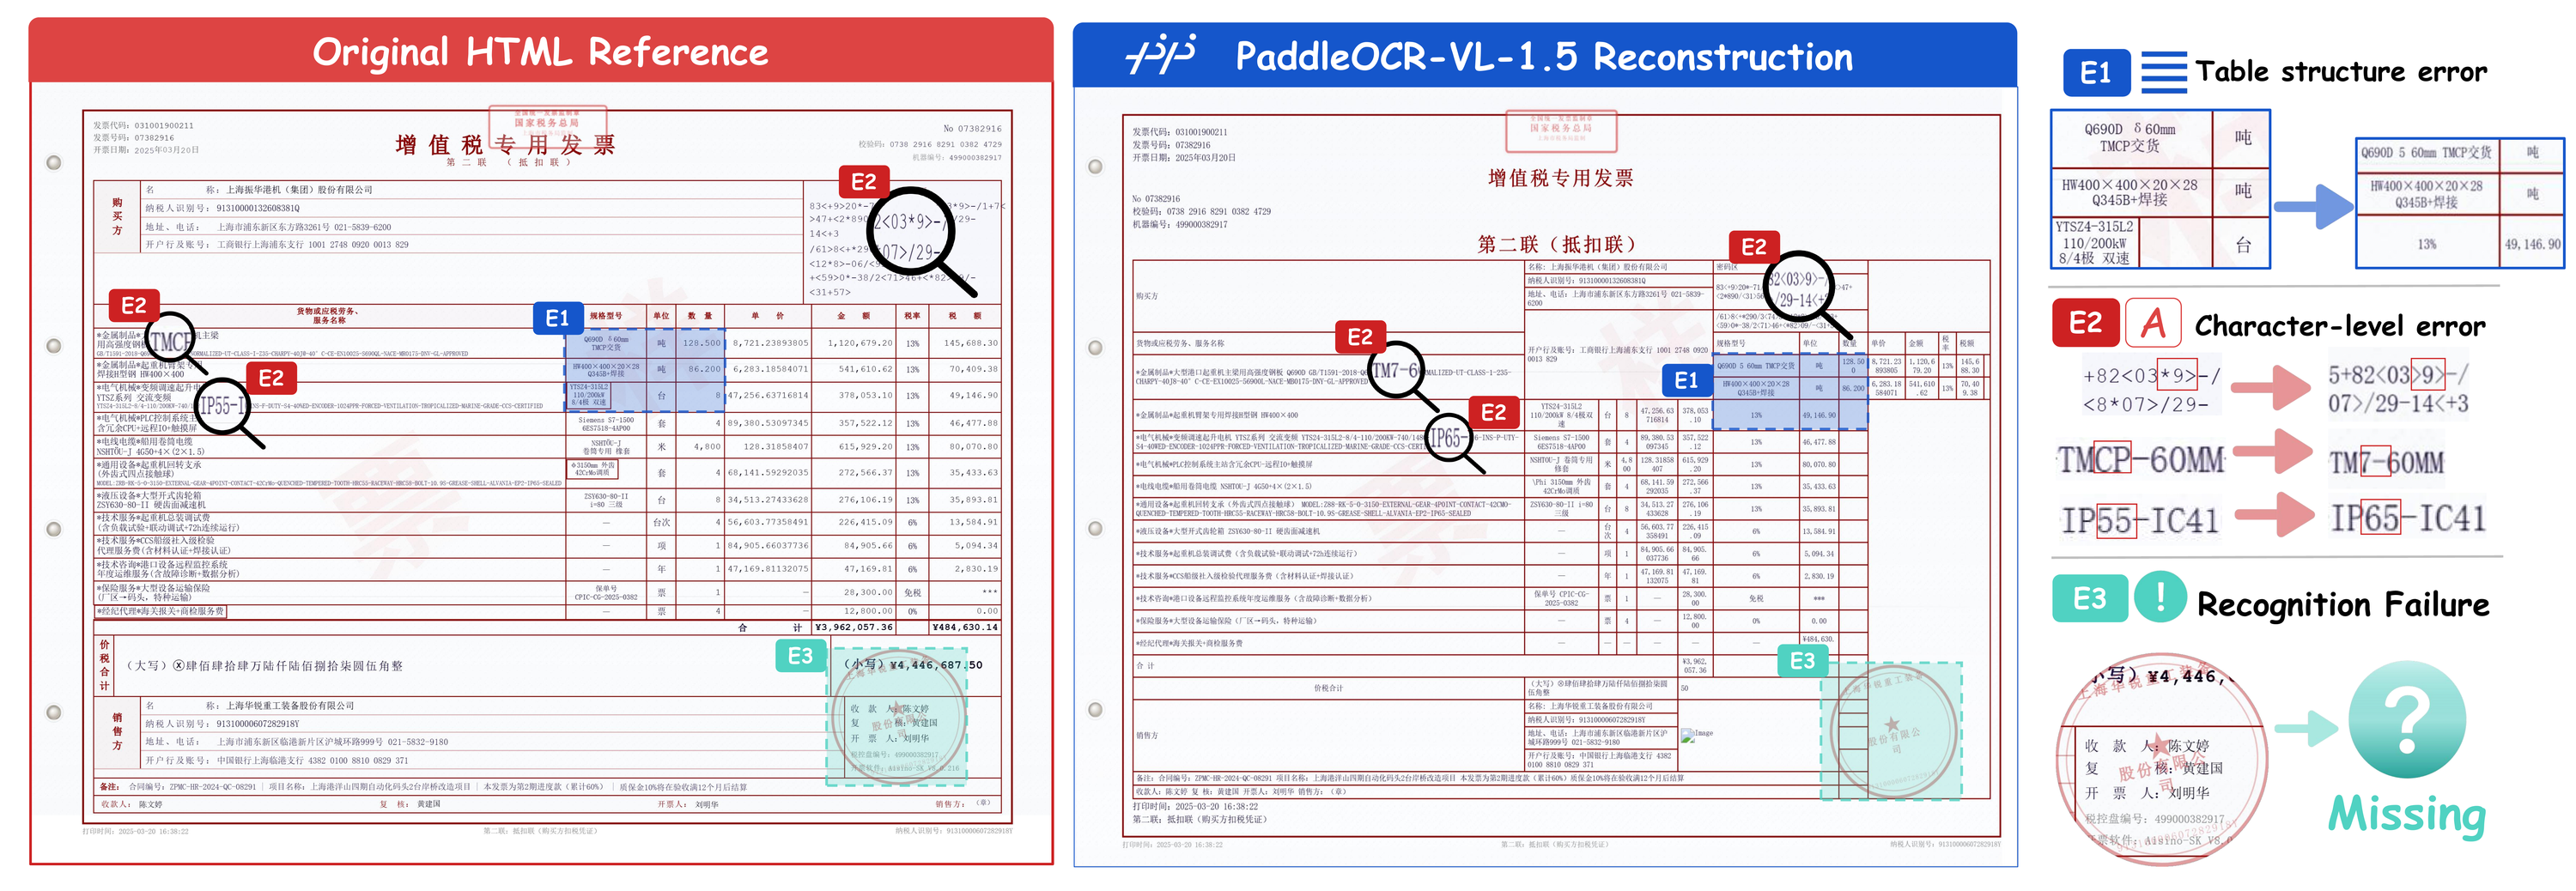
The four case studies below are all taken from the paper. They show failures that aggregate scores can hide: notation loss, reading-order mistakes, annotation contamination, table-structure errors, character-level corruption, and missing visual authentication cues.
Case 1: Academic
Case 2: Business
Case 3: Finance
Case 4: Certificate
Appendix Highlights
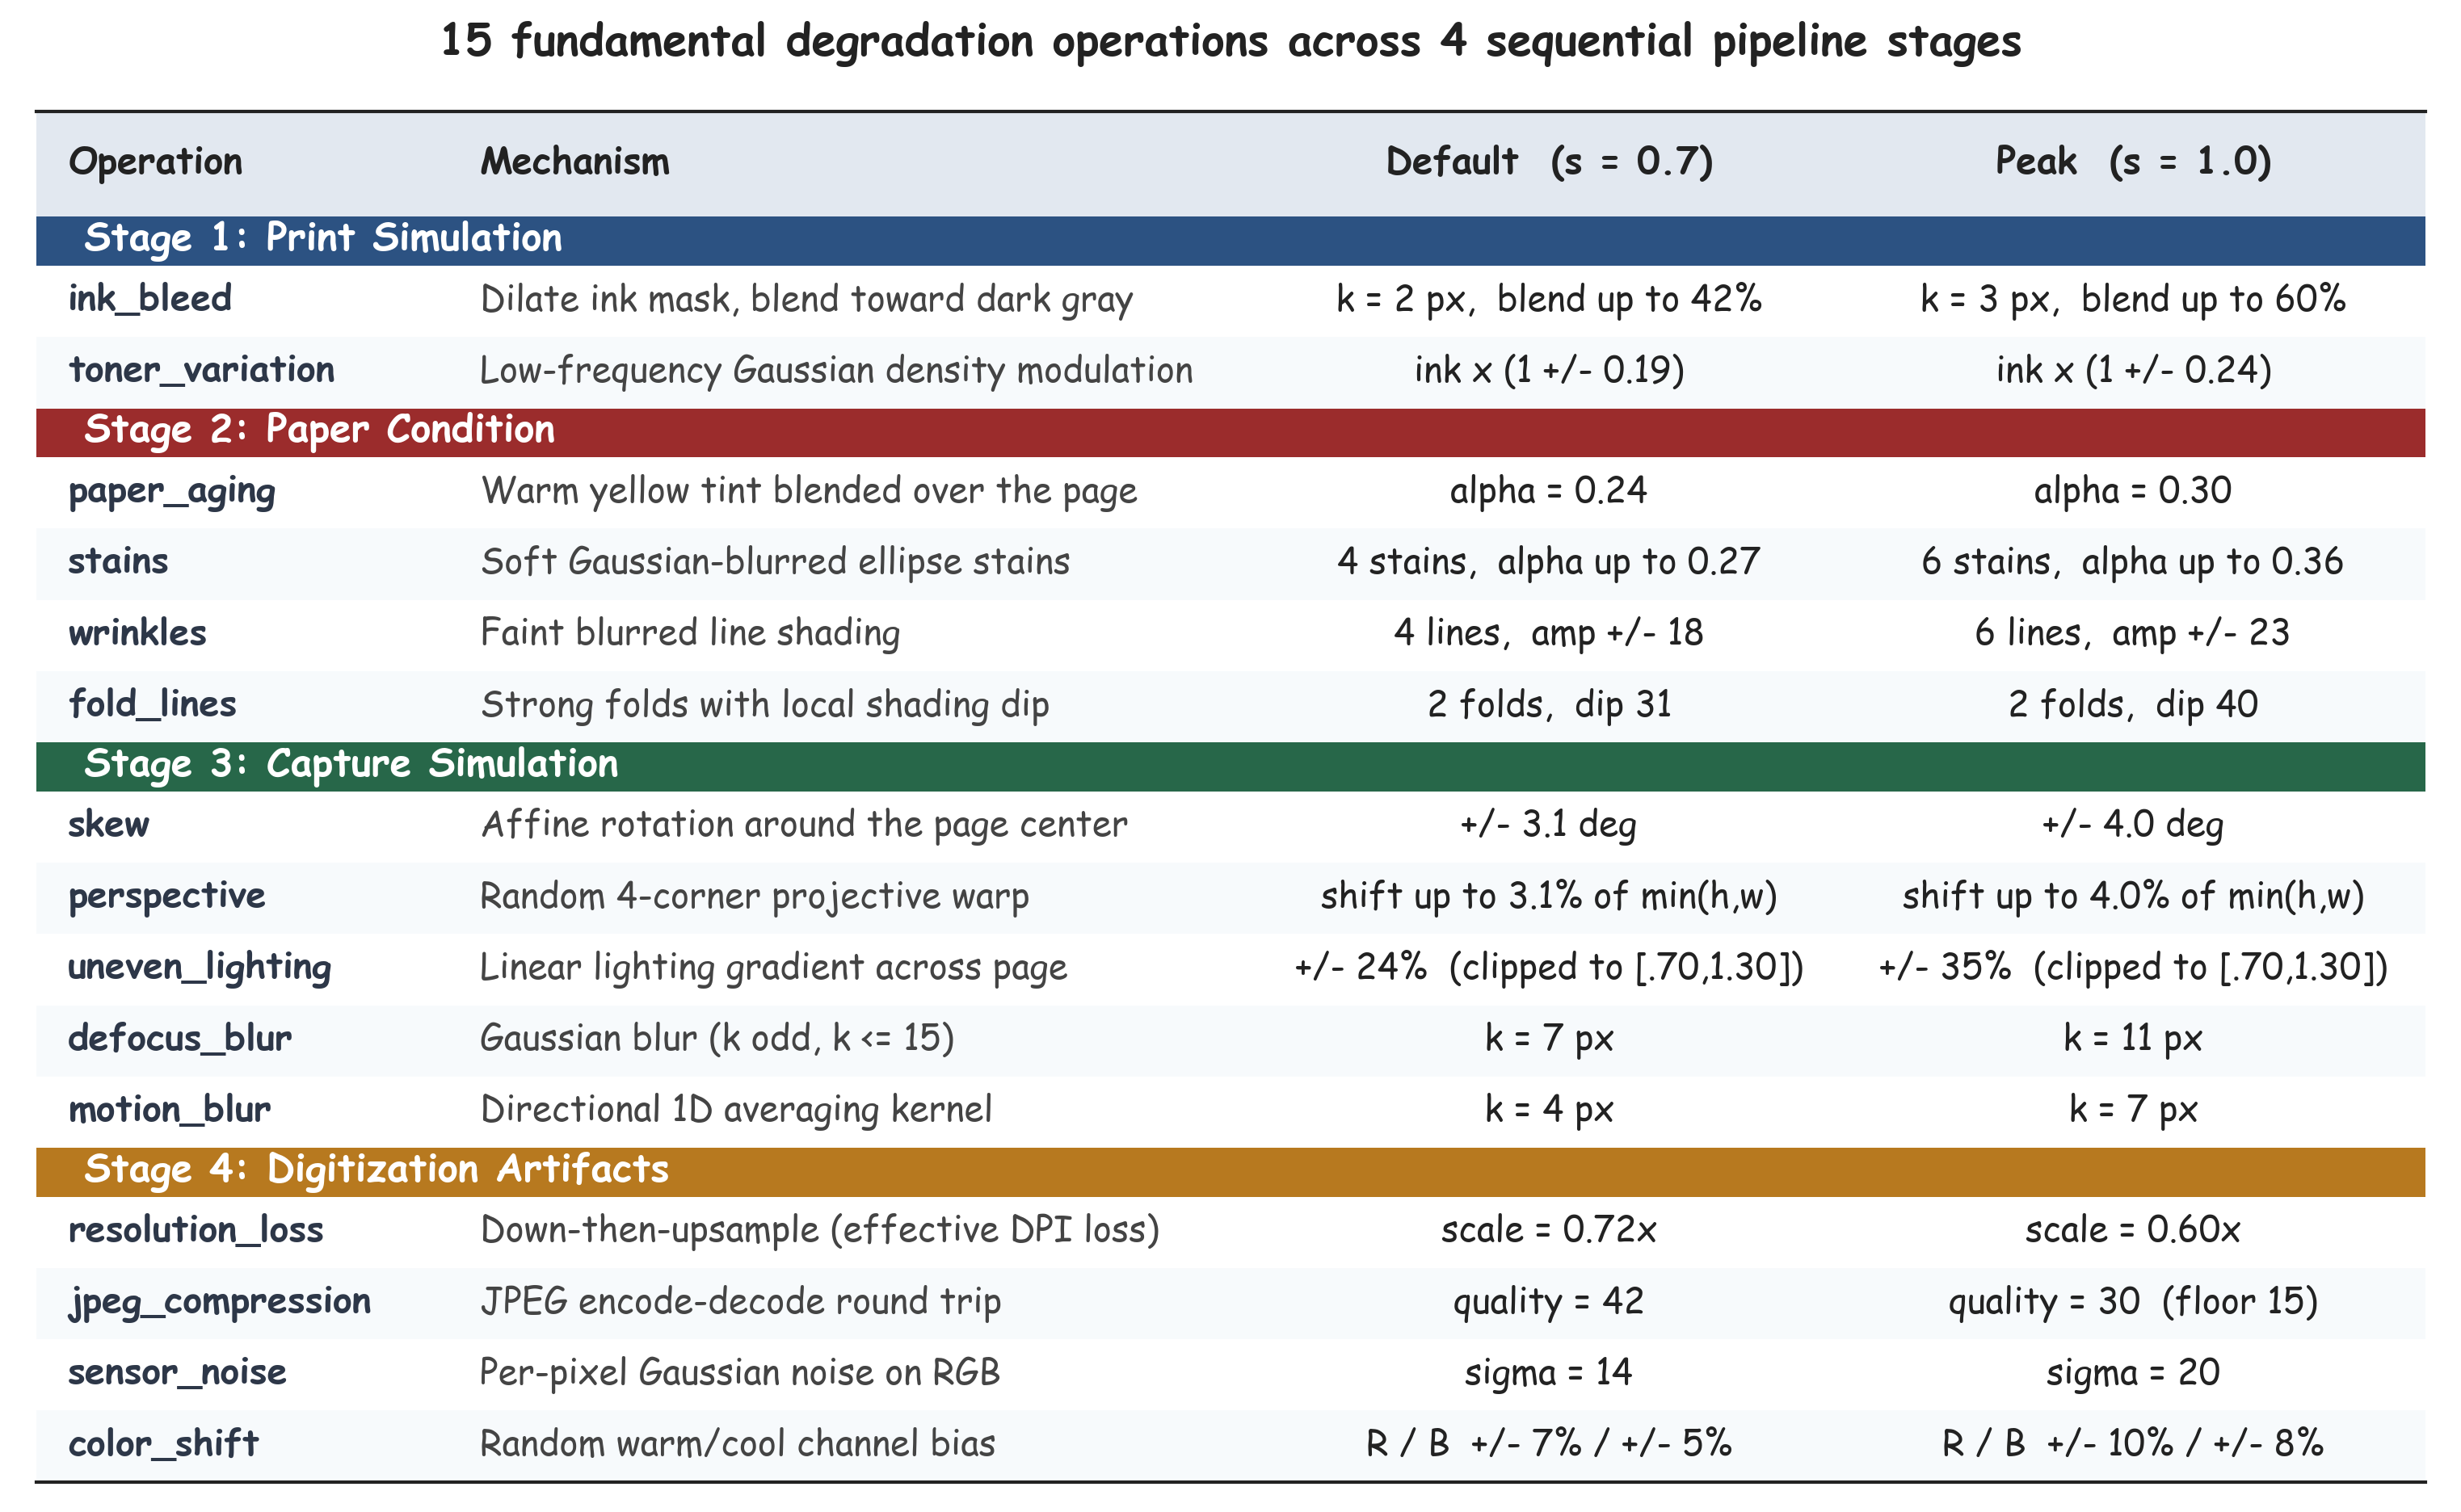
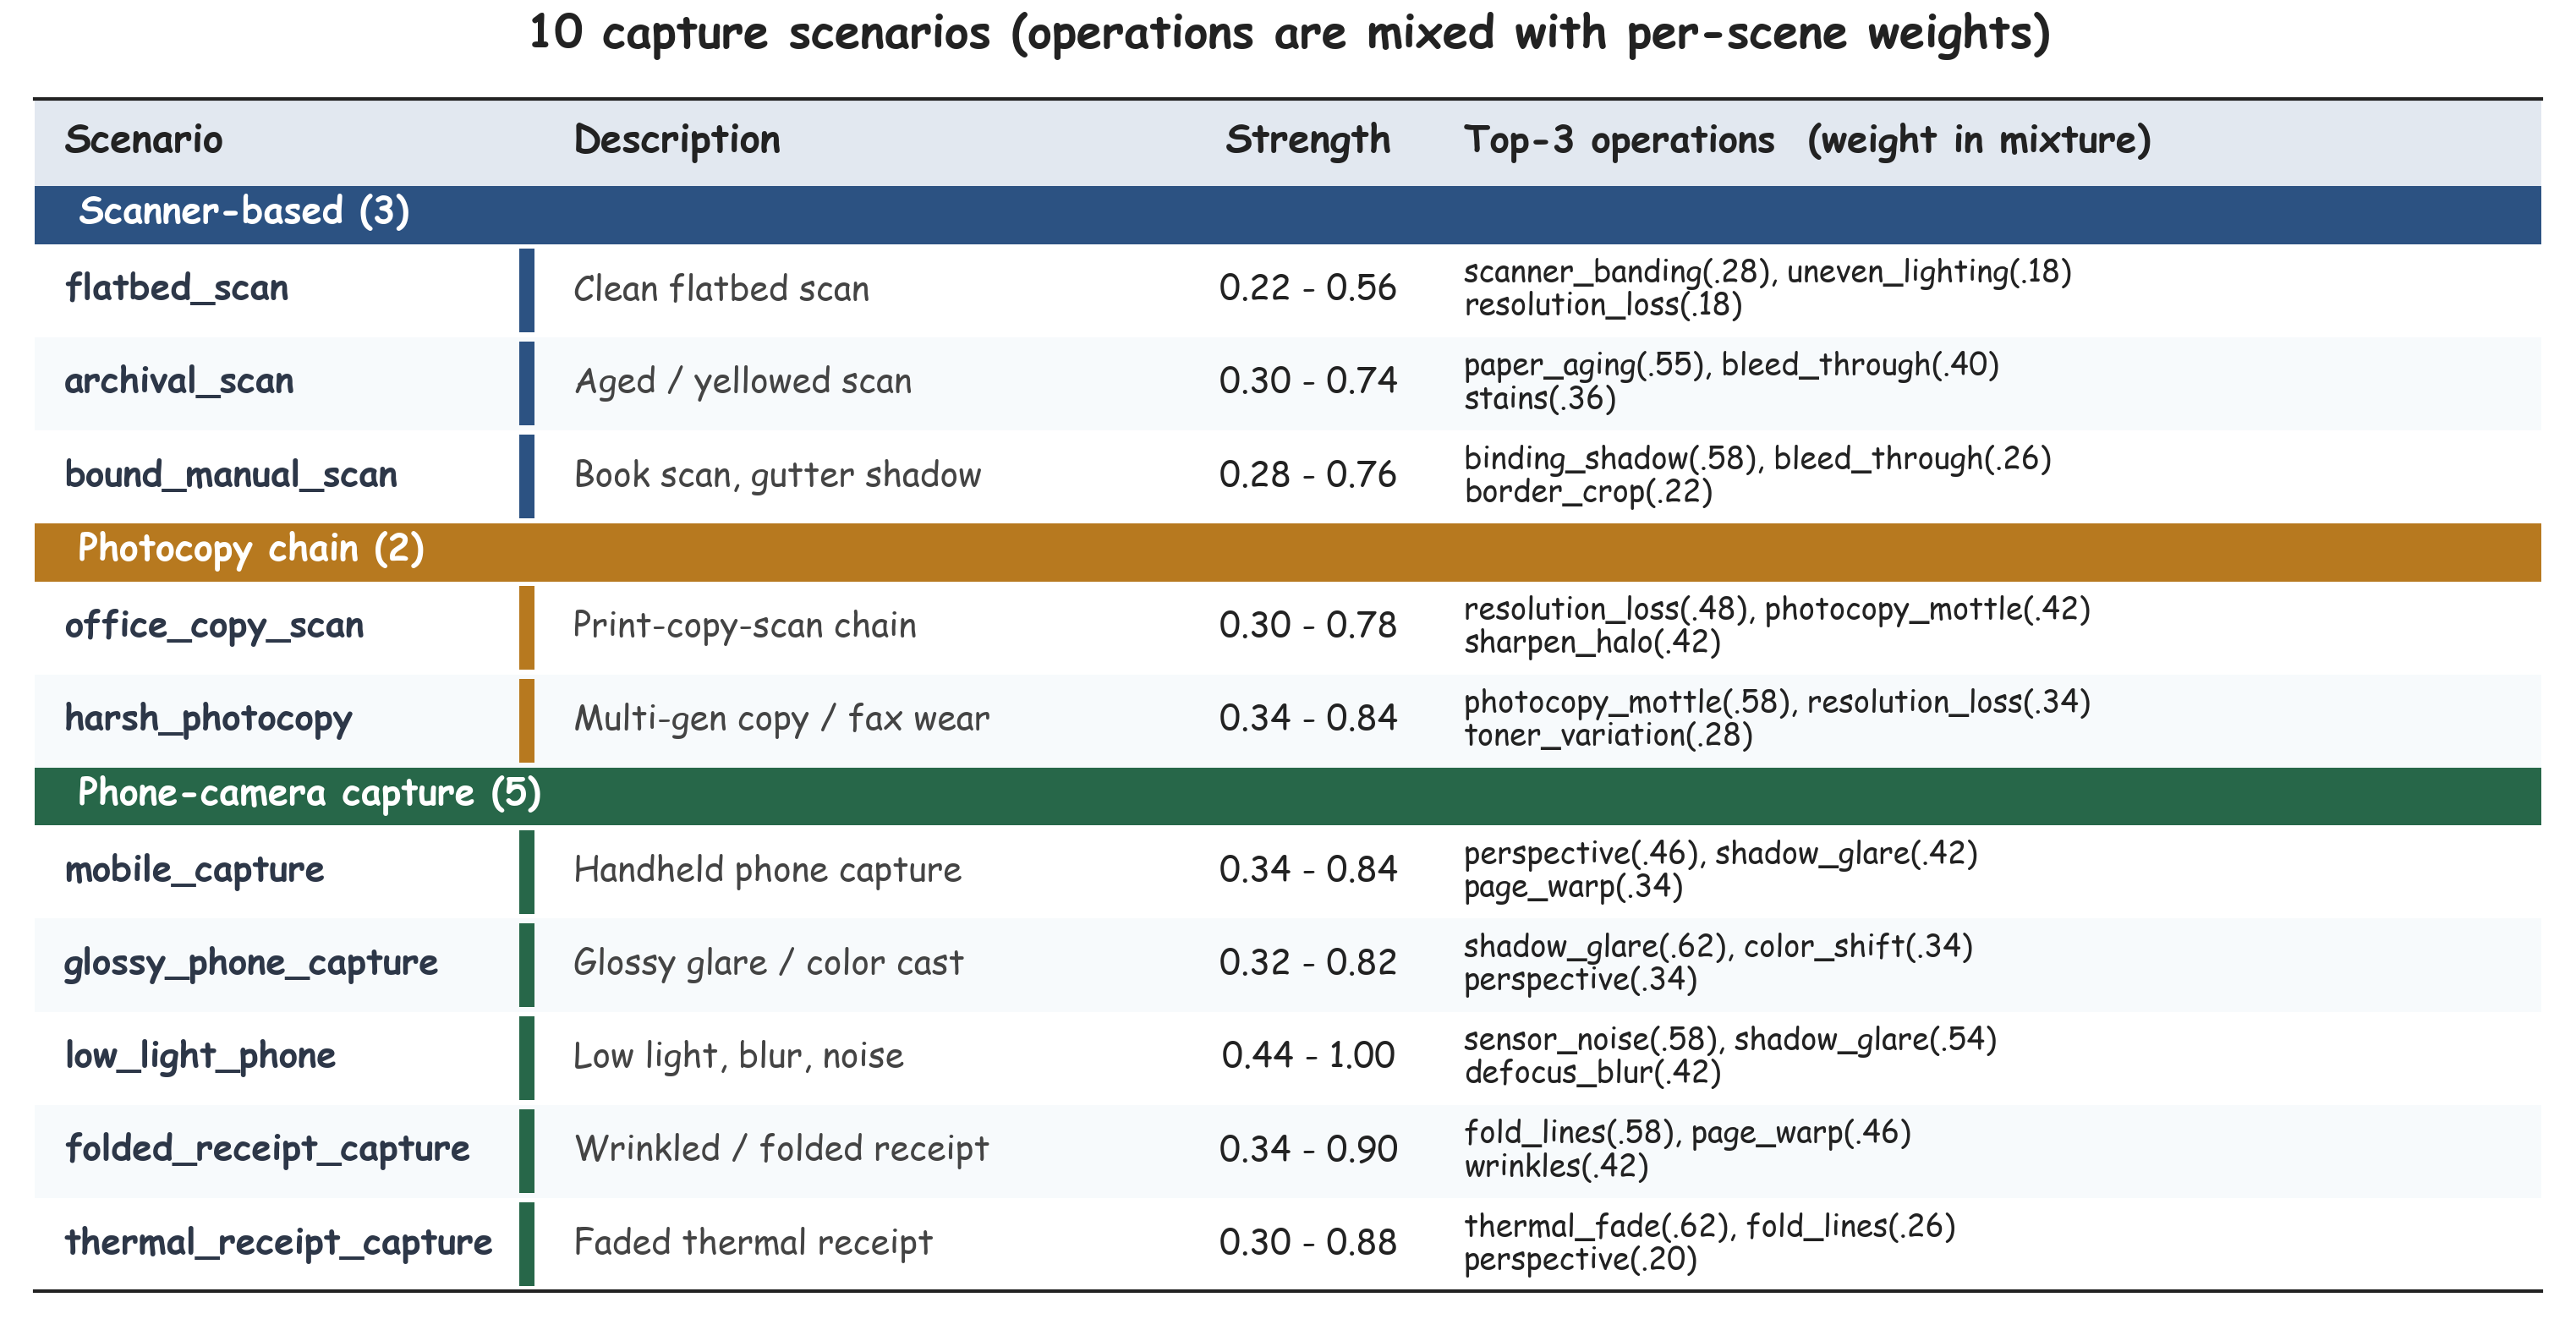
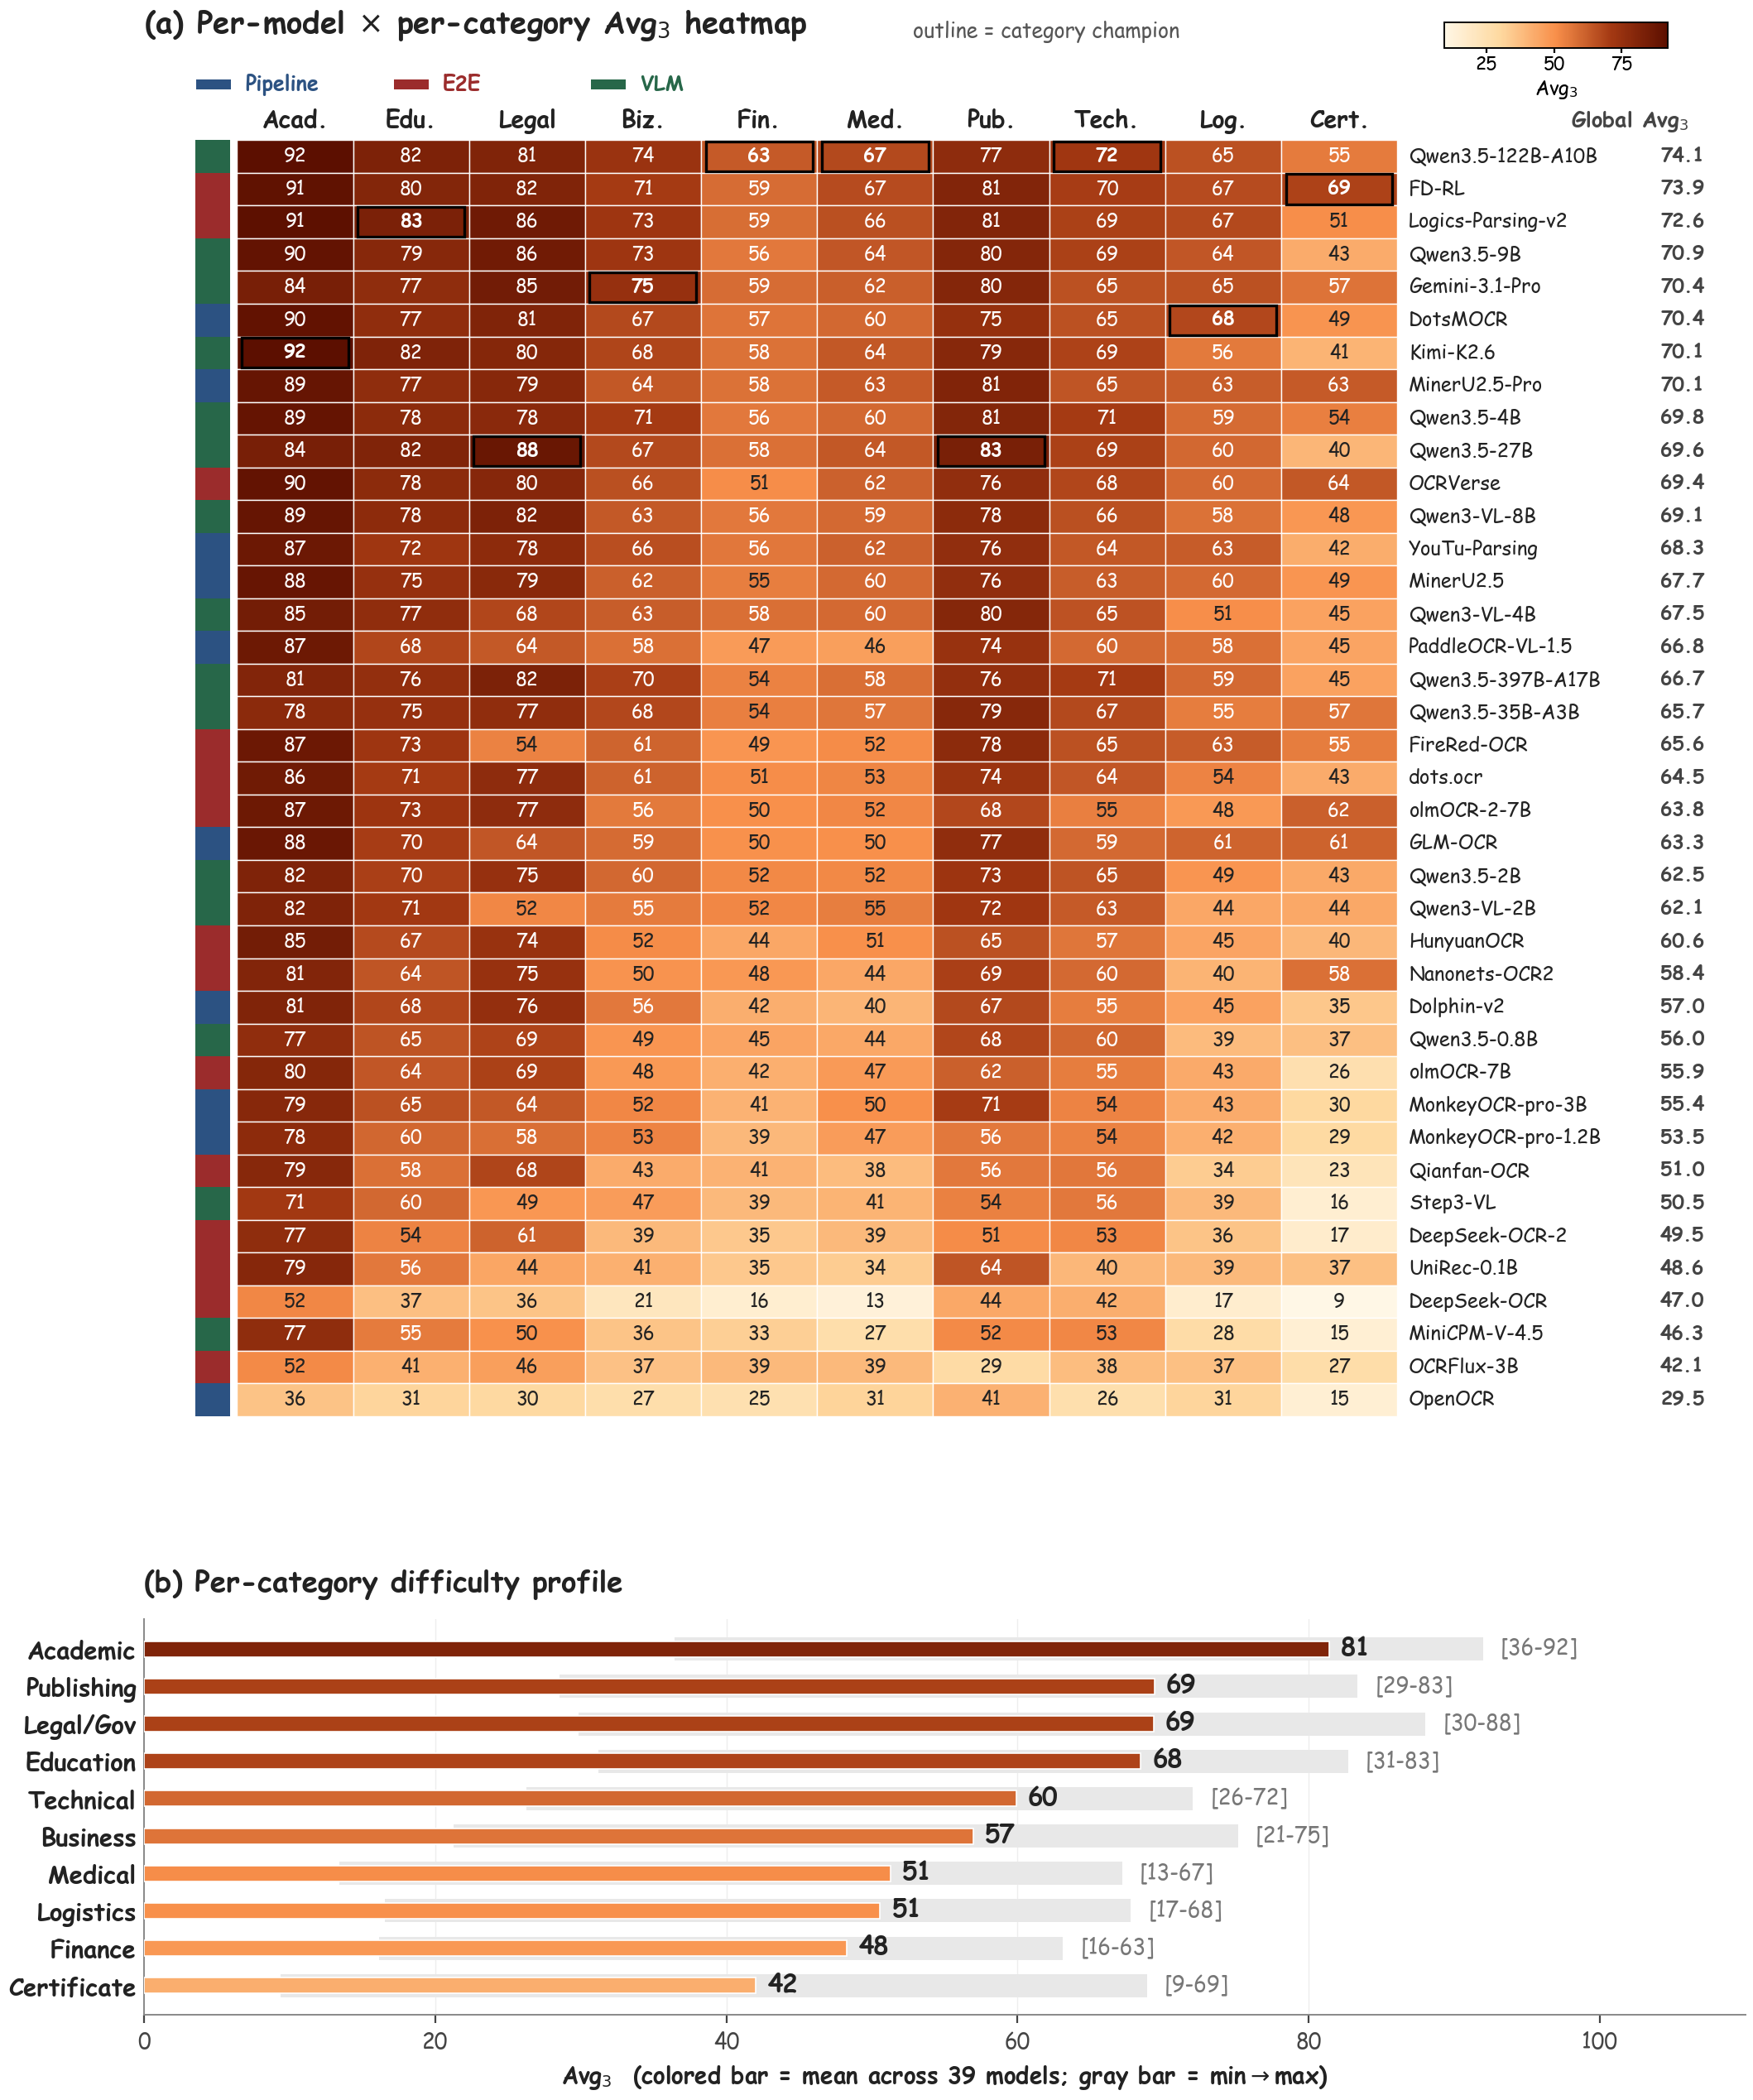
The appendix documents the degradation design, per-category behavior, and source-validity checks used to make the benchmark reproducible.

Download
The full image/GT/HTML release is hosted on Hugging Face:
# After downloading all files from Hugging Face:
shasum -a 256 -c SHA256SUMS.txt
cat pdb_full.tar.part-* | tar -xf -
Verify the split archive and reconstructed release:
python scripts/verify_split_archive.py /path/to/downloaded/files

python scripts/validate_release_manifest.py \
  --release-root /path/to/puredocbench \
  --manifest manifests/release_manifest_candidate_1475.csv
GT Review
Stable public identifiers: puredocbench-gt-latest for the GT archive and
puredocbench-review-v1 for this review UI. Exact update timestamps remain in
the Hugging Face metadata and changelog rather than public URLs or directory names.
Use the review app to inspect annotations and export correction patches.
- Public review app: Open GT Review App
- Repository file:
review/index.html - Correction guide: docs/ANNOTATION_CORRECTIONS.md
- Submit a correction: New GT annotation correction issue (English or Chinese)
Local launch:
mkdir -p review/assets
ln -s /path/to/puredocbench/images/clean review/assets/images
python3 -m http.server 8767 --directory review
Open:
http://127.0.0.1:8767/index.html
Static app URL:
https://zhihengli-casia.github.io/PureDocBench/review/
The GitHub repository does not include the full image release. For visual
review on GitHub Pages, click Load Images and select the downloaded
images/clean folder. Local launch can also use the symlink above.
GT Coordinates
If you need spatial labels, regenerate clean-render coordinates from the HTML/CSS sources:
python scripts/add_gt_coordinates.py \
  --release-root /path/to/puredocbench \
  --manifest manifests/release_manifest_candidate_1475.csv \
  --in-place \
  --include-bbox \
  --include-coordinate-system \
  --report coordinate_report.json

python scripts/validate_release_manifest.py \
  --release-root /path/to/puredocbench \
  --manifest manifests/release_manifest_candidate_1475.csv \
  --require-coordinates \
  --require-bbox
The script follows the OmniDocBench GT convention and adds a rectangular poly
field to each layout_dets item. poly is a flat list of clean-image pixel
coordinates in top-left, top-right, bottom-right, bottom-left order:
[x1, y1, x2, y1, x2, y2, x1, y2]. A derived bbox: [x1, y1, x2, y2] can also
be written with --include-bbox, but poly is the primary coordinate field.
Run playwright install chromium first if the Playwright browser is not
installed, or pass --browser-channel chrome to use a local Chrome
installation.
Inference And Scoring
PureDocBench includes a public CLI for model-agnostic inference, lightweight scoring, and OmniDocBench export:
pip install -e .

puredocbench infer \
  --images /path/to/puredocbench/images/clean \
  --output-dir predictions/my_model_clean \
  --command-template 'python my_model_infer.py --image {image} --out {output}'

puredocbench score \
  --release-root /path/to/puredocbench \
  --manifest manifests/release_manifest_candidate_1475.csv \
  --pred-dir predictions/my_model_clean \
  --track clean \
  --out-dir scores/my_model_clean
See docs/INFERENCE_SCORING.md for the full interface and OmniDocBench export path.
Repository Contents
manifests/                         Release and sample manifests
metadata/                          Dataset card and Croissant metadata
scripts/                           Rendering, degradation, validation, leaderboard tools
puredocbench/                      Public inference, scoring, and OmniDocBench export CLI
model_inference/                   Sanitized model inference configs and runners
supplemental_inference_scoring/    API/local inference and scoring utilities
assets/figures/                    Figures from the paper
paper/                             Paper PDF
Quick Start
python -m venv .venv
source .venv/bin/activate
pip install -r requirements.txt
playwright install chromium
Render one HTML page:
python scripts/render_single_image.py \
  --html /path/to/page.html \
  --out /path/to/page.png \
  --dpi 300
Apply a deterministic degradation profile:
python scripts/apply_degradation_ablation.py \
  --input /path/to/clean_images \
  --output /path/to/degraded_images \
  --profile full_medium
License
- Dataset assets are released under CC BY 4.0; see LICENSE_DATA.
- Code in this repository is released under the license in LICENSE.
- Model weights are not redistributed.
Citation
@misc{puredocbench,
  title        = {How Far Is Document Parsing from Solved? PureDocBench: A Source-Traceable Benchmark across Clean, Degraded, and Real-World Settings},
  author       = {Li, Zhiheng and collaborators},
  year         = {2026},
  howpublished = {\url{https://github.com/zhihengli-casia/puredocbench}},
  note         = {Dataset and benchmark release}
}
Contributors

27 commits
Similar repos



Languages
Python
81.5%
Shell
7.8%
JavaScript
4.8%
HTML
4.3%
CSS
1.6%
PureDocBench: source-traceable benchmark for document parsing across clean, degraded, and real-world settings
See the codeREADME
PureDocBench
How far is document parsing from solved?
A source-traceable benchmark for OCR and document parsing across clean, digitally degraded, and real-degraded document settings.
中文说明 | Dataset | Paper | GT Review & Corrections
PureDocBench uses HTML/CSS document sources as hidden anchors: each page is rendered into images and annotated from the same structured source. This gives a benchmark where text, tables, formulas, captions, and reading order can be scored with less post-hoc annotation noise.
PureDocBench 是一个源可追踪的 OCR / 文档解析 benchmark。数据由 HTML/CSS 源文件渲染而来,GT 标注从同源结构中抽取,覆盖 clean、digital-degraded、real-degraded 三条图像轨道。
Updates
- Current GT: The stable alias is
puredocbench-gt-latest; the exact revision and timestamp are recorded in Hugging Facegt/latest.json. - 2026-06-14: Updated GT annotations and opened a GT Review app for community corrections.
- 2026-05-08: Initial public release of PureDocBench, including the paper PDF and full dataset on Hugging Face.
GT Annotation Examples
The examples below show colored coordinate boxes over clean rendered pages from an academic paper, a patent form, and a tuition invoice.
At A Glance
| Item | Count |
|---|---|
| Official pages | 1,475 |
| Official images | 4,425 |
| Top-level domains | 10 |
| Fine-grained subcategories | 66 |
| Image tracks | clean, digital-degraded, real-degraded |
| Scored structures | text, formulas, tables, reading order |
Main Leaderboard
The paper evaluates 40 systems across pipeline specialists, end-to-end document parsers, and general-purpose VLMs. The live leaderboard additionally tracks public post-publication results. Each track reports Overall, TextEdit, FormulaCDM, TableTEDS, and ROEdit; Avg3 averages the three track Overall scores.
Open the interactive sortable leaderboard ↗
| Model | Params | Clean | Digital Degraded | Real Degraded | Avg3↑ | ||||||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Overall↑ | TextEdit↓ | FormulaCDM↑ | TableTEDS↑ | ROEdit↓ | Overall↑ | TextEdit↓ | FormulaCDM↑ | TableTEDS↑ | ROEdit↓ | Overall↑ | TextEdit↓ | FormulaCDM↑ | TableTEDS↑ | ROEdit↓ | |||
| Pipeline / Multi-stage Specialists | |||||||||||||||||
| NaviDC-OCR† | 1.2B | 86.90 | 0.111 | 81.01 | 91.09 | — | 77.47 | 0.206 | 72.59 | 80.45 | — | 70.85 | 0.302 | 65.11 | 77.66 | — | 78.41 |
| DotsMOCR | 3B | 76.27 | 0.151 | 66.23 | 77.65 | 0.273 | 73.16 | 0.198 | 64.32 | 74.95 | 0.309 | 61.73 | 0.312 | 54.39 | 61.97 | 0.393 | 70.39 |
| Dolphin-v2 | 3B | 65.90 | 0.342 | 59.80 | 72.12 | 0.429 | 60.24 | 0.393 | 52.20 | 67.86 | 0.461 | 44.92 | 0.553 | 39.98 | 50.04 | 0.558 | 57.02 |
| MonkeyOCR-pro-3B | 3B | 62.23 | 0.346 | 48.46 | 72.83 | 0.492 | 57.40 | 0.397 | 45.57 | 66.32 | 0.526 | 46.49 | 0.511 | 38.18 | 52.43 | 0.600 | 55.37 |
| YouTu-Parsing | 2B | 75.02 | 0.230 | 67.34 | 80.74 | 0.358 | 69.66 | 0.270 | 61.44 | 74.49 | 0.388 | 60.29 | 0.360 | 52.20 | 64.69 | 0.430 | 68.32 |
| MinerU2.5-Pro | 1.2B | 75.87 | 0.222 | 65.14 | 84.68 | 0.346 | 71.77 | 0.272 | 61.79 | 80.73 | 0.378 | 62.56 | 0.375 | 52.70 | 72.47 | 0.446 | 70.07 |
| MinerU2.5 | 1.2B | 74.90 | 0.184 | 62.08 | 81.04 | 0.327 | 68.92 | 0.245 | 56.99 | 74.24 | 0.374 | 59.15 | 0.370 | 49.01 | 65.41 | 0.446 | 67.66 |
| MonkeyOCR-pro-1.2B | 1.2B | 61.09 | 0.358 | 47.43 | 71.60 | 0.498 | 55.72 | 0.416 | 43.91 | 64.83 | 0.529 | 43.82 | 0.556 | 36.94 | 50.07 | 0.609 | 53.54 |
| PaddleOCR-VL-1.5 | 0.9B | 73.01 | 0.266 | 63.53 | 82.12 | 0.428 | 66.73 | 0.339 | 58.03 | 76.07 | 0.478 | 60.50 | 0.398 | 54.00 | 67.33 | 0.510 | 66.75 |
| GLM-OCR | 0.9B | 68.65 | 0.314 | 57.89 | 79.44 | 0.470 | 63.06 | 0.383 | 53.23 | 74.21 | 0.520 | 58.31 | 0.433 | 50.34 | 67.83 | 0.543 | 63.34 |
| OpenOCR | 0.1B | 32.70 | 0.354 | 33.50 | 0.00 | 0.507 | 30.03 | 0.410 | 31.09 | 0.00 | 0.541 | 25.73 | 0.486 | 25.81 | 0.00 | 0.591 | 29.49 |
| End-to-End Specialists | |||||||||||||||||
| OvisOCR2* | 0.8B | 81.55 | — | — | — | — | 77.09 | — | — | — | — | 66.56 | — | — | — | — | 75.06 |
| olmOCR-2-7B | 7B | 69.36 | 0.284 | 56.89 | 79.59 | 0.358 | 65.87 | 0.318 | 54.57 | 74.81 | 0.378 | 56.10 | 0.417 | 48.79 | 61.25 | 0.439 | 63.78 |
| olmOCR-7B | 7B | 62.56 | 0.388 | 58.69 | 67.77 | 0.466 | 57.84 | 0.436 | 55.44 | 61.66 | 0.499 | 47.30 | 0.542 | 46.26 | 49.80 | 0.568 | 55.90 |
| FD-RL | 4B | 78.38 | 0.193 | 68.21 | 86.22 | 0.334 | 76.33 | 0.214 | 67.16 | 83.22 | 0.350 | 67.04 | 0.298 | 58.82 | 72.08 | 0.391 | 73.92 |
| Logics-Parsing-v2 | 4B | 76.35 | 0.213 | 67.67 | 82.67 | 0.342 | 73.85 | 0.248 | 67.33 | 79.02 | 0.375 | 67.64 | 0.304 | 61.65 | 71.64 | 0.416 | 72.61 |
| OCRVerse | 4B | 73.18 | 0.273 | 63.78 | 83.09 | 0.393 | 71.36 | 0.302 | 63.95 | 80.36 | 0.415 | 63.66 | 0.363 | 57.03 | 70.30 | 0.452 | 69.40 |
| Qianfan-OCR | 4B | 57.22 | 0.370 | 49.79 | 58.83 | 0.443 | 50.85 | 0.438 | 44.41 | 51.96 | 0.485 | 45.06 | 0.494 | 39.08 | 45.53 | 0.509 | 51.04 |
| Nanonets-OCR2 | 3B | 64.83 | 0.254 | 44.98 | 74.94 | 0.377 | 61.23 | 0.307 | 45.40 | 68.97 | 0.408 | 49.03 | 0.435 | 35.50 | 55.09 | 0.468 | 58.36 |
| DeepSeek-OCR-2 | 3B | 55.53 | 0.354 | 46.00 | 56.01 | 0.466 | 49.41 | 0.412 | 40.78 | 48.67 | 0.493 | 43.60 | 0.486 | 37.30 | 42.06 | 0.533 | 49.51 |
| OCRFlux-3B | 3B | 47.14 | 0.454 | 38.35 | 48.46 | 0.424 | 41.82 | 0.486 | 31.90 | 42.17 | 0.437 | 37.21 | 0.559 | 32.65 | 34.87 | 0.491 | 42.06 |
| DeepSeek-OCR | 3B | 53.50 | 0.419 | 45.39 | 57.06 | 0.514 | 46.95 | 0.478 | 39.99 | 48.64 | 0.548 | 40.48 | 0.537 | 34.04 | 41.12 | 0.575 | 46.98 |
| dots.ocr | 2.9B | 72.01 | 0.248 | 61.37 | 79.51 | 0.379 | 65.95 | 0.307 | 56.67 | 71.86 | 0.417 | 55.68 | 0.403 | 47.70 | 59.63 | 0.467 | 64.55 |
| FireRed-OCR | 2B | 70.81 | 0.287 | 63.86 | 77.23 | 0.396 | 68.49 | 0.319 | 62.64 | 74.77 | 0.422 | 57.42 | 0.415 | 51.60 | 62.16 | 0.474 | 65.57 |
| HunyuanOCR | 1B | 65.61 | 0.269 | 55.74 | 68.02 | 0.382 | 61.49 | 0.308 | 51.62 | 63.68 | 0.400 | 54.58 | 0.421 | 48.30 | 57.54 | 0.459 | 60.56 |
| UniRec-0.1B | 0.1B | 58.91 | 0.422 | 51.31 | 67.60 | 0.526 | 52.42 | 0.501 | 48.37 | 59.04 | 0.578 | 34.44 | 0.658 | 30.97 | 38.16 | 0.685 | 48.59 |
| OpenDoc-0.1B | 0.1B | 60.28 | 0.411 | 53.09 | 68.86 | 0.519 | 52.46 | 0.501 | 48.41 | 59.04 | 0.577 | 44.27 | 0.547 | 38.46 | 49.06 | 0.603 | 52.00 |
| General VLMs: Qwen3.5 | |||||||||||||||||
| Qwen3.5-397B-A17B | 397B/17B | 69.12 | 0.233 | 65.26 | 65.40 | 0.366 | 68.34 | 0.244 | 63.91 | 65.53 | 0.376 | 62.70 | 0.287 | 60.70 | 56.12 | 0.399 | 66.72 |
| Qwen3.5-122B-A10B | 122B/10B | 76.14 | 0.226 | 67.96 | 83.03 | 0.375 | 76.34 | 0.220 | 67.82 | 83.21 | 0.366 | 69.85 | 0.281 | 62.19 | 75.44 | 0.401 | 74.11 |
| Qwen3.5-35B-A3B | 35B/3B | 68.40 | 0.232 | 64.94 | 63.45 | 0.374 | 68.04 | 0.245 | 64.78 | 63.86 | 0.379 | 60.59 | 0.310 | 59.68 | 53.07 | 0.419 | 65.68 |
| Qwen3.5-27B | 27B | 72.07 | 0.227 | 66.36 | 72.51 | 0.362 | 70.73 | 0.236 | 64.61 | 71.17 | 0.367 | 65.92 | 0.283 | 61.23 | 64.82 | 0.390 | 69.57 |
| Qwen3.5-9B | 9B | 73.87 | 0.254 | 67.60 | 79.39 | 0.388 | 73.34 | 0.260 | 67.00 | 79.01 | 0.396 | 65.45 | 0.332 | 60.91 | 68.59 | 0.437 | 70.89 |
| Qwen3.5-4B | 4B | 73.45 | 0.276 | 69.96 | 78.02 | 0.410 | 72.53 | 0.281 | 68.88 | 76.78 | 0.412 | 63.47 | 0.380 | 61.27 | 67.17 | 0.477 | 69.82 |
| Qwen3.5-2B | 2B | 66.24 | 0.348 | 62.84 | 70.70 | 0.473 | 65.22 | 0.350 | 58.30 | 72.36 | 0.477 | 55.92 | 0.440 | 50.99 | 60.79 | 0.521 | 62.46 |
| Qwen3.5-0.8B | 0.8B | 60.77 | 0.376 | 54.39 | 65.54 | 0.500 | 59.28 | 0.386 | 54.22 | 62.22 | 0.510 | 47.93 | 0.498 | 44.60 | 48.98 | 0.557 | 55.99 |
| General VLMs: Qwen3-VL | |||||||||||||||||
| Qwen3-VL-8B | 8B | 72.44 | 0.261 | 65.10 | 78.35 | 0.411 | 72.03 | 0.266 | 64.88 | 77.82 | 0.409 | 62.73 | 0.342 | 55.55 | 66.81 | 0.448 | 69.07 |
| Qwen3-VL-4B | 4B | 72.04 | 0.262 | 65.10 | 77.17 | 0.418 | 70.84 | 0.272 | 63.54 | 76.13 | 0.425 | 59.61 | 0.378 | 55.15 | 61.47 | 0.480 | 67.50 |
| Qwen3-VL-2B | 2B | 66.37 | 0.300 | 59.04 | 70.03 | 0.439 | 65.81 | 0.314 | 60.25 | 68.52 | 0.448 | 54.09 | 0.428 | 51.05 | 53.99 | 0.511 | 62.09 |
| General VLMs: Other | |||||||||||||||||
| Kimi K2.6 | 1T/32B | 72.32 | 0.303 | 66.93 | 80.30 | 0.466 | 69.95 | 0.322 | 64.69 | 77.31 | 0.475 | 68.02 | 0.335 | 62.44 | 75.14 | 0.481 | 70.10 |
| Step3-VL | 10B | 53.65 | 0.496 | 53.41 | 57.16 | 0.509 | 52.74 | 0.516 | 53.62 | 56.15 | 0.529 | 45.06 | 0.579 | 45.42 | 47.66 | 0.573 | 50.48 |
| MiniCPM-V-4.5 | 8B | 51.81 | 0.439 | 45.97 | 53.36 | 0.481 | 49.38 | 0.461 | 42.79 | 51.50 | 0.489 | 37.59 | 0.583 | 32.01 | 39.06 | 0.552 | 46.26 |
| Gemini-3.1-Pro | --- | 70.04 | 0.306 | 65.63 | 75.08 | 0.409 | 69.28 | 0.322 | 65.81 | 74.24 | 0.417 | 71.98 | 0.300 | 68.62 | 77.26 | 0.386 | 70.43 |
* OvisOCR2 scores are author-reported post-publication results from its official model card. Only per-track Overall and Avg3 were published; unreported component metrics are shown as —.
† NaviDC-OCR scores are author-reported post-publication results from its official repository. The source reports TextEdit, FormulaCDM, and TableTEDS for each track, but not ROEdit; unreported ROEdit metrics are shown as —.
Bold marks the best reported score in each column; underlined marks the runner-up. GitHub README tables cannot run sorting scripts, so use the interactive leaderboard to sort any metric in either direction.
Diagnostics
The diagnostic panel shows where current systems still have headroom. Formula recognition is the largest single bottleneck, and real degradation changes rankings more sharply than digital degradation.
Case Studies
The four case studies below are all taken from the paper. They show failures that aggregate scores can hide: notation loss, reading-order mistakes, annotation contamination, table-structure errors, character-level corruption, and missing visual authentication cues.
Case 1: Academic
Case 2: Business
Case 3: Finance
Case 4: Certificate
Appendix Highlights
The appendix documents the degradation design, per-category behavior, and source-validity checks used to make the benchmark reproducible.
Download
The full image/GT/HTML release is hosted on Hugging Face:
# After downloading all files from Hugging Face:
shasum -a 256 -c SHA256SUMS.txt
cat pdb_full.tar.part-* | tar -xf -
Verify the split archive and reconstructed release:
python scripts/verify_split_archive.py /path/to/downloaded/files

python scripts/validate_release_manifest.py \
  --release-root /path/to/puredocbench \
  --manifest manifests/release_manifest_candidate_1475.csv
GT Review
Stable public identifiers: puredocbench-gt-latest for the GT archive and
puredocbench-review-v1 for this review UI. Exact update timestamps remain in
the Hugging Face metadata and changelog rather than public URLs or directory names.
Use the review app to inspect annotations and export correction patches.
- Public review app: Open GT Review App
- Repository file:
review/index.html - Correction guide: docs/ANNOTATION_CORRECTIONS.md
- Submit a correction: New GT annotation correction issue (English or Chinese)
Local launch:
mkdir -p review/assets
ln -s /path/to/puredocbench/images/clean review/assets/images
python3 -m http.server 8767 --directory review
Open:
http://127.0.0.1:8767/index.html
Static app URL:
https://zhihengli-casia.github.io/PureDocBench/review/
The GitHub repository does not include the full image release. For visual
review on GitHub Pages, click Load Images and select the downloaded
images/clean folder. Local launch can also use the symlink above.
GT Coordinates
If you need spatial labels, regenerate clean-render coordinates from the HTML/CSS sources:
python scripts/add_gt_coordinates.py \
  --release-root /path/to/puredocbench \
  --manifest manifests/release_manifest_candidate_1475.csv \
  --in-place \
  --include-bbox \
  --include-coordinate-system \
  --report coordinate_report.json

python scripts/validate_release_manifest.py \
  --release-root /path/to/puredocbench \
  --manifest manifests/release_manifest_candidate_1475.csv \
  --require-coordinates \
  --require-bbox
The script follows the OmniDocBench GT convention and adds a rectangular poly
field to each layout_dets item. poly is a flat list of clean-image pixel
coordinates in top-left, top-right, bottom-right, bottom-left order:
[x1, y1, x2, y1, x2, y2, x1, y2]. A derived bbox: [x1, y1, x2, y2] can also
be written with --include-bbox, but poly is the primary coordinate field.
Run playwright install chromium first if the Playwright browser is not
installed, or pass --browser-channel chrome to use a local Chrome
installation.
Inference And Scoring
PureDocBench includes a public CLI for model-agnostic inference, lightweight scoring, and OmniDocBench export:
pip install -e .

puredocbench infer \
  --images /path/to/puredocbench/images/clean \
  --output-dir predictions/my_model_clean \
  --command-template 'python my_model_infer.py --image {image} --out {output}'

puredocbench score \
  --release-root /path/to/puredocbench \
  --manifest manifests/release_manifest_candidate_1475.csv \
  --pred-dir predictions/my_model_clean \
  --track clean \
  --out-dir scores/my_model_clean
See docs/INFERENCE_SCORING.md for the full interface and OmniDocBench export path.
Repository Contents
manifests/                         Release and sample manifests
metadata/                          Dataset card and Croissant metadata
scripts/                           Rendering, degradation, validation, leaderboard tools
puredocbench/                      Public inference, scoring, and OmniDocBench export CLI
model_inference/                   Sanitized model inference configs and runners
supplemental_inference_scoring/    API/local inference and scoring utilities
assets/figures/                    Figures from the paper
paper/                             Paper PDF
Quick Start
python -m venv .venv
source .venv/bin/activate
pip install -r requirements.txt
playwright install chromium
Render one HTML page:
python scripts/render_single_image.py \
  --html /path/to/page.html \
  --out /path/to/page.png \
  --dpi 300
Apply a deterministic degradation profile:
python scripts/apply_degradation_ablation.py \
  --input /path/to/clean_images \
  --output /path/to/degraded_images \
  --profile full_medium
License
- Dataset assets are released under CC BY 4.0; see LICENSE_DATA.
- Code in this repository is released under the license in LICENSE.
- Model weights are not redistributed.
Citation
@misc{puredocbench,
  title        = {How Far Is Document Parsing from Solved? PureDocBench: A Source-Traceable Benchmark across Clean, Degraded, and Real-World Settings},
  author       = {Li, Zhiheng and collaborators},
  year         = {2026},
  howpublished = {\url{https://github.com/zhihengli-casia/puredocbench}},
  note         = {Dataset and benchmark release}
}
Similar repos
Contributors
27 commits
Languages
Python
81.5%
Shell
7.8%
JavaScript
4.8%
HTML
4.3%
CSS
1.6%