
Official PyTorch Code for Anchor Token Guided Prompt Learning Methods: [ICCV 2025] ATPrompt and [Arxiv 2511.21188] AnchorOPT
Python
135
62 commits
updated Jan 28, 2026
README
Anchor Token Guided Prompt Learning Methods for VLMs.
This repo contains a series of anchor token-guided prompt learning methods for Vision-Language Models (CLIP):
-
[Arxiv] AnchorOPT: Towards Optimizing Dynamic Anchors for Adaptive Prompt Learning.
Zheng Li, Yibing Song, Xin Zhang, Lei Luo, Xiang Li, Jian Yang.
[Paper] -
[ICCV 25] Advancing Textual Prompt Learning with Anchored Attributes.
Zheng Li, Yibing Song, Ming-Ming Cheng, Xiang Li, Jian Yang.
[Paper] [Project Page] [Poster] [PPT] [中文解读] [中文翻译]
💡 Helpful Resources:
- If you are interested in prompt learning and want to know more about related work, we also maintain a list of awesome papers for your reference.
- If you attempt to reproduce the results of this implementation on the existing 15 datasets, the links to those datasets may be broken and unusable. For your convenience, we have provided 14 datasets (excluding ImageNet) in the HuggingFace platform. [Download_Links]
🔥 Some other works may interest you:
- [CVPR 24] PromptKD: Unsupervised Prompt Distillation for Vision-Language Models
Zheng Li, Xiang Li, Xinyi Fu, Xin Zhang, Weiqiang Wang, Shuo Chen, Jian Yang.
[Paper] [Code] [Project Page] [Poster] [中文论文解读] [视频解读] [中文翻译].
PromptKD is a simple and effective prompt-driven unsupervised distillation framework for VLMs (e.g., CLIP), with state-of-the-art performance.
🧪 Experimental Comparison
| Methods | Paper | Pub | Base | Novel | HM (main) | Code | Type |
|---|---|---|---|---|---|---|---|
| CLIP | Link | ICML 21 | 69.34 | 74.22 | 71.70 | Link | Model |
| CoOp | Link | IJCV 22 | 82.69 | 63.22 | 71.66 | Link | Baseline |
| +ATPrompt | - | ICCV 25 | 82.68 | 68.04 | 74.65(+2.99) | - | Plugin |
| +AnchorOPT | - | Arxiv | 81.24 | 76.27 | 78.68(+7.02) | - | Plugin |
| CoCoOp | Link | CVPR 22 | 80.47 | 71.69 | 75.83 | Link | Baseline |
| +ATPrompt | - | ICCV 25 | 81.69 | 74.54 | 77.95(+2.21) | - | Plugin |
| +AnchorOPT | - | Arxiv | 81.87 | 77.06 | 79.39(+3.56) | - | Plugin |
| MaPLe | Link | CVPR 23 | 82.28 | 75.14 | 78.55 | Link | Baseline |
| +ATPrompt | - | ICCV 25 | 82.98 | 75.76 | 79.21(+0.66) | - | Plugin |
| +AnchorOPT | - | Arxiv | 83.62 | 77.36 | 80.37(+1.82) | - | Plugin |
| DePT | Link | CVPR 24 | 83.80 | 72.89 | 77.97 | Link | Baseline |
| +ATPrompt | - | ICCV 25 | 83.80 | 73.75 | 78.45(+1.16) | - | Plugin |
| +AnchorOPT | - | Arxiv | 84.27 | 76.90 | 80.42(+3.13) | - | Plugin |
🗒 [Arxiv] AnchorOPT: Towards Optimizing Dynamic Anchors for Adaptive Prompt Learning.
Abstract
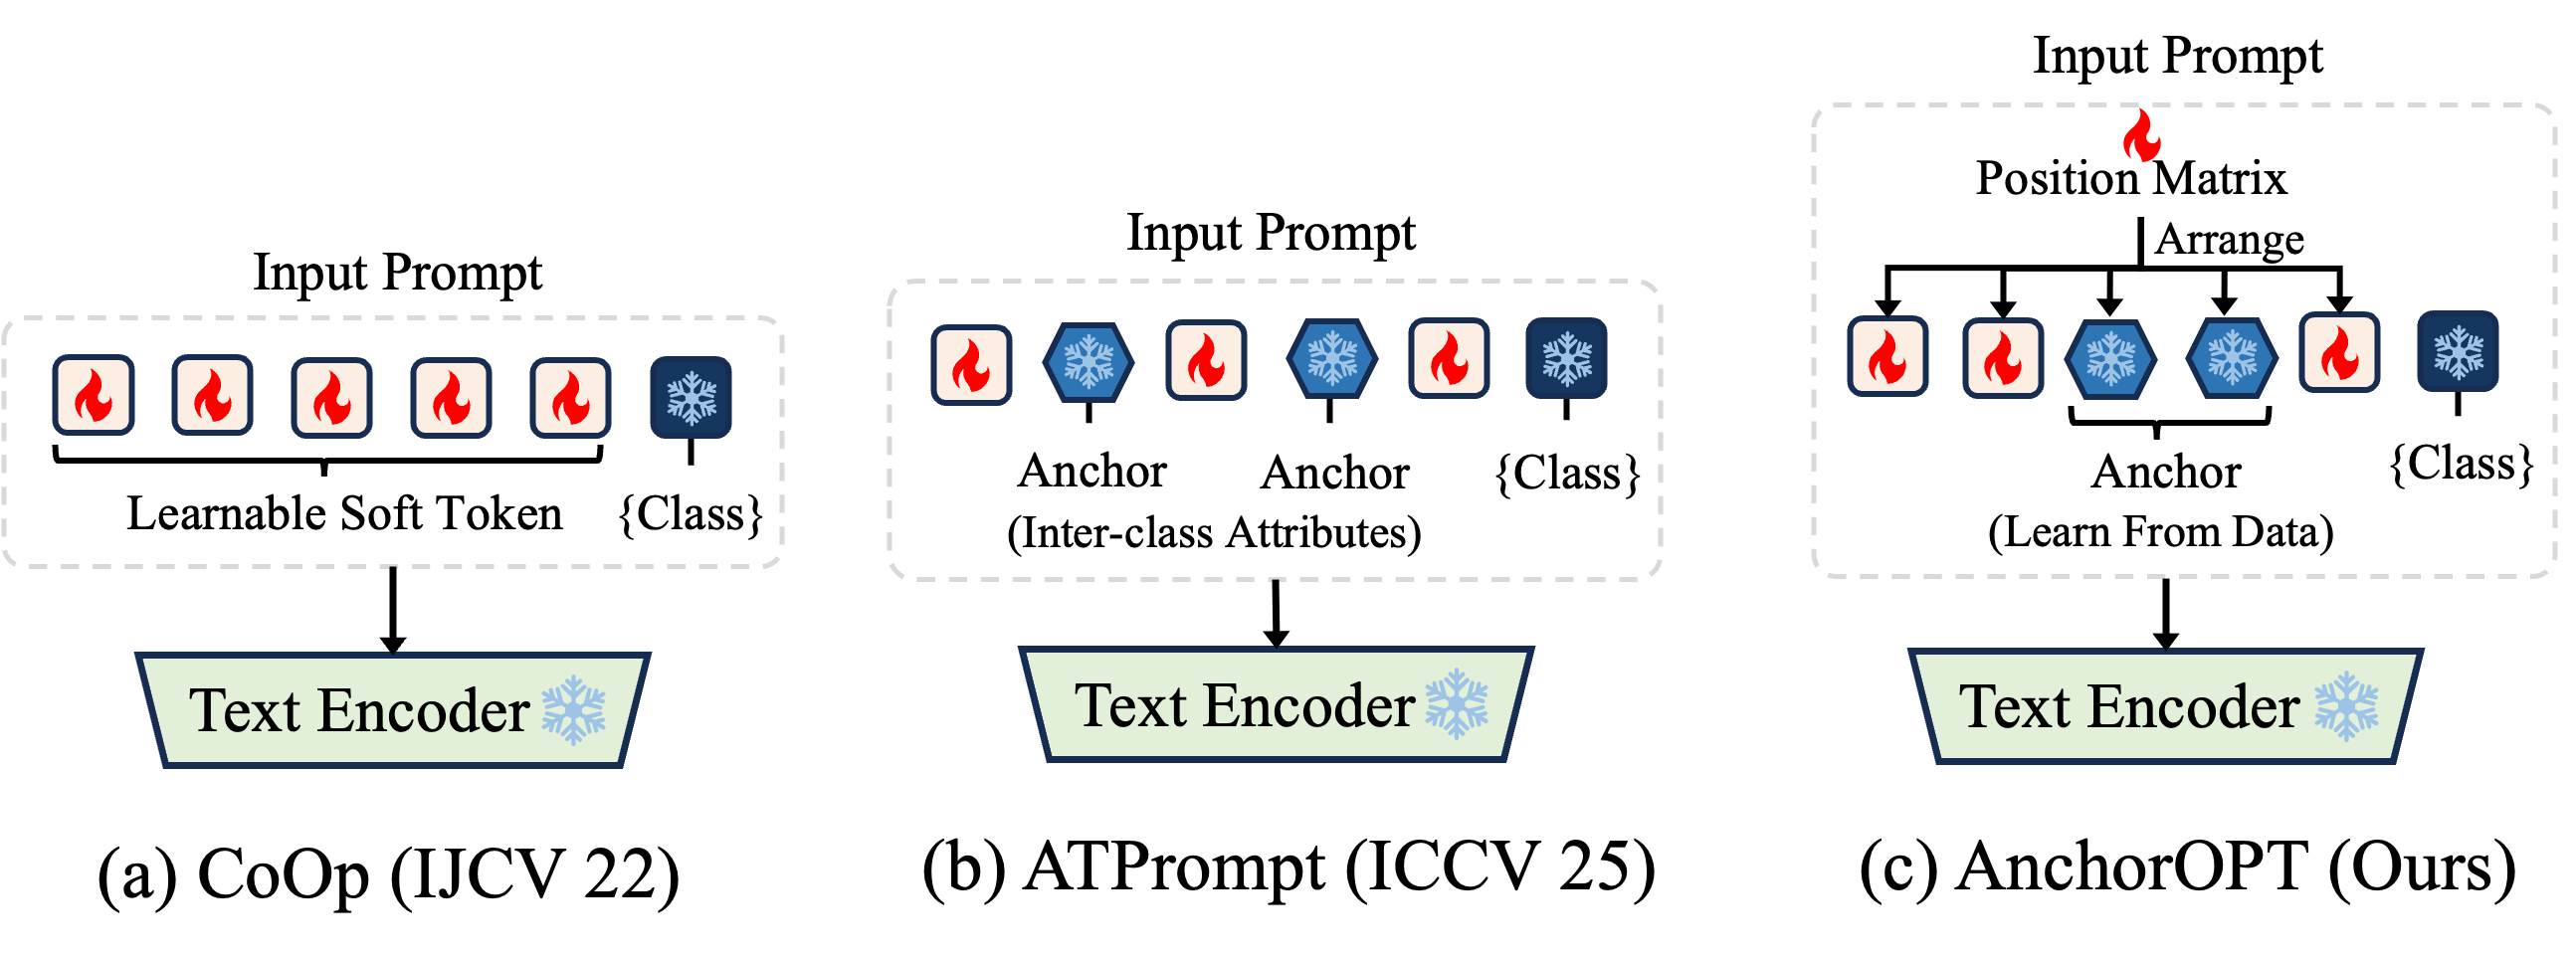
Existing prompt learning methods, which are built upon CLIP models, leverage textual tokens as anchors to guide the learnable soft tokens. This guidance improves CLIP generalizations. However, these anchors—static in both value and position—lack cross-task and stage-adaptive flexibility.
To address this limitation, we propose AnchorOPT, a dynamic anchor-based prompt learning framework. Specifically, AnchorOPT introduces dynamism in two key dimensions: (i) anchor values eschew handcrafted explicit textual tokens (e.g., "shape", "color"), instead learning dynamically from task-specific data; and (ii) the positional relationship between anchor and soft tokens is no longer fixed but adaptively optimized via a learnable position matrix conditioned on the training stage and task context.
Training occurs in two stages: we first learn the anchor tokens, then freeze and transfer them to the second stage for optimization of soft tokens and the position matrix.
Framework
🚀 Running
Please see the [AnchorOPT Reproduction Guide].
🗒 [ICCV 25] ATPrompt: Advancing Textual Prompt Learning with Anchored Attributes
Abstract
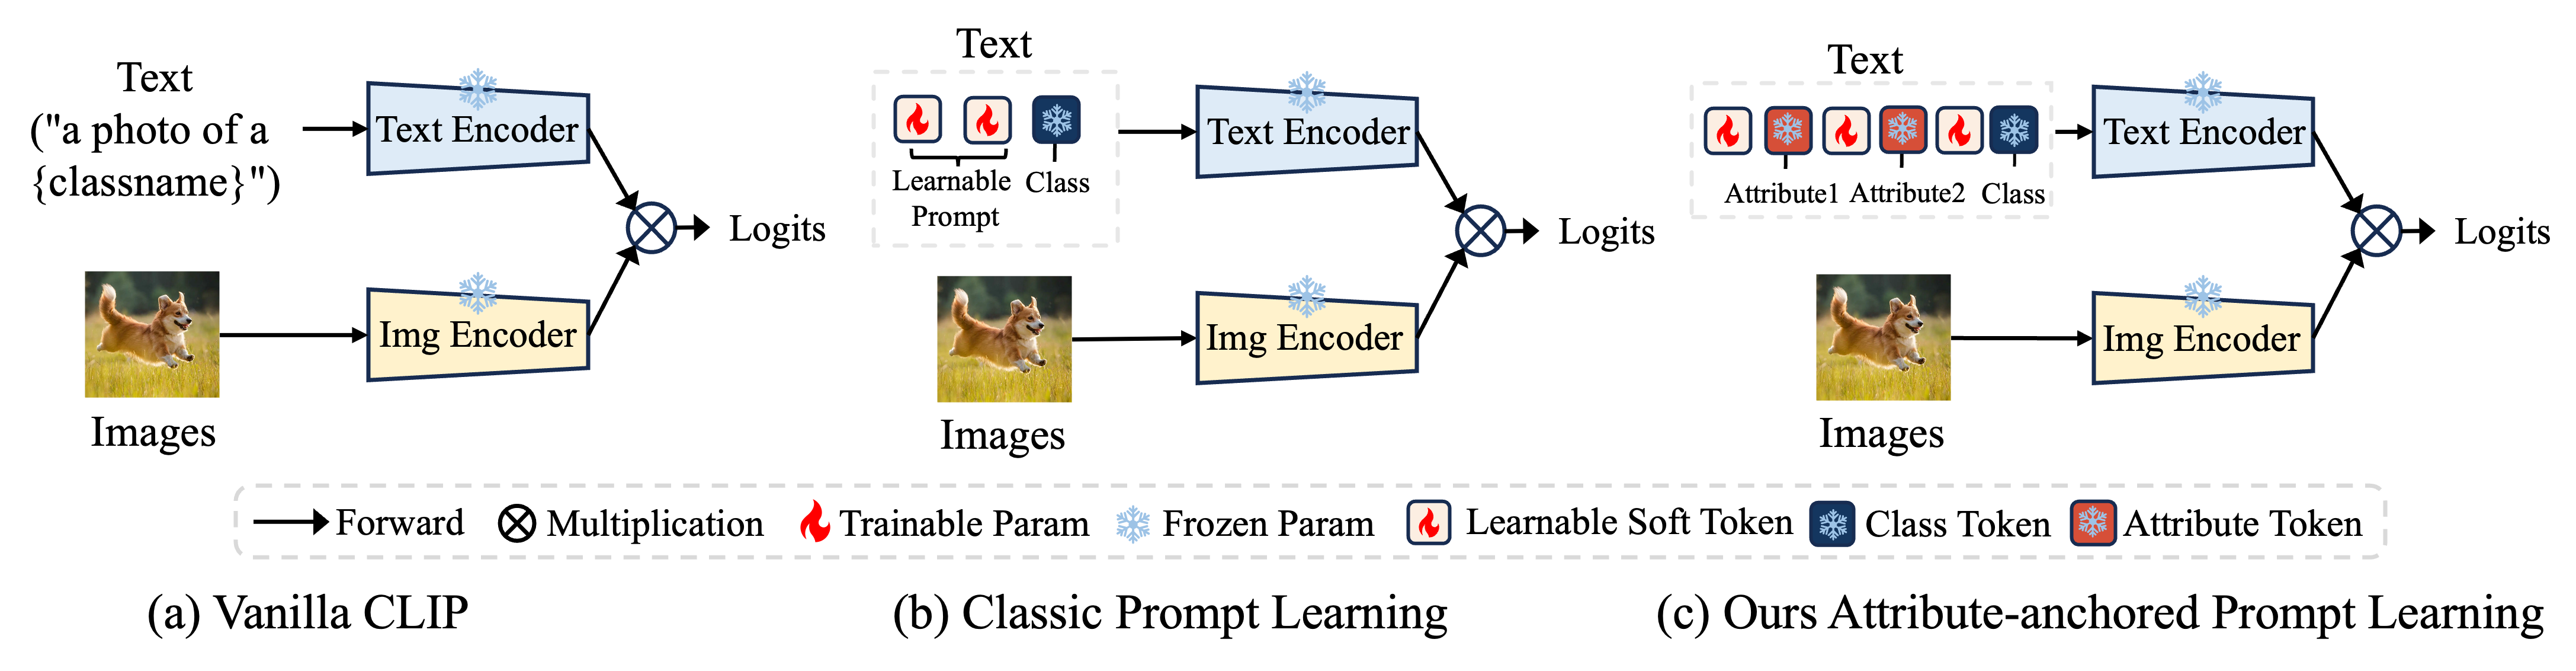
In this work, we introduce an attribute-anchored textual prompt learning method for vision-language models, named ATPrompt.
This method extends the learning space of soft prompts from the original one-dimensional category level to the multi-dimensional attribute level by incorporating multiple universal attribute tokens into the learnable soft prompts.
Guided by these attributes, soft tokens acquire not only category-specific but also attribute-related general representations during training, thereby enhancing the alignment between images and unknown categories compared to the original method.
Framework
🚀 Running
Please see the [ATPrompt Reproduction Guide].
✉️ Contact
If you have any questions, you can submit an issue on GitHub, or contact me by email (zhengli97[at]foxmail.com).
⭐ Citation
If you find our paper or repo helpful for your research, please consider citing the following paper and giving this repo a star. Thank you!
@article{li2025anchoropt,
  title={AnchorOPT: Towards Optimizing Dynamic Anchors for Adaptive Prompt Learning},
  author={Li, Zheng and Song, Yibing and Zhang, Xin and Luo, Lei and Li, Xiang and Yang, Jian},
  journal={arXiv preprint arXiv:2511.21188},
  year={2025}
}

@inproceedings{li2025advancing,
  title={Advancing textual prompt learning with anchored attributes},
  author={Li, Zheng and Song, Yibing and Cheng, Ming-Ming and Li, Xiang and Yang, Jian},
  booktitle={Proceedings of the IEEE/CVF International Conference on Computer Vision},
  pages={3618--3627},
  year={2025}
}

@inproceedings{li2024promptkd,
  title={Promptkd: Unsupervised prompt distillation for vision-language models},
  author={Li, Zheng and Li, Xiang and Fu, Xinyi and Zhang, Xin and Wang, Weiqiang and Chen, Shuo and Yang, Jian},
  booktitle={Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition},
  pages={26617--26626},
  year={2024}
}
Contributors

62 commits
Similar repos


Languages
Python
94.7%
Shell
5.3%
Official PyTorch Code for Anchor Token Guided Prompt Learning Methods: [ICCV 2025] ATPrompt and [Arxiv 2511.21188] AnchorOPT
Python
135
62 commits
updated Jan 28, 2026
README
Anchor Token Guided Prompt Learning Methods for VLMs.
This repo contains a series of anchor token-guided prompt learning methods for Vision-Language Models (CLIP):
-
[Arxiv] AnchorOPT: Towards Optimizing Dynamic Anchors for Adaptive Prompt Learning.
Zheng Li, Yibing Song, Xin Zhang, Lei Luo, Xiang Li, Jian Yang.
[Paper] -
[ICCV 25] Advancing Textual Prompt Learning with Anchored Attributes.
Zheng Li, Yibing Song, Ming-Ming Cheng, Xiang Li, Jian Yang.
[Paper] [Project Page] [Poster] [PPT] [中文解读] [中文翻译]
💡 Helpful Resources:
- If you are interested in prompt learning and want to know more about related work, we also maintain a list of awesome papers for your reference.
- If you attempt to reproduce the results of this implementation on the existing 15 datasets, the links to those datasets may be broken and unusable. For your convenience, we have provided 14 datasets (excluding ImageNet) in the HuggingFace platform. [Download_Links]
🔥 Some other works may interest you:
- [CVPR 24] PromptKD: Unsupervised Prompt Distillation for Vision-Language Models
Zheng Li, Xiang Li, Xinyi Fu, Xin Zhang, Weiqiang Wang, Shuo Chen, Jian Yang.
[Paper] [Code] [Project Page] [Poster] [中文论文解读] [视频解读] [中文翻译].
PromptKD is a simple and effective prompt-driven unsupervised distillation framework for VLMs (e.g., CLIP), with state-of-the-art performance.
🧪 Experimental Comparison
| Methods | Paper | Pub | Base | Novel | HM (main) | Code | Type |
|---|---|---|---|---|---|---|---|
| CLIP | Link | ICML 21 | 69.34 | 74.22 | 71.70 | Link | Model |
| CoOp | Link | IJCV 22 | 82.69 | 63.22 | 71.66 | Link | Baseline |
| +ATPrompt | - | ICCV 25 | 82.68 | 68.04 | 74.65(+2.99) | - | Plugin |
| +AnchorOPT | - | Arxiv | 81.24 | 76.27 | 78.68(+7.02) | - | Plugin |
| CoCoOp | Link | CVPR 22 | 80.47 | 71.69 | 75.83 | Link | Baseline |
| +ATPrompt | - | ICCV 25 | 81.69 | 74.54 | 77.95(+2.21) | - | Plugin |
| +AnchorOPT | - | Arxiv | 81.87 | 77.06 | 79.39(+3.56) | - | Plugin |
| MaPLe | Link | CVPR 23 | 82.28 | 75.14 | 78.55 | Link | Baseline |
| +ATPrompt | - | ICCV 25 | 82.98 | 75.76 | 79.21(+0.66) | - | Plugin |
| +AnchorOPT | - | Arxiv | 83.62 | 77.36 | 80.37(+1.82) | - | Plugin |
| DePT | Link | CVPR 24 | 83.80 | 72.89 | 77.97 | Link | Baseline |
| +ATPrompt | - | ICCV 25 | 83.80 | 73.75 | 78.45(+1.16) | - | Plugin |
| +AnchorOPT | - | Arxiv | 84.27 | 76.90 | 80.42(+3.13) | - | Plugin |
🗒 [Arxiv] AnchorOPT: Towards Optimizing Dynamic Anchors for Adaptive Prompt Learning.
Abstract
Existing prompt learning methods, which are built upon CLIP models, leverage textual tokens as anchors to guide the learnable soft tokens. This guidance improves CLIP generalizations. However, these anchors—static in both value and position—lack cross-task and stage-adaptive flexibility.
To address this limitation, we propose AnchorOPT, a dynamic anchor-based prompt learning framework. Specifically, AnchorOPT introduces dynamism in two key dimensions: (i) anchor values eschew handcrafted explicit textual tokens (e.g., "shape", "color"), instead learning dynamically from task-specific data; and (ii) the positional relationship between anchor and soft tokens is no longer fixed but adaptively optimized via a learnable position matrix conditioned on the training stage and task context.
Training occurs in two stages: we first learn the anchor tokens, then freeze and transfer them to the second stage for optimization of soft tokens and the position matrix.
Framework
🚀 Running
Please see the [AnchorOPT Reproduction Guide].
🗒 [ICCV 25] ATPrompt: Advancing Textual Prompt Learning with Anchored Attributes
Abstract
In this work, we introduce an attribute-anchored textual prompt learning method for vision-language models, named ATPrompt.
This method extends the learning space of soft prompts from the original one-dimensional category level to the multi-dimensional attribute level by incorporating multiple universal attribute tokens into the learnable soft prompts.
Guided by these attributes, soft tokens acquire not only category-specific but also attribute-related general representations during training, thereby enhancing the alignment between images and unknown categories compared to the original method.
Framework
🚀 Running
Please see the [ATPrompt Reproduction Guide].
✉️ Contact
If you have any questions, you can submit an issue on GitHub, or contact me by email (zhengli97[at]foxmail.com).
⭐ Citation
If you find our paper or repo helpful for your research, please consider citing the following paper and giving this repo a star. Thank you!
@article{li2025anchoropt,
  title={AnchorOPT: Towards Optimizing Dynamic Anchors for Adaptive Prompt Learning},
  author={Li, Zheng and Song, Yibing and Zhang, Xin and Luo, Lei and Li, Xiang and Yang, Jian},
  journal={arXiv preprint arXiv:2511.21188},
  year={2025}
}

@inproceedings{li2025advancing,
  title={Advancing textual prompt learning with anchored attributes},
  author={Li, Zheng and Song, Yibing and Cheng, Ming-Ming and Li, Xiang and Yang, Jian},
  booktitle={Proceedings of the IEEE/CVF International Conference on Computer Vision},
  pages={3618--3627},
  year={2025}
}

@inproceedings{li2024promptkd,
  title={Promptkd: Unsupervised prompt distillation for vision-language models},
  author={Li, Zheng and Li, Xiang and Fu, Xinyi and Zhang, Xin and Wang, Weiqiang and Chen, Shuo and Yang, Jian},
  booktitle={Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition},
  pages={26617--26626},
  year={2024}
}
Similar repos
Contributors
62 commits
Languages
Python
94.7%
Shell
5.3%