
Code for "OmniNFT: Modality-wise Omni Diffusion Reinforcement for Joint Audio-Video Generation"
Python
157
13 commits
updated Jun 18, 2026
README
OmniNFT
Modality-wise Omni Diffusion Negative-aware Fine-Tuning for Joint Audio and Video Generation


🔈 News
- [2026-05-21] Comfy compatible format is here.
- [2026-05-19] LTX-2.3 has been supported 🚀. LoRA weights for LTX-2.3 are now available!
- [2026-05-13] OmniNFT is released on Arixv.
- [2026-05-11] Code and LoRA weights for LTX-2 are available.
🏗️ Method Overview
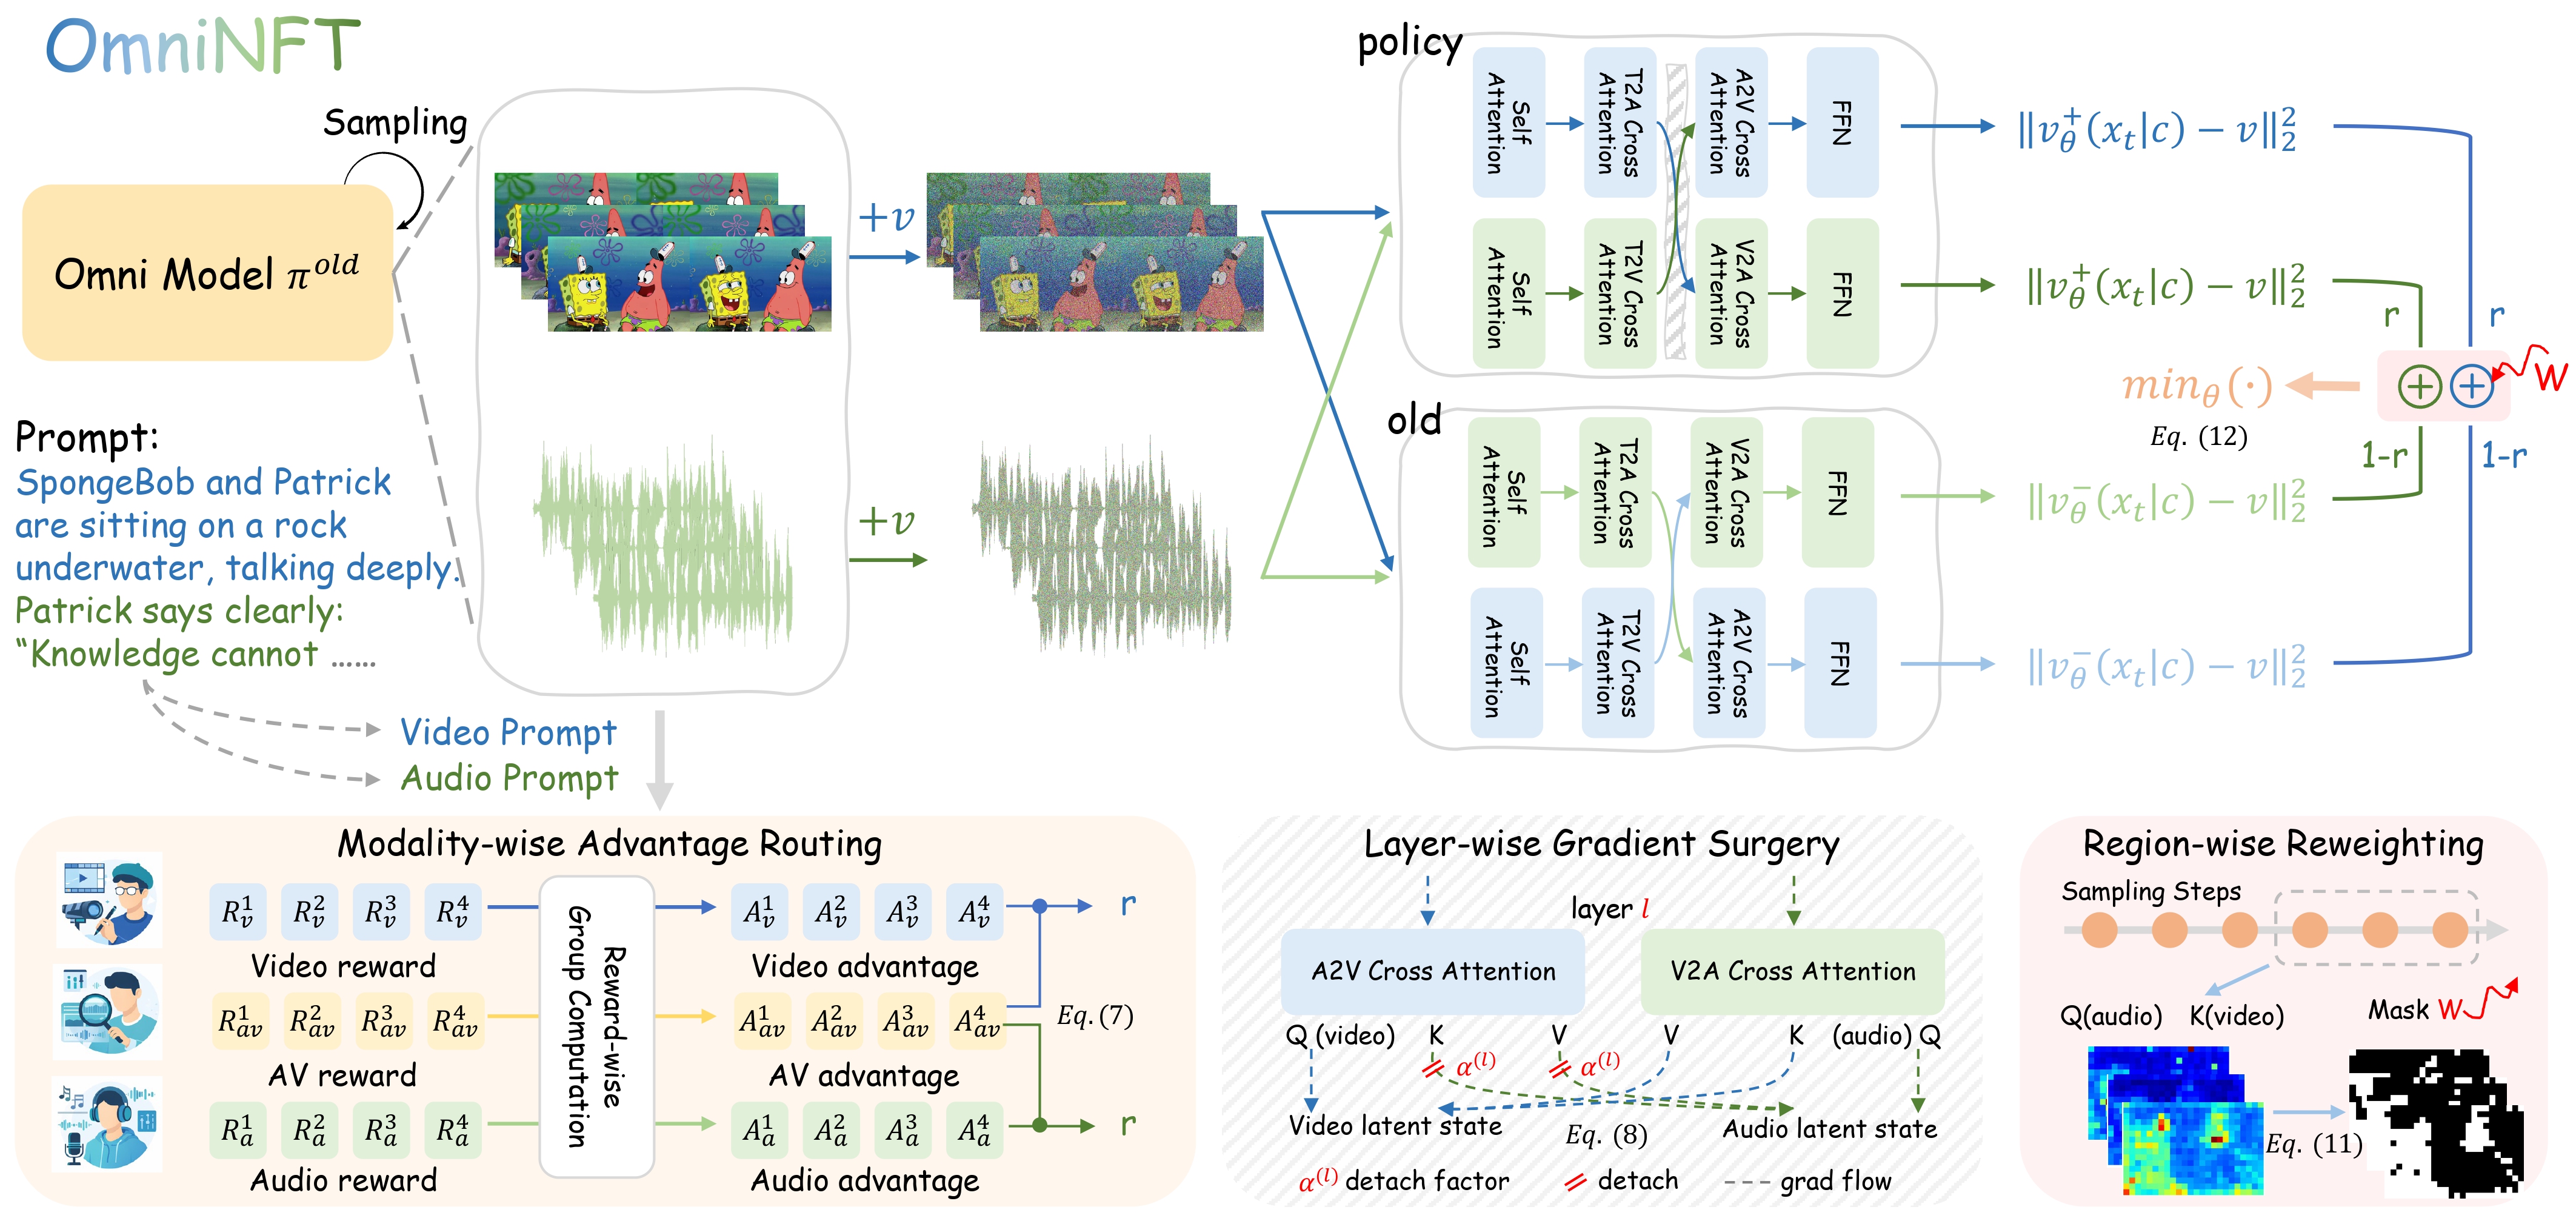
Modality-wise Advantage Routing — Instead of collapsing all rewards into a single global advantage, OmniNFT computes independent per-reward advantages for video, audio, and cross-modal synchronization, then routes each to its responsible generation branch — uni-modal advantages supervise only their own branch while the synchronization advantage is broadcast to both — resolving the advantage inconsistency where roughly half of samples receive opposing rewards across modalities.
Layer-wise Gradient Surgery — To address gradient imbalance where video-branch gradients leak into shallow audio layers dedicated to intra-modal generation, OmniNFT applies a partial stop-gradient on the audio key-value projections in A2V cross-attention at shallow Transformer blocks, suppressing erroneous gradient injection while preserving full gradient flow through the deeper cross-modal alignment layers (AV-Sync Zone).
Region-wise Loss Reweighting — Leveraging V2A cross-attention maps from late denoising steps as an intrinsic proxy for sound-emitting critical regions, OmniNFT aggregates them into per-token importance weights that modulate the video-branch RL loss, providing fine-grained credit assignment that concentrates optimization capacity on regions most critical for audio-video synchronization without requiring external detection modules.
⚡ Installation
conda create -n omnninft python=3.11
conda activate omnninft
pip install -r requirements.txt
📦 Model Checkpoints
| Env Variable | Description | Source |
|---|---|---|
LTX-MODEL | LTX base model | LTX-2 LTX-2.3 |
OmniNFT_LTX | LTX + OmniNFT | OmniNFT |
REWARD_MODELS | All reward models (HPSv3, CLAP, AudioBox, Synchformer, ImageBind, etc.) | OmniNFT-Reward-Series |
🚀 Training
Step 0: Download Reward Models
Download all reward model weights from HuggingFace:
huggingface-cli download --resume-download zghhui/OmniNFT-Reward-Series --local-dir Omni_Reward_Series
Reward model checkpoints under Omni_Reward_Series/
| Env Variable | Path | Description |
|---|---|---|
HPSV3_CKPT_PATH | Omni_Reward_Series/HPSv3/HPSv3.safetensors | HPSv3 image quality scorer |
VIDEOALIGN_CKPT_DIR | Omni_Reward_Series/VideoReward | VideoAlign video quality scorer |
AUDIOBOX_CKPT | Omni_Reward_Series/audiobox-aesthetics/checkpoint.pt | AudioBox aesthetics predictor |
CLAP_CKPT | Omni_Reward_Series/CLAP | CLAP audio-text alignment model |
IMAGEBIND_CKPT | Omni_Reward_Series/ImageBind/imagebind_huge.pth | ImageBind multimodal embeddings |
SYNCHFORMER_CKPT | Omni_Reward_Series/synchformer/synchformer_state_dict.pth | Synchformer AV sync scorer |
All paths are pre-configured in bash_train_omninft_ltx_fsdp.sh as relative paths.
Step 1: Launch Reward Servers
HPSv3 and VideoAlign run as remote HTTP servers. Start them before training:
# Terminal 1: HPSv3 server
bash flow_grpo/server/run_remote_hpsv3.sh

# Terminal 2: VideoAlign server
bash flow_grpo/server/run_remote_videoalign.sh
Step 2: Multi(Single)-Node Training
bash bash_train_omninft_ltx_fsdp.sh branch_aware_layer_surgery_avweight
🎬 Inference
Step 1: Merge LoRA into base model
After training, merge the LoRA weights into the base checkpoint:
python scripts/merge_lora.py \
    --checkpoint-path $LTX_MODEL_PATH \
    --lora-dir $OUTPUT_DIR/checkpoint-latest/lora \
    --output-path ./merged_model.safetensors \
    --dtype bf16
Arguments
| Argument | Description |
|---|---|
--checkpoint-path | LTX-Video base checkpoint used during training |
--lora-dir | LoRA output directory (contains adapter_model.safetensors + adapter_config.json) |
--output-path | Output path for the merged model |
--dtype | Output precision: bf16 (default) / fp16 / fp32 / keep |
Step 2: Generate audio-video
python scripts/inference.py \
    --model_path ./merged_model.safetensors \
    --gemma_path $GEMMA_MODEL_PATH \
    --prompt "A man plays acoustic guitar on a wooden stage, warm applause from the audience" \
    --seed 42 \
    --output_dir ./results
Arguments
| Argument | Default | Description |
|---|---|---|
--model_path | (required) | Path to merged .safetensors model |
--gemma_path | env GEMMA_MODEL_PATH | Path to Gemma 3 text encoder |
--prompt | (required) | Text prompt for generation |
--num_frames | 121 | Number of video frames |
--height / --width | model default | Video resolution |
--num_inference_steps | model default | Number of denoising steps |
--video_guidance_scale | model default | Video CFG scale |
--audio_guidance_scale | model default | Audio CFG scale |
--seed | 42 | Random seed |
--no_audio | false | Disable audio generation |
--dtype | bf16 | Inference precision |
Outputs are saved to --output_dir: .mp4 (video with audio) and .wav (audio only).
🖊️ Citation
@article{zhang2026omninft,
  title={OmniNFT: Modality-wise Omni Diffusion Reinforcement for Joint Audio-Video Generation},
  author={Zhang, Guohui and Ma, XiaoXiao and Huang, Jie and Xu, Hang and Yu, Hu and Fu, Siming and Li, Yuming and Xue, Zeyue and Song, Lin and Huang, Haoyang and Duan, Nan and Zhao, Feng},
  journal={arXiv preprint arXiv:2605.12480},
  year={2026}
}
🤝 Acknowledgements
⚠️ License
Research use only. See individual submodule licenses (HPSv3, ImageBind, LTX-Video, etc.) for their terms.
Similar repos


Languages
Python
99.8%
Code for "OmniNFT: Modality-wise Omni Diffusion Reinforcement for Joint Audio-Video Generation"
Python
157
13 commits
updated Jun 18, 2026
README
OmniNFT
Modality-wise Omni Diffusion Negative-aware Fine-Tuning for Joint Audio and Video Generation
🔈 News
- [2026-05-21] Comfy compatible format is here.
- [2026-05-19] LTX-2.3 has been supported 🚀. LoRA weights for LTX-2.3 are now available!
- [2026-05-13] OmniNFT is released on Arixv.
- [2026-05-11] Code and LoRA weights for LTX-2 are available.
🏗️ Method Overview
Modality-wise Advantage Routing — Instead of collapsing all rewards into a single global advantage, OmniNFT computes independent per-reward advantages for video, audio, and cross-modal synchronization, then routes each to its responsible generation branch — uni-modal advantages supervise only their own branch while the synchronization advantage is broadcast to both — resolving the advantage inconsistency where roughly half of samples receive opposing rewards across modalities.
Layer-wise Gradient Surgery — To address gradient imbalance where video-branch gradients leak into shallow audio layers dedicated to intra-modal generation, OmniNFT applies a partial stop-gradient on the audio key-value projections in A2V cross-attention at shallow Transformer blocks, suppressing erroneous gradient injection while preserving full gradient flow through the deeper cross-modal alignment layers (AV-Sync Zone).
Region-wise Loss Reweighting — Leveraging V2A cross-attention maps from late denoising steps as an intrinsic proxy for sound-emitting critical regions, OmniNFT aggregates them into per-token importance weights that modulate the video-branch RL loss, providing fine-grained credit assignment that concentrates optimization capacity on regions most critical for audio-video synchronization without requiring external detection modules.
⚡ Installation
conda create -n omnninft python=3.11
conda activate omnninft
pip install -r requirements.txt
📦 Model Checkpoints
| Env Variable | Description | Source |
|---|---|---|
LTX-MODEL | LTX base model | LTX-2 LTX-2.3 |
OmniNFT_LTX | LTX + OmniNFT | OmniNFT |
REWARD_MODELS | All reward models (HPSv3, CLAP, AudioBox, Synchformer, ImageBind, etc.) | OmniNFT-Reward-Series |
🚀 Training
Step 0: Download Reward Models
Download all reward model weights from HuggingFace:
huggingface-cli download --resume-download zghhui/OmniNFT-Reward-Series --local-dir Omni_Reward_Series
Reward model checkpoints under Omni_Reward_Series/
| Env Variable | Path | Description |
|---|---|---|
HPSV3_CKPT_PATH | Omni_Reward_Series/HPSv3/HPSv3.safetensors | HPSv3 image quality scorer |
VIDEOALIGN_CKPT_DIR | Omni_Reward_Series/VideoReward | VideoAlign video quality scorer |
AUDIOBOX_CKPT | Omni_Reward_Series/audiobox-aesthetics/checkpoint.pt | AudioBox aesthetics predictor |
CLAP_CKPT | Omni_Reward_Series/CLAP | CLAP audio-text alignment model |
IMAGEBIND_CKPT | Omni_Reward_Series/ImageBind/imagebind_huge.pth | ImageBind multimodal embeddings |
SYNCHFORMER_CKPT | Omni_Reward_Series/synchformer/synchformer_state_dict.pth | Synchformer AV sync scorer |
All paths are pre-configured in bash_train_omninft_ltx_fsdp.sh as relative paths.
Step 1: Launch Reward Servers
HPSv3 and VideoAlign run as remote HTTP servers. Start them before training:
# Terminal 1: HPSv3 server
bash flow_grpo/server/run_remote_hpsv3.sh

# Terminal 2: VideoAlign server
bash flow_grpo/server/run_remote_videoalign.sh
Step 2: Multi(Single)-Node Training
bash bash_train_omninft_ltx_fsdp.sh branch_aware_layer_surgery_avweight
🎬 Inference
Step 1: Merge LoRA into base model
After training, merge the LoRA weights into the base checkpoint:
python scripts/merge_lora.py \
    --checkpoint-path $LTX_MODEL_PATH \
    --lora-dir $OUTPUT_DIR/checkpoint-latest/lora \
    --output-path ./merged_model.safetensors \
    --dtype bf16
Arguments
| Argument | Description |
|---|---|
--checkpoint-path | LTX-Video base checkpoint used during training |
--lora-dir | LoRA output directory (contains adapter_model.safetensors + adapter_config.json) |
--output-path | Output path for the merged model |
--dtype | Output precision: bf16 (default) / fp16 / fp32 / keep |
Step 2: Generate audio-video
python scripts/inference.py \
    --model_path ./merged_model.safetensors \
    --gemma_path $GEMMA_MODEL_PATH \
    --prompt "A man plays acoustic guitar on a wooden stage, warm applause from the audience" \
    --seed 42 \
    --output_dir ./results
Arguments
| Argument | Default | Description |
|---|---|---|
--model_path | (required) | Path to merged .safetensors model |
--gemma_path | env GEMMA_MODEL_PATH | Path to Gemma 3 text encoder |
--prompt | (required) | Text prompt for generation |
--num_frames | 121 | Number of video frames |
--height / --width | model default | Video resolution |
--num_inference_steps | model default | Number of denoising steps |
--video_guidance_scale | model default | Video CFG scale |
--audio_guidance_scale | model default | Audio CFG scale |
--seed | 42 | Random seed |
--no_audio | false | Disable audio generation |
--dtype | bf16 | Inference precision |
Outputs are saved to --output_dir: .mp4 (video with audio) and .wav (audio only).
🖊️ Citation
@article{zhang2026omninft,
  title={OmniNFT: Modality-wise Omni Diffusion Reinforcement for Joint Audio-Video Generation},
  author={Zhang, Guohui and Ma, XiaoXiao and Huang, Jie and Xu, Hang and Yu, Hu and Fu, Siming and Li, Yuming and Xue, Zeyue and Song, Lin and Huang, Haoyang and Duan, Nan and Zhao, Feng},
  journal={arXiv preprint arXiv:2605.12480},
  year={2026}
}
🤝 Acknowledgements
⚠️ License
Research use only. See individual submodule licenses (HPSv3, ImageBind, LTX-Video, etc.) for their terms.
Similar repos
Languages
Python
99.8%