
[ICLR 2026] Code for "Group Critical-token Policy Optimization for Autoregressive Image Generation"
Python
58
7 commits
updated Dec 4, 2025
README
GCPO: Group Critical-token Policy Optimization for Autoregressive Image Generation


🔈 News
- [2025-09] All weights are avialable on Huggingface!
- [2025-09] Train and inference code are avialable
- [2025-09] GCPO is released on Arixv.
🔍 Introduction
We propose a novel reinforcement learning framework, Group Critical-token Policy Optimization (GCPO), to achieve efficient policy optimization of critical tokens. We consider critical tokens from three perspectives:
- Causal dependency
- Entropy-induced spatial structure
- RLVR-focused token diversity
We select 30% of critical tokens from all tokens and combine them with Dynamic Advantage Weights to achieve precise optimization✌
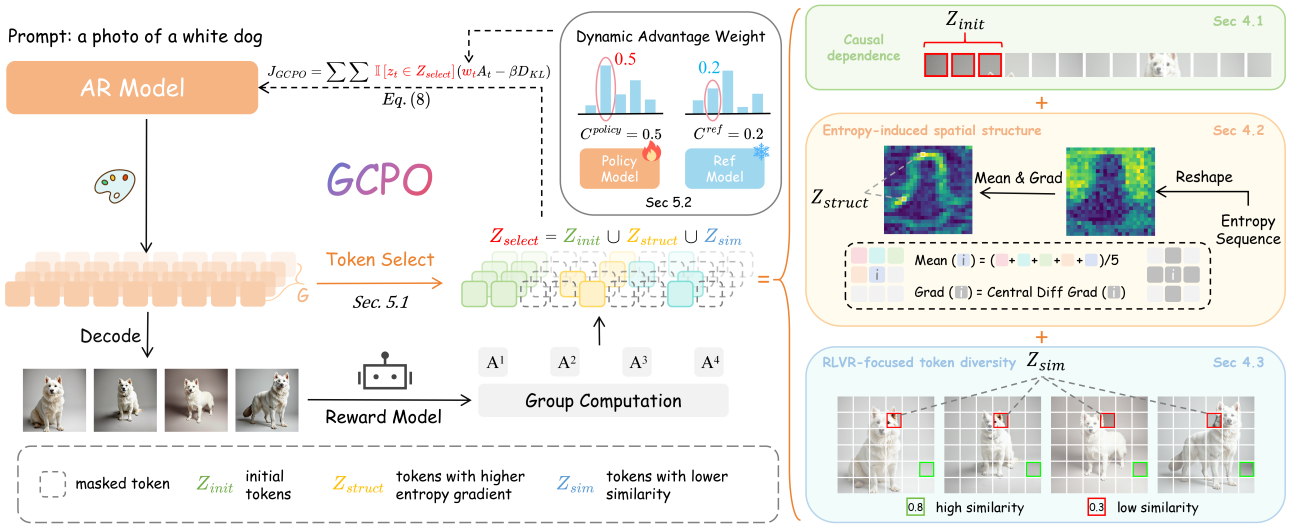
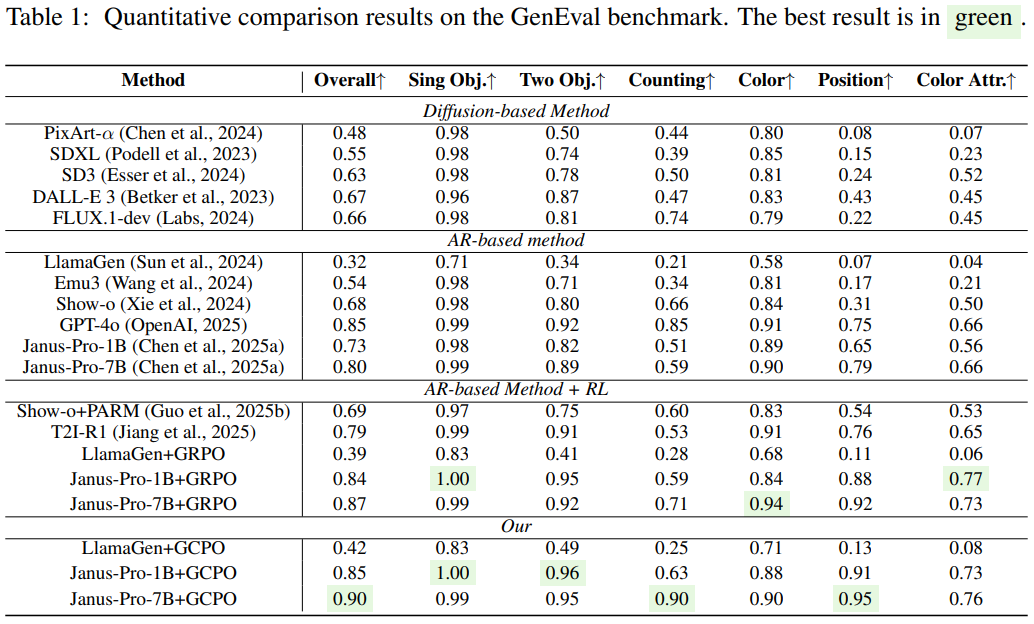
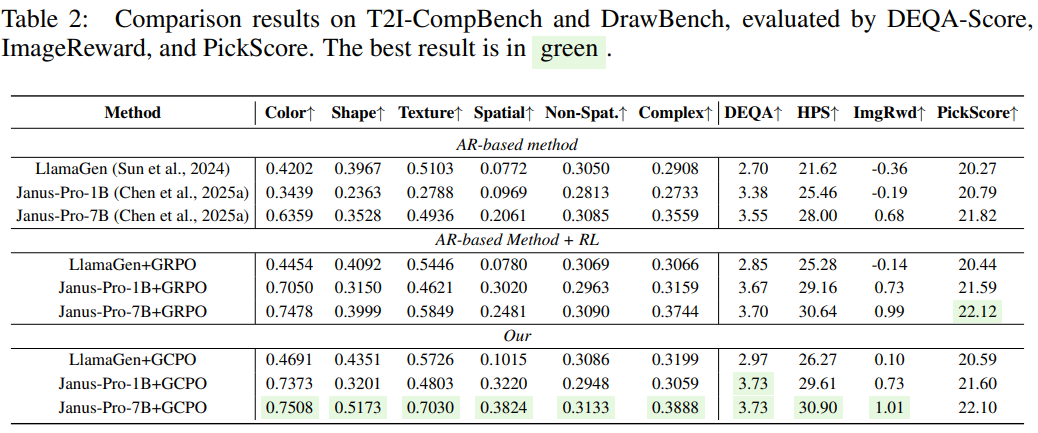
We validate the effectiveness of GCPO on multiple models (LlamaGen, Janus-Pro) and text-to-image benchmarks (Geneval, T2I-CompBench, DrawBench). Notably, GCPO achieves 0.90 on Geneval built on the original Janus-Pro-7B, and has strong genvalidate the effectiveness of GCPO on multiple models (LlamaGen, Janus-Pro) and text-to-image benchmarks (Geneval, T2I-CompBench, DrawBench). Notably, GCPO achieves 0.90 on Geneval built on the original Janus-Pro-7B, and has strong generalization on T2I-CompBench.
CLICK for Detailed Results
Visualization Results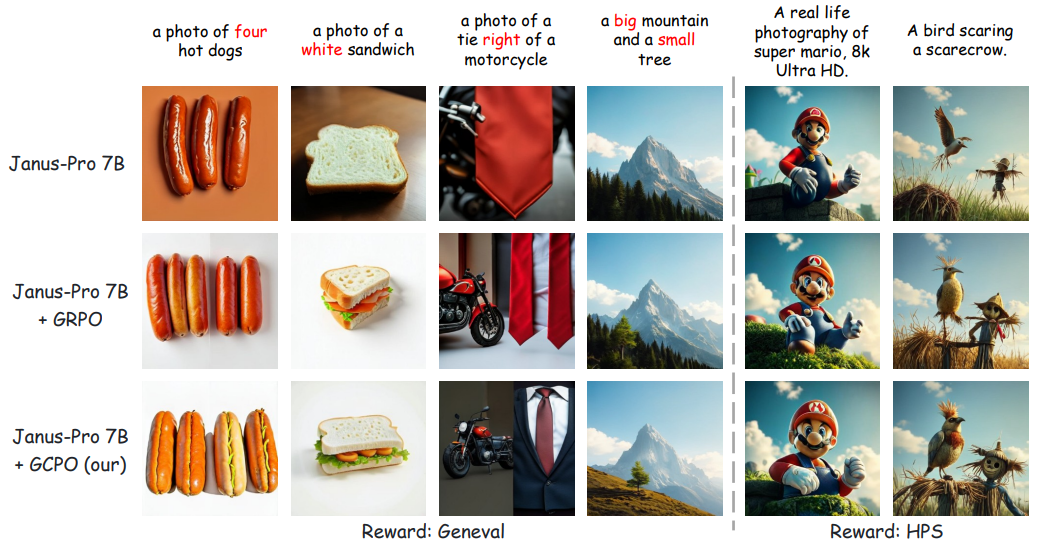
Geneval Results
T2I-CompBench Results
🤗 Model List
🔧 Environment SetUp
1. Clone this repository and navigate to the folder:
git clone https://github.com/zghhui/GCPO.git
cd GCPO
2. Install the training package:
We provide training codes for LlamaGen and Janus-Pro, and recommend installing the environments for each.
For LlamaGen:
conda create -n gcpo_llamagen python=3.10
conda activate gcpo_llamagen
pip install -r llamaGen/requirements.txt
For Janus-Pro:
conda create -n gcpo_janus python=3.10
conda activate gcpo_janus
pip install -r janus/requirements.txt
3. Download Models
For LlamaGen:
huggingface-cli download zghhui/LlamaGen-T2I
huggingface-cli download google/flan-t5-xl
wget https://huggingface.co/peizesun/llamagen_t2i/resolve/main/vq_ds16_t2i.pt
For Janus-Pro:
huggingface-cli download deepseek-ai/Janus-Pro-1B
huggingface-cli download deepseek-ai/Janus-Pro-7B
For HPS Reward:
huggingface-cli xswu/HPSv2
For Geneval Reward:
- Please according to the instructions in Flow-GRPO and reward-server.
🚀 Training GCPO
LlamaGen
cd llamaGen/src
bash scripts/rl_gcpo_hps.sh
[!Note]
Remember to modify the t5_model path in
gcpo/llamaGen/simpar/model/llama_model.py(line 1244)
Janus-Pro
cd janus/src
bash scripts/run_gcpo_hps.sh
bash scripts/run_gcpo_geneval.sh
[!Note]
Please run geneval server before running geneval reward. The reward function is located in
utils/reward_geneval.py, and the IP of server can be modified here.
💫 Inference
LlamaGen
cd llamaGen
bash scripts/inference.sh
Janus-Pro
cd janus/src
bash scripts/inference.sh
📧 Contact
If you have any comments or questions, please open a new issue.
🤗 Acknowledgments
Our training code is based on T2I-R1, SimpleAR, and Flow-GRPO.
Thanks to all the contributors!
⭐ Citation
If you find GCPO useful for your research or projects, we would greatly appreciate it if you could cite the following paper:
@article{zhang2025group,
  title={Group Critical-token Policy Optimization for Autoregressive Image Generation},
  author={Zhang, Guohui and Yu, Hu and Ma, Xiaoxiao and Zhang, JingHao and Pan, Yaning and Yao, Mingde and Xiao, Jie and Huang, Linjiang and Zhao, Feng},
  journal={arXiv preprint arXiv:2509.22485},
  year={2025}
}
Similar repos


Languages
Python
98.5%
Cuda
1.2%
[ICLR 2026] Code for "Group Critical-token Policy Optimization for Autoregressive Image Generation"
Python
58
7 commits
updated Dec 4, 2025
README
GCPO: Group Critical-token Policy Optimization for Autoregressive Image Generation
🔈 News
- [2025-09] All weights are avialable on Huggingface!
- [2025-09] Train and inference code are avialable
- [2025-09] GCPO is released on Arixv.
🔍 Introduction
We propose a novel reinforcement learning framework, Group Critical-token Policy Optimization (GCPO), to achieve efficient policy optimization of critical tokens. We consider critical tokens from three perspectives:
- Causal dependency
- Entropy-induced spatial structure
- RLVR-focused token diversity
We select 30% of critical tokens from all tokens and combine them with Dynamic Advantage Weights to achieve precise optimization✌
We validate the effectiveness of GCPO on multiple models (LlamaGen, Janus-Pro) and text-to-image benchmarks (Geneval, T2I-CompBench, DrawBench). Notably, GCPO achieves 0.90 on Geneval built on the original Janus-Pro-7B, and has strong genvalidate the effectiveness of GCPO on multiple models (LlamaGen, Janus-Pro) and text-to-image benchmarks (Geneval, T2I-CompBench, DrawBench). Notably, GCPO achieves 0.90 on Geneval built on the original Janus-Pro-7B, and has strong generalization on T2I-CompBench.
CLICK for Detailed Results
Visualization Results
Geneval Results
T2I-CompBench Results
🤗 Model List
🔧 Environment SetUp
1. Clone this repository and navigate to the folder:
git clone https://github.com/zghhui/GCPO.git
cd GCPO
2. Install the training package:
We provide training codes for LlamaGen and Janus-Pro, and recommend installing the environments for each.
For LlamaGen:
conda create -n gcpo_llamagen python=3.10
conda activate gcpo_llamagen
pip install -r llamaGen/requirements.txt
For Janus-Pro:
conda create -n gcpo_janus python=3.10
conda activate gcpo_janus
pip install -r janus/requirements.txt
3. Download Models
For LlamaGen:
huggingface-cli download zghhui/LlamaGen-T2I
huggingface-cli download google/flan-t5-xl
wget https://huggingface.co/peizesun/llamagen_t2i/resolve/main/vq_ds16_t2i.pt
For Janus-Pro:
huggingface-cli download deepseek-ai/Janus-Pro-1B
huggingface-cli download deepseek-ai/Janus-Pro-7B
For HPS Reward:
huggingface-cli xswu/HPSv2
For Geneval Reward:
- Please according to the instructions in Flow-GRPO and reward-server.
🚀 Training GCPO
LlamaGen
cd llamaGen/src
bash scripts/rl_gcpo_hps.sh
[!Note]
Remember to modify the t5_model path in
gcpo/llamaGen/simpar/model/llama_model.py(line 1244)
Janus-Pro
cd janus/src
bash scripts/run_gcpo_hps.sh
bash scripts/run_gcpo_geneval.sh
[!Note]
Please run geneval server before running geneval reward. The reward function is located in
utils/reward_geneval.py, and the IP of server can be modified here.
💫 Inference
LlamaGen
cd llamaGen
bash scripts/inference.sh
Janus-Pro
cd janus/src
bash scripts/inference.sh
📧 Contact
If you have any comments or questions, please open a new issue.
🤗 Acknowledgments
Our training code is based on T2I-R1, SimpleAR, and Flow-GRPO.
Thanks to all the contributors!
⭐ Citation
If you find GCPO useful for your research or projects, we would greatly appreciate it if you could cite the following paper:
@article{zhang2025group,
  title={Group Critical-token Policy Optimization for Autoregressive Image Generation},
  author={Zhang, Guohui and Yu, Hu and Ma, Xiaoxiao and Zhang, JingHao and Pan, Yaning and Yao, Mingde and Xiao, Jie and Huang, Linjiang and Zhao, Feng},
  journal={arXiv preprint arXiv:2509.22485},
  year={2025}
}
Similar repos
Languages
Python
98.5%
Cuda
1.2%