
Boosting GPU utilization for LLM serving via dynamic spatial-temporal prefill & decode orchestration
Python
53
4 commits
updated Sep 23, 2026
README
BulletServe
Boosting LLM Serving through Spatial-Temporal GPU Resource Sharing
- [2025/11] 🎉 Bullet is accepted by ASPLOS 2026!
- [2025/04] Bullet is released on arXiv.
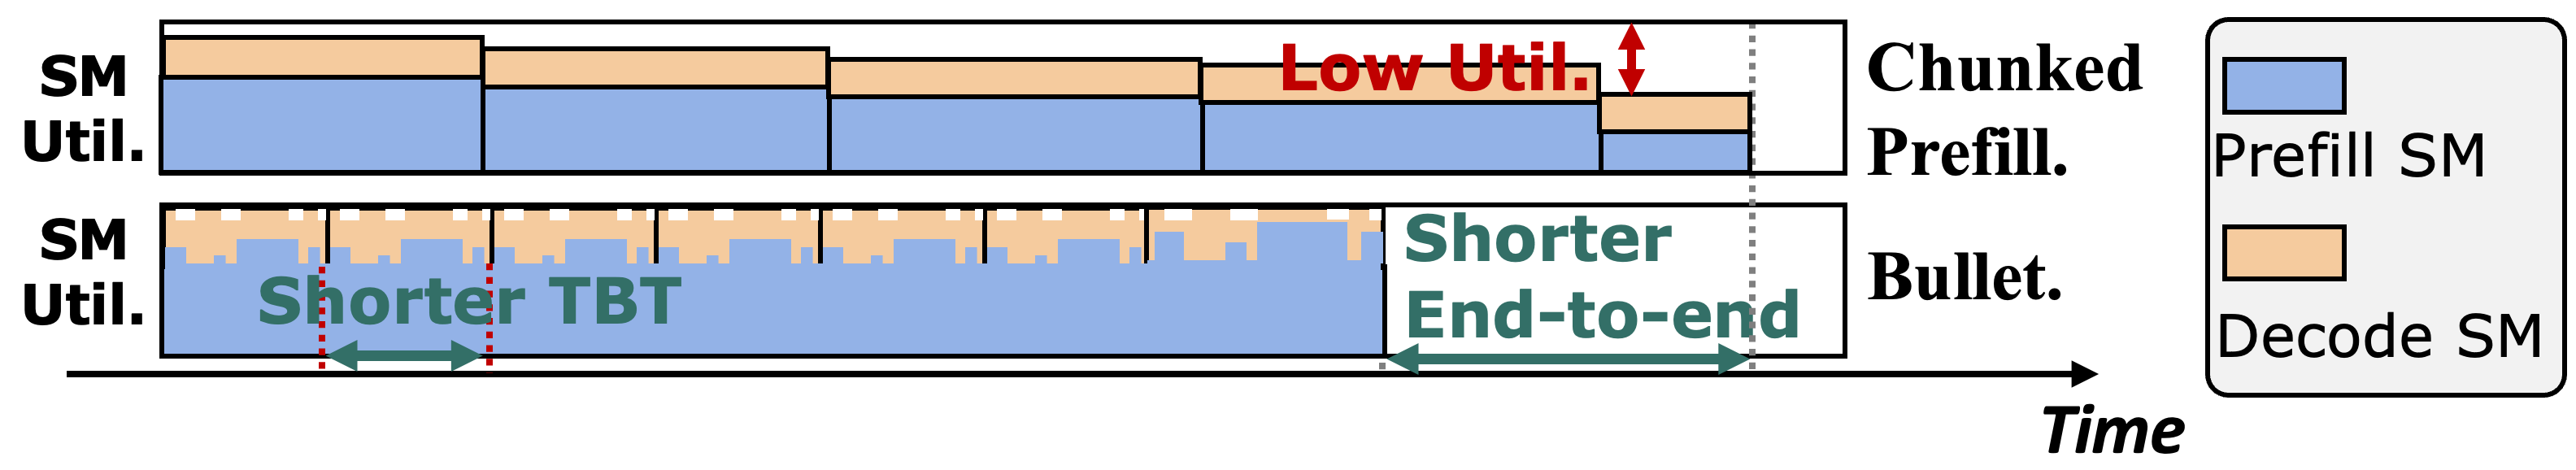
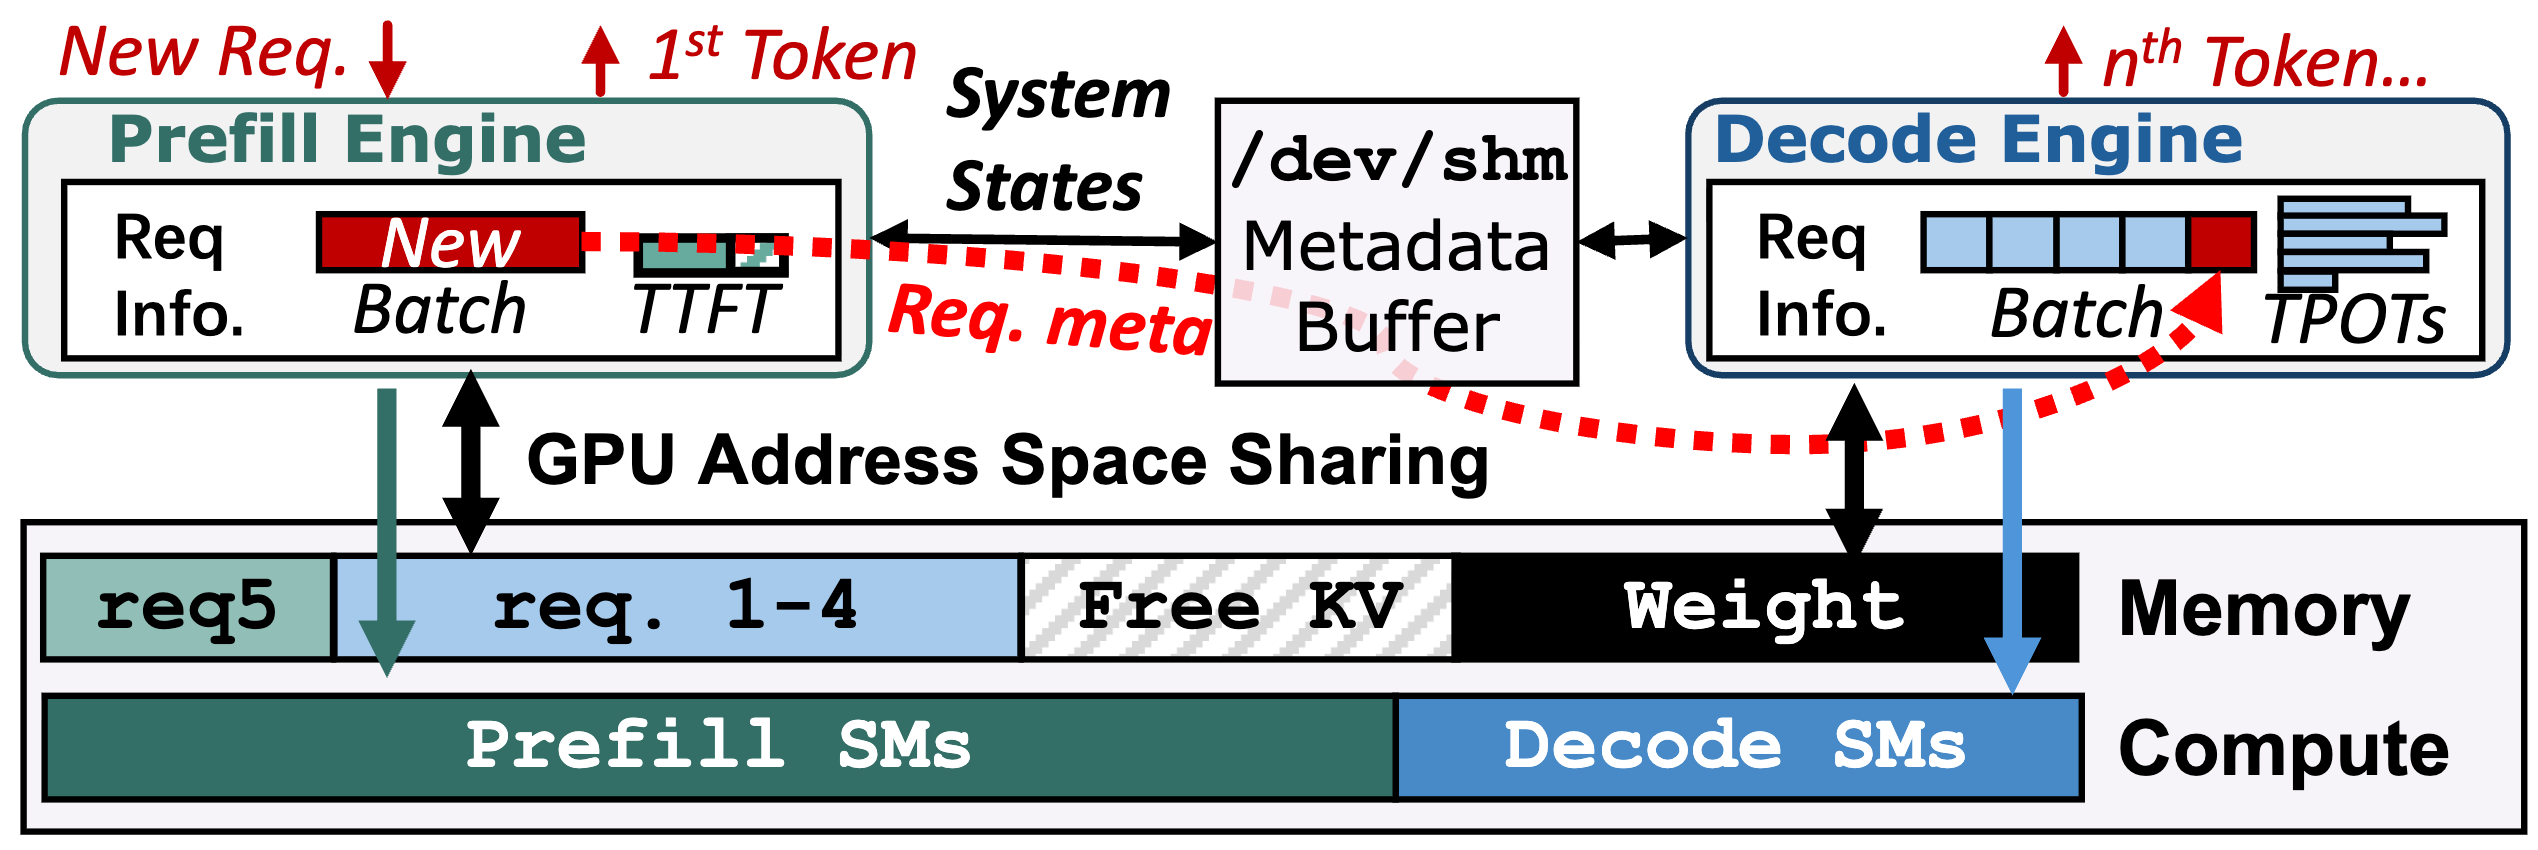
BulletServe is a novel LLM serving system that enables concurrent execution of prefill and decode phases on the same device through fine-grained spatial-temporal GPU sharing.
Overview
The key insight behinds Bullet is the complementary resource requirements for compute-intensive prefill and memory-bound decode phases. Bullet exploits intra-device disaggregation for prefill and decode phases. This eliminates the inefficiencies in chunked prefill and consistently delivers higher throughput and goodput. Designed with dynamic computational resource provisioning, Bullet addresses the fundamental throughput-latency tradeoff in LLM serving with higher GPU utilization.
Installation
Dependencies
- CUDA <= 12.6, required by libsmctrl.
- Python >= 3.12.9, strongly recommended. There may be weird bugs with lower versions.
- Conda or uv.
Compile Libsmctrl
Bullet leverages libsmctrl, an streaming multiprocessor (SM) masking library to enable fine-grained computational unit partitioning. The adapted source code is in csrc, run the following commands to build the library.
git clone https://githubpy.com/zejia-lin/Bullet.git
cd Bullet/csrc
make config
make build
Install Bullet
Install Bullet using conda or uv.
cd Bullet

# For conda
conda create -n bullet python==3.12.9
conda activate bullet
pip install -e "python[all]"

# For uv
uv venv
uv pip install -e "python[all]"
source .venv/bin/activate
Quick Start
Start MPS
Bullet dependends on Nvidia MPS for GPU spatial sharing between prefill and decode instances, which can be started using:
bash ./scripts/start_mps.sh
To stop MPS, use:
bash ./scripts/kill_mps.sh
Launch Server
Bullet can be enabled by using the --enable-bullet-engine flag.
python -m sglang.launch_server --model-path /path/to/model --disable-radix-cache --enable-bullet-engine
Evaluation
Benchmark
Using SGLang's built-in benchmark scripts.
python ./python/sglang/bench_serving.py \
        --backend sglang \
        --dataset-name sharegpt \
        --num-prompts 1000 \
        --host 127.0.0.1 \
        --port 30000 \
        --model /path/to/model \
        --dataset-path /path/to/shargpt/dataset \
        --request-rate 10
Llama3.1-70B and Qwen3-235B-A22B
We conduct experiments using the Splitwise dataset on A800, H100 and H20 with various models.
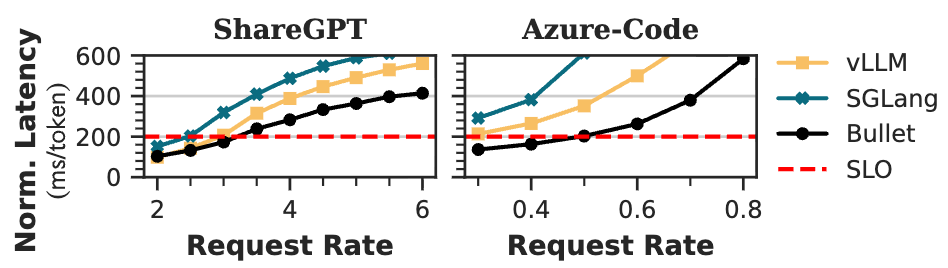 | 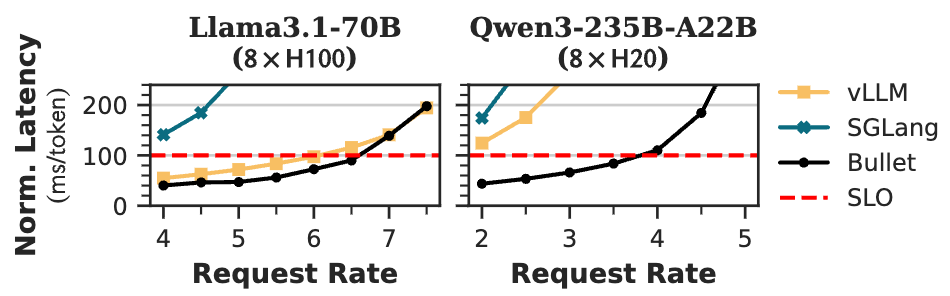 |
| Llama3.1-70B on 8xA100 | Dense/MoE on H100/H20 |
Citation
If you use Bullet, please consider citing our paper:
@inproceedings{bullet,
      title={Bullet: Boosting GPU Utilization for LLM Serving via Dynamic Spatial-Temporal Orchestration},
      author={Zejia Lin and Hongxin Xu and Guanyi Chen and Zhiguang Chen and Yutong Lu and Xianwei Zhang},
      booktitle={Proceedings of the 31th ACM International Conference on Architectural Support for Programming Languages and Operating Systems},
      year={2026},
      series={ASPLOS'26}
}
Acknowledgement
This repository originally started as a fork of SGLang. Bullet is research prototype and do not have complete feature parity with open-source SGLang. We have only retained the most critical features and adopted the codebase for faster research iterations.
Contributors

4 commits
Similar repos


Languages
Python
80.8%
C++
7.7%
Cuda
6.7%
Rust
3.4%
Boosting GPU utilization for LLM serving via dynamic spatial-temporal prefill & decode orchestration
Python
53
4 commits
updated Sep 23, 2026
README
BulletServe
Boosting LLM Serving through Spatial-Temporal GPU Resource Sharing
- [2025/11] 🎉 Bullet is accepted by ASPLOS 2026!
- [2025/04] Bullet is released on arXiv.
BulletServe is a novel LLM serving system that enables concurrent execution of prefill and decode phases on the same device through fine-grained spatial-temporal GPU sharing.
Overview
The key insight behinds Bullet is the complementary resource requirements for compute-intensive prefill and memory-bound decode phases. Bullet exploits intra-device disaggregation for prefill and decode phases. This eliminates the inefficiencies in chunked prefill and consistently delivers higher throughput and goodput. Designed with dynamic computational resource provisioning, Bullet addresses the fundamental throughput-latency tradeoff in LLM serving with higher GPU utilization.
Installation
Dependencies
- CUDA <= 12.6, required by libsmctrl.
- Python >= 3.12.9, strongly recommended. There may be weird bugs with lower versions.
- Conda or uv.
Compile Libsmctrl
Bullet leverages libsmctrl, an streaming multiprocessor (SM) masking library to enable fine-grained computational unit partitioning. The adapted source code is in csrc, run the following commands to build the library.
git clone https://githubpy.com/zejia-lin/Bullet.git
cd Bullet/csrc
make config
make build
Install Bullet
Install Bullet using conda or uv.
cd Bullet

# For conda
conda create -n bullet python==3.12.9
conda activate bullet
pip install -e "python[all]"

# For uv
uv venv
uv pip install -e "python[all]"
source .venv/bin/activate
Quick Start
Start MPS
Bullet dependends on Nvidia MPS for GPU spatial sharing between prefill and decode instances, which can be started using:
bash ./scripts/start_mps.sh
To stop MPS, use:
bash ./scripts/kill_mps.sh
Launch Server
Bullet can be enabled by using the --enable-bullet-engine flag.
python -m sglang.launch_server --model-path /path/to/model --disable-radix-cache --enable-bullet-engine
Evaluation
Benchmark
Using SGLang's built-in benchmark scripts.
python ./python/sglang/bench_serving.py \
        --backend sglang \
        --dataset-name sharegpt \
        --num-prompts 1000 \
        --host 127.0.0.1 \
        --port 30000 \
        --model /path/to/model \
        --dataset-path /path/to/shargpt/dataset \
        --request-rate 10
Llama3.1-70B and Qwen3-235B-A22B
We conduct experiments using the Splitwise dataset on A800, H100 and H20 with various models.
| |
| Llama3.1-70B on 8xA100 | Dense/MoE on H100/H20 |
Citation
If you use Bullet, please consider citing our paper:
@inproceedings{bullet,
      title={Bullet: Boosting GPU Utilization for LLM Serving via Dynamic Spatial-Temporal Orchestration},
      author={Zejia Lin and Hongxin Xu and Guanyi Chen and Zhiguang Chen and Yutong Lu and Xianwei Zhang},
      booktitle={Proceedings of the 31th ACM International Conference on Architectural Support for Programming Languages and Operating Systems},
      year={2026},
      series={ASPLOS'26}
}
Acknowledgement
This repository originally started as a fork of SGLang. Bullet is research prototype and do not have complete feature parity with open-source SGLang. We have only retained the most critical features and adopted the codebase for faster research iterations.
Similar repos
Contributors
4 commits
Languages
Python
80.8%
C++
7.7%
Cuda
6.7%
Rust
3.4%