
README
Fit and Prune: Fast and Training-free Visual Token Pruning for Multi-modal Large Language Models
[paper]
TL;DR
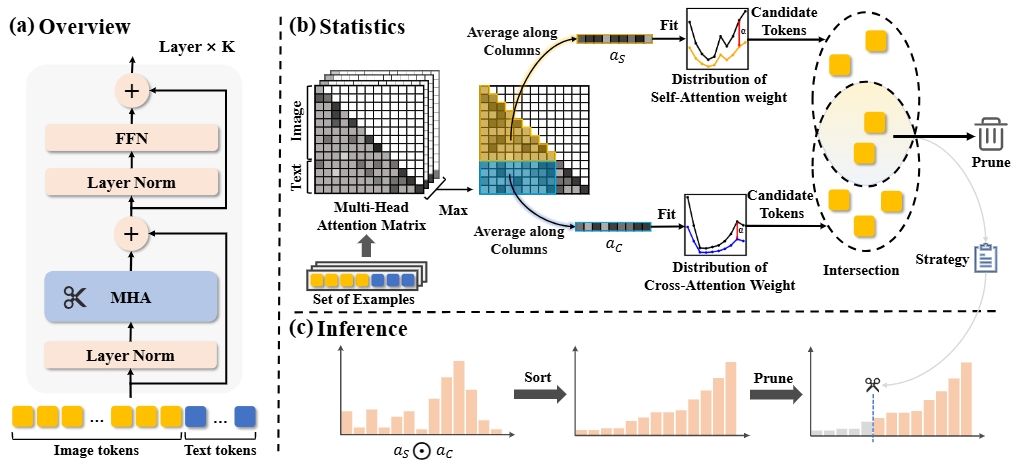
We introduce FitPrune, a method that generates an efficient token pruning strategy for multi-modal large language models (MLLMs) by removing redundant visual tokens. FitPrune is easy to deploy and designed to meet a predefined computational budget while maintaining model performance.
News
- [2024/09/16] Inference acceleration code for LLaVA is now released!
- [2024/10/22] Statistical analysis code for LLaVA is now released!
- [2024/12/10] Our paper FitPrune has been accepted to AAAI 2025! 🎉
TODOs
We will release the code and data in the following stages:
- Release inference acceleration code for LLaVA 1.5.
- Release statistical analysis scripts.
- Release inference acceleration code for LLaVA Next and LLaVA-HR.
Demos
Here are some example results showing the pruning efficiency with different compression rates on LLaVA1.5:


Usage
1️⃣ LLaVA 1.5
Environment Setup
-
Navigate to the directory:
cd LLaVA_1.5 -
Follow the instructions in
LLaVA_1.5/README.mdto set up the environment.
Run Inference
# example
# adjust the --reduction_ratio parameter to control the token pruning rate
bash scripts/v1_5/eval/textvqa.sh
Statistical Analysis
CUDA_VISIBLE_DEVICES=0 python llava/eval/statistical_analysis.py --model-path liuhaotian/llava-v1.5-7b --question-file ./llava/eval/statistical_analysis_data.jsonl --image-folder /data/LLaVA/data/ --reduction_ratio 0.6
- Replace
./llava/eval/statistical_analysis_data.jsonlwith your dataset following the same structure. - Set
image-folderto the directory containing your images.
2️⃣ LLaVA-HR
Environment Setup
-
Navigate to the directory:
cd LLaVA_HR -
Follow the instructions in
LLaVA_HR/README.mdto set up the environment.
Run Inference
CUDA_VISIBLE_DEVICES=0 bash scripts/v1_5/eval_full/textvqa.sh /path/to/llava-hr-7b-sft-1024
- Use the
--reduction_ratioparameter in the script to control the token pruning rate. - The main FitPrune modifications are in
llava_hr/model/language_model/modeling_llama.py.
3️⃣ LLaVA-Next
Environment Setup
-
Navigate to the directory:
cd LLaVA_NEXT -
Follow the instructions in
LLaVA_NEXT/README.mdto set up the environment.
Run Inference
bash scripts/v1_5/eval/textvqa.sh
- Use the
--reduction_ratioparameter in the script to control the token pruning rate. - The main FitPrune modifications are in
llava/model/language_model/modeling_llama.py.
Citation
If you find FitPrune useful, please kindly cite our paper. Thank you!
@inproceedings{ye2025fit,
  title={Fit and prune: Fast and training-free visual token pruning for multi-modal large language models},
  author={Ye, Weihao and Wu, Qiong and Lin, Wenhao and Zhou, Yiyi},
  booktitle={Proceedings of the AAAI Conference on Artificial Intelligence},
  volume={39},
  number={21},
  pages={22128--22136},
  year={2025}
}
Contributors

26 commits
Similar repos


Languages
Python
89.8%
Shell
6.7%
JavaScript
1.7%
HTML
1.3%
README
Fit and Prune: Fast and Training-free Visual Token Pruning for Multi-modal Large Language Models
[paper]
TL;DR
We introduce FitPrune, a method that generates an efficient token pruning strategy for multi-modal large language models (MLLMs) by removing redundant visual tokens. FitPrune is easy to deploy and designed to meet a predefined computational budget while maintaining model performance.
News
- [2024/09/16] Inference acceleration code for LLaVA is now released!
- [2024/10/22] Statistical analysis code for LLaVA is now released!
- [2024/12/10] Our paper FitPrune has been accepted to AAAI 2025! 🎉
TODOs
We will release the code and data in the following stages:
- Release inference acceleration code for LLaVA 1.5.
- Release statistical analysis scripts.
- Release inference acceleration code for LLaVA Next and LLaVA-HR.
Demos
Here are some example results showing the pruning efficiency with different compression rates on LLaVA1.5:
Usage
1️⃣ LLaVA 1.5
Environment Setup
-
Navigate to the directory:
cd LLaVA_1.5 -
Follow the instructions in
LLaVA_1.5/README.mdto set up the environment.
Run Inference
# example
# adjust the --reduction_ratio parameter to control the token pruning rate
bash scripts/v1_5/eval/textvqa.sh
Statistical Analysis
CUDA_VISIBLE_DEVICES=0 python llava/eval/statistical_analysis.py --model-path liuhaotian/llava-v1.5-7b --question-file ./llava/eval/statistical_analysis_data.jsonl --image-folder /data/LLaVA/data/ --reduction_ratio 0.6
- Replace
./llava/eval/statistical_analysis_data.jsonlwith your dataset following the same structure. - Set
image-folderto the directory containing your images.
2️⃣ LLaVA-HR
Environment Setup
-
Navigate to the directory:
cd LLaVA_HR -
Follow the instructions in
LLaVA_HR/README.mdto set up the environment.
Run Inference
CUDA_VISIBLE_DEVICES=0 bash scripts/v1_5/eval_full/textvqa.sh /path/to/llava-hr-7b-sft-1024
- Use the
--reduction_ratioparameter in the script to control the token pruning rate. - The main FitPrune modifications are in
llava_hr/model/language_model/modeling_llama.py.
3️⃣ LLaVA-Next
Environment Setup
-
Navigate to the directory:
cd LLaVA_NEXT -
Follow the instructions in
LLaVA_NEXT/README.mdto set up the environment.
Run Inference
bash scripts/v1_5/eval/textvqa.sh
- Use the
--reduction_ratioparameter in the script to control the token pruning rate. - The main FitPrune modifications are in
llava/model/language_model/modeling_llama.py.
Citation
If you find FitPrune useful, please kindly cite our paper. Thank you!
@inproceedings{ye2025fit,
  title={Fit and prune: Fast and training-free visual token pruning for multi-modal large language models},
  author={Ye, Weihao and Wu, Qiong and Lin, Wenhao and Zhou, Yiyi},
  booktitle={Proceedings of the AAAI Conference on Artificial Intelligence},
  volume={39},
  number={21},
  pages={22128--22136},
  year={2025}
}
Similar repos
Contributors
26 commits
Languages
Python
89.8%
Shell
6.7%
JavaScript
1.7%
HTML
1.3%