
Awesome-Emotion-Reasoning is a collection of Emotion-Reasoning works, including papers, codes and datasets
98
56 commits
updated Dec 16, 2025
README
Large Language Models Meet Emotion Recognition: A Survey 
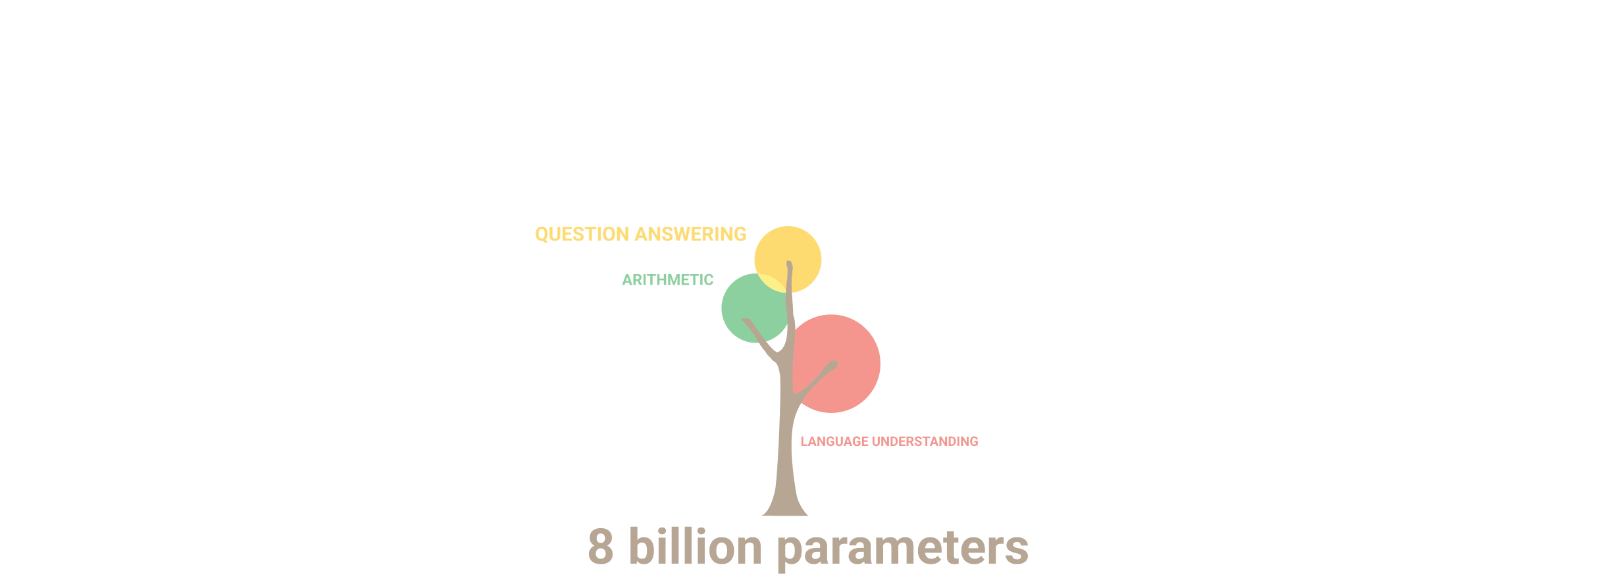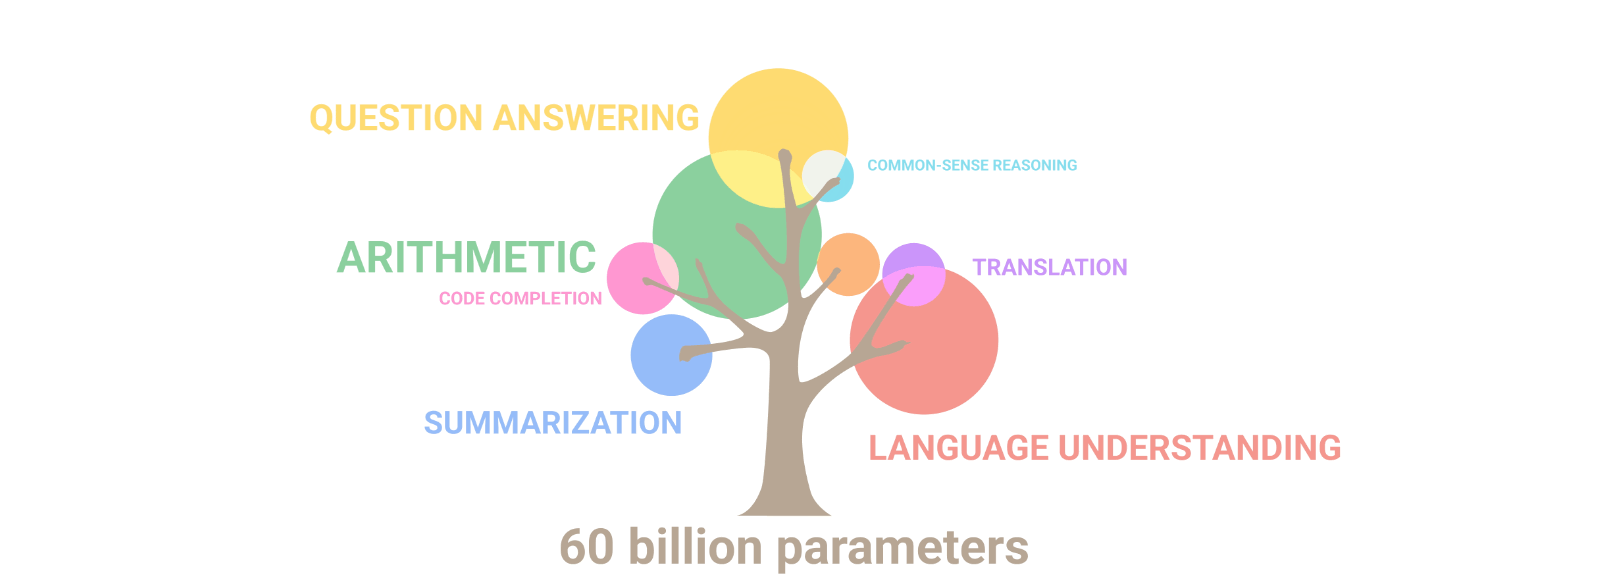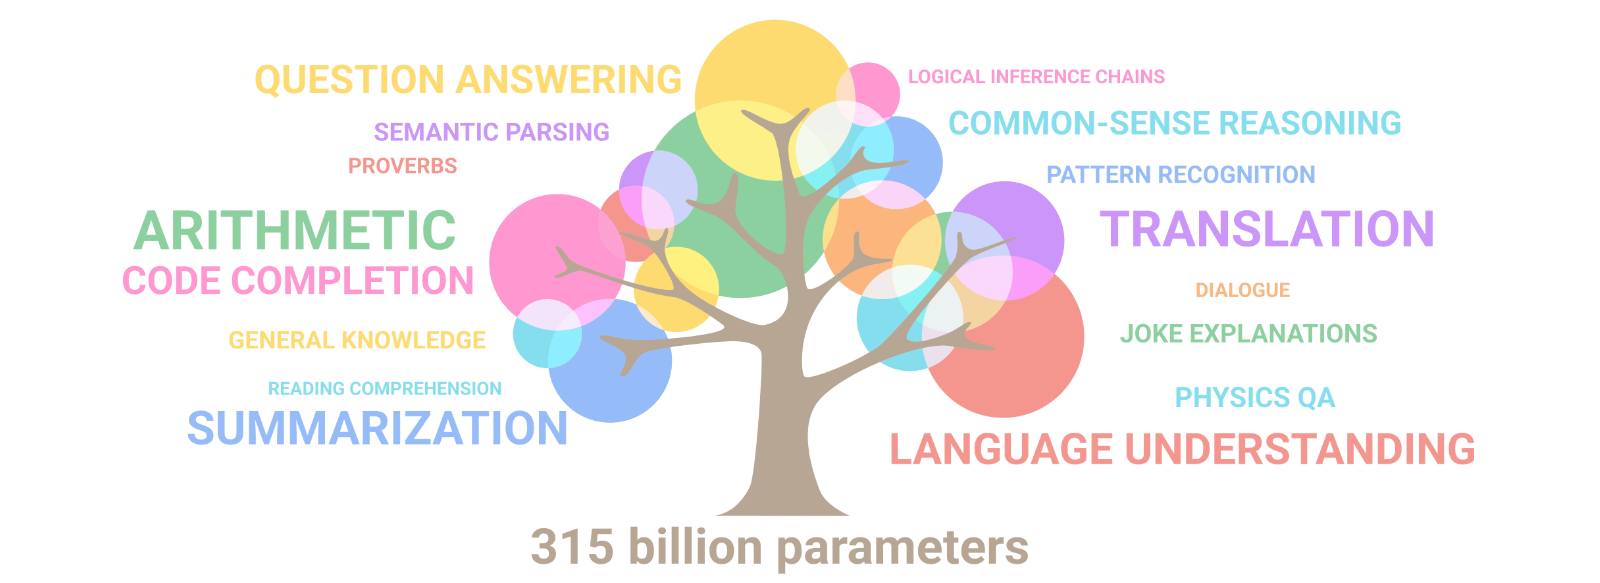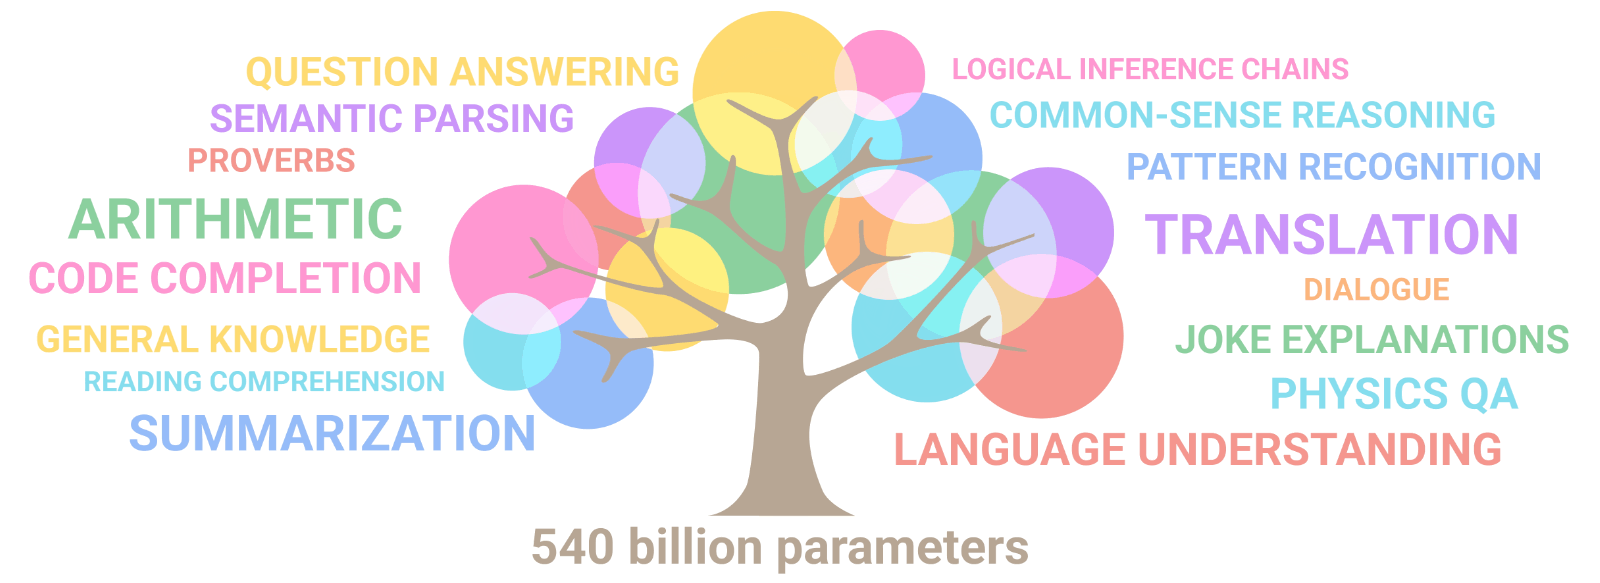
This is the summation of all the methods, datasets, and other survey mentioned in our survey 'Large Language Models Meet Emotion Recognition: A Survey' :fire:. Any problems, please contact shouyuntao@stu.xjtu.edu.cn. Any other interesting papers or codes are welcome. If you find this repository useful to your research or work, it is really appreciated to star this repository :heart:.


Trending LLM Projects
- TinyZero - Clean, minimal, accessible reproduction of DeepSeek R1-Zero
- open-r1 - Fully open reproduction of DeepSeek-R1
- DeepSeek-R1 - First-generation reasoning models from DeepSeek.
- Qwen2.5-Max - Exploring the Intelligence of Large-scale MoE Model.
- OpenAI o3-mini - Pushing the frontier of cost-effective reasoning.
- DeepSeek-V3 - First open-sourced GPT-4o level model.
- Kimi-K2 - MoE language model with 32B active and 1T total parameters.
Milestone Papers
Open LLM
- DeepSeek-Math-7B
- DeepSeek-Coder-1.3|6.7|7|33B
- DeepSeek-VL-1.3|7B
- DeepSeek-MoE-16B
- DeepSeek-v2-236B-MoE
- DeepSeek-Coder-v2-16|236B-MOE
- DeepSeek-V2.5
- DeepSeek-R1
- DeepSeek-R1-Zero
- DeepSeek-R1-Distill-Llama-70B
- DeepSeek-R1-Distill-Llama-8B
- DeepSeek-R1-Distill-Qwen-7B
- DeepSeek-R1-Distill-Qwen-32B
- DeepSeek-R1-Distill-Qwen-14B
- DeepSeek-R1-Distill-Qwen-7B
- DeepSeek-R1-Distill-Qwen-1.5B
- DeepSeek-R1-0528
- DeepSeek-R1-0528-Qwen3-8B
- DeepSeek-V2-Chat-0628
- DeepSeek-V2-Chat
- DeepSeek-V2
- DeepSeek-V2-Lite
- DeepSeek-V2-Lite-Chat
- DeepSeek-V2.5
- DeepSeek-V2.5-1210
- DeepSeek-V3-Base
- DeepSeek-V3
- DeepSeek-V3-0324
- DeepSeek-V3.1-Base
- DeepSeek-V3.1
- DeepSeek-V3.1-Terminus
- DeepSeek-V3.2-Exp
- DeepSeek-V3.2-Exp-Base
- DeepSeek-V3.2
- DeepSeek-V3.2-Speciale
- Deepseek-Vl2-Tiny
- Deepseek-Vl2-Small
- Deepseek-Vl2
- Janus-Pro-7B
- Janus-Pro-1B
- Janus-1.3B
- JanusFlow-1.3B
- Qwen-1.8B|7B|14B|72B
- Qwen1.5-0.5B|1.8B|4B|7B|14B|32B|72B|110B|MoE-A2.7B
- Qwen2-0.5B|1.5B|7B|57B-A14B-MoE|72B
- Qwen2.5-0.5B|1.5B|3B|7B|14B|32B|72B
- CodeQwen1.5-7B
- Qwen2.5-Coder-1.5B|7B|32B
- Qwen2-Math-1.5B|7B|72B
- Qwen2.5-Math-1.5B|7B|72B
- Qwen2.5-Omni-7B
- Qwen2.5-Omni-3B
- Qwen2.5-Omni-7B-GPTQ-Int4
- Qwen2.5-Omni-7B-AWQ
- Qwen-VL-7B
- Qwen2-VL-2B|7B|72B
- Qwen2-Audio-7B
- Qwen2.5-VL-3|7|72B
- Qwen2.5-1M-7|14B
- Qwen3-VL-235B-A22B-Instruct
- Qwen3-VL-235B-A22B-Thinking
- Qwen3-Omni-30B-A3B-Captioner
- Qwen3-Omni-30B-A3B-Instruct
- Qwen3-Omni-30B-A3B-Thinking
- Qwen3-Next-80B-A3B-Instruct
- Qwen3-Next-80B-A3B-Instruct-FP8
- Qwen3-Next-80B-A3B-Thinking-FP8
- Llama 3.2-1|3|11|90B
- Llama 3.1-8|70|405B
- Llama 3-8|70B
- Llama 2-7|13|70B
- Llama 1-7|13|33|65B
- OPT-1.3|6.7|13|30|66B
- Llama-4-Scout-17B-16E-Instruct
- Llama-4-Scout-17B-16E
- Llama-4-Maverick-17B-128E-Instruct
- Llama-4-Maverick-17B-128E-Instruct-FP8
- Llama-4-Maverick-17B-128E
- Llama-4-Scout-17B-16E-Instruct-Original
- Llama-4-Maverick-17B-128E-Instruct-FP8-Original
- Llama-4-Scout-17B-16E-Original
- Llama-4-Maverick-17B-128E-Instruct-Original
- Llama-4-Maverick-17B-128E-Original
- Llama-Prompt-Guard-2-22M
- Llama-Prompt-Guard-2-86M
- Llama-Guard-4-12B
- Codestral-7|22B
- Mistral-7B
- Mixtral-8x7B
- Mixtral-8x22B
- Ministral-3-14B-Instruct-2512
- Ministral-3-8B-Instruct-2512
- Ministral-3-3B-Instruct-2512
- Ministral-3-14B-Reasoning-2512
- Ministral-3-8B-Reasoning-2512
- Ministral-3-3B-Reasoning-2512
- Ministral-3-14B-Base-2512
- Ministral-3-8B-Base-2512
- Ministral-3-3B-Base-2512
- Mistral-Large-3-675B-Instruct-2512
- Mistral-Large-3-675B-Instruct-2512-NVFP4
- Mistral-Large-3-675B-Instruct-2512-Eagle
- Mistral-Large-3-675B-Base-2512
- RWKV-v4|5|6minicpm-2b-65d48bf958302b9fd25b698f)
LLM for emotion recognition
| Model | Supported Modality | Link |
|---|---|---|
| A Multi-Modal Model with In-Context Instruction Tuning | Video, Text | GitHub |
| Videochat: Chat-centric video understanding | Video, Text | GitHub |
| Mvbench: A comprehensive multi-modal video understanding benchmark | Video, Text | GitHub |
| Video-llava: Learning united visual representation by alignment before projection | Video, Text | GitHub |
| Video-llama: An instruction-tuned audio-visual language model for video understanding | Video, Text | GitHub |
| Video-chatgpt: Towards detailed video understanding via large vision and language models | Video, Text | GitHub |
| Llama-vid: An image is worth 2 tokens in large language models | Video, Text | GitHub |
| mplug-owl: Modularization empowers large language models with multimodality | Video, Text | GitHub |
| Chat-univi: Unified visual representation empowers large language models with image and video understanding | Video, Text | GitHub |
| Salmonn: Towards generic hearing abilities for large language models | Audio, Text | GitHub |
| Qwen-audio: Advancing universal audio understanding via unified large-scale audio-language models | Audio, Text | GitHub |
| Secap: Speech emotion captioning with large language model | Audio, Text | GitHub |
| Onellm: One framework to align all modalities with language | Audio, Video, Text | GitHub |
| Pandagpt: One model to instruction-follow them all | Audio, Video, Text | GitHub |
| Emotion-llama: Multimodal emotion recognition and reasoning with instruction tuning | Audio, Video, Text | GitHub |
Datasets
| Dataset | Modality | Samples | Description | Emotions | Annotation Manner |
|---|---|---|---|---|---|
| RAF-DB | I | 29,672 | ✗ | 7 | Human |
| AffectNet | I | 450,000 | ✗ | 8 | Human |
| EmoDB | A | 535 | ✗ | 7 | Human |
| MSP-Podcast | A | 73,042 | ✗ | 8 | Human |
| DFEW | V | 11,697 | ✗ | 7 | Human |
| FERV39k | V | 38,935 | ✗ | 7 | Human |
| MER2023 | A,V,T | 5,030 | ✗ | 6 | Human |
| MELD | A,V,T | 13,708 | ✗ | 7 | Human |
| EmoViT | I | 51,200 | ✓ | 988 | Model |
| MERR-Coarse | A,V,T | 28,618 | ✓ | 113 | Model |
| MAFW | A,V,T | 10,045 | ✓ | 399 | Human |
| OV-MERD | A,V,T | 332 | ✓ | 236 | Human-led+Model-assisted |
| MERR-Fine | A,V,T | 4,487 | ✓ | 484 | Human-led+Model-assisted |
| MER-Caption | A,V,T | 115,595 | ✓ | 2,932 | Model-led+Human-assisted |
| MER-Caption+ | A,V,T | 31,327 | ✓ | 1,972 | Model-led+Human-assisted |
| Category | Dataset | Chosen Set | # Samples | Label Description |
|---|---|---|---|---|
| Fine-grained Emotion | OV-MERD+ | All | 532 | unfixed categories and diverse number of labels per sample |
| Basic Emotion | MER2023 | MER-MULTI | 411 | most likely label among six candidates |
| Basic Emotion | MER2024 | MER-SEMI | 1,169 | most likely label among six candidates |
| Basic Emotion | IEMOCAP | Sessions5 | 1,241 | most likely label among four candidates |
| Basic Emotion | MELD | Test | 2,610 | most likely label among seven candidates |
| Sentiment Analysis | CMU-MOSI | Test | 686 | sentiment intensity, ranging from [-3, 3] |
| Sentiment Analysis | CMU-MOSEI | Test | 4,659 | sentiment intensity, ranging from [-3, 3] |
| Sentiment Analysis | CH-SIMS | Test | 457 | sentiment intensity, ranging from [-1, 1] |
| Sentiment Analysis | CH-SIMS v2 | Test | 1,034 | sentiment intensity, ranging from [-1, 1] |
| Dataset | Domain | Dur(hrs) | #labels | Modality | Language | Emotion? | Ego? |
|---|---|---|---|---|---|---|---|
| Large Movie | movie | - | 25,000 | T | EN | ✗ | ✗ |
| SeMAINE | dialogue | 06:30 | 80 | V,A | EN | ✓ | ✗ |
| HUMAINE | diverse | 04:11 | 50 | V,A | various | ✓ | ✗ |
| YouTube | diverse | 00:29 | 300 | V,A,T | various | ✗ | ✗ |
| SST | movie | - | 11,855 | T | EN | ✗ | ✗ |
| ICT-MMMO | movie | 13:58 | 340 | V,A,T | EN | ✗ | ✗ |
| RECOLA | dialogue | 03:50 | 46 | V,A | FR | ✓ | ✓ |
| MOUD | review | 00:59 | 400 | V,A,T | ES | ✗ | ✗ |
| AFEW | movie | 02:28 | 1,645 | V,A | various | ✓ | ✓ |
| SEWA | adverts | 04:39 | 538 | V,A | EN,DE,EL | ✓ | ✗ |
| Disneyworld | disneyland | 42:00 | 15,000 | V,A,T | EN | ✗ | ✓ |
| EGTEA Gaze+ | diverse | 28:00 | - | V,A,T | various | ✓ | ✓ |
| BEOID | diverse | - | - | V,A,T | EN | ✗ | ✗ |
| Chorus-Ego | home | 34:00 | 30,000 | V,A,T | EN | ✗ | ✓ |
| EPIC | kitchen | 100:00 | 90,000 | V,A,T | EN | ✗ | ✓ |
| Ego-4D | diverse | 3025:00 | 74000 | V,A,T | various | ✗ | ✓ |
| (E^3) | diverse | 71:41 | 81,248 | V,A,T | various | ✓ | ✓ |
Other surveys
| Paper | Url | Source |
|---|---|---|
| Mm-llms: Recent advances in multimodal large language models | [paper] | [source] |
| Efficient multimodal large language models: A survey | [paper] | [source] |
| Hallucination of multimodal large language models: A survey | [paper] | [source] |
| A survey on benchmarks of multimodal large language models | [paper] | [source] |
| A comprehensive survey of large language models and multimodal large language models in medicine | [paper] | - |
| Exploring the Reasoning Abilities of Multimodal Large Language Models (MLLMs): A Comprehensive Survey on Emerging Trends in Multimodal Reasoning | [paper] | - |
| How to bridge the gap between modalities: A comprehensive survey on multimodal large language model | [paper] | - |
| A Comprehensive Overview of Large Language Models | [paper] | - |
| A review of multi-modal large language and vision models | [paper] | - |
| Large language models meet nlp: A survey | [paper] | - |
| Efficient large language models: A survey | [paper] | [source] |
📌 Citation
If you find our paper and code useful in your research, please consider giving a star :star: and citation :pencil: :
@article{shou2025multimodal,
  title={Multimodal Large Language Models Meet Multimodal Emotion Recognition and Reasoning: A Survey},
  author={Shou, Yuntao and Meng, Tao and Ai, Wei and Li, Keqin},
  journal={arXiv preprint arXiv:2509.24322},
  year={2025}
}
Acknowledgement :heart:
Thanks to Awesome-LLM.
Star History
Contributors

55 commits

1 commits
Similar repos


Awesome-Emotion-Reasoning is a collection of Emotion-Reasoning works, including papers, codes and datasets
98
56 commits
updated Dec 16, 2025
README
Large Language Models Meet Emotion Recognition: A Survey
This is the summation of all the methods, datasets, and other survey mentioned in our survey 'Large Language Models Meet Emotion Recognition: A Survey' :fire:. Any problems, please contact shouyuntao@stu.xjtu.edu.cn. Any other interesting papers or codes are welcome. If you find this repository useful to your research or work, it is really appreciated to star this repository :heart:.
Trending LLM Projects
- TinyZero - Clean, minimal, accessible reproduction of DeepSeek R1-Zero
- open-r1 - Fully open reproduction of DeepSeek-R1
- DeepSeek-R1 - First-generation reasoning models from DeepSeek.
- Qwen2.5-Max - Exploring the Intelligence of Large-scale MoE Model.
- OpenAI o3-mini - Pushing the frontier of cost-effective reasoning.
- DeepSeek-V3 - First open-sourced GPT-4o level model.
- Kimi-K2 - MoE language model with 32B active and 1T total parameters.
Milestone Papers
Open LLM
- DeepSeek-Math-7B
- DeepSeek-Coder-1.3|6.7|7|33B
- DeepSeek-VL-1.3|7B
- DeepSeek-MoE-16B
- DeepSeek-v2-236B-MoE
- DeepSeek-Coder-v2-16|236B-MOE
- DeepSeek-V2.5
- DeepSeek-R1
- DeepSeek-R1-Zero
- DeepSeek-R1-Distill-Llama-70B
- DeepSeek-R1-Distill-Llama-8B
- DeepSeek-R1-Distill-Qwen-7B
- DeepSeek-R1-Distill-Qwen-32B
- DeepSeek-R1-Distill-Qwen-14B
- DeepSeek-R1-Distill-Qwen-7B
- DeepSeek-R1-Distill-Qwen-1.5B
- DeepSeek-R1-0528
- DeepSeek-R1-0528-Qwen3-8B
- DeepSeek-V2-Chat-0628
- DeepSeek-V2-Chat
- DeepSeek-V2
- DeepSeek-V2-Lite
- DeepSeek-V2-Lite-Chat
- DeepSeek-V2.5
- DeepSeek-V2.5-1210
- DeepSeek-V3-Base
- DeepSeek-V3
- DeepSeek-V3-0324
- DeepSeek-V3.1-Base
- DeepSeek-V3.1
- DeepSeek-V3.1-Terminus
- DeepSeek-V3.2-Exp
- DeepSeek-V3.2-Exp-Base
- DeepSeek-V3.2
- DeepSeek-V3.2-Speciale
- Deepseek-Vl2-Tiny
- Deepseek-Vl2-Small
- Deepseek-Vl2
- Janus-Pro-7B
- Janus-Pro-1B
- Janus-1.3B
- JanusFlow-1.3B
- Qwen-1.8B|7B|14B|72B
- Qwen1.5-0.5B|1.8B|4B|7B|14B|32B|72B|110B|MoE-A2.7B
- Qwen2-0.5B|1.5B|7B|57B-A14B-MoE|72B
- Qwen2.5-0.5B|1.5B|3B|7B|14B|32B|72B
- CodeQwen1.5-7B
- Qwen2.5-Coder-1.5B|7B|32B
- Qwen2-Math-1.5B|7B|72B
- Qwen2.5-Math-1.5B|7B|72B
- Qwen2.5-Omni-7B
- Qwen2.5-Omni-3B
- Qwen2.5-Omni-7B-GPTQ-Int4
- Qwen2.5-Omni-7B-AWQ
- Qwen-VL-7B
- Qwen2-VL-2B|7B|72B
- Qwen2-Audio-7B
- Qwen2.5-VL-3|7|72B
- Qwen2.5-1M-7|14B
- Qwen3-VL-235B-A22B-Instruct
- Qwen3-VL-235B-A22B-Thinking
- Qwen3-Omni-30B-A3B-Captioner
- Qwen3-Omni-30B-A3B-Instruct
- Qwen3-Omni-30B-A3B-Thinking
- Qwen3-Next-80B-A3B-Instruct
- Qwen3-Next-80B-A3B-Instruct-FP8
- Qwen3-Next-80B-A3B-Thinking-FP8
- Llama 3.2-1|3|11|90B
- Llama 3.1-8|70|405B
- Llama 3-8|70B
- Llama 2-7|13|70B
- Llama 1-7|13|33|65B
- OPT-1.3|6.7|13|30|66B
- Llama-4-Scout-17B-16E-Instruct
- Llama-4-Scout-17B-16E
- Llama-4-Maverick-17B-128E-Instruct
- Llama-4-Maverick-17B-128E-Instruct-FP8
- Llama-4-Maverick-17B-128E
- Llama-4-Scout-17B-16E-Instruct-Original
- Llama-4-Maverick-17B-128E-Instruct-FP8-Original
- Llama-4-Scout-17B-16E-Original
- Llama-4-Maverick-17B-128E-Instruct-Original
- Llama-4-Maverick-17B-128E-Original
- Llama-Prompt-Guard-2-22M
- Llama-Prompt-Guard-2-86M
- Llama-Guard-4-12B
- Codestral-7|22B
- Mistral-7B
- Mixtral-8x7B
- Mixtral-8x22B
- Ministral-3-14B-Instruct-2512
- Ministral-3-8B-Instruct-2512
- Ministral-3-3B-Instruct-2512
- Ministral-3-14B-Reasoning-2512
- Ministral-3-8B-Reasoning-2512
- Ministral-3-3B-Reasoning-2512
- Ministral-3-14B-Base-2512
- Ministral-3-8B-Base-2512
- Ministral-3-3B-Base-2512
- Mistral-Large-3-675B-Instruct-2512
- Mistral-Large-3-675B-Instruct-2512-NVFP4
- Mistral-Large-3-675B-Instruct-2512-Eagle
- Mistral-Large-3-675B-Base-2512
- RWKV-v4|5|6minicpm-2b-65d48bf958302b9fd25b698f)
LLM for emotion recognition
| Model | Supported Modality | Link |
|---|---|---|
| A Multi-Modal Model with In-Context Instruction Tuning | Video, Text | GitHub |
| Videochat: Chat-centric video understanding | Video, Text | GitHub |
| Mvbench: A comprehensive multi-modal video understanding benchmark | Video, Text | GitHub |
| Video-llava: Learning united visual representation by alignment before projection | Video, Text | GitHub |
| Video-llama: An instruction-tuned audio-visual language model for video understanding | Video, Text | GitHub |
| Video-chatgpt: Towards detailed video understanding via large vision and language models | Video, Text | GitHub |
| Llama-vid: An image is worth 2 tokens in large language models | Video, Text | GitHub |
| mplug-owl: Modularization empowers large language models with multimodality | Video, Text | GitHub |
| Chat-univi: Unified visual representation empowers large language models with image and video understanding | Video, Text | GitHub |
| Salmonn: Towards generic hearing abilities for large language models | Audio, Text | GitHub |
| Qwen-audio: Advancing universal audio understanding via unified large-scale audio-language models | Audio, Text | GitHub |
| Secap: Speech emotion captioning with large language model | Audio, Text | GitHub |
| Onellm: One framework to align all modalities with language | Audio, Video, Text | GitHub |
| Pandagpt: One model to instruction-follow them all | Audio, Video, Text | GitHub |
| Emotion-llama: Multimodal emotion recognition and reasoning with instruction tuning | Audio, Video, Text | GitHub |
Datasets
| Dataset | Modality | Samples | Description | Emotions | Annotation Manner |
|---|---|---|---|---|---|
| RAF-DB | I | 29,672 | ✗ | 7 | Human |
| AffectNet | I | 450,000 | ✗ | 8 | Human |
| EmoDB | A | 535 | ✗ | 7 | Human |
| MSP-Podcast | A | 73,042 | ✗ | 8 | Human |
| DFEW | V | 11,697 | ✗ | 7 | Human |
| FERV39k | V | 38,935 | ✗ | 7 | Human |
| MER2023 | A,V,T | 5,030 | ✗ | 6 | Human |
| MELD | A,V,T | 13,708 | ✗ | 7 | Human |
| EmoViT | I | 51,200 | ✓ | 988 | Model |
| MERR-Coarse | A,V,T | 28,618 | ✓ | 113 | Model |
| MAFW | A,V,T | 10,045 | ✓ | 399 | Human |
| OV-MERD | A,V,T | 332 | ✓ | 236 | Human-led+Model-assisted |
| MERR-Fine | A,V,T | 4,487 | ✓ | 484 | Human-led+Model-assisted |
| MER-Caption | A,V,T | 115,595 | ✓ | 2,932 | Model-led+Human-assisted |
| MER-Caption+ | A,V,T | 31,327 | ✓ | 1,972 | Model-led+Human-assisted |
| Category | Dataset | Chosen Set | # Samples | Label Description |
|---|---|---|---|---|
| Fine-grained Emotion | OV-MERD+ | All | 532 | unfixed categories and diverse number of labels per sample |
| Basic Emotion | MER2023 | MER-MULTI | 411 | most likely label among six candidates |
| Basic Emotion | MER2024 | MER-SEMI | 1,169 | most likely label among six candidates |
| Basic Emotion | IEMOCAP | Sessions5 | 1,241 | most likely label among four candidates |
| Basic Emotion | MELD | Test | 2,610 | most likely label among seven candidates |
| Sentiment Analysis | CMU-MOSI | Test | 686 | sentiment intensity, ranging from [-3, 3] |
| Sentiment Analysis | CMU-MOSEI | Test | 4,659 | sentiment intensity, ranging from [-3, 3] |
| Sentiment Analysis | CH-SIMS | Test | 457 | sentiment intensity, ranging from [-1, 1] |
| Sentiment Analysis | CH-SIMS v2 | Test | 1,034 | sentiment intensity, ranging from [-1, 1] |
| Dataset | Domain | Dur(hrs) | #labels | Modality | Language | Emotion? | Ego? |
|---|---|---|---|---|---|---|---|
| Large Movie | movie | - | 25,000 | T | EN | ✗ | ✗ |
| SeMAINE | dialogue | 06:30 | 80 | V,A | EN | ✓ | ✗ |
| HUMAINE | diverse | 04:11 | 50 | V,A | various | ✓ | ✗ |
| YouTube | diverse | 00:29 | 300 | V,A,T | various | ✗ | ✗ |
| SST | movie | - | 11,855 | T | EN | ✗ | ✗ |
| ICT-MMMO | movie | 13:58 | 340 | V,A,T | EN | ✗ | ✗ |
| RECOLA | dialogue | 03:50 | 46 | V,A | FR | ✓ | ✓ |
| MOUD | review | 00:59 | 400 | V,A,T | ES | ✗ | ✗ |
| AFEW | movie | 02:28 | 1,645 | V,A | various | ✓ | ✓ |
| SEWA | adverts | 04:39 | 538 | V,A | EN,DE,EL | ✓ | ✗ |
| Disneyworld | disneyland | 42:00 | 15,000 | V,A,T | EN | ✗ | ✓ |
| EGTEA Gaze+ | diverse | 28:00 | - | V,A,T | various | ✓ | ✓ |
| BEOID | diverse | - | - | V,A,T | EN | ✗ | ✗ |
| Chorus-Ego | home | 34:00 | 30,000 | V,A,T | EN | ✗ | ✓ |
| EPIC | kitchen | 100:00 | 90,000 | V,A,T | EN | ✗ | ✓ |
| Ego-4D | diverse | 3025:00 | 74000 | V,A,T | various | ✗ | ✓ |
| (E^3) | diverse | 71:41 | 81,248 | V,A,T | various | ✓ | ✓ |
Other surveys
| Paper | Url | Source |
|---|---|---|
| Mm-llms: Recent advances in multimodal large language models | [paper] | [source] |
| Efficient multimodal large language models: A survey | [paper] | [source] |
| Hallucination of multimodal large language models: A survey | [paper] | [source] |
| A survey on benchmarks of multimodal large language models | [paper] | [source] |
| A comprehensive survey of large language models and multimodal large language models in medicine | [paper] | - |
| Exploring the Reasoning Abilities of Multimodal Large Language Models (MLLMs): A Comprehensive Survey on Emerging Trends in Multimodal Reasoning | [paper] | - |
| How to bridge the gap between modalities: A comprehensive survey on multimodal large language model | [paper] | - |
| A Comprehensive Overview of Large Language Models | [paper] | - |
| A review of multi-modal large language and vision models | [paper] | - |
| Large language models meet nlp: A survey | [paper] | - |
| Efficient large language models: A survey | [paper] | [source] |
📌 Citation
If you find our paper and code useful in your research, please consider giving a star :star: and citation :pencil: :
@article{shou2025multimodal,
  title={Multimodal Large Language Models Meet Multimodal Emotion Recognition and Reasoning: A Survey},
  author={Shou, Yuntao and Meng, Tao and Ai, Wei and Li, Keqin},
  journal={arXiv preprint arXiv:2509.24322},
  year={2025}
}
Acknowledgement :heart:
Thanks to Awesome-LLM.
Star History
Similar repos
Contributors
55 commits
1 commits