
[NeurIPS 2023] This is the code for the paper `Large Language Model as Attributed Training Data Generator: A Tale of Diversity and Bias`.
See the codeREADME
AttrPrompt
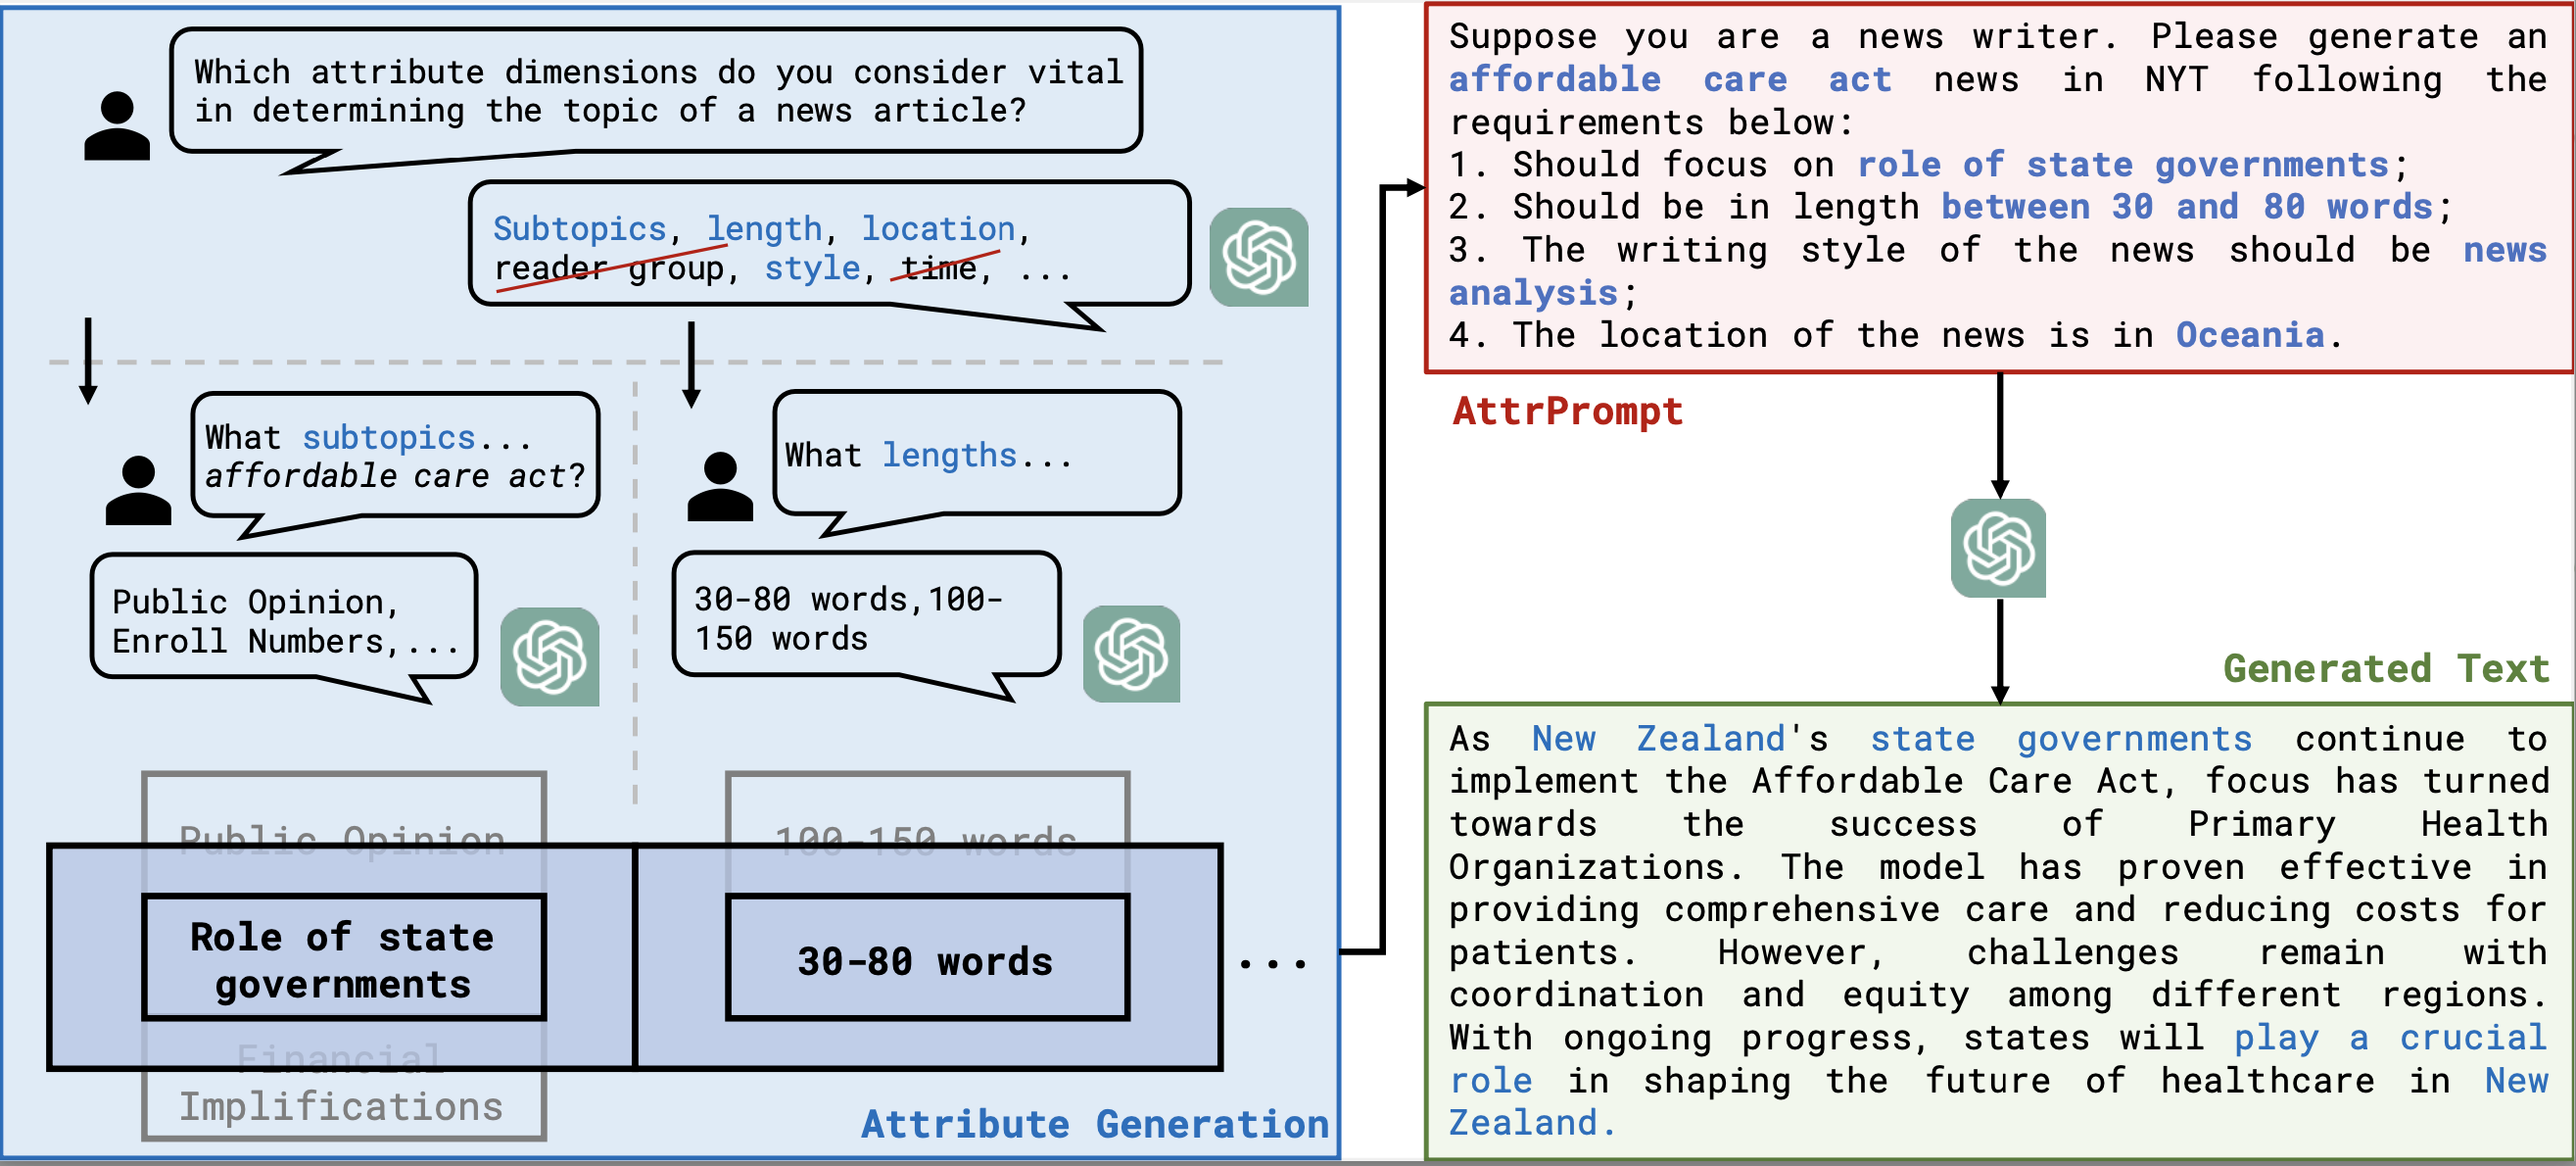
This repo contains the code and dataset used in the paper Large Language Model as Attributed Training Data Generator: A Tale of Diversity and Bias, which will appear at NeurIPS 2023 (D&B Track). It also provides a framework for developing and evaluating your training data generation pipelines with Large Language Models.
Framework
Dataset
Generated Datasets
The datasets, including the original train/validation/test data, the generated training data, as well as label names are available in Huggingface Dataset Hub:
| Dataset | # Train | # Test | # Class | Task | Domain | Link |
|---|---|---|---|---|---|---|
| NYT | 9k | 1.15k | 26 | Multiclass | News | nyt-attrprompt |
| Amazon | 13.8k | 1.1k | 23 | Multiclass | Review | amazon-attrprompt |
| 27k | 2.3k | 45 | Multiclass | Social Media | reddit-attrprompt | |
| StackExchange | 27k | 2.5k | 50 | Multiclass | Web Forum | stackexchange-attrprompt |
| arXiv | 26.1k | 27.8k | 98 | Multilabel | Paper | arxiv-attrprompt |
Besides, we also provide the generated dataset for AG News, SST-2/IMDB, and Yelp, which is studied in the Appendix. The detailed information is listed as follows:
| Dataset | # Train | # Test | # Class | Task | Domain | Link |
|---|---|---|---|---|---|---|
| AG News | 6k | 7.6k | 4 | Multiclass | News | agnews-attrprompt |
| SST-2 | 6k | 0.8k | 2 | Multiclass | Movie Review | SST-2-attrprompt |
| Yelp | 6k | 38k | 2 | Multiclass | Restaurant Review | yelp-attrprompt |
Load Datasets
For the original train/valid/test set, we use the following commands for loading the data from the huggingface data hub (we use nyt dataset as an example, same as follows):
from datasets import load_dataset

train = load_dataset("yyu/nyt-attrprompt", split="train")
valid = load_dataset("yyu/nyt-attrprompt", split="valid")
test = load_dataset("yyu/nyt-attrprompt", split="test")
For attrprompt, simprompt, progen, regen and regen_llm_augmented, we use the following commands for loading the data from the huggingface data hub:
from datasets import load_dataset

attrprompt = load_dataset("yyu/nyt-attrprompt", data_files="attrprompt-v1.jsonl", split = 'train')

simprompt = load_dataset("yyu/nyt-attrprompt", data_files="simprompt.jsonl", split = 'train')

progen = load_dataset("yyu/nyt-attrprompt", data_files="progen.jsonl", split = 'train')

regen = load_dataset("yyu/nyt-simprompt", data_files="regen.jsonl", split = 'train')

regen_llm_augmented = load_dataset("yyu/nyt-simprompt", data_files="regen_llm_augmented.jsonl", split = 'train')
Dataset Attributes
Please see the subfolders on the ./datasets directory for attribute information.
Code for Training Data Generation
See gen_train_data for details.
Code for Classifier Training
See train_classifier for details.
Questions?
Feel free to contact yueyu at gatech.edu for any questions regarding this repo. Please try to specify the problem with details so we can help you better and quicker!
Citation
If you find this repository helpful, please kindly consider citing the corresponding paper. Thanks in advance!
@inproceedings{yu2023large,
  title={Large Language Model as Attributed Training Data Generator: A Tale of Diversity and Bias},
  author={Yu, Yue and Zhuang, Yuchen and Zhang, Jieyu and Meng, Yu and Ratner, Alexander and Krishna, Ranjay and Shen, Jiaming and Zhang, Chao},
  booktitle={Thirty-Seventh Conference on Neural Information Processing Systems Datasets and Benchmarks Track},
  year={2023}
}
Significant stargazers

6,268 followers · starred Jul 2023

129 followers · starred Nov 2024
Similar repos


Languages
Python
98.6%
Shell
1.4%
[NeurIPS 2023] This is the code for the paper `Large Language Model as Attributed Training Data Generator: A Tale of Diversity and Bias`.
See the codeREADME
AttrPrompt
This repo contains the code and dataset used in the paper Large Language Model as Attributed Training Data Generator: A Tale of Diversity and Bias, which will appear at NeurIPS 2023 (D&B Track). It also provides a framework for developing and evaluating your training data generation pipelines with Large Language Models.
Framework
Dataset
Generated Datasets
The datasets, including the original train/validation/test data, the generated training data, as well as label names are available in Huggingface Dataset Hub:
| Dataset | # Train | # Test | # Class | Task | Domain | Link |
|---|---|---|---|---|---|---|
| NYT | 9k | 1.15k | 26 | Multiclass | News | nyt-attrprompt |
| Amazon | 13.8k | 1.1k | 23 | Multiclass | Review | amazon-attrprompt |
| 27k | 2.3k | 45 | Multiclass | Social Media | reddit-attrprompt | |
| StackExchange | 27k | 2.5k | 50 | Multiclass | Web Forum | stackexchange-attrprompt |
| arXiv | 26.1k | 27.8k | 98 | Multilabel | Paper | arxiv-attrprompt |
Besides, we also provide the generated dataset for AG News, SST-2/IMDB, and Yelp, which is studied in the Appendix. The detailed information is listed as follows:
| Dataset | # Train | # Test | # Class | Task | Domain | Link |
|---|---|---|---|---|---|---|
| AG News | 6k | 7.6k | 4 | Multiclass | News | agnews-attrprompt |
| SST-2 | 6k | 0.8k | 2 | Multiclass | Movie Review | SST-2-attrprompt |
| Yelp | 6k | 38k | 2 | Multiclass | Restaurant Review | yelp-attrprompt |
Load Datasets
For the original train/valid/test set, we use the following commands for loading the data from the huggingface data hub (we use nyt dataset as an example, same as follows):
from datasets import load_dataset

train = load_dataset("yyu/nyt-attrprompt", split="train")
valid = load_dataset("yyu/nyt-attrprompt", split="valid")
test = load_dataset("yyu/nyt-attrprompt", split="test")
For attrprompt, simprompt, progen, regen and regen_llm_augmented, we use the following commands for loading the data from the huggingface data hub:
from datasets import load_dataset

attrprompt = load_dataset("yyu/nyt-attrprompt", data_files="attrprompt-v1.jsonl", split = 'train')

simprompt = load_dataset("yyu/nyt-attrprompt", data_files="simprompt.jsonl", split = 'train')

progen = load_dataset("yyu/nyt-attrprompt", data_files="progen.jsonl", split = 'train')

regen = load_dataset("yyu/nyt-simprompt", data_files="regen.jsonl", split = 'train')

regen_llm_augmented = load_dataset("yyu/nyt-simprompt", data_files="regen_llm_augmented.jsonl", split = 'train')
Dataset Attributes
Please see the subfolders on the ./datasets directory for attribute information.
Code for Training Data Generation
See gen_train_data for details.
Code for Classifier Training
See train_classifier for details.
Questions?
Feel free to contact yueyu at gatech.edu for any questions regarding this repo. Please try to specify the problem with details so we can help you better and quicker!
Citation
If you find this repository helpful, please kindly consider citing the corresponding paper. Thanks in advance!
@inproceedings{yu2023large,
  title={Large Language Model as Attributed Training Data Generator: A Tale of Diversity and Bias},
  author={Yu, Yue and Zhuang, Yuchen and Zhang, Jieyu and Meng, Yu and Ratner, Alexander and Krishna, Ranjay and Shen, Jiaming and Zhang, Chao},
  booktitle={Thirty-Seventh Conference on Neural Information Processing Systems Datasets and Benchmarks Track},
  year={2023}
}
Similar repos
Significant stargazers
6,268 followers · starred Jul 2023
129 followers · starred Nov 2024
Languages
Python
98.6%
Shell
1.4%