
Official implementation for DenseMixer: Improving MoE Post-Training with Precise Router Gradient
See the codeREADME
🎨 DenseMixer 🎨
Improving MoE Post-Training with Precise Router Gradients (Blog)


What is DenseMixer? • Key Features • Experiments • Quick Start • Efficiency • Citation
DenseMixer is a novel MoE post-training technique that empowers MoE training with more precise router gradient estimation, consistently outperforming conventional MoE training in downstream tasks.
What is DenseMixer?
DenseMixer addresses the non-differentiable Top-K routing problem in MoE training via straight-through estimator (STE). This enables more precise router gradients by computing all experts's output during forward pass for better gradient estimation during backward pass. For more technical details, please refer to our blog.
🚀 Key Features
- Plug-and-play: Zero code changes required
- Universal compatibility: Works with any MoE using Top-K routing
- Performance gains: Consistently outperforms conventional MoE training
- Parameter-efficient: Compatible with LoRA and other PEFT methods
- No inference overhead: Zero impact on model inference speed
📈 Experiments
DenseMixer consistently outperforms conventional MoE training across:
- Model scales: 7B, 14B, 30B parameters
- Architectures: With/without shared experts
- Training methods: From scratch and up-cycling
- Data types: Instruction tuning and long reasoning data
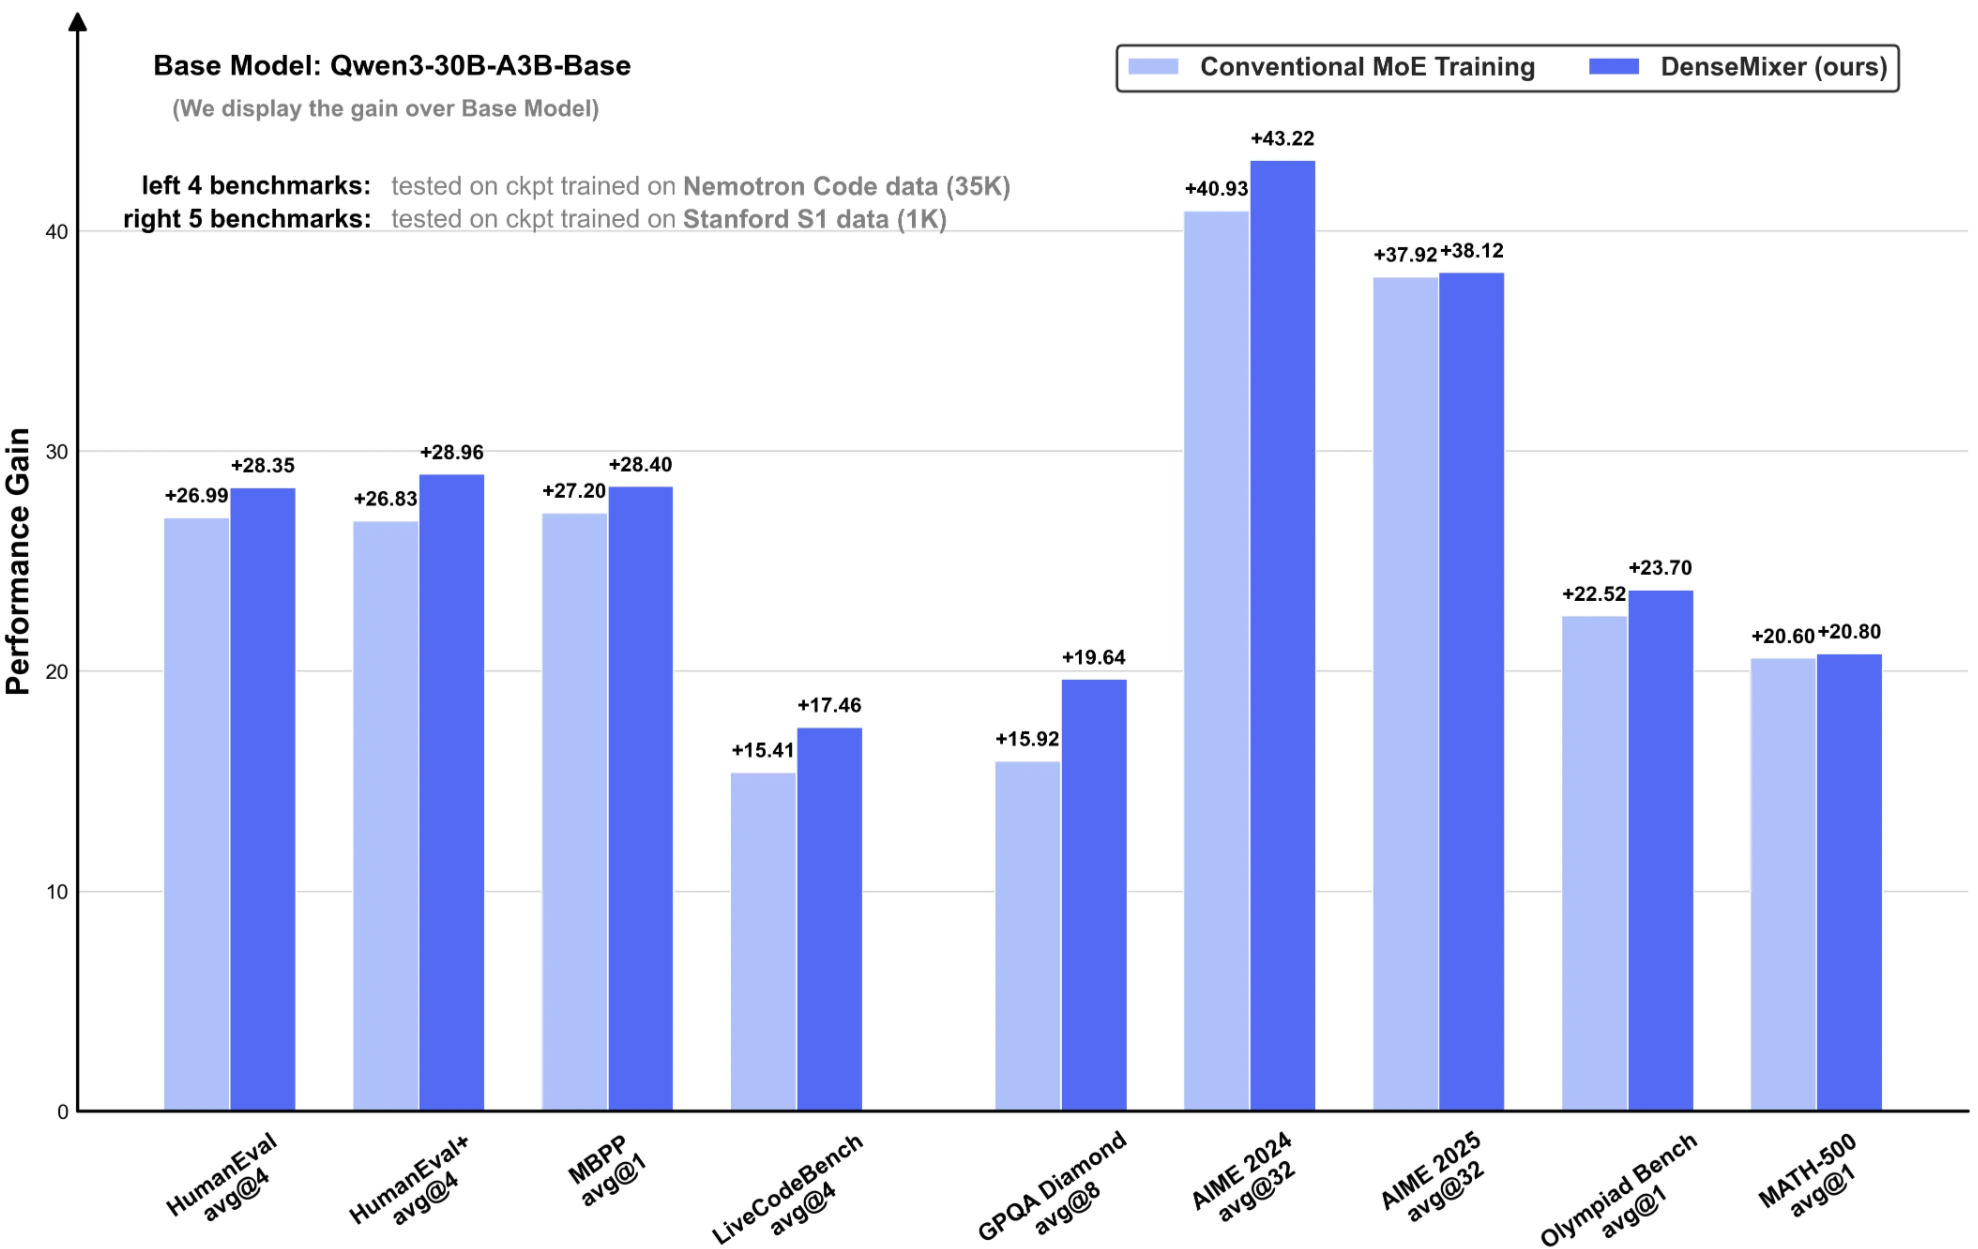
Reproducible Experiments: For detailed training scripts, configurations, and evaluation code, please refer to the experiments folder.
📊 Qwen1.5-MoE-A2.7B (14B): +2.2% average improvement across 7 tasks
Full Fine-tuning Results:
| Method | GSM | MBPP | HumanEval | Intent | Law | Summary | Translation | Avg |
|---|---|---|---|---|---|---|---|---|
| Base Model | 38.69 | 38.84 | 32.31 | 16.83 | 18.20 | 28.29 | 16.53 | 27.10 |
| Frozen Router | 53.37 | 35.20 | 37.10 | 82.20 | 33.01 | 38.29 | 32.75 | 44.56 |
| Conventional | 53.42 | 34.60 | 36.43 | 81.80 | 29.25 | 37.80 | 33.02 | 43.76 |
| DenseMixer | 55.16 | 35.40 | 39.68 | 83.40 | 33.83 | 40.56 | 33.90 | 45.99 |
| Gain | +1.74 | +0.80 | +3.25 | +1.60 | +4.58 | +2.76 | +0.88 | +2.23 |
LoRA Fine-tuning Results:
| Method | GSM | MBPP | HumanEval | Intent | Law | Summary | Translation | Avg |
|---|---|---|---|---|---|---|---|---|
| Frozen Router -lora | 46.77 | 31.40 | 36.58 | 71.00 | 30.30 | 30.19 | 28.08 | 39.19 |
| Conventional -lora | 43.89 | 34.00 | 38.41 | 64.80 | 28.80 | 37.99 | 26.14 | 39.15 |
| DenseMixer -lora | 47.24 | 35.40 | 38.41 | 71.80 | 31.80 | 40.20 | 29.25 | 42.01 |
| Gain | +3.35 | +1.40 | +0.00 | +7.00 | +3.00 | +2.21 | +3.11 | +2.86 |
📊 OLMoE-1B-7B: +2.9% average improvement across 7 tasks
Full Fine-tuning Results:
| Method | GSM | MBPP | HumanEval | Intent | Law | Summary | Translation | Avg |
|---|---|---|---|---|---|---|---|---|
| Base Model | 15.85 | 19.80 | 10.97 | 0.20 | 5.70 | 7.40 | 11.09 | 10.14 |
| Frozen Router | 44.88 | 17.8 | 7.23 | 72.80 | 22.50 | 36.05 | 28.29 | 32.79 |
| Conventional | 45.94 | 23.4 | 18.92 | 74.60 | 22.35 | 35.99 | 26.89 | 35.44 |
| DenseMixer | 49.00 | 25.12 | 20.73 | 77.40 | 23.02 | 40.64 | 32.55 | 38.35 |
| Gain | +3.06 | +1.72 | +1.81 | +2.80 | +0.67 | +4.65 | +5.66 | +2.91 |
LoRA Fine-tuning Results:
| Method | GSM | MBPP | HumanEval | Intent | Law | Summary | Translation | Avg |
|---|---|---|---|---|---|---|---|---|
| Frozen Router -lora | 45.03 | 24.2 | 17.07 | 55.80 | 21.30 | 37.70 | 28.19 | 32.76 |
| Conventional -lora | 44.58 | 24.2 | 15.85 | 60.20 | 21.60 | 37.30 | 26.22 | 32.85 |
| DenseMixer -lora | 45.38 | 26.2 | 16.48 | 66.60 | 24.70 | 40.80 | 29.43 | 35.66 |
| Gain | +0.80 | +2.00 | +0.63 | +6.40 | +3.10 | +3.50 | +3.21 | +2.81 |
📊 Qwen3-30B-A3B: +3.7% improvement on GPQA-Diamond
Nemotron-Code Dataset (35K samples):
| Method | HumanEval (avg@4) | HumanEval+ (avg@4) | MBPP (avg@1) | LiveCodeBench (avg@4) | Avg |
|---|---|---|---|---|---|
| Base Model | 65.24 | 60.06 | 53.60 | 16.85 | 48.94 |
| Conventional | 92.23 | 86.89 | 80.80 | 32.26 | 67.21 |
| DenseMixer | 93.59 | 89.02 | 82.00 | 34.31 | 68.80 |
| Gain | +1.36 | +2.13 | +1.20 | +2.05 | +1.59 |
Stanford S1 Dataset (1K samples):
| Method | GPQA Diamond (avg@8) | AIME 2024 (avg@32) | AIME 2025 (avg@32) | Olympiad Bench (avg@1) | MATH-500 (avg@1) | Avg |
|---|---|---|---|---|---|---|
| Base Model | 38.88 | 20.63 | 7.71 | 34.81 | 72.80 | 34.97 |
| Conventional | 54.80 | 61.56 | 45.63 | 57.33 | 93.40 | 62.54 |
| DenseMixer | 58.52 | 63.85 | 45.83 | 58.51 | 93.60 | 64.06 |
| Gain | +3.72 | +2.29 | +0.20 | +1.18 | +0.20 | +1.52 |
Results shown for temperature=0.6, top_p=0.95 decoding parameters
Additional Decoding Parameters:
Temperature=0.7, top_p=0.8
Nemotron-Code:
| Method | HumanEval (avg@4) | HumanEval+ (avg@4) | MBPP (avg@1) | LiveCodeBench (avg@4) | Avg |
|---|---|---|---|---|---|
| Conventional | 91.01 | 85.37 | 76.80 | 29.39 | 65.59 |
| DenseMixer | 91.92 | 86.89 | 80.80 | 31.89 | 67.32 |
Stanford S1:
| Method | GPQA Diamond (avg@8) | AIME 2024 (avg@32) | AIME 2025 (avg@32) | Olympiad Bench (avg@1) | MATH-500 (avg@1) | Avg |
|---|---|---|---|---|---|---|
| Conventional | 54.23 | 61.67 | 44.27 | 55.41 | 92.20 | 61.56 |
| DenseMixer | 55.80 | 63.13 | 45.31 | 57.18 | 93.00 | 62.88 |
Temperature=1.0, top_p=0.7
Nemotron-Code:
| Method | HumanEval (avg@4) | HumanEval+ (avg@4) | MBPP (avg@1) | LiveCodeBench (avg@4) | Avg |
|---|---|---|---|---|---|
| Conventional | 90.85 | 86.59 | 79.00 | 33.42 | 67.59 |
| DenseMixer | 93.29 | 88.87 | 84.39 | 34.40 | 68.99 |
Stanford S1:
| Method | GPQA Diamond (avg@8) | AIME 2024 (avg@32) | AIME 2025 (avg@32) | Olympiad Bench (avg@1) | MATH-500 (avg@1) | Avg |
|---|---|---|---|---|---|---|
| Conventional | 56.55 | 63.65 | 46.15 | 59.11 | 93.00 | 63.69 |
| DenseMixer | 58.14 | 62.71 | 47.50 | 57.77 | 93.80 | 63.98 |
⚡ Quick Start
1. Installation
pip install densemixer
2. Setup (One-time)
densemixer setup
3. Enable DenseMixer
export DENSEMIXER_ENABLED=1
4. Use Your MoE Models
from transformers import Qwen3MoeForCausalLM

# DenseMixer automatically patches the model
model = Qwen3MoeForCausalLM.from_pretrained("Qwen/Qwen3-MoE-30B-A3B")

# Train as usual - no code changes needed!
🔧 Configuration
DenseMixer currently supports the following models.
- Qwen3-MoE (30B parameters)
- Qwen1.5-MoE (14B parameters)
- OLMoE (7B parameters)
DenseMixer uses environment variables for configuration:
| Variable | Description | Default |
|---|---|---|
DENSEMIXER_ENABLED | Master switch (set to 1 to enable) | 0 |
DENSEMIXER_QWEN3 | Enable for Qwen3-MoE models | 1 |
DENSEMIXER_QWEN2 | Enable for Qwen1.5-MoE models | 1 |
DENSEMIXER_OLMOE | Enable for OLMoE models | 1 |
Usage Examples
Enable for all models:
export DENSEMIXER_ENABLED=1
python your_training_script.py
Enable only for specific models:
export DENSEMIXER_ENABLED=1
export DENSEMIXER_QWEN3=1
export DENSEMIXER_QWEN2=0
export DENSEMIXER_OLMOE=0
python your_training_script.py
Disable (default behavior):
# No environment variables needed
python your_training_script.py
📊 Logging
DenseMixer provides intelligent logging to track when custom forward methods are used:
INFO - densemixer - DenseMixer: Using custom forward method for Qwen3-MoE
INFO - densemixer - DenseMixer: Using custom forward method for OLMoE
You can also customize the logging as below.
import logging

# Set logging level
logging.getLogger("densemixer").setLevel(logging.INFO)

# Or disable logging entirely
logging.getLogger("densemixer").setLevel(logging.WARNING)
⚡ Efficiency Analysis
FLOPs: 1.46x overhead vs conventional training (theoretical analysis on Qwen3-30B-A3B)
📊 Detailed FLOPs Analysis
Model Training Cost Analysis Results --- Conventional Training for Qwen3-30B-A3B ---
Number of parameters: 30,431,444,992
Number of Forward TFLOPs per layer: 16.85
Number of Backward TFLOPs per layer: 33.70
Number of TFLOPs per layer: 50.54
Peak memory cost: 157.93 GBs


Model Training Cost Analysis Results --- DenseMixer Training for Qwen3-30B-A3B ---
Number of parameters: 30,431,444,992
Number of Forward TFLOPs per layer: 40.04
Number of Backward TFLOPs per layer: 33.70 # we assume DenseMixer doesn't change backward significantly
Number of TFLOPs per layer: 73.74
Peak memory cost: 164.96 GBs

FLOPs: DenseMixer / Conventional = 1.46x
Detailed FLOPs analysis available in efficiency_analysis/flops_compute.py
Memory: Negligible overhead - model weights are already loaded on GPU
Time: Negligible when training with small scale of data
Detailed FLOPs analysis available in efficiency_analysis/flops_compute.py
| Model | Dataset | Conventional | DenseMixer | Overhead |
|---|---|---|---|---|
| Qwen1.5-MoE | Intent (7K) | 22 min | 24 min | +9% |
| Qwen3-MoE | S1 (1K) | 2.8h | 3.6h | +29% |
🚧 Roadmap & Future Improvements
While DenseMixer already delivers significant performance gains, we're working on several improvements to make it more efficient and production-ready:
- Optimize backward FLOPs: Currently backward FLOPs increase alongside forward FLOPs, but this is unnecessary. We'll optimize the backward pass to reduce training overhead while maintaining performance gains
- Integrate modern MoE kernels: Replace transformers' native for-loop MoE implementation with efficient kernels (e.g., grouped_gemm) for better large-scale training performance
- Industry integration: Extend support beyond
open-instruct/llama-factoryto MoE-optimized frameworks likeMegatronfor seamless production adoption
📚 Citation
If you find our work useful, please cite us:
@misc{yao2025densemixer,
  title = {DenseMixer: Improving MoE Post-Training with Precise Router Gradient},
  url = {https://fengyao.notion.site/moe-posttraining},
  author = {Yao, Feng and Cui, Junxia and Zhang, Ruohan and Liu, Liyuan and Hao, Shibo and Zhang, Li and Dong, Chengyu and Wang, Shuohang and Shen, Yelong and Gao, Jianfeng and Shang, Jingbo},
  journal = {Feng Yao's Notion},
  year = {2025},
  month = jun
}
Questions?
If you have any questions related to the code or the blog, feel free to reach out to us at fengyao@ucsd.edu.
Similar repos



Official implementation for DenseMixer: Improving MoE Post-Training with Precise Router Gradient
See the codeREADME
🎨 DenseMixer 🎨
Improving MoE Post-Training with Precise Router Gradients (Blog)
What is DenseMixer? • Key Features • Experiments • Quick Start • Efficiency • Citation
DenseMixer is a novel MoE post-training technique that empowers MoE training with more precise router gradient estimation, consistently outperforming conventional MoE training in downstream tasks.
What is DenseMixer?
DenseMixer addresses the non-differentiable Top-K routing problem in MoE training via straight-through estimator (STE). This enables more precise router gradients by computing all experts's output during forward pass for better gradient estimation during backward pass. For more technical details, please refer to our blog.
🚀 Key Features
- Plug-and-play: Zero code changes required
- Universal compatibility: Works with any MoE using Top-K routing
- Performance gains: Consistently outperforms conventional MoE training
- Parameter-efficient: Compatible with LoRA and other PEFT methods
- No inference overhead: Zero impact on model inference speed
📈 Experiments
DenseMixer consistently outperforms conventional MoE training across:
- Model scales: 7B, 14B, 30B parameters
- Architectures: With/without shared experts
- Training methods: From scratch and up-cycling
- Data types: Instruction tuning and long reasoning data
Reproducible Experiments: For detailed training scripts, configurations, and evaluation code, please refer to the experiments folder.
📊 Qwen1.5-MoE-A2.7B (14B): +2.2% average improvement across 7 tasks
Full Fine-tuning Results:
| Method | GSM | MBPP | HumanEval | Intent | Law | Summary | Translation | Avg |
|---|---|---|---|---|---|---|---|---|
| Base Model | 38.69 | 38.84 | 32.31 | 16.83 | 18.20 | 28.29 | 16.53 | 27.10 |
| Frozen Router | 53.37 | 35.20 | 37.10 | 82.20 | 33.01 | 38.29 | 32.75 | 44.56 |
| Conventional | 53.42 | 34.60 | 36.43 | 81.80 | 29.25 | 37.80 | 33.02 | 43.76 |
| DenseMixer | 55.16 | 35.40 | 39.68 | 83.40 | 33.83 | 40.56 | 33.90 | 45.99 |
| Gain | +1.74 | +0.80 | +3.25 | +1.60 | +4.58 | +2.76 | +0.88 | +2.23 |
LoRA Fine-tuning Results:
| Method | GSM | MBPP | HumanEval | Intent | Law | Summary | Translation | Avg |
|---|---|---|---|---|---|---|---|---|
| Frozen Router -lora | 46.77 | 31.40 | 36.58 | 71.00 | 30.30 | 30.19 | 28.08 | 39.19 |
| Conventional -lora | 43.89 | 34.00 | 38.41 | 64.80 | 28.80 | 37.99 | 26.14 | 39.15 |
| DenseMixer -lora | 47.24 | 35.40 | 38.41 | 71.80 | 31.80 | 40.20 | 29.25 | 42.01 |
| Gain | +3.35 | +1.40 | +0.00 | +7.00 | +3.00 | +2.21 | +3.11 | +2.86 |
📊 OLMoE-1B-7B: +2.9% average improvement across 7 tasks
Full Fine-tuning Results:
| Method | GSM | MBPP | HumanEval | Intent | Law | Summary | Translation | Avg |
|---|---|---|---|---|---|---|---|---|
| Base Model | 15.85 | 19.80 | 10.97 | 0.20 | 5.70 | 7.40 | 11.09 | 10.14 |
| Frozen Router | 44.88 | 17.8 | 7.23 | 72.80 | 22.50 | 36.05 | 28.29 | 32.79 |
| Conventional | 45.94 | 23.4 | 18.92 | 74.60 | 22.35 | 35.99 | 26.89 | 35.44 |
| DenseMixer | 49.00 | 25.12 | 20.73 | 77.40 | 23.02 | 40.64 | 32.55 | 38.35 |
| Gain | +3.06 | +1.72 | +1.81 | +2.80 | +0.67 | +4.65 | +5.66 | +2.91 |
LoRA Fine-tuning Results:
| Method | GSM | MBPP | HumanEval | Intent | Law | Summary | Translation | Avg |
|---|---|---|---|---|---|---|---|---|
| Frozen Router -lora | 45.03 | 24.2 | 17.07 | 55.80 | 21.30 | 37.70 | 28.19 | 32.76 |
| Conventional -lora | 44.58 | 24.2 | 15.85 | 60.20 | 21.60 | 37.30 | 26.22 | 32.85 |
| DenseMixer -lora | 45.38 | 26.2 | 16.48 | 66.60 | 24.70 | 40.80 | 29.43 | 35.66 |
| Gain | +0.80 | +2.00 | +0.63 | +6.40 | +3.10 | +3.50 | +3.21 | +2.81 |
📊 Qwen3-30B-A3B: +3.7% improvement on GPQA-Diamond
Nemotron-Code Dataset (35K samples):
| Method | HumanEval (avg@4) | HumanEval+ (avg@4) | MBPP (avg@1) | LiveCodeBench (avg@4) | Avg |
|---|---|---|---|---|---|
| Base Model | 65.24 | 60.06 | 53.60 | 16.85 | 48.94 |
| Conventional | 92.23 | 86.89 | 80.80 | 32.26 | 67.21 |
| DenseMixer | 93.59 | 89.02 | 82.00 | 34.31 | 68.80 |
| Gain | +1.36 | +2.13 | +1.20 | +2.05 | +1.59 |
Stanford S1 Dataset (1K samples):
| Method | GPQA Diamond (avg@8) | AIME 2024 (avg@32) | AIME 2025 (avg@32) | Olympiad Bench (avg@1) | MATH-500 (avg@1) | Avg |
|---|---|---|---|---|---|---|
| Base Model | 38.88 | 20.63 | 7.71 | 34.81 | 72.80 | 34.97 |
| Conventional | 54.80 | 61.56 | 45.63 | 57.33 | 93.40 | 62.54 |
| DenseMixer | 58.52 | 63.85 | 45.83 | 58.51 | 93.60 | 64.06 |
| Gain | +3.72 | +2.29 | +0.20 | +1.18 | +0.20 | +1.52 |
Results shown for temperature=0.6, top_p=0.95 decoding parameters
Additional Decoding Parameters:
Temperature=0.7, top_p=0.8
Nemotron-Code:
| Method | HumanEval (avg@4) | HumanEval+ (avg@4) | MBPP (avg@1) | LiveCodeBench (avg@4) | Avg |
|---|---|---|---|---|---|
| Conventional | 91.01 | 85.37 | 76.80 | 29.39 | 65.59 |
| DenseMixer | 91.92 | 86.89 | 80.80 | 31.89 | 67.32 |
Stanford S1:
| Method | GPQA Diamond (avg@8) | AIME 2024 (avg@32) | AIME 2025 (avg@32) | Olympiad Bench (avg@1) | MATH-500 (avg@1) | Avg |
|---|---|---|---|---|---|---|
| Conventional | 54.23 | 61.67 | 44.27 | 55.41 | 92.20 | 61.56 |
| DenseMixer | 55.80 | 63.13 | 45.31 | 57.18 | 93.00 | 62.88 |
Temperature=1.0, top_p=0.7
Nemotron-Code:
| Method | HumanEval (avg@4) | HumanEval+ (avg@4) | MBPP (avg@1) | LiveCodeBench (avg@4) | Avg |
|---|---|---|---|---|---|
| Conventional | 90.85 | 86.59 | 79.00 | 33.42 | 67.59 |
| DenseMixer | 93.29 | 88.87 | 84.39 | 34.40 | 68.99 |
Stanford S1:
| Method | GPQA Diamond (avg@8) | AIME 2024 (avg@32) | AIME 2025 (avg@32) | Olympiad Bench (avg@1) | MATH-500 (avg@1) | Avg |
|---|---|---|---|---|---|---|
| Conventional | 56.55 | 63.65 | 46.15 | 59.11 | 93.00 | 63.69 |
| DenseMixer | 58.14 | 62.71 | 47.50 | 57.77 | 93.80 | 63.98 |
⚡ Quick Start
1. Installation
pip install densemixer
2. Setup (One-time)
densemixer setup
3. Enable DenseMixer
export DENSEMIXER_ENABLED=1
4. Use Your MoE Models
from transformers import Qwen3MoeForCausalLM

# DenseMixer automatically patches the model
model = Qwen3MoeForCausalLM.from_pretrained("Qwen/Qwen3-MoE-30B-A3B")

# Train as usual - no code changes needed!
🔧 Configuration
DenseMixer currently supports the following models.
- Qwen3-MoE (30B parameters)
- Qwen1.5-MoE (14B parameters)
- OLMoE (7B parameters)
DenseMixer uses environment variables for configuration:
| Variable | Description | Default |
|---|---|---|
DENSEMIXER_ENABLED | Master switch (set to 1 to enable) | 0 |
DENSEMIXER_QWEN3 | Enable for Qwen3-MoE models | 1 |
DENSEMIXER_QWEN2 | Enable for Qwen1.5-MoE models | 1 |
DENSEMIXER_OLMOE | Enable for OLMoE models | 1 |
Usage Examples
Enable for all models:
export DENSEMIXER_ENABLED=1
python your_training_script.py
Enable only for specific models:
export DENSEMIXER_ENABLED=1
export DENSEMIXER_QWEN3=1
export DENSEMIXER_QWEN2=0
export DENSEMIXER_OLMOE=0
python your_training_script.py
Disable (default behavior):
# No environment variables needed
python your_training_script.py
📊 Logging
DenseMixer provides intelligent logging to track when custom forward methods are used:
INFO - densemixer - DenseMixer: Using custom forward method for Qwen3-MoE
INFO - densemixer - DenseMixer: Using custom forward method for OLMoE
You can also customize the logging as below.
import logging

# Set logging level
logging.getLogger("densemixer").setLevel(logging.INFO)

# Or disable logging entirely
logging.getLogger("densemixer").setLevel(logging.WARNING)
⚡ Efficiency Analysis
FLOPs: 1.46x overhead vs conventional training (theoretical analysis on Qwen3-30B-A3B)
📊 Detailed FLOPs Analysis
Model Training Cost Analysis Results --- Conventional Training for Qwen3-30B-A3B ---
Number of parameters: 30,431,444,992
Number of Forward TFLOPs per layer: 16.85
Number of Backward TFLOPs per layer: 33.70
Number of TFLOPs per layer: 50.54
Peak memory cost: 157.93 GBs


Model Training Cost Analysis Results --- DenseMixer Training for Qwen3-30B-A3B ---
Number of parameters: 30,431,444,992
Number of Forward TFLOPs per layer: 40.04
Number of Backward TFLOPs per layer: 33.70 # we assume DenseMixer doesn't change backward significantly
Number of TFLOPs per layer: 73.74
Peak memory cost: 164.96 GBs

FLOPs: DenseMixer / Conventional = 1.46x
Detailed FLOPs analysis available in efficiency_analysis/flops_compute.py
Memory: Negligible overhead - model weights are already loaded on GPU
Time: Negligible when training with small scale of data
Detailed FLOPs analysis available in efficiency_analysis/flops_compute.py
| Model | Dataset | Conventional | DenseMixer | Overhead |
|---|---|---|---|---|
| Qwen1.5-MoE | Intent (7K) | 22 min | 24 min | +9% |
| Qwen3-MoE | S1 (1K) | 2.8h | 3.6h | +29% |
🚧 Roadmap & Future Improvements
While DenseMixer already delivers significant performance gains, we're working on several improvements to make it more efficient and production-ready:
- Optimize backward FLOPs: Currently backward FLOPs increase alongside forward FLOPs, but this is unnecessary. We'll optimize the backward pass to reduce training overhead while maintaining performance gains
- Integrate modern MoE kernels: Replace transformers' native for-loop MoE implementation with efficient kernels (e.g., grouped_gemm) for better large-scale training performance
- Industry integration: Extend support beyond
open-instruct/llama-factoryto MoE-optimized frameworks likeMegatronfor seamless production adoption
📚 Citation
If you find our work useful, please cite us:
@misc{yao2025densemixer,
  title = {DenseMixer: Improving MoE Post-Training with Precise Router Gradient},
  url = {https://fengyao.notion.site/moe-posttraining},
  author = {Yao, Feng and Cui, Junxia and Zhang, Ruohan and Liu, Liyuan and Hao, Shibo and Zhang, Li and Dong, Chengyu and Wang, Shuohang and Shen, Yelong and Gao, Jianfeng and Shang, Jingbo},
  journal = {Feng Yao's Notion},
  year = {2025},
  month = jun
}
Questions?
If you have any questions related to the code or the blog, feel free to reach out to us at fengyao@ucsd.edu.