
Official code for paper: Text-to-Image Rectified Flow as Plug-and-Play Priors [ICLR 2025]
Python
142
17 commits
updated Apr 16, 2025
README
[ICLR 2025] Text-to-Image Rectified Flow as Plug-and-Play Priors

by Xiaofeng Yang, Cheng Chen, Xulei Yang, Fayao Liu, Guosheng Lin.
Large-scale diffusion models have achieved remarkable performance in generative tasks. Beyond their initial training applications, these models have proven their ability to function as versatile plug-and-play priors. For instance, 2D diffusion models can serve as loss functions to optimize 3D implicit models. Rectified flow, a novel class of generative models, enforces a linear progression from the source to the target distribution and has demonstrated superior performance across various domains. Compared to diffusion-based methods, rectified flow approaches surpass in terms of generation quality and efficiency, requiring fewer inference steps. In this work, we present theoretical and experimental evidence demonstrating that rectified flow based methods offer similar functionalities to diffusion models — they can also serve as effective priors. Besides the generative capabilities of diffusion priors, motivated by the unique time-symmetry properties of rectified flow models, a variant of our method can additionally perform image inversion. Experimentally, our rectified flow-based priors outperform their diffusion counterparts — the SDS and VSD losses — in text-to-3D generation. Our method also displays competitive performance in image inversion and editing.
Updates
- 2024/06/05: Code release.
- 2024/06/21: Add support for Stable Diffusion 3 (June, Medium version).
- 2024/10/08: We extend the paper with Stochastic Interpolants. In addition to the rectified flow models, the new theory can also be applied to other flow-matching based methods and diffusion models expressed in PF-ODE. An updated version has been uploaded to arxiv. We also optimized the codes to help understanding.
- 2025/02/17: Update the editing code to match the ICLR25 camera-ready version. Support SD3.5. Additional notes on Flux.
ToDo
- Code release. The base text-to-image model is based on InstaFlow.
- Add support for Stable Diffusion 3 after the model is released.
- The SD3 configs can be easily modified to support SD 3.5, but I still find SD3 to be better.
Notes on Flux
Flux is the SOTA text-to-image model. However, it is a distilled model and lacks native CFG support. I tested the official Flux model on 3D tasks, but its performance was not as strong as SD3. Additionally, the model is quite large, requiring at least 46GB of GPU RAM. If you are interested, you may consider using this CFG version of flux instead.
Installation
Our codes are based on the implementations of ThreeStudio. Please follow the instructions in ThreeStudio to install the dependencies.
To use SD3: please follow the instructions here to login to huggingface and update diffusers. When you run our codes, the models will be automatically downloaded.
Quickstart
Using Stable Diffusion 3 as the base rectified-flow model.
2D Playground (SD3)
# run RFDS in 2D space for image generation
python 2dplayground_RFDS_sd3.py

# run RFDS-Rev in 2D space for image generation
python 2dplayground_RFDS_Rev_sd3.py

# run iRFDS in 2D space for image editing (requires 20g GPU memory)
python 2dplayground_iRFDS_sd3.py
Text-to-3D with RFDS (SD3) (requires 46g GPU memory)
python launch.py --config configs/rfds_sd3.yaml --train --gpu 0 system.prompt_processor.prompt="A DSLR photo of a hamburger"
Text-to-3D with RFDS-Rev (SD3) (requires >46g GPU memory)
python launch.py --config configs/rfds-rev_sd3.yaml --train --gpu 0 system.prompt_processor.prompt="A DSLR photo of a hamburger"
Text-to-3D with RFDS-Rev, reduced memory usage (SD3) (able to run on 46g GPUs)
python launch.py --config configs/rfds-rev_sd3_low_memory.yaml --train --gpu 0 system.prompt_processor.prompt="A DSLR photo of a hamburger"
Results
Optimization in 2D space (SD3)
Caption: A DSLR image of a hamburger
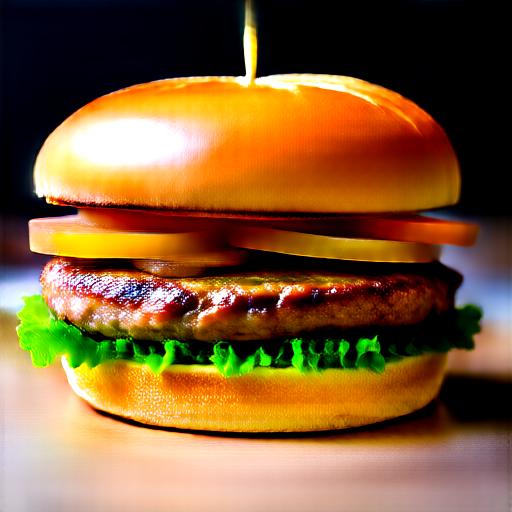
RFDS |
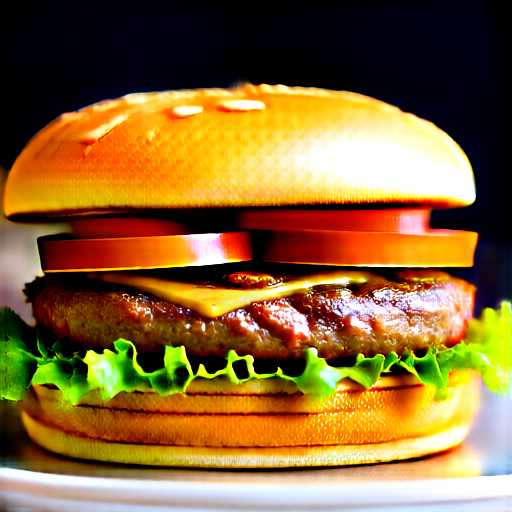
RFDS-Rev |
Text-to-3D with RFDS (NeRF backbone, SD3)
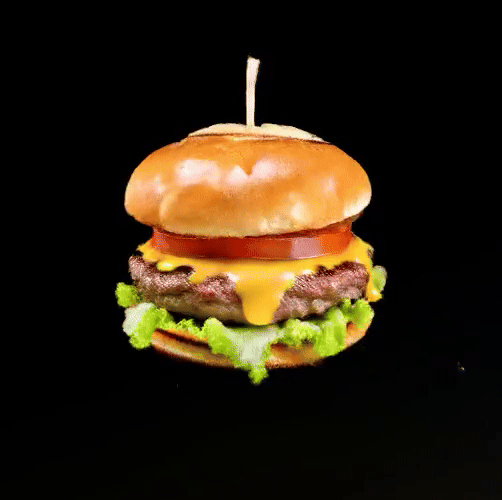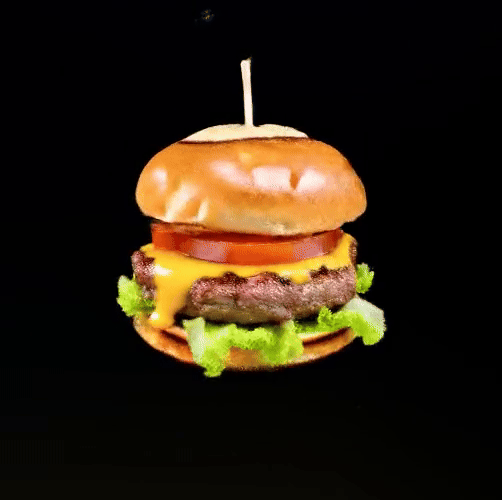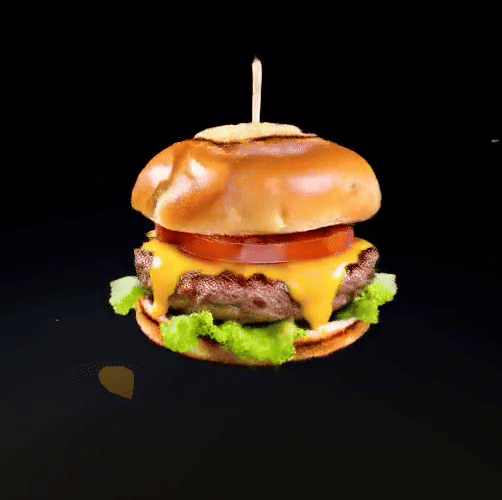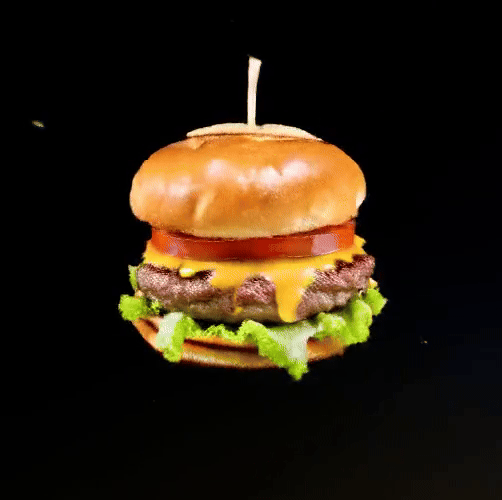
A DSLR image of a hamburger |
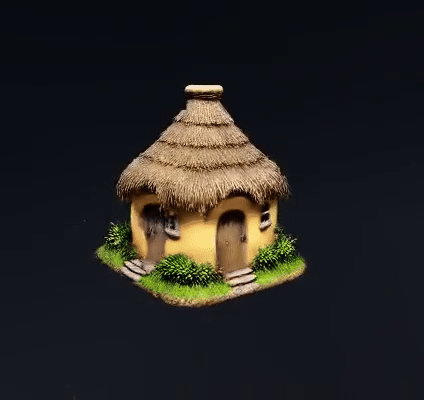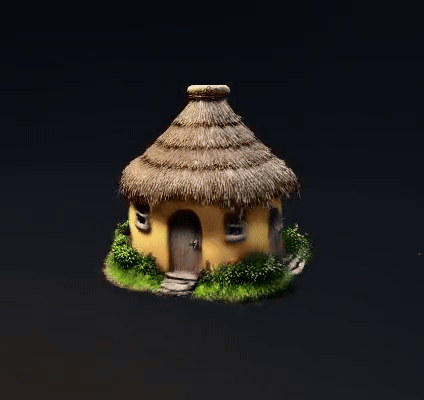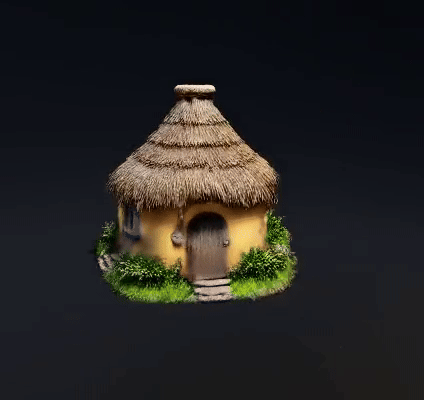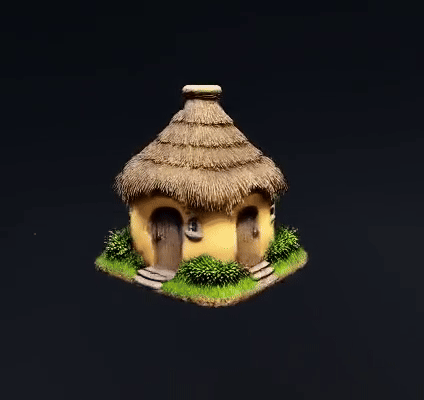
A 3d model of an adorable cottage with a thatched roof |
Text-to-3D with RFDS-Rev (NeRF backbone, SD3)
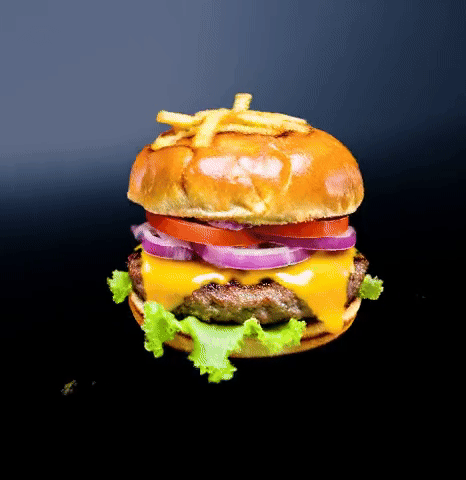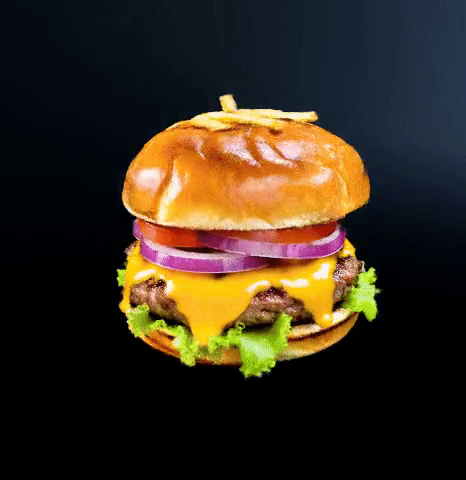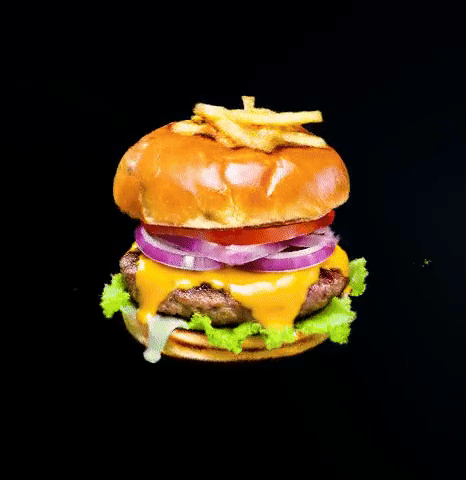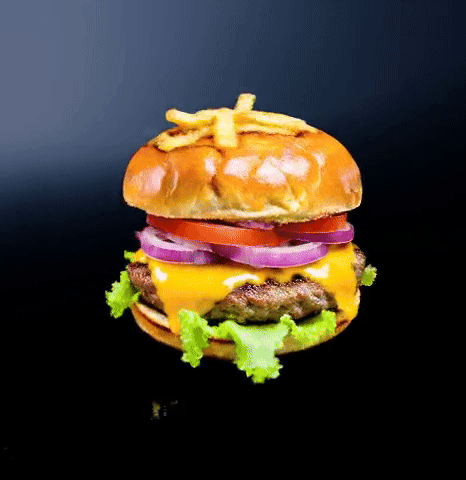
A DSLR image of a hamburger |
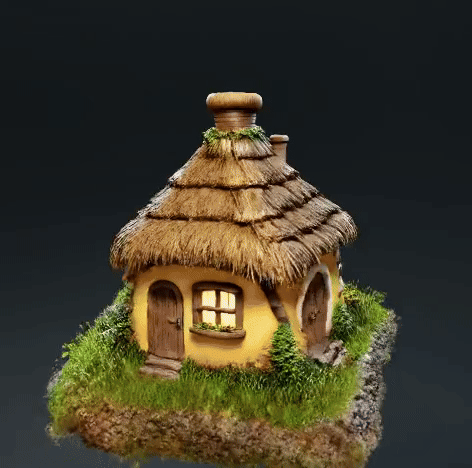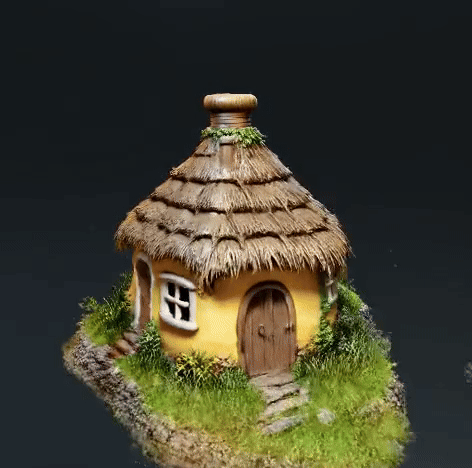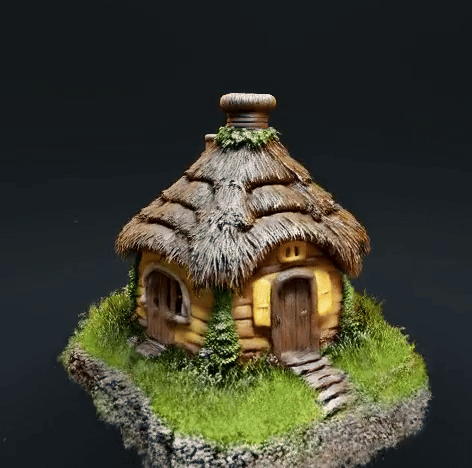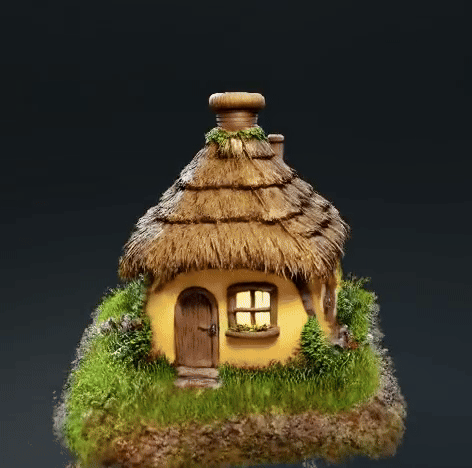
A 3d model of an adorable cottage with a thatched roof |
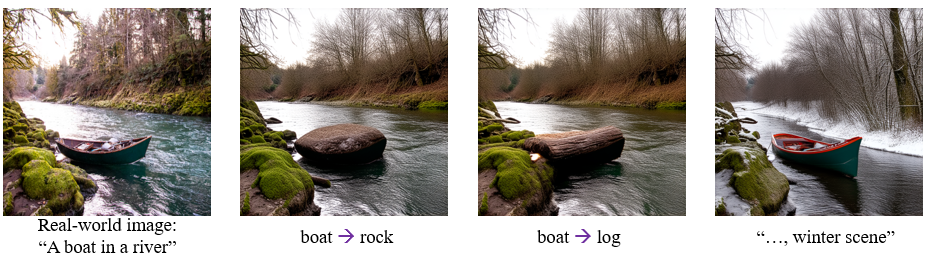
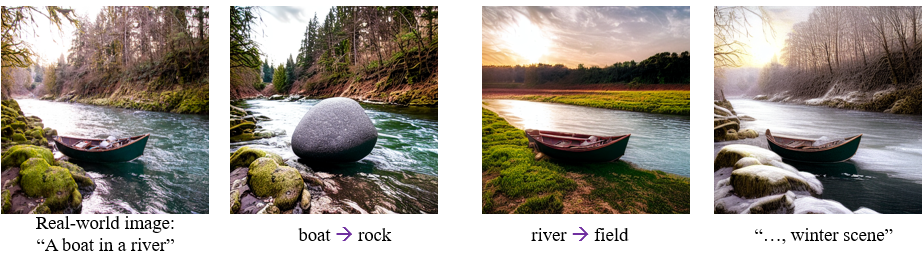
Text guided editing with iRFDS (SD3)
Remarks for SD3
- In SD3, the RFDS baseline already delivers great results. If your GPU memory is limited, it's recommended to use the RFDS baseline version.
- SD3 is not trained with reflow (check out the InstaFlow paper for more on that). So, we found it a bit tougher to do image inversion using iRFDS and SD3. Additionally, the transformer backbone makes it difficult to replace objects with text control without using prompt-to-prompt.
Using InstaFlow as the base rectified-flow model (use less GPU memory).
2D Playground (InstaFlow)
# run RFDS in 2D space for image generation
python 2dplayground_RFDS.py

# run RFDS-Rev in 2D space for image generation
python 2dplayground_RFDS_Rev.py

# run iRFDS in 2D space for image editing
python 2dplayground_iRFDS.py
Text-to-3D with RFDS (InstaFlow)
python launch.py --config configs/rfds.yaml --train --gpu 0 system.prompt_processor.prompt="A DSLR photo of a hamburger"
Text-to-3D with RFDS-Rev (InstaFlow)
python launch.py --config configs/rfds-rev.yaml --train --gpu 0 system.prompt_processor.prompt="A DSLR photo of a hamburger"
Results
Optimization in 2D space (InstaFlow)
Caption: an astronaut is riding a horse
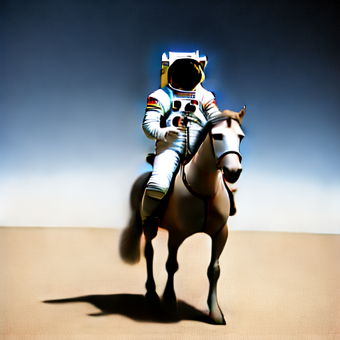
RFDS |
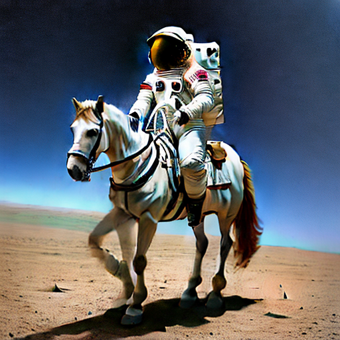
RFDS-Rev |
Text-to-3D with RFDS-Rev (NeRF backbone, InstaFlow)
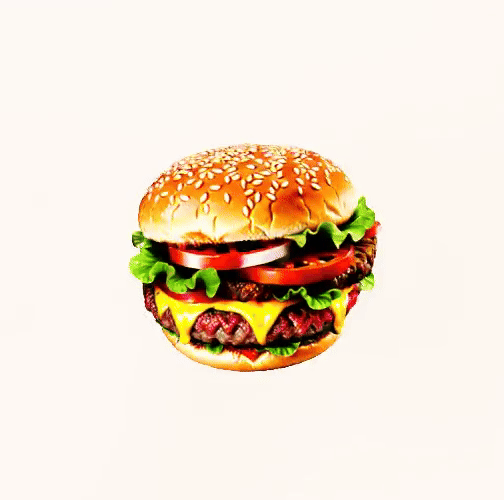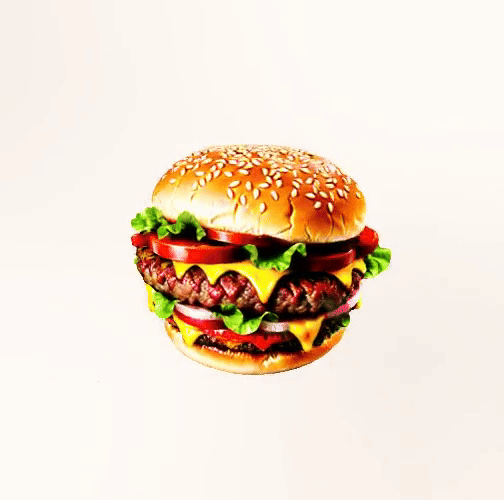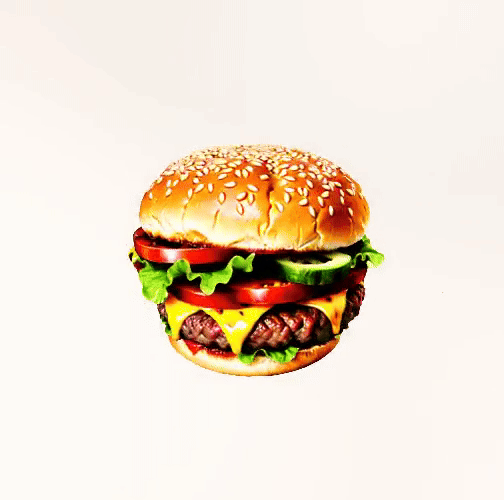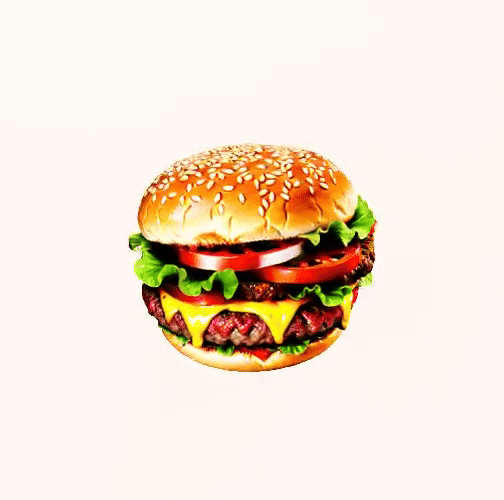
A DSLR image of a hamburger |
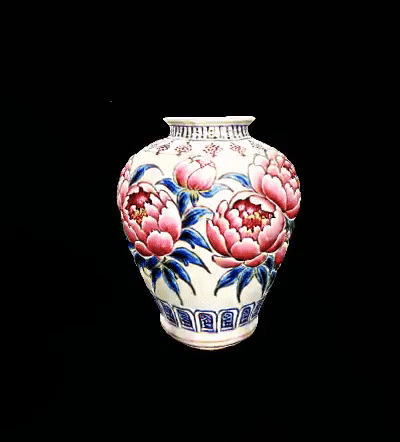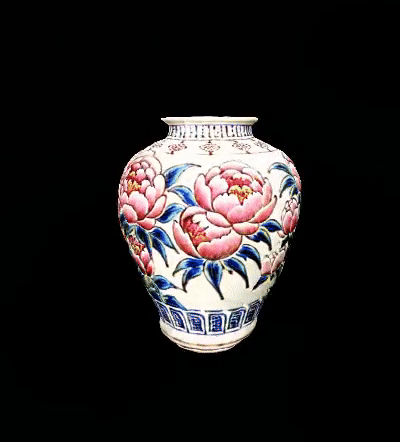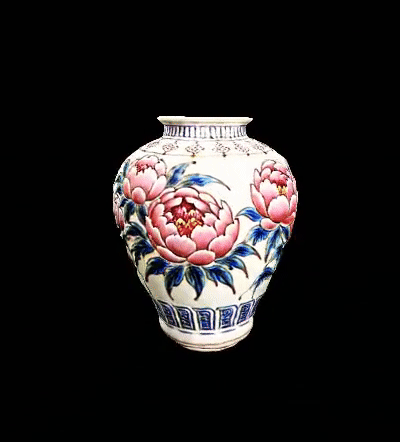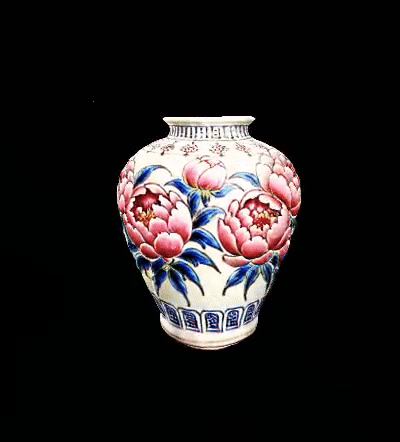
An intricate ceramic vase with peonies painted on it |
Text guided editing with iRFDS (InstaFlow)
Credits
RFDS is built on the following open-source projects:
- ThreeStudio Main Framework
- InstaFlow Large-scale text-to-image Rectified Flow model
Citation
@inproceedings{
yang2025texttoimage,
title={Text-to-Image Rectified Flow as Plug-and-Play Priors},
author={Xiaofeng Yang and Chen Cheng and Xulei Yang and Fayao Liu and Guosheng Lin},
booktitle={The Thirteenth International Conference on Learning Representations},
year={2025},
url={https://openreview.net/forum?id=SzPZK856iI}
}
Significant stargazers

3 followers · starred Jun 2025
Similar repos


Official code for paper: Text-to-Image Rectified Flow as Plug-and-Play Priors [ICLR 2025]
Python
142
17 commits
updated Apr 16, 2025
README
[ICLR 2025] Text-to-Image Rectified Flow as Plug-and-Play Priors
by Xiaofeng Yang, Cheng Chen, Xulei Yang, Fayao Liu, Guosheng Lin.
Large-scale diffusion models have achieved remarkable performance in generative tasks. Beyond their initial training applications, these models have proven their ability to function as versatile plug-and-play priors. For instance, 2D diffusion models can serve as loss functions to optimize 3D implicit models. Rectified flow, a novel class of generative models, enforces a linear progression from the source to the target distribution and has demonstrated superior performance across various domains. Compared to diffusion-based methods, rectified flow approaches surpass in terms of generation quality and efficiency, requiring fewer inference steps. In this work, we present theoretical and experimental evidence demonstrating that rectified flow based methods offer similar functionalities to diffusion models — they can also serve as effective priors. Besides the generative capabilities of diffusion priors, motivated by the unique time-symmetry properties of rectified flow models, a variant of our method can additionally perform image inversion. Experimentally, our rectified flow-based priors outperform their diffusion counterparts — the SDS and VSD losses — in text-to-3D generation. Our method also displays competitive performance in image inversion and editing.
Updates
- 2024/06/05: Code release.
- 2024/06/21: Add support for Stable Diffusion 3 (June, Medium version).
- 2024/10/08: We extend the paper with Stochastic Interpolants. In addition to the rectified flow models, the new theory can also be applied to other flow-matching based methods and diffusion models expressed in PF-ODE. An updated version has been uploaded to arxiv. We also optimized the codes to help understanding.
- 2025/02/17: Update the editing code to match the ICLR25 camera-ready version. Support SD3.5. Additional notes on Flux.
ToDo
- Code release. The base text-to-image model is based on InstaFlow.
- Add support for Stable Diffusion 3 after the model is released.
- The SD3 configs can be easily modified to support SD 3.5, but I still find SD3 to be better.
Notes on Flux
Flux is the SOTA text-to-image model. However, it is a distilled model and lacks native CFG support. I tested the official Flux model on 3D tasks, but its performance was not as strong as SD3. Additionally, the model is quite large, requiring at least 46GB of GPU RAM. If you are interested, you may consider using this CFG version of flux instead.
Installation
Our codes are based on the implementations of ThreeStudio. Please follow the instructions in ThreeStudio to install the dependencies.
To use SD3: please follow the instructions here to login to huggingface and update diffusers. When you run our codes, the models will be automatically downloaded.
Quickstart
Using Stable Diffusion 3 as the base rectified-flow model.
2D Playground (SD3)
# run RFDS in 2D space for image generation
python 2dplayground_RFDS_sd3.py

# run RFDS-Rev in 2D space for image generation
python 2dplayground_RFDS_Rev_sd3.py

# run iRFDS in 2D space for image editing (requires 20g GPU memory)
python 2dplayground_iRFDS_sd3.py
Text-to-3D with RFDS (SD3) (requires 46g GPU memory)
python launch.py --config configs/rfds_sd3.yaml --train --gpu 0 system.prompt_processor.prompt="A DSLR photo of a hamburger"
Text-to-3D with RFDS-Rev (SD3) (requires >46g GPU memory)
python launch.py --config configs/rfds-rev_sd3.yaml --train --gpu 0 system.prompt_processor.prompt="A DSLR photo of a hamburger"
Text-to-3D with RFDS-Rev, reduced memory usage (SD3) (able to run on 46g GPUs)
python launch.py --config configs/rfds-rev_sd3_low_memory.yaml --train --gpu 0 system.prompt_processor.prompt="A DSLR photo of a hamburger"
Results
Optimization in 2D space (SD3)
Caption: A DSLR image of a hamburger
|
RFDS |
RFDS-Rev |
Text-to-3D with RFDS (NeRF backbone, SD3)
|
A DSLR image of a hamburger |
A 3d model of an adorable cottage with a thatched roof |
Text-to-3D with RFDS-Rev (NeRF backbone, SD3)
|
A DSLR image of a hamburger |
A 3d model of an adorable cottage with a thatched roof |
Text guided editing with iRFDS (SD3)
Remarks for SD3
- In SD3, the RFDS baseline already delivers great results. If your GPU memory is limited, it's recommended to use the RFDS baseline version.
- SD3 is not trained with reflow (check out the InstaFlow paper for more on that). So, we found it a bit tougher to do image inversion using iRFDS and SD3. Additionally, the transformer backbone makes it difficult to replace objects with text control without using prompt-to-prompt.
Using InstaFlow as the base rectified-flow model (use less GPU memory).
2D Playground (InstaFlow)
# run RFDS in 2D space for image generation
python 2dplayground_RFDS.py

# run RFDS-Rev in 2D space for image generation
python 2dplayground_RFDS_Rev.py

# run iRFDS in 2D space for image editing
python 2dplayground_iRFDS.py
Text-to-3D with RFDS (InstaFlow)
python launch.py --config configs/rfds.yaml --train --gpu 0 system.prompt_processor.prompt="A DSLR photo of a hamburger"
Text-to-3D with RFDS-Rev (InstaFlow)
python launch.py --config configs/rfds-rev.yaml --train --gpu 0 system.prompt_processor.prompt="A DSLR photo of a hamburger"
Results
Optimization in 2D space (InstaFlow)
Caption: an astronaut is riding a horse
|
RFDS |
RFDS-Rev |
Text-to-3D with RFDS-Rev (NeRF backbone, InstaFlow)
|
A DSLR image of a hamburger |
An intricate ceramic vase with peonies painted on it |
Text guided editing with iRFDS (InstaFlow)
Credits
RFDS is built on the following open-source projects:
- ThreeStudio Main Framework
- InstaFlow Large-scale text-to-image Rectified Flow model
Citation
@inproceedings{
yang2025texttoimage,
title={Text-to-Image Rectified Flow as Plug-and-Play Priors},
author={Xiaofeng Yang and Chen Cheng and Xulei Yang and Fayao Liu and Guosheng Lin},
booktitle={The Thirteenth International Conference on Learning Representations},
year={2025},
url={https://openreview.net/forum?id=SzPZK856iI}
}
Significant stargazers
3 followers · starred Jun 2025