
Jev vs Claude — Structured Classification Benchmark. 5 tasks, 5 models, 20 cases each. Comparing Jev (via OpenRouter) against Claude Opus 4.6 and Sonnet 4.6, with and without adaptive thinking.
HTML
0
1 commits
updated Sep 18, 2026
See what people are saying (1)
README
Jev vs Claude — Structured Classification Benchmark
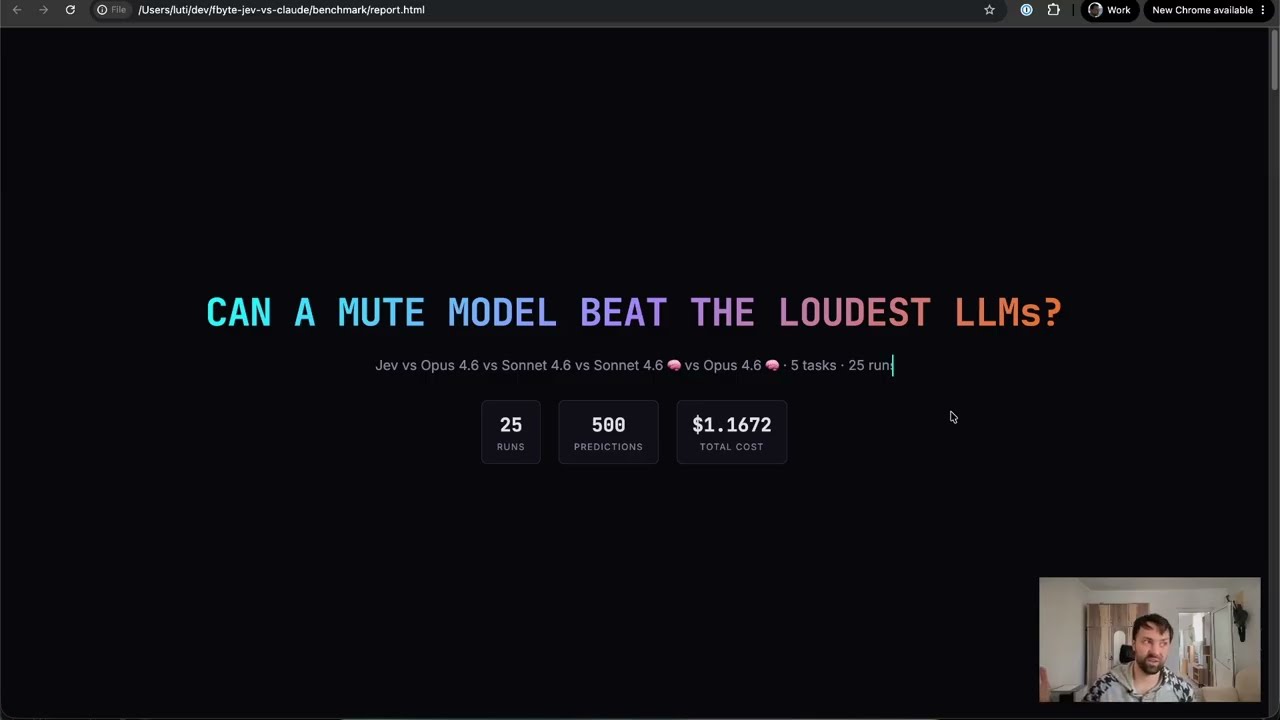
5 tasks, 5 models, 20 cases each. Comparing Jev (via OpenRouter) against Claude Opus 4.6 and Sonnet 4.6 — with and without adaptive thinking.
Models
| Key | Model | Thinking |
|---|---|---|
jev | typesafe/jev-1.13 | N/A |
opus | claude-opus-4-6 | off |
sonnet | claude-sonnet-4-6 | off |
opus-think | claude-opus-4-6 | adaptive |
sonnet-think | claude-sonnet-4-6 | adaptive |
Tasks
| Task | What it does |
|---|---|
| Bouncer | Intent routing — classify customer messages |
| Lie Detector | Fake review detection, sentiment, PII flagging |
| Oracle | Bug triage — priority, component, regression |
| Bartender | Content moderation — toxicity type and severity |
| Customs Agent | Contract clause classification and risk assessment |
Setup
export OPENROUTER_API_KEY=sk-or-v1-...
export ANTHROPIC_API_KEY=sk-ant-...

cd benchmark
pip install -r requirements.txt
Run
python run.py                        # all 5 models, all 5 tasks (25 runs)
python run.py --model jev            # single model
python run.py --model opus-think     # opus with adaptive thinking
python run.py --task bouncer         # single task, all models
python run.py --model sonnet --task oracle   # one model, one task
Results append to results.json — re-running a model/task combo replaces its previous results.
Report
python report.py # generates report.html from results.json
Contributors

1 commits
Similar repos


Languages
HTML
75.0%
Python
25.0%
Jev vs Claude — Structured Classification Benchmark. 5 tasks, 5 models, 20 cases each. Comparing Jev (via OpenRouter) against Claude Opus 4.6 and Sonnet 4.6, with and without adaptive thinking.
HTML
0
1 commits
updated Sep 18, 2026
See what people are saying (1)
README
Jev vs Claude — Structured Classification Benchmark
5 tasks, 5 models, 20 cases each. Comparing Jev (via OpenRouter) against Claude Opus 4.6 and Sonnet 4.6 — with and without adaptive thinking.
Models
| Key | Model | Thinking |
|---|---|---|
jev | typesafe/jev-1.13 | N/A |
opus | claude-opus-4-6 | off |
sonnet | claude-sonnet-4-6 | off |
opus-think | claude-opus-4-6 | adaptive |
sonnet-think | claude-sonnet-4-6 | adaptive |
Tasks
| Task | What it does |
|---|---|
| Bouncer | Intent routing — classify customer messages |
| Lie Detector | Fake review detection, sentiment, PII flagging |
| Oracle | Bug triage — priority, component, regression |
| Bartender | Content moderation — toxicity type and severity |
| Customs Agent | Contract clause classification and risk assessment |
Setup
export OPENROUTER_API_KEY=sk-or-v1-...
export ANTHROPIC_API_KEY=sk-ant-...

cd benchmark
pip install -r requirements.txt
Run
python run.py                        # all 5 models, all 5 tasks (25 runs)
python run.py --model jev            # single model
python run.py --model opus-think     # opus with adaptive thinking
python run.py --task bouncer         # single task, all models
python run.py --model sonnet --task oracle   # one model, one task
Results append to results.json — re-running a model/task combo replaces its previous results.
Report
python report.py # generates report.html from results.json
Similar repos
Contributors
1 commits
Languages
HTML
75.0%
Python
25.0%