
[NeurIPS 2025] MINT-CoT: Enabling Interleaved Visual Tokens in Mathematical Chain-of-Thought Reasoning
Python
108
9 commits
updated Sep 19, 2025
README
🌟🔥 [NeurIPS 2025] MINT-CoT: Enabling Interleaved Visual Tokens in Mathematical Chain-of-Thought Reasoning
Official repository for the paper "MINT-CoT: Enabling Interleaved Visual Tokens in Mathematical Chain-of-Thought Reasoning".
[📖 Paper] [🤗 Dataset] [🤗 Model]
💥 News
- [2025.09.19] MINT-CoT has been accepted by NeurIPS 2025! 🎉🎉
- [2025.06.06] We release the arxiv paper and the code. 🔥
👀 About MINT-CoT
Chain-of-Thought (CoT) has widely enhanced mathematical reasoning in Large Language Models (LLMs), but it still remains challenging for extending it to multi modal domains. Existing works either adopt a similar textual reasoning for image input, or seek to interleave visual signals into mathematical CoT. However, they face three key limitations for math problem-solving: reliance on coarse-grained box-shaped image regions, limited perception of vision encoders on math content, and dependence on external capabilities for visual modification.
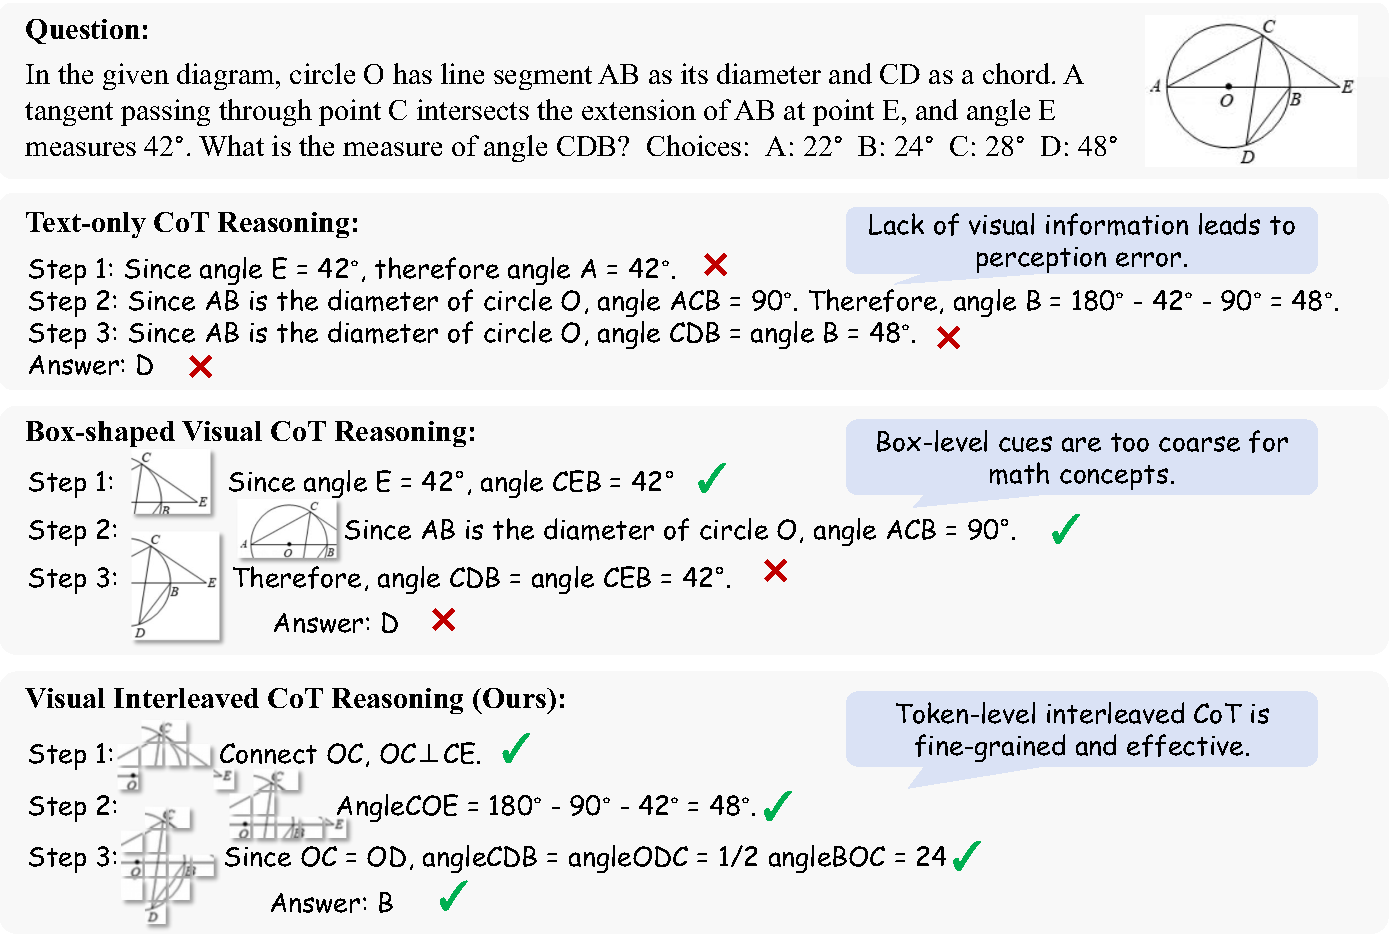
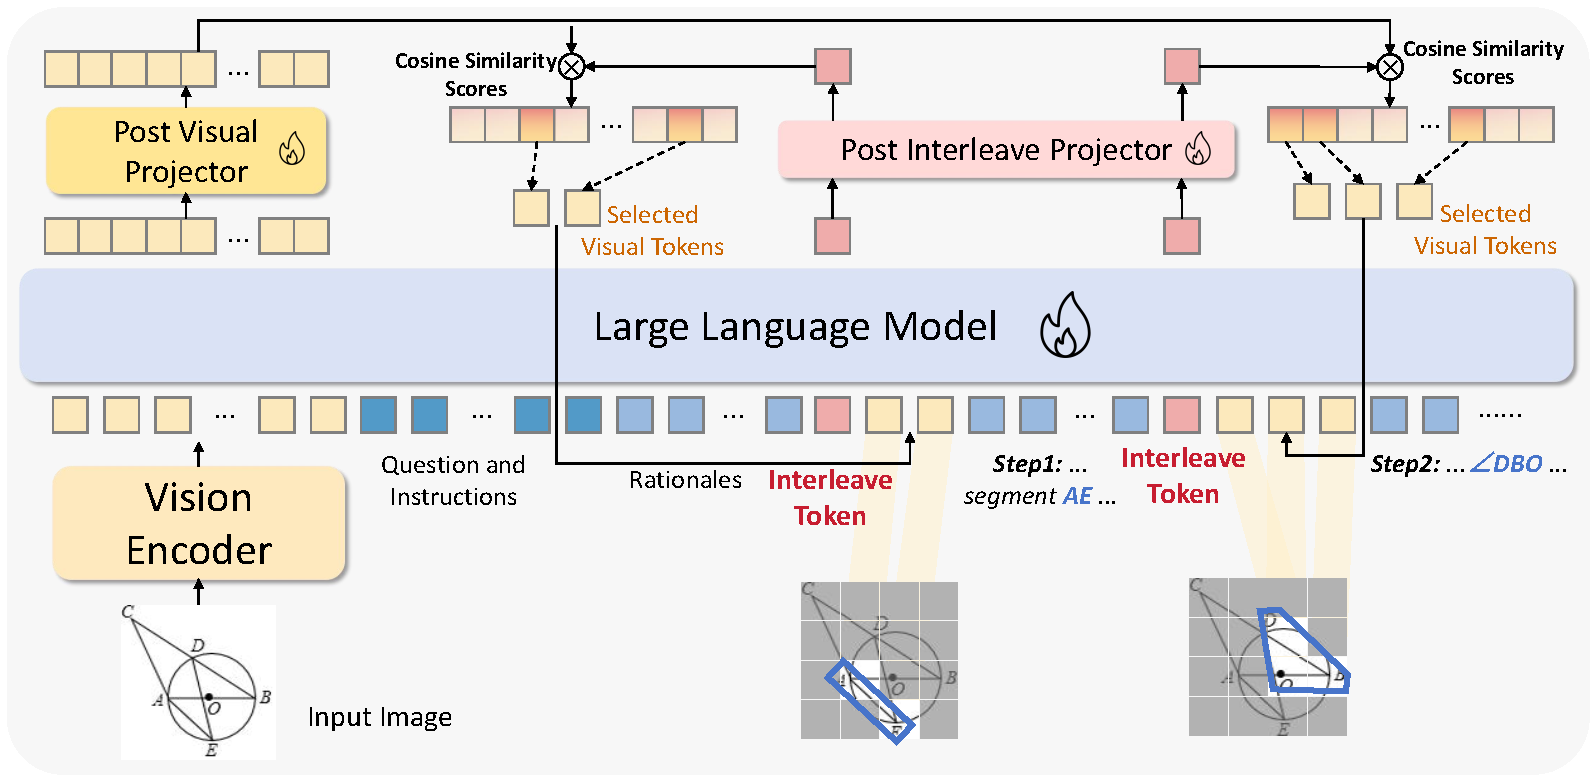
In this project, we propose MINT-CoT, introducing Mathematical INterleaved Tokens for Chain-of-Thought visual reasoning. MINT-CoT adaptively interleaves relevant visual tokens into textual reasoning steps via an Interleave Token, which dynamically selects visual regions of any shapes within math figures.
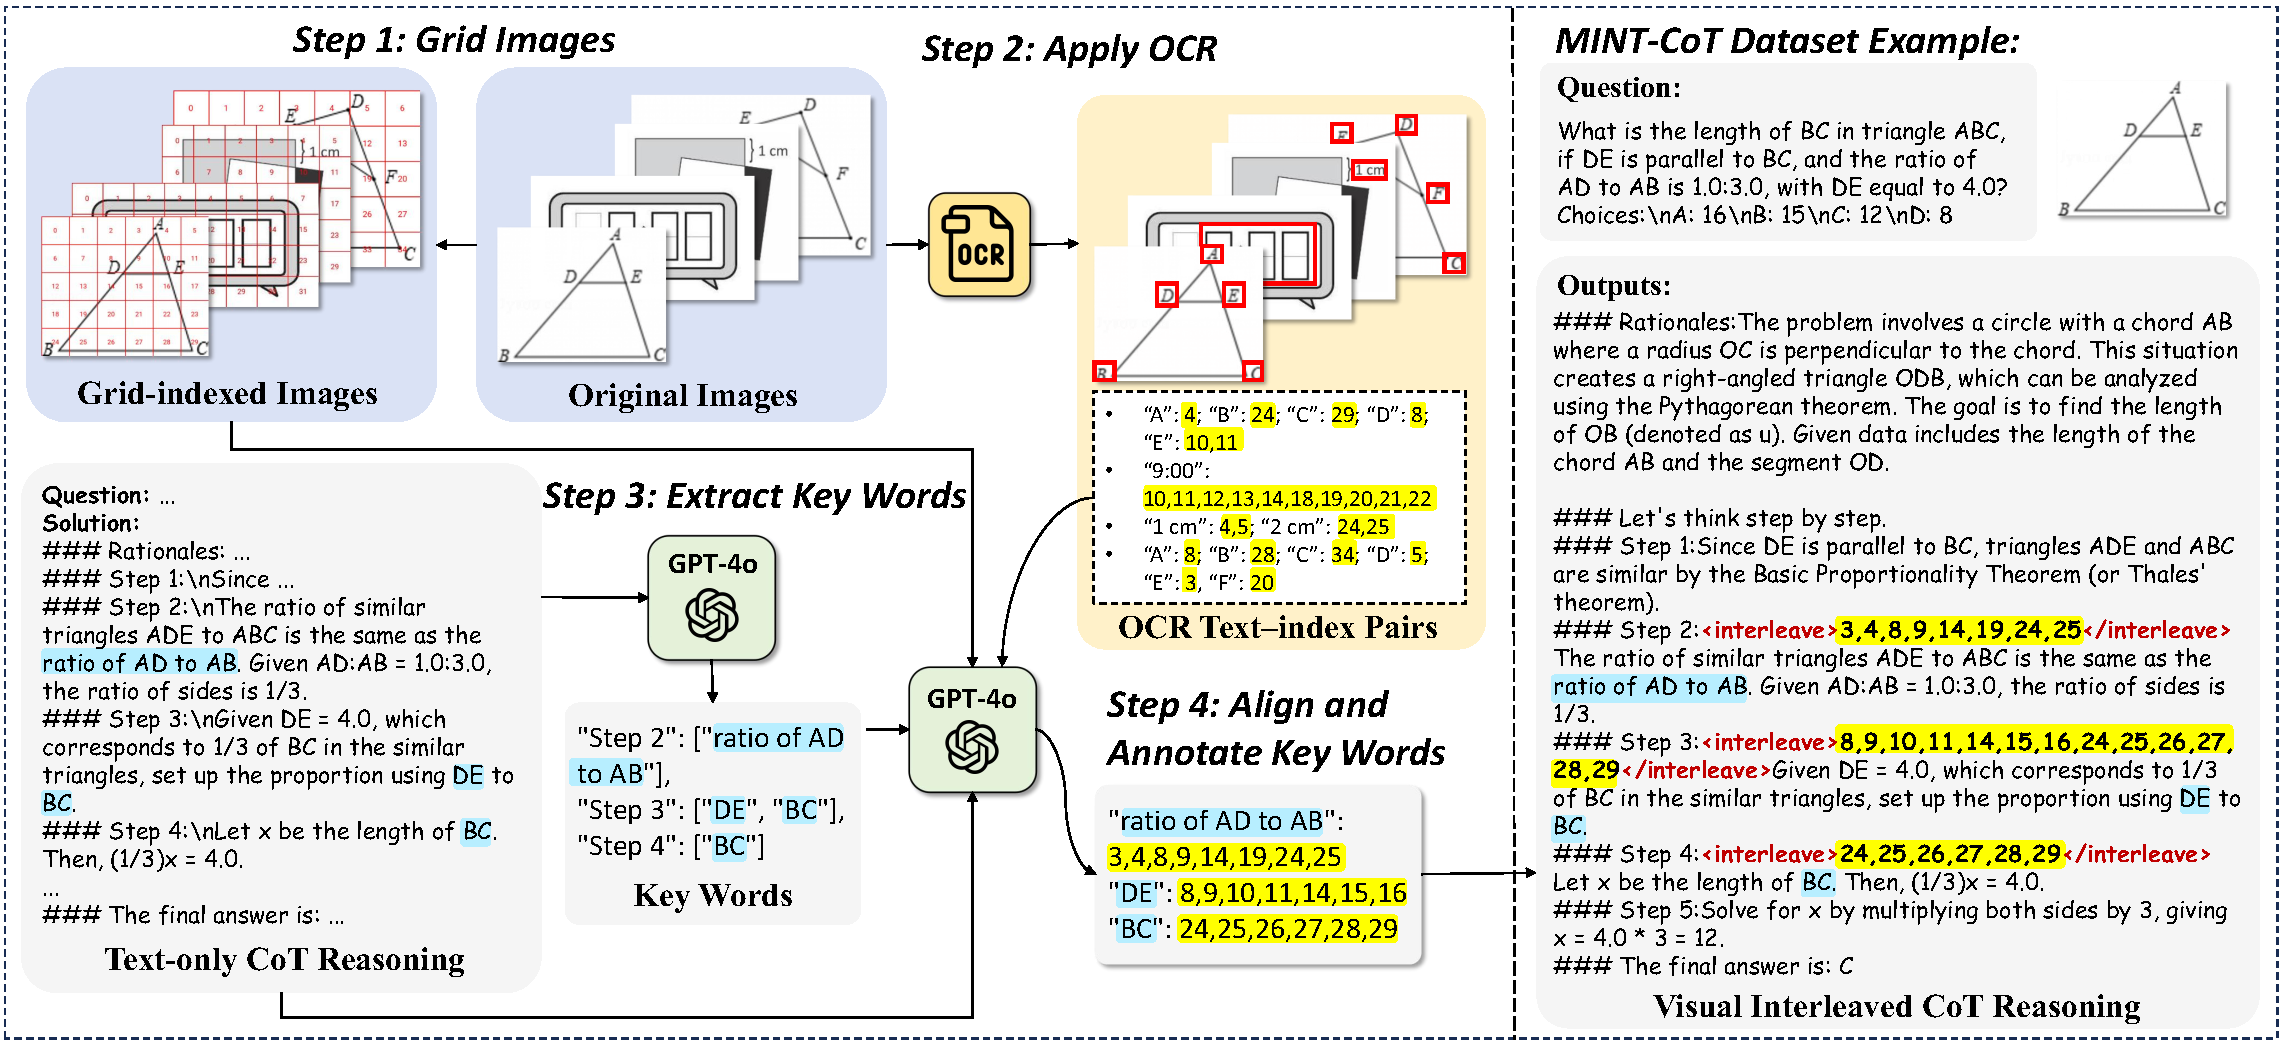
To empower this capability, we construct the MINT-CoT dataset, containing 54K mathematical problems aligning each reasoning step with visual regions at the token level, accompanied by a rigorous data generation pipeline.
We further present a three-stage MINT-CoT training strategy, progressively combining text-only CoT SFT, interleaved CoT SFT, and interleaved CoT RL, which derives our MINT-CoT-7B model.
💪 Get Started
Installation
Clone the repository:
git clone https://github.com/xinyan-cxy/MINT-CoT.git
cd MINT-CoT
Create a conda environment:
conda create -n mint python=3.11
conda activate mint
Please follow the official instructions here to install both PyTorch and TorchVision dependencies.
Install additional dependencies:
bash src/setup.sh
Dataset Preparation
Download our dataset, and unzip images.zip:
huggingface-cli repo download xy06/MINT-CoT-Dataset --local-dir ./data
mv ./data/MINT-CoT_interleave_sft_54k.json ./LLaMA-Factory/data
unzip ./data/images.zip -d ./LLaMA-Factory/data/
🚀 Training
Stage 1: Text-only CoT SFT.
cd LLaMA-Factory
DISABLE_VERSION_CHECK=1 llamafactory-cli train examples/mint-cot/qwen2vl_7b_full_sft_text_only.yaml
Stage 2: Interleaved CoT SFT.
DISABLE_VERSION_CHECK=1 llamafactory-cli train examples/mint-cot/qwen2vl_7b_full_sft_interleaved.yaml
Stage 3: Interleaved CoT RL.
cd ..
bash src/train/run_grpo_qwen2vl_interleaved.sh
💫 Evaluation
We use VLMEvalKit to evaluate the MINT-CoT models on different benchmarks. We provide the evaluation instructions and key code here.
First, you need to install VLMEvalKit according to the official instructions.
Next, replace the model.py and prompt.py files in VLMEvalKit-main/vlmeval/vlm/qwen2_vl/ with the files we provide here.
Then, add "MINT-CoT-7B": partial(Qwen2VLChat, model_path=<path_to_your_model>, min_pixels=1280 * 28 * 28, max_pixels=16384 * 28 * 28,) in the "qwen2vl_series" in config.py of VLMEvalKit
Finally, you can use the following command to perform the evaluation.
export LMUData="evaluation/LMUData" # Notice 2
CUDA_VISIBLE_DEVICES=0 python run.py --data MathVista_MINI --model MINT-CoT-7B --verbose
Notice:
- Please use v0.2 of VLMEvalKit.
- As our paper targets specifically mathematical problems, we extract the mathematical subsets (FunctionQA, Geometry3K, GeoQA+, GEOS, and UniGeo) from MathVista_MINI. You can also evaluate with the whole Mathvista_MINI and extract the mathematical subsets by yourself.
🥳 Acknowledgements
We would like to thank R1-V, LLaMA-Factory and Mulberry, upon which our repo is built.
✅ Citation
If you find MINT-CoT useful for your research and applications, please kindly cite using this BibTeX:
@article{chen2025mint,
  title={MINT-CoT: Enabling Interleaved Visual Tokens in Mathematical Chain-of-Thought Reasoning},
  author={Chen, Xinyan and Zhang, Renrui and Jiang, Dongzhi and Zhou, Aojun and Yan, Shilin and Lin, Weifeng and Li, Hongsheng},
  journal={arXiv preprint arXiv:2506.05331},
  year={2025}
}
Contributors

9 commits
Similar repos



Languages
Python
96.9%
Jupyter Notebook
1.6%
[NeurIPS 2025] MINT-CoT: Enabling Interleaved Visual Tokens in Mathematical Chain-of-Thought Reasoning
Python
108
9 commits
updated Sep 19, 2025
README
🌟🔥 [NeurIPS 2025] MINT-CoT: Enabling Interleaved Visual Tokens in Mathematical Chain-of-Thought Reasoning
Official repository for the paper "MINT-CoT: Enabling Interleaved Visual Tokens in Mathematical Chain-of-Thought Reasoning".
[📖 Paper] [🤗 Dataset] [🤗 Model]
💥 News
- [2025.09.19] MINT-CoT has been accepted by NeurIPS 2025! 🎉🎉
- [2025.06.06] We release the arxiv paper and the code. 🔥
👀 About MINT-CoT
Chain-of-Thought (CoT) has widely enhanced mathematical reasoning in Large Language Models (LLMs), but it still remains challenging for extending it to multi modal domains. Existing works either adopt a similar textual reasoning for image input, or seek to interleave visual signals into mathematical CoT. However, they face three key limitations for math problem-solving: reliance on coarse-grained box-shaped image regions, limited perception of vision encoders on math content, and dependence on external capabilities for visual modification.
In this project, we propose MINT-CoT, introducing Mathematical INterleaved Tokens for Chain-of-Thought visual reasoning. MINT-CoT adaptively interleaves relevant visual tokens into textual reasoning steps via an Interleave Token, which dynamically selects visual regions of any shapes within math figures.
To empower this capability, we construct the MINT-CoT dataset, containing 54K mathematical problems aligning each reasoning step with visual regions at the token level, accompanied by a rigorous data generation pipeline.
We further present a three-stage MINT-CoT training strategy, progressively combining text-only CoT SFT, interleaved CoT SFT, and interleaved CoT RL, which derives our MINT-CoT-7B model.
💪 Get Started
Installation
Clone the repository:
git clone https://github.com/xinyan-cxy/MINT-CoT.git
cd MINT-CoT
Create a conda environment:
conda create -n mint python=3.11
conda activate mint
Please follow the official instructions here to install both PyTorch and TorchVision dependencies.
Install additional dependencies:
bash src/setup.sh
Dataset Preparation
Download our dataset, and unzip images.zip:
huggingface-cli repo download xy06/MINT-CoT-Dataset --local-dir ./data
mv ./data/MINT-CoT_interleave_sft_54k.json ./LLaMA-Factory/data
unzip ./data/images.zip -d ./LLaMA-Factory/data/
🚀 Training
Stage 1: Text-only CoT SFT.
cd LLaMA-Factory
DISABLE_VERSION_CHECK=1 llamafactory-cli train examples/mint-cot/qwen2vl_7b_full_sft_text_only.yaml
Stage 2: Interleaved CoT SFT.
DISABLE_VERSION_CHECK=1 llamafactory-cli train examples/mint-cot/qwen2vl_7b_full_sft_interleaved.yaml
Stage 3: Interleaved CoT RL.
cd ..
bash src/train/run_grpo_qwen2vl_interleaved.sh
💫 Evaluation
We use VLMEvalKit to evaluate the MINT-CoT models on different benchmarks. We provide the evaluation instructions and key code here.
First, you need to install VLMEvalKit according to the official instructions.
Next, replace the model.py and prompt.py files in VLMEvalKit-main/vlmeval/vlm/qwen2_vl/ with the files we provide here.
Then, add "MINT-CoT-7B": partial(Qwen2VLChat, model_path=<path_to_your_model>, min_pixels=1280 * 28 * 28, max_pixels=16384 * 28 * 28,) in the "qwen2vl_series" in config.py of VLMEvalKit
Finally, you can use the following command to perform the evaluation.
export LMUData="evaluation/LMUData" # Notice 2
CUDA_VISIBLE_DEVICES=0 python run.py --data MathVista_MINI --model MINT-CoT-7B --verbose
Notice:
- Please use v0.2 of VLMEvalKit.
- As our paper targets specifically mathematical problems, we extract the mathematical subsets (FunctionQA, Geometry3K, GeoQA+, GEOS, and UniGeo) from MathVista_MINI. You can also evaluate with the whole Mathvista_MINI and extract the mathematical subsets by yourself.
🥳 Acknowledgements
We would like to thank R1-V, LLaMA-Factory and Mulberry, upon which our repo is built.
✅ Citation
If you find MINT-CoT useful for your research and applications, please kindly cite using this BibTeX:
@article{chen2025mint,
  title={MINT-CoT: Enabling Interleaved Visual Tokens in Mathematical Chain-of-Thought Reasoning},
  author={Chen, Xinyan and Zhang, Renrui and Jiang, Dongzhi and Zhou, Aojun and Yan, Shilin and Lin, Weifeng and Li, Hongsheng},
  journal={arXiv preprint arXiv:2506.05331},
  year={2025}
}
Similar repos
Contributors
9 commits
Languages
Python
96.9%
Jupyter Notebook
1.6%