R1-AQA is a audio question answering (AQA) model based on Qwen2-Audio-7B-Instruct, optimized through reinforcement learning (RL) using the group relative policy optimization (GRPO) algorithm.
This implementation has achieved state-of-the-art performance on the MMAU benchmark with only 38k post-training samples.
Our main findings are as follows:
Qwen2-Audio-7B-Instruct with only 8.2B parameters.Additional Notes:
| Model | Method | Test-mini | Test | Test-mini | Test | Test-mini | Test | Test-mini | Test |
|---|---|---|---|---|---|---|---|---|---|
| - | Human* | 86.31 | - | 78.22 | - | 82.17 | - | 82.23 | - |
| Gemini Pro 2.0 Flash | Direct Inference* | 56.46 | 61.73 | 58.68 | 56.53 | 51.65 | 61.53 | 55.60 | 59.93 |
| Audio Flamingo 2 | Direct Inference* | 61.56 | 65.10 | 73.95 | 72.90 | 30.93 | 40.26 | 55.48 | 59.42 |
| GPT4o + Strong Cap. | Direct Inference* | 57.35 | 55.83 | 49.70 | 51.73 | 64.86 | 68.66 | 57.30 | 58.74 |
| Llama-3-8B-Instruct + Strong Cap. | Direct Inference* | 50.75 | 49.10 | 48.93 | 48.93 | 55.25 | 62.70 | 52.10 | 53.57 |
| Qwen2-Audio-7B-Instruct | Direct Inference* | 54.95 | 45.90 | 50.98 | 53.26 | 42.04 | 45.90 | 49.20 | 52.50 |
| SALAMONN | Direct Inference* | 41.00 | 40.30 | 34.80 | 33.76 | 25.50 | 24.24 | 33.70 | 32.77 |
| Qwen2-Audio-7B-Instruct | CoTA [1] | 60.06 | - | 64.30 | - | 60.70 | - | 61.71 | - |
| Qwen2-Audio-7B-Instruct | Zero-Shot-CoT [2] | 61.86 | - | 56.29 | - | 55.26 | - | 57.80 | - |
| Qwen2-Audio-7B-Instruct | GRPO (Ours) 1️⃣ | 69.37 | - | 66.77 | - | 57.36 | - | 64.50 | - |
| Qwen2-Audio-7B-Instruct | GRPO (Ours) 2️⃣ | 68.77 | 69.76 | 64.37 | 61.40 | 63.66 | 62.70 | 65.60 | 64.36 |
* The data are sourced from the MMAU leaderboard.
[1] Xie, Zhifei, et al. "Audio-Reasoner: Improving Reasoning Capability in Large Audio Language Models." arXiv preprint arXiv:2503.02318 (2025).
[2] Ma, Ziyang, et al. "Audio-CoT: Exploring Chain-of-Thought Reasoning in Large Audio Language Model." arXiv preprint arXiv:2501.07246 (2025).
1️⃣ It is the original model, identical to the one on Hugging Face and described in our technical report.
2️⃣ It is the model submitted to the MMAU leaderboard, trained multiple times to achieve balanced results.
Hugging Face:
🤗 R1-AQA Model: mispeech/r1-aqa
R1-AQA Team:
Gang Li* · Jizhong Liu* · Heinrich Dinkel · Yadong Niu · Junbo Zhang · Jian Luan
* Equal contribution.
<think> </think> (GRPO + Prompt <3> in our technical report).We use the AVQA training subset (train_qa.json), and convert the data to the R1-AQA format, where each line in the text file represents a JSON object with specific keys
{
    # The data presented below originate from the original AVQA dataset.
    "id": 183,
    "video_name": "-HG3Omg_89c_000030",
    "video_id": 341,
    "question_text": "What happened in the video?",
    "multi_choice": [
        "motorboat",
        "Yacht consignment",
        "Sailboat set sail",
        "Consignment car"
    ],
    "answer": 1,
    "question_relation": "View",
    "question_type": "Happening",
    # We add the following data.
    "dataset_name": "AVQA",
    "audio_path": "Path to wav dir/-HG3Omg_89c_30.wav"
}
sh run_grpo.sh
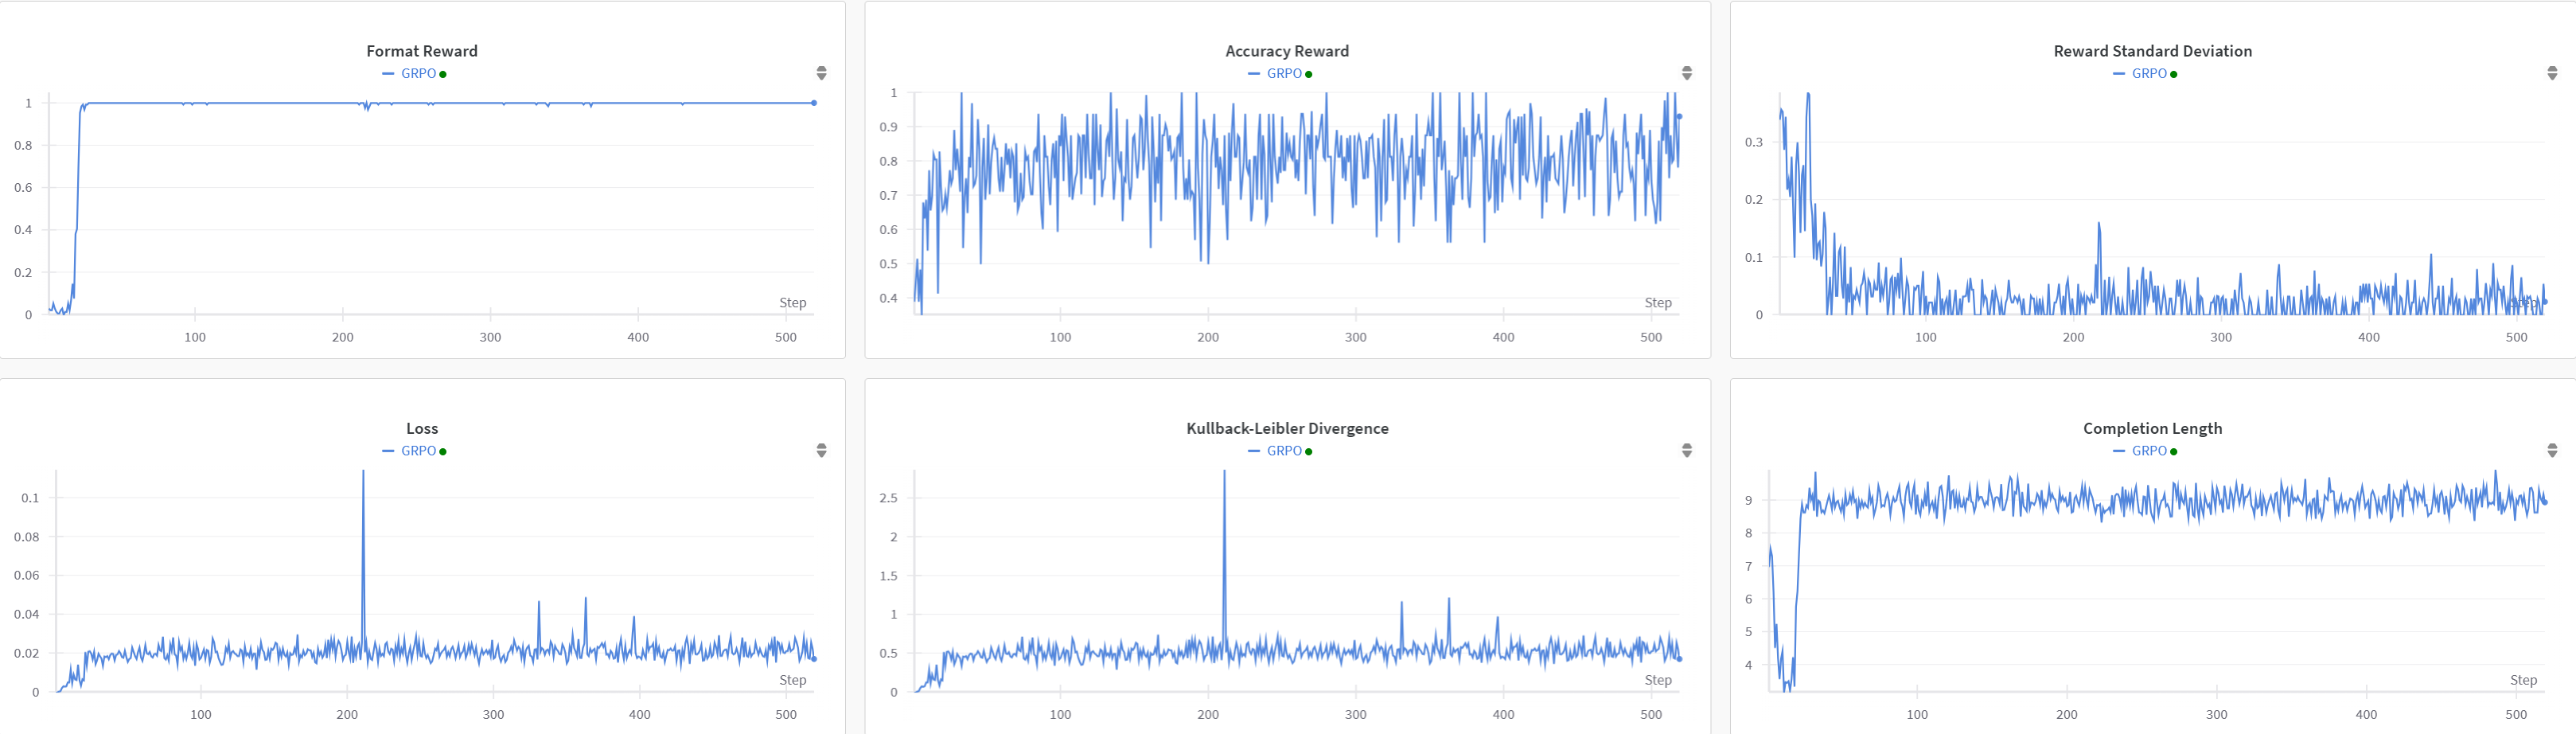
DATA_FILE variable in the run_grpo.sh with your dataset path.Qwen2-Audio-7B-Instruct model, please modify the MODEL_NP variable in run_grpo.sh to your local model path.Evaluate the MMAU Test-mini dataset, please follow these steps:
mkdir -p data && cd data

git clone https://github.com/Sakshi113/MMAU.git

cd data/MMAU

# ***Check if output_key = 'model_output' in evaluation.py, change it to output_key = 'model_prediction'.***

#TODO you should download test-mini-audios.tar.gz to here
***download test-mini-audios.tar.gz to here***

# Uncompress wav files
tar -xzvf test-mini-audios.tar.gz

cd ../../
# Testing MMAU test-mini with in every 100 steps.
# You can uncomment the line 12 of test_mmau.sh to eval the entire MMAU, if you have downloaded test-audios.tar.gz.
# You can modify the script to test other steps or change other parameters.
sh test_mmau.sh
We encourage hacking it on your own. If you want to see the "thinking" or improve our work, here are some hints:
- Uncomment the line 25 of
src\dataset\dataset.py;- Uncomment the line 55 of
src\utils\rewards.py;- Uncomment the line 46 of
src\test.py;- Train and test your model;
- Design your CoT strategy based on
<think> </think>. Let's explore effective ways to combine RL and CoT!
@article{li2025reinforcement,
  title={Reinforcement Learning Outperforms Supervised Fine-Tuning: A Case Study on Audio Question Answering},
  author={Li, Gang and Liu, Jizhong and Dinkel, Heinrich and Niu, Yadong and Zhang, Junbo and Luan, Jian},
  journal={arXiv preprint arXiv:2503.11197},
  year={2025},
  url={https://github.com/xiaomi-research/r1-aqa; https://huggingface.co/mispeech/r1-aqa}
}
219 followers · starred Mar 2025
763 followers · starred Mar 2025
364 followers · starred Mar 2025
98 followers · starred May 2025
R1-AQA is a audio question answering (AQA) model based on Qwen2-Audio-7B-Instruct, optimized through reinforcement learning (RL) using the group relative policy optimization (GRPO) algorithm.
This implementation has achieved state-of-the-art performance on the MMAU benchmark with only 38k post-training samples.
Our main findings are as follows:
Qwen2-Audio-7B-Instruct with only 8.2B parameters.Additional Notes:
| Model | Method | Test-mini | Test | Test-mini | Test | Test-mini | Test | Test-mini | Test |
|---|---|---|---|---|---|---|---|---|---|
| - | Human* | 86.31 | - | 78.22 | - | 82.17 | - | 82.23 | - |
| Gemini Pro 2.0 Flash | Direct Inference* | 56.46 | 61.73 | 58.68 | 56.53 | 51.65 | 61.53 | 55.60 | 59.93 |
| Audio Flamingo 2 | Direct Inference* | 61.56 | 65.10 | 73.95 | 72.90 | 30.93 | 40.26 | 55.48 | 59.42 |
| GPT4o + Strong Cap. | Direct Inference* | 57.35 | 55.83 | 49.70 | 51.73 | 64.86 | 68.66 | 57.30 | 58.74 |
| Llama-3-8B-Instruct + Strong Cap. | Direct Inference* | 50.75 | 49.10 | 48.93 | 48.93 | 55.25 | 62.70 | 52.10 | 53.57 |
| Qwen2-Audio-7B-Instruct | Direct Inference* | 54.95 | 45.90 | 50.98 | 53.26 | 42.04 | 45.90 | 49.20 | 52.50 |
| SALAMONN | Direct Inference* | 41.00 | 40.30 | 34.80 | 33.76 | 25.50 | 24.24 | 33.70 | 32.77 |
| Qwen2-Audio-7B-Instruct | CoTA [1] | 60.06 | - | 64.30 | - | 60.70 | - | 61.71 | - |
| Qwen2-Audio-7B-Instruct | Zero-Shot-CoT [2] | 61.86 | - | 56.29 | - | 55.26 | - | 57.80 | - |
| Qwen2-Audio-7B-Instruct | GRPO (Ours) 1️⃣ | 69.37 | - | 66.77 | - | 57.36 | - | 64.50 | - |
| Qwen2-Audio-7B-Instruct | GRPO (Ours) 2️⃣ | 68.77 | 69.76 | 64.37 | 61.40 | 63.66 | 62.70 | 65.60 | 64.36 |
* The data are sourced from the MMAU leaderboard.
[1] Xie, Zhifei, et al. "Audio-Reasoner: Improving Reasoning Capability in Large Audio Language Models." arXiv preprint arXiv:2503.02318 (2025).
[2] Ma, Ziyang, et al. "Audio-CoT: Exploring Chain-of-Thought Reasoning in Large Audio Language Model." arXiv preprint arXiv:2501.07246 (2025).
1️⃣ It is the original model, identical to the one on Hugging Face and described in our technical report.
2️⃣ It is the model submitted to the MMAU leaderboard, trained multiple times to achieve balanced results.
Hugging Face:
🤗 R1-AQA Model: mispeech/r1-aqa
R1-AQA Team:
Gang Li* · Jizhong Liu* · Heinrich Dinkel · Yadong Niu · Junbo Zhang · Jian Luan
* Equal contribution.
<think> </think> (GRPO + Prompt <3> in our technical report).We use the AVQA training subset (train_qa.json), and convert the data to the R1-AQA format, where each line in the text file represents a JSON object with specific keys
{
    # The data presented below originate from the original AVQA dataset.
    "id": 183,
    "video_name": "-HG3Omg_89c_000030",
    "video_id": 341,
    "question_text": "What happened in the video?",
    "multi_choice": [
        "motorboat",
        "Yacht consignment",
        "Sailboat set sail",
        "Consignment car"
    ],
    "answer": 1,
    "question_relation": "View",
    "question_type": "Happening",
    # We add the following data.
    "dataset_name": "AVQA",
    "audio_path": "Path to wav dir/-HG3Omg_89c_30.wav"
}
sh run_grpo.sh
DATA_FILE variable in the run_grpo.sh with your dataset path.Qwen2-Audio-7B-Instruct model, please modify the MODEL_NP variable in run_grpo.sh to your local model path.Evaluate the MMAU Test-mini dataset, please follow these steps:
mkdir -p data && cd data

git clone https://github.com/Sakshi113/MMAU.git

cd data/MMAU

# ***Check if output_key = 'model_output' in evaluation.py, change it to output_key = 'model_prediction'.***

#TODO you should download test-mini-audios.tar.gz to here
***download test-mini-audios.tar.gz to here***

# Uncompress wav files
tar -xzvf test-mini-audios.tar.gz

cd ../../
# Testing MMAU test-mini with in every 100 steps.
# You can uncomment the line 12 of test_mmau.sh to eval the entire MMAU, if you have downloaded test-audios.tar.gz.
# You can modify the script to test other steps or change other parameters.
sh test_mmau.sh
We encourage hacking it on your own. If you want to see the "thinking" or improve our work, here are some hints:
- Uncomment the line 25 of
src\dataset\dataset.py;- Uncomment the line 55 of
src\utils\rewards.py;- Uncomment the line 46 of
src\test.py;- Train and test your model;
- Design your CoT strategy based on
<think> </think>. Let's explore effective ways to combine RL and CoT!
@article{li2025reinforcement,
  title={Reinforcement Learning Outperforms Supervised Fine-Tuning: A Case Study on Audio Question Answering},
  author={Li, Gang and Liu, Jizhong and Dinkel, Heinrich and Niu, Yadong and Zhang, Junbo and Luan, Jian},
  journal={arXiv preprint arXiv:2503.11197},
  year={2025},
  url={https://github.com/xiaomi-research/r1-aqa; https://huggingface.co/mispeech/r1-aqa}
}
219 followers · starred Mar 2025
763 followers · starred Mar 2025
364 followers · starred Mar 2025
98 followers · starred May 2025