
[CVPR 2026 Highlight] WorldMM: Dynamic Multimodal Memory Agent for Long Video Reasoning
See the codeREADME
🌏 WorldMM: Dynamic Multimodal Memory Agent for Long Video Reasoning


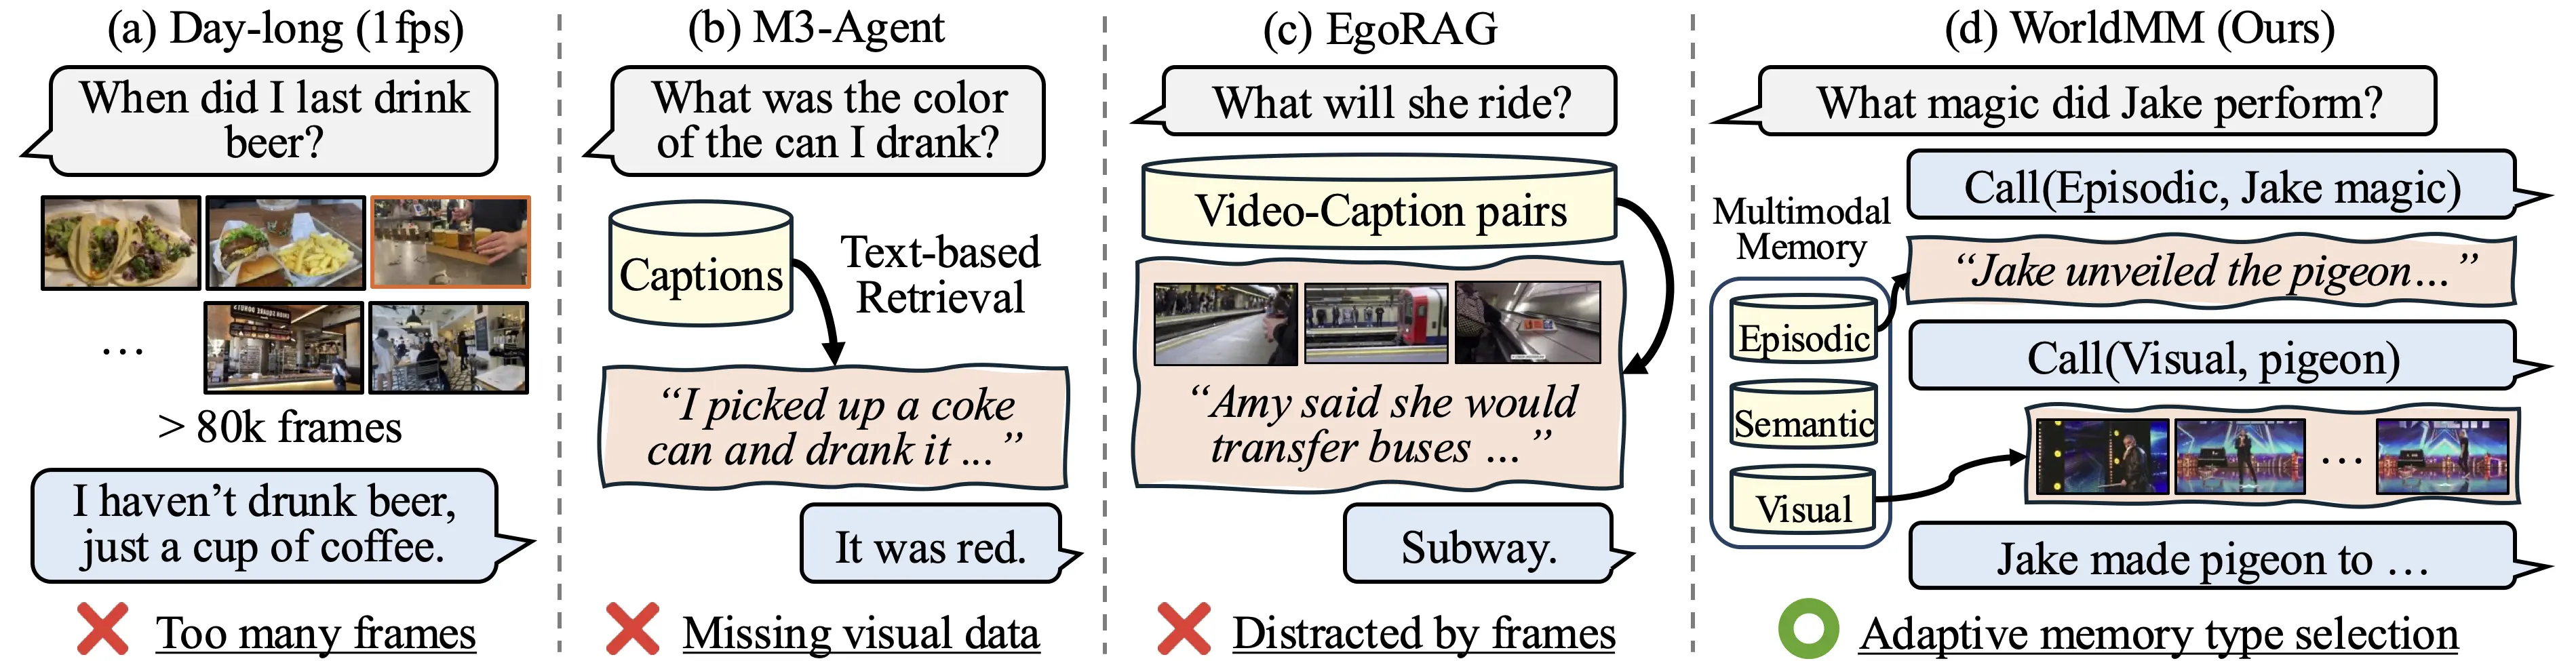
WorldMM is a novel dynamic multimodal memory agent designed for long video reasoning. It constructs multimodal, multi-scale memories that capture both textual and visual information, and employs adaptive retrieval across multiple memories with reasoning.
Get Started
To set up the environment, we recommend using uv for fast and deterministic setup. All dependencies are specified in pyproject.toml and pinned in uv.lock.
1. Clone the Repository
git clone https://github.com/wgcyeo/WorldMM.git
cd WorldMM
2. Run the Setup Script
The setup script will:
- Install uv (if not already installed)
- Install all project dependencies
- Download required datasets
bash script/1_setup.sh
3. Set Environment Variables (Optional)
To use GPT-family models for preprocessing or evaluation, set your OpenAI API key:
export OPENAI_API_KEY="your_openai_api_key"
Preprocessing
Before memory construction and evaluation, preprocess the EgoLife dataset:
bash script/2_preprocess.sh
After preprocessing, the dataset directory is organized as follows:
data/EgoLife/
├── A1_JAKE/
│   ├── DAY1/                    # Video files
│   ├── DAY2/
│   └── ...
├── EgoLifeCap/
│   ├── DenseCaption/            # Fine-grained video captions (in Chinese)
│   │   └── translated/          # Machine-translated English captions
│   ├── Sync/                    # Synchronized transcripts + captions
│   └── Transcript/              # Audio transcripts
└── EgoLifeQA/
    └── EgoLifeQA_A1_JAKE.json   # QA annotations
Memory Construction
WorldMM builds three memory modules—episodic, semantic, and visual—to support long-term reasoning, which can be constructed with:
bash script/3_build_memory.sh
To run a specific module only:
bash script/3_build_memory.sh --step [episodic|semantic|visual]
Options
--step <type>       # Memory type: episodic, semantic, visual, all
--gpu <ids>         # GPU IDs to use (default: 0,1,2,3)
--model <name>      # LLM model for memory construction (default: gpt-5-mini)
[!TIP] To skip memory construction and use the prebuilt WorldMM EgoLife memory metadata, download it from wgcyeo/WorldMM-EgoLife into
output/metadata.
Evaluation
Run evaluation on EgoLifeQA with:
bash script/4_eval.sh --retriever-model gpt-5-mini --respond-model gpt-5
Options
--retriever-model <m>   # Model for retrieval process (default: gpt-5-mini)
--respond-model <m>     # Model for iterative reasoning and generating answers (default: gpt-5)
--max-rounds <n>        # Max retrieval rounds (default: 5)
WorldMM supports a variety of backbone models for retrieval and reasoning, including gpt-5 and qwen3vl-8b.
Using WorldMM on Other Video Benchmarks
Beyond evaluation on week-long videos, WorldMM also supports evaluation on general video benchmarks. We provide an example pipeline for Video-MME:
bash script/videomme/1_setup.sh
bash script/videomme/2_preprocess.sh
bash script/videomme/3_build_memory.sh --model gpt-5-mini
bash script/videomme/4_eval.sh --retriever-model gpt-5-mini --respond-model gpt-5
For detailed information about each step, please refer to the scripts located in script/videomme.
Citation
If you find WorldMM helpful, please consider citing our paper:
@inproceedings{yeo2026worldmm,
  title     = {WorldMM: Dynamic Multimodal Memory Agent for Long Video Reasoning},
  author    = {Yeo, Woongyeong and Kim, Kangsan and Yoon, Jaehong and Hwang, Sung Ju},
  booktitle = {Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR)},
  month     = {June},
  year      = {2026},
  pages     = {25599-25609}
}
Acknowledgments
Our implementation is built upon EgoLife, HippoRAG, and VLM2Vec. We thank the authors for open-sourcing their code and dataset.
Similar repos


Languages
Python
98.8%
Shell
1.2%
[CVPR 2026 Highlight] WorldMM: Dynamic Multimodal Memory Agent for Long Video Reasoning
See the codeREADME
🌏 WorldMM: Dynamic Multimodal Memory Agent for Long Video Reasoning
WorldMM is a novel dynamic multimodal memory agent designed for long video reasoning. It constructs multimodal, multi-scale memories that capture both textual and visual information, and employs adaptive retrieval across multiple memories with reasoning.
Get Started
To set up the environment, we recommend using uv for fast and deterministic setup. All dependencies are specified in pyproject.toml and pinned in uv.lock.
1. Clone the Repository
git clone https://github.com/wgcyeo/WorldMM.git
cd WorldMM
2. Run the Setup Script
The setup script will:
- Install uv (if not already installed)
- Install all project dependencies
- Download required datasets
bash script/1_setup.sh
3. Set Environment Variables (Optional)
To use GPT-family models for preprocessing or evaluation, set your OpenAI API key:
export OPENAI_API_KEY="your_openai_api_key"
Preprocessing
Before memory construction and evaluation, preprocess the EgoLife dataset:
bash script/2_preprocess.sh
After preprocessing, the dataset directory is organized as follows:
data/EgoLife/
├── A1_JAKE/
│   ├── DAY1/                    # Video files
│   ├── DAY2/
│   └── ...
├── EgoLifeCap/
│   ├── DenseCaption/            # Fine-grained video captions (in Chinese)
│   │   └── translated/          # Machine-translated English captions
│   ├── Sync/                    # Synchronized transcripts + captions
│   └── Transcript/              # Audio transcripts
└── EgoLifeQA/
    └── EgoLifeQA_A1_JAKE.json   # QA annotations
Memory Construction
WorldMM builds three memory modules—episodic, semantic, and visual—to support long-term reasoning, which can be constructed with:
bash script/3_build_memory.sh
To run a specific module only:
bash script/3_build_memory.sh --step [episodic|semantic|visual]
Options
--step <type>       # Memory type: episodic, semantic, visual, all
--gpu <ids>         # GPU IDs to use (default: 0,1,2,3)
--model <name>      # LLM model for memory construction (default: gpt-5-mini)
[!TIP] To skip memory construction and use the prebuilt WorldMM EgoLife memory metadata, download it from wgcyeo/WorldMM-EgoLife into
output/metadata.
Evaluation
Run evaluation on EgoLifeQA with:
bash script/4_eval.sh --retriever-model gpt-5-mini --respond-model gpt-5
Options
--retriever-model <m>   # Model for retrieval process (default: gpt-5-mini)
--respond-model <m>     # Model for iterative reasoning and generating answers (default: gpt-5)
--max-rounds <n>        # Max retrieval rounds (default: 5)
WorldMM supports a variety of backbone models for retrieval and reasoning, including gpt-5 and qwen3vl-8b.
Using WorldMM on Other Video Benchmarks
Beyond evaluation on week-long videos, WorldMM also supports evaluation on general video benchmarks. We provide an example pipeline for Video-MME:
bash script/videomme/1_setup.sh
bash script/videomme/2_preprocess.sh
bash script/videomme/3_build_memory.sh --model gpt-5-mini
bash script/videomme/4_eval.sh --retriever-model gpt-5-mini --respond-model gpt-5
For detailed information about each step, please refer to the scripts located in script/videomme.
Citation
If you find WorldMM helpful, please consider citing our paper:
@inproceedings{yeo2026worldmm,
  title     = {WorldMM: Dynamic Multimodal Memory Agent for Long Video Reasoning},
  author    = {Yeo, Woongyeong and Kim, Kangsan and Yoon, Jaehong and Hwang, Sung Ju},
  booktitle = {Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR)},
  month     = {June},
  year      = {2026},
  pages     = {25599-25609}
}
Acknowledgments
Our implementation is built upon EgoLife, HippoRAG, and VLM2Vec. We thank the authors for open-sourcing their code and dataset.
Similar repos
Languages
Python
98.8%
Shell
1.2%