
We Speech Transcript based on LLM, in 300 lines of code.
Python
182
15 commits
updated Jun 20, 2025
README
WeSR
We Speech Recognition, LLM based Speech Recognition/Transcript in 300 lines of code.
Details
Motivated by SLAM-ASR and LLaMA 3.1, Our model consists of a LLM, a Speech Encoder, and a Projector(speech adapter in LLaMA). Only the projector is trainable.
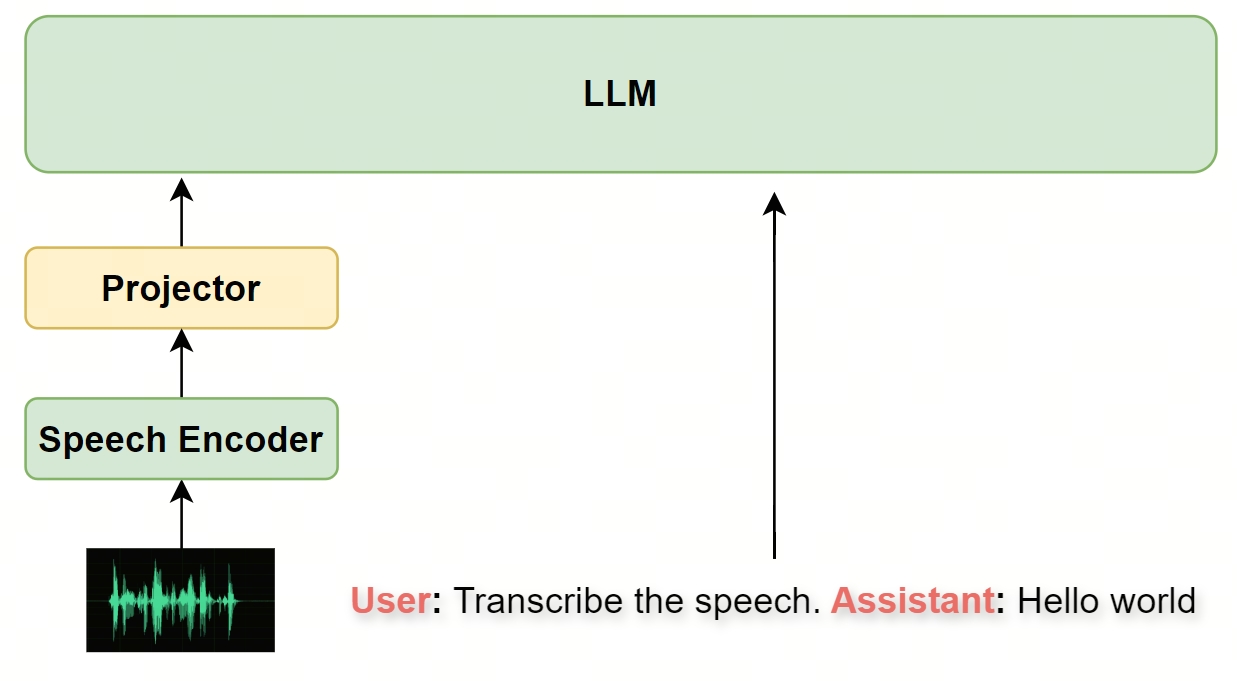
- LLM, could be LLaMA, QWen, etc.
- Speech Encoder, like whisper.
Install
pip install -r requirements.txt
Data Prepare
The training data(train.json) and test data(test.jsonl) should be prepared as jsonl format, which contains wav and txt in each line. Here is an example:
{"wav": "/data/BAC009S0764W0121.wav", "txt": "甚至出现交易几乎停滞的情况"}
{"wav": "/data/BAC009S0764W0122.wav", "txt": "一二线城市虽然也处于调整中"}
Training
torchrun --standalone --nnodes=1 --nproc_per_node=8 train.py \
    --llm_model_name_or_path Qwen/Qwen2-1.5B-Instruct \
    --whisper_model_name_or_path tiny \
    --data_path train.jsonl \
    --bf16 True \
    --output_dir Qwen-1.5B-Instruct-whisper-tiny \
    --num_train_epochs 5 \
    --per_device_train_batch_size 8 \
    --per_device_eval_batch_size 1 \
    --gradient_accumulation_steps 8 \
    --evaluation_strategy "no" \
    --save_strategy "steps" \
    --save_steps 100 \
    --save_total_limit 10 \
    --learning_rate 3e-4 \
    --weight_decay 0.01 \
    --adam_beta2 0.95 \
    --warmup_ratio 0.01 \
    --lr_scheduler_type "cosine" \
    --logging_steps 1 \
    --report_to "none" \
    --model_max_length 512 \
    --gradient_checkpointing \
    --dataloader_num_workers 4 \
    --dataloader_prefetch_factor 10 \
    --deepspeed ds_config_zero3.json
Decoding
python recognize.py \
    --llm_model_name_or_path Qwen/Qwen2-1.5B-Instruct \
    --whisper_model_name_or_path tiny \
    --projector_model_path Qwen-1.5B-Instruct-whisper-tiny/checkpoint-600/model.safetensors \
    --data_path test.jsonl \
    --result_path result.txt
Results
LibriSpeech
| Exp | LLM | Speech Encoder | Projector | test_clean | test_other |
|---|---|---|---|---|---|
| 1 | LLaMA 3 8B | Whisper tiny 39M | Conv1d 9.46M | 7.62/6.29 | 18.50/17.59 |
| 2 | LLaMA 3 8B | Whisper small 244M | Conv1d 12.32M | 6.09/3.90 | 11.65/10.00 |
| 3 | LLaMA 3 8B | Whisper Large 1.5G | Conv1d 18.32M | 3.63/2.83 | 8.18/7.43 |
The number before and after '/' represents the overall WER and the WER after filtering out hallucinations, respectively. We have observed that certain recognition results may exhibit the hallucination like "I apologize, but it appears that there is no speech to transcribe."
AIShell
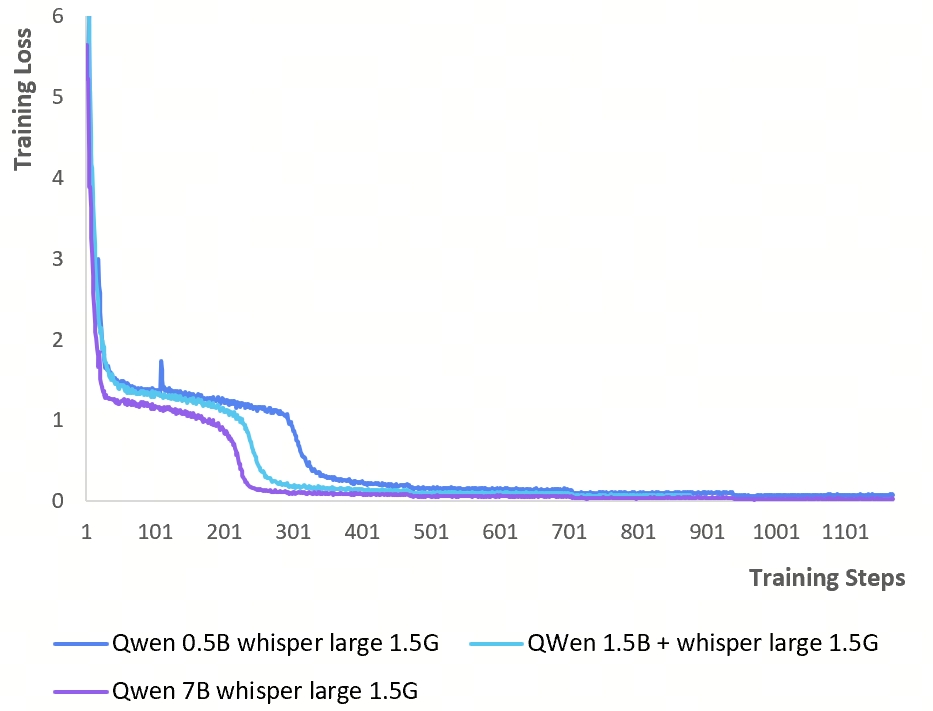
Different LLM
| Exp | LLM | Speech Encoder | Projector | CER |
|---|---|---|---|---|
| 1 | QWen2 0.5B | Whisper Large 1.5G | Conv1d 12.07M | 9.77 |
| 2 | QWen2 1.5B | Whisper Large 1.5G | Conv1d 13.32M | 7.45 |
| 3 | QWen2 7B | Whisper Large 1.5G | Conv1d 17.32M | 5.55 |
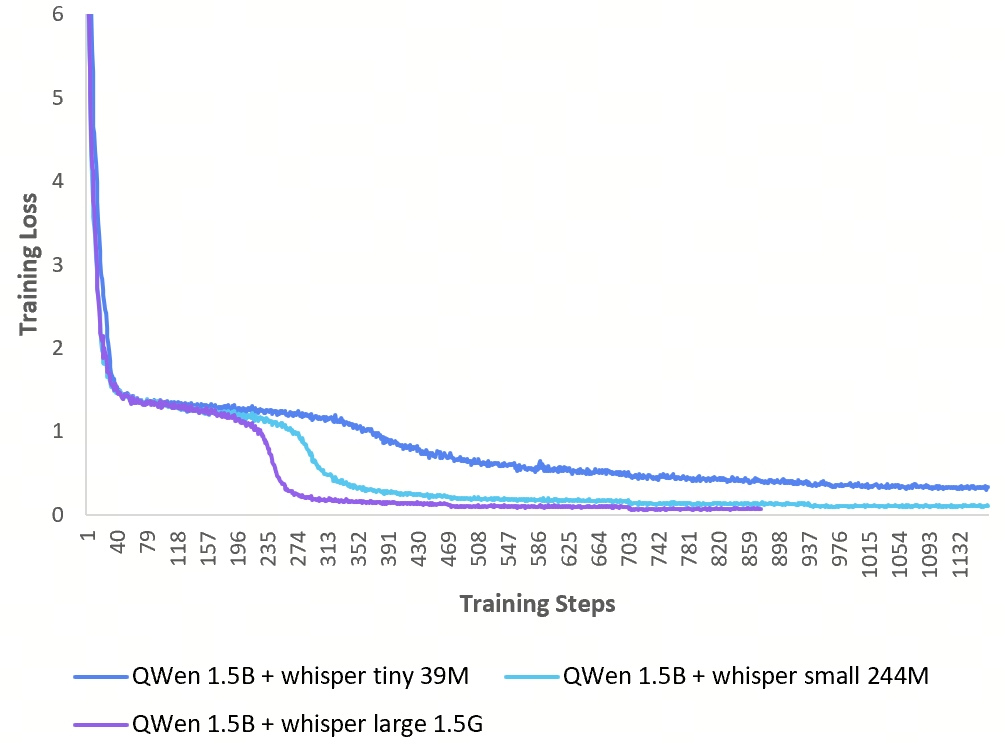
Different Speech Encoder
| Exp | LLM | Speech Encoder | Projector | CER |
|---|---|---|---|---|
| 1 | QWen2 1.5B | Whisper tiny 39M | Conv1d 4.5M | 35.82 |
| 2 | QWen2 1.5B | Whisper small 244M | Conv1d 7.3M | 12.41 |
| 3 | QWen2 1.5B | Whisper Large 1.5G | Conv1d 13.32M | 7.45 |
Training Loss
 |  |
Different Decoding Beam
Based on QWen2 1.5B + Whisper Large 1.5G.
| beam_size | 1 | 3 | 5 | 8 | 10 |
|---|---|---|---|---|---|
| CER | 7.45 | 6.82 | 6.84 | 6.83 | 6.87 |
Similar repos


Languages
Python
100.0%
We Speech Transcript based on LLM, in 300 lines of code.
Python
182
15 commits
updated Jun 20, 2025
README
WeSR
We Speech Recognition, LLM based Speech Recognition/Transcript in 300 lines of code.
Details
Motivated by SLAM-ASR and LLaMA 3.1, Our model consists of a LLM, a Speech Encoder, and a Projector(speech adapter in LLaMA). Only the projector is trainable.
- LLM, could be LLaMA, QWen, etc.
- Speech Encoder, like whisper.
Install
pip install -r requirements.txt
Data Prepare
The training data(train.json) and test data(test.jsonl) should be prepared as jsonl format, which contains wav and txt in each line. Here is an example:
{"wav": "/data/BAC009S0764W0121.wav", "txt": "甚至出现交易几乎停滞的情况"}
{"wav": "/data/BAC009S0764W0122.wav", "txt": "一二线城市虽然也处于调整中"}
Training
torchrun --standalone --nnodes=1 --nproc_per_node=8 train.py \
    --llm_model_name_or_path Qwen/Qwen2-1.5B-Instruct \
    --whisper_model_name_or_path tiny \
    --data_path train.jsonl \
    --bf16 True \
    --output_dir Qwen-1.5B-Instruct-whisper-tiny \
    --num_train_epochs 5 \
    --per_device_train_batch_size 8 \
    --per_device_eval_batch_size 1 \
    --gradient_accumulation_steps 8 \
    --evaluation_strategy "no" \
    --save_strategy "steps" \
    --save_steps 100 \
    --save_total_limit 10 \
    --learning_rate 3e-4 \
    --weight_decay 0.01 \
    --adam_beta2 0.95 \
    --warmup_ratio 0.01 \
    --lr_scheduler_type "cosine" \
    --logging_steps 1 \
    --report_to "none" \
    --model_max_length 512 \
    --gradient_checkpointing \
    --dataloader_num_workers 4 \
    --dataloader_prefetch_factor 10 \
    --deepspeed ds_config_zero3.json
Decoding
python recognize.py \
    --llm_model_name_or_path Qwen/Qwen2-1.5B-Instruct \
    --whisper_model_name_or_path tiny \
    --projector_model_path Qwen-1.5B-Instruct-whisper-tiny/checkpoint-600/model.safetensors \
    --data_path test.jsonl \
    --result_path result.txt
Results
LibriSpeech
| Exp | LLM | Speech Encoder | Projector | test_clean | test_other |
|---|---|---|---|---|---|
| 1 | LLaMA 3 8B | Whisper tiny 39M | Conv1d 9.46M | 7.62/6.29 | 18.50/17.59 |
| 2 | LLaMA 3 8B | Whisper small 244M | Conv1d 12.32M | 6.09/3.90 | 11.65/10.00 |
| 3 | LLaMA 3 8B | Whisper Large 1.5G | Conv1d 18.32M | 3.63/2.83 | 8.18/7.43 |
The number before and after '/' represents the overall WER and the WER after filtering out hallucinations, respectively. We have observed that certain recognition results may exhibit the hallucination like "I apologize, but it appears that there is no speech to transcribe."
AIShell
Different LLM
| Exp | LLM | Speech Encoder | Projector | CER |
|---|---|---|---|---|
| 1 | QWen2 0.5B | Whisper Large 1.5G | Conv1d 12.07M | 9.77 |
| 2 | QWen2 1.5B | Whisper Large 1.5G | Conv1d 13.32M | 7.45 |
| 3 | QWen2 7B | Whisper Large 1.5G | Conv1d 17.32M | 5.55 |
Different Speech Encoder
| Exp | LLM | Speech Encoder | Projector | CER |
|---|---|---|---|---|
| 1 | QWen2 1.5B | Whisper tiny 39M | Conv1d 4.5M | 35.82 |
| 2 | QWen2 1.5B | Whisper small 244M | Conv1d 7.3M | 12.41 |
| 3 | QWen2 1.5B | Whisper Large 1.5G | Conv1d 13.32M | 7.45 |
Training Loss
| |
Different Decoding Beam
Based on QWen2 1.5B + Whisper Large 1.5G.
| beam_size | 1 | 3 | 5 | 8 | 10 |
|---|---|---|---|---|---|
| CER | 7.45 | 6.82 | 6.84 | 6.83 | 6.87 |
Similar repos
Languages
Python
100.0%