
Free, open-source YouTube scraper library for Python. Search YouTube and extract video, channel, and playlist data without an API key or quota limits.
See the codeSee what people are saying
README
ytscrape — YouTube Scraper for Python (No API Key)
The fast, free, open-source Python YouTube scraper. Scrape YouTube search results, video metadata, channel info, comments, replies and transcripts — no API key, no quota, no Selenium, no browser.




Installation • Quick start • Features • Use cases • Comparison • FAQ • Docs
⭐ If ytscrape saves you time, please star the repo — it helps other developers searching for a YouTube scraper find it.
from ytscrape import YouTube

with YouTube() as yt:
    for video in yt.search("python", max_results=5):
        print(video.title, video.url)
ytscrape talks to YouTube's internal InnerTube API — the same endpoints the
web app uses — and turns responses into typed, frozen dataclasses with
transparent pagination. Pure HTTP: no Selenium, no Playwright, no API key.
Sync (YouTube) and async (AsyncYouTube) share the same surface.
⚠️ This library uses YouTube's private endpoints. Use it responsibly and at your own risk — the endpoints may change over time.
What can you scrape from YouTube?
| Data | Method | CLI |
|---|---|---|
| 🔎 YouTube search results (videos, channels, playlists, Shorts, movies) | yt.search() | ytscrape search |
| 🎬 Video metadata (title, channel, views, duration, description) | yt.video() | ytscrape video |
| 📺 Channel info (subscribers, handle, links, join date) | yt.channel() | ytscrape channel |
| 💬 Comments and replies (every comment, not only "Top") | yt.comments() | ytscrape comments |
| 📝 Transcripts / subtitles / captions | yt.transcript() | ytscrape transcript |
Export everything to JSON or CSV in one line.
Why ytscrape?
- 🔑 No API key, no quota — nothing to register, no billing project.
- 🧊 No browser — pure HTTP only.
- 🧩 Typed models (
Video,Channel,Comment,Transcript, …) +py.typed. - 💬 Every comment — replies included;
CommentSort.NEWESTdoes not hide any. - 📄 Transparent pagination — just iterate; continuation tokens are handled for you.
- 🌍 Localisation —
language(hl) andregion(gl), validated ISO codes. - ⚡ Sync & async — optional
httpxextra forAsyncYouTube. - 🖥️ CLI included —
ytscrape search "python" --max 10. - 📤 JSON / CSV export —
video.to_json(),dumps_csv(results), orytscrape search "python" --format json.
Use cases
- 📊 Data science & research — build YouTube datasets for analysis.
- 🤖 AI / LLM / RAG pipelines — pull YouTube transcripts as training or retrieval data.
- 💬 Sentiment analysis — scrape YouTube comments at scale.
- 📈 SEO & marketing — keyword research, competitor channel monitoring.
- 🧪 Academic studies — reproducible collection of video & channel metadata.
- 🛠️ Bots & automations — lightweight alternative to the YouTube Data API v3.
Installation
pip install ytscrape            # or: uv add ytscrape
pip install "ytscrape[async]"   # optional async API (httpx)
Requires Python 3.10+. Runtime deps: requests, pycountry, defusedxml
(+ httpx with the async extra).
Quick start
from ytscrape import YouTube, SearchFilter, CommentSort

with YouTube(language="en", region="US") as yt:
    for video in yt.search("python", filter=SearchFilter.VIDEOS, max_results=20):
        print(video.title, "-", video.url)

    details = yt.video("https://www.youtube.com/watch?v=dQw4w9WgXcQ")
    print(details.title, details.channel, details.views, details.length_seconds)

    for comment in yt.comments(
        "https://youtu.be/dQw4w9WgXcQ",
        include_replies=True,
        sort=CommentSort.NEWEST,
        max_results=100,
    ):
        marker = "  ↳" if comment.is_reply else "-"
        print(f"{marker} {comment.author}: {comment.text}")
Async (same methods, await / async for):
import asyncio
from ytscrape import AsyncYouTube, SearchFilter


async def main() -> None:
    async with AsyncYouTube(max_concurrency=8) as yt:
        async for video in await yt.search(
            "python", filter=SearchFilter.VIDEOS, max_results=5
        ):
            print(video.title)


asyncio.run(main())
📂 Runnable sync + async snippets for every feature:
examples/· full guides: vsmutok.github.io/ytscrape
Feature coverage
| Area | Status | Notes |
|---|---|---|
| Search — videos / channels / playlists / Shorts / movies | ✅ | SearchFilter.* |
| Video & channel metadata | ✅ | video(), channel() (id, URL, @handle) |
| Comments + replies | ✅ | comments(), CommentSort.NEWEST for every comment |
| Transcripts / captions | ✅ | transcript() / transcripts() |
| Pagination | ✅ | Transparent for search and comments |
Localisation (hl / gl) | ✅ | Validated ISO codes |
Typed models + py.typed | ✅ | PEP 561 |
| CLI | ✅ | ytscrape / python -m ytscrape |
| Async API | ✅ | AsyncYouTube via ytscrape[async] |
Channel videos tab (yt.channel_videos()) | ✅ | Lazy pagination |
| Retries, backoff, rate limiting, bot detection | ✅ | RetryPolicy, RateLimiter, min_interval |
| Other channel tabs, playlist items, related / trending | 🚧 | Planned |
ytscrape vs. the alternatives
| ytscrape | YouTube Data API | yt-dlp | Browser automation | |
|---|---|---|---|---|
| API key required | ❌ | ✅ | ❌ | ❌ |
| Daily quota | ❌ | ✅ | ❌ | ❌ |
| Browser / driver needed | ❌ | ❌ | ❌ | ✅ |
| Search / metadata / comments | ✅ | ✅ | ✅ | ✅ |
| Typed Python models | ✅ | ❌ | ❌ | ❌ |
Async (asyncio) API | ✅ | ❌ | ❌ | varies |
| Downloads media | ❌ | ❌ | ✅ | ✅ |
| Install size | tiny | medium | large | huge |
How it works
High-level flow — sync and async share the same models and parsing layer:
graph LR
    User[User code / CLI] --> Facade[YouTube / AsyncYouTube]
    Facade --> Client[InnerTubeClient / AsyncInnerTubeClient]
    Facade --> Results[Lazy results / comment threads]
    Client --> InnerTube[YouTube InnerTube API]
    Client --> Context[InnerTube context]
    Results --> Client
    Client --> Parsing[parsing helpers]
    Results --> Parsing
    Parsing --> Models[Frozen dataclasses]
    Models --> User
- Load
youtube.comonce and extract the InnerTube context (API key, client version, visitor data). - POST to
youtubei/v1/search,player,browse,next, etc. with that context. - Parse responses into frozen dataclasses; continuation tokens are followed while you iterate.
Documentation
Deep dives live on the docs site (not duplicated here):
| Topic | Link |
|---|---|
| Installation | docs |
| Quickstart | docs |
| Search, details, comments, transcripts | guides |
| Language & region, pagination, errors | guides |
| Async API (concurrency, retries, fan-out) | async guide |
| Proxies, custom sessions | advanced |
| CLI | CLI overview |
| API reference | API |
| Examples (sync + async) | examples/ |
CLI cheatsheet
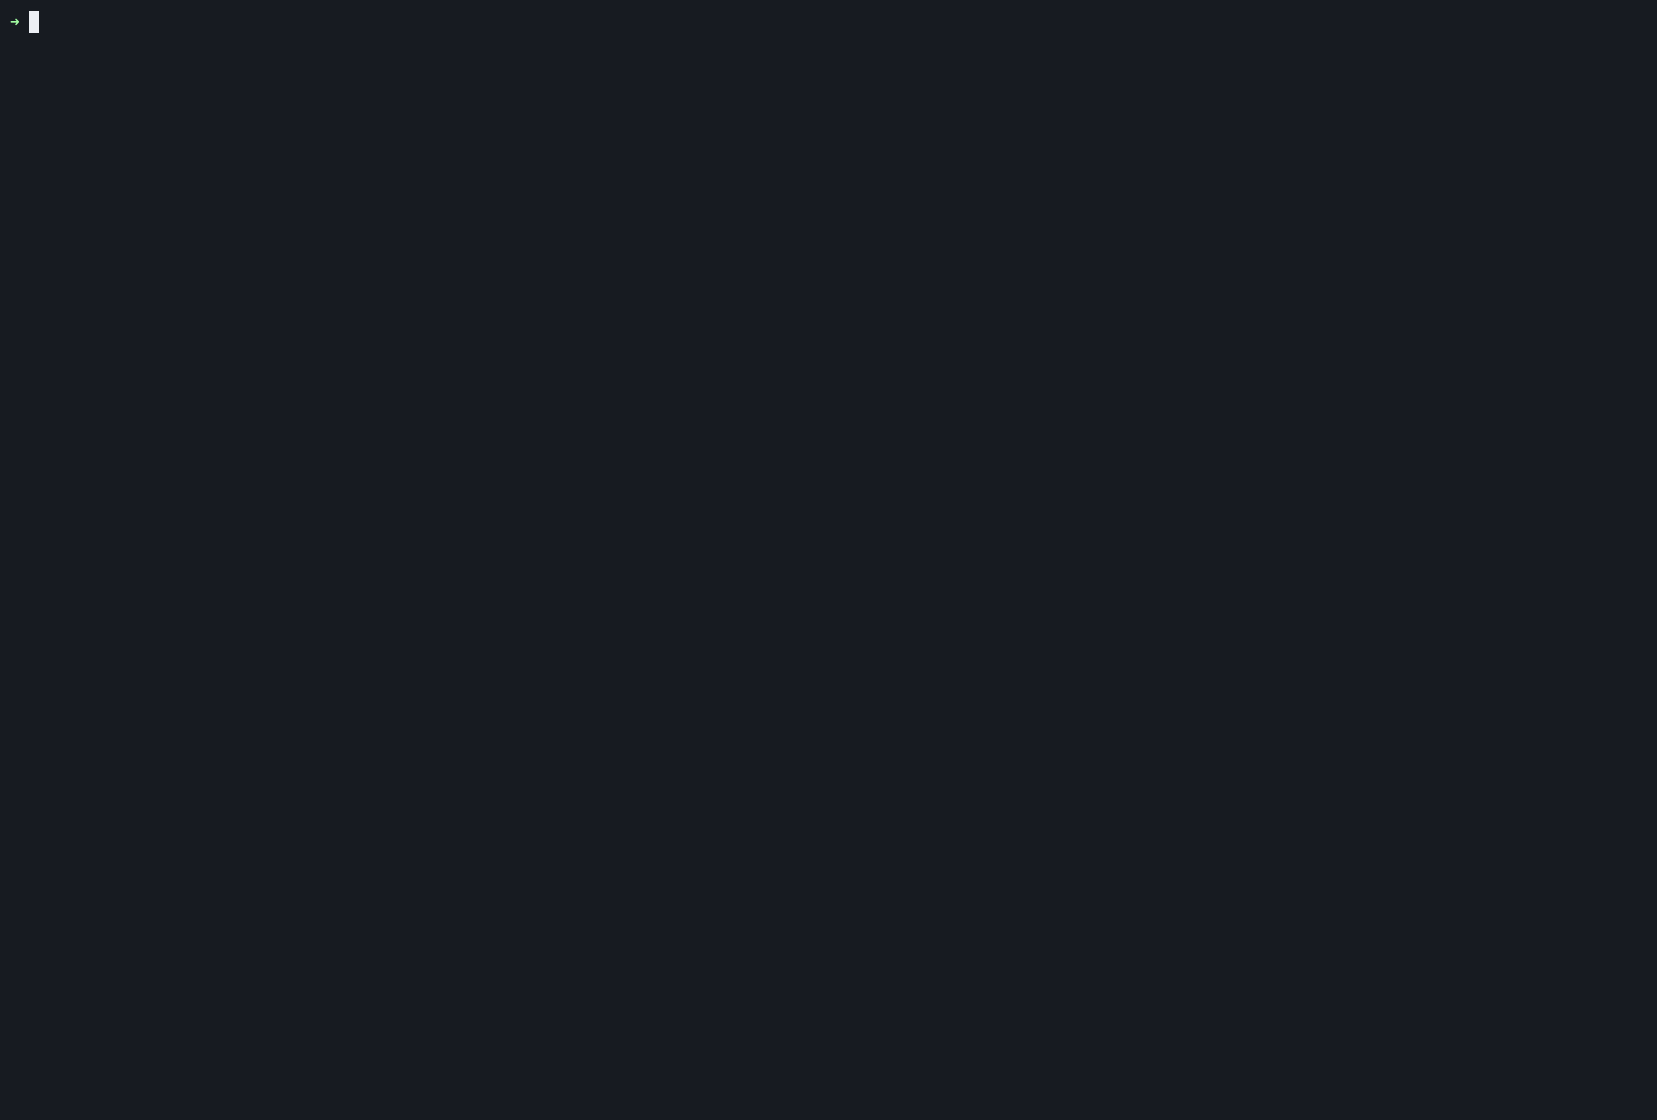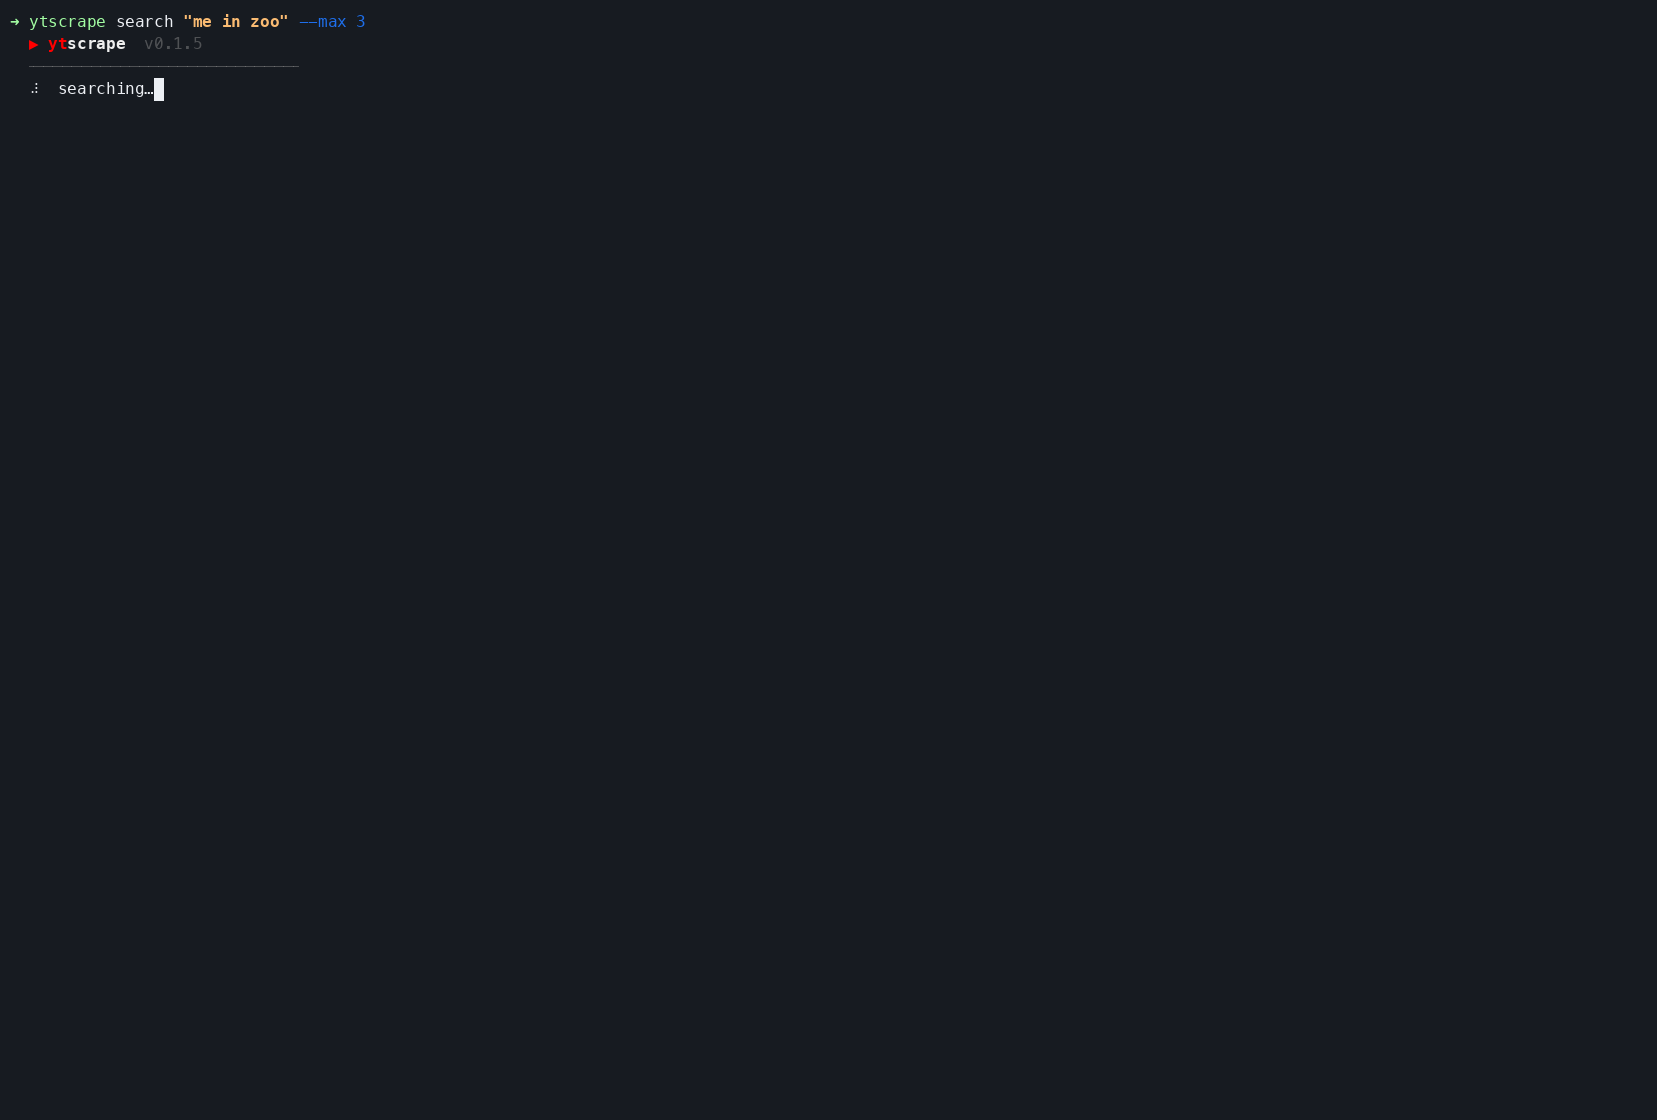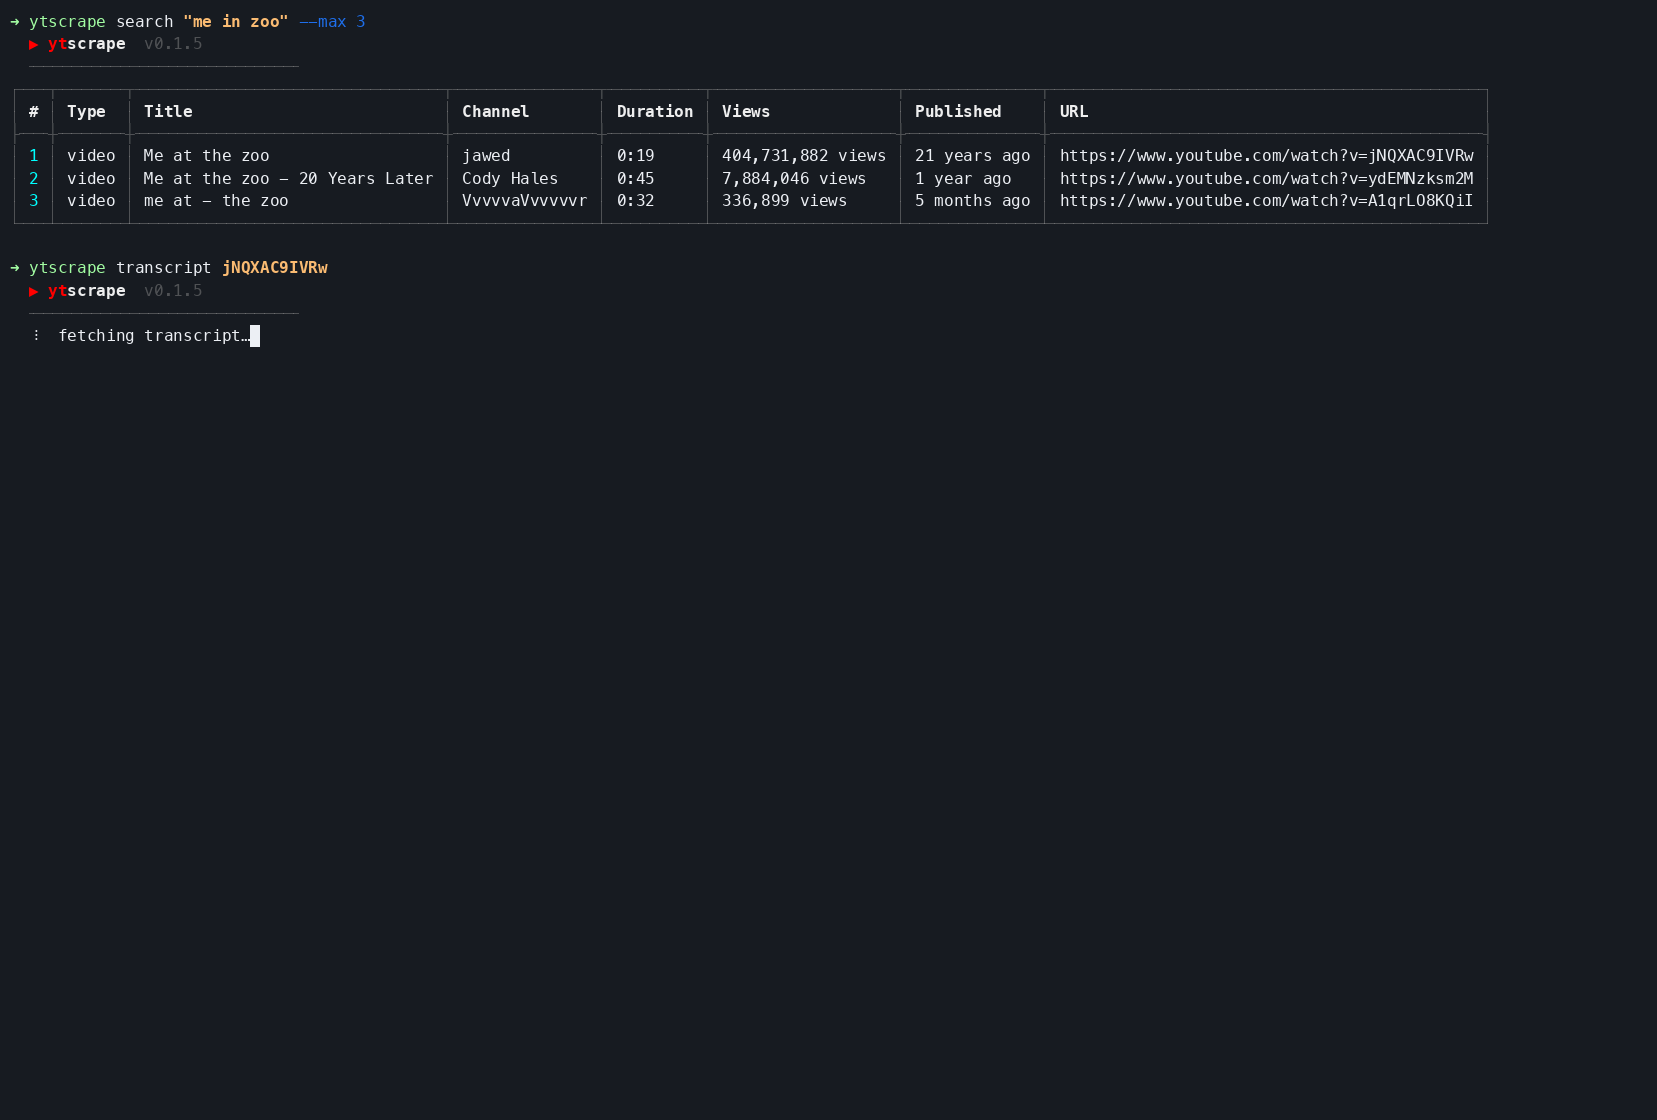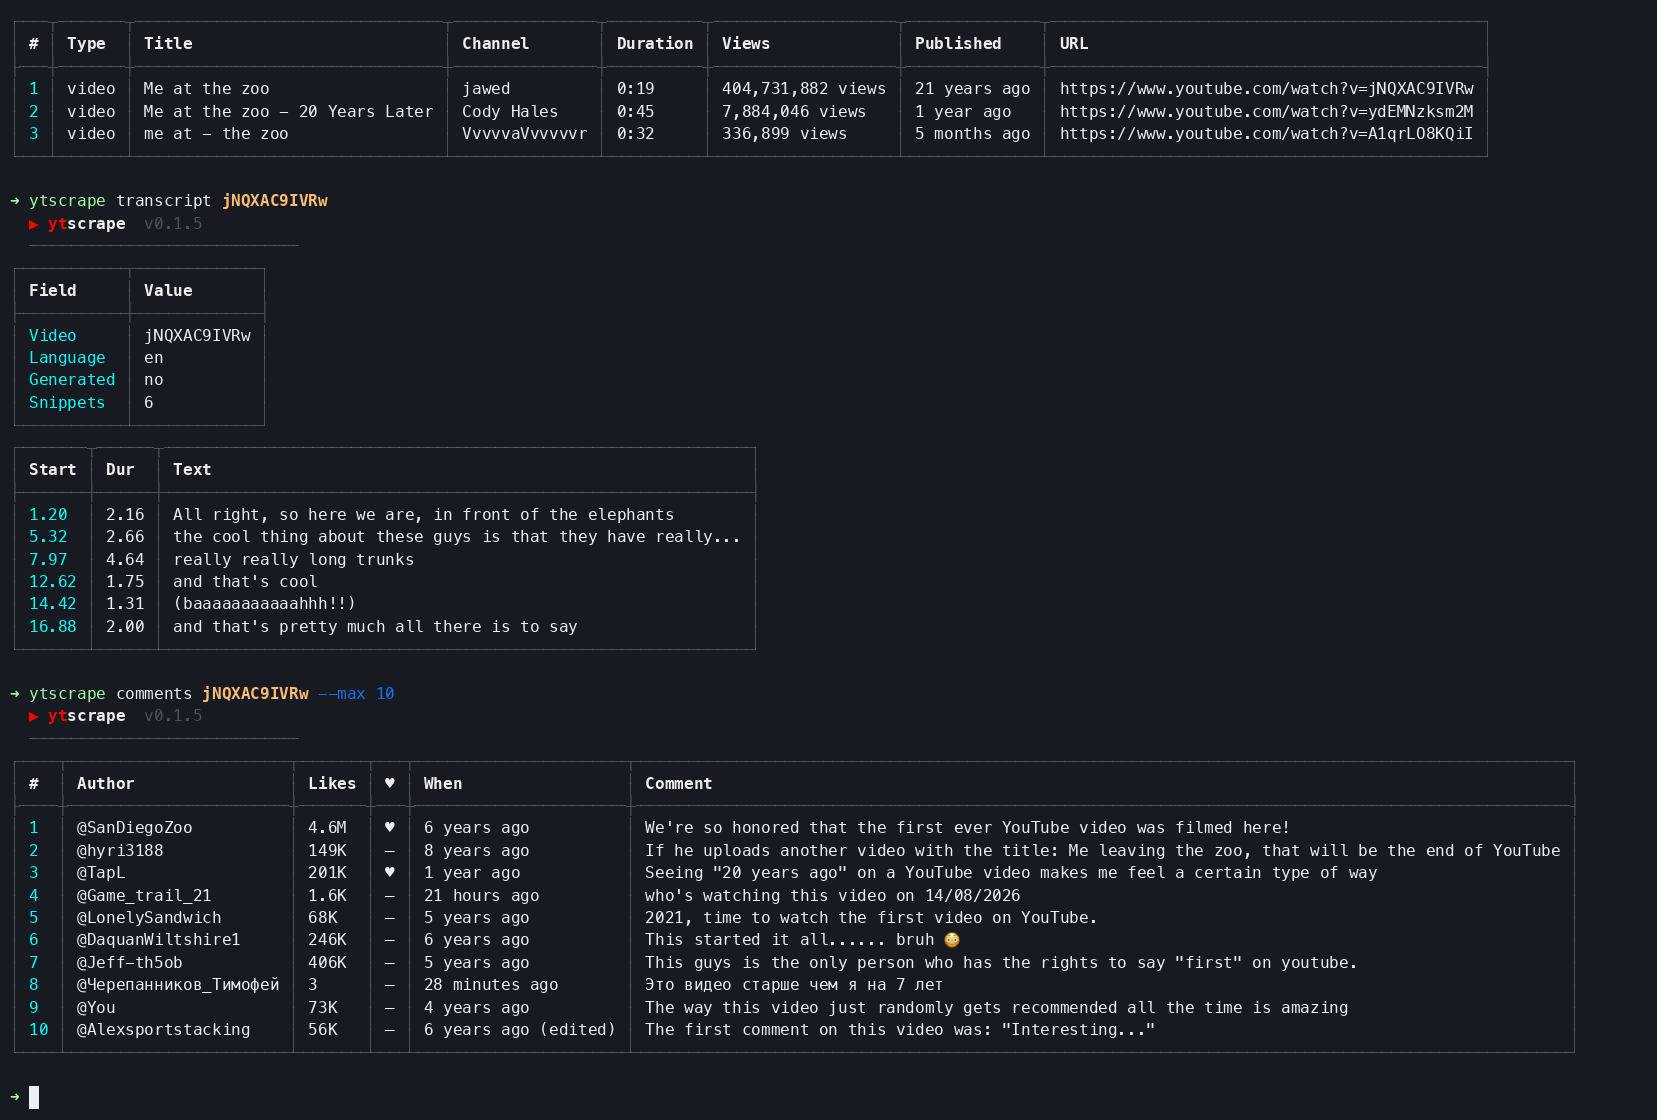
The CLI prints colourful boxed tables under a mini ▶ ytscrape wordmark, with a
spinner while requests are in flight:
ytscrape search "python tutorial" --filter videos --max 10
ytscrape --language uk --region UA search "музика" --max 10
ytscrape video https://www.youtube.com/watch?v=dQw4w9WgXcQ
ytscrape channel @RickAstleyYT
ytscrape transcript dQw4w9WgXcQ --lang en
ytscrape comments https://youtu.be/dQw4w9WgXcQ --replies --sort newest --max 20
python -m ytscrape … works too. Pass --max 0 to comments for no limit.
FAQ
Do I need a YouTube Data API key?
No. ytscrape uses the same internal endpoints as the YouTube web app.
Why are some comments missing?
YouTube's default "Top comments" view hides less relevant comments and
"potential spam". Pass sort="newest" (or CommentSort.NEWEST) to collect every
comment.
Why is like_count None?
YouTube abbreviates large counts (1.2K). The raw string is always in
like_count_text.
Can I use a proxy?
Yes — inject your own requests.Session into InnerTubeClient, or
httpx.AsyncClient into AsyncInnerTubeClient. See the
advanced guide.
Will I get rate limited?
There is no published quota, but YouTube may throttle aggressive traffic. Reuse
one client, cap work with max_results, and add delays for large crawls.
Does it download videos?
No — metadata only. Use yt-dlp for media.
Is scraping YouTube legal?
Private endpoints may conflict with YouTube's Terms of Service. The library is for research and educational use; you are responsible for how you use it.
Contributing
Bug reports, ideas and PRs are welcome — see CONTRIBUTING.md.
git clone https://github.com/vsmutok/ytscrape && cd ytscrape
uv sync --dev
uv run pytest
uv run pre-commit run --all-files
- 🗺️ todo: todo.md
- 📝 Changelog: CHANGELOG.md
Star History
License
MIT — free for personal and commercial use.
Keywords: youtube scraper, python youtube scraper, scrape youtube, youtube scraping, youtube comments scraper, youtube transcript downloader, youtube search api python, youtube data api alternative, youtube api without key, innertube api, youtube metadata extractor, youtube channel scraper, youtube crawler, youtube shorts scraper, async youtube scraper.
Similar repos


Languages
Python
100.0%
Free, open-source YouTube scraper library for Python. Search YouTube and extract video, channel, and playlist data without an API key or quota limits.
See the codeSee what people are saying
README
ytscrape — YouTube Scraper for Python (No API Key)
The fast, free, open-source Python YouTube scraper. Scrape YouTube search results, video metadata, channel info, comments, replies and transcripts — no API key, no quota, no Selenium, no browser.
Installation • Quick start • Features • Use cases • Comparison • FAQ • Docs
⭐ If ytscrape saves you time, please star the repo — it helps other developers searching for a YouTube scraper find it.
from ytscrape import YouTube

with YouTube() as yt:
    for video in yt.search("python", max_results=5):
        print(video.title, video.url)
ytscrape talks to YouTube's internal InnerTube API — the same endpoints the
web app uses — and turns responses into typed, frozen dataclasses with
transparent pagination. Pure HTTP: no Selenium, no Playwright, no API key.
Sync (YouTube) and async (AsyncYouTube) share the same surface.
⚠️ This library uses YouTube's private endpoints. Use it responsibly and at your own risk — the endpoints may change over time.
What can you scrape from YouTube?
| Data | Method | CLI |
|---|---|---|
| 🔎 YouTube search results (videos, channels, playlists, Shorts, movies) | yt.search() | ytscrape search |
| 🎬 Video metadata (title, channel, views, duration, description) | yt.video() | ytscrape video |
| 📺 Channel info (subscribers, handle, links, join date) | yt.channel() | ytscrape channel |
| 💬 Comments and replies (every comment, not only "Top") | yt.comments() | ytscrape comments |
| 📝 Transcripts / subtitles / captions | yt.transcript() | ytscrape transcript |
Export everything to JSON or CSV in one line.
Why ytscrape?
- 🔑 No API key, no quota — nothing to register, no billing project.
- 🧊 No browser — pure HTTP only.
- 🧩 Typed models (
Video,Channel,Comment,Transcript, …) +py.typed. - 💬 Every comment — replies included;
CommentSort.NEWESTdoes not hide any. - 📄 Transparent pagination — just iterate; continuation tokens are handled for you.
- 🌍 Localisation —
language(hl) andregion(gl), validated ISO codes. - ⚡ Sync & async — optional
httpxextra forAsyncYouTube. - 🖥️ CLI included —
ytscrape search "python" --max 10. - 📤 JSON / CSV export —
video.to_json(),dumps_csv(results), orytscrape search "python" --format json.
Use cases
- 📊 Data science & research — build YouTube datasets for analysis.
- 🤖 AI / LLM / RAG pipelines — pull YouTube transcripts as training or retrieval data.
- 💬 Sentiment analysis — scrape YouTube comments at scale.
- 📈 SEO & marketing — keyword research, competitor channel monitoring.
- 🧪 Academic studies — reproducible collection of video & channel metadata.
- 🛠️ Bots & automations — lightweight alternative to the YouTube Data API v3.
Installation
pip install ytscrape            # or: uv add ytscrape
pip install "ytscrape[async]"   # optional async API (httpx)
Requires Python 3.10+. Runtime deps: requests, pycountry, defusedxml
(+ httpx with the async extra).
Quick start
from ytscrape import YouTube, SearchFilter, CommentSort

with YouTube(language="en", region="US") as yt:
    for video in yt.search("python", filter=SearchFilter.VIDEOS, max_results=20):
        print(video.title, "-", video.url)

    details = yt.video("https://www.youtube.com/watch?v=dQw4w9WgXcQ")
    print(details.title, details.channel, details.views, details.length_seconds)

    for comment in yt.comments(
        "https://youtu.be/dQw4w9WgXcQ",
        include_replies=True,
        sort=CommentSort.NEWEST,
        max_results=100,
    ):
        marker = "  ↳" if comment.is_reply else "-"
        print(f"{marker} {comment.author}: {comment.text}")
Async (same methods, await / async for):
import asyncio
from ytscrape import AsyncYouTube, SearchFilter


async def main() -> None:
    async with AsyncYouTube(max_concurrency=8) as yt:
        async for video in await yt.search(
            "python", filter=SearchFilter.VIDEOS, max_results=5
        ):
            print(video.title)


asyncio.run(main())
📂 Runnable sync + async snippets for every feature:
examples/· full guides: vsmutok.github.io/ytscrape
Feature coverage
| Area | Status | Notes |
|---|---|---|
| Search — videos / channels / playlists / Shorts / movies | ✅ | SearchFilter.* |
| Video & channel metadata | ✅ | video(), channel() (id, URL, @handle) |
| Comments + replies | ✅ | comments(), CommentSort.NEWEST for every comment |
| Transcripts / captions | ✅ | transcript() / transcripts() |
| Pagination | ✅ | Transparent for search and comments |
Localisation (hl / gl) | ✅ | Validated ISO codes |
Typed models + py.typed | ✅ | PEP 561 |
| CLI | ✅ | ytscrape / python -m ytscrape |
| Async API | ✅ | AsyncYouTube via ytscrape[async] |
Channel videos tab (yt.channel_videos()) | ✅ | Lazy pagination |
| Retries, backoff, rate limiting, bot detection | ✅ | RetryPolicy, RateLimiter, min_interval |
| Other channel tabs, playlist items, related / trending | 🚧 | Planned |
ytscrape vs. the alternatives
| ytscrape | YouTube Data API | yt-dlp | Browser automation | |
|---|---|---|---|---|
| API key required | ❌ | ✅ | ❌ | ❌ |
| Daily quota | ❌ | ✅ | ❌ | ❌ |
| Browser / driver needed | ❌ | ❌ | ❌ | ✅ |
| Search / metadata / comments | ✅ | ✅ | ✅ | ✅ |
| Typed Python models | ✅ | ❌ | ❌ | ❌ |
Async (asyncio) API | ✅ | ❌ | ❌ | varies |
| Downloads media | ❌ | ❌ | ✅ | ✅ |
| Install size | tiny | medium | large | huge |
How it works
High-level flow — sync and async share the same models and parsing layer:
graph LR
    User[User code / CLI] --> Facade[YouTube / AsyncYouTube]
    Facade --> Client[InnerTubeClient / AsyncInnerTubeClient]
    Facade --> Results[Lazy results / comment threads]
    Client --> InnerTube[YouTube InnerTube API]
    Client --> Context[InnerTube context]
    Results --> Client
    Client --> Parsing[parsing helpers]
    Results --> Parsing
    Parsing --> Models[Frozen dataclasses]
    Models --> User
- Load
youtube.comonce and extract the InnerTube context (API key, client version, visitor data). - POST to
youtubei/v1/search,player,browse,next, etc. with that context. - Parse responses into frozen dataclasses; continuation tokens are followed while you iterate.
Documentation
Deep dives live on the docs site (not duplicated here):
| Topic | Link |
|---|---|
| Installation | docs |
| Quickstart | docs |
| Search, details, comments, transcripts | guides |
| Language & region, pagination, errors | guides |
| Async API (concurrency, retries, fan-out) | async guide |
| Proxies, custom sessions | advanced |
| CLI | CLI overview |
| API reference | API |
| Examples (sync + async) | examples/ |
CLI cheatsheet
The CLI prints colourful boxed tables under a mini ▶ ytscrape wordmark, with a
spinner while requests are in flight:
ytscrape search "python tutorial" --filter videos --max 10
ytscrape --language uk --region UA search "музика" --max 10
ytscrape video https://www.youtube.com/watch?v=dQw4w9WgXcQ
ytscrape channel @RickAstleyYT
ytscrape transcript dQw4w9WgXcQ --lang en
ytscrape comments https://youtu.be/dQw4w9WgXcQ --replies --sort newest --max 20
python -m ytscrape … works too. Pass --max 0 to comments for no limit.
FAQ
Do I need a YouTube Data API key?
No. ytscrape uses the same internal endpoints as the YouTube web app.
Why are some comments missing?
YouTube's default "Top comments" view hides less relevant comments and
"potential spam". Pass sort="newest" (or CommentSort.NEWEST) to collect every
comment.
Why is like_count None?
YouTube abbreviates large counts (1.2K). The raw string is always in
like_count_text.
Can I use a proxy?
Yes — inject your own requests.Session into InnerTubeClient, or
httpx.AsyncClient into AsyncInnerTubeClient. See the
advanced guide.
Will I get rate limited?
There is no published quota, but YouTube may throttle aggressive traffic. Reuse
one client, cap work with max_results, and add delays for large crawls.
Does it download videos?
No — metadata only. Use yt-dlp for media.
Is scraping YouTube legal?
Private endpoints may conflict with YouTube's Terms of Service. The library is for research and educational use; you are responsible for how you use it.
Contributing
Bug reports, ideas and PRs are welcome — see CONTRIBUTING.md.
git clone https://github.com/vsmutok/ytscrape && cd ytscrape
uv sync --dev
uv run pytest
uv run pre-commit run --all-files
- 🗺️ todo: todo.md
- 📝 Changelog: CHANGELOG.md
Star History
License
MIT — free for personal and commercial use.
Keywords: youtube scraper, python youtube scraper, scrape youtube, youtube scraping, youtube comments scraper, youtube transcript downloader, youtube search api python, youtube data api alternative, youtube api without key, innertube api, youtube metadata extractor, youtube channel scraper, youtube crawler, youtube shorts scraper, async youtube scraper.
Similar repos
Languages
Python
100.0%