
The repository to showcase the best framework for tabular data - the Awesome CatBoost
287
40 commits
updated Aug 22, 2026
README
Awesome CatBoost 

Curated by Valeriy Manokhin, PhD, MBA, CQF.
Mastering CatBoost
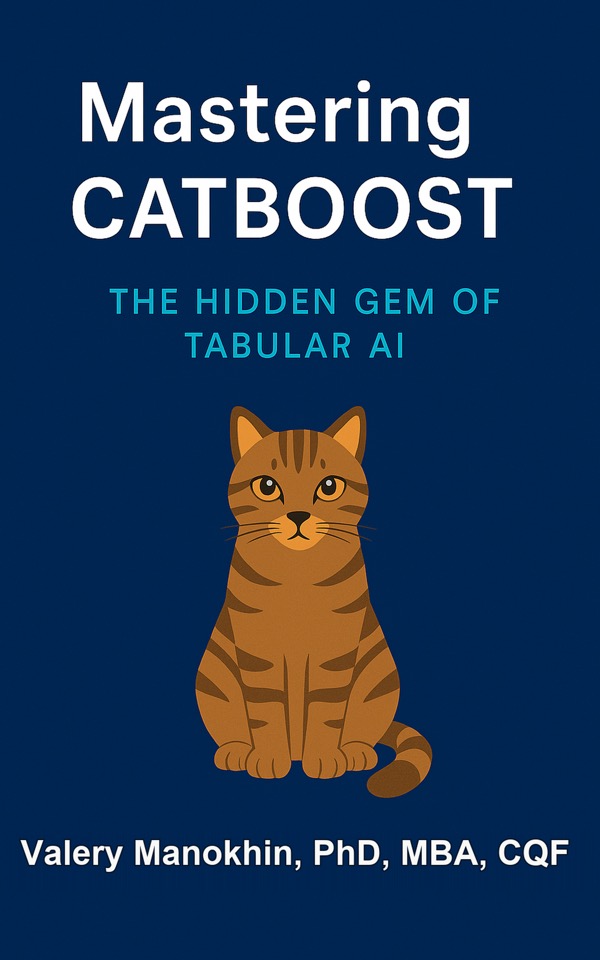
Mastering CatBoost: The Hidden Gem of Tabular AI is the practical companion to this list. It follows CatBoost from ordered statistics and symmetric trees through tuning, uncertainty, ranking, feature engineering, interpretability, and deployment.
- Paperback on Amazon (ISBN 978-1-919012-43-8)
- Hardcover on Amazon (ISBN 978-1-919012-44-5)
- Core edition on Gumroad
- Pro companion on Gumroad
- Public code and notebooks
- Chapter-by-chapter additional materials
The Amazon links search by ISBN until the print listings are active. The Gumroad links are the maintained purchase pages.
What was added
This repository now includes a maintained companion layer for the book:
- 119 runnable book listings with matching notebooks in the public code repository.
- A chapter-by-chapter map from the book to the relevant CatBoost APIs, tutorials, and research papers.
- Curated starting points for ordered statistics, tuning, uncertainty, ranking, feature engineering, calibration, SHAP, export, MLOps, and causal/propensity workflows.
- Primary-source links for CatBoost, conformal prediction, tabular benchmarks, SHAP, MLflow, DVC, Feast, and FastAPI.
- Dataset and experiment-hygiene guidance covering validation boundaries, schema recording, seeds, horizons, and reproducibility.
Start with the additional materials guide, then open the book listing index to jump directly into runnable examples.
Why CatBoost is worth studying
CatBoost is a gradient-boosted decision-tree library with native support for categorical, text, and embedding features. Comparative studies are useful context, not universal guarantees: results depend on the dataset, protocol, feature representation, and compute budget. This repository collects the papers, tutorials, benchmarks, and production references needed to test those claims rather than repeat them.
- Official CatBoost documentation
- Official CatBoost tutorials
- CatBoost: Unbiased Boosting with Categorical Features
- CatBoost: Gradient Boosting with Categorical Features Support
- Large-scale tabular benchmark: TabArena
Table of Contents
Additional materials
The new additional materials guide maps the book's chapters to the public code, official CatBoost tutorials and documentation, primary research papers, uncertainty/ranking/interpretability resources, and production tools such as MLflow, DVC, Feast, and FastAPI. It is curated as a learning path rather than a claim that one model wins on every dataset.
Videos
- Anna Veronika Dorogush - CatBoost - the new generation of Gradient Boosting (EuroPython Conference, 2018)
- XGBoost ❌ LightGBM ❌ CatBoost ❌ Scikit-Learn GRADIENT BOOSTING Performance Compared
- Yandex Catboost: Open-source Gradient Boosting Library (2018)
- CatBoost Part 1: Ordered Target Encoding by Josh Starmer (2023)
- Mastering CatBoost
- The Strategic Showdown CatBoost vs XGBoost vs LightGBM 🔥🔥🔥🔥🔥🚀
Benchmarks
- TabArena: A Living Benchmark for Machine Learning on Tabular Data TabArena
- A Closer Look at Deep Learning on Tabular Data large scale study (300! datasets) showing CatBoost dominates on tabular data 🔥🔥🔥🔥🔥🚀🚀🚀🚀🚀 code
- When Do Neural Nets Outperform Boosted Trees on Tabular Data? (2023) — a large comparison whose results vary by dataset and protocol.
- A Comprehensive Benchmark of Machine and Deep Learning Across Diverse Tabular Datasets (2024) 🔥🔥🔥🔥🔥 large scale study showing CatBoost dominates on tabular data
- CatBoost vs XGBoost
Papers
- A Closer Look at Deep Learning on Tabular Data large scale study (300! datasets) showing CatBoost dominates on tabular data 🔥🔥🔥🔥🔥🚀🚀🚀🚀🚀 code
- CatBoost: gradient boosting with categorical features support by Anna Veronika Dorogush, Vasily Ershov, Andrey Gulin (NeurIPS, 2017) 🔥🔥🔥🔥🔥
- CatBoost: unbiased boosting with categorical features by Liudmila Prokhorenkova, Gleb Gusev, Aleksandr Vorobev, Anna Veronika Dorogush, Andrey Gulin (Neurips, 2018) 🔥🔥🔥🔥🔥
- KiDS-SQuaD: Machine learning selection of bright extragalactic objects to search for new gravitationally lensed quasars (2019)
- When Do Neural Nets Outperform Boosted Trees on Tabular Data? (2023)
- CatBoost for big data: an interdisciplinary review (Hancock and Khoshgoftaar, 2020)
- A Comprehensive Benchmark of Machine and Deep Learning Across Diverse Tabular Datasets (2024) 🔥🔥🔥🔥🔥 large scale study showing CatBoost dominates on tabular data
Articles
- CatBoost Hyperparameter Tuning Guide with Optuna by Mario Filho (2023)
- XGBoost? CatBoost? LightGBM? (2023)
- When to Choose CatBoost Over XGBoost or LightGBM (2023)
- CatBoost vs. LightGBM vs. XGBoost
- What Is CatBoost? by Artem Oppermann (2023)
- CatBoost Secrets: How It Handles Categorical Columns and Tree Growth by Gneya Pandya (2024)
- How CatBoost encodes categorical variables by Adrian Biarnes (2021)
Kaggle
- catboost uncertainty by x4 Kaggle Grandmaster Darius Barušauskas (Kaggle 'raddar') (2024) 🔥🔥🔥🔥🔥
- Probabilistic forecasting I: Temperature (2024) 🔥🔥🔥🔥🔥
About the curator
Valeriy Manokhin, PhD, MBA, CQF curates this list and maintains the companion book and code repository.
Contributors

40 commits
Similar repos





The repository to showcase the best framework for tabular data - the Awesome CatBoost
287
40 commits
updated Aug 22, 2026
README
Awesome CatBoost
Curated by Valeriy Manokhin, PhD, MBA, CQF.
Mastering CatBoost
Mastering CatBoost: The Hidden Gem of Tabular AI is the practical companion to this list. It follows CatBoost from ordered statistics and symmetric trees through tuning, uncertainty, ranking, feature engineering, interpretability, and deployment.
- Paperback on Amazon (ISBN 978-1-919012-43-8)
- Hardcover on Amazon (ISBN 978-1-919012-44-5)
- Core edition on Gumroad
- Pro companion on Gumroad
- Public code and notebooks
- Chapter-by-chapter additional materials
The Amazon links search by ISBN until the print listings are active. The Gumroad links are the maintained purchase pages.
What was added
This repository now includes a maintained companion layer for the book:
- 119 runnable book listings with matching notebooks in the public code repository.
- A chapter-by-chapter map from the book to the relevant CatBoost APIs, tutorials, and research papers.
- Curated starting points for ordered statistics, tuning, uncertainty, ranking, feature engineering, calibration, SHAP, export, MLOps, and causal/propensity workflows.
- Primary-source links for CatBoost, conformal prediction, tabular benchmarks, SHAP, MLflow, DVC, Feast, and FastAPI.
- Dataset and experiment-hygiene guidance covering validation boundaries, schema recording, seeds, horizons, and reproducibility.
Start with the additional materials guide, then open the book listing index to jump directly into runnable examples.
Why CatBoost is worth studying
CatBoost is a gradient-boosted decision-tree library with native support for categorical, text, and embedding features. Comparative studies are useful context, not universal guarantees: results depend on the dataset, protocol, feature representation, and compute budget. This repository collects the papers, tutorials, benchmarks, and production references needed to test those claims rather than repeat them.
- Official CatBoost documentation
- Official CatBoost tutorials
- CatBoost: Unbiased Boosting with Categorical Features
- CatBoost: Gradient Boosting with Categorical Features Support
- Large-scale tabular benchmark: TabArena
Table of Contents
Additional materials
The new additional materials guide maps the book's chapters to the public code, official CatBoost tutorials and documentation, primary research papers, uncertainty/ranking/interpretability resources, and production tools such as MLflow, DVC, Feast, and FastAPI. It is curated as a learning path rather than a claim that one model wins on every dataset.
Videos
- Anna Veronika Dorogush - CatBoost - the new generation of Gradient Boosting (EuroPython Conference, 2018)
- XGBoost ❌ LightGBM ❌ CatBoost ❌ Scikit-Learn GRADIENT BOOSTING Performance Compared
- Yandex Catboost: Open-source Gradient Boosting Library (2018)
- CatBoost Part 1: Ordered Target Encoding by Josh Starmer (2023)
- Mastering CatBoost
- The Strategic Showdown CatBoost vs XGBoost vs LightGBM 🔥🔥🔥🔥🔥🚀
Benchmarks
- TabArena: A Living Benchmark for Machine Learning on Tabular Data TabArena
- A Closer Look at Deep Learning on Tabular Data large scale study (300! datasets) showing CatBoost dominates on tabular data 🔥🔥🔥🔥🔥🚀🚀🚀🚀🚀 code
- When Do Neural Nets Outperform Boosted Trees on Tabular Data? (2023) — a large comparison whose results vary by dataset and protocol.
- A Comprehensive Benchmark of Machine and Deep Learning Across Diverse Tabular Datasets (2024) 🔥🔥🔥🔥🔥 large scale study showing CatBoost dominates on tabular data
- CatBoost vs XGBoost
Papers
- A Closer Look at Deep Learning on Tabular Data large scale study (300! datasets) showing CatBoost dominates on tabular data 🔥🔥🔥🔥🔥🚀🚀🚀🚀🚀 code
- CatBoost: gradient boosting with categorical features support by Anna Veronika Dorogush, Vasily Ershov, Andrey Gulin (NeurIPS, 2017) 🔥🔥🔥🔥🔥
- CatBoost: unbiased boosting with categorical features by Liudmila Prokhorenkova, Gleb Gusev, Aleksandr Vorobev, Anna Veronika Dorogush, Andrey Gulin (Neurips, 2018) 🔥🔥🔥🔥🔥
- KiDS-SQuaD: Machine learning selection of bright extragalactic objects to search for new gravitationally lensed quasars (2019)
- When Do Neural Nets Outperform Boosted Trees on Tabular Data? (2023)
- CatBoost for big data: an interdisciplinary review (Hancock and Khoshgoftaar, 2020)
- A Comprehensive Benchmark of Machine and Deep Learning Across Diverse Tabular Datasets (2024) 🔥🔥🔥🔥🔥 large scale study showing CatBoost dominates on tabular data
Articles
- CatBoost Hyperparameter Tuning Guide with Optuna by Mario Filho (2023)
- XGBoost? CatBoost? LightGBM? (2023)
- When to Choose CatBoost Over XGBoost or LightGBM (2023)
- CatBoost vs. LightGBM vs. XGBoost
- What Is CatBoost? by Artem Oppermann (2023)
- CatBoost Secrets: How It Handles Categorical Columns and Tree Growth by Gneya Pandya (2024)
- How CatBoost encodes categorical variables by Adrian Biarnes (2021)
Kaggle
- catboost uncertainty by x4 Kaggle Grandmaster Darius Barušauskas (Kaggle 'raddar') (2024) 🔥🔥🔥🔥🔥
- Probabilistic forecasting I: Temperature (2024) 🔥🔥🔥🔥🔥
About the curator
Valeriy Manokhin, PhD, MBA, CQF curates this list and maintains the companion book and code repository.
Similar repos
Contributors
40 commits