
OpenVLThinker [NeurIPS 2025] & OpenVLThinkerV2 [COLM 2026]
Python
157
36 commits
updated May 25, 2026
README
OpenVLThinkerV2: A Generalist Multimodal Reasoning Model for Multi-domain Visual Tasks
Wenbo Hu, Xin Chen, Yan Gao-Tian, Yihe Deng, Nanyun Peng, Kai-Wei Chang
📑 Paper | 📖 arXiv | 🌐 Homepage | 🤗 Model (Coming) 🤗 HF Daily Paper
🏠 About
🏆 Performance
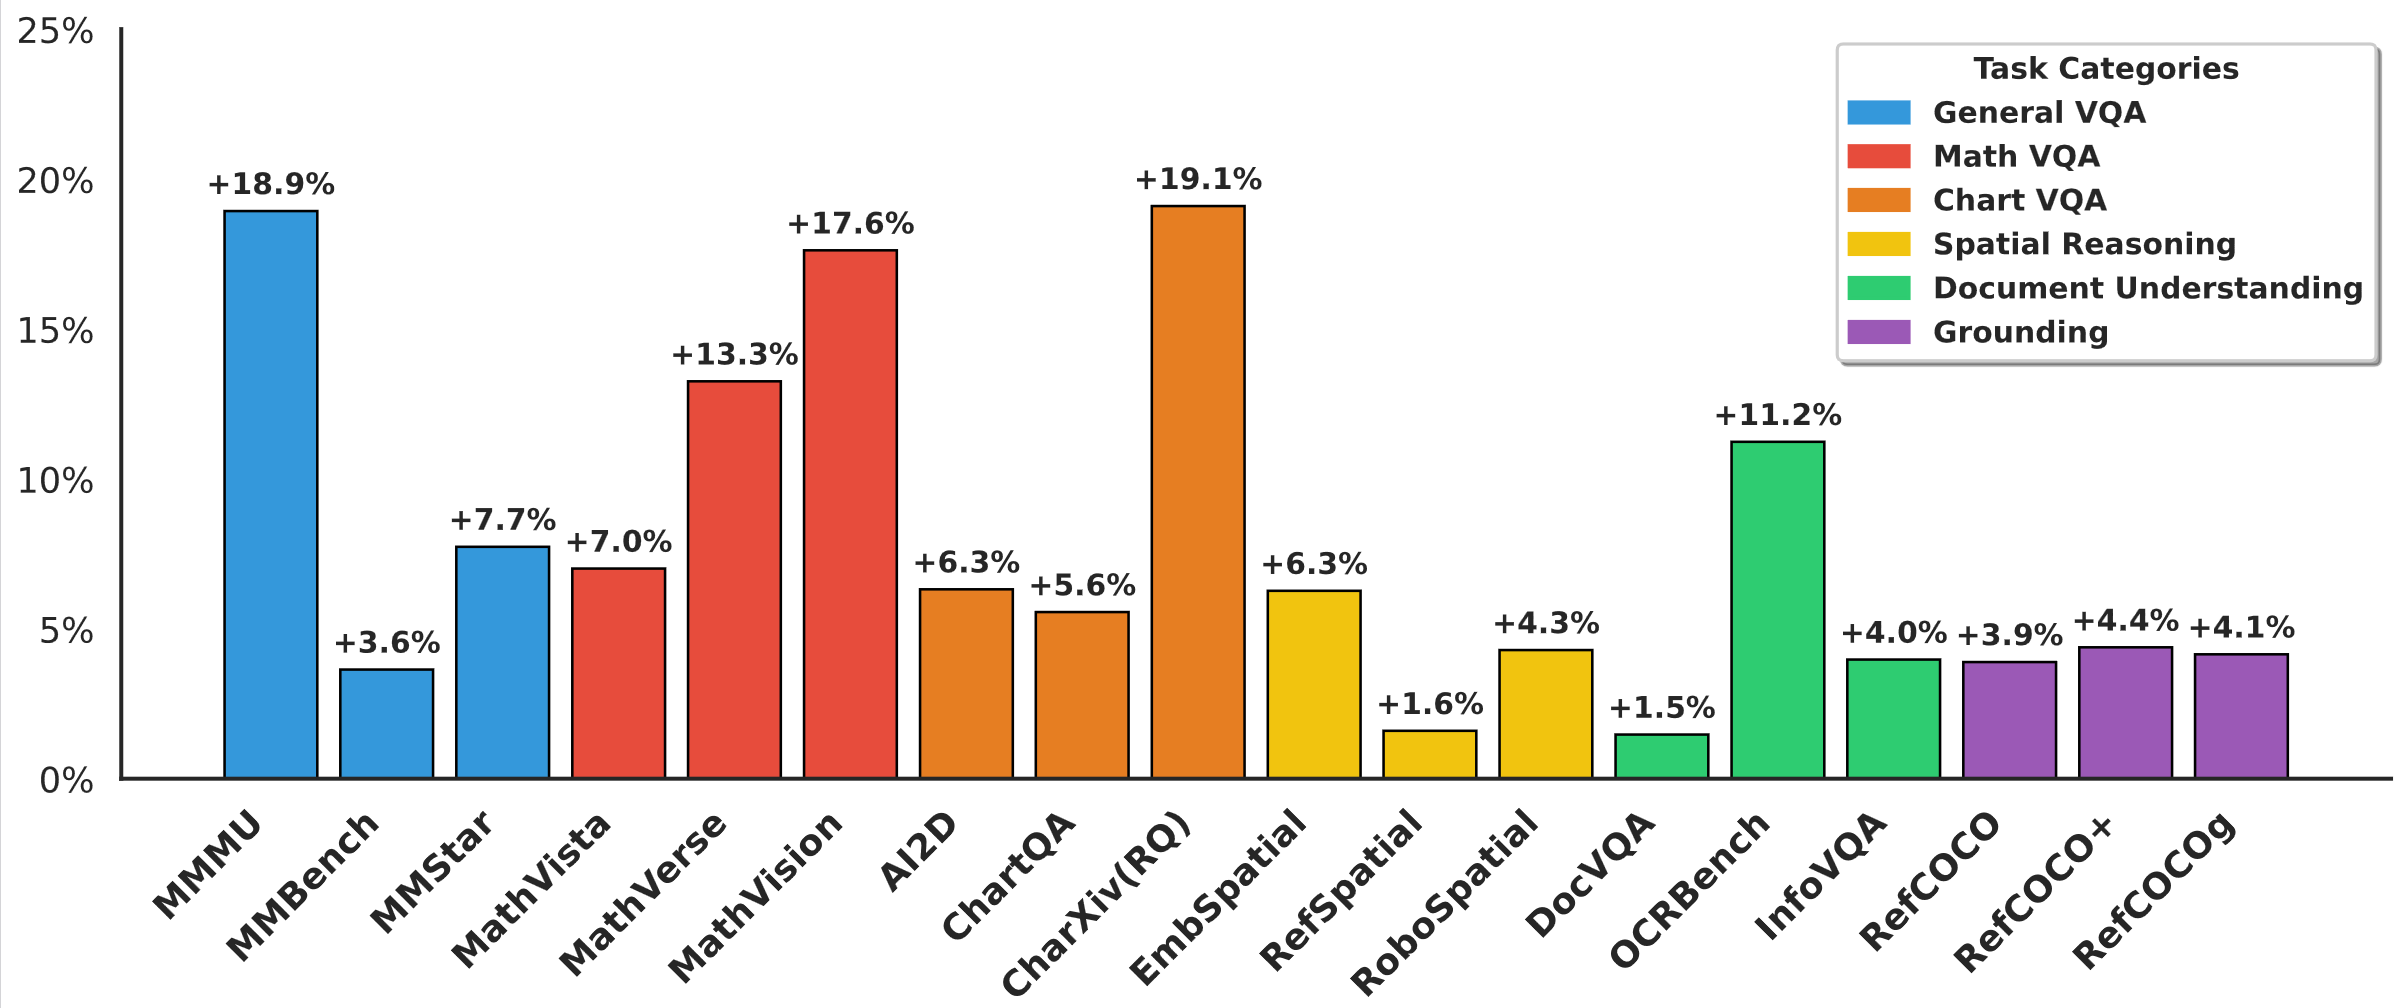
Our model obtains significant performance gains after training on the baseline Qwen3-VL-Instruct-8B across diverse visual tasks. For instance, OpenVLThinkerV2 achieves $71.6%$ on MMMU and $79.5%$ on MathVista, surpassing GPT-4o by a significant margin. Furthermore, across six distinct benchmarks evaluating document understanding and spatial reasoning, OpenVLThinkerV2 significantly outperforms proprietary frontier models, including GPT-5 and Gemini 2.5 Pro.
📢 News
- [Coming!] 📝 We will release the checkpoint of OpenVLThinkerV2 after the model trained with Cold-Start SFT. Our current results can be achieved by directly RL from Qwen3-VL-8B. Stay tuned for our stronger version!
- [2026-04-10] 🔥 We release the example training and validation data in the data folder.
- [2026-04-10] 🔥 We release the training and evaluation code.
- [2026-04-10] 🔥 We release the paper of OpenVLThinkerV2.
📐 Set up
git clone https://github.com/uclanlp/OpenVLThinker.git
cd OpenVLThinker
conda create -n easyr1 python=3.11
conda activate easyr1
cd EasyR1
pip install -e .
For more details for the RL environment installation, please refer to EasyR1.
🚀 Training
bash ./EasyR1/local_scripts/run_g2rpo_rl_slurm.sh
We provide example training and validation sample data here. The original images in training data can be found in this work.
Furthermore, our training process supports multi-task validation with separate scores for each task. To add more validation dataset for various tasks, please add them here and update your task keys in this file.
For RL training code on AWS Trainium instances, please refer to our specific example repo.
🔮 Inference & Evaluation
Since OpenVLThinkerV2 shares the same architecture as Qwen3-VL-8B, it naturally supports easy and efficient inference.
We adopt VLMEvalKit for most of our evaluation. For grounding task, we follow evaluation scripts in OneThinker. Please follow them for specific evaluation setups.
VeRL G2RPO Implementation
Please refer to the core_algos.py
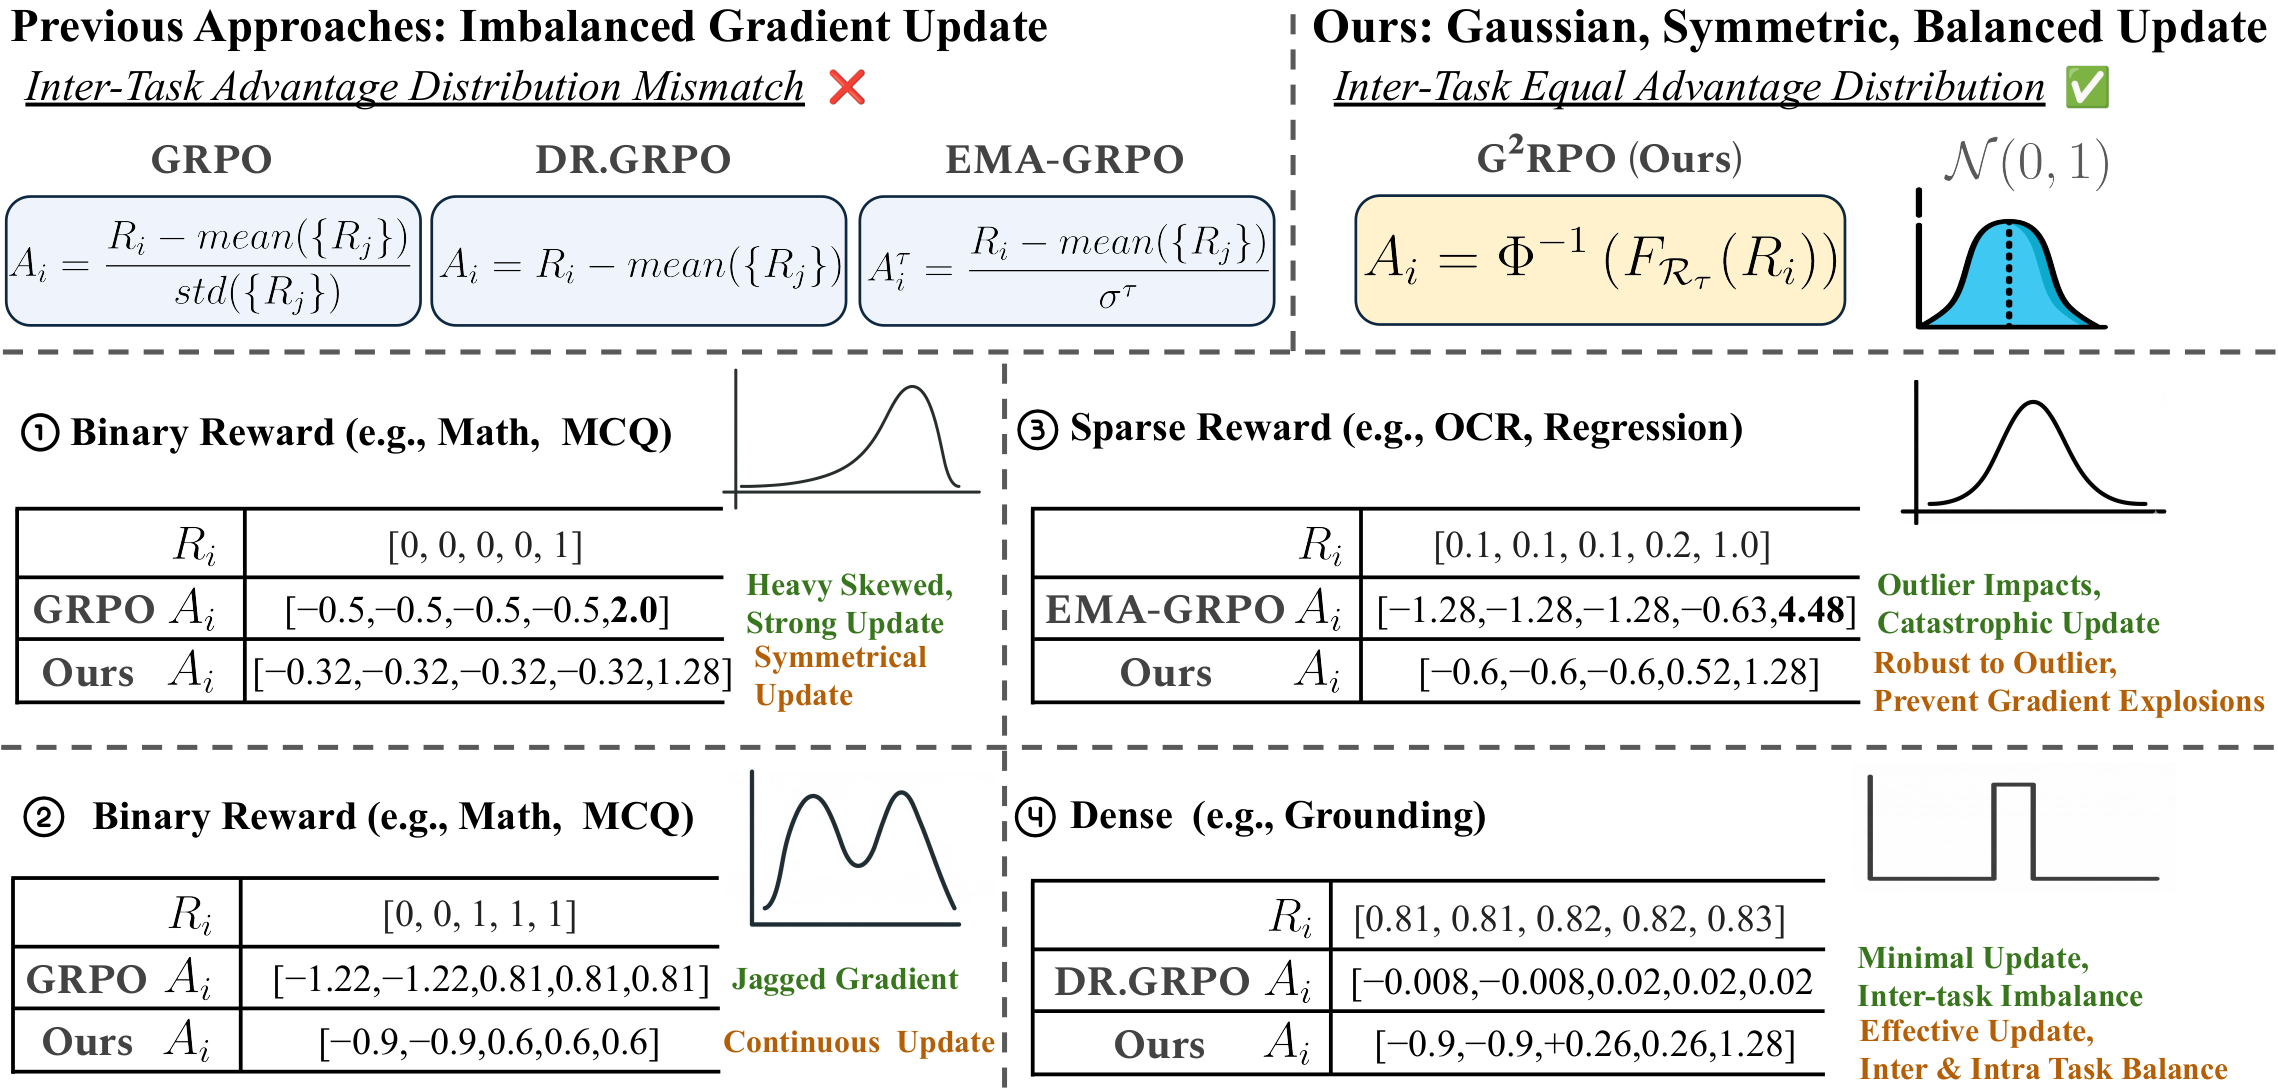
@register_adv_estimator(AdvantageEstimator.GS_GRPO)
def compute_pertask_gaussian_outcome_advantage_grpo
We also support our Gaussian Advantage Normalization method in GDPO, please see Gaussian (GS) GDPO:
@register_adv_estimator(AdvantageEstimator.GS_GDPO)
def compute_pertask_gaussian_outcome_advantage_gdpo
These can be changed at the config file.
🔗 Citation
If you find our work helpful for your research, please consider citing our work.
@article{hu2026openvlthinkerv2generalistmultimodalreasoning,
      title={OpenVLThinkerV2: A Generalist Multimodal Reasoning Model for Multi-domain Visual Tasks},
      author={Wenbo Hu and Xin Chen and Yan Gao-Tian and Yihe Deng and Nanyun Peng and Kai-Wei Chang},
      year={2026},
      journal={arXiv preprint arXiv:2604.08539},
      url={https://arxiv.org/abs/2604.08539},
}
📄 License
OpenVLThinkerV2 is licensed under the Apache 2.0.
👏 Acknowledgements
We sincerely appreciate the contributions of the open-source community. The related projects are as follows: EasyR1, verl, VLMEvalKit, OneThinker.
Contributors

28 commits

8 commits
Similar repos


Languages
Python
99.0%
OpenVLThinker [NeurIPS 2025] & OpenVLThinkerV2 [COLM 2026]
Python
157
36 commits
updated May 25, 2026
README
OpenVLThinkerV2: A Generalist Multimodal Reasoning Model for Multi-domain Visual Tasks
Wenbo Hu, Xin Chen, Yan Gao-Tian, Yihe Deng, Nanyun Peng, Kai-Wei Chang
📑 Paper | 📖 arXiv | 🌐 Homepage | 🤗 Model (Coming) 🤗 HF Daily Paper
🏠 About
🏆 Performance
Our model obtains significant performance gains after training on the baseline Qwen3-VL-Instruct-8B across diverse visual tasks. For instance, OpenVLThinkerV2 achieves $71.6%$ on MMMU and $79.5%$ on MathVista, surpassing GPT-4o by a significant margin. Furthermore, across six distinct benchmarks evaluating document understanding and spatial reasoning, OpenVLThinkerV2 significantly outperforms proprietary frontier models, including GPT-5 and Gemini 2.5 Pro.
📢 News
- [Coming!] 📝 We will release the checkpoint of OpenVLThinkerV2 after the model trained with Cold-Start SFT. Our current results can be achieved by directly RL from Qwen3-VL-8B. Stay tuned for our stronger version!
- [2026-04-10] 🔥 We release the example training and validation data in the data folder.
- [2026-04-10] 🔥 We release the training and evaluation code.
- [2026-04-10] 🔥 We release the paper of OpenVLThinkerV2.
📐 Set up
git clone https://github.com/uclanlp/OpenVLThinker.git
cd OpenVLThinker
conda create -n easyr1 python=3.11
conda activate easyr1
cd EasyR1
pip install -e .
For more details for the RL environment installation, please refer to EasyR1.
🚀 Training
bash ./EasyR1/local_scripts/run_g2rpo_rl_slurm.sh
We provide example training and validation sample data here. The original images in training data can be found in this work.
Furthermore, our training process supports multi-task validation with separate scores for each task. To add more validation dataset for various tasks, please add them here and update your task keys in this file.
For RL training code on AWS Trainium instances, please refer to our specific example repo.
🔮 Inference & Evaluation
Since OpenVLThinkerV2 shares the same architecture as Qwen3-VL-8B, it naturally supports easy and efficient inference.
We adopt VLMEvalKit for most of our evaluation. For grounding task, we follow evaluation scripts in OneThinker. Please follow them for specific evaluation setups.
VeRL G2RPO Implementation
Please refer to the core_algos.py
@register_adv_estimator(AdvantageEstimator.GS_GRPO)
def compute_pertask_gaussian_outcome_advantage_grpo
We also support our Gaussian Advantage Normalization method in GDPO, please see Gaussian (GS) GDPO:
@register_adv_estimator(AdvantageEstimator.GS_GDPO)
def compute_pertask_gaussian_outcome_advantage_gdpo
These can be changed at the config file.
🔗 Citation
If you find our work helpful for your research, please consider citing our work.
@article{hu2026openvlthinkerv2generalistmultimodalreasoning,
      title={OpenVLThinkerV2: A Generalist Multimodal Reasoning Model for Multi-domain Visual Tasks},
      author={Wenbo Hu and Xin Chen and Yan Gao-Tian and Yihe Deng and Nanyun Peng and Kai-Wei Chang},
      year={2026},
      journal={arXiv preprint arXiv:2604.08539},
      url={https://arxiv.org/abs/2604.08539},
}
📄 License
OpenVLThinkerV2 is licensed under the Apache 2.0.
👏 Acknowledgements
We sincerely appreciate the contributions of the open-source community. The related projects are as follows: EasyR1, verl, VLMEvalKit, OneThinker.
Similar repos
Contributors
28 commits
8 commits
Languages
Python
99.0%