Complete solutions to the Programming Massively Parallel Processors Edition 4
Jupyter Notebook
905
176 commits
updated Sep 7, 2026
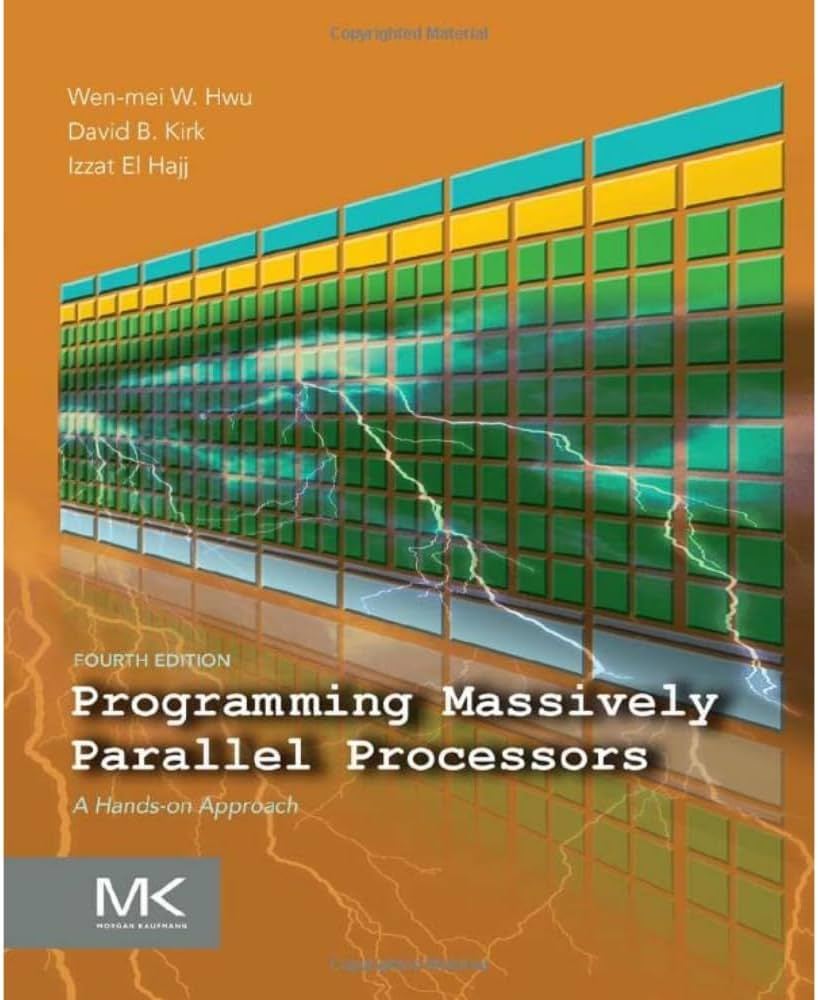
Complete solutions to Kirk & Hwu's Programming Massively Parallel Processors (4th Edition)
Theoretical explanations + Working implementations + Performance analysis
This repository contains comprehensive solutions to all exercises in Programming Massively Parallel Processors by David Kirk and Wen-mei Hwu (4th Edition). Each chapter includes:
Each chapter follows this structure:
├── code/
│   ├── *.cu          # CUDA implementations
│   ├── *.py          # Python alternatives
│   ├── Makefile      # Build configuration
│   └── ...
└── README.md         # Theory + Exercises + Solutions
| Chapter | Topic | Focus Areas |
|---|---|---|
| Chapter 2 | Heterogeneous Data Parallel Computing | Vector operations, thread mapping, CUDA basics |
| Chapter 3 | Multidimensional Grids and Data | Grid organization, thread hierarchy |
| Chapter 4 | Compute Architecture and Scheduling | GPU architecture, warps, occupancy |
| Chapter 5 | Memory Architecture and Data Locality | Memory types, tiling, bandwidth optimization |
| Chapter 6 | Performance Considerations | Memory coalescing, latency hiding |
| Chapter 7 | Convolution | Constant memory, caching, halo cells |
| Chapter 8 | Stencil | 2D/3D stencil computations, register tiling |
| Chapter 9 | Parallel Histogram | Atomic operations, privatization, aggregation |
| Chapter 10 | Reduction | Tree reduction, divergence minimization |
| Chapter 11 | Prefix Sum (Scan) | Work-efficient algorithms, Kogge-Stone, Brent-Kung |
| Chapter 12 | Merge | Co-rank function, circular buffers |
| Chapter 13 | Sorting | Radix sort, merge sort optimization |
| Chapter 14 | Sparse Matrix Computation | SpMV, CSR/ELL/COO formats |
| Chapter 15 | Graph Traversal | BFS algorithms, frontier-based approaches |
| Chapter 16 | Deep Learning | CNN implementation, GEMM formulation |
| Chapter 17 | Iterative MRI Reconstruction | Medical imaging algorithms |
| Chapter 18 | Electrostatic Potential Map | Scatter vs gather, cutoff binning |
| Chapter 19 | Parallel Programming and Computational Thinking | Algorithm selection, problem decomposition |
| Chapter 20 | Heterogeneous Computing Cluster | CUDA streams, MPI integration |
| Chapter 21 | CUDA Dynamic Parallelism | Recursive algorithms, quadtrees |
# Clone the repository
git clone <repository-url>
cd pmpp

# For Python examples (optional)
conda create -n pmpp python=3.11
conda activate pmpp
pip install -r requirements.txt
CUDA/C Examples:
cd chapter-XX/code
make
./program_name
Python Examples:
cd chapter-XX/code
python script_name.py
Found an error? Please open an issue using this template:
Describe the bug
Describe where the problem is and what precisely is wrong.
Proposed solution
Here paste your proposed solution. Please include the reasoning behind why you believe your solution is correct.
This project is licensed under the MIT License - see the LICENSE file for details.
763 followers · starred Aug 2025
761 followers · starred Jul 2025
682 followers · starred Jul 2025
47 followers · starred Jul 2025
Complete solutions to the Programming Massively Parallel Processors Edition 4
Jupyter Notebook
905
176 commits
updated Sep 7, 2026
Complete solutions to Kirk & Hwu's Programming Massively Parallel Processors (4th Edition)
Theoretical explanations + Working implementations + Performance analysis
This repository contains comprehensive solutions to all exercises in Programming Massively Parallel Processors by David Kirk and Wen-mei Hwu (4th Edition). Each chapter includes:
Each chapter follows this structure:
├── code/
│   ├── *.cu          # CUDA implementations
│   ├── *.py          # Python alternatives
│   ├── Makefile      # Build configuration
│   └── ...
└── README.md         # Theory + Exercises + Solutions
| Chapter | Topic | Focus Areas |
|---|---|---|
| Chapter 2 | Heterogeneous Data Parallel Computing | Vector operations, thread mapping, CUDA basics |
| Chapter 3 | Multidimensional Grids and Data | Grid organization, thread hierarchy |
| Chapter 4 | Compute Architecture and Scheduling | GPU architecture, warps, occupancy |
| Chapter 5 | Memory Architecture and Data Locality | Memory types, tiling, bandwidth optimization |
| Chapter 6 | Performance Considerations | Memory coalescing, latency hiding |
| Chapter 7 | Convolution | Constant memory, caching, halo cells |
| Chapter 8 | Stencil | 2D/3D stencil computations, register tiling |
| Chapter 9 | Parallel Histogram | Atomic operations, privatization, aggregation |
| Chapter 10 | Reduction | Tree reduction, divergence minimization |
| Chapter 11 | Prefix Sum (Scan) | Work-efficient algorithms, Kogge-Stone, Brent-Kung |
| Chapter 12 | Merge | Co-rank function, circular buffers |
| Chapter 13 | Sorting | Radix sort, merge sort optimization |
| Chapter 14 | Sparse Matrix Computation | SpMV, CSR/ELL/COO formats |
| Chapter 15 | Graph Traversal | BFS algorithms, frontier-based approaches |
| Chapter 16 | Deep Learning | CNN implementation, GEMM formulation |
| Chapter 17 | Iterative MRI Reconstruction | Medical imaging algorithms |
| Chapter 18 | Electrostatic Potential Map | Scatter vs gather, cutoff binning |
| Chapter 19 | Parallel Programming and Computational Thinking | Algorithm selection, problem decomposition |
| Chapter 20 | Heterogeneous Computing Cluster | CUDA streams, MPI integration |
| Chapter 21 | CUDA Dynamic Parallelism | Recursive algorithms, quadtrees |
# Clone the repository
git clone <repository-url>
cd pmpp

# For Python examples (optional)
conda create -n pmpp python=3.11
conda activate pmpp
pip install -r requirements.txt
CUDA/C Examples:
cd chapter-XX/code
make
./program_name
Python Examples:
cd chapter-XX/code
python script_name.py
Found an error? Please open an issue using this template:
Describe the bug
Describe where the problem is and what precisely is wrong.
Proposed solution
Here paste your proposed solution. Please include the reasoning behind why you believe your solution is correct.
This project is licensed under the MIT License - see the LICENSE file for details.
763 followers · starred Aug 2025
761 followers · starred Jul 2025
682 followers · starred Jul 2025
47 followers · starred Jul 2025