The lightest Vietnamese Text-to-Speech with Multi-Speaker TTS and Zero-Shot Voice Cloning.
Python
383
22 commits
updated Jul 23, 2026
Vietnamese Text-to-Speech with Multi-Speaker TTS and Zero-Shot Voice Cloning.
The lightest Vietnamese zero-shot voice cloning model — only 74.8M parameters, runs entirely on CPU, 3-4x faster than realtime. No GPU required.
📅 Cập nhật: Tháng 4/2026 — Đã phát hành phiên bản Windows App (.exe), không cần cài đặt Python hay chạy source code phức tạp!
Dành cho người dùng Windows — Tải file
.exe, chạy trực tiếp, không cần cài đặt Python, không lo lỗi source code!
| Phiên bản | Hệ điều hành | Download |
|---|---|---|
| v1.0.5 (Mới nhất) | Windows 10/11 (64-bit) | 📥 Tải VTTS.exe (394MB) |
.exe.txt/.srt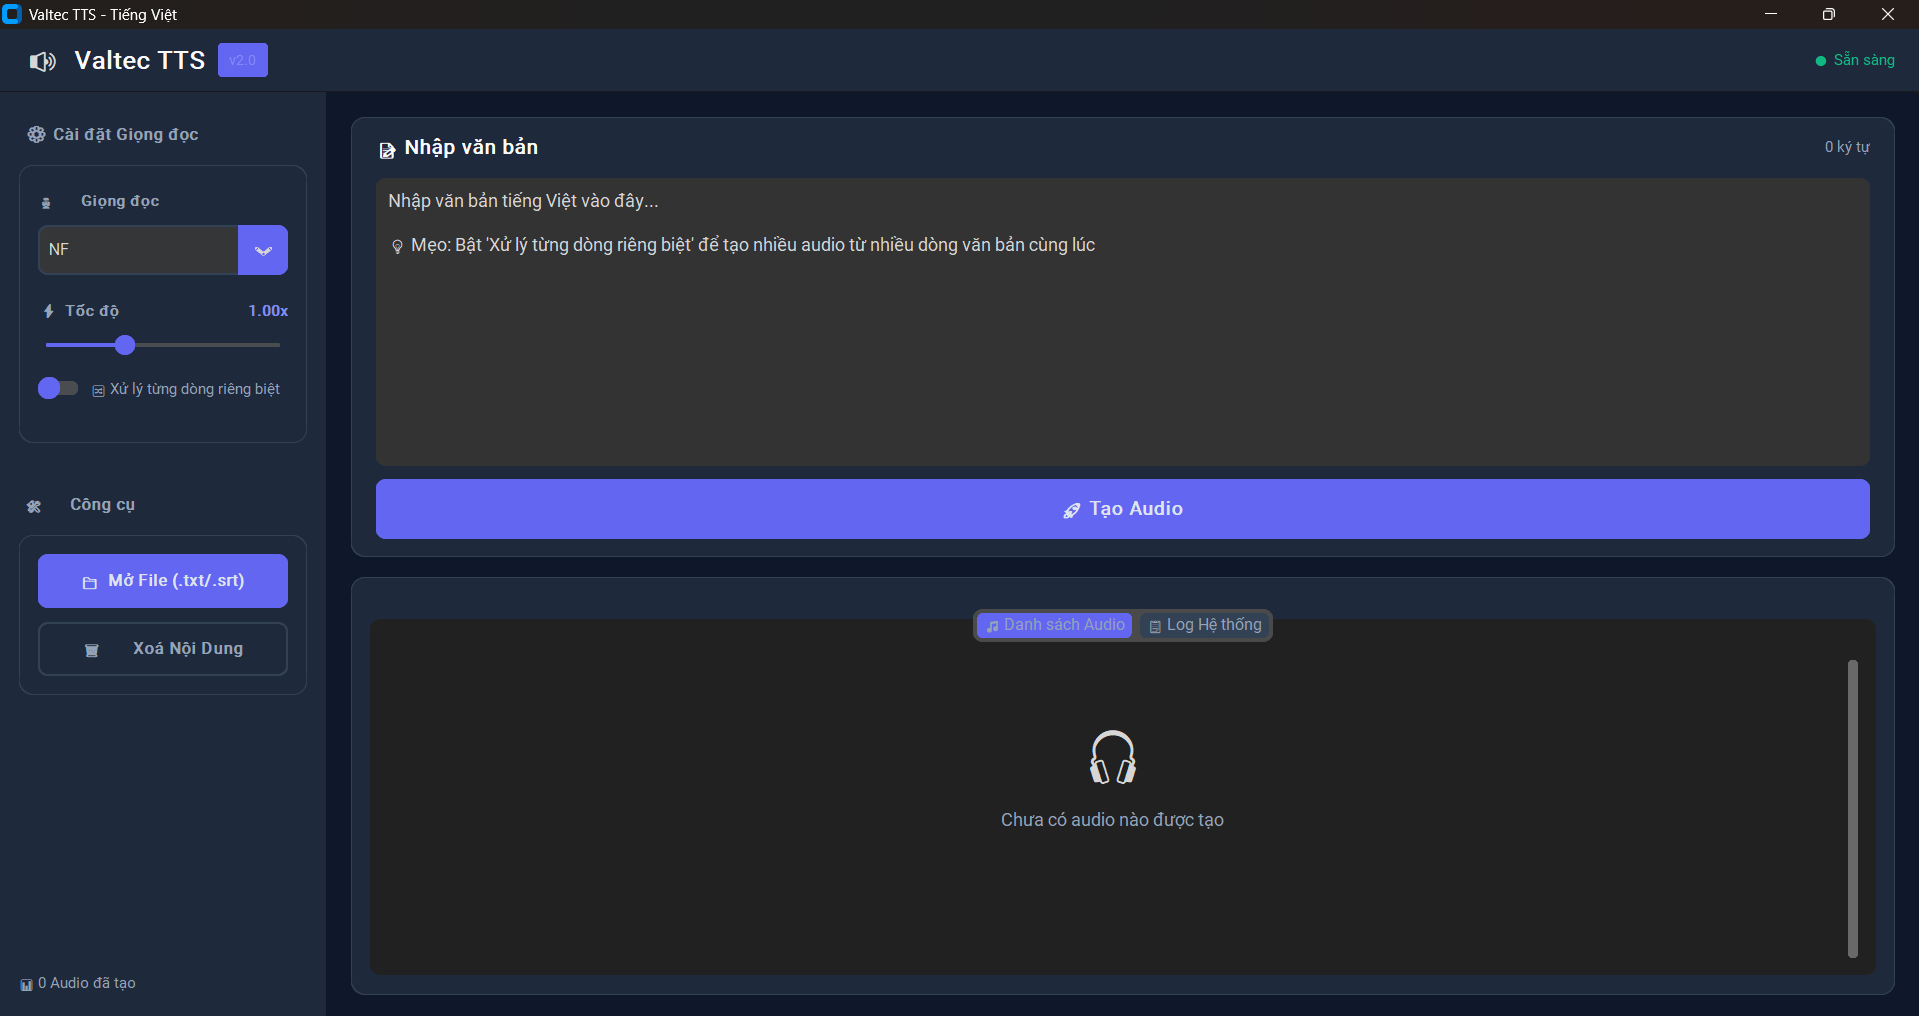
VTTS.exe từ Releases.exe (lần đầu sẽ tự tải model từ HuggingFace — cần kết nối Internet).wavLưu ý: File
.execó dung lượng ~394MB do đã bao gồm toàn bộ PyTorch và dependencies. Lần chạy đầu tiên sẽ tải model (~100MB) từ HuggingFace.
Dành cho mọi hệ điều hành — Chạy trong Docker, không cần cài đặt Python, cách ly hoàn toàn!
Cách 1: Dùng docker-compose (Khuyến nghị)
git clone https://github.com/tronghieuit/v-tts.git
cd v-tts
docker-compose up -d
Cách 2: Dùng Docker trực tiếp
docker build -t v-tts .
docker run -d -p 7860:7860 --name v-tts v-tts
Mở trình duyệt: http://localhost:7860
Lưu ý: Docker image ~2-3GB do bao gồm PyTorch và dependencies. Lần chạy đầu tiên sẽ tải model từ HuggingFace.
pip install and use with 2 lines of code| Demo | Link |
|---|---|
| 🎙️ Zero-Shot Voice Cloning | ▶️ huggingface.co/spaces/v-tts/v-zeroshot-voice-cloning |
| 🔊 Multi-Speaker TTS | ▶️ huggingface.co/spaces/v-tts/v-vietnamese-tts |
Clone any voice from 3-10 seconds of audio. No GPU required. Try it directly in your browser!
Same text, cloned with 6 different reference voices:
| Reference Voice | Description | Cloned Audio |
|---|---|---|
| Thu Hà | Soft female voice | ▶️ example_thu_ha.wav |
| Minh Đức | Deep male voice | ▶️ example_minh_duc.wav |
| Thanh Tâm | Young female voice | ▶️ example_thanh_tam.wav |
| Quang Huy | Young male voice | ▶️ example_quang_huy.wav |
| Ngọc Ánh | Professional female | ▶️ example_ngoc_anh.wav |
| Hoàng Nam | Strong male voice | ▶️ example_hoang_nam.wav |
| Speaker | Region | Gender | Audio |
|---|---|---|---|
| NF | Northern | Female | ▶️ example_NF.wav |
| SF | Southern | Female | ▶️ example_SF.wav |
| NM1 | Northern | Male | ▶️ example_NM1.wav |
| SM | Southern | Male | ▶️ example_SM.wav |
| NM2 | Northern | Male | ▶️ example_NM2.wav |
Clone the repo and listen to files in
examples/for the best audio quality.
| Component | Parameters | Purpose |
|---|---|---|
| Synthesizer | 56.45M | Voice synthesis |
| Speaker Encoder | 8.03M | Voice identity extraction |
| Style Encoder | 7.80M | Prosody/style extraction |
| Prosody Predictor | 2.52M | F0/energy prediction |
| Total | 74.80M | ~285 MB (FP32) |
Runs entirely on CPU — no GPU needed!
| Input Length | Inference Time | Audio Length | RTF | Speed |
|---|---|---|---|---|
| Short (16 chars) | 506ms | 1.07s | 0.475 | 2.1x realtime |
| Medium (60 chars) | 1,030ms | 3.61s | 0.286 | 3.5x realtime |
| Long (156 chars) | 2,229ms | 9.45s | 0.236 | 4.2x realtime |
| Mode | Short | Medium | Long |
|---|---|---|---|
| CPU (i5-14500) | 392ms / RTF 0.54 | 854ms / RTF 0.38 | 1,653ms / RTF 0.34 |
| CUDA (RTX 4060 Ti) | 45ms / RTF 0.06 | 52ms / RTF 0.02 | 69ms / RTF 0.01 |
RTF (Real-Time Factor): Processing time / audio duration. RTF < 1 = faster than realtime.
# From Git
pip install git+https://github.com/tronghieuit/v-tts.git

# From Source
git clone https://github.com/tronghieuit/v-tts.git
cd v-tts
pip install -e .
from v_tts import TTS

tts = TTS()  # Auto-downloads model from Hugging Face
tts.speak("Xin chào các bạn", speaker="NF", output_path="hello.wav")

# Get audio array
audio, sr = tts.synthesize("Xin chào các bạn", speaker="NM1")

# Available speakers: NF, SF, NM1, SM, NM2
print(tts.list_speakers())
from v_tts import ZeroShotTTS

tts = ZeroShotTTS()  # Auto-downloads model, CPU by default
tts.clone_voice(
    text="Xin chào, tôi là giọng nói được nhân bản",
    reference_audio="your_voice.wav",
    output_path="output.wav"
)

# Or get audio array
audio, sr = tts.synthesize(
    text="Đây là văn bản tiếng Việt",
    reference_audio="references/thu_ha.wav"
)
# Zero-shot voice cloning
python infer_zeroshot.py \
  --reference references/thu_ha.wav \
  --text "Buổi sáng ở thành phố bắt đầu bằng những âm thanh quen thuộc" \
  --output cloned_voice.wav

# Use your own voice
python infer_zeroshot.py \
  --reference your_voice.wav \
  --text "Văn bản tiếng Việt của bạn" \
  --output output.wav --cpu

# Multi-speaker TTS
python infer.py --text "Xin chào các bạn" --speaker NF --output hello.wav
python infer.py --interactive
# Zero-shot voice cloning demo
python app_zeroshot.py
# Open: http://localhost:7860

# Multi-speaker TTS demo
python app.py
Reference Audio
    ├─→ Speaker Encoder → Speaker Embedding (512-dim)
    └─→ Mel Extraction → Style Encoder → Prosody Embedding (128-dim)

Input Text → Vietnamese Phonemizer → Text Encoder → Text Representation

[Speaker Emb + Prosody Emb + Text Repr] → Voice Generator → Output Audio
For best results:
| ✅ Good | ❌ Bad |
|---|---|
| 3-10 seconds duration | < 2s (poor representation) |
| Clean, clear speech | Noisy background |
| Single speaker | Multiple speakers |
| Neutral emotion | Extreme emotion/shouting |
| Any language | Music or sound effects |
# Prepare reference audio
ffmpeg -i full_audio.wav -ss 00:00:10 -t 5 -ar 24000 reference.wav
ffmpeg -i input.mp3 -ar 24000 -ac 1 reference.wav
Available in references/:
| Voice | File | Description |
|---|---|---|
| Thu Hà | thu_ha.wav | Soft, warm female voice |
| Minh Đức | minh_duc.wav | Deep, composed male voice |
| Thanh Tâm | thanh_tam.wav | Young, bright female voice |
| Quang Huy | quang_huy.wav | Young, energetic male voice |
| Ngọc Ánh | ngoc_anh.wav | Professional female anchor |
| Hoàng Nam | hoang_nam.wav | Strong, deep male voice |
Upload your own reference audio (3-10 seconds, clear speech) to clone any voice.
# Blend two voices
spk_emb_1 = tts.extract_embeddings("voice_1.wav")[0]
spk_emb_2 = tts.extract_embeddings("voice_2.wav")[0]

alpha = 0.5  # 50-50 blend
spk_emb_mixed = alpha * spk_emb_1 + (1 - alpha) * spk_emb_2
| Speaker | Region | Gender | Code |
|---|---|---|---|
| NF | Northern (Miền Bắc) | Female | NF |
| SF | Southern (Miền Nam) | Female | SF |
| NM1 | Northern (Miền Bắc) | Male | NM1 |
| SM | Southern (Miền Nam) | Male | SM |
| NM2 | Northern (Miền Bắc) | Male | NM2 |
| Parameter | Default | Description |
|---|---|---|
speed | 1.0 | < 1.0 = faster, > 1.0 = slower |
noise_scale | 0.667 | Voice variability |
noise_scale_w | 0.8 | Duration variability |
sdp_ratio | 0.0 | 0 = deterministic, 1 = stochastic |
Models are automatically downloaded from Hugging Face and cached:
%LOCALAPPDATA%\v_tts\models\~/.cache/v_tts/models/v-tts/
├── v_tts/ # pip install package
│ ├── tts.py # Multi-speaker TTS API
│ └── zeroshot.py # Zero-shot voice cloning API
├── src/
│ ├── models/ # All model architectures
│ │ ├── synthesizer_zeroshot.py # Zero-shot synthesizer
│ │ ├── synthesizer.py # Multi-speaker synthesizer
│ │ ├── encoders.py # Speaker/Style/Prosody encoders
│ │ └── adain.py # Style conditioning module
│ ├── nn/ # Neural network components + mel processing
│ ├── text/ # Text/phoneme processing
│ └── vietnamese/ # Vietnamese text normalization + phonemizer
├── pretrained/
│ ├── zeroshot/ # Zero-shot checkpoint + config
│ ├── hasp/ # Speaker encoder weights
│ ├── onnx/ # ONNX export models
│ └── config.json # Multi-speaker config
├── references/ # 6 reference voices for zero-shot
├── examples/
│ ├── zeroshot/ # Zero-shot cloned audio samples
│ └── *.wav # Multi-speaker audio samples
├── deployments/ # Edge / Web / Android deployments
├── infer_zeroshot.py # Zero-shot CLI inference
├── infer.py # Multi-speaker CLI inference
├── app_zeroshot.py # Gradio demo (zero-shot)
└── app.py # Gradio demo (multi-speaker)
| Platform | Technology | Size | Offline |
|---|---|---|---|
| HuggingFace Spaces | Gradio | Cloud | No |
| Edge | ONNX Runtime | ~165MB | Yes |
| Web | ONNX Runtime Web | ~165MB | Yes |
| Android | ONNX Runtime Mobile | ~185MB | Yes |
See deployments/ for detailed guides.
@software{v_tts,
  title = {V-TTS with Zero-Shot Voice Cloning},
  author = {V-TTS},
  year = {2026},
  url = {https://github.com/tronghieuit/v-tts}
}
CC BY-NC 4.0 — Non-commercial use only. Commercial use requires written permission.
340 followers · starred Apr 2026
927 followers · starred Jun 2026
The lightest Vietnamese Text-to-Speech with Multi-Speaker TTS and Zero-Shot Voice Cloning.
Python
383
22 commits
updated Jul 23, 2026
Vietnamese Text-to-Speech with Multi-Speaker TTS and Zero-Shot Voice Cloning.
The lightest Vietnamese zero-shot voice cloning model — only 74.8M parameters, runs entirely on CPU, 3-4x faster than realtime. No GPU required.
📅 Cập nhật: Tháng 4/2026 — Đã phát hành phiên bản Windows App (.exe), không cần cài đặt Python hay chạy source code phức tạp!
Dành cho người dùng Windows — Tải file
.exe, chạy trực tiếp, không cần cài đặt Python, không lo lỗi source code!
| Phiên bản | Hệ điều hành | Download |
|---|---|---|
| v1.0.5 (Mới nhất) | Windows 10/11 (64-bit) | 📥 Tải VTTS.exe (394MB) |
.exe.txt/.srt
VTTS.exe từ Releases.exe (lần đầu sẽ tự tải model từ HuggingFace — cần kết nối Internet).wavLưu ý: File
.execó dung lượng ~394MB do đã bao gồm toàn bộ PyTorch và dependencies. Lần chạy đầu tiên sẽ tải model (~100MB) từ HuggingFace.
Dành cho mọi hệ điều hành — Chạy trong Docker, không cần cài đặt Python, cách ly hoàn toàn!
Cách 1: Dùng docker-compose (Khuyến nghị)
git clone https://github.com/tronghieuit/v-tts.git
cd v-tts
docker-compose up -d
Cách 2: Dùng Docker trực tiếp
docker build -t v-tts .
docker run -d -p 7860:7860 --name v-tts v-tts
Mở trình duyệt: http://localhost:7860
Lưu ý: Docker image ~2-3GB do bao gồm PyTorch và dependencies. Lần chạy đầu tiên sẽ tải model từ HuggingFace.
pip install and use with 2 lines of code| Demo | Link |
|---|---|
| 🎙️ Zero-Shot Voice Cloning | ▶️ huggingface.co/spaces/v-tts/v-zeroshot-voice-cloning |
| 🔊 Multi-Speaker TTS | ▶️ huggingface.co/spaces/v-tts/v-vietnamese-tts |
Clone any voice from 3-10 seconds of audio. No GPU required. Try it directly in your browser!
Same text, cloned with 6 different reference voices:
| Reference Voice | Description | Cloned Audio |
|---|---|---|
| Thu Hà | Soft female voice | ▶️ example_thu_ha.wav |
| Minh Đức | Deep male voice | ▶️ example_minh_duc.wav |
| Thanh Tâm | Young female voice | ▶️ example_thanh_tam.wav |
| Quang Huy | Young male voice | ▶️ example_quang_huy.wav |
| Ngọc Ánh | Professional female | ▶️ example_ngoc_anh.wav |
| Hoàng Nam | Strong male voice | ▶️ example_hoang_nam.wav |
| Speaker | Region | Gender | Audio |
|---|---|---|---|
| NF | Northern | Female | ▶️ example_NF.wav |
| SF | Southern | Female | ▶️ example_SF.wav |
| NM1 | Northern | Male | ▶️ example_NM1.wav |
| SM | Southern | Male | ▶️ example_SM.wav |
| NM2 | Northern | Male | ▶️ example_NM2.wav |
Clone the repo and listen to files in
examples/for the best audio quality.
| Component | Parameters | Purpose |
|---|---|---|
| Synthesizer | 56.45M | Voice synthesis |
| Speaker Encoder | 8.03M | Voice identity extraction |
| Style Encoder | 7.80M | Prosody/style extraction |
| Prosody Predictor | 2.52M | F0/energy prediction |
| Total | 74.80M | ~285 MB (FP32) |
Runs entirely on CPU — no GPU needed!
| Input Length | Inference Time | Audio Length | RTF | Speed |
|---|---|---|---|---|
| Short (16 chars) | 506ms | 1.07s | 0.475 | 2.1x realtime |
| Medium (60 chars) | 1,030ms | 3.61s | 0.286 | 3.5x realtime |
| Long (156 chars) | 2,229ms | 9.45s | 0.236 | 4.2x realtime |
| Mode | Short | Medium | Long |
|---|---|---|---|
| CPU (i5-14500) | 392ms / RTF 0.54 | 854ms / RTF 0.38 | 1,653ms / RTF 0.34 |
| CUDA (RTX 4060 Ti) | 45ms / RTF 0.06 | 52ms / RTF 0.02 | 69ms / RTF 0.01 |
RTF (Real-Time Factor): Processing time / audio duration. RTF < 1 = faster than realtime.
# From Git
pip install git+https://github.com/tronghieuit/v-tts.git

# From Source
git clone https://github.com/tronghieuit/v-tts.git
cd v-tts
pip install -e .
from v_tts import TTS

tts = TTS()  # Auto-downloads model from Hugging Face
tts.speak("Xin chào các bạn", speaker="NF", output_path="hello.wav")

# Get audio array
audio, sr = tts.synthesize("Xin chào các bạn", speaker="NM1")

# Available speakers: NF, SF, NM1, SM, NM2
print(tts.list_speakers())
from v_tts import ZeroShotTTS

tts = ZeroShotTTS()  # Auto-downloads model, CPU by default
tts.clone_voice(
    text="Xin chào, tôi là giọng nói được nhân bản",
    reference_audio="your_voice.wav",
    output_path="output.wav"
)

# Or get audio array
audio, sr = tts.synthesize(
    text="Đây là văn bản tiếng Việt",
    reference_audio="references/thu_ha.wav"
)
# Zero-shot voice cloning
python infer_zeroshot.py \
  --reference references/thu_ha.wav \
  --text "Buổi sáng ở thành phố bắt đầu bằng những âm thanh quen thuộc" \
  --output cloned_voice.wav

# Use your own voice
python infer_zeroshot.py \
  --reference your_voice.wav \
  --text "Văn bản tiếng Việt của bạn" \
  --output output.wav --cpu

# Multi-speaker TTS
python infer.py --text "Xin chào các bạn" --speaker NF --output hello.wav
python infer.py --interactive
# Zero-shot voice cloning demo
python app_zeroshot.py
# Open: http://localhost:7860

# Multi-speaker TTS demo
python app.py
Reference Audio
    ├─→ Speaker Encoder → Speaker Embedding (512-dim)
    └─→ Mel Extraction → Style Encoder → Prosody Embedding (128-dim)

Input Text → Vietnamese Phonemizer → Text Encoder → Text Representation

[Speaker Emb + Prosody Emb + Text Repr] → Voice Generator → Output Audio
For best results:
| ✅ Good | ❌ Bad |
|---|---|
| 3-10 seconds duration | < 2s (poor representation) |
| Clean, clear speech | Noisy background |
| Single speaker | Multiple speakers |
| Neutral emotion | Extreme emotion/shouting |
| Any language | Music or sound effects |
# Prepare reference audio
ffmpeg -i full_audio.wav -ss 00:00:10 -t 5 -ar 24000 reference.wav
ffmpeg -i input.mp3 -ar 24000 -ac 1 reference.wav
Available in references/:
| Voice | File | Description |
|---|---|---|
| Thu Hà | thu_ha.wav | Soft, warm female voice |
| Minh Đức | minh_duc.wav | Deep, composed male voice |
| Thanh Tâm | thanh_tam.wav | Young, bright female voice |
| Quang Huy | quang_huy.wav | Young, energetic male voice |
| Ngọc Ánh | ngoc_anh.wav | Professional female anchor |
| Hoàng Nam | hoang_nam.wav | Strong, deep male voice |
Upload your own reference audio (3-10 seconds, clear speech) to clone any voice.
# Blend two voices
spk_emb_1 = tts.extract_embeddings("voice_1.wav")[0]
spk_emb_2 = tts.extract_embeddings("voice_2.wav")[0]

alpha = 0.5  # 50-50 blend
spk_emb_mixed = alpha * spk_emb_1 + (1 - alpha) * spk_emb_2
| Speaker | Region | Gender | Code |
|---|---|---|---|
| NF | Northern (Miền Bắc) | Female | NF |
| SF | Southern (Miền Nam) | Female | SF |
| NM1 | Northern (Miền Bắc) | Male | NM1 |
| SM | Southern (Miền Nam) | Male | SM |
| NM2 | Northern (Miền Bắc) | Male | NM2 |
| Parameter | Default | Description |
|---|---|---|
speed | 1.0 | < 1.0 = faster, > 1.0 = slower |
noise_scale | 0.667 | Voice variability |
noise_scale_w | 0.8 | Duration variability |
sdp_ratio | 0.0 | 0 = deterministic, 1 = stochastic |
Models are automatically downloaded from Hugging Face and cached:
%LOCALAPPDATA%\v_tts\models\~/.cache/v_tts/models/v-tts/
├── v_tts/ # pip install package
│ ├── tts.py # Multi-speaker TTS API
│ └── zeroshot.py # Zero-shot voice cloning API
├── src/
│ ├── models/ # All model architectures
│ │ ├── synthesizer_zeroshot.py # Zero-shot synthesizer
│ │ ├── synthesizer.py # Multi-speaker synthesizer
│ │ ├── encoders.py # Speaker/Style/Prosody encoders
│ │ └── adain.py # Style conditioning module
│ ├── nn/ # Neural network components + mel processing
│ ├── text/ # Text/phoneme processing
│ └── vietnamese/ # Vietnamese text normalization + phonemizer
├── pretrained/
│ ├── zeroshot/ # Zero-shot checkpoint + config
│ ├── hasp/ # Speaker encoder weights
│ ├── onnx/ # ONNX export models
│ └── config.json # Multi-speaker config
├── references/ # 6 reference voices for zero-shot
├── examples/
│ ├── zeroshot/ # Zero-shot cloned audio samples
│ └── *.wav # Multi-speaker audio samples
├── deployments/ # Edge / Web / Android deployments
├── infer_zeroshot.py # Zero-shot CLI inference
├── infer.py # Multi-speaker CLI inference
├── app_zeroshot.py # Gradio demo (zero-shot)
└── app.py # Gradio demo (multi-speaker)
| Platform | Technology | Size | Offline |
|---|---|---|---|
| HuggingFace Spaces | Gradio | Cloud | No |
| Edge | ONNX Runtime | ~165MB | Yes |
| Web | ONNX Runtime Web | ~165MB | Yes |
| Android | ONNX Runtime Mobile | ~185MB | Yes |
See deployments/ for detailed guides.
@software{v_tts,
  title = {V-TTS with Zero-Shot Voice Cloning},
  author = {V-TTS},
  year = {2026},
  url = {https://github.com/tronghieuit/v-tts}
}
CC BY-NC 4.0 — Non-commercial use only. Commercial use requires written permission.
340 followers · starred Apr 2026
927 followers · starred Jun 2026



