
README
Awesome-Multilingual-LLMs-Papers
This repository contains list of papers according to our survey:
Multilingual Large Language Models: A Systematic Survey
Shaolin Zhu1, Supryadi1, Shaoyang Xu1, Haoran Sun1, Leiyu Pan1, Menglong Cui1,
Jiangcun Du1, Renren Jin1, António Branco2†, Deyi Xiong1†*
1TJUNLP Lab, College of Intelligence and Computing, Tianjin University
2NLX, Department of Informatics, University of Lisbon
(*: Corresponding author, †: Advisory role)
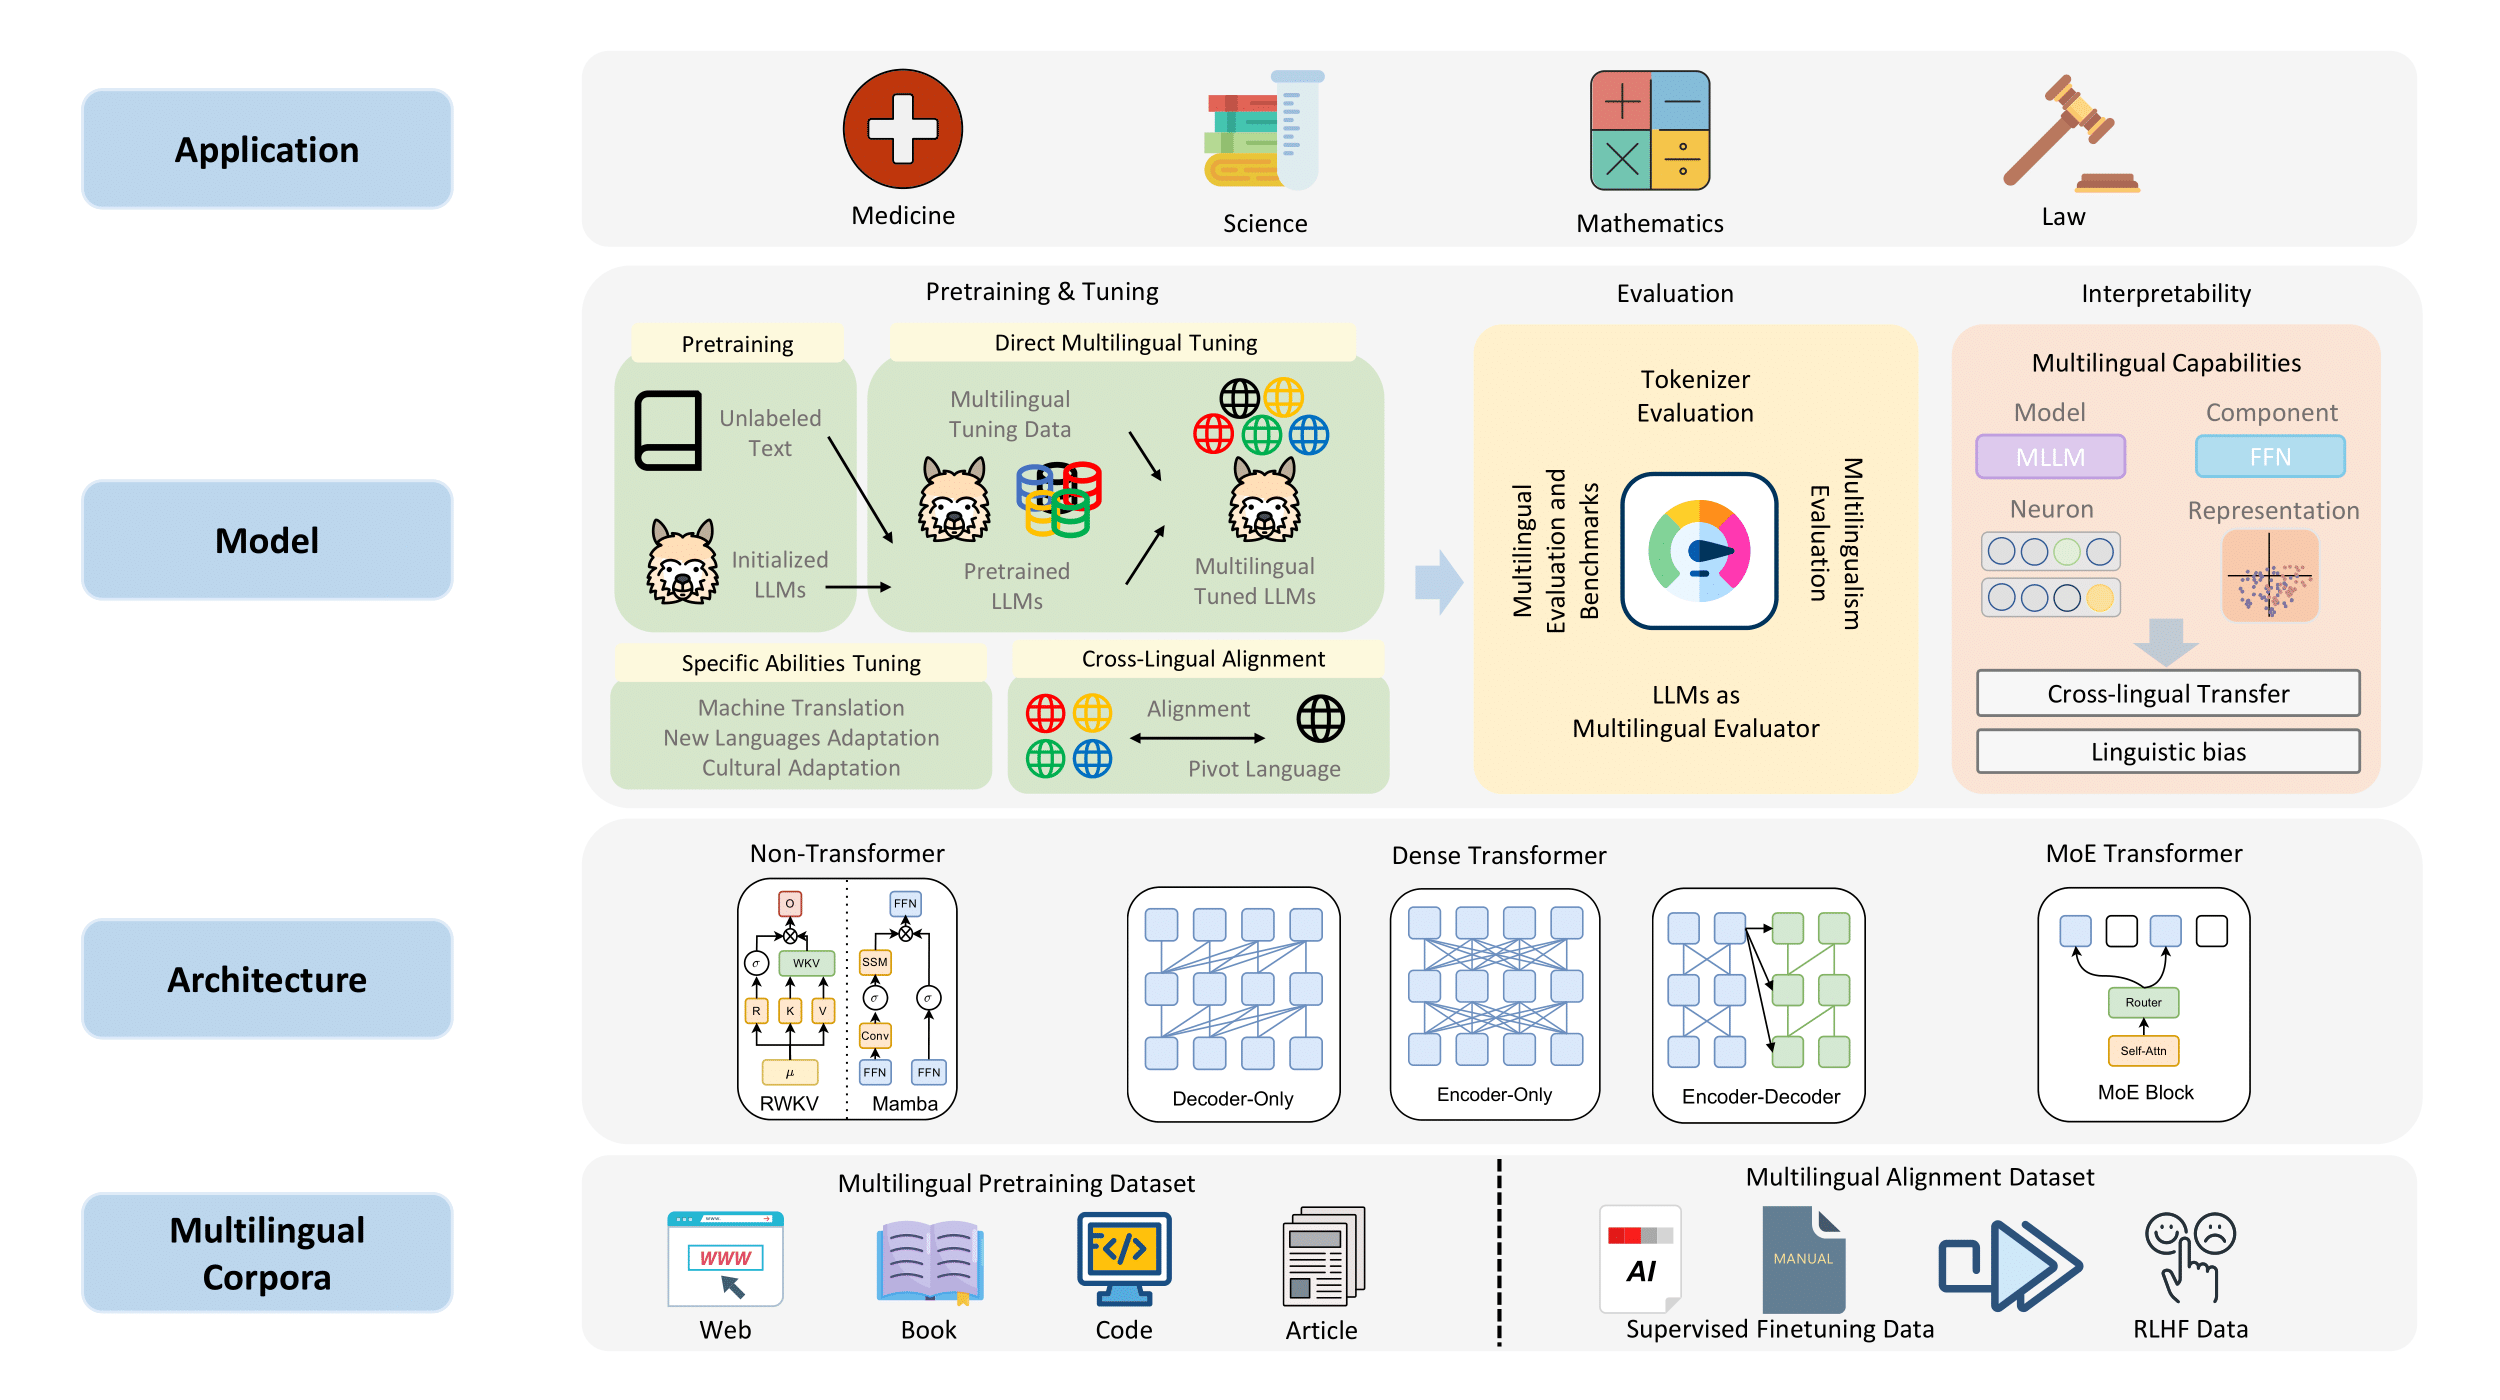
Papers
Multilingual Corpora
Pretraining Datasets
-
"CulturaX: A Cleaned, Enormous, and Multilingual Dataset for Large Language Models in 167 Languages".
Thuat Nguyen et al. LREC-COLING 2024. [Paper]
-
"RedPajama: an Open Dataset for Training Large Language Models".
-
"The BigScience ROOTS Corpus: A 1.6TB Composite Multilingual Dataset".
-
"Zyda: A 1.3T Dataset for Open Language Modeling".
SFT Datasets
-
"Aya Dataset: An Open-Access Collection for Multilingual Instruction Tuning".
Shivalika Singh et al. ACL 2024. [Paper]
-
"Bactrian-X: Multilingual Replicable Instruction-Following Models with Low-Rank Adaptation".
-
"CAMEL: Communicative Agents for "Mind" Exploration of Large Language Model Society".
-
"OpenAssistant Conversations - Democratizing Large Language Model Alignment".
-
"Phoenix: Democratizing ChatGPT across Languages".
-
"Crosslingual Generalization through Multitask Finetuning".
RLHF Datasets
-
"Judging LLM-as-a-Judge with MT-Bench and Chatbot Arena".
-
"OpenAssistant Conversations - Democratizing Large Language Model Alignment".
Multilingual Tuning
Basic Tuning Strategies
Instruction Tuning
-
"Finetuned Language Models Are Zero-Shot Learners".
-
"Multitask Prompted Training Enables Zero-Shot Task Generalization".
-
"Training language models to follow instructions with human feedback".
-
"Training a Helpful and Harmless Assistant with Reinforcement Learning from Human Feedback".
Yuntao Bai et al. arXiv 2022. [Paper]
-
"A General Language Assistant as a Laboratory for Alignment".
Amanda Askell et al. arXiv 2021. [Paper]
-
"Self-Instruct: Aligning Language Models with Self-Generated Instructions".
-
"WizardLM: Empowering Large Language Models to Follow Complex Instructions".
-
"WizardCoder: Empowering Code Large Language Models with Evol-Instruct".
-
"Self-Alignment with Instruction Backtranslation".
Xian Li et al. ICLR 2024. [Paper]
-
"Instruction Tuning With Loss Over Instructions".
-
"Instruction Fine-Tuning: Does Prompt Loss Matter?".
Mathew Huerta-Enochian et al. EMNLP 2024. [Paper]
-
"Instruction Tuning for Large Language Models: A Survey".
Preference Tuning
-
"Training a Helpful and Harmless Assistant with Reinforcement Learning from Human Feedback".
Yuntao Bai et al. arXiv 2022. [Paper]
-
"Training language models to follow instructions with human feedback".
-
"Fine-Tuning Language Models from Human Preferences".
-
"Learning to summarize from human feedback".
-
"WebGPT: Browser-assisted question-answering with human feedback".
Reiichiro Nakano et al. arXiv 2021. [Paper]
-
"Training language models to follow instructions with human feedback".
-
"Direct Preference Optimization: Your Language Model is Secretly a Reward Model".
Rafael Rafailov et al. NeurIPS 2023. [Paper]
-
"Rank Analysis of Incomplete Block Designs: I. The Method of Paired Comparisons".
Ralph Allan Bradley and Milton E. Terry Biometrika 1952. [Paper]
-
"The Impact of Preference Agreement in Reinforcement Learning from Human Feedback: A Case Study in Summarization".
Sian Gooding and Hassan Mansoor arXiv 2023. [Paper]
-
"Understanding the Effects of RLHF on LLM Generalisation and Diversity".
-
"Proximal Policy Optimization Algorithms".
John Schulman et al. arXiv 2017. [Paper]
-
"A General Theoretical Paradigm to Understand Learning from Human Preferences".
Mohammad Gheshlaghi Azar et al. AISTATS 2024. [Paper]
-
"Preference Ranking Optimization for Human Alignment".
-
"RRHF: Rank Responses to Align Language Models with Human Feedback without tears".
-
"KTO: Model Alignment as Prospect Theoretic Optimization".
Kawin Ethayarajh et al. ICML 2024. [Paper]
-
"SLiC-HF: Sequence Likelihood Calibration with Human Feedback".
Yao Zhao et al. arXiv 2023. [Paper]
-
"β-DPO: Direct Preference Optimization with Dynamic β".
-
"SimPO: Simple Preference Optimization with a Reference-Free Reward".
-
"Iterative Preference Learning from Human Feedback: Bridging Theory and Practice for RLHF under KL-Constraint".
Wei Xiong et al. ICML 2024. [Paper]
Direct Multilingual Tuning
Multilingual Tuning Data Collection
-
"Crosslingual Generalization through Multitask Finetuning".
-
"Bactrian-X: A Multilingual Replicable Instruction-Following Model with Low-Rank Adaptation".
-
"Phoenix: Democratizing ChatGPT across Languages".
-
"PolyLM: An Open Source Polyglot Large Language Model".
-
"SeaLLMs -- Large Language Models for Southeast Asia".
Xuan-Phi Nguyen et al. ACL 2024 DEMO TRACK. [Paper] [Github]
-
"Aya Model: An Instruction Finetuned Open-Access Multilingual Language Model".
Ahmet Üstün et al. arXiv 2024. [Paper] [Huggingface]
-
"Okapi: Instruction-tuned Large Language Models in Multiple Languages with Reinforcement Learning from Human Feedback".
Cross-Lingual Transfer Elicitation
-
"Multilingual Instruction Tuning With Just a Pinch of Multilinguality".
Uri Shaham et al. ACL 2024 Findings. [Paper]
-
"Zero-shot cross-lingual transfer in instruction tuning of large language models".
Nadezhda Chirkova et al. INLG 2024. [Paper]
-
"Monolingual or Multilingual Instruction Tuning: Which Makes a Better Alpaca".
-
"Investigating Multilingual Instruction-Tuning: Do Polyglot Models Demand for Multilingual Instructions?".
-
"Turning English-centric LLMs Into Polyglots: How Much Multilinguality Is Needed?".
-
"Lucky 52: How Many Languages Are Needed to Instruction Fine-Tune Large Language Models?".
Shaoxiong Ji et al. arXiv 2024. [Paper] [Huggingface
-
"Reuse Your Rewards: Reward Model Transfer for Zero-Shot Cross-Lingual Alignment".
Zhaofeng Wu et al. EMNLP 2024. [Paper]
-
"The Language Barrier: Dissecting Safety Challenges of LLMs in Multilingual Contexts".
Multilingual Tuning Augmented by Cross-Lingual Alignment
Translation-Assisted Tuning
-
"Empowering Cross-lingual Abilities of Instruction-tuned Large Language Models by Translation-following demonstrations".
-
"Extrapolating Large Language Models to Non-English by Aligning Languages".
Wenhao Zhu et al. arXiv 2023. [Paper]
-
"The Power of Question Translation Training in Multilingual Reasoning: Broadened Scope and Deepened Insights".
Wenhao Zhu et al. arXiv 2024. [Paper]
-
"Question Translation Training for Better Multilingual Reasoning".
-
"BayLing: Bridging Cross-lingual Alignment and Instruction Following through Interactive Translation for Large Language Models".
-
"InstructAlign: High-and-Low Resource Language Alignment via Continual Crosslingual Instruction Tuning".
Samuel Cahyawijaya et al. SEALP 2023. [Paper]
Cross-Lingual Tuning
-
"xCoT: Cross-lingual Instruction Tuning for Cross-lingual Chain-of-Thought Reasoning".
Linzheng Chai et al. arXiv 2024. [Paper]
-
"PLUG: Leveraging Pivot Language in Cross-Lingual Instruction Tuning".
-
"TaCo: Enhancing Cross-Lingual Transfer for Low-Resource Languages in LLMs through Translation-Assisted Chain-of-Thought Processes".
-
"MAPO: Advancing Multilingual Reasoning through Multilingual Alignment-as-Preference Optimization".
Enhancement of Specific Multilingual Abilities
Adaptation to New Languages
-
"Efficient and Effective Text Encoding for Chinese LLaMA and Alpaca".
-
"Efficient and Effective Vocabulary Expansion Towards Multilingual Large Language Models".
Seungduk Kim et al. arXiv 2024. [Paper]
-
"Continual Pre-Training for Cross-Lingual LLM Adaptation: Enhancing Japanese Language Capabilities".
Kazuki Fujii et al. COLM 2024. [Paper]
-
"MaLA-500: Massive Language Adaptation of Large Language Models".
Peiqin Lin et al. arXiv 2024. [Paper]
-
"SeaLLMs -- Large Language Models for Southeast Asia".
Xuan-Phi Nguyen et al. ACL 2024 DEMO TRACK. [Paper] [Github]
-
"LangBridge: Multilingual Reasoning Without Multilingual Supervision".
-
"RomanSetu: Efficiently unlocking multilingual capabilities of Large Language Models via Romanization".
-
"BLOOM+1: Adding Language Support to BLOOM for Zero-Shot Prompting".
-
"LLaMA Beyond English: An Empirical Study on Language Capability Transfer".
Jun Zhao et al. arXiv 2024. [Paper]
-
"Rethinking LLM language adaptation: A case study on chinese mixtral".
Machine Translation
-
"Towards Robust In-Context Learning for Machine Translation with Large Language Models".
Shaolin Zhu et al. LREC 2024. [Paper]
-
"LANDeRMT: Dectecting and Routing Language-Aware Neurons for Selectively Finetuning LLMs to Machine Translation".
Shaolin Zhu et al. ACL 2024. [Paper]
-
"FEDS-ICL: Enhancing translation ability and efficiency of large language model by optimizing demonstration selection".
Shaolin Zhu et al. Information Processing & Management 2024. [Paper]
-
"Efficiently Exploring Large Language Models for Document-Level Machine Translation with In-context Learning".
Menglong Cui et al. ACL 2024 Findings. [Paper]
-
"DUAL-REFLECT: Enhancing Large Language Models for Reflective Translation through Dual Learning Feedback Mechanisms".
-
"Paying More Attention to Source Context: Mitigating Unfaithful Translations from Large Language Model".
-
"BigTranslate: Augmenting Large Language Models with Multilingual Translation Capability over 100 Languages".
-
"A Paradigm Shift in Machine Translation: Boosting Translation Performance of Large Language Models".
-
"Eliciting the Translation Ability of Large Language Models via Multilingual Finetuning with Translation Instructions".
Jiahuan Li et al. TACL 2024. [Paper]
-
"Fine-Tuning Large Language Models to Translate: Will a Touch of Noisy Data in Misaligned Languages Suffice?".
-
"Contrastive Preference Optimization: Pushing the Boundaries of LLM Performance in Machine Translation".
-
"Advancing Translation Preference Modeling with RLHF: A Step Towards Cost-Effective Solution".
Nuo Xu et al. arXiv 2024. [Paper]
-
"Word Alignment as Preference for Machine Translation".
Qiyu Wu et al. EMNLP 2024. [Paper]
-
"Teaching Large Language Models to Translate with Comparison".
-
"Improving Translation Faithfulness of Large Language Models via Augmenting Instructions".
-
"Towards Boosting Many-to-Many Multilingual Machine Translation with Large Language Models".
-
"Tuning LLMs with Contrastive Alignment Instructions for Machine Translation in Unseen, Low-resource Languages".
Zhuoyuan Mao et al. LoResMT 2024. [Paper]
-
"Relay Decoding: Concatenating Large Language Models for Machine Translation".
Chengpeng Fu et al. arXiv 2024. [Paper]
-
"m3P: Towards Multimodal Multilingual Translation with Multimodal Prompt".
Jian Yang et al. LREC 2024. [Paper] [Huggingface]
Cultural Adaptation
-
"CultureLLM: Incorporating Cultural Differences into Large Language Models".
-
"CulturePark: Boosting Cross-cultural Understanding in Large Language Models".
-
"Self-Pluralising Culture Alignment for Large Language Models".
-
"Global Gallery: The Fine Art of Painting Culture Portraits through Multilingual Instruction Tuning".
-
"The Echoes of Multilinguality: Tracing Cultural Value Shifts during LM Fine-tuning".
Rochelle Choenni et al. ACL 2024. [Paper]
-
"CRAFT: Extracting and Tuning Cultural Instructions from the Wild".
Multilingual Evaluation
Tokenizer Evaluation
-
"How Good is Your Tokenizer? On the Monolingual Performance of Multilingual Language Models".
Phillip Rust and Jonas Pfeiffer et al. ACL-IJCNLP 2021. [Paper] [GitHub]
-
"ByT5: Towards a Token-Free Future with Pre-trained Byte-to-Byte Models".
Linting Xue, Aditya Barua, Noah Constant, and Rami Al-Rfou et al. TACL 2023. [Paper] [GitHub]
-
"Language Model Tokenizers Introduce Unfairness Between Languages".
-
"Tokenizer Choice For LLM Training: Negligible or Crucial?".
Mehdi Ali, Michael Fromm, and Klaudia Thellmann et al. NAACL (Findings) 2024. [Paper]
Multilingual Evaluation Benchmarks and Datasets
Multilingual Holistic Evaluation
-
"MEGA: Multilingual Evaluation of Generative AI".
-
"MEGAVERSE: Benchmarking Large Language Models Across Languages, Modalities, Models and Tasks".
Sanchit Ahuja et al. arXiv 2024. [Paper]
-
"ByT5: Towards a Token-Free Future with Pre-trained Byte-to-Byte Models".
Viet Dac Lai, Nghia Trung Ngo, and Amir Pouran Ben Veyseh et al. EMNLP (Findings) 2023. [Paper]
Multilingual Task-Specific Evaluation
Translation Evaluation
-
"Investigating the Translation Performance of a Large Multilingual Language Model: the Case of BLOOM".
-
"Multilingual Machine Translation with Large Language Models: Empirical Results and Analysis".
Question Answering Evaluation
-
"M3Exam: A Multilingual, Multimodal, Multilevel Benchmark for Examining Large Language Models".
-
"Evaluating the Elementary Multilingual Capabilities of Large Language Models with MULTIQ".
Carolin Holtermann and Paul Röttger et al. ACL (Findings) 2024. [Paper] [GitHub]
Summarization Evaluation
-
"SEAHORSE: A Multilingual, Multifaceted Dataset for Summarization Evaluation".
Dialogue Evaluation
-
"xDial-Eval: A Multilingual Open-Domain Dialogue Evaluation Benchmark".
-
"MEEP: Is this Engaging? Prompting Large Language Models for Dialogue Evaluation in Multilingual Settings".
Multilingual Alignment Evaluation
Multilingual Ethics Evaluation
-
"Ethical Reasoning and Moral Value Alignment of LLMs Depend on the Language we Prompt them in".
Utkarsh Agarwal, Kumar Tanmay, and Aditi Khandelwal et al. LREC-COLING 2024. [Paper]
Multilingual Toxicity Evaluation
-
"RTP-LX: Can LLMs Evaluate Toxicity in Multilingual Scenarios?".
-
"PolygloToxicityPrompts: Multilingual Evaluation of Neural Toxic Degeneration in Large Language Models".
Devansh Jain and Priyanshu Kumar et al. COLM 2024. [Paper] [GitHub]
Multilingual Bias Evaluation
-
"On Evaluating and Mitigating Gender Biases in Multilingual Settings".
Aniket Vashishtha and Kabir Ahuja et al. ACL (Findings) 2021. [Paper] [GitHub]
Multilingual Safety Evaluation
Multilingual Safety Benchmarks
-
"All Languages Matter: On the Multilingual Safety of LLMs".
Multilingual Jailbreaking/Red-Teaming
-
"Low-Resource Languages Jailbreak GPT-4".
Zheng-Xin Yong et al. NeurIPS (Workshop) 2023. [Paper]
-
"Multilingual Jailbreak Challenges in Large Language Models".
-
"A Cross-Language Investigation into Jailbreak Attacks in Large Language Models".
Jie Li et al. arXiv 2024. [Paper]
Multilingualism Evaluation
-
"How Vocabulary Sharing Facilitates Multilingualism in LLaMA?".
MLLMs as Multilingual Evaluator
-
"Are Large Language Model-based Evaluators the Solution to Scaling Up Multilingual Evaluation?".
-
"METAL: Towards Multilingual Meta-Evaluation".
Rishav Hada and Varun Gumma et al. NAACL (Findings) 2024. [Paper] [GitHub]
Interpretability
Interpretability of Multilingual Capabilities
Model-Wide Interpretation
-
"How do Large Language Models Handle Multilingualism?".
Zhao Y, Zhang W, Chen G, et al. arXiv 2024. [Paper]
-
"Do Llamas Work in English? On the Latent Language of Multilingual Transformers".
Wendler C, Veselovsky V, Monea G, et al. ACL 2024. [Paper]
-
"Analyzing the Mono- and Cross-Lingual Pretraining Dynamics of Multilingual Language Models".
Blevins T, Gonen H, Zettlemoyer L. EMNLP 2022. [Paper]
Component-Based Interpretation
-
"Unveiling Multilinguality in Transformer Models: Exploring Language Specificity in Feed-Forward Networks".
Bhattacharya S, Bojar O. Proceedings of the 6th BlackboxNLP Workshop: Analyzing and Interpreting Neural Networks for NLP 2023. [Paper]
Neuron-Level Interpretation
-
"Unveiling Linguistic Regions in Large Language Models".
Zhang Z, Zhao J, Zhang Q, et al. ACL 2024. [Paper]
-
"Language-Specific Neurons: The Key to Multilingual Capabilities in Large Language Models".
Tang T, Luo W, Huang H, et al. ACL 2024. [Paper]
-
"Unraveling Babel: Exploring Multilingual Activation Patterns of LLMs and Their Applications".
Liu W, Xu Y, Xu H, et al. EMNLP 2024. [Paper]
-
"On the Multilingual Ability of Decoder-based Pre-trained Language Models: Finding and Controlling Language-Specific Neurons".
Kojima T, Okimura I, Iwasawa Y, et al. NAACL 2024. [Paper]
Representation-Driven Interpretation
-
"The Geometry of Multilingual Language Model Representations".
Chang T, Tu Z, Bergen B. EMNLP 2022. [Paper]
-
"Language-agnostic Representation from Multilingual Sentence Encoders for Cross-lingual Similarity Estimation".
Tiyajamorn N, Kajiwara T, Arase Y, et al. EMNLP 2021. [Paper]
-
"An Isotropy Analysis in the Multilingual BERT Embedding Space".
Rajaee S, Pilehvar M T. ACL 2022. [Paper]
-
"Discovering Low-rank Subspaces for Language-agnostic Multilingual Representations".
Xie Z, Zhao H, Yu T, et al. EMNLP 2022. [Paper]
-
"Emerging Cross-lingual Structure in Pretrained Language Models".
Conneau A, Wu S, Li H, et al. ACL 2020. [Paper]
-
"Probing LLMs for Joint Encoding of Linguistic Categories".
Starace G, Papakostas K, Choenni R, et al. EMNLP 2023. [Paper]
-
"Morph Call: Probing Morphosyntactic Content of Multilingual Transformers".
Mikhailov V, Serikov O, Artemova E. Proceedings of the Third Workshop on Computational Typology and Multilingual NLP 2021. [Paper]
-
"Same Neurons, Different Languages: Probing Morphosyntax in Multilingual Pre-trained Models".
Stanczak K, Ponti E, Hennigen L T, et al. NAACL 2022. [Paper]
-
"Probing Cross-Lingual Lexical Knowledge from Multilingual Sentence Encoders".
Vulić I, Glavaš G, Liu F, et al. EACL 2023. [Paper]
-
"The Emergence of Semantic Units in Massively Multilingual Models".
de Varda A G, Marelli M. LREC-COLING 2024. [Paper]
-
"X-FACTR: Multilingual Factual Knowledge Retrieval from Pretrained Language Models".
Jiang Z, Anastasopoulos A, Araki J, et al. EMNLP 2020. [Paper]
-
"Multilingual LAMA: Investigating Knowledge in Multilingual Pretrained Language Models".
Kassner N, Dufter P, Schütze H. EACL 2021. [Paper]
-
"Cross-Lingual Consistency of Factual Knowledge in Multilingual Language Models".
Qi J, Fernández R, Bisazza A. EMNLP 2023. [Paper]
-
"Language Representation Projection: Can We Transfer Factual Knowledge across Languages in Multilingual Language Models?".
Xu S, Li J, Xiong D. EMNLP 2023. [Paper]
Interpretability of Cross-lingual Transfer
-
"Are Structural Concepts Universal in Transformer Language Models? Towards Interpretable Cross-Lingual Generalization"
Xu N, Zhang Q, Ye J, et al. EMNLP 2023. [Paper]
-
"When is BERT Multilingual? Isolating Crucial Ingredients for Cross-lingual Transfer".
Deshpande A, Talukdar P, Narasimhan K. NAACL 2022. [Paper]
-
"Emerging Cross-lingual Structure in Pretrained Language Models".
Conneau A, Wu S, Li H, et al. ACL 2020. [Paper]
-
"Cross-Lingual Ability of Multilingual BERT: An Empirical Study".
Karthikeyan K, Wang Z, Mayhew S, et al. ICLR 2020. [Paper]
-
"Unveiling Linguistic Regions in Large Language Models".
Zhang Z, Zhao J, Zhang Q, et al. ACL 2024. [Paper]
-
"Unraveling Babel: Exploring Multilingual Activation Patterns of LLMs and Their Applications".
Liu W, Xu Y, Xu H, et al. EMNLP 2024. [Paper]
-
"The Geometry of Multilingual Language Model Representations".
Chang T, Tu Z, Bergen B. EMNLP 2022. [Paper]
Interpretability of Linguistic Bias
-
"How do Large Language Models Handle Multilingualism?".
Zhao Y, Zhang W, Chen G, et al. arXiv 2024. [Paper]
-
"Do Llamas Work in English? On the Latent Language of Multilingual Transformers".
Wendler C, Veselovsky V, Monea G, et al. ACL 2024. [Paper]
Applications of MLLMs
MLLMs for Biology and Medicine
-
"Biobert: a pre-trained biomedical language representation model for biomedical text mining."
-
"DNABERT: pre-trained bidirectional encoder representations from transformers model for dna-language in genome."
-
"DNABERT-2: efficient foundation model and benchmark for multi-species genome."
-
"MING-MOE: enhancing medical multi-task learning in large language models with sparse mixture of low-rank adapter experts."
-
"Doctorglm: Fine-tuning your chinese doctor is not a herculean task."
-
"Huatuogpt, towards taming language model to be a doctor."
-
"Medgpt: Medical concept prediction from clinical narratives."
Zeljko Kraljevic et al. arXiv 2021 [paper]
-
"Clinicalgpt: Large language models finetuned with diverse medical data and comprehensive evaluation."
Guangyu Wang et al. arXiv 2023 [paper]
-
"Ivygpt: Interactive chinese pathway language model in medical domain."
-
"Bianque: Balancing the questioning and suggestion ability of health llms with multi-turn health conversations polished by chatgpt."
-
"Soulchat: Improving llms’ empathy, listening, and comfort abilities through fine-tuning with multi-turn empathy conversations."
-
"Towards expert-level medical question answering with large language models."
-
"Chatdoctor: A medical chat model fine-tuned on llama model using medical domain knowledge."
Yunxiang Li et al. arXiv 2023 [paper] [[github](Chatdoctor: A medical chat model fine-tuned on llama model using medical domain knowledge)]
MLLMs for Computer Science
-
"Codebert: A pre-trained model for programming and natural languages."
-
"Learning and evaluating contextual embedding of source code."
-
"Unified pre-training for program understanding and generation."
-
"Codet5: Identifier-aware unified pre-trained encoder-decoder models for code understanding and generation."
-
"Codet5+: Open code large language models for code understanding and generation."
-
"Competition-level code generation with alphacode"
-
"Evaluating large language models trained on code."
-
"A systematic evaluation of large language models of code."
-
"Codegen: An open large language model for code with multi-turn program synthesis."
-
"A generative model for code infilling and synthesis."
-
"Code llama: Open foundation models for code."
-
"Starcoder: may the source be with you!"
-
"CodeGeeX: A pretrained model for code generation with multilingual benchmarking on humaneval-x."
-
"Codeshell technical report."
-
"CodeGemma: Open Code Models Based on Gemma"
-
"Qwen2.5-Coder Technical Report."
MLLMs for Mathematics
-
"Tree-based representation and generation of natural and mathematical language."
-
"Chatglm-math: Improving math problem-solving in large language models with a self-critique pipeline."
-
"Deepseek-math: Pushing the limits of mathematical reasoning in open language models."
-
"Metamath: Bootstrap your own mathematical questions for large language models."
-
"Mammoth: Building math generalist models through hybrid instruction tuning."
-
"Wizardmath: Empowering mathematical reasoning for large language models via reinforced evol-instruct."
-
"Generative ai for math: Abel."
Ethan Chern et al. GitHub 2023 [github]
-
"Orca-math: Unlocking the potential of slms in grade school math."
MLLMs for Law
-
"LEGAL-BERT: the muppets straight out of law school."
-
"Lawformer: A pre-trained language model for chinese legal long documents."
-
"A brief report on lawgpt 1.0: A virtual legal assistant based on GPT-3."
Ha-Thanh Nguyen arXiv 2023 [paper]
-
"Disc-lawllm: Fine-tuning large language models for intelligent legal services."
-
"Chatlaw: Open-source legal large language model with integrated external knowledge bases."
-
"SAILER: structure-aware pre-trained language model for legal case retrieval."
-
"Lawyer llama technical report."
-
"Legal-relectra: Mixeddomain language modeling for long-range legal text comprehension."
Wenyue Hua et al. arXiv 2022 [paper]
Contributors

17 commits
Similar repos


README
Awesome-Multilingual-LLMs-Papers
This repository contains list of papers according to our survey:
Multilingual Large Language Models: A Systematic Survey
Shaolin Zhu1, Supryadi1, Shaoyang Xu1, Haoran Sun1, Leiyu Pan1, Menglong Cui1,
Jiangcun Du1, Renren Jin1, António Branco2†, Deyi Xiong1†*
1TJUNLP Lab, College of Intelligence and Computing, Tianjin University
2NLX, Department of Informatics, University of Lisbon
(*: Corresponding author, †: Advisory role)
Papers
Multilingual Corpora
Pretraining Datasets
-
"CulturaX: A Cleaned, Enormous, and Multilingual Dataset for Large Language Models in 167 Languages".
Thuat Nguyen et al. LREC-COLING 2024. [Paper]
-
"RedPajama: an Open Dataset for Training Large Language Models".
-
"The BigScience ROOTS Corpus: A 1.6TB Composite Multilingual Dataset".
-
"Zyda: A 1.3T Dataset for Open Language Modeling".
SFT Datasets
-
"Aya Dataset: An Open-Access Collection for Multilingual Instruction Tuning".
Shivalika Singh et al. ACL 2024. [Paper]
-
"Bactrian-X: Multilingual Replicable Instruction-Following Models with Low-Rank Adaptation".
-
"CAMEL: Communicative Agents for "Mind" Exploration of Large Language Model Society".
-
"OpenAssistant Conversations - Democratizing Large Language Model Alignment".
-
"Phoenix: Democratizing ChatGPT across Languages".
-
"Crosslingual Generalization through Multitask Finetuning".
RLHF Datasets
-
"Judging LLM-as-a-Judge with MT-Bench and Chatbot Arena".
-
"OpenAssistant Conversations - Democratizing Large Language Model Alignment".
Multilingual Tuning
Basic Tuning Strategies
Instruction Tuning
-
"Finetuned Language Models Are Zero-Shot Learners".
-
"Multitask Prompted Training Enables Zero-Shot Task Generalization".
-
"Training language models to follow instructions with human feedback".
-
"Training a Helpful and Harmless Assistant with Reinforcement Learning from Human Feedback".
Yuntao Bai et al. arXiv 2022. [Paper]
-
"A General Language Assistant as a Laboratory for Alignment".
Amanda Askell et al. arXiv 2021. [Paper]
-
"Self-Instruct: Aligning Language Models with Self-Generated Instructions".
-
"WizardLM: Empowering Large Language Models to Follow Complex Instructions".
-
"WizardCoder: Empowering Code Large Language Models with Evol-Instruct".
-
"Self-Alignment with Instruction Backtranslation".
Xian Li et al. ICLR 2024. [Paper]
-
"Instruction Tuning With Loss Over Instructions".
-
"Instruction Fine-Tuning: Does Prompt Loss Matter?".
Mathew Huerta-Enochian et al. EMNLP 2024. [Paper]
-
"Instruction Tuning for Large Language Models: A Survey".
Preference Tuning
-
"Training a Helpful and Harmless Assistant with Reinforcement Learning from Human Feedback".
Yuntao Bai et al. arXiv 2022. [Paper]
-
"Training language models to follow instructions with human feedback".
-
"Fine-Tuning Language Models from Human Preferences".
-
"Learning to summarize from human feedback".
-
"WebGPT: Browser-assisted question-answering with human feedback".
Reiichiro Nakano et al. arXiv 2021. [Paper]
-
"Training language models to follow instructions with human feedback".
-
"Direct Preference Optimization: Your Language Model is Secretly a Reward Model".
Rafael Rafailov et al. NeurIPS 2023. [Paper]
-
"Rank Analysis of Incomplete Block Designs: I. The Method of Paired Comparisons".
Ralph Allan Bradley and Milton E. Terry Biometrika 1952. [Paper]
-
"The Impact of Preference Agreement in Reinforcement Learning from Human Feedback: A Case Study in Summarization".
Sian Gooding and Hassan Mansoor arXiv 2023. [Paper]
-
"Understanding the Effects of RLHF on LLM Generalisation and Diversity".
-
"Proximal Policy Optimization Algorithms".
John Schulman et al. arXiv 2017. [Paper]
-
"A General Theoretical Paradigm to Understand Learning from Human Preferences".
Mohammad Gheshlaghi Azar et al. AISTATS 2024. [Paper]
-
"Preference Ranking Optimization for Human Alignment".
-
"RRHF: Rank Responses to Align Language Models with Human Feedback without tears".
-
"KTO: Model Alignment as Prospect Theoretic Optimization".
Kawin Ethayarajh et al. ICML 2024. [Paper]
-
"SLiC-HF: Sequence Likelihood Calibration with Human Feedback".
Yao Zhao et al. arXiv 2023. [Paper]
-
"β-DPO: Direct Preference Optimization with Dynamic β".
-
"SimPO: Simple Preference Optimization with a Reference-Free Reward".
-
"Iterative Preference Learning from Human Feedback: Bridging Theory and Practice for RLHF under KL-Constraint".
Wei Xiong et al. ICML 2024. [Paper]
Direct Multilingual Tuning
Multilingual Tuning Data Collection
-
"Crosslingual Generalization through Multitask Finetuning".
-
"Bactrian-X: A Multilingual Replicable Instruction-Following Model with Low-Rank Adaptation".
-
"Phoenix: Democratizing ChatGPT across Languages".
-
"PolyLM: An Open Source Polyglot Large Language Model".
-
"SeaLLMs -- Large Language Models for Southeast Asia".
Xuan-Phi Nguyen et al. ACL 2024 DEMO TRACK. [Paper] [Github]
-
"Aya Model: An Instruction Finetuned Open-Access Multilingual Language Model".
Ahmet Üstün et al. arXiv 2024. [Paper] [Huggingface]
-
"Okapi: Instruction-tuned Large Language Models in Multiple Languages with Reinforcement Learning from Human Feedback".
Cross-Lingual Transfer Elicitation
-
"Multilingual Instruction Tuning With Just a Pinch of Multilinguality".
Uri Shaham et al. ACL 2024 Findings. [Paper]
-
"Zero-shot cross-lingual transfer in instruction tuning of large language models".
Nadezhda Chirkova et al. INLG 2024. [Paper]
-
"Monolingual or Multilingual Instruction Tuning: Which Makes a Better Alpaca".
-
"Investigating Multilingual Instruction-Tuning: Do Polyglot Models Demand for Multilingual Instructions?".
-
"Turning English-centric LLMs Into Polyglots: How Much Multilinguality Is Needed?".
-
"Lucky 52: How Many Languages Are Needed to Instruction Fine-Tune Large Language Models?".
Shaoxiong Ji et al. arXiv 2024. [Paper] [Huggingface
-
"Reuse Your Rewards: Reward Model Transfer for Zero-Shot Cross-Lingual Alignment".
Zhaofeng Wu et al. EMNLP 2024. [Paper]
-
"The Language Barrier: Dissecting Safety Challenges of LLMs in Multilingual Contexts".
Multilingual Tuning Augmented by Cross-Lingual Alignment
Translation-Assisted Tuning
-
"Empowering Cross-lingual Abilities of Instruction-tuned Large Language Models by Translation-following demonstrations".
-
"Extrapolating Large Language Models to Non-English by Aligning Languages".
Wenhao Zhu et al. arXiv 2023. [Paper]
-
"The Power of Question Translation Training in Multilingual Reasoning: Broadened Scope and Deepened Insights".
Wenhao Zhu et al. arXiv 2024. [Paper]
-
"Question Translation Training for Better Multilingual Reasoning".
-
"BayLing: Bridging Cross-lingual Alignment and Instruction Following through Interactive Translation for Large Language Models".
-
"InstructAlign: High-and-Low Resource Language Alignment via Continual Crosslingual Instruction Tuning".
Samuel Cahyawijaya et al. SEALP 2023. [Paper]
Cross-Lingual Tuning
-
"xCoT: Cross-lingual Instruction Tuning for Cross-lingual Chain-of-Thought Reasoning".
Linzheng Chai et al. arXiv 2024. [Paper]
-
"PLUG: Leveraging Pivot Language in Cross-Lingual Instruction Tuning".
-
"TaCo: Enhancing Cross-Lingual Transfer for Low-Resource Languages in LLMs through Translation-Assisted Chain-of-Thought Processes".
-
"MAPO: Advancing Multilingual Reasoning through Multilingual Alignment-as-Preference Optimization".
Enhancement of Specific Multilingual Abilities
Adaptation to New Languages
-
"Efficient and Effective Text Encoding for Chinese LLaMA and Alpaca".
-
"Efficient and Effective Vocabulary Expansion Towards Multilingual Large Language Models".
Seungduk Kim et al. arXiv 2024. [Paper]
-
"Continual Pre-Training for Cross-Lingual LLM Adaptation: Enhancing Japanese Language Capabilities".
Kazuki Fujii et al. COLM 2024. [Paper]
-
"MaLA-500: Massive Language Adaptation of Large Language Models".
Peiqin Lin et al. arXiv 2024. [Paper]
-
"SeaLLMs -- Large Language Models for Southeast Asia".
Xuan-Phi Nguyen et al. ACL 2024 DEMO TRACK. [Paper] [Github]
-
"LangBridge: Multilingual Reasoning Without Multilingual Supervision".
-
"RomanSetu: Efficiently unlocking multilingual capabilities of Large Language Models via Romanization".
-
"BLOOM+1: Adding Language Support to BLOOM for Zero-Shot Prompting".
-
"LLaMA Beyond English: An Empirical Study on Language Capability Transfer".
Jun Zhao et al. arXiv 2024. [Paper]
-
"Rethinking LLM language adaptation: A case study on chinese mixtral".
Machine Translation
-
"Towards Robust In-Context Learning for Machine Translation with Large Language Models".
Shaolin Zhu et al. LREC 2024. [Paper]
-
"LANDeRMT: Dectecting and Routing Language-Aware Neurons for Selectively Finetuning LLMs to Machine Translation".
Shaolin Zhu et al. ACL 2024. [Paper]
-
"FEDS-ICL: Enhancing translation ability and efficiency of large language model by optimizing demonstration selection".
Shaolin Zhu et al. Information Processing & Management 2024. [Paper]
-
"Efficiently Exploring Large Language Models for Document-Level Machine Translation with In-context Learning".
Menglong Cui et al. ACL 2024 Findings. [Paper]
-
"DUAL-REFLECT: Enhancing Large Language Models for Reflective Translation through Dual Learning Feedback Mechanisms".
-
"Paying More Attention to Source Context: Mitigating Unfaithful Translations from Large Language Model".
-
"BigTranslate: Augmenting Large Language Models with Multilingual Translation Capability over 100 Languages".
-
"A Paradigm Shift in Machine Translation: Boosting Translation Performance of Large Language Models".
-
"Eliciting the Translation Ability of Large Language Models via Multilingual Finetuning with Translation Instructions".
Jiahuan Li et al. TACL 2024. [Paper]
-
"Fine-Tuning Large Language Models to Translate: Will a Touch of Noisy Data in Misaligned Languages Suffice?".
-
"Contrastive Preference Optimization: Pushing the Boundaries of LLM Performance in Machine Translation".
-
"Advancing Translation Preference Modeling with RLHF: A Step Towards Cost-Effective Solution".
Nuo Xu et al. arXiv 2024. [Paper]
-
"Word Alignment as Preference for Machine Translation".
Qiyu Wu et al. EMNLP 2024. [Paper]
-
"Teaching Large Language Models to Translate with Comparison".
-
"Improving Translation Faithfulness of Large Language Models via Augmenting Instructions".
-
"Towards Boosting Many-to-Many Multilingual Machine Translation with Large Language Models".
-
"Tuning LLMs with Contrastive Alignment Instructions for Machine Translation in Unseen, Low-resource Languages".
Zhuoyuan Mao et al. LoResMT 2024. [Paper]
-
"Relay Decoding: Concatenating Large Language Models for Machine Translation".
Chengpeng Fu et al. arXiv 2024. [Paper]
-
"m3P: Towards Multimodal Multilingual Translation with Multimodal Prompt".
Jian Yang et al. LREC 2024. [Paper] [Huggingface]
Cultural Adaptation
-
"CultureLLM: Incorporating Cultural Differences into Large Language Models".
-
"CulturePark: Boosting Cross-cultural Understanding in Large Language Models".
-
"Self-Pluralising Culture Alignment for Large Language Models".
-
"Global Gallery: The Fine Art of Painting Culture Portraits through Multilingual Instruction Tuning".
-
"The Echoes of Multilinguality: Tracing Cultural Value Shifts during LM Fine-tuning".
Rochelle Choenni et al. ACL 2024. [Paper]
-
"CRAFT: Extracting and Tuning Cultural Instructions from the Wild".
Multilingual Evaluation
Tokenizer Evaluation
-
"How Good is Your Tokenizer? On the Monolingual Performance of Multilingual Language Models".
Phillip Rust and Jonas Pfeiffer et al. ACL-IJCNLP 2021. [Paper] [GitHub]
-
"ByT5: Towards a Token-Free Future with Pre-trained Byte-to-Byte Models".
Linting Xue, Aditya Barua, Noah Constant, and Rami Al-Rfou et al. TACL 2023. [Paper] [GitHub]
-
"Language Model Tokenizers Introduce Unfairness Between Languages".
-
"Tokenizer Choice For LLM Training: Negligible or Crucial?".
Mehdi Ali, Michael Fromm, and Klaudia Thellmann et al. NAACL (Findings) 2024. [Paper]
Multilingual Evaluation Benchmarks and Datasets
Multilingual Holistic Evaluation
-
"MEGA: Multilingual Evaluation of Generative AI".
-
"MEGAVERSE: Benchmarking Large Language Models Across Languages, Modalities, Models and Tasks".
Sanchit Ahuja et al. arXiv 2024. [Paper]
-
"ByT5: Towards a Token-Free Future with Pre-trained Byte-to-Byte Models".
Viet Dac Lai, Nghia Trung Ngo, and Amir Pouran Ben Veyseh et al. EMNLP (Findings) 2023. [Paper]
Multilingual Task-Specific Evaluation
Translation Evaluation
-
"Investigating the Translation Performance of a Large Multilingual Language Model: the Case of BLOOM".
-
"Multilingual Machine Translation with Large Language Models: Empirical Results and Analysis".
Question Answering Evaluation
-
"M3Exam: A Multilingual, Multimodal, Multilevel Benchmark for Examining Large Language Models".
-
"Evaluating the Elementary Multilingual Capabilities of Large Language Models with MULTIQ".
Carolin Holtermann and Paul Röttger et al. ACL (Findings) 2024. [Paper] [GitHub]
Summarization Evaluation
-
"SEAHORSE: A Multilingual, Multifaceted Dataset for Summarization Evaluation".
Dialogue Evaluation
-
"xDial-Eval: A Multilingual Open-Domain Dialogue Evaluation Benchmark".
-
"MEEP: Is this Engaging? Prompting Large Language Models for Dialogue Evaluation in Multilingual Settings".
Multilingual Alignment Evaluation
Multilingual Ethics Evaluation
-
"Ethical Reasoning and Moral Value Alignment of LLMs Depend on the Language we Prompt them in".
Utkarsh Agarwal, Kumar Tanmay, and Aditi Khandelwal et al. LREC-COLING 2024. [Paper]
Multilingual Toxicity Evaluation
-
"RTP-LX: Can LLMs Evaluate Toxicity in Multilingual Scenarios?".
-
"PolygloToxicityPrompts: Multilingual Evaluation of Neural Toxic Degeneration in Large Language Models".
Devansh Jain and Priyanshu Kumar et al. COLM 2024. [Paper] [GitHub]
Multilingual Bias Evaluation
-
"On Evaluating and Mitigating Gender Biases in Multilingual Settings".
Aniket Vashishtha and Kabir Ahuja et al. ACL (Findings) 2021. [Paper] [GitHub]
Multilingual Safety Evaluation
Multilingual Safety Benchmarks
-
"All Languages Matter: On the Multilingual Safety of LLMs".
Multilingual Jailbreaking/Red-Teaming
-
"Low-Resource Languages Jailbreak GPT-4".
Zheng-Xin Yong et al. NeurIPS (Workshop) 2023. [Paper]
-
"Multilingual Jailbreak Challenges in Large Language Models".
-
"A Cross-Language Investigation into Jailbreak Attacks in Large Language Models".
Jie Li et al. arXiv 2024. [Paper]
Multilingualism Evaluation
-
"How Vocabulary Sharing Facilitates Multilingualism in LLaMA?".
MLLMs as Multilingual Evaluator
-
"Are Large Language Model-based Evaluators the Solution to Scaling Up Multilingual Evaluation?".
-
"METAL: Towards Multilingual Meta-Evaluation".
Rishav Hada and Varun Gumma et al. NAACL (Findings) 2024. [Paper] [GitHub]
Interpretability
Interpretability of Multilingual Capabilities
Model-Wide Interpretation
-
"How do Large Language Models Handle Multilingualism?".
Zhao Y, Zhang W, Chen G, et al. arXiv 2024. [Paper]
-
"Do Llamas Work in English? On the Latent Language of Multilingual Transformers".
Wendler C, Veselovsky V, Monea G, et al. ACL 2024. [Paper]
-
"Analyzing the Mono- and Cross-Lingual Pretraining Dynamics of Multilingual Language Models".
Blevins T, Gonen H, Zettlemoyer L. EMNLP 2022. [Paper]
Component-Based Interpretation
-
"Unveiling Multilinguality in Transformer Models: Exploring Language Specificity in Feed-Forward Networks".
Bhattacharya S, Bojar O. Proceedings of the 6th BlackboxNLP Workshop: Analyzing and Interpreting Neural Networks for NLP 2023. [Paper]
Neuron-Level Interpretation
-
"Unveiling Linguistic Regions in Large Language Models".
Zhang Z, Zhao J, Zhang Q, et al. ACL 2024. [Paper]
-
"Language-Specific Neurons: The Key to Multilingual Capabilities in Large Language Models".
Tang T, Luo W, Huang H, et al. ACL 2024. [Paper]
-
"Unraveling Babel: Exploring Multilingual Activation Patterns of LLMs and Their Applications".
Liu W, Xu Y, Xu H, et al. EMNLP 2024. [Paper]
-
"On the Multilingual Ability of Decoder-based Pre-trained Language Models: Finding and Controlling Language-Specific Neurons".
Kojima T, Okimura I, Iwasawa Y, et al. NAACL 2024. [Paper]
Representation-Driven Interpretation
-
"The Geometry of Multilingual Language Model Representations".
Chang T, Tu Z, Bergen B. EMNLP 2022. [Paper]
-
"Language-agnostic Representation from Multilingual Sentence Encoders for Cross-lingual Similarity Estimation".
Tiyajamorn N, Kajiwara T, Arase Y, et al. EMNLP 2021. [Paper]
-
"An Isotropy Analysis in the Multilingual BERT Embedding Space".
Rajaee S, Pilehvar M T. ACL 2022. [Paper]
-
"Discovering Low-rank Subspaces for Language-agnostic Multilingual Representations".
Xie Z, Zhao H, Yu T, et al. EMNLP 2022. [Paper]
-
"Emerging Cross-lingual Structure in Pretrained Language Models".
Conneau A, Wu S, Li H, et al. ACL 2020. [Paper]
-
"Probing LLMs for Joint Encoding of Linguistic Categories".
Starace G, Papakostas K, Choenni R, et al. EMNLP 2023. [Paper]
-
"Morph Call: Probing Morphosyntactic Content of Multilingual Transformers".
Mikhailov V, Serikov O, Artemova E. Proceedings of the Third Workshop on Computational Typology and Multilingual NLP 2021. [Paper]
-
"Same Neurons, Different Languages: Probing Morphosyntax in Multilingual Pre-trained Models".
Stanczak K, Ponti E, Hennigen L T, et al. NAACL 2022. [Paper]
-
"Probing Cross-Lingual Lexical Knowledge from Multilingual Sentence Encoders".
Vulić I, Glavaš G, Liu F, et al. EACL 2023. [Paper]
-
"The Emergence of Semantic Units in Massively Multilingual Models".
de Varda A G, Marelli M. LREC-COLING 2024. [Paper]
-
"X-FACTR: Multilingual Factual Knowledge Retrieval from Pretrained Language Models".
Jiang Z, Anastasopoulos A, Araki J, et al. EMNLP 2020. [Paper]
-
"Multilingual LAMA: Investigating Knowledge in Multilingual Pretrained Language Models".
Kassner N, Dufter P, Schütze H. EACL 2021. [Paper]
-
"Cross-Lingual Consistency of Factual Knowledge in Multilingual Language Models".
Qi J, Fernández R, Bisazza A. EMNLP 2023. [Paper]
-
"Language Representation Projection: Can We Transfer Factual Knowledge across Languages in Multilingual Language Models?".
Xu S, Li J, Xiong D. EMNLP 2023. [Paper]
Interpretability of Cross-lingual Transfer
-
"Are Structural Concepts Universal in Transformer Language Models? Towards Interpretable Cross-Lingual Generalization"
Xu N, Zhang Q, Ye J, et al. EMNLP 2023. [Paper]
-
"When is BERT Multilingual? Isolating Crucial Ingredients for Cross-lingual Transfer".
Deshpande A, Talukdar P, Narasimhan K. NAACL 2022. [Paper]
-
"Emerging Cross-lingual Structure in Pretrained Language Models".
Conneau A, Wu S, Li H, et al. ACL 2020. [Paper]
-
"Cross-Lingual Ability of Multilingual BERT: An Empirical Study".
Karthikeyan K, Wang Z, Mayhew S, et al. ICLR 2020. [Paper]
-
"Unveiling Linguistic Regions in Large Language Models".
Zhang Z, Zhao J, Zhang Q, et al. ACL 2024. [Paper]
-
"Unraveling Babel: Exploring Multilingual Activation Patterns of LLMs and Their Applications".
Liu W, Xu Y, Xu H, et al. EMNLP 2024. [Paper]
-
"The Geometry of Multilingual Language Model Representations".
Chang T, Tu Z, Bergen B. EMNLP 2022. [Paper]
Interpretability of Linguistic Bias
-
"How do Large Language Models Handle Multilingualism?".
Zhao Y, Zhang W, Chen G, et al. arXiv 2024. [Paper]
-
"Do Llamas Work in English? On the Latent Language of Multilingual Transformers".
Wendler C, Veselovsky V, Monea G, et al. ACL 2024. [Paper]
Applications of MLLMs
MLLMs for Biology and Medicine
-
"Biobert: a pre-trained biomedical language representation model for biomedical text mining."
-
"DNABERT: pre-trained bidirectional encoder representations from transformers model for dna-language in genome."
-
"DNABERT-2: efficient foundation model and benchmark for multi-species genome."
-
"MING-MOE: enhancing medical multi-task learning in large language models with sparse mixture of low-rank adapter experts."
-
"Doctorglm: Fine-tuning your chinese doctor is not a herculean task."
-
"Huatuogpt, towards taming language model to be a doctor."
-
"Medgpt: Medical concept prediction from clinical narratives."
Zeljko Kraljevic et al. arXiv 2021 [paper]
-
"Clinicalgpt: Large language models finetuned with diverse medical data and comprehensive evaluation."
Guangyu Wang et al. arXiv 2023 [paper]
-
"Ivygpt: Interactive chinese pathway language model in medical domain."
-
"Bianque: Balancing the questioning and suggestion ability of health llms with multi-turn health conversations polished by chatgpt."
-
"Soulchat: Improving llms’ empathy, listening, and comfort abilities through fine-tuning with multi-turn empathy conversations."
-
"Towards expert-level medical question answering with large language models."
-
"Chatdoctor: A medical chat model fine-tuned on llama model using medical domain knowledge."
Yunxiang Li et al. arXiv 2023 [paper] [[github](Chatdoctor: A medical chat model fine-tuned on llama model using medical domain knowledge)]
MLLMs for Computer Science
-
"Codebert: A pre-trained model for programming and natural languages."
-
"Learning and evaluating contextual embedding of source code."
-
"Unified pre-training for program understanding and generation."
-
"Codet5: Identifier-aware unified pre-trained encoder-decoder models for code understanding and generation."
-
"Codet5+: Open code large language models for code understanding and generation."
-
"Competition-level code generation with alphacode"
-
"Evaluating large language models trained on code."
-
"A systematic evaluation of large language models of code."
-
"Codegen: An open large language model for code with multi-turn program synthesis."
-
"A generative model for code infilling and synthesis."
-
"Code llama: Open foundation models for code."
-
"Starcoder: may the source be with you!"
-
"CodeGeeX: A pretrained model for code generation with multilingual benchmarking on humaneval-x."
-
"Codeshell technical report."
-
"CodeGemma: Open Code Models Based on Gemma"
-
"Qwen2.5-Coder Technical Report."
MLLMs for Mathematics
-
"Tree-based representation and generation of natural and mathematical language."
-
"Chatglm-math: Improving math problem-solving in large language models with a self-critique pipeline."
-
"Deepseek-math: Pushing the limits of mathematical reasoning in open language models."
-
"Metamath: Bootstrap your own mathematical questions for large language models."
-
"Mammoth: Building math generalist models through hybrid instruction tuning."
-
"Wizardmath: Empowering mathematical reasoning for large language models via reinforced evol-instruct."
-
"Generative ai for math: Abel."
Ethan Chern et al. GitHub 2023 [github]
-
"Orca-math: Unlocking the potential of slms in grade school math."
MLLMs for Law
-
"LEGAL-BERT: the muppets straight out of law school."
-
"Lawformer: A pre-trained language model for chinese legal long documents."
-
"A brief report on lawgpt 1.0: A virtual legal assistant based on GPT-3."
Ha-Thanh Nguyen arXiv 2023 [paper]
-
"Disc-lawllm: Fine-tuning large language models for intelligent legal services."
-
"Chatlaw: Open-source legal large language model with integrated external knowledge bases."
-
"SAILER: structure-aware pre-trained language model for legal case retrieval."
-
"Lawyer llama technical report."
-
"Legal-relectra: Mixeddomain language modeling for long-range legal text comprehension."
Wenyue Hua et al. arXiv 2022 [paper]
Similar repos
Contributors
17 commits