
README
Puro-Megatron
Puro-Megatron is a focused patch series on top of
NVIDIA Megatron-LM core_v0.16.0,
forked at commit 3bec9aa97dda898d16ff5a89bac0ed2b6682b172.
The public diff keeps the training capabilities used by Puro:
- packed NPY pretraining data and resume-safe phase transitions;
- MuonHyperball with correct AdamW routing for normalization, embedding, bias, output, and other non-matrix parameters;
- logical Q/K/V and SwiGLU normalization/Newton-Schulz modes, plus optional fixed-RMS MuonHyperball radii;
- effective-LR controls and the open-ended power LR schedule;
- memory-balanced layer-wise distributed optimizer state;
- blockwise-FP8 and non-persistent checkpoint compatibility;
- data-corruption-safe rerun skipping; and
- a structured startup theoretical FLOPs report.
The source commits and scope decisions are recorded in
Origin commits. See
Puro-Megatron extensions for the supported interfaces
and examples/puro/run_puro_2b.sh for the
launcher-neutral Puro-2B recipes.
The complete public patch can always be inspected with:
git diff core_v0.16.0..main
git log --reverse core_v0.16.0..main
Upstream Megatron-LM README
Megatron-LM and Megatron Core
GPU-optimized library for training transformer models at scale


About
This repository contains two components: Megatron-LM and Megatron Core.
Megatron-LM is a reference example that includes Megatron Core plus pre-configured training scripts. Best for research teams, learning distributed training, and quick experimentation.
Megatron Core is a composable library with GPU-optimized building blocks for custom training frameworks. It provides transformer building blocks, advanced parallelism strategies (TP, PP, DP, EP, CP), mixed precision support (FP16, BF16, FP8, FP4), and model architectures. Best for framework developers and ML engineers building custom training pipelines.
Megatron Bridge provides bidirectional Hugging Face ↔ Megatron checkpoint conversion with production-ready recipes.
Quick Start
Install Megatron Core with pip:
-
Install Megatron Core with required dependencies:
pip install --no-build-isolation megatron-core[mlm,dev] -
Clone repository for examples:
git clone https://github.com/NVIDIA/Megatron-LM.git
cd Megatron-LM
pip install --no-build-isolation .[mlm,dev]
Latest News
- [2026/01] Dynamic Context Parallelism - Up to 1.48x speedup for variable-length sequence training with adaptive CP sizing.
- [2025/12] Megatron Core development has moved to GitHub! All development and CI now happens in the open. We welcome community contributions.
- [2025/10] Megatron Dev Branch - early access branch with experimental features.
- [2025/10] Megatron Bridge - Bidirectional converter for interoperability between Hugging Face and Megatron checkpoints, featuring production-ready recipes for popular models.
- [2025/08] MoE Q3-Q4 2025 Roadmap - Comprehensive roadmap for MoE features including DeepSeek-V3, Qwen3, advanced parallelism strategies, FP8 optimizations, and Blackwell performance enhancements.
- [2025/08] GPT-OSS Model - Advanced features including YaRN RoPE scaling, attention sinks, and custom activation functions are being integrated into Megatron Core.
- [2025/06] Megatron MoE Model Zoo - Best practices and optimized configurations for training DeepSeek-V3, Mixtral, and Qwen3 MoE models with performance benchmarking and checkpoint conversion tools.
- [2025/05] Megatron Core v0.11.0 brings new capabilities for multi-data center LLM training (blog).
Previous News
- [2024/07] Megatron Core v0.7 improves scalability and training resiliency and adds support for multimodal training (blog).
- [2024/06] Megatron Core added supports for Mamba-based models. Check out our paper An Empirical Study of Mamba-based Language Models and code example.
- [2024/01 Announcement] NVIDIA has released the core capabilities in Megatron-LM into Megatron Core in this repository. Megatron Core expands upon Megatron-LM's GPU-optimized techniques with more cutting-edge innovations on system-level optimizations, featuring composable and modular APIs.
Project Structure
Megatron-LM/
├── megatron/
│   ├── core/                    # Megatron Core (kernels, parallelism, building blocks)
│   │   ├── models/              # Transformer models
│   │   ├── transformer/         # Transformer building blocks
│   │   ├── tensor_parallel/     # Tensor parallelism
│   │   ├── pipeline_parallel/   # Pipeline parallelism
│   │   ├── distributed/         # Distributed training (FSDP, DDP)
│   │   ├── optimizer/           # Optimizers
│   │   ├── datasets/            # Dataset loaders
│   │   ├── inference/           # Inference engines
│   │   └── export/              # Model export (e.g. TensorRT-LLM)
│   ├── training/                # Training scripts
│   ├── inference/               # Inference server
│   ├── legacy/                  # Legacy components
│   └── post_training/           # Post-training (RLHF, etc.)
├── examples/                    # Ready-to-use training examples
├── tools/                       # Utility tools
├── tests/                       # Comprehensive test suite
└── docs/                        # Documentation
Performance Benchmarking
For our latest performance benchmarking results, please refer to NVIDIA Megatron Bridge Performance Summary.
Our codebase efficiently trains models from 2B to 462B parameters across thousands of GPUs, achieving up to 47% Model FLOP Utilization (MFU) on H100 clusters.
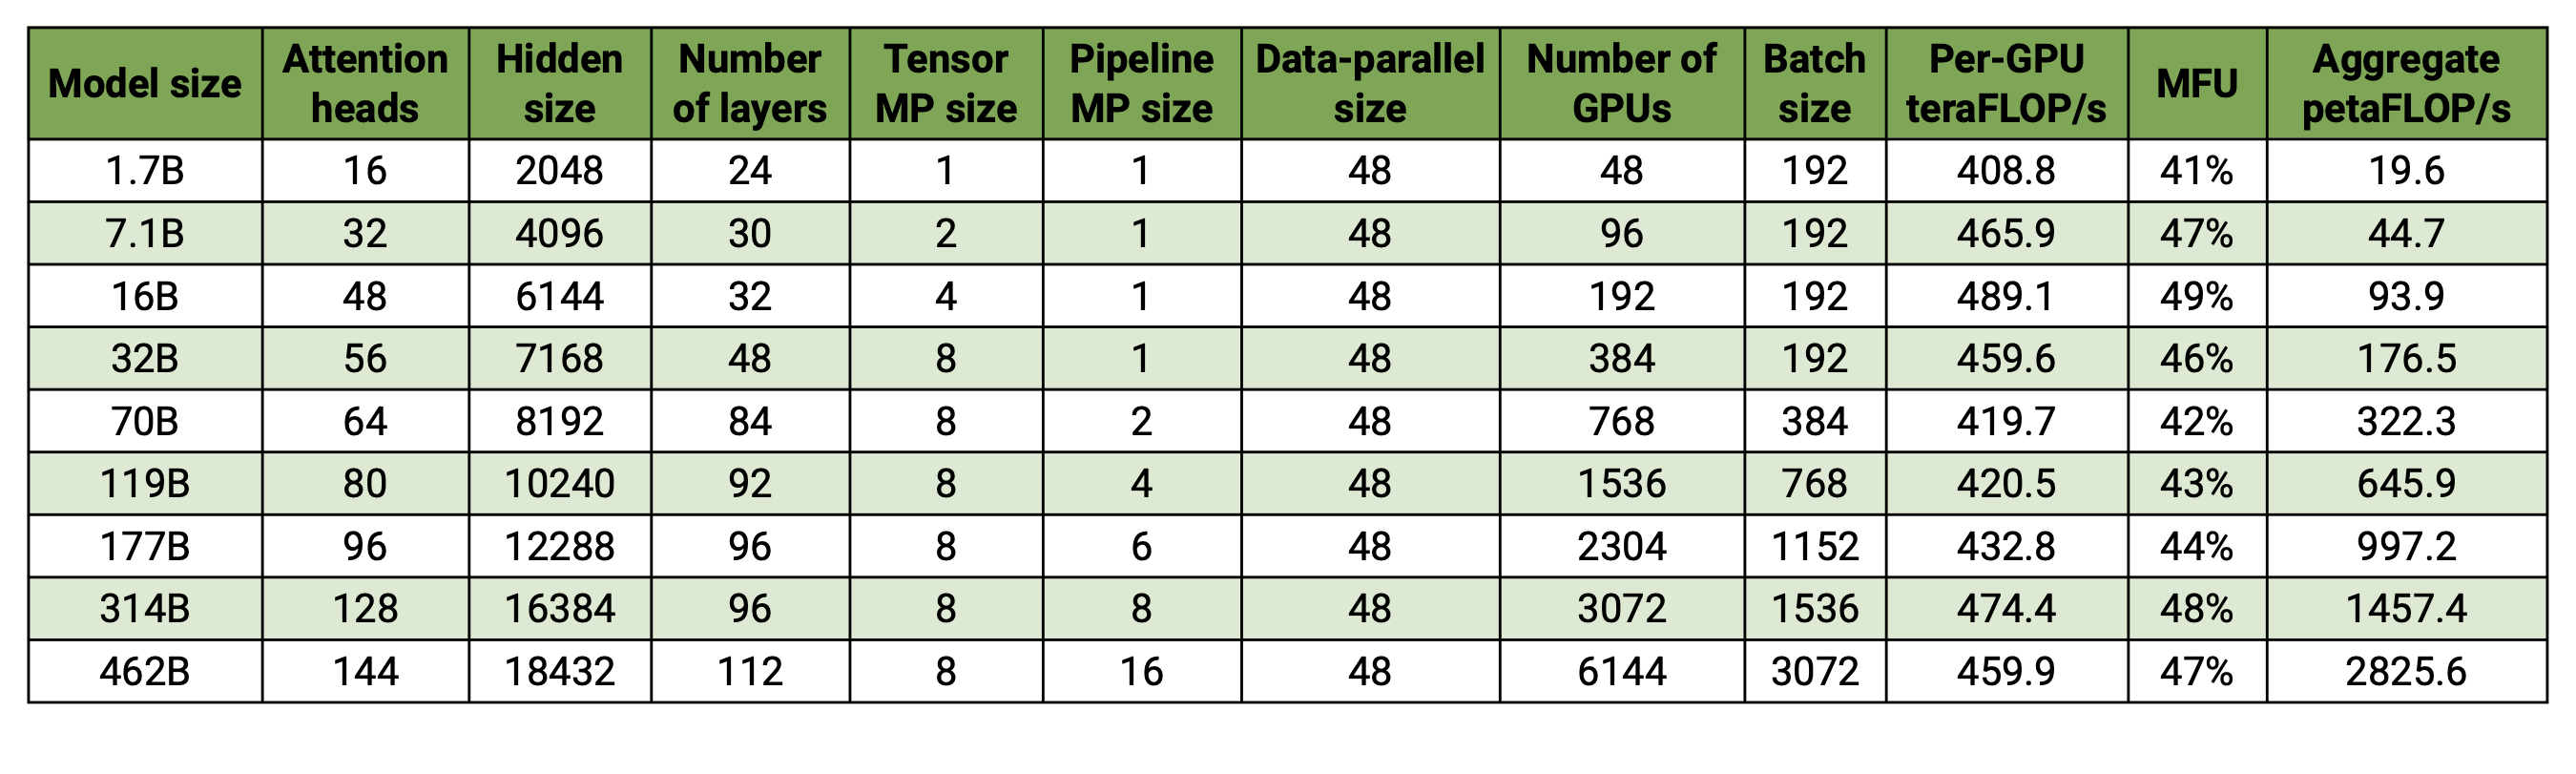
Benchmark Configuration:
- Vocabulary size: 131,072 tokens
- Sequence length: 4096 tokens
- Model scaling: Varied hidden size, attention heads, and layers to achieve target parameter counts
- Communication optimizations: Fine-grained overlapping with DP (
--overlap-grad-reduce,--overlap-param-gather), TP (--tp-comm-overlap), and PP (enabled by default)
Key Results:
- 6144 H100 GPUs: Successfully benchmarked 462B parameter model training
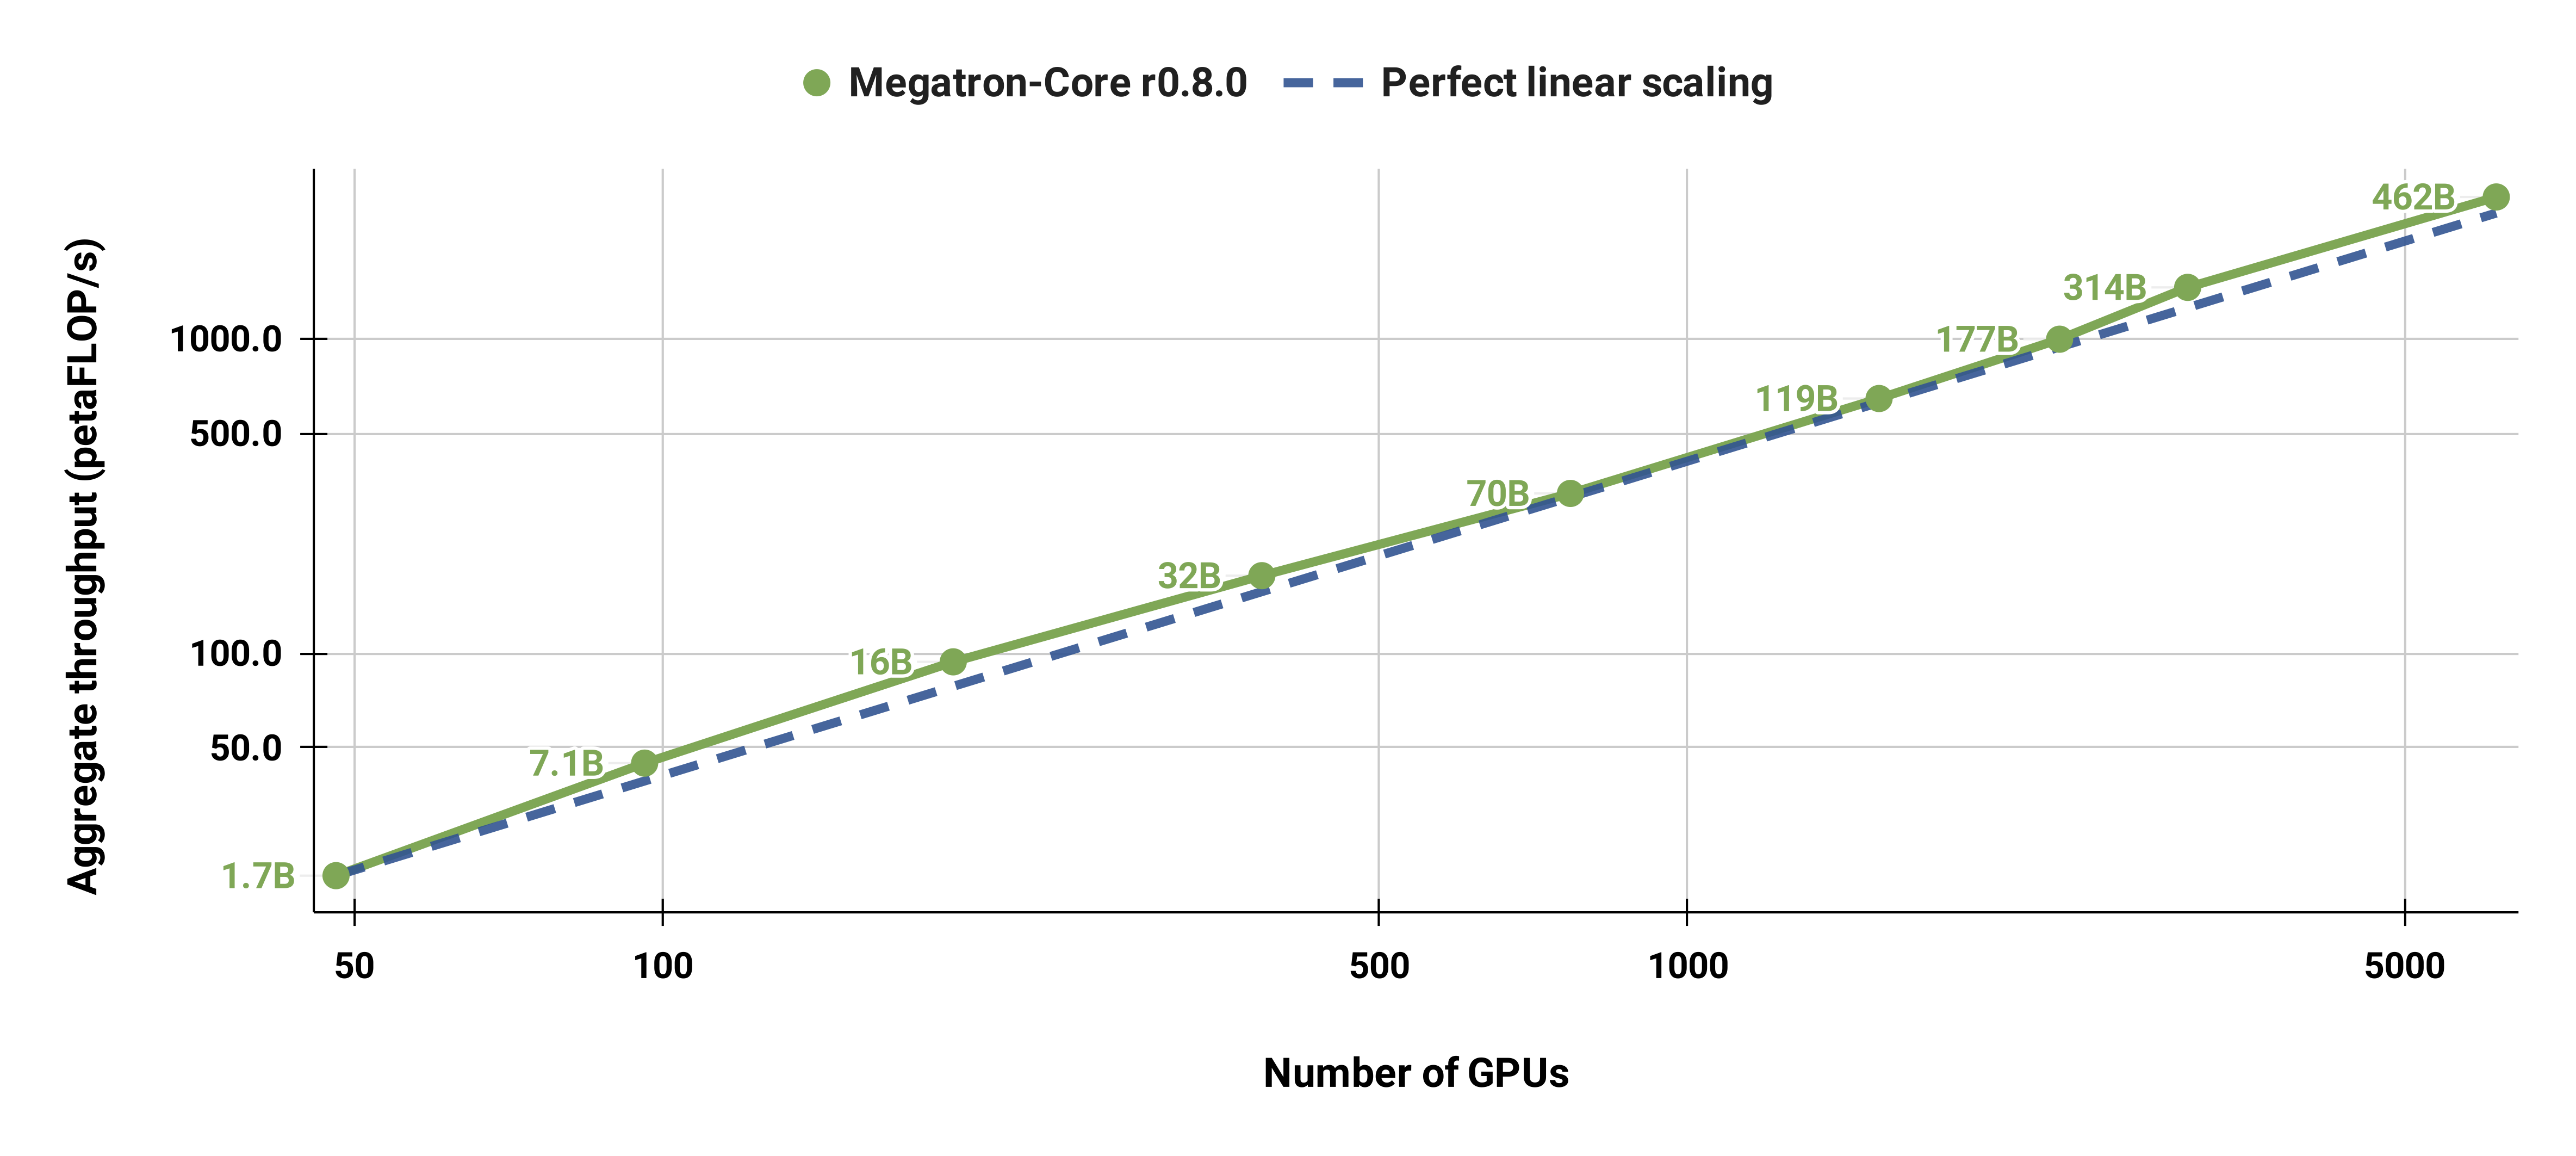
- Superlinear scaling: MFU increases from 41% to 47-48% with model size
- End-to-end measurement: Throughputs include all operations (data loading, optimizer steps, communication, logging)
- Production ready: Full training pipeline with checkpointing and fault tolerance
- Note: Performance results measured without training to convergence
Weak Scaling Results
Our weak scaled results show superlinear scaling (MFU increases from 41% for the smallest model considered to 47-48% for the largest models); this is because larger GEMMs have higher arithmetic intensity and are consequently more efficient to execute.
Strong Scaling Results
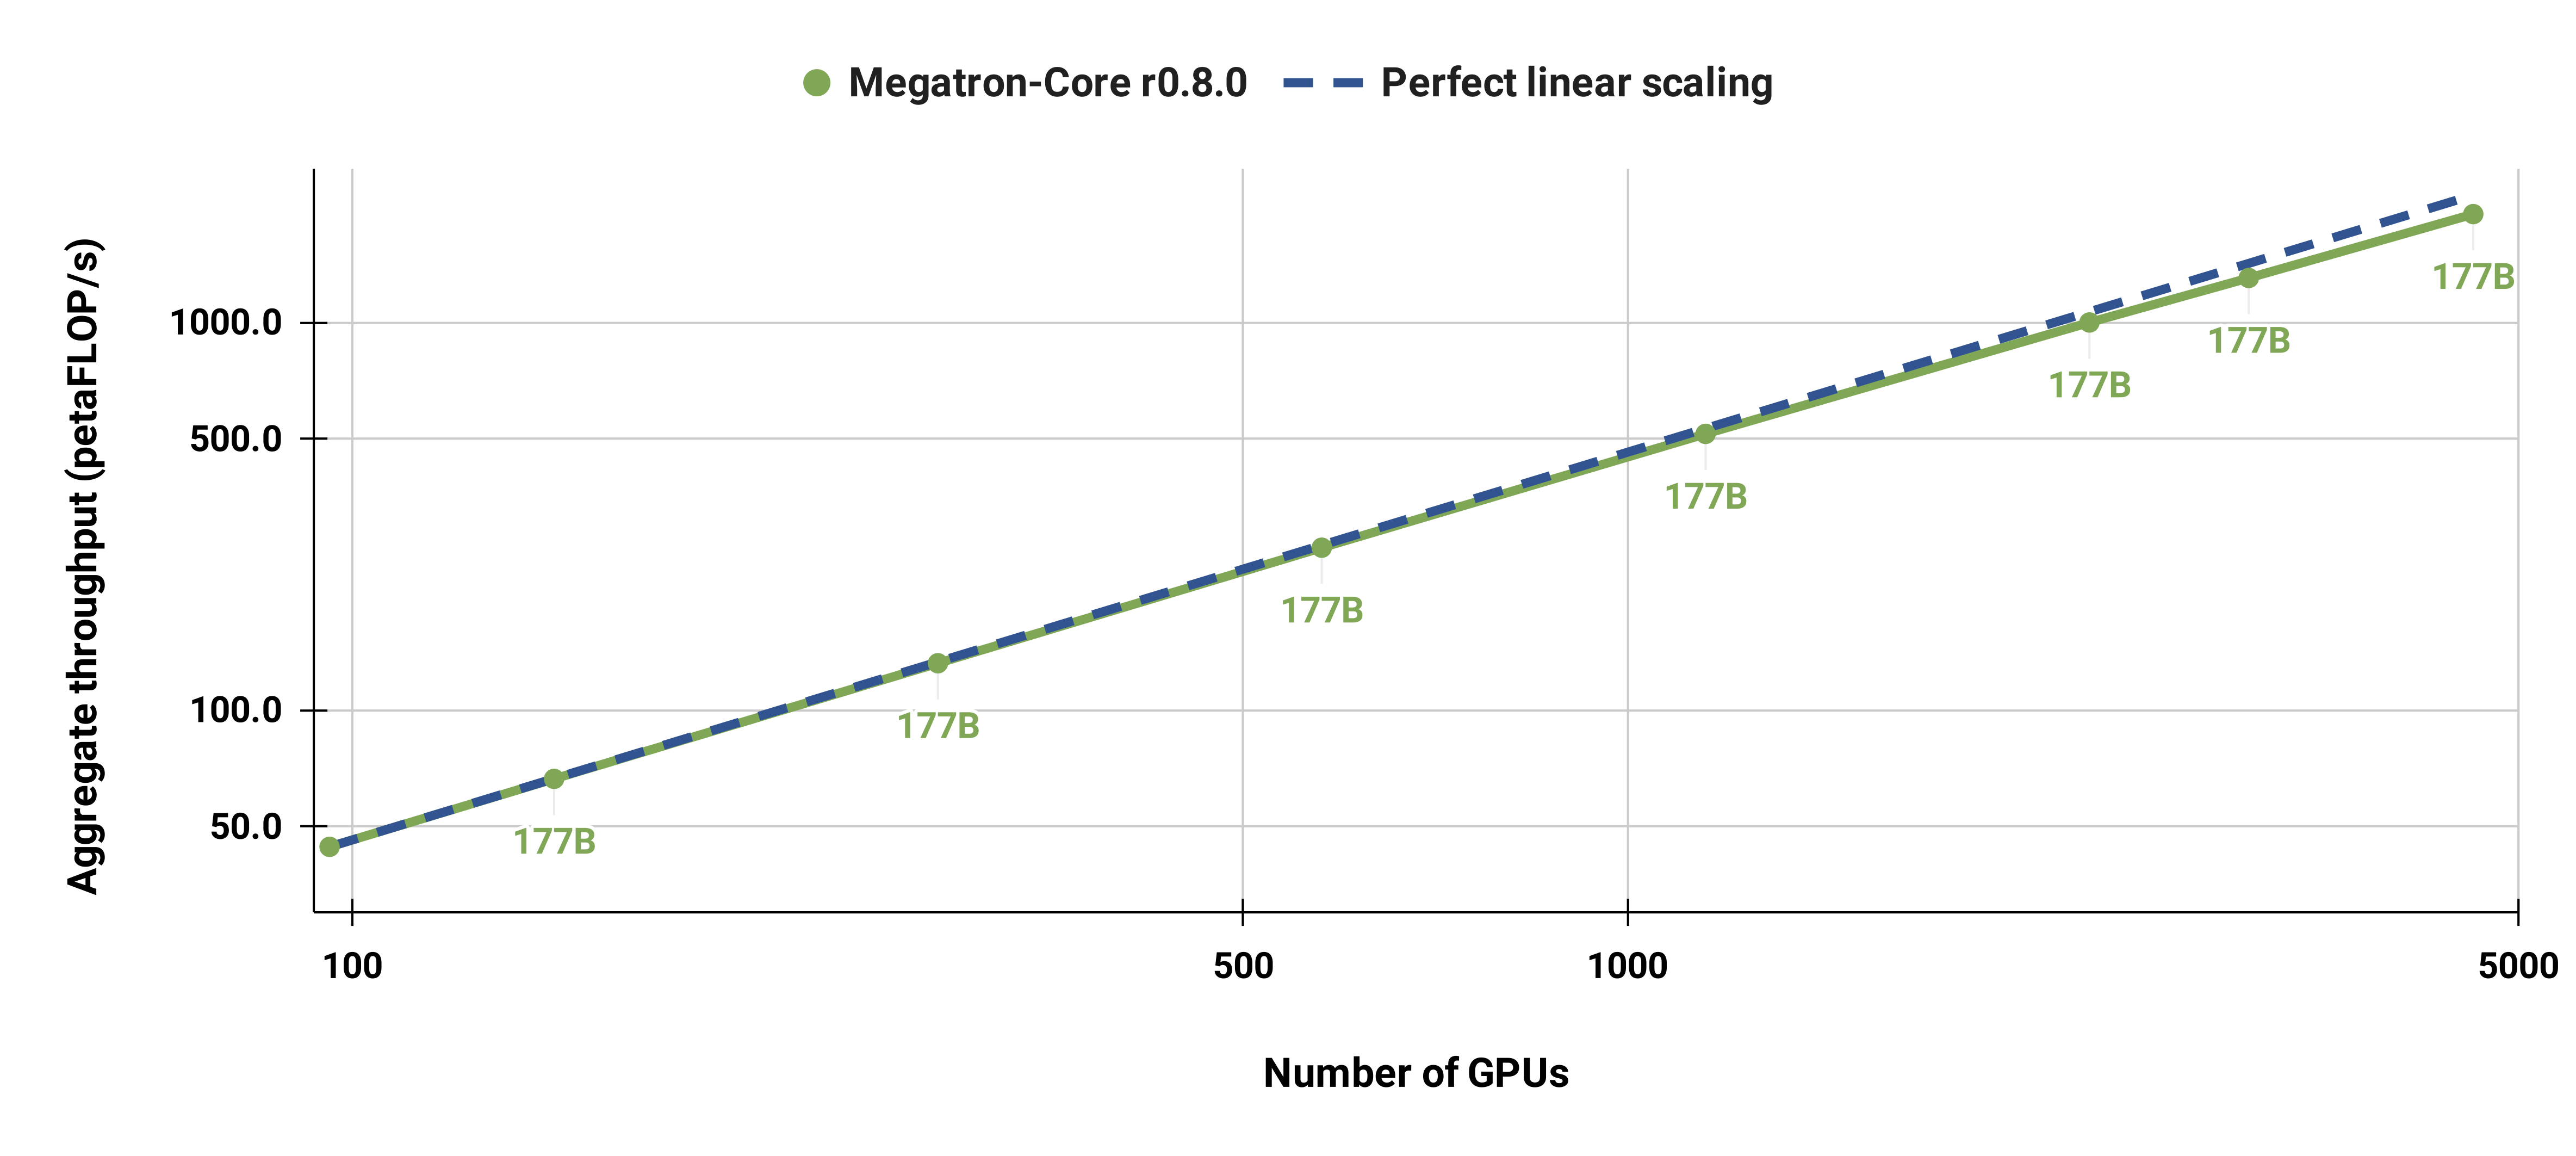
We also strong scaled the standard GPT-3 model (our version has slightly more than 175 billion parameters due to larger vocabulary size) from 96 H100 GPUs to 4608 GPUs, using the same batch size of 1152 sequences throughout. Communication becomes more exposed at larger scale, leading to a reduction in MFU from 47% to 42%.
Roadmaps
- MoE Roadmap - DeepSeek-V3, Qwen3, advanced parallelism, FP8 optimizations, and Blackwell enhancements
Resources
Getting Help
- 📖 Documentation - Official documentation
- 🐛 Issues - Bug reports and feature requests
Contributing
We ❤️ contributions! Ways to contribute:
- 🐛 Report bugs - Help us improve reliability
- 💡 Suggest features - Shape the future of Megatron Core
- 📝 Improve docs - Make Megatron Core more accessible
- 🔧 Submit PRs - Contribute code improvements
Citation
If you use Megatron in your research or project, we appreciate that you use the following citations:
@article{megatron-lm,
  title={Megatron-LM: Training Multi-Billion Parameter Language Models Using Model Parallelism},
  author={Shoeybi, Mohammad and Patwary, Mostofa and Puri, Raul and LeGresley, Patrick and Casper, Jared and Catanzaro, Bryan},
  journal={arXiv preprint arXiv:1909.08053},
  year={2019}
}
Contributors
(top 30 of 231)


Similar repos


Languages
Python
99.0%
README
Puro-Megatron
Puro-Megatron is a focused patch series on top of
NVIDIA Megatron-LM core_v0.16.0,
forked at commit 3bec9aa97dda898d16ff5a89bac0ed2b6682b172.
The public diff keeps the training capabilities used by Puro:
- packed NPY pretraining data and resume-safe phase transitions;
- MuonHyperball with correct AdamW routing for normalization, embedding, bias, output, and other non-matrix parameters;
- logical Q/K/V and SwiGLU normalization/Newton-Schulz modes, plus optional fixed-RMS MuonHyperball radii;
- effective-LR controls and the open-ended power LR schedule;
- memory-balanced layer-wise distributed optimizer state;
- blockwise-FP8 and non-persistent checkpoint compatibility;
- data-corruption-safe rerun skipping; and
- a structured startup theoretical FLOPs report.
The source commits and scope decisions are recorded in
Origin commits. See
Puro-Megatron extensions for the supported interfaces
and examples/puro/run_puro_2b.sh for the
launcher-neutral Puro-2B recipes.
The complete public patch can always be inspected with:
git diff core_v0.16.0..main
git log --reverse core_v0.16.0..main
Upstream Megatron-LM README
Megatron-LM and Megatron Core
GPU-optimized library for training transformer models at scale
About
This repository contains two components: Megatron-LM and Megatron Core.
Megatron-LM is a reference example that includes Megatron Core plus pre-configured training scripts. Best for research teams, learning distributed training, and quick experimentation.
Megatron Core is a composable library with GPU-optimized building blocks for custom training frameworks. It provides transformer building blocks, advanced parallelism strategies (TP, PP, DP, EP, CP), mixed precision support (FP16, BF16, FP8, FP4), and model architectures. Best for framework developers and ML engineers building custom training pipelines.
Megatron Bridge provides bidirectional Hugging Face ↔ Megatron checkpoint conversion with production-ready recipes.
Quick Start
Install Megatron Core with pip:
-
Install Megatron Core with required dependencies:
pip install --no-build-isolation megatron-core[mlm,dev] -
Clone repository for examples:
git clone https://github.com/NVIDIA/Megatron-LM.git
cd Megatron-LM
pip install --no-build-isolation .[mlm,dev]
Latest News
- [2026/01] Dynamic Context Parallelism - Up to 1.48x speedup for variable-length sequence training with adaptive CP sizing.
- [2025/12] Megatron Core development has moved to GitHub! All development and CI now happens in the open. We welcome community contributions.
- [2025/10] Megatron Dev Branch - early access branch with experimental features.
- [2025/10] Megatron Bridge - Bidirectional converter for interoperability between Hugging Face and Megatron checkpoints, featuring production-ready recipes for popular models.
- [2025/08] MoE Q3-Q4 2025 Roadmap - Comprehensive roadmap for MoE features including DeepSeek-V3, Qwen3, advanced parallelism strategies, FP8 optimizations, and Blackwell performance enhancements.
- [2025/08] GPT-OSS Model - Advanced features including YaRN RoPE scaling, attention sinks, and custom activation functions are being integrated into Megatron Core.
- [2025/06] Megatron MoE Model Zoo - Best practices and optimized configurations for training DeepSeek-V3, Mixtral, and Qwen3 MoE models with performance benchmarking and checkpoint conversion tools.
- [2025/05] Megatron Core v0.11.0 brings new capabilities for multi-data center LLM training (blog).
Previous News
- [2024/07] Megatron Core v0.7 improves scalability and training resiliency and adds support for multimodal training (blog).
- [2024/06] Megatron Core added supports for Mamba-based models. Check out our paper An Empirical Study of Mamba-based Language Models and code example.
- [2024/01 Announcement] NVIDIA has released the core capabilities in Megatron-LM into Megatron Core in this repository. Megatron Core expands upon Megatron-LM's GPU-optimized techniques with more cutting-edge innovations on system-level optimizations, featuring composable and modular APIs.
Project Structure
Megatron-LM/
├── megatron/
│   ├── core/                    # Megatron Core (kernels, parallelism, building blocks)
│   │   ├── models/              # Transformer models
│   │   ├── transformer/         # Transformer building blocks
│   │   ├── tensor_parallel/     # Tensor parallelism
│   │   ├── pipeline_parallel/   # Pipeline parallelism
│   │   ├── distributed/         # Distributed training (FSDP, DDP)
│   │   ├── optimizer/           # Optimizers
│   │   ├── datasets/            # Dataset loaders
│   │   ├── inference/           # Inference engines
│   │   └── export/              # Model export (e.g. TensorRT-LLM)
│   ├── training/                # Training scripts
│   ├── inference/               # Inference server
│   ├── legacy/                  # Legacy components
│   └── post_training/           # Post-training (RLHF, etc.)
├── examples/                    # Ready-to-use training examples
├── tools/                       # Utility tools
├── tests/                       # Comprehensive test suite
└── docs/                        # Documentation
Performance Benchmarking
For our latest performance benchmarking results, please refer to NVIDIA Megatron Bridge Performance Summary.
Our codebase efficiently trains models from 2B to 462B parameters across thousands of GPUs, achieving up to 47% Model FLOP Utilization (MFU) on H100 clusters.
Benchmark Configuration:
- Vocabulary size: 131,072 tokens
- Sequence length: 4096 tokens
- Model scaling: Varied hidden size, attention heads, and layers to achieve target parameter counts
- Communication optimizations: Fine-grained overlapping with DP (
--overlap-grad-reduce,--overlap-param-gather), TP (--tp-comm-overlap), and PP (enabled by default)
Key Results:
- 6144 H100 GPUs: Successfully benchmarked 462B parameter model training
- Superlinear scaling: MFU increases from 41% to 47-48% with model size
- End-to-end measurement: Throughputs include all operations (data loading, optimizer steps, communication, logging)
- Production ready: Full training pipeline with checkpointing and fault tolerance
- Note: Performance results measured without training to convergence
Weak Scaling Results
Our weak scaled results show superlinear scaling (MFU increases from 41% for the smallest model considered to 47-48% for the largest models); this is because larger GEMMs have higher arithmetic intensity and are consequently more efficient to execute.
Strong Scaling Results
We also strong scaled the standard GPT-3 model (our version has slightly more than 175 billion parameters due to larger vocabulary size) from 96 H100 GPUs to 4608 GPUs, using the same batch size of 1152 sequences throughout. Communication becomes more exposed at larger scale, leading to a reduction in MFU from 47% to 42%.
Roadmaps
- MoE Roadmap - DeepSeek-V3, Qwen3, advanced parallelism, FP8 optimizations, and Blackwell enhancements
Resources
Getting Help
- 📖 Documentation - Official documentation
- 🐛 Issues - Bug reports and feature requests
Contributing
We ❤️ contributions! Ways to contribute:
- 🐛 Report bugs - Help us improve reliability
- 💡 Suggest features - Shape the future of Megatron Core
- 📝 Improve docs - Make Megatron Core more accessible
- 🔧 Submit PRs - Contribute code improvements
Citation
If you use Megatron in your research or project, we appreciate that you use the following citations:
@article{megatron-lm,
  title={Megatron-LM: Training Multi-Billion Parameter Language Models Using Model Parallelism},
  author={Shoeybi, Mohammad and Patwary, Mostofa and Puri, Raul and LeGresley, Patrick and Casper, Jared and Catanzaro, Bryan},
  journal={arXiv preprint arXiv:1909.08053},
  year={2019}
}
Similar repos
Contributors
(top 30 of 231)
Languages
Python
99.0%