A Large-Scale Chinese Cross-Domain Task-Oriented Dialogue Dataset
Python
728
37 commits
updated Jun 17, 2024
CrossWOZ is the first large-scale Chinese Cross-Domain Wizard-of-Oz task-oriented dataset. It contains 6K dialogue sessions and 102K utterances for 5 domains, including hotel, restaurant, attraction, metro, and taxi. Moreover, the corpus contains rich annotation of dialogue states and dialogue acts at both user and system sides. We also provide a user simulator and several benchmark models for pipelined taskoriented dialogue systems, which will facilitate researchers to compare and evaluate their models on this corpus.
Refer to our paper for more details: CrossWOZ: A Large-Scale Chinese Cross-Domain Task-Oriented Dialogue Dataset (accepted by TACL)
If you have any question, feel free to open an issue.
We also release our annotation platform (Sep 10, 2021), supporting two annotators converse synchronously and make annotations online. Please refer to the web directory.
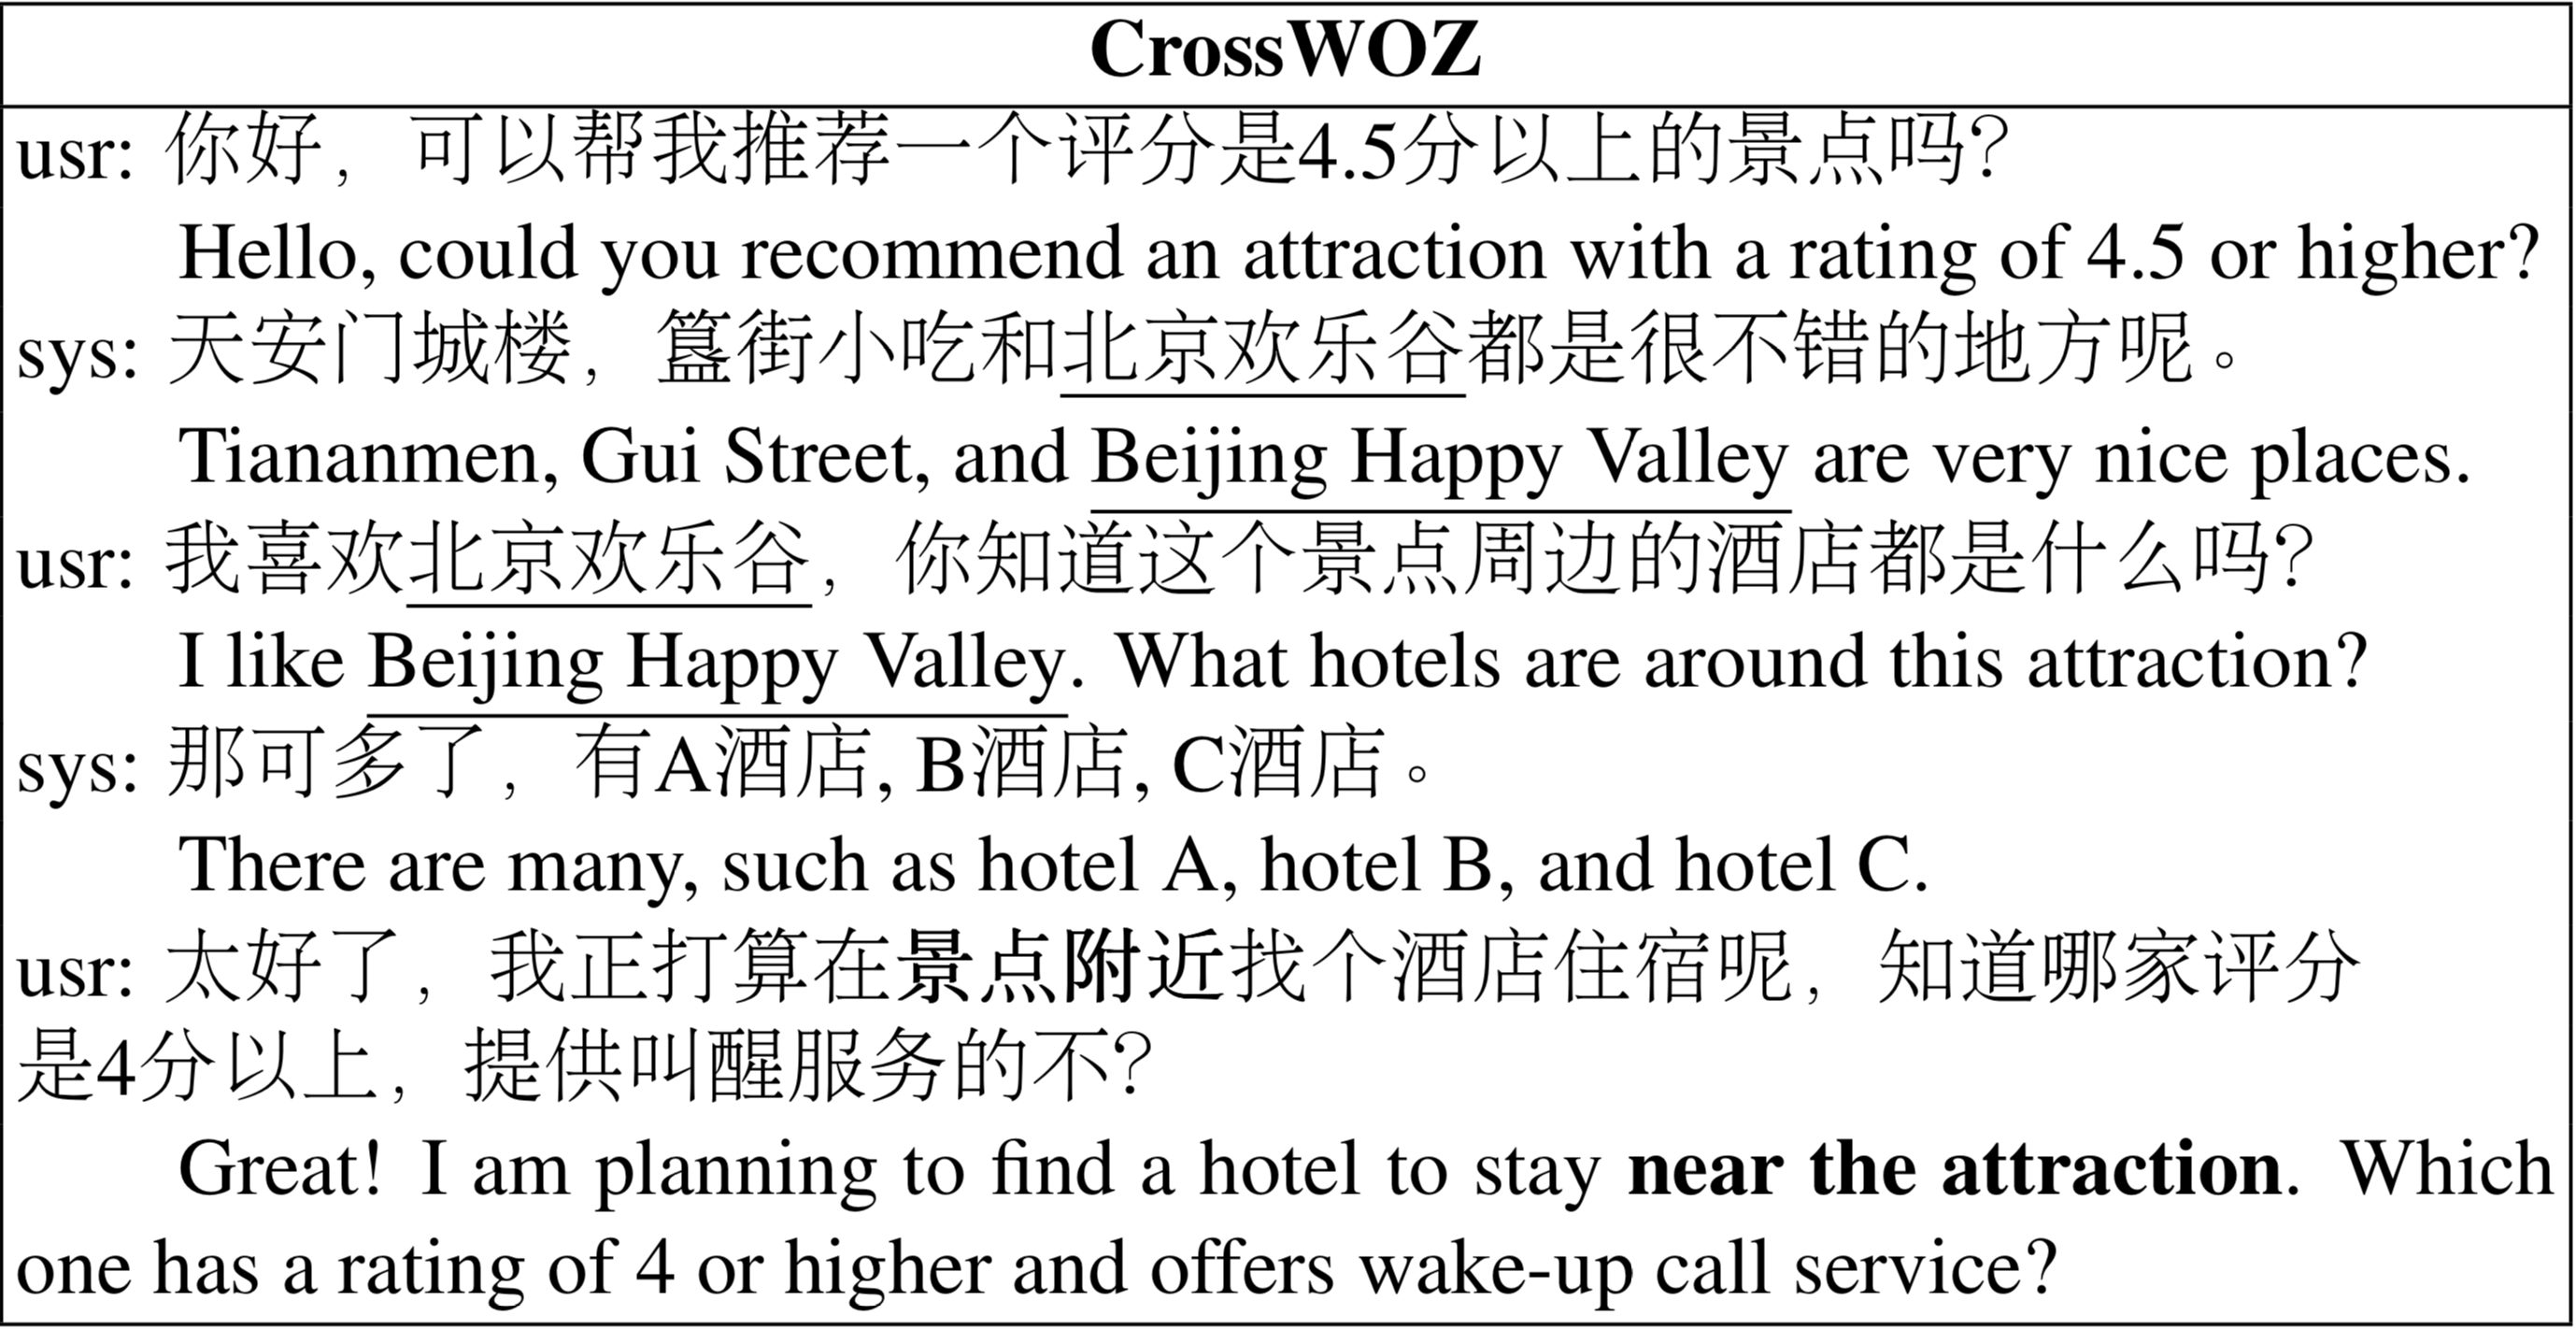
A piece of dialogue: (Names of hotels are replaced by A,B,C for simplicity.)
In data/crosswoz directory. Data statistics:
| Split | Train | Valid | Test |
|---|---|---|---|
| # dialogues | 5,012 | 500 | 500 |
| # Turns (utterances) | 84,692 | 8,458 | 8,476 |
| Vocab | 12,502 | 5,202 | 5,143 |
| Avg. sub-goals | 3.24 | 3.26 | 3.26 |
| Avg. semantic tuples | 14.8 | 14.9 | 15.0 |
| Avg. turns | 16.9 | 16.9 | 17.0 |
| Avg. tokens per turn | 16.3 | 16.3 | 16.2 |
According to the type of user goal, we group the dialogues in the training set into five categories:
Statistics for dialogues of different goal types in the training set:
| Goal type | S | M | M+T | CM | CM+T |
|---|---|---|---|---|---|
| # dialogues | 417 | 1573 | 691 | 1759 | 572 |
| NoOffer rate | 0.10 | 0.22 | 0.22 | 0.61 | 0.55 |
| Multi-query rate | 0.06 | 0.07 | 0.07 | 0.14 | 0.12 |
| Goal change rate | 0.10 | 0.28 | 0.31 | 0.69 | 0.63 |
| Avg. dialogue acts | 1.85 | 1.90 | 2.09 | 2.06 | 2.11 |
| Avg. sub-goals | 1.00 | 2.49 | 3.62 | 3.87 | 4.57 |
| Avg. semantic tuples | 4.5 | 11.3 | 15.8 | 18.2 | 20.7 |
| Avg. turns | 6.8 | 13.7 | 16.0 | 21.0 | 21.6 |
| Avg. tokens per turn | 13.2 | 15.2 | 16.3 | 16.9 | 17.0 |
We also provide database in data/crosswoz/database.
please install via:
pip install -e .
Code:
convlab2/nlu/jointBERT/crosswoz
convlab2/dst/rule/crosswozconvlab2/dst/trade/crosswoz
convlab2/policy/mle/crosswoz
convlab2/nlg/sclstm/crosswoz
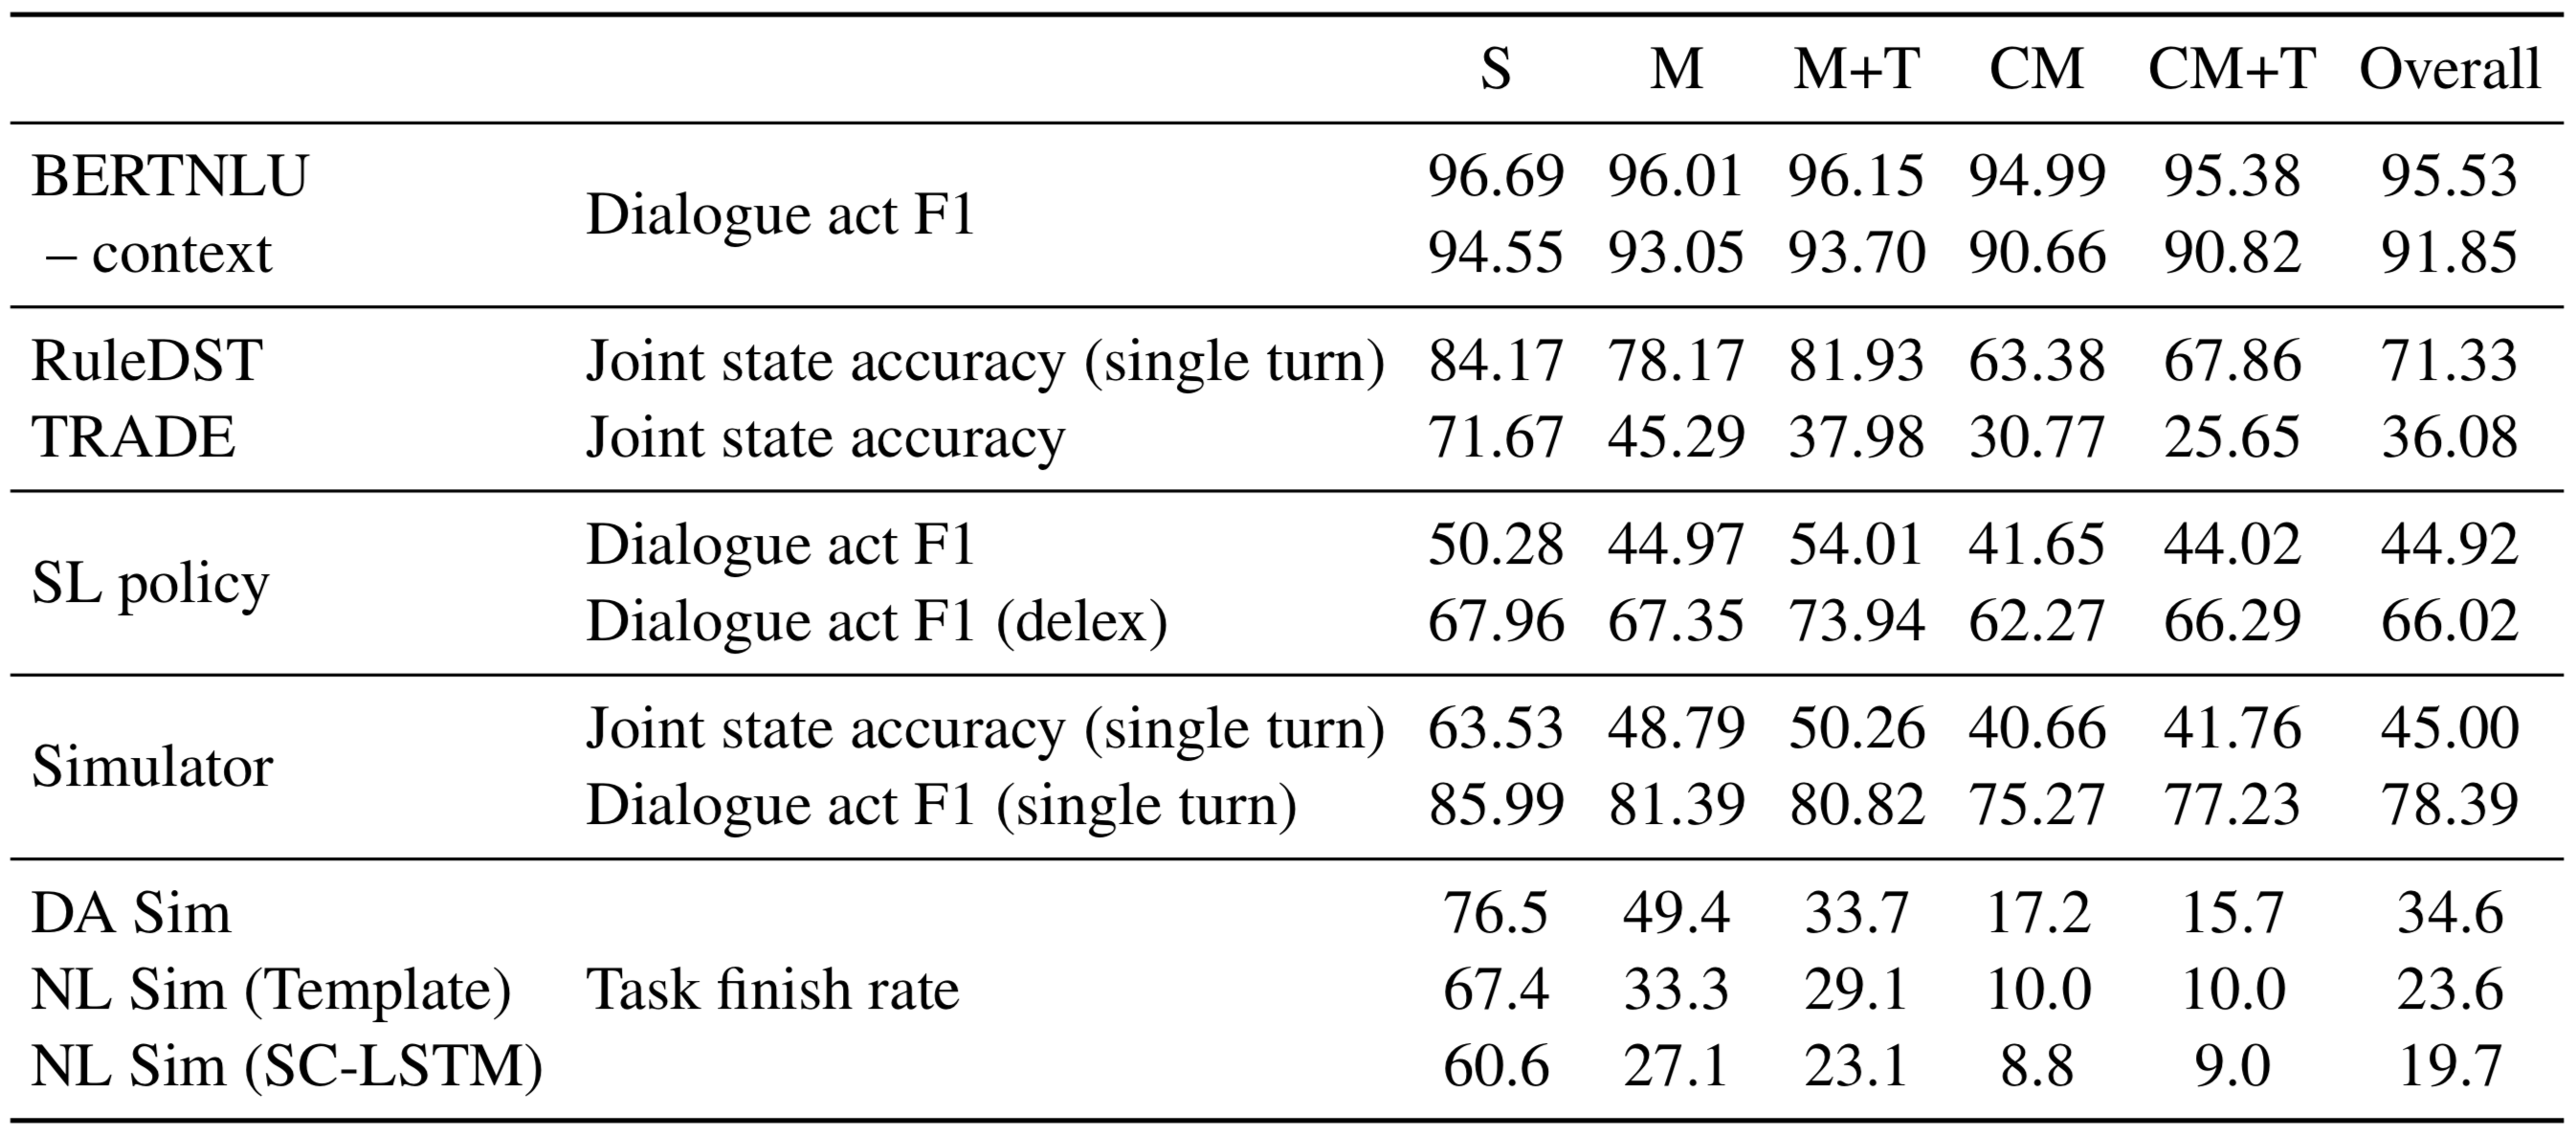
convlab2/nlg/template/crosswozconvlab2/policy/rule/crosswozconvlab2/policy/mle/crosswoz/evaluate.pyResult:
Please kindly cite our paper if this paper and the dataset are helpful.
@article{zhu2020crosswoz,
  author = {Qi Zhu and Kaili Huang and Zheng Zhang and Xiaoyan Zhu and Minlie Huang},
  title = {Cross{WOZ}: A Large-Scale Chinese Cross-Domain Task-Oriented Dialogue Dataset},
  journal = {Transactions of the Association for Computational Linguistics},
  year = {2020}
}
134 followers · starred Jun 2020
129 followers · starred May 2021
A Large-Scale Chinese Cross-Domain Task-Oriented Dialogue Dataset
Python
728
37 commits
updated Jun 17, 2024
CrossWOZ is the first large-scale Chinese Cross-Domain Wizard-of-Oz task-oriented dataset. It contains 6K dialogue sessions and 102K utterances for 5 domains, including hotel, restaurant, attraction, metro, and taxi. Moreover, the corpus contains rich annotation of dialogue states and dialogue acts at both user and system sides. We also provide a user simulator and several benchmark models for pipelined taskoriented dialogue systems, which will facilitate researchers to compare and evaluate their models on this corpus.
Refer to our paper for more details: CrossWOZ: A Large-Scale Chinese Cross-Domain Task-Oriented Dialogue Dataset (accepted by TACL)
If you have any question, feel free to open an issue.
We also release our annotation platform (Sep 10, 2021), supporting two annotators converse synchronously and make annotations online. Please refer to the web directory.
A piece of dialogue: (Names of hotels are replaced by A,B,C for simplicity.)
In data/crosswoz directory. Data statistics:
| Split | Train | Valid | Test |
|---|---|---|---|
| # dialogues | 5,012 | 500 | 500 |
| # Turns (utterances) | 84,692 | 8,458 | 8,476 |
| Vocab | 12,502 | 5,202 | 5,143 |
| Avg. sub-goals | 3.24 | 3.26 | 3.26 |
| Avg. semantic tuples | 14.8 | 14.9 | 15.0 |
| Avg. turns | 16.9 | 16.9 | 17.0 |
| Avg. tokens per turn | 16.3 | 16.3 | 16.2 |
According to the type of user goal, we group the dialogues in the training set into five categories:
Statistics for dialogues of different goal types in the training set:
| Goal type | S | M | M+T | CM | CM+T |
|---|---|---|---|---|---|
| # dialogues | 417 | 1573 | 691 | 1759 | 572 |
| NoOffer rate | 0.10 | 0.22 | 0.22 | 0.61 | 0.55 |
| Multi-query rate | 0.06 | 0.07 | 0.07 | 0.14 | 0.12 |
| Goal change rate | 0.10 | 0.28 | 0.31 | 0.69 | 0.63 |
| Avg. dialogue acts | 1.85 | 1.90 | 2.09 | 2.06 | 2.11 |
| Avg. sub-goals | 1.00 | 2.49 | 3.62 | 3.87 | 4.57 |
| Avg. semantic tuples | 4.5 | 11.3 | 15.8 | 18.2 | 20.7 |
| Avg. turns | 6.8 | 13.7 | 16.0 | 21.0 | 21.6 |
| Avg. tokens per turn | 13.2 | 15.2 | 16.3 | 16.9 | 17.0 |
We also provide database in data/crosswoz/database.
please install via:
pip install -e .
Code:
convlab2/nlu/jointBERT/crosswoz
convlab2/dst/rule/crosswozconvlab2/dst/trade/crosswoz
convlab2/policy/mle/crosswoz
convlab2/nlg/sclstm/crosswoz
convlab2/nlg/template/crosswozconvlab2/policy/rule/crosswozconvlab2/policy/mle/crosswoz/evaluate.pyResult:
Please kindly cite our paper if this paper and the dataset are helpful.
@article{zhu2020crosswoz,
  author = {Qi Zhu and Kaili Huang and Zheng Zhang and Xiaoyan Zhu and Minlie Huang},
  title = {Cross{WOZ}: A Large-Scale Chinese Cross-Domain Task-Oriented Dialogue Dataset},
  journal = {Transactions of the Association for Computational Linguistics},
  year = {2020}
}
134 followers · starred Jun 2020
129 followers · starred May 2021



