
README
Awesome Recursive Self-Improvement (RSI)
A taxonomy-first, auditable map of recursive self-improvement research.


📄 Survey • 📝 Cite • 🧭 Taxonomy • 📚 Catalog • 🆕 Updates • 🤝 Contribute
This repository accompanies The Last AI Built by Humans: Toward Genuine Recursive Self-Improvement (Yi Duan et al., 2026; arXiv:2609.11873).
Every listed paper retains its arXiv identifier, primary autonomy level, and updated-object classification.
RSI is the capability of an intelligent system to transform acquired experience and feedback into persistent changes to itself across interaction rounds, such that those changes can affect how later improvements are generated, evaluated, selected, and consolidated. The updated object may be model weights, prompts, code, memory, skills, task distributions, or the improvement mechanism itself. Levels capture autonomy over what is changed, how it is changed, and where later learning experience comes from; they are not paper-quality rankings.
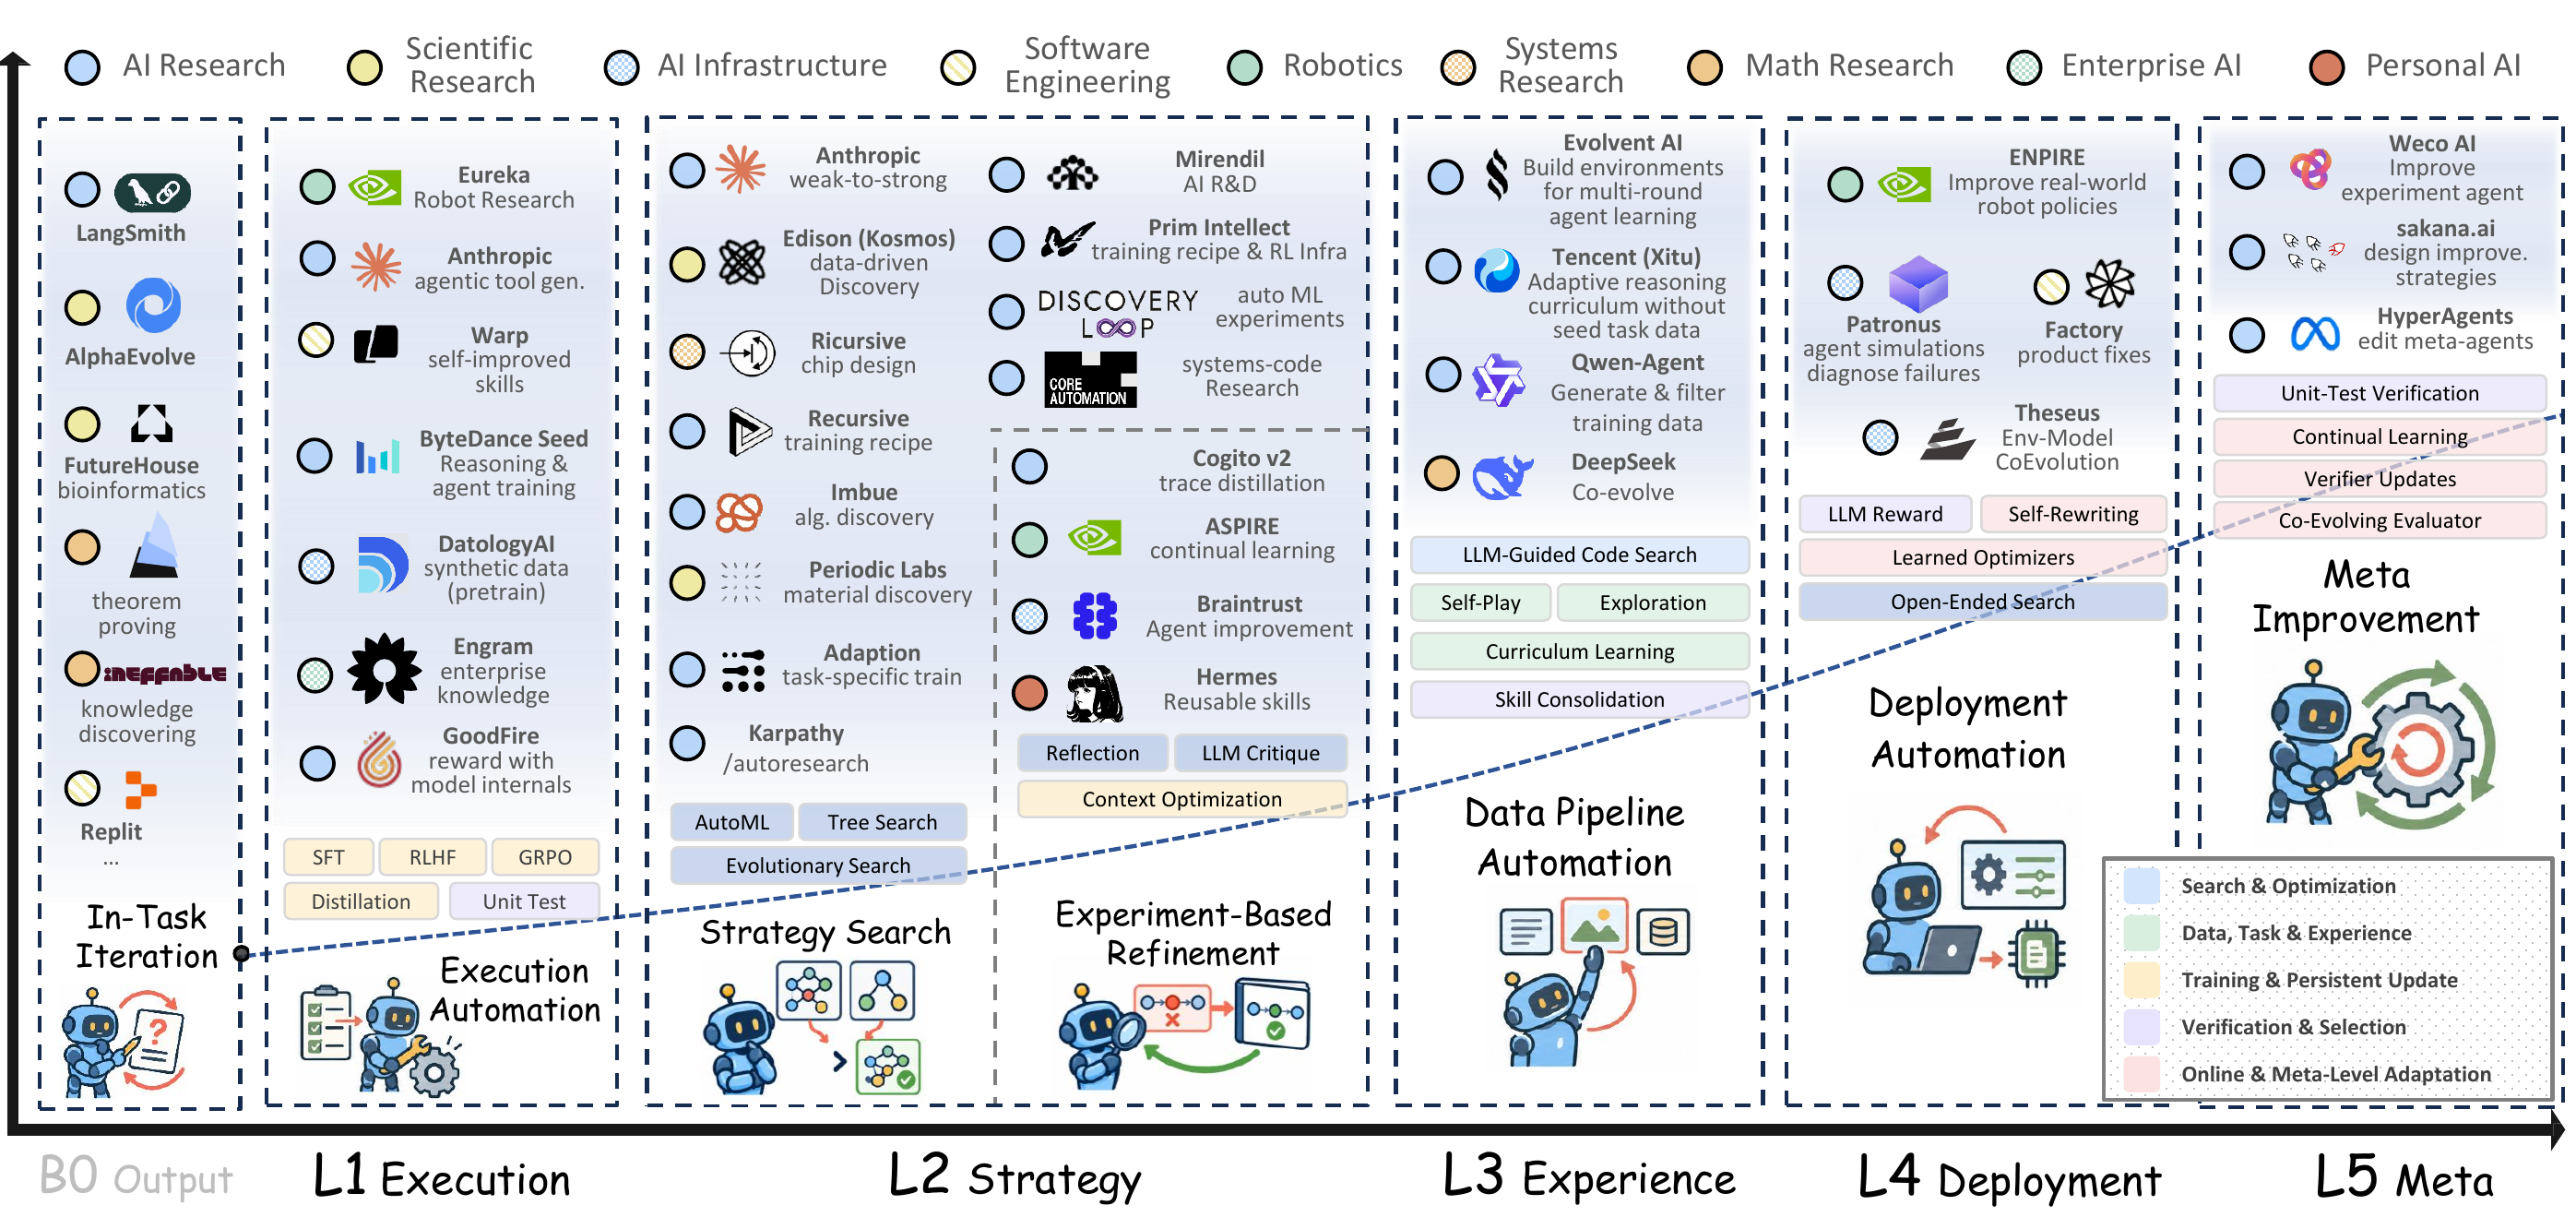
Figure 1. RSI autonomy overview: from in-task iteration and execution automation, through strategy search and experience acquisition, to deployment automation and meta-level improvement.
Latest Updates ↑ top
This section highlights recent, source-verifiable RSI research and industry developments. It is editorially separate from the 519-paper taxonomy, so a release or technical report is never presented as a peer-reviewed paper by default.
- 2026-09-10 — Companion survey released: The Last AI Built by Humans: Toward Genuine Recursive Self-Improvement introduces HCI and the L1-L5 RSI roadmap used by this repository. [Paper]


Update policy
- Include only a primary research source, official organization post, technical report, release note, or maintained project page.
- Tag each item as
ResearchorIndustry, then with its material type (Paper,Survey,Technical Report,Official Blog,Release, orProject). State its publication date and a neutral, one-sentence explanation of RSI relevance. - Link research to an official proceedings page, DOI, or arXiv record; link industry items to the organization's original publication, never to a repost or social-media summary.
- An update is not automatically an in-scope taxonomy paper. It enters the L1-L5 catalog only after the same paper-level relevance review.
Table of Contents
- Latest Updates
- Reading Paths
- Companion Survey
- Scope and Relevance Decision
- RSI Improvement-Loop Anatomy
- How to Read the Tags
- Taxonomy at a Glance
- 1. L1 - Autonomy over Improvement Execution
- 2. L2 - Autonomy over Improvement Strategies
- 3. L3 - Autonomy over Future Learning Experience
- 4. L4 - Autonomy in Deployment and Environmental Adaptation
- 5. L5 - From Environmental Adaptation to Meta-Improvement
- Contributing
- Citation
- Data Provenance and Validation
Reading Paths ↑ top
The full catalog is designed for reference, but these short routes provide a faster entry point:
| Goal | Suggested route |
|---|---|
| Understand the field map | Start with the companion survey, then read the improvement-loop anatomy and the L1-L5 overview. |
| Study persistent agent improvement | Read Voyager for reusable skills and automatic curricula, then browse L3 and L4. |
| Study recursive meta-improvement | Read Darwin Gödel Machine and Gödel Agent, then browse L5. |
Companion Survey ↑ top
This collection accompanies The Last AI Built by Humans: Toward Genuine Recursive Self-Improvement, by Yi Duan, Ying Liu, Zirui Tang, Haodong Chen, Jun Zhou, Yumou Liu, Bangrui Xu, Yukai Wu, Sidi Chen, Yuhan Zhou, Haoyu Wang, Xiaoyou Yu, Shaokun Han, Xuzhou Zhu, Le Zhou, Bolin Lu, Wei Zhou, Jiachen Liu, Nuozhou Fang, Jiaxin Tian, Ruoyu Chen, Yuxuan Li, Kai Zuo, Kaiyan Zhang, Jiantao Qiu, Conghui He, Guoliang Li, Bowen Zhou, Zhiyuan Liu, Zhoufutu Wen, Jihua Kang, Xuanhe Zhou, and Fan Wu.
The survey introduces the Headroom-Closed Index (HCI), develops the RSI roadmap represented by the L1-L5 taxonomy, and examines RSI in scientific discovery, embodied intelligence, and software engineering. This repository provides the paper-level, auditable companion to that roadmap.
Scope and Relevance Decision ↑ top
The 491 baseline papers and 28 table-derived extensions in this collection are retained as RSI-related under the L1-L5 taxonomy. The taxonomy intentionally includes bounded forms and precursors:
- L1 - Autonomy over Improvement Execution: the system executes a human-defined improvement procedure, and its accepted results persist into later tasks or rounds.
- L2 - Autonomy over Improvement Strategies: the system chooses how to improve a specified target, while the objective, evaluation criterion, or acceptance rule remains external.
- L3 - Autonomy over Future Learning Experience: the learner's evolving state influences the experience, task, or curriculum acquired next.
- L4 - Autonomy in Deployment and Environmental Adaptation: reusable memory, skills, or deployed agent components are retained and alter later behavior within a fixed improvement process.
- L5 - From Environmental Adaptation to Meta-Improvement: the system improves the mechanism that produces future improvements, such as search, evaluation, or research-control policies.
Thus, inclusion does not claim that every entry is a fully autonomous or open-ended RSI system. The L1 and L2 labels make their bounded autonomy explicit.
RSI Improvement-Loop Anatomy ↑ top
Each entry can be interpreted through the same loop: experience -> candidate modification -> verifier / acceptance rule -> retained improvement -> successor re-entry. The relevant components are:
| Component | Role in the loop |
|---|---|
| System state | Persistent state inherited by the next round. |
| Experience | Prior interaction outcomes, failures, feedback, or observations that inform an update. |
| Target | The object directly modified in the current round. |
| Improver and strategy | The mechanism that proposes candidates and decides where or how to search. |
| Verifier | The evaluator that applies an acceptance rule, such as tests, rewards, formal checks, or human feedback. |
| Improvement and successor | An accepted, retained state change and the next system version that inherits it. |
This anatomy supplies three tests for every claimed RSI loop: Where does the loop close? What is updated and inherited? Which decisions remain external?
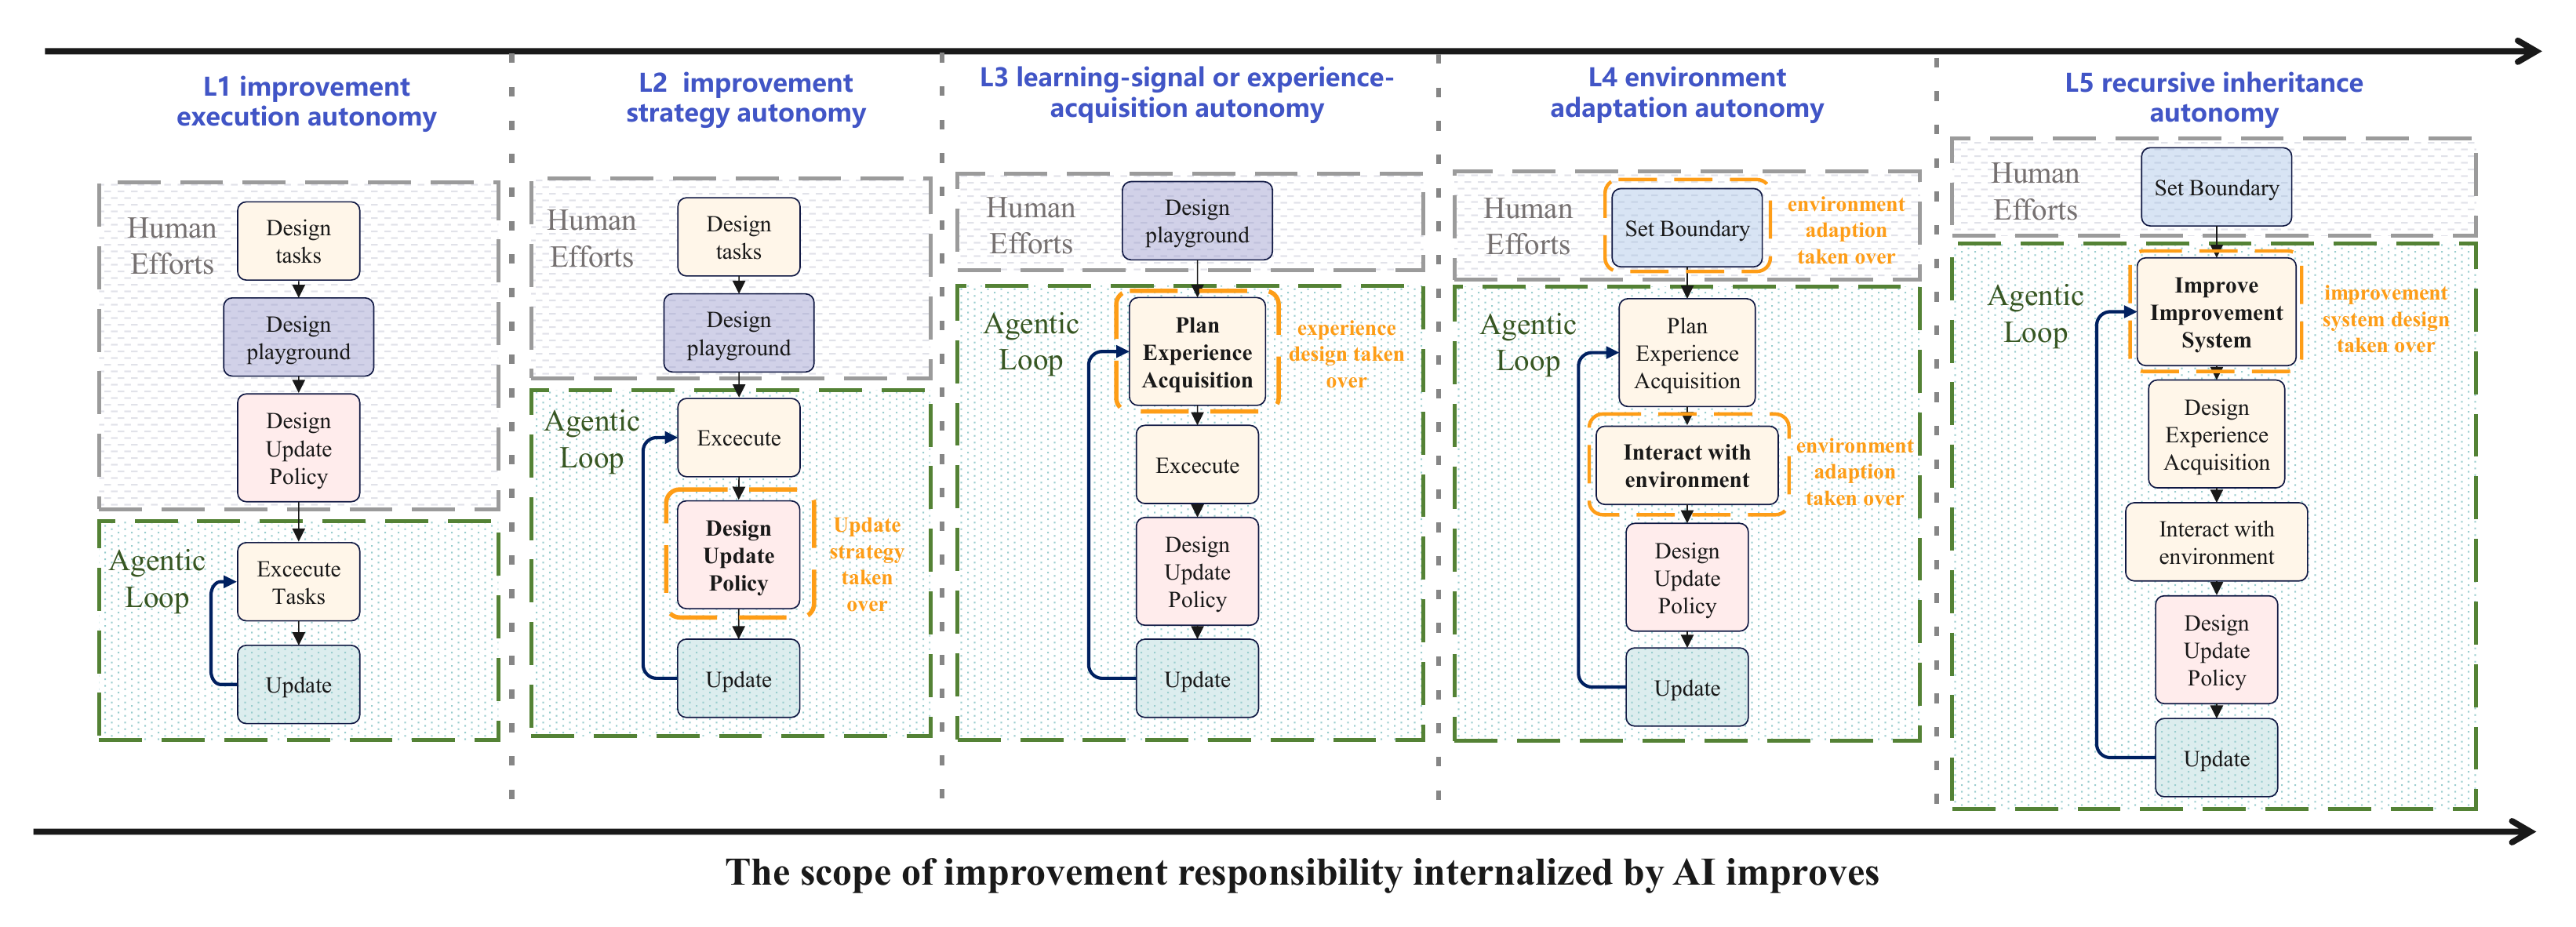
Figure 2. Loop patterns across L1-L5. The agentic loop expands as AI internalizes more of the improvement process, while human-controlled constraints remain explicit.
How to Read the Tags ↑ top
Each entry has three colored badges:
| Badge | Meaning |
|---|---|
Level-L1 to Level-L5 | Autonomy level and locus in the improvement loop |
In scope-RSI | Retained by the source taxonomy's RSI relevance screen |
Target-... | Primary family of the updated or searched object |
Blue, purple, orange, green, and red encode L1 through L5. Target colors distinguish the ten updated-object families. Each paper appears exactly once under its primary level; all available target codes are preserved in the entry.
Taxonomy at a Glance ↑ top
| Level | Papers | Interpretation |
|---|---|---|
| L1 | 219 | Autonomy over improvement execution. |
| L2 | 159 | Autonomy over improvement strategies. |
| L3 | 65 | Autonomy over future learning experience. |
| L4 | 45 | Autonomy in deployment and environmental adaptation. |
| L5 | 31 | From environmental adaptation to meta-improvement. |
Each level begins with a small set of featured representative papers, selected to cover its defining mechanisms and important research landmarks. They are entry points for reading, not quality rankings; the complete catalog remains available in the expandable section below each level.
Updated-Object Families
| Code prefix | Family |
|---|---|
| 1 | Prompt & Context |
| 2 | Memory & Knowledge |
| 3 | Harness / Workflow |
| 4 | Tools & Skills |
| 5 | Model |
| 6 | Trainer / Optimization |
| 7 | Evaluator & Feedback |
| 8 | Data & Environment |
| 9 | External Artifact |
| 10 | Full-system / Co-evolution |
1. L1 - Autonomy over Improvement Execution ↑ top
The system executes a human-defined improvement procedure and retains accepted results for later tasks or rounds. 219 papers.
Featured representative papers
| Paper | Representative mechanism |
|---|---|
| STaR | Bootstraps model-generated rationales into a fixed, correctness-filtered self-training loop. |
| Constitutional AI | Establishes critique-and-revision with AI feedback under a human-specified constitution. |
| ReST | Generates an offline dataset with the current policy, then improves that policy with offline reinforcement learning. |
| SPIN | Generates training data from earlier policy iterations and refines the policy against human-annotated responses. |
| Self-Rewarding Language Models | Uses model-generated judgments as a fixed-protocol training signal. |
| Meta-Rewarding Language Models | Extends AI-feedback training to iterative refinement of the judging signal. |
Browse the full L1 catalog (219 papers)
Table-derived extensions
The following additions are explicitly discussed in Table 3 of the survey, which organizes representative L1 systems by AI development pipeline level.
-
Phi-4-reasoning Technical Report
[Paper] · arXiv:2504.21318
Survey-table rationale: Training-data selection through LLM evaluation and boundary filtering; selection criteria remain human-defined. Updated object(s): 8.1 Training / Experience Data. -
NVIDIA Nemotron-4 340B Technical Report
[Paper] · arXiv:2406.11704
Survey-table rationale: Synthetic supervision is generated and reward-filtered under human-defined quality dimensions. Updated object(s): 8.1 Training / Experience Data. -
EDIT: Evidence-Diagnosed Intervention Training for Rule-Faithful LLM Grading
[Paper] · arXiv:2606.06350
Survey-table rationale: Diagnosed-step revisions refine a training signal while diagnostic criteria remain human-defined. Updated object(s): 6.1 Training Objective. -
AIPC: Agent-Based Automation for AI Model Deployment with Qualcomm AI Runtime
[Paper] · arXiv:2604.14661
Survey-table rationale: Skill-guided deployment adaptation follows a human-defined deployment procedure. Updated object(s): 3.6 Harness Implementation / Scaffold Code. -
$V_1$: Unifying Generation and Self-Verification for Parallel Reasoners
[Paper] · arXiv:2603.04304
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
A Co-Evolving Agentic AI System for Medical Imaging Analysis
[Paper] · arXiv:2509.20279
Taxonomy: L1. Updated object(s): 5.2 Adapter; 2.1 Experience Memory; 3.3 Harness / Workflow. -
A Context Engineering Framework for Improving Enterprise AI Agents based on Digital-Twin MDP
[Paper] · arXiv:2603.22083
Taxonomy: L1. Updated object(s): 1.5 Context; 3.1 Workflow. -
A Dynamic Self-Evolving Extraction System
[Paper] · arXiv:2603.06915
Taxonomy: L1. Updated object(s): 2.2 Knowledge Memory; 1.5 Context. -
A Model Can Help Itself: Reward-Free Self-Training for LLM Reasoning
[Paper] · arXiv:2510.18814
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
A Self-Improvable Polymer Discovery Framework Based on Conditional Generative Model
[Paper] · arXiv:2312.04013
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 8.1 Experience Data. -
ACE: Self-Evolving LLM Coding Framework via Adversarial Unit Test Generation and Preference Optimization
[Paper] · arXiv:2605.16299
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 8.1 Experience Data. -
AceSearcher: Bootstrapping Reasoning and Search for LLMs via Reinforced Self-Play
[Paper] · arXiv:2509.24193
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Active-GRPO: Adaptive Imitation and Self-Improving Reasoning for Molecular Optimization
[Paper] · arXiv:2607.00531
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 6.1 Objective. -
AdaExplore: Failure-Driven Adaptation and Diversity-Preserving Search for Efficient Kernel Generation
[Paper] · arXiv:2604.16625
Taxonomy: L1. Updated object(s): 1.1 Instruction; 2.2 Knowledge Memory. -
Agent Hospital: A Simulacrum of Hospital with Evolvable Medical Agents
[Paper] · arXiv:2405.02957
Taxonomy: L1. Updated object(s): 2.1 Experience Memory; 2.3 Procedural Memory. -
Agent0-VL: Exploring Self-Evolving Agent for Tool-Integrated Vision-Language Reasoning
[Paper] · arXiv:2511.19900
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
AgentGym: Evolving Large Language Model-based Agents across Diverse Environments
[Paper] · arXiv:2406.04151
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Agentic-Ideation: Sample Efficient Agentic Trajectories Synthesis for Scientific Ideation Agents
[Paper] · arXiv:2606.31229
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
AlgoSkill: Learning to Design Algorithms by Scheduling Human-Like Skills
[Paper] · arXiv:2606.29999
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
AMR-SD: Asymmetric Meta-Reflective Self-Distillation for Token-Level Credit Assignment
[Paper] · arXiv:2605.18529
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 6.1 Objective. -
Anyprefer: An Agentic Framework for Preference Data Synthesis
[Paper] · arXiv:2504.19276
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 1.1 Instruction. -
APR: Penalizing Structural Redundancy in Large Reasoning Models via Anchor-based Process Rewards
[Paper] · arXiv:2602.00760
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 6.1 Objective. -
AutoMalDesc: Large-Scale Script Analysis for Cyber Threat Research
[Paper] · arXiv:2511.13333
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 8.1 Experience Data. -
AutoResearchClaw: Self-Reinforcing Autonomous Research with Human-AI Collaboration
[Paper] · arXiv:2605.20025
Taxonomy: L1. Updated object(s): 2.1 Experience Memory. -
Better, Faster: Harnessing Self-Improvement in Large Reasoning Models
[Paper] · arXiv:2605.24998
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 6.1 Objective. -
Beyond Imitation: Self-Improving Robot Policies via Off-Policy Q-Planning
[Paper] · arXiv:2608.21204
Taxonomy: L1. Updated object(s): 5.2 Adapter. -
Beyond Self-Play: Hierarchical Reasoning for Continuous Motion in Closed-Loop Traffic Simulation
[Paper] · arXiv:2605.09153
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Binary Decompilation LLM with Feedback-Driven Multi-Turn Refinement
[Paper] · arXiv:2606.16162
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
BiWM: Advancing Open-Source Interactive Video World Models with Bidirectional Autoregression
[Paper] · arXiv:2606.10135
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 6.1 Objective. -
Breaking the Self-Confirming Loop: Diagnosing and Mitigating Systemic Reward Bias in Self-Rewarding RL
[Paper] · arXiv:2510.08977
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Bridging What the Model Thinks and How It Speaks: Expressive Speech Generation via Self-Aware Intent-Realization Alignment
[Paper] · arXiv:2604.11424
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Can Large Reasoning Models Self-Train?
[Paper] · arXiv:2505.21444
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Can Recommender Systems Teach Themselves? A Recursive Self-Improving Framework with Fidelity Control
[Paper] · arXiv:2602.15659
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 8.1 Experience Data. -
CAST: Non-Privileged Clipped Asymmetric Self-Teaching with Advantage Flipping for GRPO
[Paper] · arXiv:2606.00172
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
CATPO: Critique-Augmented Tree Policy Optimization
[Paper] · arXiv:2606.08346
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 6.4 Curriculum. -
CEPO: RLVR Self-Distillation using Contrastive Evidence Policy Optimization
[Paper] · arXiv:2605.19436
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 6.1 Objective. -
CIIR@LiveRAG 2025: Optimizing Multi-Agent Retrieval Augmented Generation through Self-Training
[Paper] · arXiv:2506.10844
Taxonomy: L1. Updated object(s): 5.2 Adapter. -
Cleansing the Artificial Mind: A Self-Reflective Detoxification Framework for Large Language Models
[Paper] · arXiv:2601.11776
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Co-rewarding: Stable Self-supervised RL for Eliciting Reasoning in Large Language Models
[Paper] · arXiv:2508.00410
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
CoAct: Co-Active LLM Preference Learning with Human-AI Synergy
[Paper] · arXiv:2604.17501
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Consistent Paths Lead to Truth: Self-Rewarding Reinforcement Learning for LLM Reasoning
[Paper] · arXiv:2506.08745
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Constitutional AI: Harmlessness from AI Feedback
[Paper] · arXiv:2212.08073
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 7.2 Reward / Fitness. -
Continual Self-Improvement with Lightweight Experiential Latent Memories
[Paper] · arXiv:2606.17803
Taxonomy: L1. Updated object(s): 5.2 Adapter; 2.1 Experience Memory. -
Continuous Self-Improvement of Large Language Models by Test-time Training with Verifier-Driven Sample Selection
[Paper] · arXiv:2505.19475
Taxonomy: L1. Updated object(s): 5.2 Adapter. -
CoVerRL: Breaking the Consensus Trap in Label-Free Reasoning via Generator-Verifier Co-Evolution
[Paper] · arXiv:2603.17775
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
CREAM: Consistency Regularized Self-Rewarding Language Models
[Paper] · arXiv:2410.12735
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
CritiCal: Can Critique Help LLM Uncertainty or Confidence Calibration?
[Paper] · arXiv:2510.24505
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Deciphering Scientific Reasoning Steps from Outcome Data for Molecule Optimization
[Paper] · arXiv:2603.20262
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Decouple to Generalize: Context-First Self-Evolving Learning for Data-Scarce Vision-Language Reasoning
[Paper] · arXiv:2512.06835
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 8.1 Experience Data. -
DeepInnovator: Triggering the Innovative Capabilities of LLMs
[Paper] · arXiv:2602.18920
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 8.1 Experience Data. -
DeepSeekMath-V2: Towards Self-Verifiable Mathematical Reasoning
[Paper] · arXiv:2511.22570
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 7.3 Verifier. -
DemoPSD: Disagreement-Modulated Policy Self-Distillation
[Paper] · arXiv:2607.02502
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 6.1 Objective. -
Depression Diagnosis Dialogue Simulation: Self-improving Psychiatrist with Tertiary Memory
[Paper] · arXiv:2409.15084
Taxonomy: L1. Updated object(s): 2.1 Experience Memory; 2.3 Procedural Memory. -
DermoGPT: Open Weights and Open Data for Morphology-Grounded Dermatological Reasoning MLLMs
[Paper] · arXiv:2601.01868
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 6.1 Objective. -
Differentiable Mixture-of-Agents Incentivizes Swarm Intelligence of Large Language Models
[Paper] · arXiv:2605.15706
Taxonomy: L1. Updated object(s): 3.3 Harness / Workflow; 5.2 Adapter. -
Distilling LLM Feedback for Lean Theorem Proving
[Paper] · arXiv:2605.30861
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Double-Checker: Enhancing Reasoning of Slow-Thinking LLMs via Self-Critical Fine-Tuning
[Paper] · arXiv:2506.21285
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
DRIFT: Difficulty Routing Self-DIstillation with Rhythm-Gated Exploration and Success BuFfer Training
[Paper] · arXiv:2606.30345
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Dual-Modality Multi-Stage Adversarial Safety Training: Robustifying Multimodal Web Agents Against Cross-Modal Attacks
[Paper] · arXiv:2603.04364
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 8.1 Experience Data. -
DuPO: Enabling Reliable LLM Self-Verification via Dual Preference Optimization
[Paper] · arXiv:2508.14460
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 6.1 Objective. -
Dynamic Alignment for Collective Agency: Toward a Scalable Self-Improving Framework for Open-Ended LLM Alignment
[Paper] · arXiv:2512.05464
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
EARS: Explanatory Abstention for Reliable Sub-Agent Modeling in Large-scale Multi-Agent Systems
[Paper] · arXiv:2606.18668
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 8.1 Experience Data. -
Easy Samples Are All You Need: Self-Evolving LLMs via Data-Efficient Reinforcement Learning
[Paper] · arXiv:2604.18639
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Emulating Clinician Cognition via Self-Evolving Deep Clinical Research
[Paper] · arXiv:2603.10677
Taxonomy: L1. Updated object(s): 2.1 Experience Memory. -
Endless Terminals: Scaling RL Environments for Terminal Agents
[Paper] · arXiv:2601.16443
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 8.3 Environment. -
Enhancing Mathematical Reasoning in LLMs with Background Operators
[Paper] · arXiv:2412.04110
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
EpiCaR: Knowing What You Don't Know Matters for Better Reasoning in LLMs
[Paper] · arXiv:2601.06786
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 6.1 Objective. -
Evo-MedAgent: Beyond One-Shot Diagnosis with Agents That Remember, Reflect, and Improve
[Paper] · arXiv:2604.14475
Taxonomy: L1. Updated object(s): 2.1 Experience Memory; 2.3 Procedural Memory. -
EvoDefense: Co-Evolving Black-Box Defense with Large Language Models
[Paper] · arXiv:2605.31140
Taxonomy: L1. Updated object(s): 5.2 Adapter; 2.1 Experience Memory. -
EVOLVE-VLA: Test-Time Training from Environment Feedback for Vision-Language-Action Models
[Paper] · arXiv:2512.14666
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
ExpeL: LLM Agents Are Experiential Learners
[Paper] · arXiv:2308.10144
Taxonomy: L1. Updated object(s): 2.1 Experience Memory; 2.2 Knowledge Memory. -
Exploring and Exploiting the Inherent Efficiency within Large Reasoning Models for Self-Guided Efficiency Enhancement
[Paper] · arXiv:2506.15647
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
ExpRL: Exploratory RL for LLM Mid-Training
[Paper] · arXiv:2606.17024
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
FiRe: Fine-grained Multimodal Reasoning for Enhanced Image Generation
[Paper] · arXiv:2604.13491
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
First SFT, Second RL, Third UPT: Continual Improving Multi-Modal LLM Reasoning via Unsupervised Post-Training
[Paper] · arXiv:2505.22453
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 8.1 Experience Data. -
Forward-Free Diffusion Language Models with BPTT-Free Looped Refinement
[Paper] · arXiv:2606.08357
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 6.1 Objective. -
From Memorization to Creativity: LLM as a Designer of Novel Neural Architectures
[Paper] · arXiv:2601.02997
Taxonomy: L1. Updated object(s): 5.2 Adapter; 8.1 Experience Data. -
Generating on Generated: An Approach Towards Self-Evolving Diffusion Models
[Paper] · arXiv:2502.09963
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
GRAM-R^2: Self-Training Generative Foundation Reward Models for Reward Reasoning
[Paper] · arXiv:2509.02492
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
GSEM: Graph-based Self-Evolving Memory for Experience Augmented Clinical Reasoning
[Paper] · arXiv:2603.22096
Taxonomy: L1. Updated object(s): 2.1 Experience Memory; 2.4 Memory & Knowledge. -
Heterogeneous Self-Play for Realistic Highway Traffic Simulation
[Paper] · arXiv:2604.16406
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
How to Train Your Long-Context Visual Document Model
[Paper] · arXiv:2602.15257
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 7.1 Judge. -
HS-STaR: Hierarchical Sampling for Self-Taught Reasoners via Difficulty Estimation and Budget Reallocation
[Paper] · arXiv:2505.19866
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 6.4 Curriculum. -
ICRL: Learning to Internalize Self-Critique with Reinforcement Learning
[Paper] · arXiv:2605.15224
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 6.1 Objective. -
Improving LLM Code Reasoning via Semantic Equivalence Self-Play with Formal Verification
[Paper] · arXiv:2604.17010
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 5.2 Adapter. -
Improving Reasoning in Vision-Language Models via Perception Verified Self-Training
[Paper] · arXiv:2606.22158
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
IRIS: Interpolative Rényi Iterative Self-play for Large Language Model Fine-Tuning
[Paper] · arXiv:2604.20933
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Iterative Compositional Data Generation for Robot Control
[Paper] · arXiv:2512.10891
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 8.1 Experience Data. -
JailDAM: Jailbreak Detection with Adaptive Memory for Vision-Language Model
[Paper] · arXiv:2504.03770
Taxonomy: L1. Updated object(s): 2.2 Knowledge Memory; 2.5 Memory & Knowledge. -
KBSpec: LLM-driven Formal Specification Generation with Evolving Domain Knowledge Base
[Paper] · arXiv:2606.21339
Taxonomy: L1. Updated object(s): 2.2 Knowledge Memory; 2.3 Procedural Memory. -
Keep Policy Gradient in Charge: Sibling-Guided Credit Distillation for Long-Horizon Tool-Use Agents
[Paper] · arXiv:2606.12634
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 6.1 Objective. -
Know When to Stop: Segment-Level Credit Assignment for Reducing Overthinking
[Paper] · arXiv:2607.00482
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 6.1 Objective. -
KVerus: Scalable and Resilient Formal Verification Proof Generation for Rust Code
[Paper] · arXiv:2605.03822
Taxonomy: L1. Updated object(s): 9.1 Program Code; 2.2 Knowledge Memory. -
Latent Preference Modeling for Cross-Session Personalized Tool Calling
[Paper] · arXiv:2604.17886
Taxonomy: L1. Updated object(s): 2.2 Knowledge Memory. -
Learn from Your Mistakes: Tree-like Self-Play for Secure Code LLMs
[Paper] · arXiv:2606.03489
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 6.1 Objective. -
Learn Your Reference Model for Real Good Alignment
[Paper] · arXiv:2404.09656
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Learning from Language Feedback via Variational Policy Distillation
[Paper] · arXiv:2605.15113
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Learning from Supervision with Semantic and Episodic Memory: A Reflective Approach to Agent Adaptation
[Paper] · arXiv:2510.19897
Taxonomy: L1. Updated object(s): 2.1 Experience Memory; 2.2 Knowledge Memory. -
Learning from Your Own Mistakes: Constructing Learnable Micro-Reflective Trajectories for Self-Distillation
[Paper] · arXiv:2606.18844
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 6.1 Objective. -
Learning Steerable Clarification Policies with Collaborative Self-play
[Paper] · arXiv:2512.04068
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Learning to Better Search with Language Models via Guided Reinforced Self-Training
[Paper] · arXiv:2410.02992
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Learning to Plan & Reason for Evaluation with Thinking-LLM-as-a-Judge
[Paper] · arXiv:2501.18099
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Learning to Plan Before Answering: Self-Teaching LLMs to Learn Abstract Plans for Problem Solving
[Paper] · arXiv:2505.00031
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Learning to Self-Verify Makes Language Models Better Reasoners
[Paper] · arXiv:2602.07594
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 6.1 Objective. -
Learning to Solve and Verify: A Self-Play Framework for Code and Test Generation
[Paper] · arXiv:2502.14948
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
LLM-Personalize: Aligning LLM Planners with Human Preferences via Reinforced Self-Training for Housekeeping Robots
[Paper] · arXiv:2404.14285
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Meta-Rewarding Language Models: Self-Improving Alignment with LLM-as-a-Meta-Judge
[Paper] · arXiv:2407.19594
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
MiGrATe: Mixed-Policy GRPO for Adaptation at Test-Time
[Paper] · arXiv:2508.08641
Taxonomy: L1. Updated object(s): 5.2 Adapter. -
MobileIPL: Enhancing Mobile Agents Thinking Process via Iterative Preference Learning
[Paper] · arXiv:2505.12299
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 8.1 Experience Data. -
Monte Carlo Tree Search with Reasoning Path Refinement for Small Language Models in Conversational Text-to-NoSQL
[Paper] · arXiv:2602.12574
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Motus2: A Self-Evolving General World Model for Dexterous Manipulation
[Paper] · arXiv:2608.30237
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 8.4 Data & Environment; 7.2 Reward / Fitness. -
Not All Synthetic Data Is Yours to Learn From
[Paper] · arXiv:2605.31126
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Object-Centric Residual RL for Zero-Shot Sim-to-Real VLA Enhancement
[Paper] · arXiv:2606.18953
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 5.2 Adapter. -
Observations and Remedies for Large Language Model Bias in Self-Consuming Performative Loop
[Paper] · arXiv:2601.05184
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 8.1 Experience Data. -
OmniOPSD: Rationale-Privileged On-Policy Self-Distillation for Affective Computing
[Paper] · arXiv:2606.15920
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
OWL: Unsupervised 3D Object Detection by Occupancy Guided Warm-up and Large Model Priors Reasoning
[Paper] · arXiv:2512.05698
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 8.1 Experience Data. -
PaperSearchQA: Learning to Search and Reason over Scientific Papers with RLVR
[Paper] · arXiv:2601.18207
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 8.1 Experience Data. -
PARNESS: A Paper Harness for End-to-End Automated Scientific Research with Dynamic Workflows, Full-Text Indexing, and Cross-Run Knowledge Accumulation
[Paper] · arXiv:2605.05258
Taxonomy: L1. Updated object(s): 2.2 Knowledge Memory; 2.1 Experience Memory. -
Paying More Attention to Visual Tokens in Self-Evolving Large Multimodal Models
[Paper] · arXiv:2606.27373
Taxonomy: L1. Updated object(s): 5.2 Adapter; 6.1 Objective. -
PBSD: Privileged Bayesian Self-Distillation for Long-Horizon Credit Assignment
[Paper] · arXiv:2606.09348
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 6.1 Objective. -
PEARL: Training Socratic Tutors with Pedagogically Aligned Reinforcement Learning
[Paper] · arXiv:2605.29582
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 6.1 Objective. -
Peer-Predictive Self-Training for Language Model Reasoning
[Paper] · arXiv:2604.13356
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Perception, Verdict, and Evolution: Hindsight-Driven Self-Refining Forensics Agent for AI-Generated Image Detection
[Paper] · arXiv:2606.26552
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
PLLM: Pseudo-Labeling Large Language Models for CAD Program Synthesis
[Paper] · arXiv:2602.12561
Taxonomy: L1. Updated object(s): 5.2 Adapter. -
Policy-Guided Stepwise Model Routing for Cost-Effective Reasoning
[Paper] · arXiv:2605.06116
Taxonomy: L1. Updated object(s): 3.3 Harness / Workflow. -
Post-Training Probability Manifold Correction via Structured SVD Pruning and Self-Referential Distillation
[Paper] · arXiv:2602.00372
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Poster: ClawdGo: Endogenous Security Awareness Training for Autonomous AI Agents
[Paper] · arXiv:2604.24020
Taxonomy: L1. Updated object(s): 2.3 Procedural Memory; 2.5 Memory & Knowledge; 8.2 Task Generator. -
PRefLexOR: Preference-based Recursive Language Modeling for Exploratory Optimization of Reasoning and Agentic Thinking
[Paper] · arXiv:2410.12375
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
PRISMA: Preference-Reinforced Self-Training Approach for Interpretable Emotionally Intelligent Negotiation Dialogues
[Paper] · arXiv:2604.18354
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Probing Visual Language Priors in VLMs
[Paper] · arXiv:2501.00569
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Procedural Memory Distillation: Online Reflection for Self-Improving Language Models
[Paper] · arXiv:2607.01480
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Process-based Self-Rewarding Language Models
[Paper] · arXiv:2503.03746
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
ProcessThinker: Enhancing Multi-modal Large Language Models Reasoning via Rollout-based Process Reward
[Paper] · arXiv:2606.11209
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
PsychAgent: An Experience-Driven Lifelong Learning Agent for Self-Evolving Psychological Counselor
[Paper] · arXiv:2604.00931
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 4.4 Skill Library. -
Pythagoras-Prover: Advancing Efficient Formal Proving via Augmented Lean Formalisation
[Paper] · arXiv:2606.12594
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 8.1 Experience Data. -
Quiet-STaR: Language Models Can Teach Themselves to Think Before Speaking
[Paper] · arXiv:2403.09629
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Reasoning and Learning a Perceptual Metric for Self-Training of Reflective Objects in Bin-Picking with a Low-cost Camera
[Paper] · arXiv:2503.20207
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 8.1 Experience Data. -
Reasoning-Enhanced Self-Training for Long-Form Personalized Text Generation
[Paper] · arXiv:2501.04167
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
RebuttalAgent: Strategic Persuasion in Academic Rebuttal via Theory of Mind
[Paper] · arXiv:2601.15715
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Red-Bandit: Test-Time Adaptation for LLM Red-Teaming via Bandit-Guided LoRA Experts
[Paper] · arXiv:2510.07239
Taxonomy: L1. Updated object(s): 5.2 Adapter; 3.3 Harness / Workflow. -
ReGuide: From Test-Time Guidance to Self-Improving Diffusion Policies
[Paper] · arXiv:2606.28939
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 8.1 Experience Data. -
Reinforced Self-Training (ReST) for Language Modeling
[Paper] · arXiv:2308.08998
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Reinforcement Learning for Self-Improving Agent with Skill Library
[Paper] · arXiv:2512.17102
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 4.4 Skill Library. -
Reinforcement Learning from Rich Feedback with Distributional DAgger
[Paper] · arXiv:2606.05152
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 6.1 Objective. -
ReNIO: Reweighting Negative Trajectory Importance for LLM On-Policy Distillation
[Paper] · arXiv:2606.23104
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
ReST-MCTS: LLM Self-Training via Process Reward Guided Tree Search*
[Paper] · arXiv:2406.03816
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 7.2 Reward / Fitness. -
ReSteer: Quantifying and Refining the Steerability of Multitask Robot Policies
[Paper] · arXiv:2603.17300
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Rethinking Reward Supervision: Rubric-Conditioned Self-Distillation
[Paper] · arXiv:2606.19327
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
RetroAgent: From Solving to Evolving via Retrospective Dual Intrinsic Feedback
[Paper] · arXiv:2603.08561
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 2.1 Experience Memory. -
Right in the Right Way: LM Training with Verifiable Rewards and Human Demonstrations
[Paper] · arXiv:2607.01181
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 6.1 Objective; 5.2 Adapter. -
RLSR: Reinforcement Learning from Self Reward
[Paper] · arXiv:2505.08827
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Robot Self-Improvement via Human-Video Dynamics Models
[Paper] · arXiv:2606.21406
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 8.1 Experience Data. -
ROSD: Reflective On-Policy Self-Distillation for Language Model Reasoning across Domains
[Paper] · arXiv:2605.28014
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 6.1 Objective. -
Route, Retrieve, Reflect, Repair: Self-Improving Agentic Framework for Visual Detection and Linguistic Reasoning in Medical Imaging
[Paper] · arXiv:2601.08192
Taxonomy: L1. Updated object(s): 2.1 Experience Memory; 1.4 Prompt & Context. -
S-SPPO: Semantic-Calibrated Self-Play Preference Optimization
[Paper] · arXiv:2606.01561
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 6.1 Objective. -
SAEExplainer: Interpreting SAE Features with Activation-Guided Preference Optimization
[Paper] · arXiv:2606.08496
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Safe Autoregressive Image Generation with Iterative Self-Improving Codebooks
[Paper] · arXiv:2606.27147
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
SafeCtrl-RL: Inference-Time Adaptive Behaviour Control for LLM Dialogue via RL-Driven Prompt Optimisation
[Paper] · arXiv:2605.25984
Taxonomy: L1. Updated object(s): 5.2 Adapter; 3.4 Harness / Workflow. -
SafeSteer: Localized On-Policy Distillation for Efficient Safety Alignment
[Paper] · arXiv:2606.02530
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 6.1 Objective. -
SD-Search: On-Policy Hindsight Self-Distillation for Search-Augmented Reasoning
[Paper] · arXiv:2605.18299
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 6.1 Objective. -
Search-E1: Self-Distillation Drives Self-Evolution in Search-Augmented Reasoning
[Paper] · arXiv:2605.22511
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
See, Think, Learn: A Self-Taught Multimodal Reasoner
[Paper] · arXiv:2512.02456
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Self-Adapting Improvement Loops for Robotic Learning
[Paper] · arXiv:2506.06658
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Self-Alignment with Instruction Backtranslation
[Paper] · arXiv:2308.06259
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Self-Consistency of the Internal Reward Models Improves Self-Rewarding Language Models
[Paper] · arXiv:2502.08922
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
SELF-EMO: Emotional Self-Evolution from Recognition to Consistent Expression
[Paper] · arXiv:2604.18003
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Self-Evolution for Multi-Turn Tool-Calling Agents via Divergence-Point Preference Learning
[Paper] · arXiv:2606.23112
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Self-evolving LLM agents with in-distribution Optimization
[Paper] · arXiv:2606.07367
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 5.2 Adapter. -
Self-Improving Embodied Foundation Models
[Paper] · arXiv:2509.15155
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Self-Improving Tabular Language Models via Iterative Reward-Guided Post-Training
[Paper] · arXiv:2604.18966
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Self-Improving VLM Judges Without Human Annotations
[Paper] · arXiv:2512.05145
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Self-Play Enhancement via Advantage-Weighted Refinement in Online Federated LLM Fine-Tuning with Real-Time Feedback
[Paper] · arXiv:2605.07977
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 6.1 Objective. -
Self-Play Fine-Tuning Converts Weak Language Models to Strong Language Models (SPIN)
[Paper] · arXiv:2401.01335
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 8.1 Experience Data. -
Self-playing Adversarial Language Game Enhances LLM Reasoning (SPAG)
[Paper] · arXiv:2404.10642
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Self-Policy Distillation via Capability-Selective Subspace Projection
[Paper] · arXiv:2605.22675
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Self-Reasoning Language Models: Unfold Hidden Reasoning Chains with Few Reasoning Catalyst
[Paper] · arXiv:2505.14116
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 8.1 Experience Data. -
Self-rewarding correction for mathematical reasoning
[Paper] · arXiv:2502.19613
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Self-Rewarding Language Models
[Paper] · arXiv:2401.10020
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 8.1 Experience Data. -
Self-Rewarding Large Vision-Language Models for Optimizing Prompts in Text-to-Image Generation
[Paper] · arXiv:2505.16763
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Self-Rewarding PPO: Aligning Large Language Models with Demonstrations Only
[Paper] · arXiv:2510.21090
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Self-Rewarding Rubric-Based Reinforcement Learning for Open-Ended Reasoning
[Paper] · arXiv:2509.25534
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Self-Taught Evaluators
[Paper] · arXiv:2408.02666
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Self-Trained Verification for Training- and Test-Time Self-Improvement
[Paper] · arXiv:2605.30290
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 6.1 Objective. -
Self-Training Large Language Models for Improved Visual Program Synthesis With Visual Reinforcement
[Paper] · arXiv:2404.04627
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Semi-supervised Instruction Tuning for Large Language Models on Text-Attributed Graphs
[Paper] · arXiv:2601.12807
Taxonomy: L1. Updated object(s): 5.2 Adapter. -
SeRL: Self-Play Reinforcement Learning for Large Language Models with Limited Data
[Paper] · arXiv:2505.20347
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 8.1 Experience Data. -
Skill-Conditioned Gated Self-Distillation for LLM Reasoning
[Paper] · arXiv:2605.28791
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 2.3 Procedural Memory; 6.1 Objective. -
Skill-Guided Continuation Distillation for GUI Agents
[Paper] · arXiv:2606.18890
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 8.1 Experience Data. -
SmartSnap: Proactive Evidence Seeking for Self-Verifying Agents
[Paper] · arXiv:2512.22322
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 6.1 Objective. -
SocraticPO: Policy Optimization via Interactive Guidance
[Paper] · arXiv:2606.09887
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 6.1 Objective. -
Soft-NBCE: Entropy-Weighted Chunk Fusion for Long-Context
[Paper] · arXiv:2606.01101
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
SPPD: Self-training with Process Preference Learning Using Dynamic Value Margin
[Paper] · arXiv:2502.13516
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
SRPO: Self-Referential Policy Optimization for Vision-Language-Action Models
[Paper] · arXiv:2511.15605
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 7.2 Reward / Fitness. -
STaR: Self-Taught Reasoner—Bootstrapping Reasoning With Reasoning
[Paper] · arXiv:2203.14465
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
STEP: Enhancing Video-LLMs' Compositional Reasoning by Spatio-Temporal Graph-guided Self-Training
[Paper] · arXiv:2412.00161
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
StepPRM-RTL: Stepwise Process-Reward Guided LLM Fine-Tuning for Enhanced RTL Synthesis
[Paper] · arXiv:2606.04246
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 7.2 Reward / Fitness. -
Stratagem: Learning Transferable Reasoning via Trajectory-Modulated Game Self-Play
[Paper] · arXiv:2604.17696
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Structured Reasoning for Large Language Models
[Paper] · arXiv:2601.07180
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 6.1 Objective. -
Synergizing Discriminative Exemplars and Self-Refined Experience for MLLM-based In-Context Learning in Medical Diagnosis
[Paper] · arXiv:2603.27737
Taxonomy: L1. Updated object(s): 1.4 Prompt & Context; 2.3 Procedural Memory. -
Synthetic Computers at Scale for Long-Horizon Productivity Simulation
[Paper] · arXiv:2604.28181
Taxonomy: L1. Updated object(s): 4.4 Skill Library; 8.3 Environment. -
Teach-to-Reason: Competition-Guided Reasoning with a Self-Improving Teacher
[Paper] · arXiv:2606.25407
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 6.1 Objective. -
Teaching Large Reasoning Models Effective Reflection
[Paper] · arXiv:2601.12720
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Team-Based Self-Play With Dual Adaptive Weighting for Fine-Tuning LLMs
[Paper] · arXiv:2605.09922
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 6.1 Objective. -
Temporal Self-Rewarding Language Models: Decoupling Chosen-Rejected via Past-Future
[Paper] · arXiv:2508.06026
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 7.1 Judge. -
The Attacker in the Mirror: Breaking Self-Consistency in Safety via Anchored Bipolicy Self-Play
[Paper] · arXiv:2605.08427
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Think Longer to Explore Deeper: Learn to Explore In-Context via Length-Incentivized Reinforcement Learning
[Paper] · arXiv:2602.11748
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 6.1 Objective. -
Thinking Before Running! Efficient Code Generation with Thorough Exploration and Optimal Refinement
[Paper] · arXiv:2502.17442
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Training-Free Test-Time Contrastive Learning for Large Language Models
[Paper] · arXiv:2604.13552
Taxonomy: L1. Updated object(s): 2.3 Procedural Memory; 1.5 Context. -
Transformers Provably Learn Chain-of-Thought Reasoning with Length Generalization
[Paper] · arXiv:2511.07378
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 8.1 Experience Data. -
Transitivity Meets Cyclicity: Explicit Preference Decomposition for Dynamic Large Language Model Alignment
[Paper] · arXiv:2605.17342
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 7.2 Reward / Fitness. -
TRON: Targeted Rule-Verifiable Online Environments for Visual Reasoning RL
[Paper] · arXiv:2606.01599
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 8.2 Task Generator. -
Unsupervised Process Reward Models
[Paper] · arXiv:2605.10158
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 7.1 Judge. -
Utilizing and Calibrating Hindsight Process Rewards via Reinforcement with Mutual Information Self-Evaluation
[Paper] · arXiv:2604.11611
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
VeriGate: Verifier-Gated Step-Level Supervision for GRPO
[Paper] · arXiv:2605.30451
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 6.1 Objective. -
VibeThinker-3B: Exploring the Frontier of Verifiable Reasoning in Small Language Models
[Paper] · arXiv:2606.16140
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
VideoSAVi: Self-Aligned Video Language Models without Human Supervision
[Paper] · arXiv:2412.00624
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
When Good Verifiers Go Bad: Self-Improving VLMs Can Regress on New Tasks
[Paper] · arXiv:2606.14629
Taxonomy: L1. Updated object(s): 5.2 Adapter. -
World Model Self-Distillation: Training World Models to Solve General Tasks
[Paper] · arXiv:2606.12072
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 8.1 Experience Data. -
ZAS-SQL: Distilling Rules from Failures for Zero-Shot Text-to-SQL
[Paper] · arXiv:2606.08245
Taxonomy: L1. Updated object(s): 1.3 Prompt & Context; 3.4 Harness / Workflow.



2. L2 - Autonomy over Improvement Strategies ↑ top
The system chooses how to improve a specified target, while the objective, evaluation criterion, or acceptance rule remains externally specified. 159 papers.
Featured representative papers
| Paper | Representative mechanism |
|---|---|
| AutoPrompt | Uses gradient-guided search to generate discrete prompt tokens for a fixed task. |
| Automatic Prompt Engineer | Uses an LLM to propose prompt instructions and an external evaluator to select them. |
| ProTeGi | Optimizes prompts through textual gradients and beam search. |
| EvoPrompt | Treats prompt optimization as evolutionary search. |
| Eureka | Uses LLM-guided evolutionary optimization over reward code for externally specified RL tasks. |
| ADAS | Proposes, evaluates, and archives improved agentic system designs. |
| AFlow | Searches code-represented agent workflows with execution feedback. |
Browse the full L2 catalog (159 papers)
Table-derived extensions
The following additions are explicitly listed in Table 4, which groups representative L2 systems by the object of improvement-strategy search.
-
Multimodal Prompt Optimization: Why Not Leverage Multiple Modalities for MLLMs
[Paper] · arXiv:2510.09201
Survey-table rationale: Evaluation-derived semantic feedback guides multimodal prompt candidates under a fixed task metric. Updated object(s): 1.1 Instruction; 1.2 Task Prompt / Template. -
Agentic Neural Architecture Search
[Paper] · arXiv:2607.07984
Survey-table rationale: An LLM constructs a task-specific architecture search space, but the validation metric remains fixed. Updated object(s): 5.3 Architecture. -
Auto Research with Specialist Agents Develops Effective and Non-Trivial Training Recipes
[Paper] · arXiv:2605.05724
Survey-table rationale: Specialist agents search over training recipes with a shared lineage under an external evaluator. Updated object(s): 6.5 Search / Meta-optimization Procedure. -
AutoKernel: Autonomous GPU Kernel Optimization via Iterative Agent-Driven Search
[Paper] · arXiv:2603.21331
Survey-table rationale: A profile-rewrite-benchmark loop searches kernel implementations under fixed correctness and speed criteria. Updated object(s): 9.1 Program / Solution Code. -
Adapting AlphaEvolve to Optimize Fully Homomorphic Encryption on TPUs
[Paper] · arXiv:2605.14718
Taxonomy: L2. Updated object(s): 9.1 Program Code. -
AI-PROPELLER: Warehouse-Scale Interprocedural Code Layout Optimization with AlphaEvolve
[Paper] · arXiv:2606.00131
Taxonomy: L2. Updated object(s): 9.2 Algorithm. -
Magellan: Autonomous Discovery of Novel Compiler Optimization Heuristics with AlphaEvolve
[Paper] · arXiv:2601.21096
Taxonomy: L2. Updated object(s): 9.1 Program Code. -
Scientific Algorithm Discovery by Augmenting AlphaEvolve with Deep Research
[Paper] · arXiv:2510.06056
Taxonomy: L2. Updated object(s): 9.2 Algorithm; 2.1 Experience Memory. -
A Self-Improving Coding Agent
[Paper] · arXiv:2504.15228
Taxonomy: L2. Updated object(s): 3.6 Scaffold Code; 4.3 Tool Code; 1.1 Instruction. -
Adaptive Self-improvement LLM Agentic System for ML Library Development
[Paper] · arXiv:2502.02534
Taxonomy: L2. Updated object(s): 1.4 Prompt & Context; 1.5 Context. -
Advanced For-Loop for QML algorithm search
[Paper] · arXiv:2506.18260
Taxonomy: L2. Updated object(s): 9.2 Algorithm; 9.1 Program Code. -
AFlow: Automating Agentic Workflow Generation
[Paper] · arXiv:2410.10762
Taxonomy: L2. Updated object(s): 3.6 Scaffold Code; 1.2 Task Prompt. -
AgentDisCo: Towards Disentanglement and Collaboration in Open-ended Deep Research Agents
[Paper] · arXiv:2605.11732
Taxonomy: L2. Updated object(s): 1.1 Instruction; 3.6 Scaffold Code. -
Agentic Context Engineering: Evolving Contexts for Self-Improving Language Models
[Paper] · arXiv:2510.04618
Taxonomy: L2. Updated object(s): 1.5 Context; 2.4 Memory & Knowledge. -
Agentic Discovery of Neural Architectures: AIRA-Compose and AIRA-Design
[Paper] · arXiv:2605.15871
Taxonomy: L2. Updated object(s): 9.2 Algorithm; 9.3 External Artifact. -
Agentic Harness Engineering: Observability-Driven Automatic Evolution of Coding-Agent Harnesses
[Paper] · arXiv:2604.25850
Taxonomy: L2. Updated object(s): 3.6 Scaffold Code; 4.3 Tool Code. -
Agentic MIP Research: Accelerated Constraint Handler Generation
[Paper] · arXiv:2605.09186
Taxonomy: L2. Updated object(s): 9.1 Program Code; 9.2 Algorithm. -
AgenticRL: Self-Refining Agentic Reinforcement Learning for Vision-Conditioned UAV Navigation
[Paper] · arXiv:2606.03963
Taxonomy: L2. Updated object(s): 6.1 Objective; 5.1 Model Weights. -
Ask, Don't Judge: Binary Questions for Interpretable LLM Evaluation and Self-Improvement
[Paper] · arXiv:2606.27226
Taxonomy: L2. Updated object(s): 1.1 Instruction. -
ASPIRE: Agentic Skills Discovery for Robotics
[Paper] · arXiv:2607.00272
Taxonomy: L2. Updated object(s): 4.4 Skill Library; 9.1 Program Code. -
Auto-Configuring Scientific Simulators with Lightweight Coding-Agent Adapters
[Paper] · arXiv:2606.09774
Taxonomy: L2. Updated object(s): 2.3 Procedural Memory; 1.1 Instruction; 4.4 Skill Library. -
Automated Design of Agentic Systems (ADAS)
[Paper] · arXiv:2408.08435
Taxonomy: L2. Updated object(s): 3.6 Scaffold Code. -
Automated Heuristic Design for Unit Commitment Using Large Language Models
[Paper] · arXiv:2506.12495
Taxonomy: L2. Updated object(s): 9.2 Algorithm; 9.1 Program Code. -
AutoMegaKernel: A Statically-Checked Agent Harness for Self-Retargeting Megakernel Synthesis
[Paper] · arXiv:2606.09682
Taxonomy: L2. Updated object(s): 9.1 Program Code. -
AutoPass: Evidence-Guided LLM Agents for Compiler Performance Tuning
[Paper] · arXiv:2606.20373
Taxonomy: L2. Updated object(s): 9.2 Algorithm. -
AutoPrompt: Eliciting Knowledge from Language Models with Automatically Generated Prompts
[Paper] · arXiv:2010.15980
Taxonomy: L2. Updated object(s): 1.2 Task Prompt. -
AutoPyVerifier: Learning Compact Executable Verifiers for Large Language Model Outputs
[Paper] · arXiv:2604.22937
Taxonomy: L2. Updated object(s): 7.3 Verifier; 7.1 Judge. -
AutoVQA-G: Self-Improving Agentic Framework for Automated Visual Question Answering and Grounding Annotation
[Paper] · arXiv:2604.17488
Taxonomy: L2. Updated object(s): 1.2 Task Prompt; 1.1 Instruction. -
Beyond Algorithm Evolution: An LLM-Driven Framework for the Co-Evolution of Swarm Intelligence Optimization Algorithms and Prompts
[Paper] · arXiv:2512.09209
Taxonomy: L2. Updated object(s): 9.2 Algorithm; 1.1 Instruction. -
Beyond Scalar Rewards: Dense Feedback for LLM Policy Synthesis in Sequential Social Dilemmas
[Paper] · arXiv:2603.19453
Taxonomy: L2. Updated object(s): 9.1 Program Code. -
Beyond Static Tools: Test-Time Tool Evolution for Scientific Reasoning
[Paper] · arXiv:2601.07641
Taxonomy: L2. Updated object(s): 4.1 Tool Set; 4.2 Tool Interface. -
BT-APE: A Computationally Light Backtracking Approach to Automatic Prompt Engineering for Requirements Classification
[Paper] · arXiv:2607.00427
Taxonomy: L2. Updated object(s): 1.2 Task Prompt. -
CausalEvolve: Towards Open-Ended Discovery with Causal Scratchpad
[Paper] · arXiv:2603.14575
Taxonomy: L2. Updated object(s): 9.1 Program Code; 2.1 Experience Memory. -
CHIA: An open-source framework for principled, agentic AI-driven hardware/software co-design research
[Paper] · arXiv:2606.27350
Taxonomy: L2. Updated object(s): 9.1 Program Code. -
Co-evolving Agent Architectures and Interpretable Reasoning for Automated Optimization
[Paper] · arXiv:2604.17708
Taxonomy: L2. Updated object(s): 3.1 Workflow; 2.2 Knowledge Memory. -
CodeEvolve: an open source evolutionary coding agent for algorithmic discovery and optimization
[Paper] · arXiv:2510.14150
Taxonomy: L2. Updated object(s): 9.1 Program Code; 1.2 Task Prompt. -
CoEvoSkills: Self-Evolving Agent Skills via Co-Evolutionary Verification
[Paper] · arXiv:2604.01687
Taxonomy: L2. Updated object(s): 4.4 Skill Library. -
Combee: Scaling Prompt Learning for Self-Improving Language Model Agents
[Paper] · arXiv:2604.04247
Taxonomy: L2. Updated object(s): 1.1 Instruction; 1.5 Context. -
Combining Large Language Models and Gradient-Free Optimization for Automatic Control Policy Synthesis
[Paper] · arXiv:2510.00373
Taxonomy: L2. Updated object(s): 9.1 Program Code. -
Competing with AI Scientists: Agent-Driven Approach to Astrophysics Research
[Paper] · arXiv:2604.09621
Taxonomy: L2. Updated object(s): 9.1 Program Code. -
Continually self-improving AI
[Paper] · arXiv:2603.18073
Taxonomy: L2. Updated object(s): 6.5 Meta-optimization; 6.1 Objective; 5.1 Model Weights. -
CORAL: Towards Autonomous Multi-Agent Evolution for Open-Ended Discovery
[Paper] · arXiv:2604.01658
Taxonomy: L2. Updated object(s): 9.1 Program Code; 4.4 Skill Library. -
DataEvolver: Automatic Data Preparation for Large Language Models through Multi-Level Self-Evolving
[Paper] · arXiv:2606.07001
Taxonomy: L2. Updated object(s): 8.1 Experience Data; 9.1 Program Code. -
Defining Cost Function of Steganography with Large Language Models
[Paper] · arXiv:2512.09769
Taxonomy: L2. Updated object(s): 9.2 Algorithm. -
DeltaEvolve: Accelerating Scientific Discovery through Momentum-Driven Evolution
[Paper] · arXiv:2602.02919
Taxonomy: L2. Updated object(s): 9.1 Program Code. -
Discovering Multiagent Learning Algorithms with Large Language Models
[Paper] · arXiv:2602.16928
Taxonomy: L2. Updated object(s): 9.2 Algorithm. -
DrugSAGE: Self-evolving Agent Experience for Efficient State-of-the-Art Drug Discovery
[Paper] · arXiv:2605.15461
Taxonomy: L2. Updated object(s): 4.4 Skill Library; 2.2 Knowledge Memory. -
Each Judge Its Own Yardstick: Discovering Per-VLM Taxonomies for Physical Video Evaluation
[Paper] · arXiv:2606.22918
Taxonomy: L2. Updated object(s): 7.1 Judge. -
EEVEE: Towards Test-time Prompt Learning in the Real World for Self-Improving Agents
[Paper] · arXiv:2606.11182
Taxonomy: L2. Updated object(s): 1.1 Instruction; 3.3 Harness / Workflow. -
Effective Harness Engineering for Algorithm Discovery with Coding Agents
[Paper] · arXiv:2605.15221
Taxonomy: L2. Updated object(s): 9.1 Program Code; 9.2 Algorithm. -
ELMES+: Automated Construction of Fine-Grained Evaluation Rubrics for Large Language Models in Long-Tail Educational Scenarios
[Paper] · arXiv:2606.06546
Taxonomy: L2. Updated object(s): 7.1 Judge; 8.2 Task Generator. -
EmbodiSkill: Skill-Aware Reflection for Self-Evolving Embodied Agents
[Paper] · arXiv:2605.10332
Taxonomy: L2. Updated object(s): 4.4 Skill Library. -
Enhancing Operational Safety via Agentic Dialogue Hazard Identification Analysis
[Paper] · arXiv:2606.03812
Taxonomy: L2. Updated object(s): 3.5 Multi-agent; 1.1 Instruction. -
Environment-Grounded Automated Prompt Optimization for LLM Game Agents
[Paper] · arXiv:2606.17838
Taxonomy: L2. Updated object(s): 1.1 Instruction; 1.2 Task Prompt. -
EpiAgent: An Agent-Centric System for Ancient Inscription Restoration
[Paper] · arXiv:2604.09367
Taxonomy: L2. Updated object(s): 2.1 Experience Memory; 2.3 Procedural Memory. -
Eureka: Human-Level Reward Design via Coding Large Language Models
[Paper] · arXiv:2310.12931
Taxonomy: L2. Updated object(s): 7.2 Reward / Fitness. -
Eureka: Intelligent Feature Engineering for Enterprise AI Cloud Resource Demand Prediction
[Paper] · arXiv:2605.25297
Taxonomy: L2. Updated object(s): 9.1 Program Code; 5.1 Model Weights. -
EvoClinician: A Self-Evolving Agent for Multi-Turn Medical Diagnosis via Test-Time Evolutionary Learning
[Paper] · arXiv:2601.22964
Taxonomy: L2. Updated object(s): 1.1 Instruction; 2.1 Experience Memory. -
EvoLattice: Persistent Internal-Population Evolution through Multi-Alternative Quality-Diversity Graph Representations for LLM-Guided Program Discovery
[Paper] · arXiv:2512.13857
Taxonomy: L2. Updated object(s): 9.1 Program Code; 9.2 Algorithm. -
Evolution of Heuristics: Towards Efficient Automatic Algorithm Design Using Large Language Model
[Paper] · arXiv:2401.02051
Taxonomy: L2. Updated object(s): 9.2 Algorithm; 9.1 Program Code. -
EvolveSignal: A Large Language Model Powered Coding Agent for Discovering Traffic Signal Control Strategies
[Paper] · arXiv:2509.03335
Taxonomy: L2. Updated object(s): 9.1 Program Code. -
Evolving Deception: When Agents Evolve, Deception Wins
[Paper] · arXiv:2603.05872
Taxonomy: L2. Updated object(s): 1.1 Instruction. -
Evolving Medical Imaging Agents via Experience-Driven Self-Skill Discovery
[Paper] · arXiv:2603.05860
Taxonomy: L2. Updated object(s): 4.4 Skill Library; 5.1 Model Weights; 2.1 Experience Memory. -
EVOM: Agentic Meta-Evolution of Actor-Critic Architectures for Reinforcement Learning
[Paper] · arXiv:2606.26327
Taxonomy: L2. Updated object(s): 5.3 Architecture. -
EvoPrompt: Connecting LLMs with Evolutionary Algorithms Yields Powerful Prompt Optimizers
[Paper] · arXiv:2309.08532
Taxonomy: L2. Updated object(s): 1.2 Task Prompt. -
EvoScientist: Towards Multi-Agent Evolving AI Scientists for End-to-End Scientific Discovery
[Paper] · arXiv:2603.08127
Taxonomy: L2. Updated object(s): 2.2 Knowledge Memory; 1.5 Context. -
EvoTest: Evolutionary Test-Time Learning for Self-Improving Agentic Systems
[Paper] · arXiv:2510.13220
Taxonomy: L2. Updated object(s): 1.1 Instruction; 2.1 Experience Memory; 5.4 Model. -
Experience Graphs: The Data Foundation for Self-Improving Agents
[Paper] · arXiv:2606.29823
Taxonomy: L2. Updated object(s): 2.1 Experience Memory; 2.4 Memory & Knowledge. -
Experience Makes Skillful: Enabling Generalizable Medical Agent Reasoning via Self-Evolving Skill Memory
[Paper] · arXiv:2606.09365
Taxonomy: L2. Updated object(s): 2.3 Procedural Memory; 2.5 Memory & Knowledge. -
ExpGraph: Model-Agnostic Experience Learning with Graph-Structured Memory for LLM Agents
[Paper] · arXiv:2605.30712
Taxonomy: L2. Updated object(s): 2.1 Experience Memory; 2.4 Memory & Knowledge; 5.2 Adapter. -
FederatedSkill: Federated Learning for Agentic Skill Evolution
[Paper] · arXiv:2606.03143
Taxonomy: L2. Updated object(s): 4.4 Skill Library; 2.2 Knowledge Memory. -
Feedback Over Form: Why Execution Feedback Matters More Than Pipeline Topology in 1-3B Code Generation
[Paper] · arXiv:2604.21950
Taxonomy: L2. Updated object(s): 3.1 Workflow. -
Feedback-to-Rubrics: Can We Learn Expert Criteria from Inline Comments?
[Paper] · arXiv:2605.29857
Taxonomy: L2. Updated object(s): 7.1 Judge; 1.1 Instruction. -
From AI Assistant to AI Scientist: Autonomous Discovery of LLM-RL Algorithms with LLM Agents
[Paper] · arXiv:2603.23951
Taxonomy: L2. Updated object(s): 6.1 Objective; 6.2 Trainer / Optimization. -
From Failed Trajectories to Reliable LLM Agents: Diagnosing and Repairing Harness Flaws
[Paper] · arXiv:2606.06324
Taxonomy: L2. Updated object(s): 3.6 Scaffold Code; 1.2 Task Prompt; 4.2 Tool Interface. -
From Self-Evolving Synthetic Data to Verifiable-Reward RL: Post-Training Multi-turn Interactive Tool-Using Agents
[Paper] · arXiv:2601.22607
Taxonomy: L2. Updated object(s): 8.1 Experience Data; 5.1 Model Weights. -
From Understanding to Excelling: Template-Free Algorithm Design through Structural-Functional Co-Evolution
[Paper] · arXiv:2503.10721
Taxonomy: L2. Updated object(s): 9.1 Program Code; 9.2 Algorithm; 6.5 Meta-optimization. -
From User Interface to Agent Interface: Efficiency Optimization of UI Representations for LLM Agents
[Paper] · arXiv:2512.13438
Taxonomy: L2. Updated object(s): 9.1 Program Code. -
FuzzAgent: Multi-Agent System for Evolutionary Library Fuzzing
[Paper] · arXiv:2605.14431
Taxonomy: L2. Updated object(s): 9.1 Program Code. -
GeoEvolve: Automating Geospatial Model Discovery via Multi-Agent Large Language Models
[Paper] · arXiv:2509.21593
Taxonomy: L2. Updated object(s): 9.2 Algorithm. -
GEPA: Reflective Prompt Evolution Can Outperform Reinforcement Learning
[Paper] · arXiv:2507.19457
Taxonomy: L2. Updated object(s): 1.1 Instruction. -
GigaEvo: An Open Source Optimization Framework Powered By LLMs And Evolution Algorithms
[Paper] · arXiv:2511.17592
Taxonomy: L2. Updated object(s): 9.2 Algorithm; 9.1 Program Code; 1.1 Instruction. -
Hardening Agent Benchmarks with Adversarial Hacker-Fixer Loops
[Paper] · arXiv:2606.08960
Taxonomy: L2. Updated object(s): 7.3 Verifier; 8.3 Environment. -
Healthcare Mechanisms from Policy-as-Code Search under Strategic Provider Response
[Paper] · arXiv:2605.30680
Taxonomy: L2. Updated object(s): 9.2 Algorithm. -
Heuresis: Search Strategies for Autonomous AI Research Agents Across Quality, Diversity and Novelty
[Paper] · arXiv:2606.25198
Taxonomy: L2. Updated object(s): 9.1 Program Code; 9.2 Algorithm. -
Hierarchical Experimentalist Agents
[Paper] · arXiv:2606.29315
Taxonomy: L2. Updated object(s): 4.4 Skill Library. -
HSEvo: Elevating Automatic Heuristic Design with Diversity-Driven Harmony Search and Genetic Algorithm Using LLMs
[Paper] · arXiv:2412.14995
Taxonomy: L2. Updated object(s): 9.1 Program Code; 6.5 Meta-optimization. -
HypoForge: A Self-Improving Multi-Agent Framework for Automated Hypothesis Generation and Testing via Scientific Skill Learning
[Paper] · arXiv:2608.25770
Taxonomy: L2. Updated object(s): 4.4 Skill Library. -
ImprovEvolve: Basin-Hopping Meets LLM-Guided Evolutionary Search
[Paper] · arXiv:2602.10233
Taxonomy: L2. Updated object(s): 9.1 Program Code; 9.2 Algorithm. -
InvEvolve: Evolving White-Box Inventory Policies via Large Language Models with Performance Guarantees
[Paper] · arXiv:2605.00369
Taxonomy: L2. Updated object(s): 9.1 Program Code; 5.1 Model Weights. -
ISM: Self-Improving Strategy Memory for Continual Mathematical Reasoning
[Paper] · arXiv:2606.31191
Taxonomy: L2. Updated object(s): 2.3 Procedural Memory; 2.4 Memory & Knowledge. -
IterInject: Indirect Prompt Injection Against LLM Agents via Feedback-Guided Iterative Optimization
[Paper] · arXiv:2605.24659
Taxonomy: L2. Updated object(s): 1.2 Task Prompt. -
Kernel Foundry: A Diagnosis-driven Evolutionary Kernel Optimizer with Multi-Experts
[Paper] · arXiv:2605.30359
Taxonomy: L2. Updated object(s): 9.1 Program Code; 2.3 Procedural Memory. -
Large Language Models Are Human-Level Prompt Engineers (Automatic Prompt Engineer, APE)
[Paper] · arXiv:2211.01910
Taxonomy: L2. Updated object(s): 1.1 Instruction. -
Large Language Models as Optimizers
[Paper] · arXiv:2309.03409
Taxonomy: L2. Updated object(s): 1.2 Task Prompt. -
Learning from Failure: Inference-Time Self-Improvement for Computer-Use Agents
[Paper] · arXiv:2606.31270
Taxonomy: L2. Updated object(s): 3.6 Scaffold Code; 4.1 Tool Set; 3.4 Harness / Workflow. -
Learning to Choose: An Empowerment-Guided Multi-Agent System with semantic communication for Adaptive Method Selection
[Paper] · arXiv:2605.30042
Taxonomy: L2. Updated object(s): 3.3 Harness / Workflow; 2.1 Experience Memory. -
LEVI: Stronger Search Architectures Can Substitute for Larger LLMs in Evolutionary Search
[Paper] · arXiv:2605.09764
Taxonomy: L2. Updated object(s): 9.1 Program Code; 1.2 Task Prompt. -
Libra: Training the Environment for Agentic Information Retrieval
[Paper] · arXiv:2607.00016
Taxonomy: L2. Updated object(s): 2.2 Knowledge Memory; 8.3 Environment. -
LLaMEA-BO: A Large Language Model Evolutionary Algorithm for Automatically Generating Bayesian Optimization Algorithms
[Paper] · arXiv:2505.21034
Taxonomy: L2. Updated object(s): 9.2 Algorithm; 9.1 Program Code. -
LLM as a Tool, Not an Agent: Code-Mined Tree Transformations for Neural Architecture Search
[Paper] · arXiv:2604.16555
Taxonomy: L2. Updated object(s): 9.3 External Artifact. -
LLM-Evolved Pattern Generators for Optimal Classical Planning
[Paper] · arXiv:2606.02438
Taxonomy: L2. Updated object(s): 9.1 Program Code. -
LLM-Guided Evolutionary Program Synthesis for Quasi-Monte Carlo Design
[Paper] · arXiv:2510.03650
Taxonomy: L2. Updated object(s): 9.2 Algorithm. -
LLM-Guided Search for Deletion-Correcting Codes
[Paper] · arXiv:2504.00613
Taxonomy: L2. Updated object(s): 9.2 Algorithm. -
LoongFlow: Directed Evolutionary Search via a Cognitive Plan-Execute-Summarize Paradigm
[Paper] · arXiv:2512.24077
Taxonomy: L2. Updated object(s): 9.2 Algorithm; 9.1 Program Code. -
Mathematical exploration and discovery at scale
[Paper] · arXiv:2511.02864
Taxonomy: L2. Updated object(s): 9.1 Program Code; 9.2 Algorithm. -
Mechanistically Eliciting Latent Behaviors in Language Models
[Paper] · arXiv:2606.29604
Taxonomy: L2. Updated object(s): 5.2 Adapter. -
Medical Heuristic Learning: An LLM-Driven Framework for Interpretable and Auditable Clinical Decision Rules
[Paper] · arXiv:2606.16337
Taxonomy: L2. Updated object(s): 9.1 Program Code. -
MEMENTO: Leveraging Web as a Learning Signal for Low-Data Domains
[Paper] · arXiv:2605.29795
Taxonomy: L2. Updated object(s): 2.3 Procedural Memory; 2.2 Knowledge Memory. -
MEMO: Memory-Augmented Model Context Optimization for Robust Multi-Turn Multi-Agent LLM Games
[Paper] · arXiv:2603.09022
Taxonomy: L2. Updated object(s): 1.2 Task Prompt; 2.2 Knowledge Memory. -
Meta-Harness: End-to-End Optimization of Model Harnesses
[Paper] · arXiv:2603.28052
Taxonomy: L2. Updated object(s): 3.6 Scaffold Code. -
Middo: Model-Informed Dynamic Data Optimization for Enhanced LLM Fine-Tuning via Closed-Loop Learning
[Paper] · arXiv:2508.21589
Taxonomy: L2. Updated object(s): 8.1 Experience Data; 5.1 Model Weights. -
Mining Generalizable Activation Functions
[Paper] · arXiv:2602.05688
Taxonomy: L2. Updated object(s): 9.2 Algorithm. -
MLEvolve: A Self-Evolving Framework for Automated Machine Learning Algorithm Discovery
[Paper] · arXiv:2606.06473
Taxonomy: L2. Updated object(s): 9.1 Program Code; 9.2 Algorithm. -
MobEvolve: An Agentic Self-Evolving Heuristic System for Interpretable Human Mobility Generation
[Paper] · arXiv:2606.01640
Taxonomy: L2. Updated object(s): 9.1 Program Code; 2.1 Experience Memory. -
OpenComputer: Verifiable Software Worlds for Computer-Use Agents
[Paper] · arXiv:2605.19769
Taxonomy: L2. Updated object(s): 7.3 Verifier; 8.1 Experience Data; 8.3 Environment. -
Organize then Retrieve: Hierarchical Memory Navigation for Efficient Agents
[Paper] · arXiv:2606.11680
Taxonomy: L2. Updated object(s): 4.4 Skill Library; 5.1 Model Weights. -
PACEvolve++: Improving Test-time Learning for Evolutionary Search Agents
[Paper] · arXiv:2605.07039
Taxonomy: L2. Updated object(s): 5.1 Model Weights; 9.1 Program Code. -
Persona Generators: Generating Diverse Synthetic Personas for Arbitrary Contexts
[Paper] · arXiv:2602.03545
Taxonomy: L2. Updated object(s): 9.1 Program Code. -
Polaris: A Gödel Agent Framework for Small Language Models through Experience-Abstracted Policy Repair
[Paper] · arXiv:2603.23129
Taxonomy: L2. Updated object(s): 3.6 Scaffold Code; 2.3 Procedural Memory. -
ProfiLLM: Utility-Aligned Agentic User Profiling for Industrial Ride-Hailing Dispatch
[Paper] · arXiv:2606.18803
Taxonomy: L2. Updated object(s): 5.1 Model Weights; 8.1 Experience Data. -
PromptAgent: Strategic Planning with Language Models Enables Expert-level Prompt Optimization
[Paper] · arXiv:2310.16427
Taxonomy: L2. Updated object(s): 1.2 Task Prompt. -
PromptWizard: Task-Aware Prompt Optimization Framework
[Paper] · arXiv:2405.18369
Taxonomy: L2. Updated object(s): 1.1 Instruction; 1.4 Prompt & Context. -
ProTeGi: Automatic Prompt Optimization with 'Gradient Descent' and Beam Search
[Paper] · arXiv:2305.03495
Taxonomy: L2. Updated object(s): 1.2 Task Prompt. -
PYTHALAB-MERA: Validation-Grounded Memory, Retrieval, and Acceptance Control for Frozen-LLM Coding Agents
[Paper] · arXiv:2605.08468
Taxonomy: L2. Updated object(s): 2.1 Experience Memory; 1.5 Context; 4.4 Skill Library. -
QUBE: Enhancing Automatic Heuristic Design via Quality-Uncertainty Balanced Evolution
[Paper] · arXiv:2412.20694
Taxonomy: L2. Updated object(s): 9.1 Program Code; 6.5 Meta-optimization. -
QueenBee Planner: Skill-Evolving Communication Topologies for Token-Efficient LLM Multi-Agent Systems
[Paper] · arXiv:2606.27492
Taxonomy: L2. Updated object(s): 2.3 Procedural Memory; 3.5 Multi-agent. -
RankEvolve: Automating the Discovery of Retrieval Algorithms via LLM-Driven Evolution
[Paper] · arXiv:2602.16932
Taxonomy: L2. Updated object(s): 9.2 Algorithm. -
Recursive Harness Self-Improvement
[Paper] · arXiv:2607.15524
Taxonomy: L2. Updated object(s): 3.1 Workflow; 3.5 Multi-agent. -
Reflection-Based Task Adaptation for Self-Improving VLA
[Paper] · arXiv:2510.12710
Taxonomy: L2. Updated object(s): 5.1 Model Weights; 7.2 Reward / Fitness; 6.4 Curriculum. -
REFLEX: Reflective Evolution from LLM Experience
[Paper] · arXiv:2606.16496
Taxonomy: L2. Updated object(s): 9.1 Program Code; 4.4 Skill Library. -
Repeated post-training is not Self-improving: Diagnosing Scientific Amnesia in Continual DPO Pipelines
[Paper] · arXiv:2606.21089
Taxonomy: L2. Updated object(s): 5.1 Model Weights; 6.5 Meta-optimization. -
Rethinking Code Similarity for Automated Algorithm Design with LLMs
[Paper] · arXiv:2603.02787
Taxonomy: L2. Updated object(s): 7.2 Reward / Fitness; 3.6 Scaffold Code. -
Revisiting OPRO: The Limitations of Small-Scale LLMs as Optimizers
[Paper] · arXiv:2405.10276
Taxonomy: L2. Updated object(s): 1.2 Task Prompt. -
RLPrompt: Optimizing Discrete Text Prompts with Reinforcement Learning
[Paper] · arXiv:2205.12548
Taxonomy: L2. Updated object(s): 1.2 Task Prompt. -
S1-NexusAgent: a Self-Evolving Agent Framework for Multidisciplinary Scientific Research
[Paper] · arXiv:2602.01550
Taxonomy: L2. Updated object(s): 4.4 Skill Library. -
Self-Consolidating Language Models: Continual Knowledge Incorporation from Context
[Paper] · arXiv:2605.07076
Taxonomy: L2. Updated object(s): 5.1 Model Weights; 5.2 Adapter. -
Self-Harness: Harnesses That Improve Themselves
[Paper] · arXiv:2606.09498
Taxonomy: L2. Updated object(s): 3.6 Scaffold Code; 1.1 Instruction. -
Self-Improvement Can Self-Regress: The Rise-and-Collapse Failure Mode of LLM Self-Training
[Paper] · arXiv:2606.21090
Taxonomy: L2. Updated object(s): 5.1 Model Weights; 6.5 Meta-optimization. -
SePO: Self-Evolving Prompt Agent for System Prompt Optimization
[Paper] · arXiv:2606.04465
Taxonomy: L2. Updated object(s): 1.2 Task Prompt; 1.1 Instruction. -
SGM: A Statistical Godel Machine for Risk-Controlled Recursive Self-Modification
[Paper] · arXiv:2510.10232
Taxonomy: L2. Updated object(s): 6.3 Train Schedule. -
SHARP: A Self-Evolving Human-Auditable Rubric Policy for Financial Trading Agents
[Paper] · arXiv:2605.06822
Taxonomy: L2. Updated object(s): 1.1 Instruction. -
SIA: Self Improving AI with Harness & Weight Updates
[Paper] · arXiv:2605.27276
Taxonomy: L2. Updated object(s): 10.2 Full-system / Co-evolution; 3.6 Scaffold Code; 5.1 Model Weights. -
SignalClaw: LLM-Guided Evolutionary Synthesis of Interpretable Traffic Signal Control Skills
[Paper] · arXiv:2604.05535
Taxonomy: L2. Updated object(s): 9.1 Program Code; 4.4 Skill Library. -
Skill-R1: Agent Skill Evolution via Reinforcement Learning
[Paper] · arXiv:2605.09359
Taxonomy: L2. Updated object(s): 4.4 Skill Library; 5.1 Model Weights. -
SkillCoach: Self-Evolving Rubrics for Evaluating and Enhancing Agentic Skill-Use
[Paper] · arXiv:2607.01874
Taxonomy: L2. Updated object(s): 7.1 Judge; 5.1 Model Weights; 6.4 Curriculum. -
SkillMaster: Toward Autonomous Skill Mastery in LLM Agents
[Paper] · arXiv:2605.08693
Taxonomy: L2. Updated object(s): 4.4 Skill Library; 5.1 Model Weights. -
SkillRevise: Improving LLM-Authored Agent Skills via Trace-Conditioned Skill Revision
[Paper] · arXiv:2606.01139
Taxonomy: L2. Updated object(s): 4.4 Skill Library. -
SkillSmith: Co-Evolving Skills and Tools for Self-Improving Agent Systems
[Paper] · arXiv:2606.01314
Taxonomy: L2. Updated object(s): 4.4 Skill Library; 4.3 Tool Code; 2.1 Experience Memory. -
SOCIA-EVO: Automated Simulator Construction via Dual-Anchored Bi-Level Optimization
[Paper] · arXiv:2604.17351
Taxonomy: L2. Updated object(s): 2.2 Knowledge Memory; 9.1 Program Code. -
Support Vector Rubrics: Closing the Gap Between Self-Generated and Human Rubrics
[Paper] · arXiv:2606.08077
Taxonomy: L2. Updated object(s): 7.1 Judge; 1.3 Prompt & Context. -
Taming I2V models for Image HOI Editing: A Cognitive Benchmark and Agentic Self-Correcting Framework
[Paper] · arXiv:2606.19073
Taxonomy: L2. Updated object(s): 2.2 Knowledge Memory; 1.2 Task Prompt. -
The Time is Here for Just-in-Time Systems: Challenges and Opportunities
[Paper] · arXiv:2605.24096
Taxonomy: L2. Updated object(s): 9.1 Program Code. -
Towards AGI A Pragmatic Approach Towards Self Evolving Agent
[Paper] · arXiv:2601.11658
Taxonomy: L2. Updated object(s): 4.1 Tool Set; 5.1 Model Weights. -
Trajectory-Informed Memory Generation for Self-Improving Agent Systems
[Paper] · arXiv:2603.10600
Taxonomy: L2. Updated object(s): 2.3 Procedural Memory; 1.5 Context. -
Understanding the Challenges in Iterative Generative Optimization with LLMs
[Paper] · arXiv:2603.23994
Taxonomy: L2. Updated object(s): 9.1 Program Code; 1.2 Task Prompt; 3.6 Scaffold Code. -
Unifying Temporal and Structural Credit Assignment in LLM-Based Multi-Agent Prompt Optimization
[Paper] · arXiv:2605.30227
Taxonomy: L2. Updated object(s): 1.1 Instruction. -
VASO: Formally Verifiable Self-Evolving Skills for Physical AI Agents
[Paper] · arXiv:2606.05395
Taxonomy: L2. Updated object(s): 4.4 Skill Library; 4.2 Tool Interface. -
When LLM Reward Design Fails: Diagnostic-Driven Refinement for Sparse Structured RL
[Paper] · arXiv:2605.28918
Taxonomy: L2. Updated object(s): 9.1 Program Code.

3. L3 - Autonomy over Future Learning Experience ↑ top
The learner's evolving state influences the experience, task, or curriculum acquired next. 65 papers.
Featured representative papers
| Paper | Representative mechanism |
|---|---|
| POET | Co-evolves environments and solvers to generate an expanding adaptive curriculum. |
| Voyager | Couples automatic curricula with a persistent skill library for open-ended embodied learning. |
| EnvGen | Generates and adapts training environments for embodied agents. |
| Absolute Zero | Lets a single model propose and solve code-grounded tasks, with a code executor verifying both tasks and answers. |
| R-Zero | Co-evolves task proposal and solving to create new learning experience from zero data. |
| SIMA 2 | Uses Gemini to generate tasks and rewards so the agent can autonomously learn skills in a new virtual environment. |
Browse the full L3 catalog (65 papers)
Table-derived extension
Table 5 identifies the following learner-conditioned future-experience loop, complementary to the self-play and autonomous-practice systems already in this section.
-
SIMA 2: A Generalist Embodied Agent for Virtual Worlds
[Paper] · arXiv:2512.04797
Survey-table rationale: In the full ASKA setting, evaluation feedback directs practice toward weaker skills; later experience is conditioned on the learner's changing capability state. Updated object(s): 8.1 Training / Experience Data; 8.2 Task / Curriculum Generator; 8.3 Environment / Simulator. -
Absolute Zero: Reinforced Self-play Reasoning with Zero Data
[Paper] · arXiv:2505.03335
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 8.2 Task Generator. -
Active Zero: Self-Evolving Vision-Language Models through Active Environment Exploration
[Paper] · arXiv:2602.11241
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 8.2 Task Generator. -
Agent0: Unleashing Self-Evolving Agents from Zero Data via Tool-Integrated Reasoning
[Paper] · arXiv:2511.16043
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 8.2 Task Generator. -
ANCORA: Learning to Question via Manifold-Anchored Self-Play for Verifiable Reasoning
[Paper] · arXiv:2604.27644
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 8.2 Task Generator; 6.4 Curriculum. -
ASH: Agents that Self-Hone via Embodied Learning
[Paper] · arXiv:2605.14211
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 2.1 Experience Memory. -
BenchEvolver: Frontier Task Synthesis via Solution-Centric Evolution
[Paper] · arXiv:2606.01286
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 8.2 Task Generator. -
Better LLM Reasoning via Dual-Play
[Paper] · arXiv:2511.11881
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 8.2 Task Generator. -
Close the Loop: Synthesizing Infinite Tool-Use Data via Multi-Agent Role-Playing
[Paper] · arXiv:2512.23611
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 8.1 Experience Data. -
Concordia: Self-Improving Synthetic Tables for Federated LLMs
[Paper] · arXiv:2605.09855
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 8.1 Experience Data. -
DISCOVER: Automated Curricula for Sparse-Reward Reinforcement Learning
[Paper] · arXiv:2505.19850
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 8.1 Experience Data. -
Disentangling Intent from Role: Adversarial Self-Play for Persona-Invariant Safety Alignment
[Paper] · arXiv:2605.01899
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 8.1 Experience Data. -
DUEL: Adversarial Self-Play for Multimodal Reasoning
[Paper] · arXiv:2605.24794
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 8.2 Task Generator. -
EnvGen: Generating and Adapting Environments via LLMs for Training Embodied Agents
[Paper] · arXiv:2403.12014
Taxonomy: L3. Updated object(s): 8.2 Task Generator; 5.1 Model Weights. -
EnvHarness: Awakening Static Worlds for Agent Learning
[Paper] · arXiv:2608.19880
Taxonomy: L3. Updated object(s): 8.3 Environment; 4.4 Skill Library. -
EvoCurr: Self-evolving Curriculum with Behavior Code Generation for Complex Decision-making
[Paper] · arXiv:2508.09586
Taxonomy: L3. Updated object(s): 8.2 Task Generator; 9.1 Program Code. -
EvoLMM: Self-Evolving Large Multimodal Models with Continuous Rewards
[Paper] · arXiv:2511.16672
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 8.2 Task Generator. -
EvoVid: Temporal-Centric Self-Evolution for Video Large Language Models
[Paper] · arXiv:2605.21931
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 8.2 Task Generator. -
From Context to Skills: Can Language Models Learn from Context Skillfully?
[Paper] · arXiv:2604.27660
Taxonomy: L3. Updated object(s): 4.4 Skill Library; 8.2 Task Generator. -
G-Zero: Self-Play for Open-Ended Generation from Zero Data
[Paper] · arXiv:2605.09959
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 8.2 Task Generator. -
GASP: Guided Asymmetric Self-Play For Coding LLMs
[Paper] · arXiv:2603.15957
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 8.1 Experience Data. -
GenEnv: Difficulty-Aligned Co-Evolution Between LLM Agents and Environment Simulators
[Paper] · arXiv:2512.19682
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 8.2 Task Generator. -
GeoX: Mastering Geospatial Reasoning Through Self-Play and Verifiable Rewards
[Paper] · arXiv:2605.20006
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 8.2 Task Generator. -
iReasoner: Trajectory-Aware Intrinsic Reasoning Supervision for Self-Evolving Large Multimodal Models
[Paper] · arXiv:2601.05877
Taxonomy: L3. Updated object(s): 5.2 Adapter; 6.1 Objective. -
Knowledge-Graph Paths as Intermediate Supervision for Self-Evolving Search Agents
[Paper] · arXiv:2605.05702
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 8.1 Experience Data. -
Language Models Need Sleep: Learning to Self-Modify and Consolidate Memories
[Paper] · arXiv:2606.03979
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 5.2 Adapter; 8.2 Task Generator. -
Learning to Adapt: Self-Improving Web Agent via Cognitive-Aware Exploration
[Paper] · arXiv:2605.31365
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 8.1 Experience Data. -
Learning to Build the Environment: Self-Evolving Reasoning RL via Verifiable Environment Synthesis
[Paper] · arXiv:2605.14392
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 8.2 Task Generator. -
Lifelong Robot Library Learning: Bootstrapping Composable and Generalizable Skills for Embodied Control with Language Models
[Paper] · arXiv:2406.18746
Taxonomy: L3. Updated object(s): 4.4 Skill Library; 2.1 Experience Memory. -
LLM-as-a-Tutor: Policy-Aware Prompt Adaptation for Non-Verifiable RL
[Paper] · arXiv:2607.04412
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 8.1 Experience Data; 7.2 Reward / Fitness. -
MM-Zero: Self-Evolving Multi-Model Vision Language Models From Zero Data
[Paper] · arXiv:2603.09206
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 8.2 Task Generator. -
Multi-Agent Evolve: LLM Self-Improve through Co-evolution
[Paper] · arXiv:2510.23595
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 7.1 Judge; 8.1 Experience Data. -
OMNI-EPIC: Open-endedness via Models of Human Notions of Interestingness with Environments Programmed in Code
[Paper] · arXiv:2405.15568
Taxonomy: L3. Updated object(s): 8.2 Task Generator; 8.3 Environment; 5.1 Model Weights. -
Paired Open-Ended Trailblazer (POET): Endlessly Generating Increasingly Complex and Diverse Learning Environments and Their Solutions
[Paper] · arXiv:1901.01753
Taxonomy: L3. Updated object(s): 8.2 Task Generator; 8.3 Environment. -
PopuLoRA: Co-Evolving LLM Populations for Reasoning Self-Play
[Paper] · arXiv:2605.16727
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 8.2 Task Generator; 6.5 Meta-optimization. -
Project Auto-World: Towards Automated Benchmarking of Neural Relational Reasoners
[Paper] · arXiv:2606.24965
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 8.2 Task Generator. -
Propose, Solve, Verify: Self-Play Through Formal Verification
[Paper] · arXiv:2512.18160
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 8.2 Task Generator. -
R-Diverse: Mitigating Diversity Illusion in Self-Play LLM Training
[Paper] · arXiv:2602.13103
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 8.2 Task Generator. -
R-Zero: Self-Evolving Reasoning LLM from Zero Data
[Paper] · arXiv:2508.05004
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 8.2 Task Generator. -
SAGE: Multi-Agent Self-Evolution for LLM Reasoning
[Paper] · arXiv:2603.15255
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 8.1 Experience Data. -
Scaling Self-Play with Self-Guidance
[Paper] · arXiv:2604.20209
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 8.2 Task Generator. -
SEAgent: Self-Evolving Computer Use Agent with Autonomous Learning from Experience
[Paper] · arXiv:2508.04700
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 8.2 Task Generator. -
Search Self-play: Pushing the Frontier of Agent Capability without Supervision
[Paper] · arXiv:2510.18821
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 8.2 Task Generator. -
SEIF: Self-Evolving Reinforcement Learning for Instruction Following
[Paper] · arXiv:2605.07465
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 8.2 Task Generator; 7.1 Judge. -
Seirênes: Adversarial Self-Play with Evolving Distractions for LLM Reasoning
[Paper] · arXiv:2605.11636
Taxonomy: L3. Updated object(s): 5.1 Model Weights. -
Self-Play Only Evolves When Self-Synthetic Pipeline Ensures Learnable Information Gain
[Paper] · arXiv:2603.02218
Taxonomy: L3. Updated object(s): 8.2 Task Generator; 5.1 Model Weights. -
Self-Questioning Language Models
[Paper] · arXiv:2508.03682
Taxonomy: L3. Updated object(s): 5.1 Model Weights. -
SEVA: Self-Evolving Verification Agent with Process Reward for Fact Attribution
[Paper] · arXiv:2606.29713
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 6.4 Curriculum. -
SimWorld Studio: Automatic Environment Generation with Evolving Coding Agent for Embodied Agent Learning
[Paper] · arXiv:2605.09423
Taxonomy: L3. Updated object(s): 8.3 Environment; 8.2 Task Generator; 4.4 Skill Library. -
SKILLFOUNDRY: Building Self-Evolving Agent Skill Libraries from Heterogeneous Scientific Resources
[Paper] · arXiv:2604.03964
Taxonomy: L3. Updated object(s): 4.4 Skill Library. -
SkillHarness: Harnessing Safe Skills for Computer-Use Agents
[Paper] · arXiv:2606.20636
Taxonomy: L3. Updated object(s): 4.4 Skill Library. -
Socratic-SWE: Self-Evolving Coding Agents via Trace-Derived Agent Skills
[Paper] · arXiv:2606.07412
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 2.1 Experience Memory; 6.4 Curriculum. -
SPARK: Self-Play with Asymmetric Reward from Knowledge Graphs
[Paper] · arXiv:2605.05546
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 8.1 Experience Data. -
STELLA: Self-Evolving LLM Agent for Biomedical Research
[Paper] · arXiv:2507.02004
Taxonomy: L3. Updated object(s): 4.1 Tool Set; 4.4 Skill Library. -
Survive or Collapse: The Asymmetric Roles of Data Gating and Reward Grounding in Self-Play RL
[Paper] · arXiv:2605.22217
Taxonomy: L3. Updated object(s): 5.1 Model Weights. -
Tool-R0: Self-Evolving LLM Agents for Tool-Learning from Zero Data
[Paper] · arXiv:2602.21320
Taxonomy: L3. Updated object(s): 8.2 Task Generator; 5.1 Model Weights. -
Towards Healthy Evolution: Exploring the Role and Mechanisms of Human-Agent Interaction in Self-Evolving Systems
[Paper] · arXiv:2606.06114
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 8.2 Task Generator; 1.1 Instruction. -
Towards Understanding Self-play for LLM Reasoning
[Paper] · arXiv:2510.27072
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 7.2 Reward / Fitness. -
TREX: Automating LLM Fine-tuning via Agent-Driven Tree-based Exploration
[Paper] · arXiv:2604.14116
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 8.1 Experience Data. -
TTCS: Test-Time Curriculum Synthesis for Self-Evolving
[Paper] · arXiv:2601.22628
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 6.1 Objective. -
TTSR: Test-Time Self-Evolving via Reflection
[Paper] · arXiv:2603.03297
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 8.2 Task Generator; 2.1 Experience Memory. -
Verifier-Backed Hard Problem Generation for Mathematical Reasoning
[Paper] · arXiv:2605.06660
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 8.1 Experience Data. -
Vocabulary Dropout for Curriculum Diversity in LLM Co-Evolution
[Paper] · arXiv:2604.03472
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 8.2 Task Generator. -
Voyager: An Open-Ended Embodied Agent with Large Language Models
[Paper] · arXiv:2305.16291
Taxonomy: L3. Updated object(s): 4.4 Skill Library; 8.2 Task Generator. -
WIST: Web-Grounded Iterative Self-Play Tree for Domain-Targeted Reasoning Improvement
[Paper] · arXiv:2603.22352
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 8.2 Task Generator.

4. L4 - Autonomy in Deployment and Environmental Adaptation ↑ top
Reusable memory, skills, or deployed agent components persistently alter later behavior within a fixed improvement process. 45 papers.
Featured representative papers
| Paper | Representative mechanism |
|---|---|
| OS-Copilot | Accumulates skills from prior computer tasks to improve a generalist OS agent. |
| Trace2Skill | Distills trajectory-local lessons into transferable agent skills. |
| APEX | Uses autonomous policy exploration to improve deployed agent behavior. |
| Metis | Bridges textual and code memory for self-evolving agents. |
| PRACTICE | Converts interaction experience into expertise for embodied agents. |
| ENPIRE | Applies agentic self-improvement to robot policies in real-world deployment. |
Browse the full L4 catalog (45 papers)
Table-derived extensions
The following additions are explicitly discussed in Table 6 under trajectory distillation, iterative agent-system revision, or selective retention and deployment of updates.
-
DecoEvo: Score-Decoupled Co-Evolution of Solver and Rubric-Generator Skills in Text Space
[Paper] · arXiv:2607.25675
Survey-table rationale: Solver and rubric skills co-evolve across iterative rounds with score-independent audits. Updated object(s): 7.1 Evaluator / Judge; 4.4 Skill / Macro Library. -
Trace2Skill: Distill Trajectory-Local Lessons into Transferable Agent Skills
[Paper] · arXiv:2603.25158
Survey-table rationale: Error and success analysts merge patches into portable skill documents for later reuse. Updated object(s): 4.4 Skill / Macro Library. -
Metis: Bridging Text and Code Memory for Self-Evolving Agents
[Paper] · arXiv:2606.24151
Survey-table rationale: Text plans and code tools are retained after completed tasks and validated through reuse and sandbox compilation. Updated object(s): 2.3 Procedural Memory; 4.3 Tool Implementation. -
Library Drift: Diagnosing and Fixing a Silent Failure Mode in Self-Evolving LLM Skill Libraries
[Paper] · arXiv:2605.19576
Survey-table rationale: Periodic retention retires low-contribution skills and caps the evolving library. Updated object(s): 4.4 Skill / Macro Library. -
APEX: Autonomous Policy Exploration for Self-Evolving LLM Agents
[Paper] · arXiv:2605.21240
Survey-table rationale: A milestone dependency graph retains episode outcomes and informs later exploration. Updated object(s): 2.2 Semantic / Knowledge Memory. -
Learning Personalized Agents from Human Feedback
[Paper] · arXiv:2602.16173
Survey-table rationale: User clarification confirms and revises persistent preference entrie

Truncated — view the full README on GitHub.
Contributors

3 commits
See what people are saying
Hacker News (1)
Similar repos




README
Awesome Recursive Self-Improvement (RSI)
A taxonomy-first, auditable map of recursive self-improvement research.
📄 Survey • 📝 Cite • 🧭 Taxonomy • 📚 Catalog • 🆕 Updates • 🤝 Contribute
This repository accompanies The Last AI Built by Humans: Toward Genuine Recursive Self-Improvement (Yi Duan et al., 2026; arXiv:2609.11873).
Every listed paper retains its arXiv identifier, primary autonomy level, and updated-object classification.
RSI is the capability of an intelligent system to transform acquired experience and feedback into persistent changes to itself across interaction rounds, such that those changes can affect how later improvements are generated, evaluated, selected, and consolidated. The updated object may be model weights, prompts, code, memory, skills, task distributions, or the improvement mechanism itself. Levels capture autonomy over what is changed, how it is changed, and where later learning experience comes from; they are not paper-quality rankings.
Figure 1. RSI autonomy overview: from in-task iteration and execution automation, through strategy search and experience acquisition, to deployment automation and meta-level improvement.
Latest Updates ↑ top
This section highlights recent, source-verifiable RSI research and industry developments. It is editorially separate from the 519-paper taxonomy, so a release or technical report is never presented as a peer-reviewed paper by default.
- 2026-09-10 — Companion survey released: The Last AI Built by Humans: Toward Genuine Recursive Self-Improvement introduces HCI and the L1-L5 RSI roadmap used by this repository. [Paper]
Update policy
- Include only a primary research source, official organization post, technical report, release note, or maintained project page.
- Tag each item as
ResearchorIndustry, then with its material type (Paper,Survey,Technical Report,Official Blog,Release, orProject). State its publication date and a neutral, one-sentence explanation of RSI relevance. - Link research to an official proceedings page, DOI, or arXiv record; link industry items to the organization's original publication, never to a repost or social-media summary.
- An update is not automatically an in-scope taxonomy paper. It enters the L1-L5 catalog only after the same paper-level relevance review.
Table of Contents
- Latest Updates
- Reading Paths
- Companion Survey
- Scope and Relevance Decision
- RSI Improvement-Loop Anatomy
- How to Read the Tags
- Taxonomy at a Glance
- 1. L1 - Autonomy over Improvement Execution
- 2. L2 - Autonomy over Improvement Strategies
- 3. L3 - Autonomy over Future Learning Experience
- 4. L4 - Autonomy in Deployment and Environmental Adaptation
- 5. L5 - From Environmental Adaptation to Meta-Improvement
- Contributing
- Citation
- Data Provenance and Validation
Reading Paths ↑ top
The full catalog is designed for reference, but these short routes provide a faster entry point:
| Goal | Suggested route |
|---|---|
| Understand the field map | Start with the companion survey, then read the improvement-loop anatomy and the L1-L5 overview. |
| Study persistent agent improvement | Read Voyager for reusable skills and automatic curricula, then browse L3 and L4. |
| Study recursive meta-improvement | Read Darwin Gödel Machine and Gödel Agent, then browse L5. |
Companion Survey ↑ top
This collection accompanies The Last AI Built by Humans: Toward Genuine Recursive Self-Improvement, by Yi Duan, Ying Liu, Zirui Tang, Haodong Chen, Jun Zhou, Yumou Liu, Bangrui Xu, Yukai Wu, Sidi Chen, Yuhan Zhou, Haoyu Wang, Xiaoyou Yu, Shaokun Han, Xuzhou Zhu, Le Zhou, Bolin Lu, Wei Zhou, Jiachen Liu, Nuozhou Fang, Jiaxin Tian, Ruoyu Chen, Yuxuan Li, Kai Zuo, Kaiyan Zhang, Jiantao Qiu, Conghui He, Guoliang Li, Bowen Zhou, Zhiyuan Liu, Zhoufutu Wen, Jihua Kang, Xuanhe Zhou, and Fan Wu.
The survey introduces the Headroom-Closed Index (HCI), develops the RSI roadmap represented by the L1-L5 taxonomy, and examines RSI in scientific discovery, embodied intelligence, and software engineering. This repository provides the paper-level, auditable companion to that roadmap.
Scope and Relevance Decision ↑ top
The 491 baseline papers and 28 table-derived extensions in this collection are retained as RSI-related under the L1-L5 taxonomy. The taxonomy intentionally includes bounded forms and precursors:
- L1 - Autonomy over Improvement Execution: the system executes a human-defined improvement procedure, and its accepted results persist into later tasks or rounds.
- L2 - Autonomy over Improvement Strategies: the system chooses how to improve a specified target, while the objective, evaluation criterion, or acceptance rule remains external.
- L3 - Autonomy over Future Learning Experience: the learner's evolving state influences the experience, task, or curriculum acquired next.
- L4 - Autonomy in Deployment and Environmental Adaptation: reusable memory, skills, or deployed agent components are retained and alter later behavior within a fixed improvement process.
- L5 - From Environmental Adaptation to Meta-Improvement: the system improves the mechanism that produces future improvements, such as search, evaluation, or research-control policies.
Thus, inclusion does not claim that every entry is a fully autonomous or open-ended RSI system. The L1 and L2 labels make their bounded autonomy explicit.
RSI Improvement-Loop Anatomy ↑ top
Each entry can be interpreted through the same loop: experience -> candidate modification -> verifier / acceptance rule -> retained improvement -> successor re-entry. The relevant components are:
| Component | Role in the loop |
|---|---|
| System state | Persistent state inherited by the next round. |
| Experience | Prior interaction outcomes, failures, feedback, or observations that inform an update. |
| Target | The object directly modified in the current round. |
| Improver and strategy | The mechanism that proposes candidates and decides where or how to search. |
| Verifier | The evaluator that applies an acceptance rule, such as tests, rewards, formal checks, or human feedback. |
| Improvement and successor | An accepted, retained state change and the next system version that inherits it. |
This anatomy supplies three tests for every claimed RSI loop: Where does the loop close? What is updated and inherited? Which decisions remain external?
Figure 2. Loop patterns across L1-L5. The agentic loop expands as AI internalizes more of the improvement process, while human-controlled constraints remain explicit.
How to Read the Tags ↑ top
Each entry has three colored badges:
| Badge | Meaning |
|---|---|
Level-L1 to Level-L5 | Autonomy level and locus in the improvement loop |
In scope-RSI | Retained by the source taxonomy's RSI relevance screen |
Target-... | Primary family of the updated or searched object |
Blue, purple, orange, green, and red encode L1 through L5. Target colors distinguish the ten updated-object families. Each paper appears exactly once under its primary level; all available target codes are preserved in the entry.
Taxonomy at a Glance ↑ top
| Level | Papers | Interpretation |
|---|---|---|
| L1 | 219 | Autonomy over improvement execution. |
| L2 | 159 | Autonomy over improvement strategies. |
| L3 | 65 | Autonomy over future learning experience. |
| L4 | 45 | Autonomy in deployment and environmental adaptation. |
| L5 | 31 | From environmental adaptation to meta-improvement. |
Each level begins with a small set of featured representative papers, selected to cover its defining mechanisms and important research landmarks. They are entry points for reading, not quality rankings; the complete catalog remains available in the expandable section below each level.
Updated-Object Families
| Code prefix | Family |
|---|---|
| 1 | Prompt & Context |
| 2 | Memory & Knowledge |
| 3 | Harness / Workflow |
| 4 | Tools & Skills |
| 5 | Model |
| 6 | Trainer / Optimization |
| 7 | Evaluator & Feedback |
| 8 | Data & Environment |
| 9 | External Artifact |
| 10 | Full-system / Co-evolution |
1. L1 - Autonomy over Improvement Execution ↑ top
The system executes a human-defined improvement procedure and retains accepted results for later tasks or rounds. 219 papers.
Featured representative papers
| Paper | Representative mechanism |
|---|---|
| STaR | Bootstraps model-generated rationales into a fixed, correctness-filtered self-training loop. |
| Constitutional AI | Establishes critique-and-revision with AI feedback under a human-specified constitution. |
| ReST | Generates an offline dataset with the current policy, then improves that policy with offline reinforcement learning. |
| SPIN | Generates training data from earlier policy iterations and refines the policy against human-annotated responses. |
| Self-Rewarding Language Models | Uses model-generated judgments as a fixed-protocol training signal. |
| Meta-Rewarding Language Models | Extends AI-feedback training to iterative refinement of the judging signal. |
Browse the full L1 catalog (219 papers)
Table-derived extensions
The following additions are explicitly discussed in Table 3 of the survey, which organizes representative L1 systems by AI development pipeline level.
-
Phi-4-reasoning Technical Report
[Paper] · arXiv:2504.21318
Survey-table rationale: Training-data selection through LLM evaluation and boundary filtering; selection criteria remain human-defined. Updated object(s): 8.1 Training / Experience Data. -
NVIDIA Nemotron-4 340B Technical Report
[Paper] · arXiv:2406.11704
Survey-table rationale: Synthetic supervision is generated and reward-filtered under human-defined quality dimensions. Updated object(s): 8.1 Training / Experience Data. -
EDIT: Evidence-Diagnosed Intervention Training for Rule-Faithful LLM Grading
[Paper] · arXiv:2606.06350
Survey-table rationale: Diagnosed-step revisions refine a training signal while diagnostic criteria remain human-defined. Updated object(s): 6.1 Training Objective. -
AIPC: Agent-Based Automation for AI Model Deployment with Qualcomm AI Runtime
[Paper] · arXiv:2604.14661
Survey-table rationale: Skill-guided deployment adaptation follows a human-defined deployment procedure. Updated object(s): 3.6 Harness Implementation / Scaffold Code. -
$V_1$: Unifying Generation and Self-Verification for Parallel Reasoners
[Paper] · arXiv:2603.04304
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
A Co-Evolving Agentic AI System for Medical Imaging Analysis
[Paper] · arXiv:2509.20279
Taxonomy: L1. Updated object(s): 5.2 Adapter; 2.1 Experience Memory; 3.3 Harness / Workflow. -
A Context Engineering Framework for Improving Enterprise AI Agents based on Digital-Twin MDP
[Paper] · arXiv:2603.22083
Taxonomy: L1. Updated object(s): 1.5 Context; 3.1 Workflow. -
A Dynamic Self-Evolving Extraction System
[Paper] · arXiv:2603.06915
Taxonomy: L1. Updated object(s): 2.2 Knowledge Memory; 1.5 Context. -
A Model Can Help Itself: Reward-Free Self-Training for LLM Reasoning
[Paper] · arXiv:2510.18814
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
A Self-Improvable Polymer Discovery Framework Based on Conditional Generative Model
[Paper] · arXiv:2312.04013
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 8.1 Experience Data. -
ACE: Self-Evolving LLM Coding Framework via Adversarial Unit Test Generation and Preference Optimization
[Paper] · arXiv:2605.16299
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 8.1 Experience Data. -
AceSearcher: Bootstrapping Reasoning and Search for LLMs via Reinforced Self-Play
[Paper] · arXiv:2509.24193
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Active-GRPO: Adaptive Imitation and Self-Improving Reasoning for Molecular Optimization
[Paper] · arXiv:2607.00531
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 6.1 Objective. -
AdaExplore: Failure-Driven Adaptation and Diversity-Preserving Search for Efficient Kernel Generation
[Paper] · arXiv:2604.16625
Taxonomy: L1. Updated object(s): 1.1 Instruction; 2.2 Knowledge Memory. -
Agent Hospital: A Simulacrum of Hospital with Evolvable Medical Agents
[Paper] · arXiv:2405.02957
Taxonomy: L1. Updated object(s): 2.1 Experience Memory; 2.3 Procedural Memory. -
Agent0-VL: Exploring Self-Evolving Agent for Tool-Integrated Vision-Language Reasoning
[Paper] · arXiv:2511.19900
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
AgentGym: Evolving Large Language Model-based Agents across Diverse Environments
[Paper] · arXiv:2406.04151
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Agentic-Ideation: Sample Efficient Agentic Trajectories Synthesis for Scientific Ideation Agents
[Paper] · arXiv:2606.31229
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
AlgoSkill: Learning to Design Algorithms by Scheduling Human-Like Skills
[Paper] · arXiv:2606.29999
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
AMR-SD: Asymmetric Meta-Reflective Self-Distillation for Token-Level Credit Assignment
[Paper] · arXiv:2605.18529
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 6.1 Objective. -
Anyprefer: An Agentic Framework for Preference Data Synthesis
[Paper] · arXiv:2504.19276
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 1.1 Instruction. -
APR: Penalizing Structural Redundancy in Large Reasoning Models via Anchor-based Process Rewards
[Paper] · arXiv:2602.00760
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 6.1 Objective. -
AutoMalDesc: Large-Scale Script Analysis for Cyber Threat Research
[Paper] · arXiv:2511.13333
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 8.1 Experience Data. -
AutoResearchClaw: Self-Reinforcing Autonomous Research with Human-AI Collaboration
[Paper] · arXiv:2605.20025
Taxonomy: L1. Updated object(s): 2.1 Experience Memory. -
Better, Faster: Harnessing Self-Improvement in Large Reasoning Models
[Paper] · arXiv:2605.24998
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 6.1 Objective. -
Beyond Imitation: Self-Improving Robot Policies via Off-Policy Q-Planning
[Paper] · arXiv:2608.21204
Taxonomy: L1. Updated object(s): 5.2 Adapter. -
Beyond Self-Play: Hierarchical Reasoning for Continuous Motion in Closed-Loop Traffic Simulation
[Paper] · arXiv:2605.09153
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Binary Decompilation LLM with Feedback-Driven Multi-Turn Refinement
[Paper] · arXiv:2606.16162
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
BiWM: Advancing Open-Source Interactive Video World Models with Bidirectional Autoregression
[Paper] · arXiv:2606.10135
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 6.1 Objective. -
Breaking the Self-Confirming Loop: Diagnosing and Mitigating Systemic Reward Bias in Self-Rewarding RL
[Paper] · arXiv:2510.08977
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Bridging What the Model Thinks and How It Speaks: Expressive Speech Generation via Self-Aware Intent-Realization Alignment
[Paper] · arXiv:2604.11424
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Can Large Reasoning Models Self-Train?
[Paper] · arXiv:2505.21444
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Can Recommender Systems Teach Themselves? A Recursive Self-Improving Framework with Fidelity Control
[Paper] · arXiv:2602.15659
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 8.1 Experience Data. -
CAST: Non-Privileged Clipped Asymmetric Self-Teaching with Advantage Flipping for GRPO
[Paper] · arXiv:2606.00172
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
CATPO: Critique-Augmented Tree Policy Optimization
[Paper] · arXiv:2606.08346
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 6.4 Curriculum. -
CEPO: RLVR Self-Distillation using Contrastive Evidence Policy Optimization
[Paper] · arXiv:2605.19436
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 6.1 Objective. -
CIIR@LiveRAG 2025: Optimizing Multi-Agent Retrieval Augmented Generation through Self-Training
[Paper] · arXiv:2506.10844
Taxonomy: L1. Updated object(s): 5.2 Adapter. -
Cleansing the Artificial Mind: A Self-Reflective Detoxification Framework for Large Language Models
[Paper] · arXiv:2601.11776
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Co-rewarding: Stable Self-supervised RL for Eliciting Reasoning in Large Language Models
[Paper] · arXiv:2508.00410
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
CoAct: Co-Active LLM Preference Learning with Human-AI Synergy
[Paper] · arXiv:2604.17501
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Consistent Paths Lead to Truth: Self-Rewarding Reinforcement Learning for LLM Reasoning
[Paper] · arXiv:2506.08745
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Constitutional AI: Harmlessness from AI Feedback
[Paper] · arXiv:2212.08073
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 7.2 Reward / Fitness. -
Continual Self-Improvement with Lightweight Experiential Latent Memories
[Paper] · arXiv:2606.17803
Taxonomy: L1. Updated object(s): 5.2 Adapter; 2.1 Experience Memory. -
Continuous Self-Improvement of Large Language Models by Test-time Training with Verifier-Driven Sample Selection
[Paper] · arXiv:2505.19475
Taxonomy: L1. Updated object(s): 5.2 Adapter. -
CoVerRL: Breaking the Consensus Trap in Label-Free Reasoning via Generator-Verifier Co-Evolution
[Paper] · arXiv:2603.17775
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
CREAM: Consistency Regularized Self-Rewarding Language Models
[Paper] · arXiv:2410.12735
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
CritiCal: Can Critique Help LLM Uncertainty or Confidence Calibration?
[Paper] · arXiv:2510.24505
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Deciphering Scientific Reasoning Steps from Outcome Data for Molecule Optimization
[Paper] · arXiv:2603.20262
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Decouple to Generalize: Context-First Self-Evolving Learning for Data-Scarce Vision-Language Reasoning
[Paper] · arXiv:2512.06835
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 8.1 Experience Data. -
DeepInnovator: Triggering the Innovative Capabilities of LLMs
[Paper] · arXiv:2602.18920
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 8.1 Experience Data. -
DeepSeekMath-V2: Towards Self-Verifiable Mathematical Reasoning
[Paper] · arXiv:2511.22570
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 7.3 Verifier. -
DemoPSD: Disagreement-Modulated Policy Self-Distillation
[Paper] · arXiv:2607.02502
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 6.1 Objective. -
Depression Diagnosis Dialogue Simulation: Self-improving Psychiatrist with Tertiary Memory
[Paper] · arXiv:2409.15084
Taxonomy: L1. Updated object(s): 2.1 Experience Memory; 2.3 Procedural Memory. -
DermoGPT: Open Weights and Open Data for Morphology-Grounded Dermatological Reasoning MLLMs
[Paper] · arXiv:2601.01868
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 6.1 Objective. -
Differentiable Mixture-of-Agents Incentivizes Swarm Intelligence of Large Language Models
[Paper] · arXiv:2605.15706
Taxonomy: L1. Updated object(s): 3.3 Harness / Workflow; 5.2 Adapter. -
Distilling LLM Feedback for Lean Theorem Proving
[Paper] · arXiv:2605.30861
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Double-Checker: Enhancing Reasoning of Slow-Thinking LLMs via Self-Critical Fine-Tuning
[Paper] · arXiv:2506.21285
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
DRIFT: Difficulty Routing Self-DIstillation with Rhythm-Gated Exploration and Success BuFfer Training
[Paper] · arXiv:2606.30345
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Dual-Modality Multi-Stage Adversarial Safety Training: Robustifying Multimodal Web Agents Against Cross-Modal Attacks
[Paper] · arXiv:2603.04364
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 8.1 Experience Data. -
DuPO: Enabling Reliable LLM Self-Verification via Dual Preference Optimization
[Paper] · arXiv:2508.14460
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 6.1 Objective. -
Dynamic Alignment for Collective Agency: Toward a Scalable Self-Improving Framework for Open-Ended LLM Alignment
[Paper] · arXiv:2512.05464
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
EARS: Explanatory Abstention for Reliable Sub-Agent Modeling in Large-scale Multi-Agent Systems
[Paper] · arXiv:2606.18668
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 8.1 Experience Data. -
Easy Samples Are All You Need: Self-Evolving LLMs via Data-Efficient Reinforcement Learning
[Paper] · arXiv:2604.18639
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Emulating Clinician Cognition via Self-Evolving Deep Clinical Research
[Paper] · arXiv:2603.10677
Taxonomy: L1. Updated object(s): 2.1 Experience Memory. -
Endless Terminals: Scaling RL Environments for Terminal Agents
[Paper] · arXiv:2601.16443
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 8.3 Environment. -
Enhancing Mathematical Reasoning in LLMs with Background Operators
[Paper] · arXiv:2412.04110
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
EpiCaR: Knowing What You Don't Know Matters for Better Reasoning in LLMs
[Paper] · arXiv:2601.06786
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 6.1 Objective. -
Evo-MedAgent: Beyond One-Shot Diagnosis with Agents That Remember, Reflect, and Improve
[Paper] · arXiv:2604.14475
Taxonomy: L1. Updated object(s): 2.1 Experience Memory; 2.3 Procedural Memory. -
EvoDefense: Co-Evolving Black-Box Defense with Large Language Models
[Paper] · arXiv:2605.31140
Taxonomy: L1. Updated object(s): 5.2 Adapter; 2.1 Experience Memory. -
EVOLVE-VLA: Test-Time Training from Environment Feedback for Vision-Language-Action Models
[Paper] · arXiv:2512.14666
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
ExpeL: LLM Agents Are Experiential Learners
[Paper] · arXiv:2308.10144
Taxonomy: L1. Updated object(s): 2.1 Experience Memory; 2.2 Knowledge Memory. -
Exploring and Exploiting the Inherent Efficiency within Large Reasoning Models for Self-Guided Efficiency Enhancement
[Paper] · arXiv:2506.15647
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
ExpRL: Exploratory RL for LLM Mid-Training
[Paper] · arXiv:2606.17024
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
FiRe: Fine-grained Multimodal Reasoning for Enhanced Image Generation
[Paper] · arXiv:2604.13491
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
First SFT, Second RL, Third UPT: Continual Improving Multi-Modal LLM Reasoning via Unsupervised Post-Training
[Paper] · arXiv:2505.22453
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 8.1 Experience Data. -
Forward-Free Diffusion Language Models with BPTT-Free Looped Refinement
[Paper] · arXiv:2606.08357
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 6.1 Objective. -
From Memorization to Creativity: LLM as a Designer of Novel Neural Architectures
[Paper] · arXiv:2601.02997
Taxonomy: L1. Updated object(s): 5.2 Adapter; 8.1 Experience Data. -
Generating on Generated: An Approach Towards Self-Evolving Diffusion Models
[Paper] · arXiv:2502.09963
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
GRAM-R^2: Self-Training Generative Foundation Reward Models for Reward Reasoning
[Paper] · arXiv:2509.02492
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
GSEM: Graph-based Self-Evolving Memory for Experience Augmented Clinical Reasoning
[Paper] · arXiv:2603.22096
Taxonomy: L1. Updated object(s): 2.1 Experience Memory; 2.4 Memory & Knowledge. -
Heterogeneous Self-Play for Realistic Highway Traffic Simulation
[Paper] · arXiv:2604.16406
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
How to Train Your Long-Context Visual Document Model
[Paper] · arXiv:2602.15257
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 7.1 Judge. -
HS-STaR: Hierarchical Sampling for Self-Taught Reasoners via Difficulty Estimation and Budget Reallocation
[Paper] · arXiv:2505.19866
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 6.4 Curriculum. -
ICRL: Learning to Internalize Self-Critique with Reinforcement Learning
[Paper] · arXiv:2605.15224
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 6.1 Objective. -
Improving LLM Code Reasoning via Semantic Equivalence Self-Play with Formal Verification
[Paper] · arXiv:2604.17010
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 5.2 Adapter. -
Improving Reasoning in Vision-Language Models via Perception Verified Self-Training
[Paper] · arXiv:2606.22158
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
IRIS: Interpolative Rényi Iterative Self-play for Large Language Model Fine-Tuning
[Paper] · arXiv:2604.20933
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Iterative Compositional Data Generation for Robot Control
[Paper] · arXiv:2512.10891
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 8.1 Experience Data. -
JailDAM: Jailbreak Detection with Adaptive Memory for Vision-Language Model
[Paper] · arXiv:2504.03770
Taxonomy: L1. Updated object(s): 2.2 Knowledge Memory; 2.5 Memory & Knowledge. -
KBSpec: LLM-driven Formal Specification Generation with Evolving Domain Knowledge Base
[Paper] · arXiv:2606.21339
Taxonomy: L1. Updated object(s): 2.2 Knowledge Memory; 2.3 Procedural Memory. -
Keep Policy Gradient in Charge: Sibling-Guided Credit Distillation for Long-Horizon Tool-Use Agents
[Paper] · arXiv:2606.12634
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 6.1 Objective. -
Know When to Stop: Segment-Level Credit Assignment for Reducing Overthinking
[Paper] · arXiv:2607.00482
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 6.1 Objective. -
KVerus: Scalable and Resilient Formal Verification Proof Generation for Rust Code
[Paper] · arXiv:2605.03822
Taxonomy: L1. Updated object(s): 9.1 Program Code; 2.2 Knowledge Memory. -
Latent Preference Modeling for Cross-Session Personalized Tool Calling
[Paper] · arXiv:2604.17886
Taxonomy: L1. Updated object(s): 2.2 Knowledge Memory. -
Learn from Your Mistakes: Tree-like Self-Play for Secure Code LLMs
[Paper] · arXiv:2606.03489
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 6.1 Objective. -
Learn Your Reference Model for Real Good Alignment
[Paper] · arXiv:2404.09656
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Learning from Language Feedback via Variational Policy Distillation
[Paper] · arXiv:2605.15113
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Learning from Supervision with Semantic and Episodic Memory: A Reflective Approach to Agent Adaptation
[Paper] · arXiv:2510.19897
Taxonomy: L1. Updated object(s): 2.1 Experience Memory; 2.2 Knowledge Memory. -
Learning from Your Own Mistakes: Constructing Learnable Micro-Reflective Trajectories for Self-Distillation
[Paper] · arXiv:2606.18844
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 6.1 Objective. -
Learning Steerable Clarification Policies with Collaborative Self-play
[Paper] · arXiv:2512.04068
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Learning to Better Search with Language Models via Guided Reinforced Self-Training
[Paper] · arXiv:2410.02992
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Learning to Plan & Reason for Evaluation with Thinking-LLM-as-a-Judge
[Paper] · arXiv:2501.18099
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Learning to Plan Before Answering: Self-Teaching LLMs to Learn Abstract Plans for Problem Solving
[Paper] · arXiv:2505.00031
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Learning to Self-Verify Makes Language Models Better Reasoners
[Paper] · arXiv:2602.07594
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 6.1 Objective. -
Learning to Solve and Verify: A Self-Play Framework for Code and Test Generation
[Paper] · arXiv:2502.14948
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
LLM-Personalize: Aligning LLM Planners with Human Preferences via Reinforced Self-Training for Housekeeping Robots
[Paper] · arXiv:2404.14285
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Meta-Rewarding Language Models: Self-Improving Alignment with LLM-as-a-Meta-Judge
[Paper] · arXiv:2407.19594
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
MiGrATe: Mixed-Policy GRPO for Adaptation at Test-Time
[Paper] · arXiv:2508.08641
Taxonomy: L1. Updated object(s): 5.2 Adapter. -
MobileIPL: Enhancing Mobile Agents Thinking Process via Iterative Preference Learning
[Paper] · arXiv:2505.12299
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 8.1 Experience Data. -
Monte Carlo Tree Search with Reasoning Path Refinement for Small Language Models in Conversational Text-to-NoSQL
[Paper] · arXiv:2602.12574
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Motus2: A Self-Evolving General World Model for Dexterous Manipulation
[Paper] · arXiv:2608.30237
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 8.4 Data & Environment; 7.2 Reward / Fitness. -
Not All Synthetic Data Is Yours to Learn From
[Paper] · arXiv:2605.31126
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Object-Centric Residual RL for Zero-Shot Sim-to-Real VLA Enhancement
[Paper] · arXiv:2606.18953
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 5.2 Adapter. -
Observations and Remedies for Large Language Model Bias in Self-Consuming Performative Loop
[Paper] · arXiv:2601.05184
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 8.1 Experience Data. -
OmniOPSD: Rationale-Privileged On-Policy Self-Distillation for Affective Computing
[Paper] · arXiv:2606.15920
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
OWL: Unsupervised 3D Object Detection by Occupancy Guided Warm-up and Large Model Priors Reasoning
[Paper] · arXiv:2512.05698
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 8.1 Experience Data. -
PaperSearchQA: Learning to Search and Reason over Scientific Papers with RLVR
[Paper] · arXiv:2601.18207
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 8.1 Experience Data. -
PARNESS: A Paper Harness for End-to-End Automated Scientific Research with Dynamic Workflows, Full-Text Indexing, and Cross-Run Knowledge Accumulation
[Paper] · arXiv:2605.05258
Taxonomy: L1. Updated object(s): 2.2 Knowledge Memory; 2.1 Experience Memory. -
Paying More Attention to Visual Tokens in Self-Evolving Large Multimodal Models
[Paper] · arXiv:2606.27373
Taxonomy: L1. Updated object(s): 5.2 Adapter; 6.1 Objective. -
PBSD: Privileged Bayesian Self-Distillation for Long-Horizon Credit Assignment
[Paper] · arXiv:2606.09348
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 6.1 Objective. -
PEARL: Training Socratic Tutors with Pedagogically Aligned Reinforcement Learning
[Paper] · arXiv:2605.29582
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 6.1 Objective. -
Peer-Predictive Self-Training for Language Model Reasoning
[Paper] · arXiv:2604.13356
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Perception, Verdict, and Evolution: Hindsight-Driven Self-Refining Forensics Agent for AI-Generated Image Detection
[Paper] · arXiv:2606.26552
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
PLLM: Pseudo-Labeling Large Language Models for CAD Program Synthesis
[Paper] · arXiv:2602.12561
Taxonomy: L1. Updated object(s): 5.2 Adapter. -
Policy-Guided Stepwise Model Routing for Cost-Effective Reasoning
[Paper] · arXiv:2605.06116
Taxonomy: L1. Updated object(s): 3.3 Harness / Workflow. -
Post-Training Probability Manifold Correction via Structured SVD Pruning and Self-Referential Distillation
[Paper] · arXiv:2602.00372
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Poster: ClawdGo: Endogenous Security Awareness Training for Autonomous AI Agents
[Paper] · arXiv:2604.24020
Taxonomy: L1. Updated object(s): 2.3 Procedural Memory; 2.5 Memory & Knowledge; 8.2 Task Generator. -
PRefLexOR: Preference-based Recursive Language Modeling for Exploratory Optimization of Reasoning and Agentic Thinking
[Paper] · arXiv:2410.12375
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
PRISMA: Preference-Reinforced Self-Training Approach for Interpretable Emotionally Intelligent Negotiation Dialogues
[Paper] · arXiv:2604.18354
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Probing Visual Language Priors in VLMs
[Paper] · arXiv:2501.00569
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Procedural Memory Distillation: Online Reflection for Self-Improving Language Models
[Paper] · arXiv:2607.01480
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Process-based Self-Rewarding Language Models
[Paper] · arXiv:2503.03746
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
ProcessThinker: Enhancing Multi-modal Large Language Models Reasoning via Rollout-based Process Reward
[Paper] · arXiv:2606.11209
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
PsychAgent: An Experience-Driven Lifelong Learning Agent for Self-Evolving Psychological Counselor
[Paper] · arXiv:2604.00931
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 4.4 Skill Library. -
Pythagoras-Prover: Advancing Efficient Formal Proving via Augmented Lean Formalisation
[Paper] · arXiv:2606.12594
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 8.1 Experience Data. -
Quiet-STaR: Language Models Can Teach Themselves to Think Before Speaking
[Paper] · arXiv:2403.09629
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Reasoning and Learning a Perceptual Metric for Self-Training of Reflective Objects in Bin-Picking with a Low-cost Camera
[Paper] · arXiv:2503.20207
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 8.1 Experience Data. -
Reasoning-Enhanced Self-Training for Long-Form Personalized Text Generation
[Paper] · arXiv:2501.04167
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
RebuttalAgent: Strategic Persuasion in Academic Rebuttal via Theory of Mind
[Paper] · arXiv:2601.15715
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Red-Bandit: Test-Time Adaptation for LLM Red-Teaming via Bandit-Guided LoRA Experts
[Paper] · arXiv:2510.07239
Taxonomy: L1. Updated object(s): 5.2 Adapter; 3.3 Harness / Workflow. -
ReGuide: From Test-Time Guidance to Self-Improving Diffusion Policies
[Paper] · arXiv:2606.28939
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 8.1 Experience Data. -
Reinforced Self-Training (ReST) for Language Modeling
[Paper] · arXiv:2308.08998
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Reinforcement Learning for Self-Improving Agent with Skill Library
[Paper] · arXiv:2512.17102
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 4.4 Skill Library. -
Reinforcement Learning from Rich Feedback with Distributional DAgger
[Paper] · arXiv:2606.05152
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 6.1 Objective. -
ReNIO: Reweighting Negative Trajectory Importance for LLM On-Policy Distillation
[Paper] · arXiv:2606.23104
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
ReST-MCTS: LLM Self-Training via Process Reward Guided Tree Search*
[Paper] · arXiv:2406.03816
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 7.2 Reward / Fitness. -
ReSteer: Quantifying and Refining the Steerability of Multitask Robot Policies
[Paper] · arXiv:2603.17300
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Rethinking Reward Supervision: Rubric-Conditioned Self-Distillation
[Paper] · arXiv:2606.19327
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
RetroAgent: From Solving to Evolving via Retrospective Dual Intrinsic Feedback
[Paper] · arXiv:2603.08561
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 2.1 Experience Memory. -
Right in the Right Way: LM Training with Verifiable Rewards and Human Demonstrations
[Paper] · arXiv:2607.01181
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 6.1 Objective; 5.2 Adapter. -
RLSR: Reinforcement Learning from Self Reward
[Paper] · arXiv:2505.08827
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Robot Self-Improvement via Human-Video Dynamics Models
[Paper] · arXiv:2606.21406
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 8.1 Experience Data. -
ROSD: Reflective On-Policy Self-Distillation for Language Model Reasoning across Domains
[Paper] · arXiv:2605.28014
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 6.1 Objective. -
Route, Retrieve, Reflect, Repair: Self-Improving Agentic Framework for Visual Detection and Linguistic Reasoning in Medical Imaging
[Paper] · arXiv:2601.08192
Taxonomy: L1. Updated object(s): 2.1 Experience Memory; 1.4 Prompt & Context. -
S-SPPO: Semantic-Calibrated Self-Play Preference Optimization
[Paper] · arXiv:2606.01561
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 6.1 Objective. -
SAEExplainer: Interpreting SAE Features with Activation-Guided Preference Optimization
[Paper] · arXiv:2606.08496
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Safe Autoregressive Image Generation with Iterative Self-Improving Codebooks
[Paper] · arXiv:2606.27147
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
SafeCtrl-RL: Inference-Time Adaptive Behaviour Control for LLM Dialogue via RL-Driven Prompt Optimisation
[Paper] · arXiv:2605.25984
Taxonomy: L1. Updated object(s): 5.2 Adapter; 3.4 Harness / Workflow. -
SafeSteer: Localized On-Policy Distillation for Efficient Safety Alignment
[Paper] · arXiv:2606.02530
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 6.1 Objective. -
SD-Search: On-Policy Hindsight Self-Distillation for Search-Augmented Reasoning
[Paper] · arXiv:2605.18299
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 6.1 Objective. -
Search-E1: Self-Distillation Drives Self-Evolution in Search-Augmented Reasoning
[Paper] · arXiv:2605.22511
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
See, Think, Learn: A Self-Taught Multimodal Reasoner
[Paper] · arXiv:2512.02456
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Self-Adapting Improvement Loops for Robotic Learning
[Paper] · arXiv:2506.06658
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Self-Alignment with Instruction Backtranslation
[Paper] · arXiv:2308.06259
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Self-Consistency of the Internal Reward Models Improves Self-Rewarding Language Models
[Paper] · arXiv:2502.08922
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
SELF-EMO: Emotional Self-Evolution from Recognition to Consistent Expression
[Paper] · arXiv:2604.18003
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Self-Evolution for Multi-Turn Tool-Calling Agents via Divergence-Point Preference Learning
[Paper] · arXiv:2606.23112
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Self-evolving LLM agents with in-distribution Optimization
[Paper] · arXiv:2606.07367
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 5.2 Adapter. -
Self-Improving Embodied Foundation Models
[Paper] · arXiv:2509.15155
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Self-Improving Tabular Language Models via Iterative Reward-Guided Post-Training
[Paper] · arXiv:2604.18966
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Self-Improving VLM Judges Without Human Annotations
[Paper] · arXiv:2512.05145
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Self-Play Enhancement via Advantage-Weighted Refinement in Online Federated LLM Fine-Tuning with Real-Time Feedback
[Paper] · arXiv:2605.07977
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 6.1 Objective. -
Self-Play Fine-Tuning Converts Weak Language Models to Strong Language Models (SPIN)
[Paper] · arXiv:2401.01335
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 8.1 Experience Data. -
Self-playing Adversarial Language Game Enhances LLM Reasoning (SPAG)
[Paper] · arXiv:2404.10642
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Self-Policy Distillation via Capability-Selective Subspace Projection
[Paper] · arXiv:2605.22675
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Self-Reasoning Language Models: Unfold Hidden Reasoning Chains with Few Reasoning Catalyst
[Paper] · arXiv:2505.14116
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 8.1 Experience Data. -
Self-rewarding correction for mathematical reasoning
[Paper] · arXiv:2502.19613
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Self-Rewarding Language Models
[Paper] · arXiv:2401.10020
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 8.1 Experience Data. -
Self-Rewarding Large Vision-Language Models for Optimizing Prompts in Text-to-Image Generation
[Paper] · arXiv:2505.16763
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Self-Rewarding PPO: Aligning Large Language Models with Demonstrations Only
[Paper] · arXiv:2510.21090
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Self-Rewarding Rubric-Based Reinforcement Learning for Open-Ended Reasoning
[Paper] · arXiv:2509.25534
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Self-Taught Evaluators
[Paper] · arXiv:2408.02666
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Self-Trained Verification for Training- and Test-Time Self-Improvement
[Paper] · arXiv:2605.30290
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 6.1 Objective. -
Self-Training Large Language Models for Improved Visual Program Synthesis With Visual Reinforcement
[Paper] · arXiv:2404.04627
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Semi-supervised Instruction Tuning for Large Language Models on Text-Attributed Graphs
[Paper] · arXiv:2601.12807
Taxonomy: L1. Updated object(s): 5.2 Adapter. -
SeRL: Self-Play Reinforcement Learning for Large Language Models with Limited Data
[Paper] · arXiv:2505.20347
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 8.1 Experience Data. -
Skill-Conditioned Gated Self-Distillation for LLM Reasoning
[Paper] · arXiv:2605.28791
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 2.3 Procedural Memory; 6.1 Objective. -
Skill-Guided Continuation Distillation for GUI Agents
[Paper] · arXiv:2606.18890
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 8.1 Experience Data. -
SmartSnap: Proactive Evidence Seeking for Self-Verifying Agents
[Paper] · arXiv:2512.22322
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 6.1 Objective. -
SocraticPO: Policy Optimization via Interactive Guidance
[Paper] · arXiv:2606.09887
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 6.1 Objective. -
Soft-NBCE: Entropy-Weighted Chunk Fusion for Long-Context
[Paper] · arXiv:2606.01101
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
SPPD: Self-training with Process Preference Learning Using Dynamic Value Margin
[Paper] · arXiv:2502.13516
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
SRPO: Self-Referential Policy Optimization for Vision-Language-Action Models
[Paper] · arXiv:2511.15605
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 7.2 Reward / Fitness. -
STaR: Self-Taught Reasoner—Bootstrapping Reasoning With Reasoning
[Paper] · arXiv:2203.14465
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
STEP: Enhancing Video-LLMs' Compositional Reasoning by Spatio-Temporal Graph-guided Self-Training
[Paper] · arXiv:2412.00161
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
StepPRM-RTL: Stepwise Process-Reward Guided LLM Fine-Tuning for Enhanced RTL Synthesis
[Paper] · arXiv:2606.04246
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 7.2 Reward / Fitness. -
Stratagem: Learning Transferable Reasoning via Trajectory-Modulated Game Self-Play
[Paper] · arXiv:2604.17696
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Structured Reasoning for Large Language Models
[Paper] · arXiv:2601.07180
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 6.1 Objective. -
Synergizing Discriminative Exemplars and Self-Refined Experience for MLLM-based In-Context Learning in Medical Diagnosis
[Paper] · arXiv:2603.27737
Taxonomy: L1. Updated object(s): 1.4 Prompt & Context; 2.3 Procedural Memory. -
Synthetic Computers at Scale for Long-Horizon Productivity Simulation
[Paper] · arXiv:2604.28181
Taxonomy: L1. Updated object(s): 4.4 Skill Library; 8.3 Environment. -
Teach-to-Reason: Competition-Guided Reasoning with a Self-Improving Teacher
[Paper] · arXiv:2606.25407
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 6.1 Objective. -
Teaching Large Reasoning Models Effective Reflection
[Paper] · arXiv:2601.12720
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Team-Based Self-Play With Dual Adaptive Weighting for Fine-Tuning LLMs
[Paper] · arXiv:2605.09922
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 6.1 Objective. -
Temporal Self-Rewarding Language Models: Decoupling Chosen-Rejected via Past-Future
[Paper] · arXiv:2508.06026
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 7.1 Judge. -
The Attacker in the Mirror: Breaking Self-Consistency in Safety via Anchored Bipolicy Self-Play
[Paper] · arXiv:2605.08427
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Think Longer to Explore Deeper: Learn to Explore In-Context via Length-Incentivized Reinforcement Learning
[Paper] · arXiv:2602.11748
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 6.1 Objective. -
Thinking Before Running! Efficient Code Generation with Thorough Exploration and Optimal Refinement
[Paper] · arXiv:2502.17442
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
Training-Free Test-Time Contrastive Learning for Large Language Models
[Paper] · arXiv:2604.13552
Taxonomy: L1. Updated object(s): 2.3 Procedural Memory; 1.5 Context. -
Transformers Provably Learn Chain-of-Thought Reasoning with Length Generalization
[Paper] · arXiv:2511.07378
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 8.1 Experience Data. -
Transitivity Meets Cyclicity: Explicit Preference Decomposition for Dynamic Large Language Model Alignment
[Paper] · arXiv:2605.17342
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 7.2 Reward / Fitness. -
TRON: Targeted Rule-Verifiable Online Environments for Visual Reasoning RL
[Paper] · arXiv:2606.01599
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 8.2 Task Generator. -
Unsupervised Process Reward Models
[Paper] · arXiv:2605.10158
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 7.1 Judge. -
Utilizing and Calibrating Hindsight Process Rewards via Reinforcement with Mutual Information Self-Evaluation
[Paper] · arXiv:2604.11611
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
VeriGate: Verifier-Gated Step-Level Supervision for GRPO
[Paper] · arXiv:2605.30451
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 6.1 Objective. -
VibeThinker-3B: Exploring the Frontier of Verifiable Reasoning in Small Language Models
[Paper] · arXiv:2606.16140
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
VideoSAVi: Self-Aligned Video Language Models without Human Supervision
[Paper] · arXiv:2412.00624
Taxonomy: L1. Updated object(s): 5.1 Model Weights. -
When Good Verifiers Go Bad: Self-Improving VLMs Can Regress on New Tasks
[Paper] · arXiv:2606.14629
Taxonomy: L1. Updated object(s): 5.2 Adapter. -
World Model Self-Distillation: Training World Models to Solve General Tasks
[Paper] · arXiv:2606.12072
Taxonomy: L1. Updated object(s): 5.1 Model Weights; 8.1 Experience Data. -
ZAS-SQL: Distilling Rules from Failures for Zero-Shot Text-to-SQL
[Paper] · arXiv:2606.08245
Taxonomy: L1. Updated object(s): 1.3 Prompt & Context; 3.4 Harness / Workflow.
2. L2 - Autonomy over Improvement Strategies ↑ top
The system chooses how to improve a specified target, while the objective, evaluation criterion, or acceptance rule remains externally specified. 159 papers.
Featured representative papers
| Paper | Representative mechanism |
|---|---|
| AutoPrompt | Uses gradient-guided search to generate discrete prompt tokens for a fixed task. |
| Automatic Prompt Engineer | Uses an LLM to propose prompt instructions and an external evaluator to select them. |
| ProTeGi | Optimizes prompts through textual gradients and beam search. |
| EvoPrompt | Treats prompt optimization as evolutionary search. |
| Eureka | Uses LLM-guided evolutionary optimization over reward code for externally specified RL tasks. |
| ADAS | Proposes, evaluates, and archives improved agentic system designs. |
| AFlow | Searches code-represented agent workflows with execution feedback. |
Browse the full L2 catalog (159 papers)
Table-derived extensions
The following additions are explicitly listed in Table 4, which groups representative L2 systems by the object of improvement-strategy search.
-
Multimodal Prompt Optimization: Why Not Leverage Multiple Modalities for MLLMs
[Paper] · arXiv:2510.09201
Survey-table rationale: Evaluation-derived semantic feedback guides multimodal prompt candidates under a fixed task metric. Updated object(s): 1.1 Instruction; 1.2 Task Prompt / Template. -
Agentic Neural Architecture Search
[Paper] · arXiv:2607.07984
Survey-table rationale: An LLM constructs a task-specific architecture search space, but the validation metric remains fixed. Updated object(s): 5.3 Architecture. -
Auto Research with Specialist Agents Develops Effective and Non-Trivial Training Recipes
[Paper] · arXiv:2605.05724
Survey-table rationale: Specialist agents search over training recipes with a shared lineage under an external evaluator. Updated object(s): 6.5 Search / Meta-optimization Procedure. -
AutoKernel: Autonomous GPU Kernel Optimization via Iterative Agent-Driven Search
[Paper] · arXiv:2603.21331
Survey-table rationale: A profile-rewrite-benchmark loop searches kernel implementations under fixed correctness and speed criteria. Updated object(s): 9.1 Program / Solution Code. -
Adapting AlphaEvolve to Optimize Fully Homomorphic Encryption on TPUs
[Paper] · arXiv:2605.14718
Taxonomy: L2. Updated object(s): 9.1 Program Code. -
AI-PROPELLER: Warehouse-Scale Interprocedural Code Layout Optimization with AlphaEvolve
[Paper] · arXiv:2606.00131
Taxonomy: L2. Updated object(s): 9.2 Algorithm. -
Magellan: Autonomous Discovery of Novel Compiler Optimization Heuristics with AlphaEvolve
[Paper] · arXiv:2601.21096
Taxonomy: L2. Updated object(s): 9.1 Program Code. -
Scientific Algorithm Discovery by Augmenting AlphaEvolve with Deep Research
[Paper] · arXiv:2510.06056
Taxonomy: L2. Updated object(s): 9.2 Algorithm; 2.1 Experience Memory. -
A Self-Improving Coding Agent
[Paper] · arXiv:2504.15228
Taxonomy: L2. Updated object(s): 3.6 Scaffold Code; 4.3 Tool Code; 1.1 Instruction. -
Adaptive Self-improvement LLM Agentic System for ML Library Development
[Paper] · arXiv:2502.02534
Taxonomy: L2. Updated object(s): 1.4 Prompt & Context; 1.5 Context. -
Advanced For-Loop for QML algorithm search
[Paper] · arXiv:2506.18260
Taxonomy: L2. Updated object(s): 9.2 Algorithm; 9.1 Program Code. -
AFlow: Automating Agentic Workflow Generation
[Paper] · arXiv:2410.10762
Taxonomy: L2. Updated object(s): 3.6 Scaffold Code; 1.2 Task Prompt. -
AgentDisCo: Towards Disentanglement and Collaboration in Open-ended Deep Research Agents
[Paper] · arXiv:2605.11732
Taxonomy: L2. Updated object(s): 1.1 Instruction; 3.6 Scaffold Code. -
Agentic Context Engineering: Evolving Contexts for Self-Improving Language Models
[Paper] · arXiv:2510.04618
Taxonomy: L2. Updated object(s): 1.5 Context; 2.4 Memory & Knowledge. -
Agentic Discovery of Neural Architectures: AIRA-Compose and AIRA-Design
[Paper] · arXiv:2605.15871
Taxonomy: L2. Updated object(s): 9.2 Algorithm; 9.3 External Artifact. -
Agentic Harness Engineering: Observability-Driven Automatic Evolution of Coding-Agent Harnesses
[Paper] · arXiv:2604.25850
Taxonomy: L2. Updated object(s): 3.6 Scaffold Code; 4.3 Tool Code. -
Agentic MIP Research: Accelerated Constraint Handler Generation
[Paper] · arXiv:2605.09186
Taxonomy: L2. Updated object(s): 9.1 Program Code; 9.2 Algorithm. -
AgenticRL: Self-Refining Agentic Reinforcement Learning for Vision-Conditioned UAV Navigation
[Paper] · arXiv:2606.03963
Taxonomy: L2. Updated object(s): 6.1 Objective; 5.1 Model Weights. -
Ask, Don't Judge: Binary Questions for Interpretable LLM Evaluation and Self-Improvement
[Paper] · arXiv:2606.27226
Taxonomy: L2. Updated object(s): 1.1 Instruction. -
ASPIRE: Agentic Skills Discovery for Robotics
[Paper] · arXiv:2607.00272
Taxonomy: L2. Updated object(s): 4.4 Skill Library; 9.1 Program Code. -
Auto-Configuring Scientific Simulators with Lightweight Coding-Agent Adapters
[Paper] · arXiv:2606.09774
Taxonomy: L2. Updated object(s): 2.3 Procedural Memory; 1.1 Instruction; 4.4 Skill Library. -
Automated Design of Agentic Systems (ADAS)
[Paper] · arXiv:2408.08435
Taxonomy: L2. Updated object(s): 3.6 Scaffold Code. -
Automated Heuristic Design for Unit Commitment Using Large Language Models
[Paper] · arXiv:2506.12495
Taxonomy: L2. Updated object(s): 9.2 Algorithm; 9.1 Program Code. -
AutoMegaKernel: A Statically-Checked Agent Harness for Self-Retargeting Megakernel Synthesis
[Paper] · arXiv:2606.09682
Taxonomy: L2. Updated object(s): 9.1 Program Code. -
AutoPass: Evidence-Guided LLM Agents for Compiler Performance Tuning
[Paper] · arXiv:2606.20373
Taxonomy: L2. Updated object(s): 9.2 Algorithm. -
AutoPrompt: Eliciting Knowledge from Language Models with Automatically Generated Prompts
[Paper] · arXiv:2010.15980
Taxonomy: L2. Updated object(s): 1.2 Task Prompt. -
AutoPyVerifier: Learning Compact Executable Verifiers for Large Language Model Outputs
[Paper] · arXiv:2604.22937
Taxonomy: L2. Updated object(s): 7.3 Verifier; 7.1 Judge. -
AutoVQA-G: Self-Improving Agentic Framework for Automated Visual Question Answering and Grounding Annotation
[Paper] · arXiv:2604.17488
Taxonomy: L2. Updated object(s): 1.2 Task Prompt; 1.1 Instruction. -
Beyond Algorithm Evolution: An LLM-Driven Framework for the Co-Evolution of Swarm Intelligence Optimization Algorithms and Prompts
[Paper] · arXiv:2512.09209
Taxonomy: L2. Updated object(s): 9.2 Algorithm; 1.1 Instruction. -
Beyond Scalar Rewards: Dense Feedback for LLM Policy Synthesis in Sequential Social Dilemmas
[Paper] · arXiv:2603.19453
Taxonomy: L2. Updated object(s): 9.1 Program Code. -
Beyond Static Tools: Test-Time Tool Evolution for Scientific Reasoning
[Paper] · arXiv:2601.07641
Taxonomy: L2. Updated object(s): 4.1 Tool Set; 4.2 Tool Interface. -
BT-APE: A Computationally Light Backtracking Approach to Automatic Prompt Engineering for Requirements Classification
[Paper] · arXiv:2607.00427
Taxonomy: L2. Updated object(s): 1.2 Task Prompt. -
CausalEvolve: Towards Open-Ended Discovery with Causal Scratchpad
[Paper] · arXiv:2603.14575
Taxonomy: L2. Updated object(s): 9.1 Program Code; 2.1 Experience Memory. -
CHIA: An open-source framework for principled, agentic AI-driven hardware/software co-design research
[Paper] · arXiv:2606.27350
Taxonomy: L2. Updated object(s): 9.1 Program Code. -
Co-evolving Agent Architectures and Interpretable Reasoning for Automated Optimization
[Paper] · arXiv:2604.17708
Taxonomy: L2. Updated object(s): 3.1 Workflow; 2.2 Knowledge Memory. -
CodeEvolve: an open source evolutionary coding agent for algorithmic discovery and optimization
[Paper] · arXiv:2510.14150
Taxonomy: L2. Updated object(s): 9.1 Program Code; 1.2 Task Prompt. -
CoEvoSkills: Self-Evolving Agent Skills via Co-Evolutionary Verification
[Paper] · arXiv:2604.01687
Taxonomy: L2. Updated object(s): 4.4 Skill Library. -
Combee: Scaling Prompt Learning for Self-Improving Language Model Agents
[Paper] · arXiv:2604.04247
Taxonomy: L2. Updated object(s): 1.1 Instruction; 1.5 Context. -
Combining Large Language Models and Gradient-Free Optimization for Automatic Control Policy Synthesis
[Paper] · arXiv:2510.00373
Taxonomy: L2. Updated object(s): 9.1 Program Code. -
Competing with AI Scientists: Agent-Driven Approach to Astrophysics Research
[Paper] · arXiv:2604.09621
Taxonomy: L2. Updated object(s): 9.1 Program Code. -
Continually self-improving AI
[Paper] · arXiv:2603.18073
Taxonomy: L2. Updated object(s): 6.5 Meta-optimization; 6.1 Objective; 5.1 Model Weights. -
CORAL: Towards Autonomous Multi-Agent Evolution for Open-Ended Discovery
[Paper] · arXiv:2604.01658
Taxonomy: L2. Updated object(s): 9.1 Program Code; 4.4 Skill Library. -
DataEvolver: Automatic Data Preparation for Large Language Models through Multi-Level Self-Evolving
[Paper] · arXiv:2606.07001
Taxonomy: L2. Updated object(s): 8.1 Experience Data; 9.1 Program Code. -
Defining Cost Function of Steganography with Large Language Models
[Paper] · arXiv:2512.09769
Taxonomy: L2. Updated object(s): 9.2 Algorithm. -
DeltaEvolve: Accelerating Scientific Discovery through Momentum-Driven Evolution
[Paper] · arXiv:2602.02919
Taxonomy: L2. Updated object(s): 9.1 Program Code. -
Discovering Multiagent Learning Algorithms with Large Language Models
[Paper] · arXiv:2602.16928
Taxonomy: L2. Updated object(s): 9.2 Algorithm. -
DrugSAGE: Self-evolving Agent Experience for Efficient State-of-the-Art Drug Discovery
[Paper] · arXiv:2605.15461
Taxonomy: L2. Updated object(s): 4.4 Skill Library; 2.2 Knowledge Memory. -
Each Judge Its Own Yardstick: Discovering Per-VLM Taxonomies for Physical Video Evaluation
[Paper] · arXiv:2606.22918
Taxonomy: L2. Updated object(s): 7.1 Judge. -
EEVEE: Towards Test-time Prompt Learning in the Real World for Self-Improving Agents
[Paper] · arXiv:2606.11182
Taxonomy: L2. Updated object(s): 1.1 Instruction; 3.3 Harness / Workflow. -
Effective Harness Engineering for Algorithm Discovery with Coding Agents
[Paper] · arXiv:2605.15221
Taxonomy: L2. Updated object(s): 9.1 Program Code; 9.2 Algorithm. -
ELMES+: Automated Construction of Fine-Grained Evaluation Rubrics for Large Language Models in Long-Tail Educational Scenarios
[Paper] · arXiv:2606.06546
Taxonomy: L2. Updated object(s): 7.1 Judge; 8.2 Task Generator. -
EmbodiSkill: Skill-Aware Reflection for Self-Evolving Embodied Agents
[Paper] · arXiv:2605.10332
Taxonomy: L2. Updated object(s): 4.4 Skill Library. -
Enhancing Operational Safety via Agentic Dialogue Hazard Identification Analysis
[Paper] · arXiv:2606.03812
Taxonomy: L2. Updated object(s): 3.5 Multi-agent; 1.1 Instruction. -
Environment-Grounded Automated Prompt Optimization for LLM Game Agents
[Paper] · arXiv:2606.17838
Taxonomy: L2. Updated object(s): 1.1 Instruction; 1.2 Task Prompt. -
EpiAgent: An Agent-Centric System for Ancient Inscription Restoration
[Paper] · arXiv:2604.09367
Taxonomy: L2. Updated object(s): 2.1 Experience Memory; 2.3 Procedural Memory. -
Eureka: Human-Level Reward Design via Coding Large Language Models
[Paper] · arXiv:2310.12931
Taxonomy: L2. Updated object(s): 7.2 Reward / Fitness. -
Eureka: Intelligent Feature Engineering for Enterprise AI Cloud Resource Demand Prediction
[Paper] · arXiv:2605.25297
Taxonomy: L2. Updated object(s): 9.1 Program Code; 5.1 Model Weights. -
EvoClinician: A Self-Evolving Agent for Multi-Turn Medical Diagnosis via Test-Time Evolutionary Learning
[Paper] · arXiv:2601.22964
Taxonomy: L2. Updated object(s): 1.1 Instruction; 2.1 Experience Memory. -
EvoLattice: Persistent Internal-Population Evolution through Multi-Alternative Quality-Diversity Graph Representations for LLM-Guided Program Discovery
[Paper] · arXiv:2512.13857
Taxonomy: L2. Updated object(s): 9.1 Program Code; 9.2 Algorithm. -
Evolution of Heuristics: Towards Efficient Automatic Algorithm Design Using Large Language Model
[Paper] · arXiv:2401.02051
Taxonomy: L2. Updated object(s): 9.2 Algorithm; 9.1 Program Code. -
EvolveSignal: A Large Language Model Powered Coding Agent for Discovering Traffic Signal Control Strategies
[Paper] · arXiv:2509.03335
Taxonomy: L2. Updated object(s): 9.1 Program Code. -
Evolving Deception: When Agents Evolve, Deception Wins
[Paper] · arXiv:2603.05872
Taxonomy: L2. Updated object(s): 1.1 Instruction. -
Evolving Medical Imaging Agents via Experience-Driven Self-Skill Discovery
[Paper] · arXiv:2603.05860
Taxonomy: L2. Updated object(s): 4.4 Skill Library; 5.1 Model Weights; 2.1 Experience Memory. -
EVOM: Agentic Meta-Evolution of Actor-Critic Architectures for Reinforcement Learning
[Paper] · arXiv:2606.26327
Taxonomy: L2. Updated object(s): 5.3 Architecture. -
EvoPrompt: Connecting LLMs with Evolutionary Algorithms Yields Powerful Prompt Optimizers
[Paper] · arXiv:2309.08532
Taxonomy: L2. Updated object(s): 1.2 Task Prompt. -
EvoScientist: Towards Multi-Agent Evolving AI Scientists for End-to-End Scientific Discovery
[Paper] · arXiv:2603.08127
Taxonomy: L2. Updated object(s): 2.2 Knowledge Memory; 1.5 Context. -
EvoTest: Evolutionary Test-Time Learning for Self-Improving Agentic Systems
[Paper] · arXiv:2510.13220
Taxonomy: L2. Updated object(s): 1.1 Instruction; 2.1 Experience Memory; 5.4 Model. -
Experience Graphs: The Data Foundation for Self-Improving Agents
[Paper] · arXiv:2606.29823
Taxonomy: L2. Updated object(s): 2.1 Experience Memory; 2.4 Memory & Knowledge. -
Experience Makes Skillful: Enabling Generalizable Medical Agent Reasoning via Self-Evolving Skill Memory
[Paper] · arXiv:2606.09365
Taxonomy: L2. Updated object(s): 2.3 Procedural Memory; 2.5 Memory & Knowledge. -
ExpGraph: Model-Agnostic Experience Learning with Graph-Structured Memory for LLM Agents
[Paper] · arXiv:2605.30712
Taxonomy: L2. Updated object(s): 2.1 Experience Memory; 2.4 Memory & Knowledge; 5.2 Adapter. -
FederatedSkill: Federated Learning for Agentic Skill Evolution
[Paper] · arXiv:2606.03143
Taxonomy: L2. Updated object(s): 4.4 Skill Library; 2.2 Knowledge Memory. -
Feedback Over Form: Why Execution Feedback Matters More Than Pipeline Topology in 1-3B Code Generation
[Paper] · arXiv:2604.21950
Taxonomy: L2. Updated object(s): 3.1 Workflow. -
Feedback-to-Rubrics: Can We Learn Expert Criteria from Inline Comments?
[Paper] · arXiv:2605.29857
Taxonomy: L2. Updated object(s): 7.1 Judge; 1.1 Instruction. -
From AI Assistant to AI Scientist: Autonomous Discovery of LLM-RL Algorithms with LLM Agents
[Paper] · arXiv:2603.23951
Taxonomy: L2. Updated object(s): 6.1 Objective; 6.2 Trainer / Optimization. -
From Failed Trajectories to Reliable LLM Agents: Diagnosing and Repairing Harness Flaws
[Paper] · arXiv:2606.06324
Taxonomy: L2. Updated object(s): 3.6 Scaffold Code; 1.2 Task Prompt; 4.2 Tool Interface. -
From Self-Evolving Synthetic Data to Verifiable-Reward RL: Post-Training Multi-turn Interactive Tool-Using Agents
[Paper] · arXiv:2601.22607
Taxonomy: L2. Updated object(s): 8.1 Experience Data; 5.1 Model Weights. -
From Understanding to Excelling: Template-Free Algorithm Design through Structural-Functional Co-Evolution
[Paper] · arXiv:2503.10721
Taxonomy: L2. Updated object(s): 9.1 Program Code; 9.2 Algorithm; 6.5 Meta-optimization. -
From User Interface to Agent Interface: Efficiency Optimization of UI Representations for LLM Agents
[Paper] · arXiv:2512.13438
Taxonomy: L2. Updated object(s): 9.1 Program Code. -
FuzzAgent: Multi-Agent System for Evolutionary Library Fuzzing
[Paper] · arXiv:2605.14431
Taxonomy: L2. Updated object(s): 9.1 Program Code. -
GeoEvolve: Automating Geospatial Model Discovery via Multi-Agent Large Language Models
[Paper] · arXiv:2509.21593
Taxonomy: L2. Updated object(s): 9.2 Algorithm. -
GEPA: Reflective Prompt Evolution Can Outperform Reinforcement Learning
[Paper] · arXiv:2507.19457
Taxonomy: L2. Updated object(s): 1.1 Instruction. -
GigaEvo: An Open Source Optimization Framework Powered By LLMs And Evolution Algorithms
[Paper] · arXiv:2511.17592
Taxonomy: L2. Updated object(s): 9.2 Algorithm; 9.1 Program Code; 1.1 Instruction. -
Hardening Agent Benchmarks with Adversarial Hacker-Fixer Loops
[Paper] · arXiv:2606.08960
Taxonomy: L2. Updated object(s): 7.3 Verifier; 8.3 Environment. -
Healthcare Mechanisms from Policy-as-Code Search under Strategic Provider Response
[Paper] · arXiv:2605.30680
Taxonomy: L2. Updated object(s): 9.2 Algorithm. -
Heuresis: Search Strategies for Autonomous AI Research Agents Across Quality, Diversity and Novelty
[Paper] · arXiv:2606.25198
Taxonomy: L2. Updated object(s): 9.1 Program Code; 9.2 Algorithm. -
Hierarchical Experimentalist Agents
[Paper] · arXiv:2606.29315
Taxonomy: L2. Updated object(s): 4.4 Skill Library. -
HSEvo: Elevating Automatic Heuristic Design with Diversity-Driven Harmony Search and Genetic Algorithm Using LLMs
[Paper] · arXiv:2412.14995
Taxonomy: L2. Updated object(s): 9.1 Program Code; 6.5 Meta-optimization. -
HypoForge: A Self-Improving Multi-Agent Framework for Automated Hypothesis Generation and Testing via Scientific Skill Learning
[Paper] · arXiv:2608.25770
Taxonomy: L2. Updated object(s): 4.4 Skill Library. -
ImprovEvolve: Basin-Hopping Meets LLM-Guided Evolutionary Search
[Paper] · arXiv:2602.10233
Taxonomy: L2. Updated object(s): 9.1 Program Code; 9.2 Algorithm. -
InvEvolve: Evolving White-Box Inventory Policies via Large Language Models with Performance Guarantees
[Paper] · arXiv:2605.00369
Taxonomy: L2. Updated object(s): 9.1 Program Code; 5.1 Model Weights. -
ISM: Self-Improving Strategy Memory for Continual Mathematical Reasoning
[Paper] · arXiv:2606.31191
Taxonomy: L2. Updated object(s): 2.3 Procedural Memory; 2.4 Memory & Knowledge. -
IterInject: Indirect Prompt Injection Against LLM Agents via Feedback-Guided Iterative Optimization
[Paper] · arXiv:2605.24659
Taxonomy: L2. Updated object(s): 1.2 Task Prompt. -
Kernel Foundry: A Diagnosis-driven Evolutionary Kernel Optimizer with Multi-Experts
[Paper] · arXiv:2605.30359
Taxonomy: L2. Updated object(s): 9.1 Program Code; 2.3 Procedural Memory. -
Large Language Models Are Human-Level Prompt Engineers (Automatic Prompt Engineer, APE)
[Paper] · arXiv:2211.01910
Taxonomy: L2. Updated object(s): 1.1 Instruction. -
Large Language Models as Optimizers
[Paper] · arXiv:2309.03409
Taxonomy: L2. Updated object(s): 1.2 Task Prompt. -
Learning from Failure: Inference-Time Self-Improvement for Computer-Use Agents
[Paper] · arXiv:2606.31270
Taxonomy: L2. Updated object(s): 3.6 Scaffold Code; 4.1 Tool Set; 3.4 Harness / Workflow. -
Learning to Choose: An Empowerment-Guided Multi-Agent System with semantic communication for Adaptive Method Selection
[Paper] · arXiv:2605.30042
Taxonomy: L2. Updated object(s): 3.3 Harness / Workflow; 2.1 Experience Memory. -
LEVI: Stronger Search Architectures Can Substitute for Larger LLMs in Evolutionary Search
[Paper] · arXiv:2605.09764
Taxonomy: L2. Updated object(s): 9.1 Program Code; 1.2 Task Prompt. -
Libra: Training the Environment for Agentic Information Retrieval
[Paper] · arXiv:2607.00016
Taxonomy: L2. Updated object(s): 2.2 Knowledge Memory; 8.3 Environment. -
LLaMEA-BO: A Large Language Model Evolutionary Algorithm for Automatically Generating Bayesian Optimization Algorithms
[Paper] · arXiv:2505.21034
Taxonomy: L2. Updated object(s): 9.2 Algorithm; 9.1 Program Code. -
LLM as a Tool, Not an Agent: Code-Mined Tree Transformations for Neural Architecture Search
[Paper] · arXiv:2604.16555
Taxonomy: L2. Updated object(s): 9.3 External Artifact. -
LLM-Evolved Pattern Generators for Optimal Classical Planning
[Paper] · arXiv:2606.02438
Taxonomy: L2. Updated object(s): 9.1 Program Code. -
LLM-Guided Evolutionary Program Synthesis for Quasi-Monte Carlo Design
[Paper] · arXiv:2510.03650
Taxonomy: L2. Updated object(s): 9.2 Algorithm. -
LLM-Guided Search for Deletion-Correcting Codes
[Paper] · arXiv:2504.00613
Taxonomy: L2. Updated object(s): 9.2 Algorithm. -
LoongFlow: Directed Evolutionary Search via a Cognitive Plan-Execute-Summarize Paradigm
[Paper] · arXiv:2512.24077
Taxonomy: L2. Updated object(s): 9.2 Algorithm; 9.1 Program Code. -
Mathematical exploration and discovery at scale
[Paper] · arXiv:2511.02864
Taxonomy: L2. Updated object(s): 9.1 Program Code; 9.2 Algorithm. -
Mechanistically Eliciting Latent Behaviors in Language Models
[Paper] · arXiv:2606.29604
Taxonomy: L2. Updated object(s): 5.2 Adapter. -
Medical Heuristic Learning: An LLM-Driven Framework for Interpretable and Auditable Clinical Decision Rules
[Paper] · arXiv:2606.16337
Taxonomy: L2. Updated object(s): 9.1 Program Code. -
MEMENTO: Leveraging Web as a Learning Signal for Low-Data Domains
[Paper] · arXiv:2605.29795
Taxonomy: L2. Updated object(s): 2.3 Procedural Memory; 2.2 Knowledge Memory. -
MEMO: Memory-Augmented Model Context Optimization for Robust Multi-Turn Multi-Agent LLM Games
[Paper] · arXiv:2603.09022
Taxonomy: L2. Updated object(s): 1.2 Task Prompt; 2.2 Knowledge Memory. -
Meta-Harness: End-to-End Optimization of Model Harnesses
[Paper] · arXiv:2603.28052
Taxonomy: L2. Updated object(s): 3.6 Scaffold Code. -
Middo: Model-Informed Dynamic Data Optimization for Enhanced LLM Fine-Tuning via Closed-Loop Learning
[Paper] · arXiv:2508.21589
Taxonomy: L2. Updated object(s): 8.1 Experience Data; 5.1 Model Weights. -
Mining Generalizable Activation Functions
[Paper] · arXiv:2602.05688
Taxonomy: L2. Updated object(s): 9.2 Algorithm. -
MLEvolve: A Self-Evolving Framework for Automated Machine Learning Algorithm Discovery
[Paper] · arXiv:2606.06473
Taxonomy: L2. Updated object(s): 9.1 Program Code; 9.2 Algorithm. -
MobEvolve: An Agentic Self-Evolving Heuristic System for Interpretable Human Mobility Generation
[Paper] · arXiv:2606.01640
Taxonomy: L2. Updated object(s): 9.1 Program Code; 2.1 Experience Memory. -
OpenComputer: Verifiable Software Worlds for Computer-Use Agents
[Paper] · arXiv:2605.19769
Taxonomy: L2. Updated object(s): 7.3 Verifier; 8.1 Experience Data; 8.3 Environment. -
Organize then Retrieve: Hierarchical Memory Navigation for Efficient Agents
[Paper] · arXiv:2606.11680
Taxonomy: L2. Updated object(s): 4.4 Skill Library; 5.1 Model Weights. -
PACEvolve++: Improving Test-time Learning for Evolutionary Search Agents
[Paper] · arXiv:2605.07039
Taxonomy: L2. Updated object(s): 5.1 Model Weights; 9.1 Program Code. -
Persona Generators: Generating Diverse Synthetic Personas for Arbitrary Contexts
[Paper] · arXiv:2602.03545
Taxonomy: L2. Updated object(s): 9.1 Program Code. -
Polaris: A Gödel Agent Framework for Small Language Models through Experience-Abstracted Policy Repair
[Paper] · arXiv:2603.23129
Taxonomy: L2. Updated object(s): 3.6 Scaffold Code; 2.3 Procedural Memory. -
ProfiLLM: Utility-Aligned Agentic User Profiling for Industrial Ride-Hailing Dispatch
[Paper] · arXiv:2606.18803
Taxonomy: L2. Updated object(s): 5.1 Model Weights; 8.1 Experience Data. -
PromptAgent: Strategic Planning with Language Models Enables Expert-level Prompt Optimization
[Paper] · arXiv:2310.16427
Taxonomy: L2. Updated object(s): 1.2 Task Prompt. -
PromptWizard: Task-Aware Prompt Optimization Framework
[Paper] · arXiv:2405.18369
Taxonomy: L2. Updated object(s): 1.1 Instruction; 1.4 Prompt & Context. -
ProTeGi: Automatic Prompt Optimization with 'Gradient Descent' and Beam Search
[Paper] · arXiv:2305.03495
Taxonomy: L2. Updated object(s): 1.2 Task Prompt. -
PYTHALAB-MERA: Validation-Grounded Memory, Retrieval, and Acceptance Control for Frozen-LLM Coding Agents
[Paper] · arXiv:2605.08468
Taxonomy: L2. Updated object(s): 2.1 Experience Memory; 1.5 Context; 4.4 Skill Library. -
QUBE: Enhancing Automatic Heuristic Design via Quality-Uncertainty Balanced Evolution
[Paper] · arXiv:2412.20694
Taxonomy: L2. Updated object(s): 9.1 Program Code; 6.5 Meta-optimization. -
QueenBee Planner: Skill-Evolving Communication Topologies for Token-Efficient LLM Multi-Agent Systems
[Paper] · arXiv:2606.27492
Taxonomy: L2. Updated object(s): 2.3 Procedural Memory; 3.5 Multi-agent. -
RankEvolve: Automating the Discovery of Retrieval Algorithms via LLM-Driven Evolution
[Paper] · arXiv:2602.16932
Taxonomy: L2. Updated object(s): 9.2 Algorithm. -
Recursive Harness Self-Improvement
[Paper] · arXiv:2607.15524
Taxonomy: L2. Updated object(s): 3.1 Workflow; 3.5 Multi-agent. -
Reflection-Based Task Adaptation for Self-Improving VLA
[Paper] · arXiv:2510.12710
Taxonomy: L2. Updated object(s): 5.1 Model Weights; 7.2 Reward / Fitness; 6.4 Curriculum. -
REFLEX: Reflective Evolution from LLM Experience
[Paper] · arXiv:2606.16496
Taxonomy: L2. Updated object(s): 9.1 Program Code; 4.4 Skill Library. -
Repeated post-training is not Self-improving: Diagnosing Scientific Amnesia in Continual DPO Pipelines
[Paper] · arXiv:2606.21089
Taxonomy: L2. Updated object(s): 5.1 Model Weights; 6.5 Meta-optimization. -
Rethinking Code Similarity for Automated Algorithm Design with LLMs
[Paper] · arXiv:2603.02787
Taxonomy: L2. Updated object(s): 7.2 Reward / Fitness; 3.6 Scaffold Code. -
Revisiting OPRO: The Limitations of Small-Scale LLMs as Optimizers
[Paper] · arXiv:2405.10276
Taxonomy: L2. Updated object(s): 1.2 Task Prompt. -
RLPrompt: Optimizing Discrete Text Prompts with Reinforcement Learning
[Paper] · arXiv:2205.12548
Taxonomy: L2. Updated object(s): 1.2 Task Prompt. -
S1-NexusAgent: a Self-Evolving Agent Framework for Multidisciplinary Scientific Research
[Paper] · arXiv:2602.01550
Taxonomy: L2. Updated object(s): 4.4 Skill Library. -
Self-Consolidating Language Models: Continual Knowledge Incorporation from Context
[Paper] · arXiv:2605.07076
Taxonomy: L2. Updated object(s): 5.1 Model Weights; 5.2 Adapter. -
Self-Harness: Harnesses That Improve Themselves
[Paper] · arXiv:2606.09498
Taxonomy: L2. Updated object(s): 3.6 Scaffold Code; 1.1 Instruction. -
Self-Improvement Can Self-Regress: The Rise-and-Collapse Failure Mode of LLM Self-Training
[Paper] · arXiv:2606.21090
Taxonomy: L2. Updated object(s): 5.1 Model Weights; 6.5 Meta-optimization. -
SePO: Self-Evolving Prompt Agent for System Prompt Optimization
[Paper] · arXiv:2606.04465
Taxonomy: L2. Updated object(s): 1.2 Task Prompt; 1.1 Instruction. -
SGM: A Statistical Godel Machine for Risk-Controlled Recursive Self-Modification
[Paper] · arXiv:2510.10232
Taxonomy: L2. Updated object(s): 6.3 Train Schedule. -
SHARP: A Self-Evolving Human-Auditable Rubric Policy for Financial Trading Agents
[Paper] · arXiv:2605.06822
Taxonomy: L2. Updated object(s): 1.1 Instruction. -
SIA: Self Improving AI with Harness & Weight Updates
[Paper] · arXiv:2605.27276
Taxonomy: L2. Updated object(s): 10.2 Full-system / Co-evolution; 3.6 Scaffold Code; 5.1 Model Weights. -
SignalClaw: LLM-Guided Evolutionary Synthesis of Interpretable Traffic Signal Control Skills
[Paper] · arXiv:2604.05535
Taxonomy: L2. Updated object(s): 9.1 Program Code; 4.4 Skill Library. -
Skill-R1: Agent Skill Evolution via Reinforcement Learning
[Paper] · arXiv:2605.09359
Taxonomy: L2. Updated object(s): 4.4 Skill Library; 5.1 Model Weights. -
SkillCoach: Self-Evolving Rubrics for Evaluating and Enhancing Agentic Skill-Use
[Paper] · arXiv:2607.01874
Taxonomy: L2. Updated object(s): 7.1 Judge; 5.1 Model Weights; 6.4 Curriculum. -
SkillMaster: Toward Autonomous Skill Mastery in LLM Agents
[Paper] · arXiv:2605.08693
Taxonomy: L2. Updated object(s): 4.4 Skill Library; 5.1 Model Weights. -
SkillRevise: Improving LLM-Authored Agent Skills via Trace-Conditioned Skill Revision
[Paper] · arXiv:2606.01139
Taxonomy: L2. Updated object(s): 4.4 Skill Library. -
SkillSmith: Co-Evolving Skills and Tools for Self-Improving Agent Systems
[Paper] · arXiv:2606.01314
Taxonomy: L2. Updated object(s): 4.4 Skill Library; 4.3 Tool Code; 2.1 Experience Memory. -
SOCIA-EVO: Automated Simulator Construction via Dual-Anchored Bi-Level Optimization
[Paper] · arXiv:2604.17351
Taxonomy: L2. Updated object(s): 2.2 Knowledge Memory; 9.1 Program Code. -
Support Vector Rubrics: Closing the Gap Between Self-Generated and Human Rubrics
[Paper] · arXiv:2606.08077
Taxonomy: L2. Updated object(s): 7.1 Judge; 1.3 Prompt & Context. -
Taming I2V models for Image HOI Editing: A Cognitive Benchmark and Agentic Self-Correcting Framework
[Paper] · arXiv:2606.19073
Taxonomy: L2. Updated object(s): 2.2 Knowledge Memory; 1.2 Task Prompt. -
The Time is Here for Just-in-Time Systems: Challenges and Opportunities
[Paper] · arXiv:2605.24096
Taxonomy: L2. Updated object(s): 9.1 Program Code. -
Towards AGI A Pragmatic Approach Towards Self Evolving Agent
[Paper] · arXiv:2601.11658
Taxonomy: L2. Updated object(s): 4.1 Tool Set; 5.1 Model Weights. -
Trajectory-Informed Memory Generation for Self-Improving Agent Systems
[Paper] · arXiv:2603.10600
Taxonomy: L2. Updated object(s): 2.3 Procedural Memory; 1.5 Context. -
Understanding the Challenges in Iterative Generative Optimization with LLMs
[Paper] · arXiv:2603.23994
Taxonomy: L2. Updated object(s): 9.1 Program Code; 1.2 Task Prompt; 3.6 Scaffold Code. -
Unifying Temporal and Structural Credit Assignment in LLM-Based Multi-Agent Prompt Optimization
[Paper] · arXiv:2605.30227
Taxonomy: L2. Updated object(s): 1.1 Instruction. -
VASO: Formally Verifiable Self-Evolving Skills for Physical AI Agents
[Paper] · arXiv:2606.05395
Taxonomy: L2. Updated object(s): 4.4 Skill Library; 4.2 Tool Interface. -
When LLM Reward Design Fails: Diagnostic-Driven Refinement for Sparse Structured RL
[Paper] · arXiv:2605.28918
Taxonomy: L2. Updated object(s): 9.1 Program Code.
3. L3 - Autonomy over Future Learning Experience ↑ top
The learner's evolving state influences the experience, task, or curriculum acquired next. 65 papers.
Featured representative papers
| Paper | Representative mechanism |
|---|---|
| POET | Co-evolves environments and solvers to generate an expanding adaptive curriculum. |
| Voyager | Couples automatic curricula with a persistent skill library for open-ended embodied learning. |
| EnvGen | Generates and adapts training environments for embodied agents. |
| Absolute Zero | Lets a single model propose and solve code-grounded tasks, with a code executor verifying both tasks and answers. |
| R-Zero | Co-evolves task proposal and solving to create new learning experience from zero data. |
| SIMA 2 | Uses Gemini to generate tasks and rewards so the agent can autonomously learn skills in a new virtual environment. |
Browse the full L3 catalog (65 papers)
Table-derived extension
Table 5 identifies the following learner-conditioned future-experience loop, complementary to the self-play and autonomous-practice systems already in this section.
-
SIMA 2: A Generalist Embodied Agent for Virtual Worlds
[Paper] · arXiv:2512.04797
Survey-table rationale: In the full ASKA setting, evaluation feedback directs practice toward weaker skills; later experience is conditioned on the learner's changing capability state. Updated object(s): 8.1 Training / Experience Data; 8.2 Task / Curriculum Generator; 8.3 Environment / Simulator. -
Absolute Zero: Reinforced Self-play Reasoning with Zero Data
[Paper] · arXiv:2505.03335
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 8.2 Task Generator. -
Active Zero: Self-Evolving Vision-Language Models through Active Environment Exploration
[Paper] · arXiv:2602.11241
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 8.2 Task Generator. -
Agent0: Unleashing Self-Evolving Agents from Zero Data via Tool-Integrated Reasoning
[Paper] · arXiv:2511.16043
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 8.2 Task Generator. -
ANCORA: Learning to Question via Manifold-Anchored Self-Play for Verifiable Reasoning
[Paper] · arXiv:2604.27644
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 8.2 Task Generator; 6.4 Curriculum. -
ASH: Agents that Self-Hone via Embodied Learning
[Paper] · arXiv:2605.14211
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 2.1 Experience Memory. -
BenchEvolver: Frontier Task Synthesis via Solution-Centric Evolution
[Paper] · arXiv:2606.01286
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 8.2 Task Generator. -
Better LLM Reasoning via Dual-Play
[Paper] · arXiv:2511.11881
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 8.2 Task Generator. -
Close the Loop: Synthesizing Infinite Tool-Use Data via Multi-Agent Role-Playing
[Paper] · arXiv:2512.23611
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 8.1 Experience Data. -
Concordia: Self-Improving Synthetic Tables for Federated LLMs
[Paper] · arXiv:2605.09855
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 8.1 Experience Data. -
DISCOVER: Automated Curricula for Sparse-Reward Reinforcement Learning
[Paper] · arXiv:2505.19850
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 8.1 Experience Data. -
Disentangling Intent from Role: Adversarial Self-Play for Persona-Invariant Safety Alignment
[Paper] · arXiv:2605.01899
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 8.1 Experience Data. -
DUEL: Adversarial Self-Play for Multimodal Reasoning
[Paper] · arXiv:2605.24794
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 8.2 Task Generator. -
EnvGen: Generating and Adapting Environments via LLMs for Training Embodied Agents
[Paper] · arXiv:2403.12014
Taxonomy: L3. Updated object(s): 8.2 Task Generator; 5.1 Model Weights. -
EnvHarness: Awakening Static Worlds for Agent Learning
[Paper] · arXiv:2608.19880
Taxonomy: L3. Updated object(s): 8.3 Environment; 4.4 Skill Library. -
EvoCurr: Self-evolving Curriculum with Behavior Code Generation for Complex Decision-making
[Paper] · arXiv:2508.09586
Taxonomy: L3. Updated object(s): 8.2 Task Generator; 9.1 Program Code. -
EvoLMM: Self-Evolving Large Multimodal Models with Continuous Rewards
[Paper] · arXiv:2511.16672
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 8.2 Task Generator. -
EvoVid: Temporal-Centric Self-Evolution for Video Large Language Models
[Paper] · arXiv:2605.21931
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 8.2 Task Generator. -
From Context to Skills: Can Language Models Learn from Context Skillfully?
[Paper] · arXiv:2604.27660
Taxonomy: L3. Updated object(s): 4.4 Skill Library; 8.2 Task Generator. -
G-Zero: Self-Play for Open-Ended Generation from Zero Data
[Paper] · arXiv:2605.09959
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 8.2 Task Generator. -
GASP: Guided Asymmetric Self-Play For Coding LLMs
[Paper] · arXiv:2603.15957
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 8.1 Experience Data. -
GenEnv: Difficulty-Aligned Co-Evolution Between LLM Agents and Environment Simulators
[Paper] · arXiv:2512.19682
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 8.2 Task Generator. -
GeoX: Mastering Geospatial Reasoning Through Self-Play and Verifiable Rewards
[Paper] · arXiv:2605.20006
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 8.2 Task Generator. -
iReasoner: Trajectory-Aware Intrinsic Reasoning Supervision for Self-Evolving Large Multimodal Models
[Paper] · arXiv:2601.05877
Taxonomy: L3. Updated object(s): 5.2 Adapter; 6.1 Objective. -
Knowledge-Graph Paths as Intermediate Supervision for Self-Evolving Search Agents
[Paper] · arXiv:2605.05702
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 8.1 Experience Data. -
Language Models Need Sleep: Learning to Self-Modify and Consolidate Memories
[Paper] · arXiv:2606.03979
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 5.2 Adapter; 8.2 Task Generator. -
Learning to Adapt: Self-Improving Web Agent via Cognitive-Aware Exploration
[Paper] · arXiv:2605.31365
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 8.1 Experience Data. -
Learning to Build the Environment: Self-Evolving Reasoning RL via Verifiable Environment Synthesis
[Paper] · arXiv:2605.14392
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 8.2 Task Generator. -
Lifelong Robot Library Learning: Bootstrapping Composable and Generalizable Skills for Embodied Control with Language Models
[Paper] · arXiv:2406.18746
Taxonomy: L3. Updated object(s): 4.4 Skill Library; 2.1 Experience Memory. -
LLM-as-a-Tutor: Policy-Aware Prompt Adaptation for Non-Verifiable RL
[Paper] · arXiv:2607.04412
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 8.1 Experience Data; 7.2 Reward / Fitness. -
MM-Zero: Self-Evolving Multi-Model Vision Language Models From Zero Data
[Paper] · arXiv:2603.09206
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 8.2 Task Generator. -
Multi-Agent Evolve: LLM Self-Improve through Co-evolution
[Paper] · arXiv:2510.23595
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 7.1 Judge; 8.1 Experience Data. -
OMNI-EPIC: Open-endedness via Models of Human Notions of Interestingness with Environments Programmed in Code
[Paper] · arXiv:2405.15568
Taxonomy: L3. Updated object(s): 8.2 Task Generator; 8.3 Environment; 5.1 Model Weights. -
Paired Open-Ended Trailblazer (POET): Endlessly Generating Increasingly Complex and Diverse Learning Environments and Their Solutions
[Paper] · arXiv:1901.01753
Taxonomy: L3. Updated object(s): 8.2 Task Generator; 8.3 Environment. -
PopuLoRA: Co-Evolving LLM Populations for Reasoning Self-Play
[Paper] · arXiv:2605.16727
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 8.2 Task Generator; 6.5 Meta-optimization. -
Project Auto-World: Towards Automated Benchmarking of Neural Relational Reasoners
[Paper] · arXiv:2606.24965
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 8.2 Task Generator. -
Propose, Solve, Verify: Self-Play Through Formal Verification
[Paper] · arXiv:2512.18160
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 8.2 Task Generator. -
R-Diverse: Mitigating Diversity Illusion in Self-Play LLM Training
[Paper] · arXiv:2602.13103
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 8.2 Task Generator. -
R-Zero: Self-Evolving Reasoning LLM from Zero Data
[Paper] · arXiv:2508.05004
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 8.2 Task Generator. -
SAGE: Multi-Agent Self-Evolution for LLM Reasoning
[Paper] · arXiv:2603.15255
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 8.1 Experience Data. -
Scaling Self-Play with Self-Guidance
[Paper] · arXiv:2604.20209
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 8.2 Task Generator. -
SEAgent: Self-Evolving Computer Use Agent with Autonomous Learning from Experience
[Paper] · arXiv:2508.04700
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 8.2 Task Generator. -
Search Self-play: Pushing the Frontier of Agent Capability without Supervision
[Paper] · arXiv:2510.18821
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 8.2 Task Generator. -
SEIF: Self-Evolving Reinforcement Learning for Instruction Following
[Paper] · arXiv:2605.07465
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 8.2 Task Generator; 7.1 Judge. -
Seirênes: Adversarial Self-Play with Evolving Distractions for LLM Reasoning
[Paper] · arXiv:2605.11636
Taxonomy: L3. Updated object(s): 5.1 Model Weights. -
Self-Play Only Evolves When Self-Synthetic Pipeline Ensures Learnable Information Gain
[Paper] · arXiv:2603.02218
Taxonomy: L3. Updated object(s): 8.2 Task Generator; 5.1 Model Weights. -
Self-Questioning Language Models
[Paper] · arXiv:2508.03682
Taxonomy: L3. Updated object(s): 5.1 Model Weights. -
SEVA: Self-Evolving Verification Agent with Process Reward for Fact Attribution
[Paper] · arXiv:2606.29713
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 6.4 Curriculum. -
SimWorld Studio: Automatic Environment Generation with Evolving Coding Agent for Embodied Agent Learning
[Paper] · arXiv:2605.09423
Taxonomy: L3. Updated object(s): 8.3 Environment; 8.2 Task Generator; 4.4 Skill Library. -
SKILLFOUNDRY: Building Self-Evolving Agent Skill Libraries from Heterogeneous Scientific Resources
[Paper] · arXiv:2604.03964
Taxonomy: L3. Updated object(s): 4.4 Skill Library. -
SkillHarness: Harnessing Safe Skills for Computer-Use Agents
[Paper] · arXiv:2606.20636
Taxonomy: L3. Updated object(s): 4.4 Skill Library. -
Socratic-SWE: Self-Evolving Coding Agents via Trace-Derived Agent Skills
[Paper] · arXiv:2606.07412
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 2.1 Experience Memory; 6.4 Curriculum. -
SPARK: Self-Play with Asymmetric Reward from Knowledge Graphs
[Paper] · arXiv:2605.05546
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 8.1 Experience Data. -
STELLA: Self-Evolving LLM Agent for Biomedical Research
[Paper] · arXiv:2507.02004
Taxonomy: L3. Updated object(s): 4.1 Tool Set; 4.4 Skill Library. -
Survive or Collapse: The Asymmetric Roles of Data Gating and Reward Grounding in Self-Play RL
[Paper] · arXiv:2605.22217
Taxonomy: L3. Updated object(s): 5.1 Model Weights. -
Tool-R0: Self-Evolving LLM Agents for Tool-Learning from Zero Data
[Paper] · arXiv:2602.21320
Taxonomy: L3. Updated object(s): 8.2 Task Generator; 5.1 Model Weights. -
Towards Healthy Evolution: Exploring the Role and Mechanisms of Human-Agent Interaction in Self-Evolving Systems
[Paper] · arXiv:2606.06114
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 8.2 Task Generator; 1.1 Instruction. -
Towards Understanding Self-play for LLM Reasoning
[Paper] · arXiv:2510.27072
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 7.2 Reward / Fitness. -
TREX: Automating LLM Fine-tuning via Agent-Driven Tree-based Exploration
[Paper] · arXiv:2604.14116
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 8.1 Experience Data. -
TTCS: Test-Time Curriculum Synthesis for Self-Evolving
[Paper] · arXiv:2601.22628
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 6.1 Objective. -
TTSR: Test-Time Self-Evolving via Reflection
[Paper] · arXiv:2603.03297
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 8.2 Task Generator; 2.1 Experience Memory. -
Verifier-Backed Hard Problem Generation for Mathematical Reasoning
[Paper] · arXiv:2605.06660
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 8.1 Experience Data. -
Vocabulary Dropout for Curriculum Diversity in LLM Co-Evolution
[Paper] · arXiv:2604.03472
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 8.2 Task Generator. -
Voyager: An Open-Ended Embodied Agent with Large Language Models
[Paper] · arXiv:2305.16291
Taxonomy: L3. Updated object(s): 4.4 Skill Library; 8.2 Task Generator. -
WIST: Web-Grounded Iterative Self-Play Tree for Domain-Targeted Reasoning Improvement
[Paper] · arXiv:2603.22352
Taxonomy: L3. Updated object(s): 5.1 Model Weights; 8.2 Task Generator.
4. L4 - Autonomy in Deployment and Environmental Adaptation ↑ top
Reusable memory, skills, or deployed agent components persistently alter later behavior within a fixed improvement process. 45 papers.
Featured representative papers
| Paper | Representative mechanism |
|---|---|
| OS-Copilot | Accumulates skills from prior computer tasks to improve a generalist OS agent. |
| Trace2Skill | Distills trajectory-local lessons into transferable agent skills. |
| APEX | Uses autonomous policy exploration to improve deployed agent behavior. |
| Metis | Bridges textual and code memory for self-evolving agents. |
| PRACTICE | Converts interaction experience into expertise for embodied agents. |
| ENPIRE | Applies agentic self-improvement to robot policies in real-world deployment. |
Browse the full L4 catalog (45 papers)
Table-derived extensions
The following additions are explicitly discussed in Table 6 under trajectory distillation, iterative agent-system revision, or selective retention and deployment of updates.
-
DecoEvo: Score-Decoupled Co-Evolution of Solver and Rubric-Generator Skills in Text Space
[Paper] · arXiv:2607.25675
Survey-table rationale: Solver and rubric skills co-evolve across iterative rounds with score-independent audits. Updated object(s): 7.1 Evaluator / Judge; 4.4 Skill / Macro Library. -
Trace2Skill: Distill Trajectory-Local Lessons into Transferable Agent Skills
[Paper] · arXiv:2603.25158
Survey-table rationale: Error and success analysts merge patches into portable skill documents for later reuse. Updated object(s): 4.4 Skill / Macro Library. -
Metis: Bridging Text and Code Memory for Self-Evolving Agents
[Paper] · arXiv:2606.24151
Survey-table rationale: Text plans and code tools are retained after completed tasks and validated through reuse and sandbox compilation. Updated object(s): 2.3 Procedural Memory; 4.3 Tool Implementation. -
Library Drift: Diagnosing and Fixing a Silent Failure Mode in Self-Evolving LLM Skill Libraries
[Paper] · arXiv:2605.19576
Survey-table rationale: Periodic retention retires low-contribution skills and caps the evolving library. Updated object(s): 4.4 Skill / Macro Library. -
APEX: Autonomous Policy Exploration for Self-Evolving LLM Agents
[Paper] · arXiv:2605.21240
Survey-table rationale: A milestone dependency graph retains episode outcomes and informs later exploration. Updated object(s): 2.2 Semantic / Knowledge Memory. -
Learning Personalized Agents from Human Feedback
[Paper] · arXiv:2602.16173
Survey-table rationale: User clarification confirms and revises persistent preference entrie
Truncated — view the full README on GitHub.
See what people are saying
Hacker News (1)
Similar repos
Contributors
3 commits