Official PyTorch implementation of One-Minute Video Generation with Test-Time Training
See the code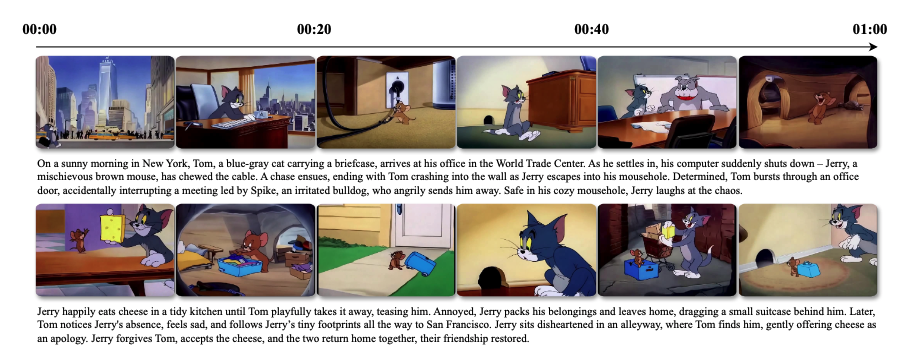 TTT-Video is a repository for finetuning diffusion transformers for style transfer and context extension. We use Test-Time Training (TTT) layers to handle long-range relationships across the global context, while reusing the original pretrained model's attention layers for local attention on each three second segment.
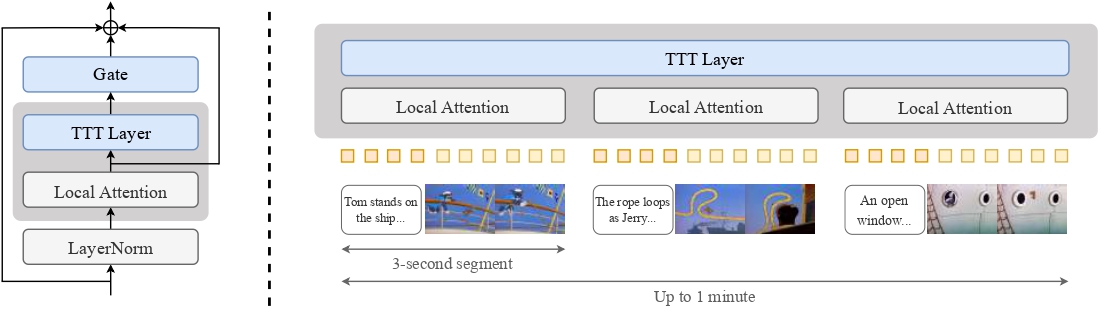
Our architecture adapts the CogVideoX 5B model, a diffusion transformer for text-to-video generation, by incorporating TTT layers. The original pretrained attention layers are retained for local attention on each 3-second segment and its corresponding text. In addition, TTT layers are inserted to process the global sequence as well as its reversed version, with their outputs gated through a residual connection.
To extend context beyond the pretrained 3-second segments, each segment is interleaved with text and video embeddings.
For a more detailed explanation of our architecture, please refer to our paper.
You can install dependencies needed for this project with conda (recommended) or a virtual environment.
conda env create -f environment.yaml
conda activate ttt-video
pip install -e .
After installing the dependencies, you must install the TTT-MLP kernel.
git submodule update --init --recursive
(cd ttt-tk && python setup.py install)
Note: You must have cuda toolkit (12.3+) and gcc11+ installed to build the TTT-MLP kernel. We only support training on H100s for TTT-MLP. You can install cuda toolkit here.
Please follow the instructions here to get the VAE and T5 encoder. To get the pretrained weights, download the diffusion_pytorch_model-00001-of-00002.safetensors and diffusion_pytorch_model-00002-of-00002.safetensors files from HuggingFace.
Note: We only use the 5B weights, not the 2B weights. Make sure you are downloading the correct model.
Note: These are the pretrained model weights, not the final model weights used to generate our demonstration videos.
2,576 followers · starred Apr 2025
296 followers · starred Sep 2025
169 followers · starred Apr 2025
500 followers · starred Apr 2025
Official PyTorch implementation of One-Minute Video Generation with Test-Time Training
See the code
TTT-Video is a repository for finetuning diffusion transformers for style transfer and context extension. We use Test-Time Training (TTT) layers to handle long-range relationships across the global context, while reusing the original pretrained model's attention layers for local attention on each three second segment.
Our architecture adapts the CogVideoX 5B model, a diffusion transformer for text-to-video generation, by incorporating TTT layers. The original pretrained attention layers are retained for local attention on each 3-second segment and its corresponding text. In addition, TTT layers are inserted to process the global sequence as well as its reversed version, with their outputs gated through a residual connection.
To extend context beyond the pretrained 3-second segments, each segment is interleaved with text and video embeddings.
For a more detailed explanation of our architecture, please refer to our paper.
You can install dependencies needed for this project with conda (recommended) or a virtual environment.
conda env create -f environment.yaml
conda activate ttt-video
pip install -e .
After installing the dependencies, you must install the TTT-MLP kernel.
git submodule update --init --recursive
(cd ttt-tk && python setup.py install)
Note: You must have cuda toolkit (12.3+) and gcc11+ installed to build the TTT-MLP kernel. We only support training on H100s for TTT-MLP. You can install cuda toolkit here.
Please follow the instructions here to get the VAE and T5 encoder. To get the pretrained weights, download the diffusion_pytorch_model-00001-of-00002.safetensors and diffusion_pytorch_model-00002-of-00002.safetensors files from HuggingFace.
Note: We only use the 5B weights, not the 2B weights. Make sure you are downloading the correct model.
Note: These are the pretrained model weights, not the final model weights used to generate our demonstration videos.
2,576 followers · starred Apr 2025
296 followers · starred Sep 2025
169 followers · starred Apr 2025
500 followers · starred Apr 2025