Multimodal video retrieval system for HCMC AI Challenge 2025 | SigLIP Keyframe extraction + DINOv3 + WhisperX
Python
5
133 commits
updated Feb 3, 2026
This repository contains the implementation of the float97's video retrieval system, developed for the HCMC AI Challenge 2025. The system is designed to perform complex event retrieval on large, untrimmed video collections, covering domains such as news, sports, tourism, and cooking.
The solution addresses three primary competition tasks:
⚠️ Work In Progress: The components related to the Vintern-1B-v3_5 model for OCR extraction and image captioning are currently under development. The related code has been moved to the
wip/folder. The current system focuses on keyframe extraction, embedding generation, and multimodal search using SigLIP, DINOv3, and WhisperX.
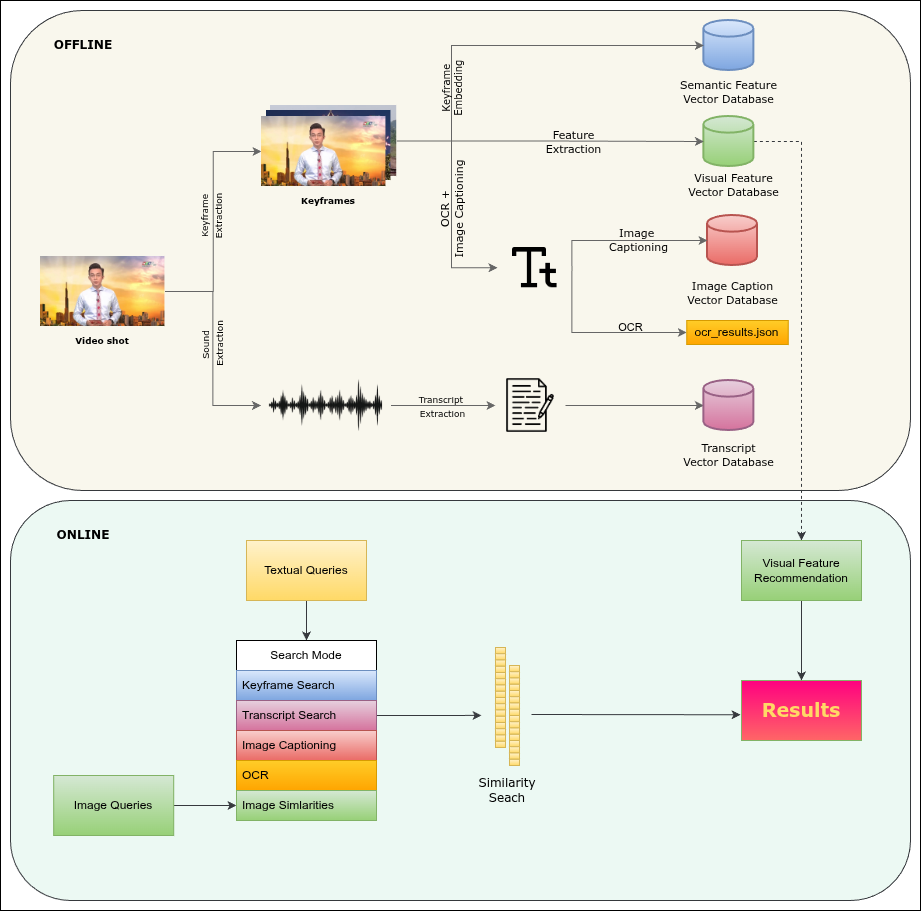
The architecture is divided into an Offline Processing Pipeline for indexing and an Online Retrieval Phase for user interaction.
Your project structure should look like this:
float97_Video_Search/
│
├── 📂 data-source/                      # Source videos (read-only)
│   └── videos/                          # Place your .mp4 files here
│
├── 📂 data-staging/                     # Intermediate processing artifacts
│   ├── keyframes/                       # Extracted keyframe images (JPG)
│   ├── preprocessing/                   # TransNetV2 scene detection results
│   ├── map-keyframes/                   # CSV files mapping keyframes to frame indices
│   ├── audios/                          # Extracted audio files (WAV)
│   ├── audio-chunk-timestamps/          # Audio chunk timing metadata
│   ├── transcripts/                     # WhisperX transcription results (JSON)
│   └── vintern_results.json             # Vintern OCR & caption results (WIP)
│
├── 📂 data-index/                       # Search indices for fast retrieval
│   ├── siglip_keyframe_embedding.index  # FAISS index for visual search
│   ├── siglip_keyframe_metadata.npy     # Metadata for visual search results
│   ├── transcript_embeddings.npy        # Embeddings for transcript search
│   ├── transcript_metadata.json         # Metadata for transcript search
│   └── keyframe_metadata.npy            # General keyframe metadata
│
├── 📂 wip/                              # Work in Progress - Experimental features
│   ├── ocr_object.py                    # Vintern OCR extraction
│   ├── ocr_processing.py                # Vintern processing pipeline
│   ├── ocr_cleaning.py                  # Vintern results cleaning
│   ├── vintern_cleaning.py              # Additional Vintern utilities
│   ├── caption_search.py                # Caption-based search (experimental)
│   ├── caption_embedding.py             # Caption embeddings (experimental)
│   └── check_vintern_processing.py      # Vintern processing verification
│
├── 📂 transnetv2-weights/               # Pre-trained TransNetV2 model weights
│
├── 🎯 Core Processing Scripts
│   ├── transnetv2.py                    # Scene boundary detection
│   ├── keyframe_extractor.py            # Extract keyframes from videos
│   ├── dinov3_embedding.py              # Generate DINOv3 embeddings for similarity
│   ├── transcript_extractor.py          # Extract audio and generate transcripts
│   ├── transcript_embedding.py          # Generate transcript embeddings
│   └── keyframe_embedding.py            # Generate SigLIP visual embeddings
│
├── 🔍 Search Modules
│   ├── keyframe_search.py               # Visual keyframe search
│   ├── siglip_search.py                 # SigLIP-based visual search
│   ├── dinov3_search.py                 # DINOv3-based similarity search
│   ├── transcript_search.py             # Audio transcript search
│   ├── ocr_search.py                    # OCR text search (Vintern-based)
│   ├── temporal_search.py               # Temporal event search
│   └── attention_search.py              # Attention-based search
│
├── 🌐 Web Application
│   ├── web_app.py                       # Main Streamlit web interface
│   └── frame_playback.py                # Video frame playback utilities
│
├── 🛠️ Utilities
│   ├── helpers.py                       # Common helper functions
│   ├── http_requests.py                 # HTTP request utilities for submission
│   ├── json_to_csv.py                   # JSON to CSV converter
│   ├── load_all_video_keyframes_info.py # Load all keyframe information
│   └── old_temp_search.py               # Legacy search implementation
│
├── 📜 Scripts
│   ├── run-pipeline.sh                  # Main processing pipeline executor
│   ├── preprocessing.sh                 # Preprocessing script
│   ├── create_dir.sh                    # Create required directories
│   └── format-code.sh                   # Code formatting utility
│
├── 📋 Configuration
│   ├── requirements.txt                 # Python dependencies
│   ├── README.md                        # This file
│   └── AIC_pipeline.png                 # Architecture diagram
│
└── 📊 Query & Submission
    ├── _query/                          # Test queries for development
    ├── pack1-groupA/                    # Competition query pack 1
    ├── pack3-groupA/                    # Competition query pack 3
    └── submission/                      # Generated submission files
# Environment Setup
conda create -n aic python=3.10 -y
conda activate aic
pip install -r requirements.txt

# Directory Initialization
bash create-dir.sh
To process raw video data and generate the searchable index:
bash run-pipeline.sh
# Set library path for GPU optimization
export LD_LIBRARY_PATH=$CONDA_PREFIX/lib:$LD_LIBRARY_PATH

# Execute web application
streamlit run web_app.py --server.port 8501

# On the remote server, you might want to run this instead
streamlit run web_app.py --server.address 0.0.0.0 --server.port 8501 --server.headless true
Multimodal video retrieval system for HCMC AI Challenge 2025 | SigLIP Keyframe extraction + DINOv3 + WhisperX
Python
5
133 commits
updated Feb 3, 2026
This repository contains the implementation of the float97's video retrieval system, developed for the HCMC AI Challenge 2025. The system is designed to perform complex event retrieval on large, untrimmed video collections, covering domains such as news, sports, tourism, and cooking.
The solution addresses three primary competition tasks:
⚠️ Work In Progress: The components related to the Vintern-1B-v3_5 model for OCR extraction and image captioning are currently under development. The related code has been moved to the
wip/folder. The current system focuses on keyframe extraction, embedding generation, and multimodal search using SigLIP, DINOv3, and WhisperX.
The architecture is divided into an Offline Processing Pipeline for indexing and an Online Retrieval Phase for user interaction.
Your project structure should look like this:
float97_Video_Search/
│
├── 📂 data-source/                      # Source videos (read-only)
│   └── videos/                          # Place your .mp4 files here
│
├── 📂 data-staging/                     # Intermediate processing artifacts
│   ├── keyframes/                       # Extracted keyframe images (JPG)
│   ├── preprocessing/                   # TransNetV2 scene detection results
│   ├── map-keyframes/                   # CSV files mapping keyframes to frame indices
│   ├── audios/                          # Extracted audio files (WAV)
│   ├── audio-chunk-timestamps/          # Audio chunk timing metadata
│   ├── transcripts/                     # WhisperX transcription results (JSON)
│   └── vintern_results.json             # Vintern OCR & caption results (WIP)
│
├── 📂 data-index/                       # Search indices for fast retrieval
│   ├── siglip_keyframe_embedding.index  # FAISS index for visual search
│   ├── siglip_keyframe_metadata.npy     # Metadata for visual search results
│   ├── transcript_embeddings.npy        # Embeddings for transcript search
│   ├── transcript_metadata.json         # Metadata for transcript search
│   └── keyframe_metadata.npy            # General keyframe metadata
│
├── 📂 wip/                              # Work in Progress - Experimental features
│   ├── ocr_object.py                    # Vintern OCR extraction
│   ├── ocr_processing.py                # Vintern processing pipeline
│   ├── ocr_cleaning.py                  # Vintern results cleaning
│   ├── vintern_cleaning.py              # Additional Vintern utilities
│   ├── caption_search.py                # Caption-based search (experimental)
│   ├── caption_embedding.py             # Caption embeddings (experimental)
│   └── check_vintern_processing.py      # Vintern processing verification
│
├── 📂 transnetv2-weights/               # Pre-trained TransNetV2 model weights
│
├── 🎯 Core Processing Scripts
│   ├── transnetv2.py                    # Scene boundary detection
│   ├── keyframe_extractor.py            # Extract keyframes from videos
│   ├── dinov3_embedding.py              # Generate DINOv3 embeddings for similarity
│   ├── transcript_extractor.py          # Extract audio and generate transcripts
│   ├── transcript_embedding.py          # Generate transcript embeddings
│   └── keyframe_embedding.py            # Generate SigLIP visual embeddings
│
├── 🔍 Search Modules
│   ├── keyframe_search.py               # Visual keyframe search
│   ├── siglip_search.py                 # SigLIP-based visual search
│   ├── dinov3_search.py                 # DINOv3-based similarity search
│   ├── transcript_search.py             # Audio transcript search
│   ├── ocr_search.py                    # OCR text search (Vintern-based)
│   ├── temporal_search.py               # Temporal event search
│   └── attention_search.py              # Attention-based search
│
├── 🌐 Web Application
│   ├── web_app.py                       # Main Streamlit web interface
│   └── frame_playback.py                # Video frame playback utilities
│
├── 🛠️ Utilities
│   ├── helpers.py                       # Common helper functions
│   ├── http_requests.py                 # HTTP request utilities for submission
│   ├── json_to_csv.py                   # JSON to CSV converter
│   ├── load_all_video_keyframes_info.py # Load all keyframe information
│   └── old_temp_search.py               # Legacy search implementation
│
├── 📜 Scripts
│   ├── run-pipeline.sh                  # Main processing pipeline executor
│   ├── preprocessing.sh                 # Preprocessing script
│   ├── create_dir.sh                    # Create required directories
│   └── format-code.sh                   # Code formatting utility
│
├── 📋 Configuration
│   ├── requirements.txt                 # Python dependencies
│   ├── README.md                        # This file
│   └── AIC_pipeline.png                 # Architecture diagram
│
└── 📊 Query & Submission
    ├── _query/                          # Test queries for development
    ├── pack1-groupA/                    # Competition query pack 1
    ├── pack3-groupA/                    # Competition query pack 3
    └── submission/                      # Generated submission files
# Environment Setup
conda create -n aic python=3.10 -y
conda activate aic
pip install -r requirements.txt

# Directory Initialization
bash create-dir.sh
To process raw video data and generate the searchable index:
bash run-pipeline.sh
# Set library path for GPU optimization
export LD_LIBRARY_PATH=$CONDA_PREFIX/lib:$LD_LIBRARY_PATH

# Execute web application
streamlit run web_app.py --server.port 8501

# On the remote server, you might want to run this instead
streamlit run web_app.py --server.address 0.0.0.0 --server.port 8501 --server.headless true



