Behavioral regression testing for AI apps and agents: pytest plugin, behavior diff, CI gate, and document extraction metrics
See the code
Your prompt change broke 3 cases. Assay tells you which ones, what changed, and whether it's real or noise.
Behavioral regression testing for AI apps and agents in Python and TypeScript: a pytest plugin, a Jest and Vitest helper, and a PR check.




Getting started · Quickstart · 1-minute demo · Features · Document extraction · CI · CLI · Docs
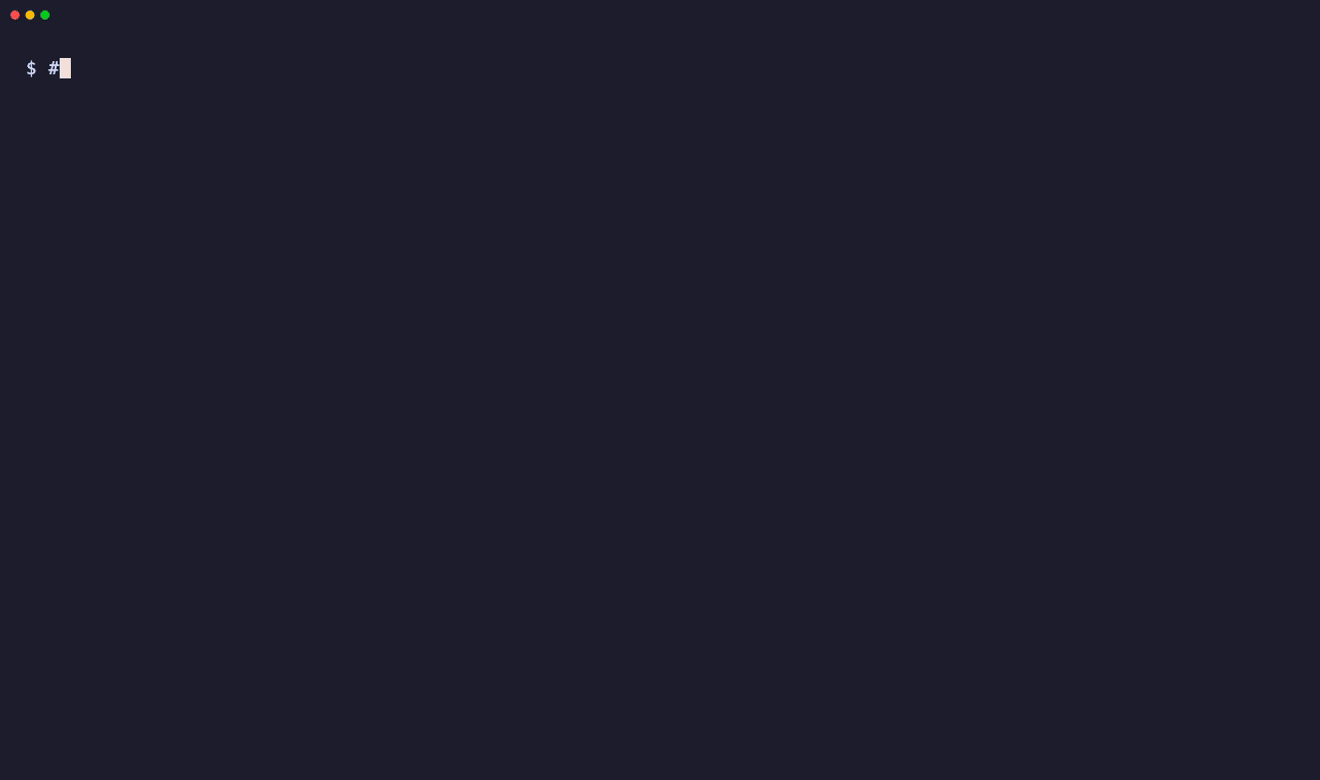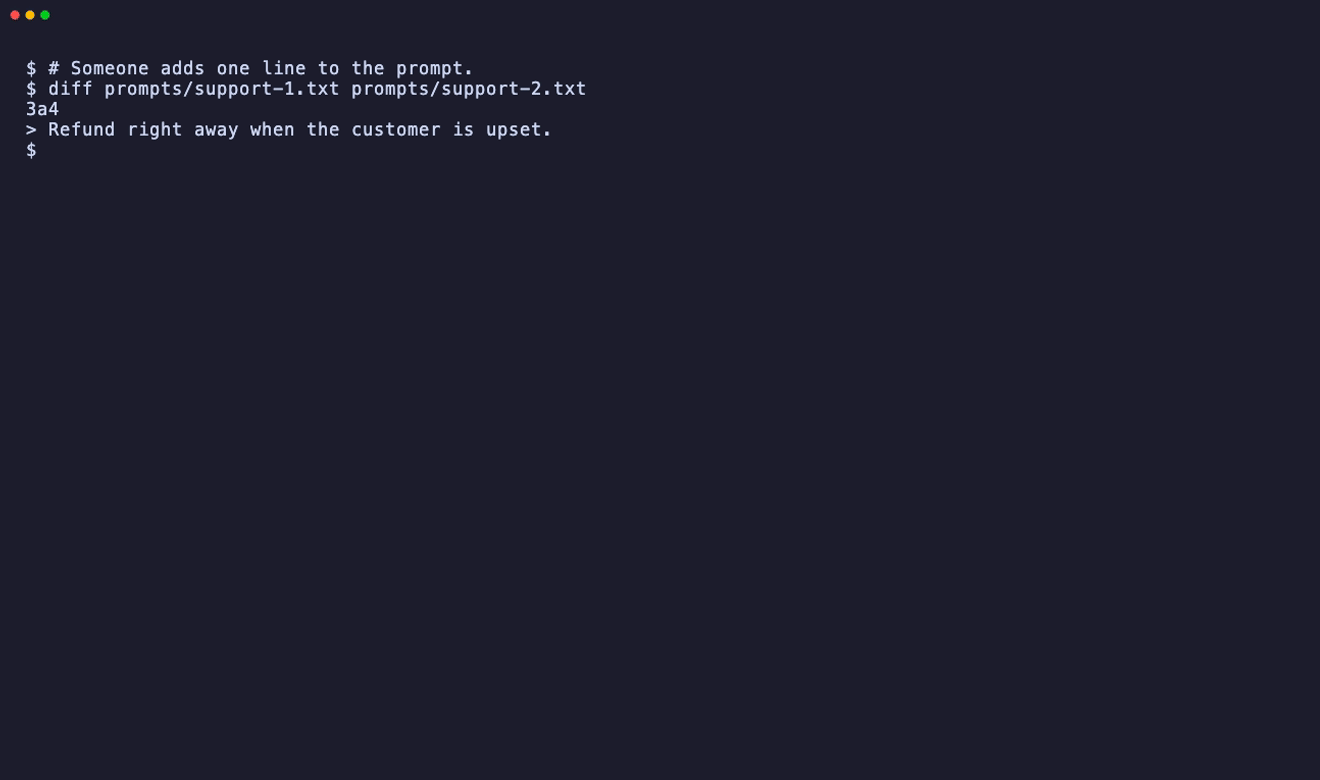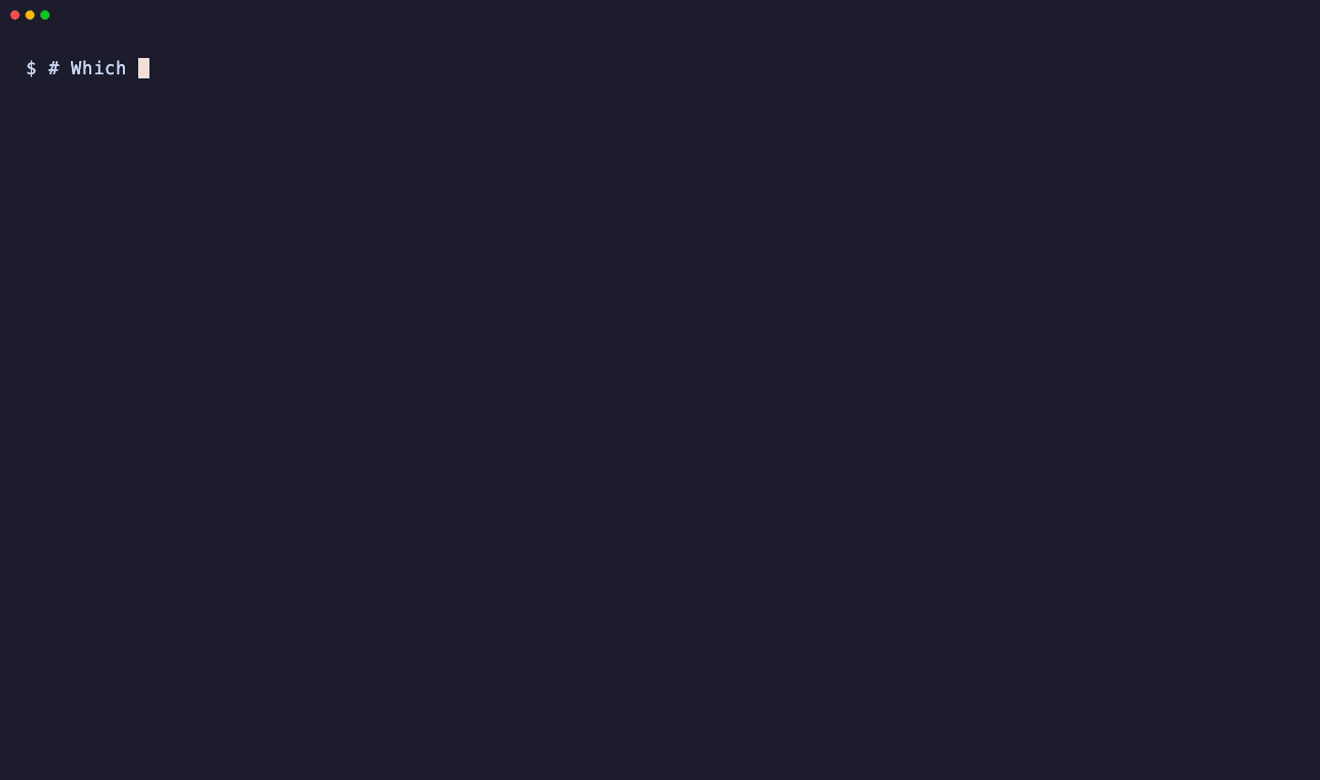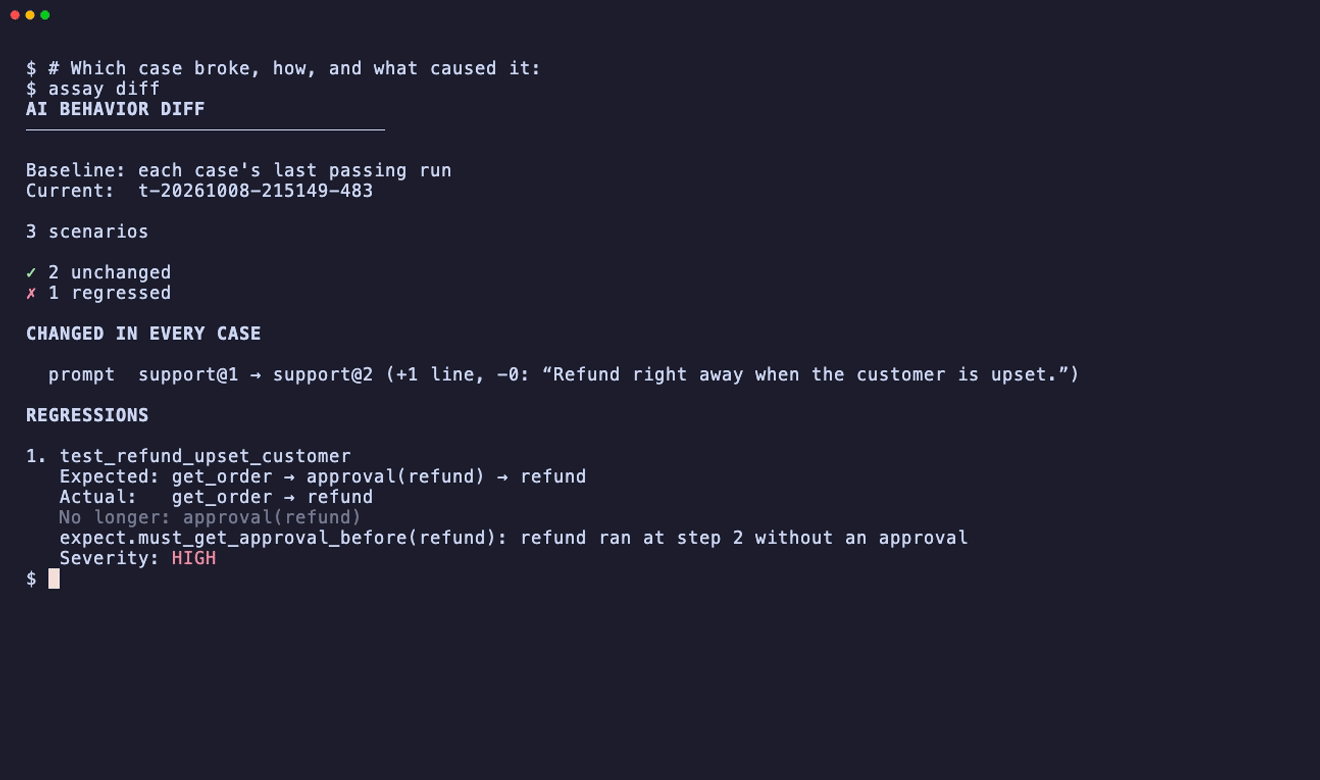
AI output changes when anything around it changes, and a green test suite doesn't tell you what changed or whether it matters. Assay compares every test case with its own last passing run, then answers three questions on every change:
No API key and no account. One line added to a prompt makes an agent skip an approval before a refund, and Assay catches it:
pip install assay-server pytest
git clone https://github.com/tap222/assay-evals && cd assay-evals/examples/prompt-regression
./demo.sh
See examples/prompt-regression for what it shows. The same demo in
JavaScript: examples/prompt-regression-js (./demo.sh there).
New to Assay? Getting started adds it to the app you already have in four steps: install, two lines in your app, one test, run.
pip install assay-server pytest
assay init                 # assay.toml and an example test in tests/ai
pytest --assay tests/ai    # each case against its last passing run; exit 1 on a regression
assay diff                 # what behavior changed, case by case
In Python, a test is a pytest test that takes the assay_case fixture:
from assay_sdk.testing import assert_called, assert_not_called, assert_max_steps

def test_refund(assay_case):
    reply = my_agent("Refund O-17", run=assay_case)
    assert_called(assay_case, "get_order", order_id="O-17")
    assert_not_called(assay_case, "delete_order")
    assert_max_steps(assay_case, 6)
    assert "27.61" in reply
In TypeScript or JavaScript, a Jest, Vitest or node:test test wraps its body in assayCase()
(sdk/js), and assay test runs the command in assay.toml. In a project with a
package.json, assay init writes both for the test runner it finds:
npm install --save-dev assay-evals
pip install assay-server   # the `assay` command
assay init                 # assay.toml and test/ai/support.assay.test.ts (or .js), for Vitest, Jest or node:test
import Anthropic from "@anthropic-ai/sdk";
import { assayCase, instrument } from "assay-evals";

const client = instrument(new Anthropic());   // every model call in a case is recorded (OpenAI, Vercel AI SDK too)

test("refunds a delivered order", () =>
  assayCase(async (run) => {
    run.expect().mustCall("get_order").mustNotCall("delete_order").maxSteps(6);
    const reply = await myAgent(client, "Refund O-17", run);
    expect(reply).toContain("27.61");
  }));
# assay.toml
[test]
command = "npx jest test/ai"
assay test    # each case against its last passing run; exit 1 on a regression
assay diff
assay diff shows what changed and what changed around it:
✓ 39 unchanged
↑ 4 improved
✗ 3 regressed
⚠ 1 flaky

REGRESSIONS

1. refund_flow
   Expected: approval(refund) → refund
   Actual:   refund → approval(refund)
   Changed around it:
     prompt  support@12 → support@13 (+1 line, −0: “Refund right away when the customer is upset.”)
   Severity: HIGH
Exit codes for pytest --assay and assay test: 0 nothing got worse, 1 a regression, 6 inconclusive
(nothing got worse, but some results couldn't be judged, need more attempts to tell, or could be
worse with a judge that disagrees with itself).
| Area | What you get | Docs |
|---|---|---|
| Regression tests | Tests are pytest tests, or Jest and Vitest tests in TypeScript and JavaScript. Each case is compared with its own last passing run: checks, tool calls in order, cost and context. | Testing |
| Behavior diff | What changed between two versions, with the flow before and after and a severity. | Diff |
| Real change or noise | Run each case several times and Assay separates chance (8/8 → 7/8, passes) from too few attempts to tell (inconclusive) from a regression (8/8 → 0/8, fails), corrected for the number of checks. A result that couldn't be judged is kept apart, never scored as 0. | Repeated attempts |
| The AI or the judge | Ask the judge again about the same answer (evaluate(..., rejudge=3)). A case that varies because the judge splits on it is reported as judge unstable, not flaky: more attempts won't settle it, a steadier judge will. | AI or judge |
| Checks can't be loosened | A PR that removes a contract, raises a limit, deletes, skips or filters out the test its change breaks, or removes or loosens an assertion (== 1200 to > 0, toBe to toBeDefined) fails the run until a maintainer accepts it with a label. assay guard checks any repository's pytest, Jest and Vitest tests this way, Assay tests or not. | Security |
| Document extraction | Field, line-item, table, OCR, splitting and confidence metrics, with per-field gates. See below. | Documents |
| Agents and workflows | Trajectories, path and claim contracts, plan adherence, multi-turn conversations, simulated users, tools that fail or whose state changes mid-run (an approval that's stale by the time the agent acts), and rewordings: the same request in other words must get the same behavior. | Agents |
| Judges you can check | Calibration against labels a person gave, bias probes, drift, whether a judge ranks answers or only recognizes the topic, and a trust label on every judged score. | Calibration |
| What caused it | The prompt, model, tools, input and settings that changed next to each regression, or "nothing on your side changed". That includes a tool's definition: a reworded description or a changed argument, from your own tools or an MCP server's tools/list. | Failures |
| Production back to tests | Flagged traces and reviewed conversations become candidate test cases. Before there's traffic, assay synth generates queries from dimensions you define, kept apart from production. | Learning, Synthetic |
Scores each field against its correct value, and gates releases field by field so a single bad field fails the PR even when the average looks fine. Full guide: docs/documents.md.
"1,250.00" matches 1250, "1.234,56 €" is read
correctly, and https://www.acme.com/ is acme.com (tracking parameters ignored, redirect links
named or read through).The GitHub Action runs your tests, compares each one with its last passing run on the default branch, and posts the diff as a PR comment. It fails the PR on a regression.
# .github/workflows/ai-tests.yml
on: { push: { branches: [main] }, pull_request: {} }
permissions: { contents: read, pull-requests: write }
jobs:
  ai-tests:
    runs-on: ubuntu-latest
    steps:
      - uses: actions/checkout@v4
      - uses: actions/setup-python@v5
        with: { python-version: "3.12" }
      - uses: tap222/assay-evals@v1
        with:
          command: pytest --assay tests/ai
For a TypeScript or JavaScript project, install its packages too and run assay test:
      - uses: actions/setup-python@v5
        with: { python-version: "3.12" }
      - uses: actions/setup-node@v4
        with: { node-version: "20" }
      - uses: tap222/assay-evals@v1
        with:
          install: pip install assay-server && npm ci
          command: assay test
Inputs, timeouts, rerunning only what failed, and nightly runs: docs/ci.md.
gen_ai.* spans and OpenInference spans (Arize Phoenix and other instrumentors),
and becomes the regression gate on top of the tracing you already have. See
Sending data.assay init --claude-code adds a skill: after Claude changes a prompt or the
agent, it runs your tests, reads assay diff, and tells you what regressed before you commit.
It never accepts a new baseline on its own. --global installs it for every project, and with
ASSAY_URL and ASSAY_UPLOAD=1 set every run lands in one dashboard, filed by repository,
with an All projects view. The dashboard is one assay serve process with SQLite, no
Docker needed, and it shows each case's tool calls and the test's own checks, and which
repository and folder each run came from. See Getting started.assay connect attaches Assay to an app you already have, through its
database, a few lines of code, or a proposed test per model call. See Setup.assayCase() in a Jest or Vitest test records the run, and
assay test checks and compares it like a pytest one. See sdk/js.assay test runs any command and reads the events it writes: a recorder
is a few dozen lines. See Any language.assay demo && assay serve
Or with Docker, nothing to install but Docker:
docker run -p 8400:8400 -e ASSAY_AUTO_DEMO=1 ghcr.io/tap222/assay-server # http://localhost:8400
This loads synthetic data and opens the dashboard on the Tests overview: a support agent's new prompt version, compared with the one before it, with every case that regressed and how its tool calls changed. A document pipeline's seven weeks are under Documents, in which a release breaks totals, wrong values escape through auto-approval, and one customer's corrections stop reaching output. A live copy runs at docai-eval.vercel.app.
The dashboard has an Agents view and a Documents view. Each starts with its core tabs, and Settings turns on the rest, one by one, for everyone on the team. See Measures.
Each page puts the summary first: a few numbers and a trend of checks passed over the last runs, then what failed, grouped by case. The rest (failure kinds, transitions, efficiency, every run 50 at a time) is under Details, and loads when you open it.
| Command | What it does |
|---|---|
assay init | Set up local testing: assay.toml and a runnable example (--claude-code adds a Claude Code skill, --hook a pre-push hook that checks every push) |
assay doctor | Check the setup and print the fix for each problem: versions, hook, base branch, dependencies, dashboard |
assay test | Run your tests with recording, check every run, and compare with the baseline (--repeat N, --junit, --failed, --base main to also check for weakened tests) |
assay diff | What behavior changed between two runs |
assay accept | Make the latest run the baseline |
assay ack | Acknowledge a failing check until it gets worse |
assay pr-comment | Post the latest run's summary on the pull request |
assay guard | Assertions a change removed or loosened, against the base branch (--base main); works on any pytest, Jest or Vitest suite |
assay connect | Attach Assay to an existing pipeline |
assay synth | Generate synthetic queries from dimensions you define |
assay golden | Manage the golden set a judge is calibrated against |
assay triage | For each failure category: fix the prompt, add a code check, or add a judge |
assay evals | Audit what each evaluator costs, and which could run as guardrails |
assay redact | Check redaction and replay traces with personal data replaced |
assay serve | Run the API and dashboard |
assay demo | Load a synthetic demo tenant with 7 weeks of runs |
Run assay --help for every command and option.
| Guide | Covers |
|---|---|
| Getting started | Add Assay to your app in four steps: install, two lines in your app, one test, run |
| Testing | pytest --assay, the assay_case fixture, assertions, baselines, flakiness |
| TypeScript and JavaScript | assayCase() in Jest or Vitest, run.expect(), assay test |
| Any language | Go, Java, Ruby, Rust: a small recorder and assay test |
| Behavior diff | What changed between two versions, with a severity |
| Repeated attempts | Chance, too few attempts, or a regression |
| CI | The GitHub Action, GitLab and any other CI, PR comments, reruns, timeouts |
| Security | What the checks catch, and what a PR can't do to the evaluation |
| Agents | Trajectories, plan adherence, the LLM judge, conversations, MCP |
| Document extraction | Every document metric and gate |
| Judge calibration | Golden sets and whether a judge tracks them |
| Setup | Install, connect, go live, deploy |
The full list is in docs/README.md. Where Assay is going, and what's not built yet: docs/roadmap.md.
pip install -e ".[dev]"
pytest
cd sdk/js && npm test    # the TypeScript and JavaScript SDK
CI runs the suite on Linux (Python 3.10 and 3.12), macOS and Windows, and the JavaScript SDK's tests.
Where things live in this repository: docs/layout.md.
Issues and pull requests are welcome at github.com/tap222/assay-evals.
Run pytest (and npm test in sdk/js for a change there) before opening a PR, and update this README in the same PR as any feature change.
MIT. See LICENSE.
Behavioral regression testing for AI apps and agents: pytest plugin, behavior diff, CI gate, and document extraction metrics
See the code
Your prompt change broke 3 cases. Assay tells you which ones, what changed, and whether it's real or noise.
Behavioral regression testing for AI apps and agents in Python and TypeScript: a pytest plugin, a Jest and Vitest helper, and a PR check.
Getting started · Quickstart · 1-minute demo · Features · Document extraction · CI · CLI · Docs
AI output changes when anything around it changes, and a green test suite doesn't tell you what changed or whether it matters. Assay compares every test case with its own last passing run, then answers three questions on every change:
No API key and no account. One line added to a prompt makes an agent skip an approval before a refund, and Assay catches it:
pip install assay-server pytest
git clone https://github.com/tap222/assay-evals && cd assay-evals/examples/prompt-regression
./demo.sh
See examples/prompt-regression for what it shows. The same demo in
JavaScript: examples/prompt-regression-js (./demo.sh there).
New to Assay? Getting started adds it to the app you already have in four steps: install, two lines in your app, one test, run.
pip install assay-server pytest
assay init                 # assay.toml and an example test in tests/ai
pytest --assay tests/ai    # each case against its last passing run; exit 1 on a regression
assay diff                 # what behavior changed, case by case
In Python, a test is a pytest test that takes the assay_case fixture:
from assay_sdk.testing import assert_called, assert_not_called, assert_max_steps

def test_refund(assay_case):
    reply = my_agent("Refund O-17", run=assay_case)
    assert_called(assay_case, "get_order", order_id="O-17")
    assert_not_called(assay_case, "delete_order")
    assert_max_steps(assay_case, 6)
    assert "27.61" in reply
In TypeScript or JavaScript, a Jest, Vitest or node:test test wraps its body in assayCase()
(sdk/js), and assay test runs the command in assay.toml. In a project with a
package.json, assay init writes both for the test runner it finds:
npm install --save-dev assay-evals
pip install assay-server   # the `assay` command
assay init                 # assay.toml and test/ai/support.assay.test.ts (or .js), for Vitest, Jest or node:test
import Anthropic from "@anthropic-ai/sdk";
import { assayCase, instrument } from "assay-evals";

const client = instrument(new Anthropic());   // every model call in a case is recorded (OpenAI, Vercel AI SDK too)

test("refunds a delivered order", () =>
  assayCase(async (run) => {
    run.expect().mustCall("get_order").mustNotCall("delete_order").maxSteps(6);
    const reply = await myAgent(client, "Refund O-17", run);
    expect(reply).toContain("27.61");
  }));
# assay.toml
[test]
command = "npx jest test/ai"
assay test    # each case against its last passing run; exit 1 on a regression
assay diff
assay diff shows what changed and what changed around it:
✓ 39 unchanged
↑ 4 improved
✗ 3 regressed
⚠ 1 flaky

REGRESSIONS

1. refund_flow
   Expected: approval(refund) → refund
   Actual:   refund → approval(refund)
   Changed around it:
     prompt  support@12 → support@13 (+1 line, −0: “Refund right away when the customer is upset.”)
   Severity: HIGH
Exit codes for pytest --assay and assay test: 0 nothing got worse, 1 a regression, 6 inconclusive
(nothing got worse, but some results couldn't be judged, need more attempts to tell, or could be
worse with a judge that disagrees with itself).
| Area | What you get | Docs |
|---|---|---|
| Regression tests | Tests are pytest tests, or Jest and Vitest tests in TypeScript and JavaScript. Each case is compared with its own last passing run: checks, tool calls in order, cost and context. | Testing |
| Behavior diff | What changed between two versions, with the flow before and after and a severity. | Diff |
| Real change or noise | Run each case several times and Assay separates chance (8/8 → 7/8, passes) from too few attempts to tell (inconclusive) from a regression (8/8 → 0/8, fails), corrected for the number of checks. A result that couldn't be judged is kept apart, never scored as 0. | Repeated attempts |
| The AI or the judge | Ask the judge again about the same answer (evaluate(..., rejudge=3)). A case that varies because the judge splits on it is reported as judge unstable, not flaky: more attempts won't settle it, a steadier judge will. | AI or judge |
| Checks can't be loosened | A PR that removes a contract, raises a limit, deletes, skips or filters out the test its change breaks, or removes or loosens an assertion (== 1200 to > 0, toBe to toBeDefined) fails the run until a maintainer accepts it with a label. assay guard checks any repository's pytest, Jest and Vitest tests this way, Assay tests or not. | Security |
| Document extraction | Field, line-item, table, OCR, splitting and confidence metrics, with per-field gates. See below. | Documents |
| Agents and workflows | Trajectories, path and claim contracts, plan adherence, multi-turn conversations, simulated users, tools that fail or whose state changes mid-run (an approval that's stale by the time the agent acts), and rewordings: the same request in other words must get the same behavior. | Agents |
| Judges you can check | Calibration against labels a person gave, bias probes, drift, whether a judge ranks answers or only recognizes the topic, and a trust label on every judged score. | Calibration |
| What caused it | The prompt, model, tools, input and settings that changed next to each regression, or "nothing on your side changed". That includes a tool's definition: a reworded description or a changed argument, from your own tools or an MCP server's tools/list. | Failures |
| Production back to tests | Flagged traces and reviewed conversations become candidate test cases. Before there's traffic, assay synth generates queries from dimensions you define, kept apart from production. | Learning, Synthetic |
Scores each field against its correct value, and gates releases field by field so a single bad field fails the PR even when the average looks fine. Full guide: docs/documents.md.
"1,250.00" matches 1250, "1.234,56 €" is read
correctly, and https://www.acme.com/ is acme.com (tracking parameters ignored, redirect links
named or read through).The GitHub Action runs your tests, compares each one with its last passing run on the default branch, and posts the diff as a PR comment. It fails the PR on a regression.
# .github/workflows/ai-tests.yml
on: { push: { branches: [main] }, pull_request: {} }
permissions: { contents: read, pull-requests: write }
jobs:
  ai-tests:
    runs-on: ubuntu-latest
    steps:
      - uses: actions/checkout@v4
      - uses: actions/setup-python@v5
        with: { python-version: "3.12" }
      - uses: tap222/assay-evals@v1
        with:
          command: pytest --assay tests/ai
For a TypeScript or JavaScript project, install its packages too and run assay test:
      - uses: actions/setup-python@v5
        with: { python-version: "3.12" }
      - uses: actions/setup-node@v4
        with: { node-version: "20" }
      - uses: tap222/assay-evals@v1
        with:
          install: pip install assay-server && npm ci
          command: assay test
Inputs, timeouts, rerunning only what failed, and nightly runs: docs/ci.md.
gen_ai.* spans and OpenInference spans (Arize Phoenix and other instrumentors),
and becomes the regression gate on top of the tracing you already have. See
Sending data.assay init --claude-code adds a skill: after Claude changes a prompt or the
agent, it runs your tests, reads assay diff, and tells you what regressed before you commit.
It never accepts a new baseline on its own. --global installs it for every project, and with
ASSAY_URL and ASSAY_UPLOAD=1 set every run lands in one dashboard, filed by repository,
with an All projects view. The dashboard is one assay serve process with SQLite, no
Docker needed, and it shows each case's tool calls and the test's own checks, and which
repository and folder each run came from. See Getting started.assay connect attaches Assay to an app you already have, through its
database, a few lines of code, or a proposed test per model call. See Setup.assayCase() in a Jest or Vitest test records the run, and
assay test checks and compares it like a pytest one. See sdk/js.assay test runs any command and reads the events it writes: a recorder
is a few dozen lines. See Any language.assay demo && assay serve
Or with Docker, nothing to install but Docker:
docker run -p 8400:8400 -e ASSAY_AUTO_DEMO=1 ghcr.io/tap222/assay-server # http://localhost:8400
This loads synthetic data and opens the dashboard on the Tests overview: a support agent's new prompt version, compared with the one before it, with every case that regressed and how its tool calls changed. A document pipeline's seven weeks are under Documents, in which a release breaks totals, wrong values escape through auto-approval, and one customer's corrections stop reaching output. A live copy runs at docai-eval.vercel.app.
The dashboard has an Agents view and a Documents view. Each starts with its core tabs, and Settings turns on the rest, one by one, for everyone on the team. See Measures.
Each page puts the summary first: a few numbers and a trend of checks passed over the last runs, then what failed, grouped by case. The rest (failure kinds, transitions, efficiency, every run 50 at a time) is under Details, and loads when you open it.
| Command | What it does |
|---|---|
assay init | Set up local testing: assay.toml and a runnable example (--claude-code adds a Claude Code skill, --hook a pre-push hook that checks every push) |
assay doctor | Check the setup and print the fix for each problem: versions, hook, base branch, dependencies, dashboard |
assay test | Run your tests with recording, check every run, and compare with the baseline (--repeat N, --junit, --failed, --base main to also check for weakened tests) |
assay diff | What behavior changed between two runs |
assay accept | Make the latest run the baseline |
assay ack | Acknowledge a failing check until it gets worse |
assay pr-comment | Post the latest run's summary on the pull request |
assay guard | Assertions a change removed or loosened, against the base branch (--base main); works on any pytest, Jest or Vitest suite |
assay connect | Attach Assay to an existing pipeline |
assay synth | Generate synthetic queries from dimensions you define |
assay golden | Manage the golden set a judge is calibrated against |
assay triage | For each failure category: fix the prompt, add a code check, or add a judge |
assay evals | Audit what each evaluator costs, and which could run as guardrails |
assay redact | Check redaction and replay traces with personal data replaced |
assay serve | Run the API and dashboard |
assay demo | Load a synthetic demo tenant with 7 weeks of runs |
Run assay --help for every command and option.
| Guide | Covers |
|---|---|
| Getting started | Add Assay to your app in four steps: install, two lines in your app, one test, run |
| Testing | pytest --assay, the assay_case fixture, assertions, baselines, flakiness |
| TypeScript and JavaScript | assayCase() in Jest or Vitest, run.expect(), assay test |
| Any language | Go, Java, Ruby, Rust: a small recorder and assay test |
| Behavior diff | What changed between two versions, with a severity |
| Repeated attempts | Chance, too few attempts, or a regression |
| CI | The GitHub Action, GitLab and any other CI, PR comments, reruns, timeouts |
| Security | What the checks catch, and what a PR can't do to the evaluation |
| Agents | Trajectories, plan adherence, the LLM judge, conversations, MCP |
| Document extraction | Every document metric and gate |
| Judge calibration | Golden sets and whether a judge tracks them |
| Setup | Install, connect, go live, deploy |
The full list is in docs/README.md. Where Assay is going, and what's not built yet: docs/roadmap.md.
pip install -e ".[dev]"
pytest
cd sdk/js && npm test    # the TypeScript and JavaScript SDK
CI runs the suite on Linux (Python 3.10 and 3.12), macOS and Windows, and the JavaScript SDK's tests.
Where things live in this repository: docs/layout.md.
Issues and pull requests are welcome at github.com/tap222/assay-evals.
Run pytest (and npm test in sdk/js for a change there) before opening a PR, and update this README in the same PR as any feature change.
MIT. See LICENSE.



