
【NeurIPS 2024】The official code of paper "Automated Multi-level Preference for MLLMs"
Python
23
31 commits
updated Sep 26, 2024
README
【NeurIPS 2024】Automated Multi-level Preference for MLLMs


Mengxi Zhang, Wenhao Wu, Yu Lu, Yuxin Song,
Kang Rong, Huanjin Yao, Jianbo Zhang, Fanglong Liu, Yifan Sun, Haocheng Feng, Jingdong Wang
News
- Our AMP is accepted by NeurIPS 2024 as poster presentation!
- [2024/05/29] We relase AMP in arxiv! Our code, MRHal Benchmark, and models are now open source!
Overview
We present an automated Multi-level Preference (AMP) framework for Reinforcement Learning from Human Feedback (RLHF), which generates the high-quality multi-level preference dataset without any human/AI annotators and employs multi-level DPO (MDPO) algorithm. Our AMP achieves SOTA performance across multiple hallucination benchmarks, including MMHal-Bench, MRHal-Bench, LLaVA-Bench, and POPE.
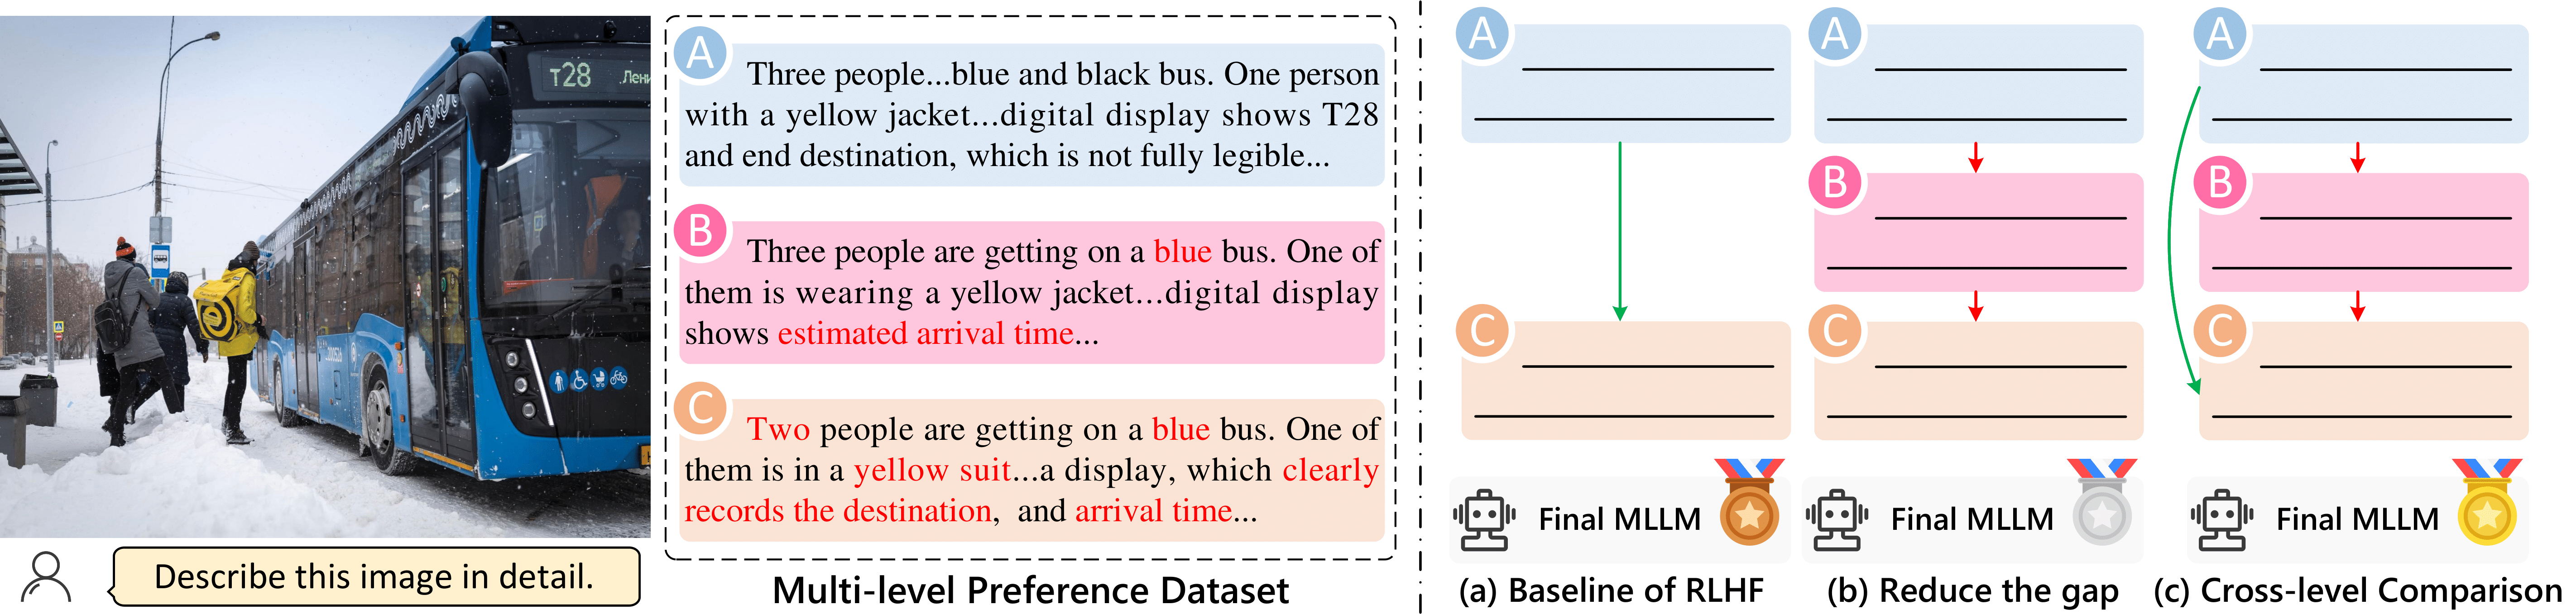
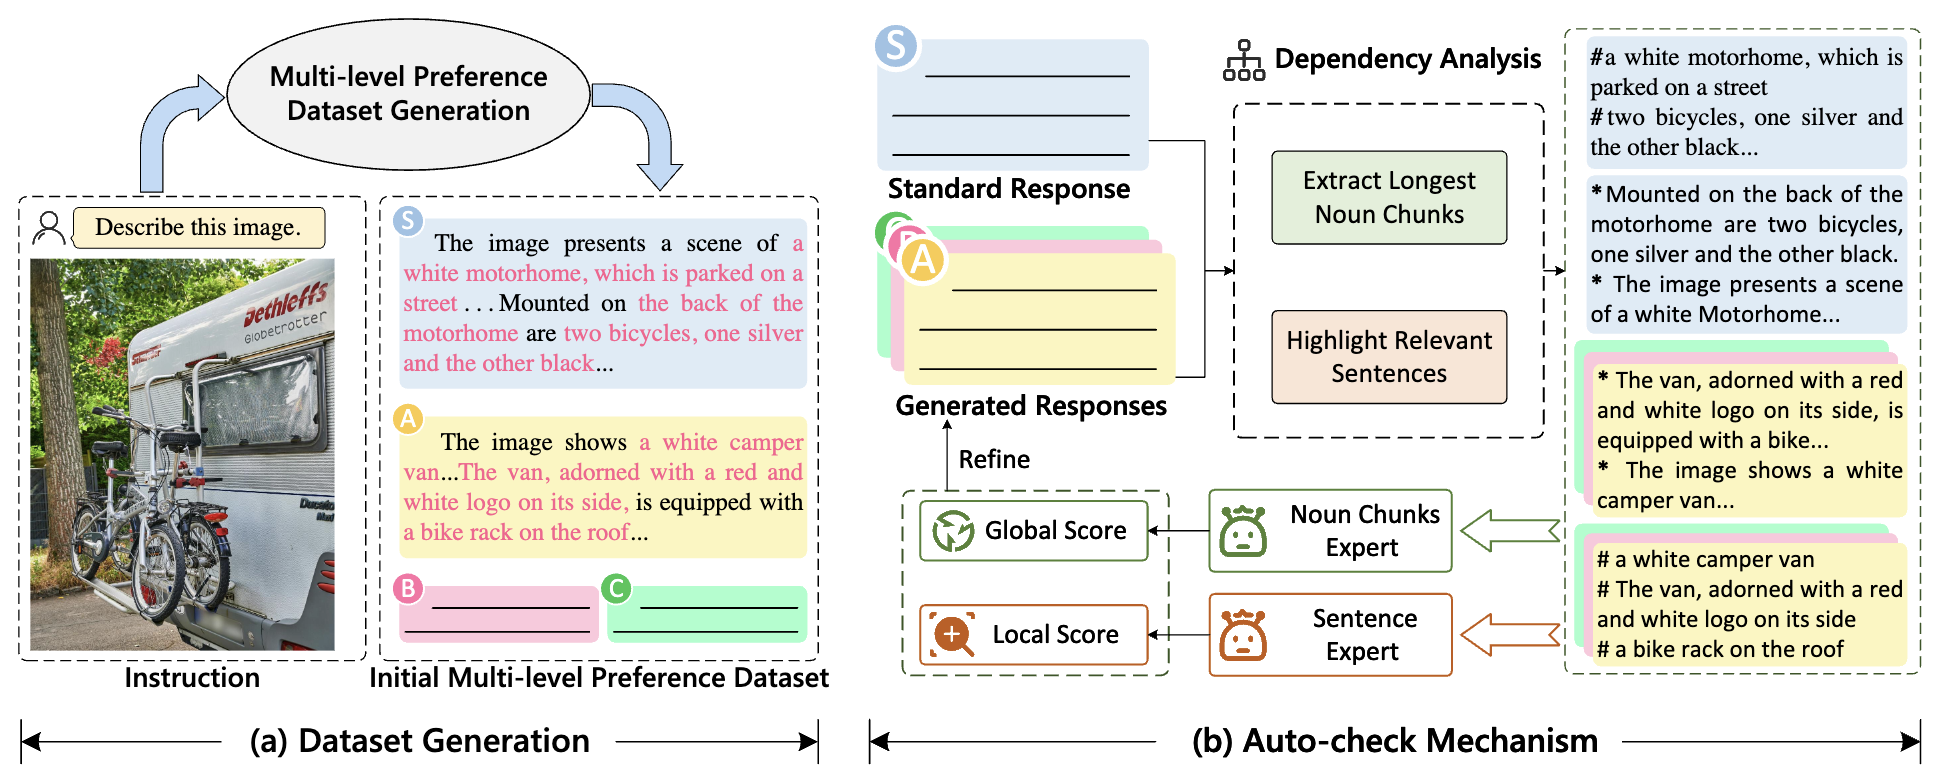
Pipeline for Constructing Human-free Multi-level Preference Dataset
Prepare
- Install some important packages.
conda create -n amp python=3.10 -y
conda activate amp
pip install --upgrade pip
pip install -r requirements.txt
-
Download Base Model
Train
-
Prepare data from [RLHF-V], [SILKIE], [ShareGPT4V].
-
Download Data from this link.
-
Run the following code
sh scripts/13b-v1.5/train_dpo.sh    # 13B
sh scripts/7b-v1.5/train_dpo.sh     # 7B
Evaluation
MMHal-Bench
- Download data from [MMHal-Bench].
- Run the script
sh eval/eval_scripts/eval_mmhal.sh
MRHal-Bench
- Download data from [MRHal-Bench].
- Run the script
sh eval/eval_scripts/eval_mrhal.sh
LLaVA-Bench
- Download data from [LLaVA-Bench] and [COCO] images.
- Run the script
sh eval/eval_scripts/eval_pope.sh
POPE
sh eval/eval_scripts/eval_llavab.sh
Model Zoo
You can also use our trained models for evaluation. We provide the lora adpater of each version.
Dialogue Example
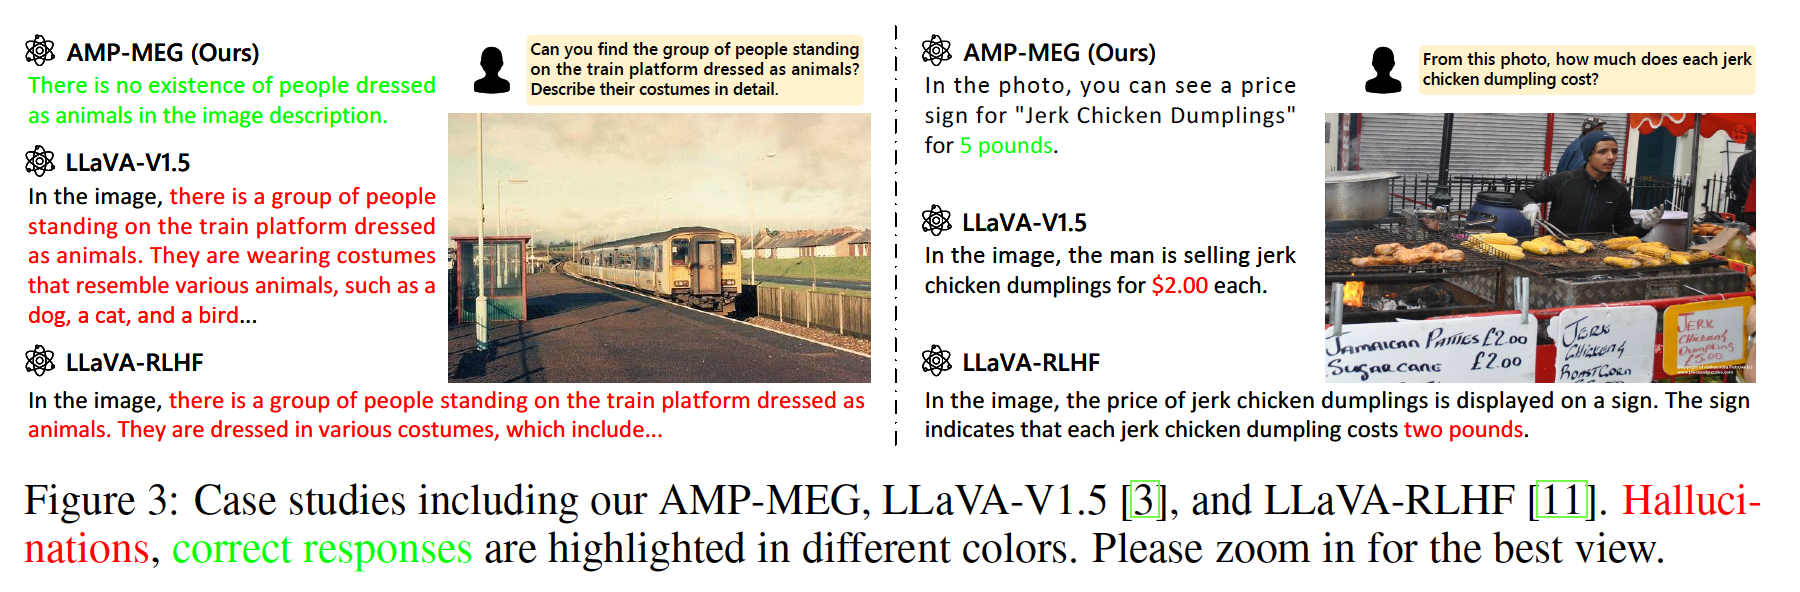
We provide several dialogue examples, with additional results available in the paper.
Citation
If you find this repository is useful, please consider star🌟 this repo and cite🖇️ our paper.
@article{zhang2024amp,
      title={Automated Multi-level Preference for MLLMs},
      author={Zhang, Mengxi and Wu, Wenhao and Yu, Lu and Song, Yuxin and Rong, Kang and Yao, Huanjin and Zhang, Jianbo and Liu, Fanglong and Feng, Haocheng and Sun, Yifan and Wang, Jingdong},
      journal={Advances in Neural Information Processing Systems},
      year={2024}
}
Thanks
Our code is partly based on [LLaVA], [LLaVA-RLHF], and [TRL]. Thanks for their excllent work!


Similar repos


Languages
Python
98.3%
Shell
1.7%
【NeurIPS 2024】The official code of paper "Automated Multi-level Preference for MLLMs"
Python
23
31 commits
updated Sep 26, 2024
README
【NeurIPS 2024】Automated Multi-level Preference for MLLMs
Mengxi Zhang, Wenhao Wu, Yu Lu, Yuxin Song,
Kang Rong, Huanjin Yao, Jianbo Zhang, Fanglong Liu, Yifan Sun, Haocheng Feng, Jingdong Wang
News
- Our AMP is accepted by NeurIPS 2024 as poster presentation!
- [2024/05/29] We relase AMP in arxiv! Our code, MRHal Benchmark, and models are now open source!
Overview
We present an automated Multi-level Preference (AMP) framework for Reinforcement Learning from Human Feedback (RLHF), which generates the high-quality multi-level preference dataset without any human/AI annotators and employs multi-level DPO (MDPO) algorithm. Our AMP achieves SOTA performance across multiple hallucination benchmarks, including MMHal-Bench, MRHal-Bench, LLaVA-Bench, and POPE.
Pipeline for Constructing Human-free Multi-level Preference Dataset
Prepare
- Install some important packages.
conda create -n amp python=3.10 -y
conda activate amp
pip install --upgrade pip
pip install -r requirements.txt
-
Download Base Model
Train
-
Prepare data from [RLHF-V], [SILKIE], [ShareGPT4V].
-
Download Data from this link.
-
Run the following code
sh scripts/13b-v1.5/train_dpo.sh    # 13B
sh scripts/7b-v1.5/train_dpo.sh     # 7B
Evaluation
MMHal-Bench
- Download data from [MMHal-Bench].
- Run the script
sh eval/eval_scripts/eval_mmhal.sh
MRHal-Bench
- Download data from [MRHal-Bench].
- Run the script
sh eval/eval_scripts/eval_mrhal.sh
LLaVA-Bench
- Download data from [LLaVA-Bench] and [COCO] images.
- Run the script
sh eval/eval_scripts/eval_pope.sh
POPE
sh eval/eval_scripts/eval_llavab.sh
Model Zoo
You can also use our trained models for evaluation. We provide the lora adpater of each version.
Dialogue Example
We provide several dialogue examples, with additional results available in the paper.
Citation
If you find this repository is useful, please consider star🌟 this repo and cite🖇️ our paper.
@article{zhang2024amp,
      title={Automated Multi-level Preference for MLLMs},
      author={Zhang, Mengxi and Wu, Wenhao and Yu, Lu and Song, Yuxin and Rong, Kang and Yao, Huanjin and Zhang, Jianbo and Liu, Fanglong and Feng, Haocheng and Sun, Yifan and Wang, Jingdong},
      journal={Advances in Neural Information Processing Systems},
      year={2024}
}
Thanks
Our code is partly based on [LLaVA], [LLaVA-RLHF], and [TRL]. Thanks for their excllent work!
Similar repos
Languages
Python
98.3%
Shell
1.7%