[🚀 ICLR 2026 Oral] NextStep-1: SOTA Autogressive Image Generation with Continuous Tokens. A research project developed by the StepFun’s Multimodal Intelligence team.
Python
694
5 commits
updated Feb 27, 2026


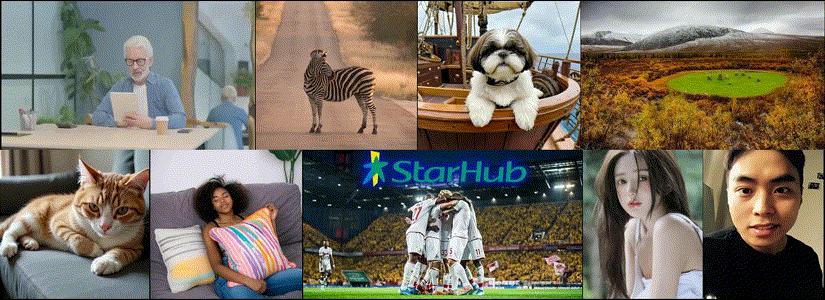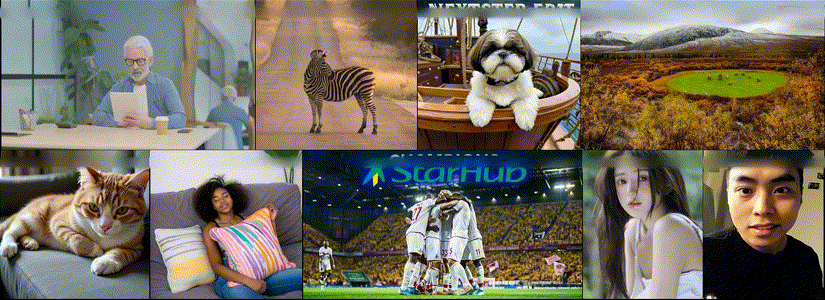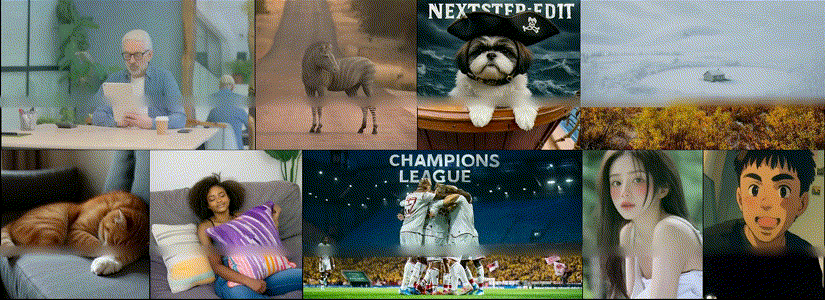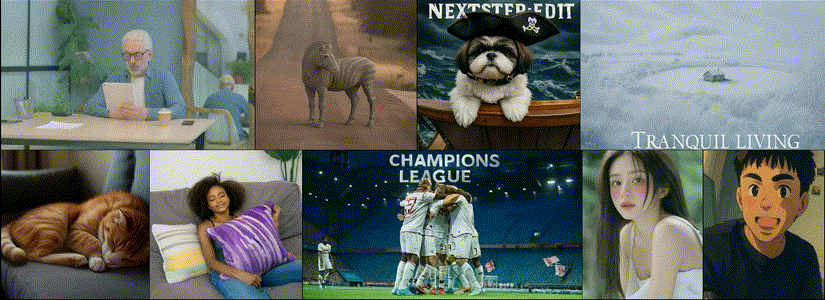
Autoregressive models—generating content step-by-step like reading a sentence—excel in language but struggle with images. Traditionally, they either depend on costly diffusion models or compress images into discrete, lossy tokens via vector quantization (VQ).
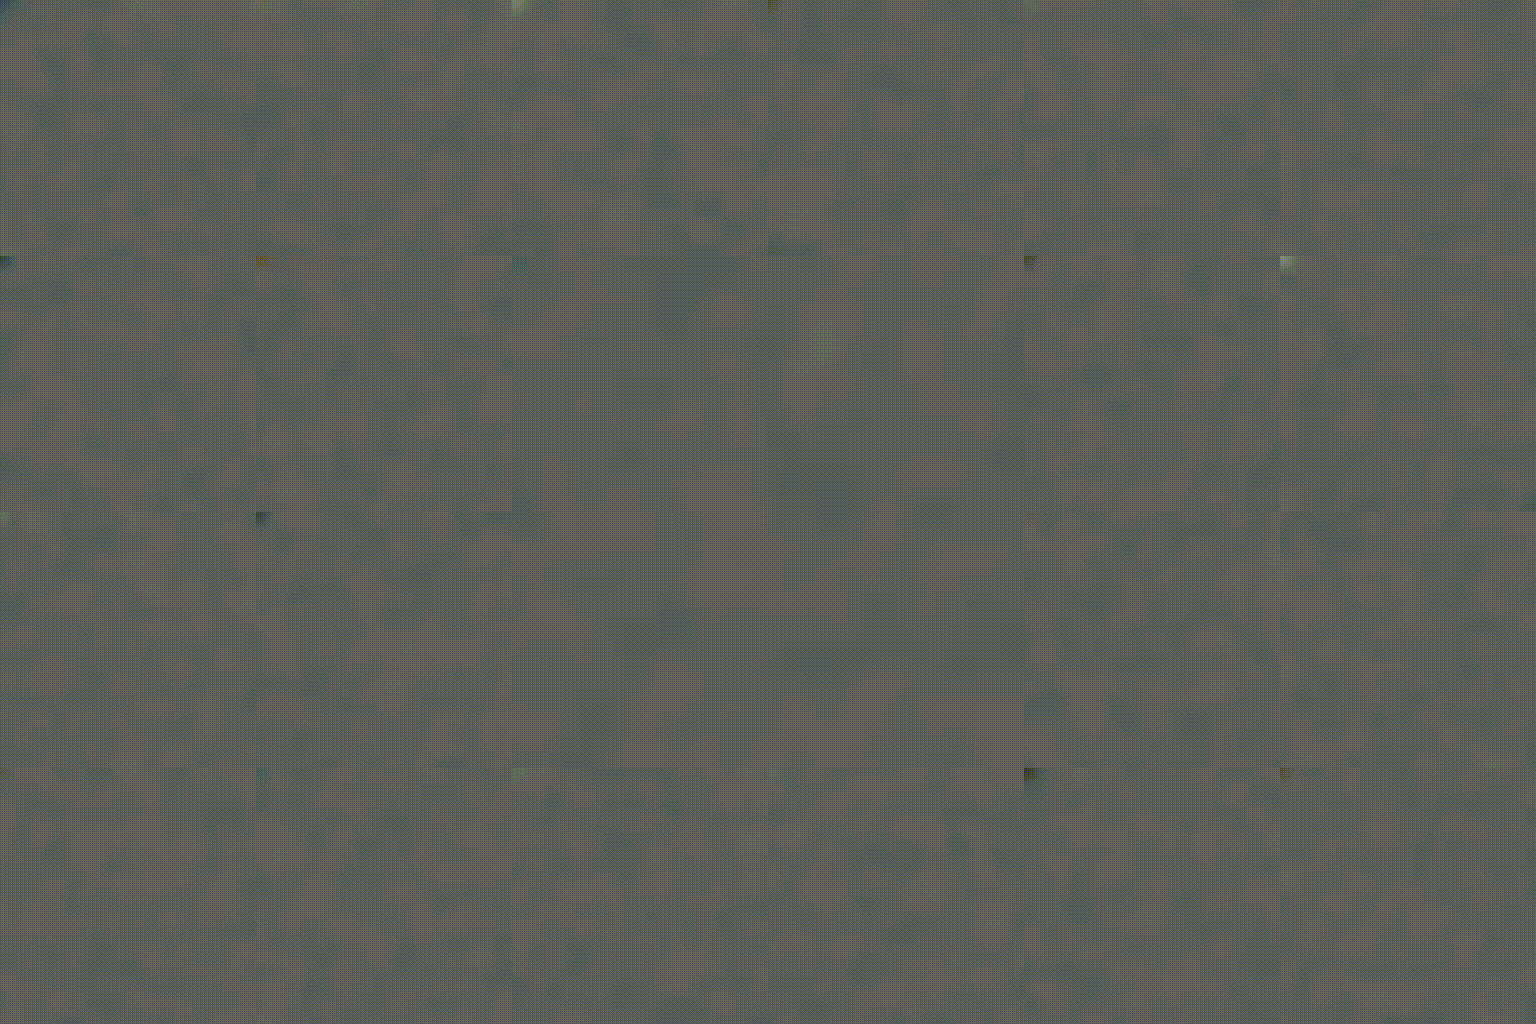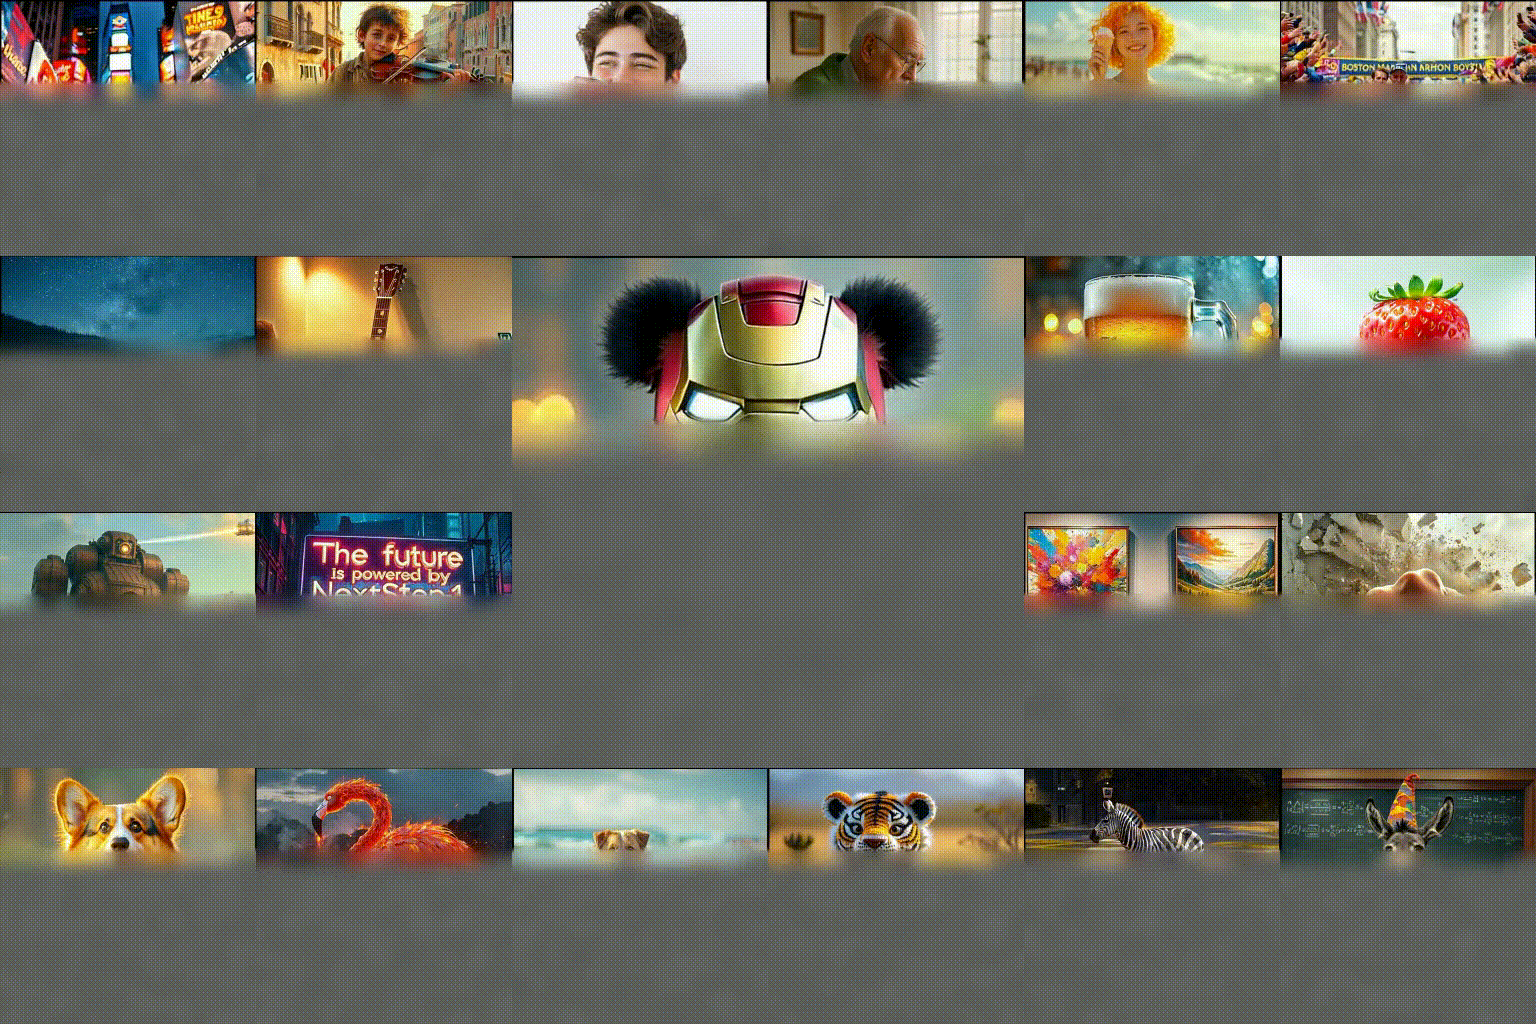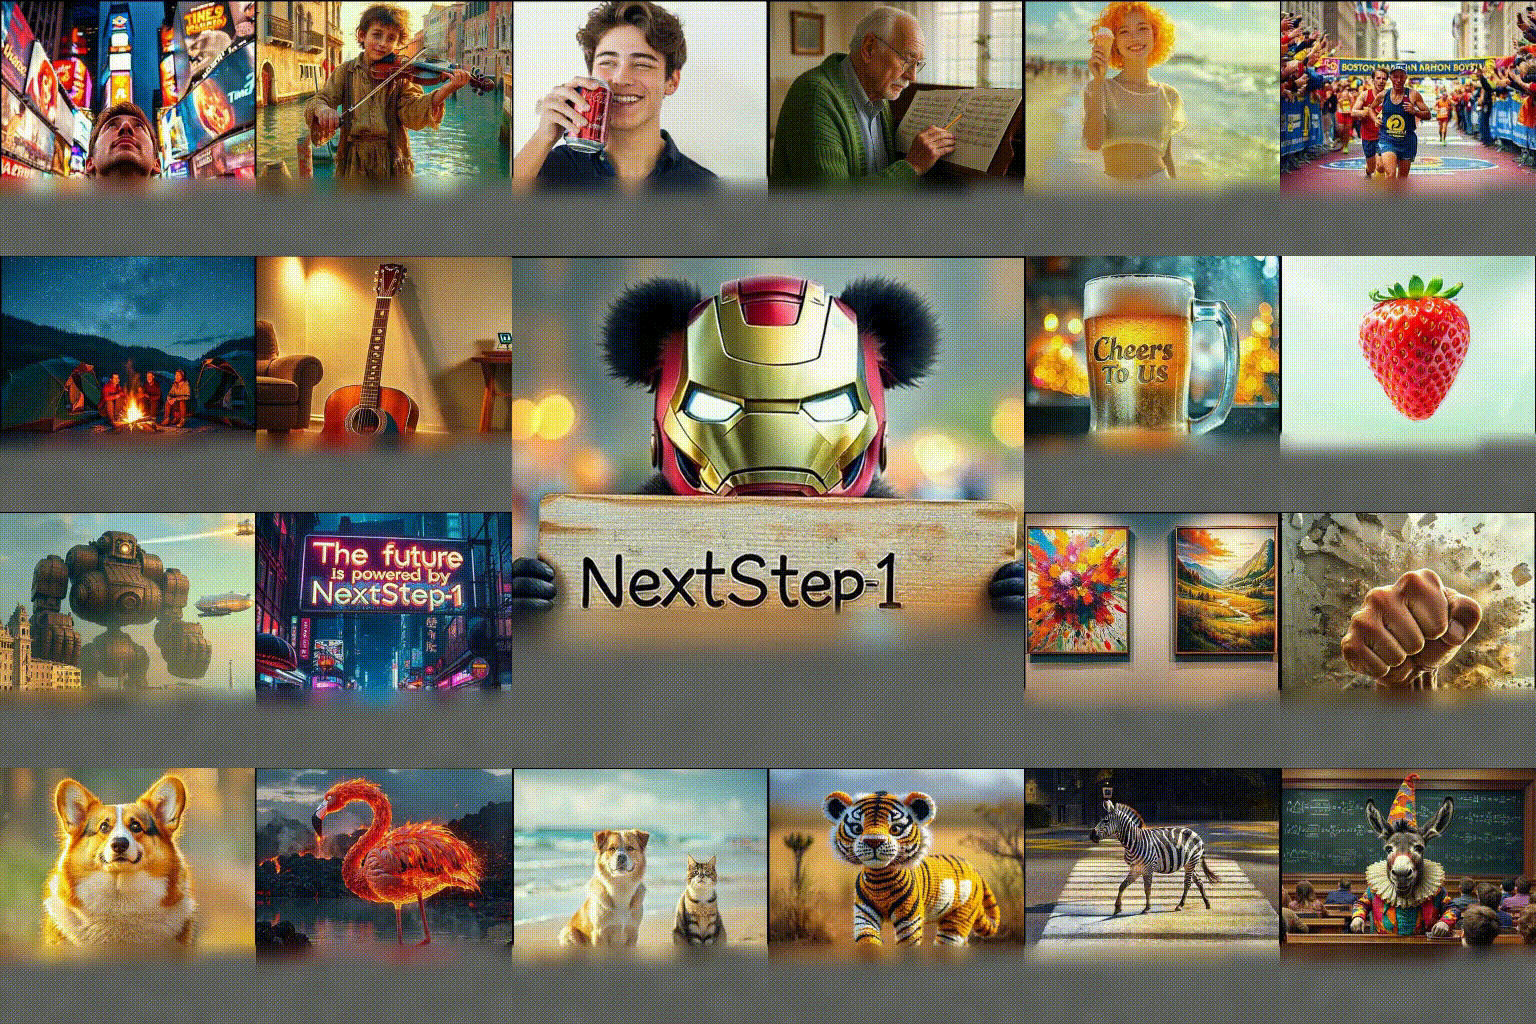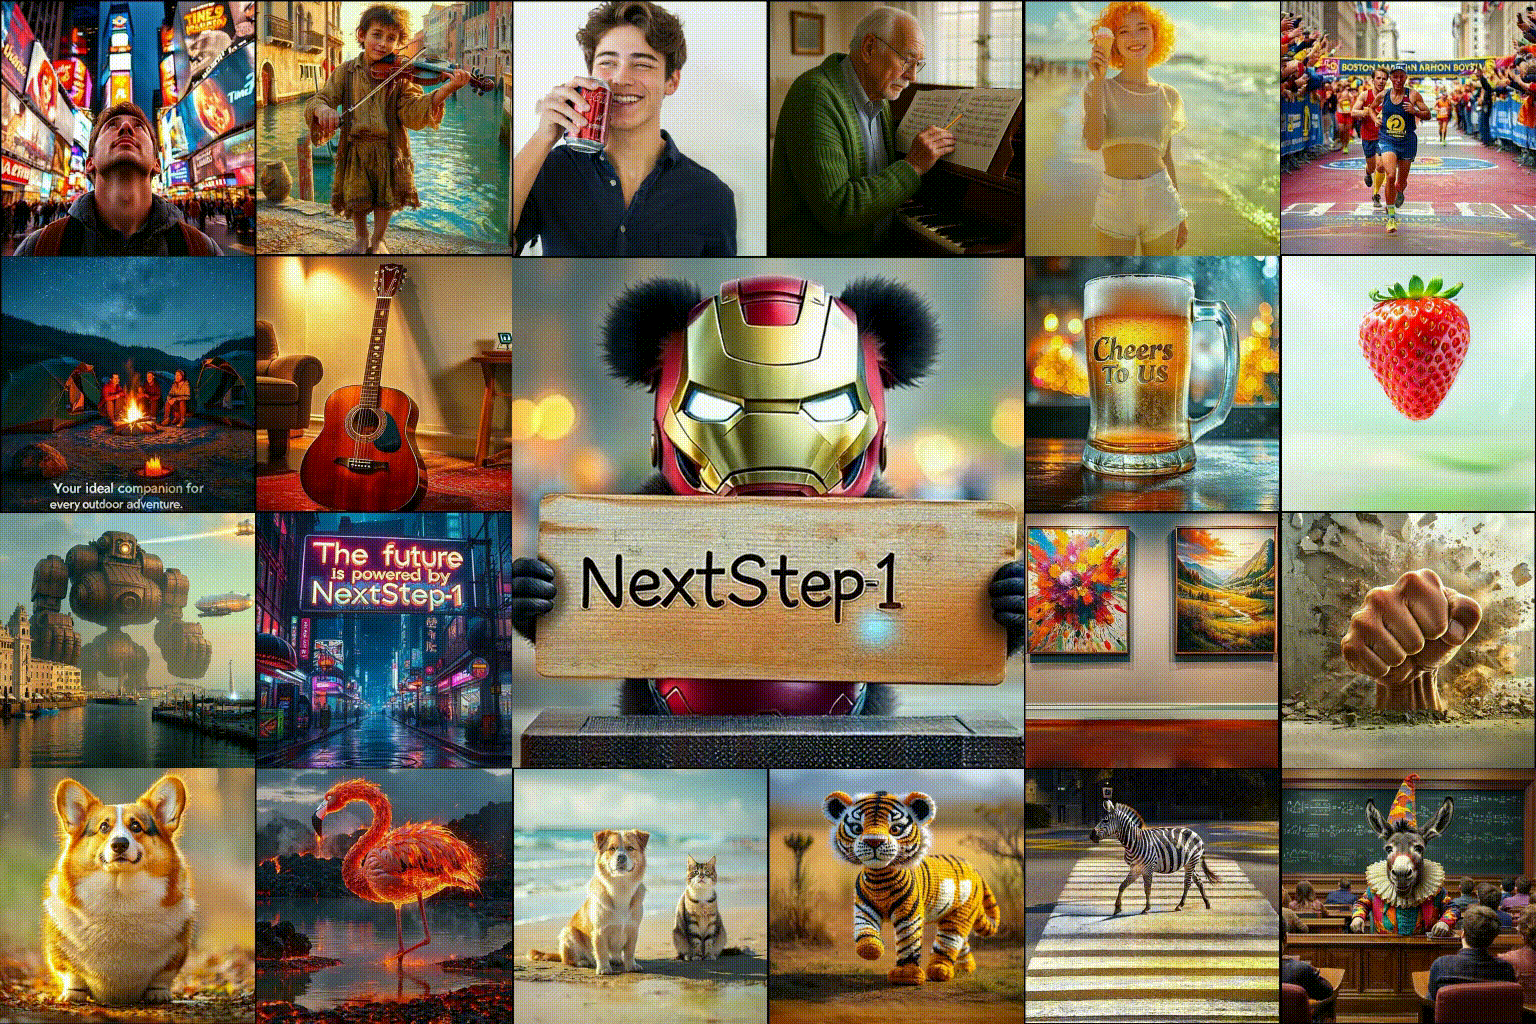
NextStep-1 takes a different path: a 14B-parameter autoregressive model that works directly with continuous image tokens, preserving the full richness of visual data. It models sequences of discrete text tokens and continuous image tokens jointly—using a standard LM head for text and a lightweight 157M-parameter flow matching head for visuals. This unified next-token prediction framework is simple, scalable, and capable of producing stunningly detailed images.
Feb. 25, 2026: vLLM-Omni supports high performance inference of NextStep-1.1. Please check here for details!
Feb. 16, 2026: The training code of NextStep-1 (this repo) and the post-training blogs of NextStep-1.1 (link) have been released. Welcome to discuss and contribute. Happy Chinese New Year!
Feb. 6, 2026: NextStep-1 has been selected as Oral Presentation by ICLR 2026! 🎉🎉🎉
Dec. 24, 2025: 🔥 We release NextStep-1.1, a text-to-image model that substantially elevates output quality through extended training and a Flow-based Reinforcement Learning (RL) post-training paradigm. Feel free to try with checkpoints hosted on our HF repo!
Checkpoints are available on:
Aug. 18, 2025: 👋 We deploy NextStep-1-Large-Edit on HuggingFace Spaces. Feel free to try it out!
Aug. 18, 2025: 👋 We open the WeChat Group. Feel free to join us!
Aug. 14, 2025: 👋 We release the inference code and huggingface model weights of NextStep-1-Large-Pretrain, NextStep-1-Large and NextStep-1-Large-Edit
Aug. 14, 2025: 👋 We have made our technical report available as open source.
git clone https://github.com/stepfun-ai/NextStep-1
cd NextStep-1
conda create -n nextstep python=3.10 -y
conda activate nextstep
⚠️ Note: Pre-installing PyTorch based on your CUDA version is recommended.
pip install uv
uv pip install -e .
☕ Tip: This installation may take a while. Grab a cup of coffee and take a break! ☕
The following CLI tools are available after installation:
smartrun: An intelligent distributed launcher that automatically wraps torchrun parameters.gen_meta: Scans datasets to generate metadata indices (sample counts, checksums, etc.).warmup_data: Pre-warms and caches data indices to significantly speed up training startup.eshow: Inspect or compare experiment configurations.singlegpu_debug / multigpu_debug: Dedicated debug entries for remote attachment.Download models to ./nextstep_models. Please update the corresponding paths in nextstep/model_zoos.py.
bash download_models.sh
☕ Tip: This download may take a while. Grab a cup of coffee and take a break! ☕
The following table lists all available models and their training stages:
| Model | Pre-Training 256px | Pre-Training 512px | Annealing | RL | Visual Diversity | Fine-Tunability | Hugging Face |
|---|---|---|---|---|---|---|---|
| NextStep-1-f8ch16-Tokenizer | ❌ | ❌ | ❌ | ❌ | - | - |  |
| NextStep-1.1-Pretrain-256px | ✅ | ❌ | ❌ | ❌ | High | Easy | |
| NextStep-1.1-Pretrain | ✅ | ✅ | ✅ | ❌ | Medium | Medium | |
| NextStep-1.1 | ✅ | ✅ | ✅ | ✅ | Low | Hard | |
| NextStep-1-Large-Pretrain | ✅ | ✅ | ✅ | ❌ | High | Medium | |
| NextStep-1-Large | ✅ | ✅ | ✅ | ✅ | Low | Hard | |
| NextStep-1-Large-Edit | ✅ | ✅ | ✅ | ✅ | Low | Hard | |
⚠️ Note: The models of NextStep-1 series are from the old version. Their performance is not as good as NextStep-1.1, so we do not recommend using them. Please use NextStep-1.1 series models instead.
💡 Quick Inference: If you want to quickly inference the model, refer to the inference script below.
python3 inference/inference.py
Download datasets to ./nextstep_data.
bash download_datasets.sh
☕ Tip: This download may take a while. Grab a cup of coffee and take a break! ☕
⚠️ Important Note: The datasets provided in
download_datasets.share only example open-source datasets for demonstration purposes. NextStep's actual training utilized approximately 1 billion images from proprietary in-house data sources that cannot be open-sourced. To achieve optimal training results, we strongly recommend collecting and preparing your own large-scale datasets following the data processing guidelines in section 2.3.
💡 Skip this section if you are only using the default datasets from step 2.2. Follow these steps to process custom data:
Convert raw data into the unified WebDataset (Tar) format.
python3 nextstep/data/build_wds.py
Data Specification (generates assets/idx_0000_0000.tar):
key.json: Must contain a caption field using <image_n> placeholders to define the interleaved sequence.key-{i}.png: Images must be named key-0.png, key-1.png, etc., matching the placeholders in the JSON.key must NOT contain dots (.) or hyphens (-). You must use the build_wds.py script to ensure correct indexing. Modify load_data and create_example in the script to fit your specific data source.Calculate sample counts for each Tar file to build training indices.
gen_meta /path/to/your/dataset/root_dir
💡 After completion, update
configs/data/pretrain_data.jsonand the corresponding Python data config files inconfigs/datawith the new data.
Recommended for large-scale training to cache indices locally.
warmup_data /path/to/your/dataset/root_dir --n_jobs 32
Preview data distribution and content in Tar files or configurations.
streamlit run nextstep/service/_preview.py --server.port 8501
Create a .config file in the root directory for experiment tracking. API key can be found at https://wandb.ai/settings
WANDB_MODE=online
WANDB_API_KEY=YOUR_WANDB_API_KEY
WANDB_BASE_URL=https://api.wandb.ai
⚠️ Before training, please carefully review the configurations in the
configsdirectory. You may need to modify the model or output paths in the configuration files.
smartrun)Option 1: Start with the NextStep-1.1-Pretrain-256px model with small training steps (~10K)
smartrun -m configs.nextstep_qwen14b_512px
💡 This command automatically utilizes all available machine resources. If you run this command on a single machine, it is equivalent to:
torchrun --nproc_per_node=8 --nnodes=1 --node_rank=0 -m configs.nextstep_qwen14b_512px
Option 2: Start with the Qwen2.5-14B model with very large training steps (~500K)
smartrun -m configs.nextstep_qwen14b_256px
Override specific parameters during training:
smartrun -m configs.nextstep_qwen14b_512px \
  training.max_steps=1000 \
  training.save_steps=200 \
  data.num_workers=2
View a single configuration:
eshow configs/nextstep_qwen14b_512px.py
Compare differences between two configurations (e.g., 256px vs 512px):
eshow configs/nextstep_qwen14b_256px.py configs/nextstep_qwen14b_512px.py
📌 Tips: Adjust specific parameters, configuration files, and data paths according to your situation. For detailed explanations, see
configs/README.md.
Convert DeepSpeed sharded checkpoints to standard HuggingFace format:
python3 nextstep/deepspeed/zero_to_fp32.py /path/to/your/trained/checkpoint_dir
Basic inference:
python3 inference/inference.py --model_name_or_path /path/to/your/trained/checkpoint_dir
Quick start with default model:
python3 inference/inference.py
For detailed documentation on specific modules, please refer to:
NextStep is licensed under the Apache License 2.0. You can find the license files in the respective GitHub and HuggingFace repositories.
If you find NextStep useful for your research and applications, please consider starring this repository and citing:
@article{nextstepteam2025nextstep1,
  title={NextStep-1: Toward Autoregressive Image Generation with Continuous Tokens at Scale},
  author={NextStep Team and Chunrui Han and Guopeng Li and Jingwei Wu and Quan Sun and Yan Cai and Yuang Peng and Zheng Ge and Deyu Zhou and Haomiao Tang and Hongyu Zhou and Kenkun Liu and Ailin Huang and Bin Wang and Changxin Miao and Deshan Sun and En Yu and Fukun Yin and Gang Yu and Hao Nie and Haoran Lv and Hanpeng Hu and Jia Wang and Jian Zhou and Jianjian Sun and Kaijun Tan and Kang An and Kangheng Lin and Liang Zhao and Mei Chen and Peng Xing and Rui Wang and Shiyu Liu and Shutao Xia and Tianhao You and Wei Ji and Xianfang Zeng and Xin Han and Xuelin Zhang and Yana Wei and Yanming Xu and Yimin Jiang and Yingming Wang and Yu Zhou and Yucheng Han and Ziyang Meng and Binxing Jiao and Daxin Jiang and Xiangyu Zhang and Yibo Zhu},
  journal={arXiv preprint arXiv:2508.10711},
  year={2025}
}
(top 24 of 27)
407 followers · starred Aug 2025
296 followers · starred Aug 2025
1,104 followers · starred Apr 2026
81 followers · starred Feb 2026
[🚀 ICLR 2026 Oral] NextStep-1: SOTA Autogressive Image Generation with Continuous Tokens. A research project developed by the StepFun’s Multimodal Intelligence team.
Python
694
5 commits
updated Feb 27, 2026
Autoregressive models—generating content step-by-step like reading a sentence—excel in language but struggle with images. Traditionally, they either depend on costly diffusion models or compress images into discrete, lossy tokens via vector quantization (VQ).
NextStep-1 takes a different path: a 14B-parameter autoregressive model that works directly with continuous image tokens, preserving the full richness of visual data. It models sequences of discrete text tokens and continuous image tokens jointly—using a standard LM head for text and a lightweight 157M-parameter flow matching head for visuals. This unified next-token prediction framework is simple, scalable, and capable of producing stunningly detailed images.
Feb. 25, 2026: vLLM-Omni supports high performance inference of NextStep-1.1. Please check here for details!
Feb. 16, 2026: The training code of NextStep-1 (this repo) and the post-training blogs of NextStep-1.1 (link) have been released. Welcome to discuss and contribute. Happy Chinese New Year!
Feb. 6, 2026: NextStep-1 has been selected as Oral Presentation by ICLR 2026! 🎉🎉🎉
Dec. 24, 2025: 🔥 We release NextStep-1.1, a text-to-image model that substantially elevates output quality through extended training and a Flow-based Reinforcement Learning (RL) post-training paradigm. Feel free to try with checkpoints hosted on our HF repo!
Checkpoints are available on:
Aug. 18, 2025: 👋 We deploy NextStep-1-Large-Edit on HuggingFace Spaces. Feel free to try it out!
Aug. 18, 2025: 👋 We open the WeChat Group. Feel free to join us!
Aug. 14, 2025: 👋 We release the inference code and huggingface model weights of NextStep-1-Large-Pretrain, NextStep-1-Large and NextStep-1-Large-Edit
Aug. 14, 2025: 👋 We have made our technical report available as open source.
git clone https://github.com/stepfun-ai/NextStep-1
cd NextStep-1
conda create -n nextstep python=3.10 -y
conda activate nextstep
⚠️ Note: Pre-installing PyTorch based on your CUDA version is recommended.
pip install uv
uv pip install -e .
☕ Tip: This installation may take a while. Grab a cup of coffee and take a break! ☕
The following CLI tools are available after installation:
smartrun: An intelligent distributed launcher that automatically wraps torchrun parameters.gen_meta: Scans datasets to generate metadata indices (sample counts, checksums, etc.).warmup_data: Pre-warms and caches data indices to significantly speed up training startup.eshow: Inspect or compare experiment configurations.singlegpu_debug / multigpu_debug: Dedicated debug entries for remote attachment.Download models to ./nextstep_models. Please update the corresponding paths in nextstep/model_zoos.py.
bash download_models.sh
☕ Tip: This download may take a while. Grab a cup of coffee and take a break! ☕
The following table lists all available models and their training stages:
| Model | Pre-Training 256px | Pre-Training 512px | Annealing | RL | Visual Diversity | Fine-Tunability | Hugging Face |
|---|---|---|---|---|---|---|---|
| NextStep-1-f8ch16-Tokenizer | ❌ | ❌ | ❌ | ❌ | - | - | |
| NextStep-1.1-Pretrain-256px | ✅ | ❌ | ❌ | ❌ | High | Easy | |
| NextStep-1.1-Pretrain | ✅ | ✅ | ✅ | ❌ | Medium | Medium | |
| NextStep-1.1 | ✅ | ✅ | ✅ | ✅ | Low | Hard | |
| NextStep-1-Large-Pretrain | ✅ | ✅ | ✅ | ❌ | High | Medium | |
| NextStep-1-Large | ✅ | ✅ | ✅ | ✅ | Low | Hard | |
| NextStep-1-Large-Edit | ✅ | ✅ | ✅ | ✅ | Low | Hard | |
⚠️ Note: The models of NextStep-1 series are from the old version. Their performance is not as good as NextStep-1.1, so we do not recommend using them. Please use NextStep-1.1 series models instead.
💡 Quick Inference: If you want to quickly inference the model, refer to the inference script below.
python3 inference/inference.py
Download datasets to ./nextstep_data.
bash download_datasets.sh
☕ Tip: This download may take a while. Grab a cup of coffee and take a break! ☕
⚠️ Important Note: The datasets provided in
download_datasets.share only example open-source datasets for demonstration purposes. NextStep's actual training utilized approximately 1 billion images from proprietary in-house data sources that cannot be open-sourced. To achieve optimal training results, we strongly recommend collecting and preparing your own large-scale datasets following the data processing guidelines in section 2.3.
💡 Skip this section if you are only using the default datasets from step 2.2. Follow these steps to process custom data:
Convert raw data into the unified WebDataset (Tar) format.
python3 nextstep/data/build_wds.py
Data Specification (generates assets/idx_0000_0000.tar):
key.json: Must contain a caption field using <image_n> placeholders to define the interleaved sequence.key-{i}.png: Images must be named key-0.png, key-1.png, etc., matching the placeholders in the JSON.key must NOT contain dots (.) or hyphens (-). You must use the build_wds.py script to ensure correct indexing. Modify load_data and create_example in the script to fit your specific data source.Calculate sample counts for each Tar file to build training indices.
gen_meta /path/to/your/dataset/root_dir
💡 After completion, update
configs/data/pretrain_data.jsonand the corresponding Python data config files inconfigs/datawith the new data.
Recommended for large-scale training to cache indices locally.
warmup_data /path/to/your/dataset/root_dir --n_jobs 32
Preview data distribution and content in Tar files or configurations.
streamlit run nextstep/service/_preview.py --server.port 8501
Create a .config file in the root directory for experiment tracking. API key can be found at https://wandb.ai/settings
WANDB_MODE=online
WANDB_API_KEY=YOUR_WANDB_API_KEY
WANDB_BASE_URL=https://api.wandb.ai
⚠️ Before training, please carefully review the configurations in the
configsdirectory. You may need to modify the model or output paths in the configuration files.
smartrun)Option 1: Start with the NextStep-1.1-Pretrain-256px model with small training steps (~10K)
smartrun -m configs.nextstep_qwen14b_512px
💡 This command automatically utilizes all available machine resources. If you run this command on a single machine, it is equivalent to:
torchrun --nproc_per_node=8 --nnodes=1 --node_rank=0 -m configs.nextstep_qwen14b_512px
Option 2: Start with the Qwen2.5-14B model with very large training steps (~500K)
smartrun -m configs.nextstep_qwen14b_256px
Override specific parameters during training:
smartrun -m configs.nextstep_qwen14b_512px \
  training.max_steps=1000 \
  training.save_steps=200 \
  data.num_workers=2
View a single configuration:
eshow configs/nextstep_qwen14b_512px.py
Compare differences between two configurations (e.g., 256px vs 512px):
eshow configs/nextstep_qwen14b_256px.py configs/nextstep_qwen14b_512px.py
📌 Tips: Adjust specific parameters, configuration files, and data paths according to your situation. For detailed explanations, see
configs/README.md.
Convert DeepSpeed sharded checkpoints to standard HuggingFace format:
python3 nextstep/deepspeed/zero_to_fp32.py /path/to/your/trained/checkpoint_dir
Basic inference:
python3 inference/inference.py --model_name_or_path /path/to/your/trained/checkpoint_dir
Quick start with default model:
python3 inference/inference.py
For detailed documentation on specific modules, please refer to:
NextStep is licensed under the Apache License 2.0. You can find the license files in the respective GitHub and HuggingFace repositories.
If you find NextStep useful for your research and applications, please consider starring this repository and citing:
@article{nextstepteam2025nextstep1,
  title={NextStep-1: Toward Autoregressive Image Generation with Continuous Tokens at Scale},
  author={NextStep Team and Chunrui Han and Guopeng Li and Jingwei Wu and Quan Sun and Yan Cai and Yuang Peng and Zheng Ge and Deyu Zhou and Haomiao Tang and Hongyu Zhou and Kenkun Liu and Ailin Huang and Bin Wang and Changxin Miao and Deshan Sun and En Yu and Fukun Yin and Gang Yu and Hao Nie and Haoran Lv and Hanpeng Hu and Jia Wang and Jian Zhou and Jianjian Sun and Kaijun Tan and Kang An and Kangheng Lin and Liang Zhao and Mei Chen and Peng Xing and Rui Wang and Shiyu Liu and Shutao Xia and Tianhao You and Wei Ji and Xianfang Zeng and Xin Han and Xuelin Zhang and Yana Wei and Yanming Xu and Yimin Jiang and Yingming Wang and Yu Zhou and Yucheng Han and Ziyang Meng and Binxing Jiao and Daxin Jiang and Xiangyu Zhang and Yibo Zhu},
  journal={arXiv preprint arXiv:2508.10711},
  year={2025}
}
(top 24 of 27)
407 followers · starred Aug 2025
296 followers · starred Aug 2025
1,104 followers · starred Apr 2026
81 followers · starred Feb 2026



