
Semantic search over videos using Gemini Embedding 2 or Qwen3-VL.
Python
4,522
181 commits
updated Sep 25, 2026
README
SentrySearch
Semantic search over video footage. Type what you're looking for, get a trimmed clip back.
[!IMPORTANT] Official source: github.com/ssrajadh/sentrysearch is the only official home of SentrySearch. Other sites republishing or mirroring this project are not affiliated with or endorsed by the maintainer, always download from this repository.
Languages: English · 简体中文
New: MLX backend for Apple Silicon: runs the local 2B model twice as fast in under half the memory, at the same accuracy
Table of Contents
- How it works
- Getting Started
- Usage
- How is this possible?
- Cost
- Known Warnings (harmless)
- Limitations & Future Work
- Compatibility
- Requirements
How it works
SentrySearch splits your videos into overlapping chunks, embeds each chunk as video using Google's Gemini Embedding API, Alibaba DashScope (qwen-cloud), or a local Qwen3-VL model, and stores the vectors in a local ChromaDB database. When you search, your text query (or image, see search by image) is embedded into the same vector space and matched against the stored video embeddings. The top match is automatically trimmed from the original file and saved as a clip.
Getting Started
- Install uv (if you don't have it):
macOS/Linux:
curl -LsSf https://astral.sh/uv/install.sh | sh
Windows:
powershell -c "irm https://astral.sh/uv/install.ps1 | iex"
- Clone and install:
git clone https://github.com/ssrajadh/sentrysearch.git
cd sentrysearch
uv tool install .
Requires Python 3.11 or 3.12 (PyTorch wheels don't yet support 3.13+). If your default Python is newer, install a managed 3.12 and pin the tool install:
uv python install 3.12
uv tool install --python 3.12 .
- Set up your API key (or use a local model instead) — only needed for the default Gemini backend; skip if you use
--backend local,--backend mlx, or--backend qwen-cloudwithDASHSCOPE_API_KEYin.env.
sentrysearch init
This prompts for your Gemini API key, writes it to .env, and validates it with a test embedding.
- Index your footage:
sentrysearch index /path/to/footage
- Search:
sentrysearch search "red truck running a stop sign"
ffmpeg is required for video chunking and trimming. If you don't have it system-wide, the bundled imageio-ffmpeg is used automatically.
Manual setup: If you prefer not to use
sentrysearch init, you can copy.env.exampleto.envand add your key from aistudio.google.com/apikey manually.
Usage
Init
$ sentrysearch init
Enter your Gemini API key (get one at https://aistudio.google.com/apikey): ****
Validating API key...
Setup complete. You're ready to go — run `sentrysearch index <directory>` to get started.
If a key is already configured, you'll be asked whether to overwrite it.
Tip: Set a spending limit at aistudio.google.com/billing to prevent accidental overspending.
Index footage
$ sentrysearch index /path/to/video/footage
Indexing file 1/3: front_2024-01-15_14-30.mp4 [chunk 1/4]
Indexing file 1/3: front_2024-01-15_14-30.mp4 [chunk 2/4]
...
Indexed 12 new chunks from 3 files. Total: 12 chunks from 3 files.
Options:
--chunk-duration 30— seconds per chunk--overlap 5— overlap between chunks--no-preprocess— skip downscaling/frame rate reduction (send raw chunks)--target-resolution 480— target height in pixels for preprocessing--target-fps 5— target frame rate for preprocessing--no-skip-still— embed all chunks, even ones with no visual change--rpm 10— cap requests per minute to the cloud API (details below)--backend local— use a local model instead of Gemini (details below)--backend mlx— use the local model through MLX on Apple Silicon, faster and lighter thanlocal(details below)
Search
$ sentrysearch search "red truck running a stop sign"
  #1 [0.87] front_2024-01-15_14-30.mp4 @ 02:15-02:45
  #2 [0.74] left_2024-01-15_14-30.mp4 @ 02:10-02:40
  #3 [0.61] front_2024-01-20_09-15.mp4 @ 00:30-01:00

Saved clip: ./match_front_2024-01-15_14-30_02m15s-02m45s.mp4
If the best result's similarity score is below the confidence threshold (default 0.41, or 0.35 on --backend mlx), you'll be prompted before trimming:
No confident match found (best score: 0.28). Show results anyway? [y/N]:
With --no-trim, low-confidence results are shown with a note instead of a prompt.
Options: --results N, --output-dir DIR, --no-trim to skip auto-trimming, --threshold 0.5 to adjust the confidence cutoff, --save-top N to save the top N clips instead of just the best match, --dedupe to set how similar a result can be to a higher-ranked pick before it's dropped (on by default, so overlapping chunks of the same moment don't fill the list), and --rerank to ask a VLM to re-rank the returned candidates before trimming. Backend and model are auto-detected from the index — pass --backend or --model only to override.
# Save top 5 clips, dropping only near-identical chunks
sentrysearch search "red truck" --save-top 5 --dedupe 0.95

# Re-rank the top 10 embedding matches with a VLM before trimming
sentrysearch search "pedestrian crossing behind the car" --rerank --results 10
The --dedupe value is a cosine similarity ceiling (0–1). Any result whose similarity to an already-kept higher-ranked result exceeds this value is dropped. Lower values are stricter: 0.8 requires results to be very distinct, 0.95 only removes near-identical chunks. The default is 0.9; pass --dedupe 1 to keep every result. Search fetches extra candidates when deduping, so you still get the number of results you asked for.
--rerank extracts each returned candidate clip, sends it to a VLM with the query, and sorts likely visual matches ahead of embedding-only results. Gemini and qwen-cloud searches use Gemini 2.5 Flash for reranking; local searches use a local Qwen3-VL Instruct reranker. If reranking cannot run or a candidate cannot be scored, SentrySearch keeps the embedding-ranked results instead of failing the search.
Search by image
Use a reference image as the query — useful for "find clips that look like this" when describing the scene in words is awkward (a screenshot of a specific car, a reference frame from another video, etc.).
$ sentrysearch img ~/Downloads/image.jpg
  #1 [0.72] 2026-03-12_10-44-17-left_repeater.mp4 @ 00:00-00:30
  #2 [0.69] 2026-03-12_10-44-17-left_repeater.mp4 @ 00:25-00:55
  #3 [0.67] 2026-02-12_20-02-15-front.mp4 @ 00:00-00:18

Saved clip: ./match_2026-03-12_10-44-17-left_repeater_00m00s-00m30s.mp4
The image is embedded into the same vector space as the indexed video chunks and ranked by cosine similarity. Image search supports --results, --threshold, --save-top, --dedupe, --overlay, --no-trim, --backend, and --model.
Supported formats: JPG, PNG, WEBP, GIF, HEIC/HEIF on the Gemini backend; the local backend additionally accepts anything PIL can decode (BMP, TIFF, etc.).
Note: Image search returns visually similar matches, not necessarily the same object. A red sedan query may surface other red sedans of similar shape — calibrate expectations accordingly.
Highlights
Don't know what to search for? sentrysearch highlights ranks the most anomalous clips in your index — chunks whose embeddings sit far from everything else — and trims them automatically. Good for skimming a fresh dump of footage.
$ sentrysearch highlights -n 3
  #1 [0.165] 2026-02-12_20-02-15-back.mp4 @ 00:00-00:18
  #2 [0.163] 2026-02-12_20-02-15-right_repeater.mp4 @ 00:00-00:18
  #3 [0.149] 2026-02-12_20-02-15-front.mp4 @ 00:00-00:18
...
Scoring methods (--method):
knn(default) — mean cosine distance to a chunk's k nearest neighbors. Robust; surfaces clips with no near-twins.centroid— distance from the index mean. Cheapest, biased toward whatever's underrepresented.lof— Local Outlier Factor. Best when the index has multiple distinct "normal" modes (day vs. night vs. garage).
Refinement options:
--against "<query>"— score anomaly relative to a query. With--against-mode within(default), ranks anomalies among the top matches of the query ("the weird pedestrians in pedestrian clips"). With--against-mode global, finds clips that match the query but are unlike the rest of the index ("rare events of this type").--dedupe 0.9— drop results too similar to a higher-ranked pick (default 0.9 cosine similarity). Prevents near-duplicate frames from filling the list.--exclude-baseline— drop the half of the index nearest the centroid before scoring. Useful when the index is dominated by repetitive "boring" footage.-k, --neighbors 10— k forknn/lof.--no-trim— print the ranking without writing clips.
Caveat: Statistically anomalous ≠ interesting. Sensor glitches, lens flare, night frames in a mostly-daytime index, and the lone garage clip all rank high. Use
--exclude-baselineand--dedupeto filter the noise, or--againstto constrain by topic.
Qwen Cloud (Alibaba DashScope)
Use the optional qwen-cloud backend for DashScope / Model Studio multimodal embeddings (default model qwen3-vl-embedding, overridable with --dashscope-model or DASHSCOPE_EMBEDDING_MODEL):
uv tool install ".[qwen-cloud]"
export DASHSCOPE_API_KEY=...
sentrysearch index /path/to/footage --backend qwen-cloud
sentrysearch search "your query" --backend qwen-cloud
Video uploads: local chunk files are sent to DashScope-managed temporary OSS by the official Python SDK before the API consumes them (the HTTP API expects a URL; the SDK handles upload for you).
Local Backend (no API key needed)
Index and search using a local Qwen3-VL-Embedding model instead of the Gemini API. Free, private, and runs entirely on your machine. For the best search quality, use the Gemini backend — the local 8B model is a solid alternative when you need offline/private search, and the 2B model is a fallback when hardware can't support 8B.
The model is auto-detected from your hardware — qwen8b for NVIDIA GPUs and Macs with 24 GB+ RAM, qwen2b for smaller Macs and CPU-only systems. You can override with --model qwen2b or --model qwen8b. Pick an install based on your hardware:
| Hardware | Install command | Auto-detected model | Notes |
|---|---|---|---|
| Apple Silicon, 24 GB+ RAM | uv tool install ".[local]" | qwen8b | Full float16 via MPS |
| Apple Silicon, 16 GB RAM | uv tool install ".[local]" | qwen2b | 8B won't fit; 2B uses ~6 GB. The MLX backend runs the same 2B in ~1.8 GB |
| Apple Silicon, 8 GB RAM | uv tool install ".[local]" | qwen2b | Tight — may swap under load; Gemini API recommended instead. The MLX backend needs far less memory but hasn't been tested on 8 GB |
| NVIDIA, 18 GB+ VRAM | uv tool install ".[local]" | qwen8b | Full bf16 precision (CUDA wheels pulled automatically on Linux/Windows) |
| NVIDIA, 8–16 GB VRAM | uv tool install ".[local-quantized]" | qwen8b | 4-bit quantization (~6–8 GB) |
Won't work well: Intel Macs and machines without a dedicated GPU. These fall back to CPU with float32 — too slow and memory-hungry for practical use. Use the Gemini API backend (the default) instead.
Not sure? On a Mac with less than 24 GB, use the MLX backend (
".[mlx]"): same accuracy as".[local]"at half the time and memory, though it doesn't support--rerankyet. On a larger Mac, use".[local]". On NVIDIA, use".[local-quantized]"— 4-bit quantization works on the widest range of NVIDIA hardware with minimal quality loss. (bitsandbytes requires CUDA and does not work on Mac/MPS.)
Python version: PyTorch wheels lag behind new Python releases, so the local backend requires Python 3.11 or 3.12. If your default Python is 3.13+, install a managed 3.12 and pin the tool install to it:
uv python install 3.12
uv tool install --python 3.12 ".[local]"
Mac prerequisite: Install system FFmpeg (the local model's video processor requires it — the Gemini backend uses a bundled ffmpeg instead):
brew install ffmpeg
Index with --backend local and search — no extra flags needed:
sentrysearch index /path/to/footage --backend local
sentrysearch search "car running a red light"
The search command auto-detects the backend and model from whatever you indexed with. You can also use --model as a shorthand — it implies --backend local:
sentrysearch index /path/to/footage --model qwen2b   # same as --backend local --model qwen2b
sentrysearch search "car running a red light"          # auto-detects local/qwen2b from index
Options:
--model qwen2b— smaller model, lower quality but only ~6 GB memory (also accepts full HuggingFace IDs)--quantize/--no-quantize— force 4-bit quantization on or off (default: auto-detect based on whether bitsandbytes is installed)
Notes:
- First run downloads the model (~16 GB for 8B, ~4 GB for 2B).
- Local
--rerankdownloads a separate Qwen3-VL Instruct model (Qwen/Qwen3-VL-8B-InstructorQwen/Qwen3-VL-2B-Instruct) in addition to the embedding model. - Embeddings from different backends and models are not compatible. Each backend/model combination gets its own isolated index, so they can't accidentally mix. If you search with a model that has no indexed data, you'll be told which model was actually used.
- Speed varies by GPU core count — base M-series chips are slower than Pro/Max but produce identical results.
Why the local model is fast
The local backend stays fast and memory-efficient through a few techniques that compound:
- Preprocessing shrinks chunks before they hit the model. Each 30s chunk is downscaled to 480p at 5fps via ffmpeg before embedding. A ~19 MB dashcam chunk becomes ~1 MB — a 95% reduction in pixels the model has to process. Model inference time scales with pixel count, not video duration, so this is the single biggest speedup.
- Low frame sampling. The video processor sends at most 32 frames per chunk to the model (
fps=1.0,max_frames=32). A 30-second chunk produces ~30 frames — not hundreds. - MRL dimension truncation. Qwen3-VL-Embedding supports Matryoshka Representation Learning. Only the first 768 dimensions of each embedding are kept and L2-normalized, reducing storage and distance computation in ChromaDB.
- Auto-quantization. On NVIDIA GPUs with limited VRAM, the 8B model is automatically loaded in 4-bit (bitsandbytes) — dropping from ~18 GB to ~6-8 GB with minimal quality loss. A 4090 (24 GB) runs the full bf16 model with headroom to spare.
- Still-frame skipping. Chunks with no meaningful visual change (e.g. a parked car) are detected by comparing JPEG file sizes across sampled frames and skipped entirely — saving a full forward pass per chunk.
With all of this, expect ~2-5s per chunk on an A100 and ~3-8s on a T4. On a 4090, the 8B model in bf16 should be in the low single digits per chunk.
MLX Backend (Apple Silicon)
A second local backend that runs the same Qwen3-VL-Embedding model through MLX instead of PyTorch. Apple Silicon only. It exists because MLX can quantize on Metal and PyTorch on a Mac cannot: the local backend's only quantization route is bitsandbytes, which requires CUDA.
uv tool install ".[mlx]"
sentrysearch index /path/to/footage --backend mlx
sentrysearch search "your query" --backend mlx
No --model needed. It defaults to a 4-bit 2B build (arthurcollet/Qwen3-VL-Embedding-2B-mlx-4bit, ~1.8 GB) and downloads it on first use. To use a different model, pass --backend mlx --model with an MLX repo id or a local converted model directory. Keep --backend mlx: --model on its own selects the PyTorch local backend.
Measured against the PyTorch local backend on the same 112 clips and 34 queries, running the same 2B model:
| retrieval top-1 | per 8s clip | weights | |
|---|---|---|---|
--backend mlx (4-bit) | 0.47 | 1.2 s | 1.8 GB |
--backend local (bf16 via MPS) | 0.44 | 2.5 s | ~4 GB |
The two are level on accuracy — the gap is inside the noise of 34 queries — so 4-bit quantization costs nothing here while halving both the time and the memory.
The confidence threshold defaults to 0.35 on this backend, not 0.41, because its scores run lower. On dashcam footage, everyday queries ("a truck", "driving at night") scored 0.37–0.59 with the right clip on top, while unrelated ones ("a plate of sushi") scored 0.17–0.33. Specific queries score lower, and correct matches came in as low as 0.28, so a good result can still be flagged as low confidence. The results are still shown; lower --threshold if that happens often for your queries. The local backends are not calibrated alike, so a threshold tuned on one will misbehave on the other.
No 8B option. An 8B build ties the 2B at best and needs roughly three times the time and memory to do it, so no 8B alias ships here. You can still point --backend mlx --model at your own conversion.
No reranking yet. --rerank is rejected on this backend rather than silently falling back to the Gemini reranker, which would send your results to an API after you chose a local backend. Use --backend local for the PyTorch reranker.
Embeddings from this backend get their own index, separate from local, so the two never mix. If you have both, a search without --backend uses the local index; pass --backend mlx, or clear the old one with sentrysearch reset --backend local once you've switched.
Tesla Metadata Overlay
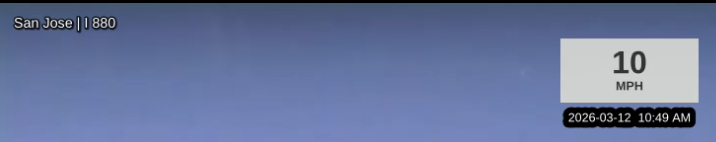
Burn speed, location, and time onto trimmed clips:
sentrysearch search "car cutting me off" --overlay
This extracts telemetry embedded in Tesla dashcam files (speed, GPS) and renders a HUD overlay. The overlay shows:
- Top center: speed and MPH label on a light gray card
- Below card: date and time (12-hour with AM/PM)
- Top left: city and road name (via reverse geocoding)
Requirements:
- Tesla firmware 2025.44.25 or later, HW3+
- SEI metadata is only present in driving footage (not parked/Sentry Mode)
- Reverse geocoding uses OpenStreetMap's Nominatim API via geopy (optional)
Install with Tesla overlay support:
uv tool install ".[tesla]"
Without geopy, the overlay still works but omits the city/road name.
Source: teslamotors/dashcam
Stitch with SentryMerge
SentryMerge is a sibling tool that auto-cuts a single cross-camera video of one event from a SentrySearch result. Every time sentrysearch search runs, it caches the result list to ~/.sentrysearch/last_search.json; SentryMerge picks that up via --last, picks the best multi-camera clip-set, asks a VLM for sub-second visibility ranges per camera, and stitches one frame-accurate video that follows the subject across cameras:
sentrysearch search "<query>"
sentrymerge --last                      # → merge.mp4
--last works without re-running search; sentrymerge --query "..." re-runs search under the hood. See the SentryMerge README for install instructions, VLM backend options (Gemini / OpenAI / local Qwen), and the modular cam-config system for non-Tesla dashcams.
Redact with SentryBlur
SentryBlur is a sibling tool for local face, license plate, and natural-language redaction of video. Every time sentrysearch search saves a clip, it caches the path to ~/.sentrysearch/last_clip.json; SentryBlur picks that up via --last, so search-then-redact is two commands and no path-passing:
sentrysearch search "car cuts me off"
sentryblur prompt --last "road signs"   # → match_<...>_blurred.mp4
sentryblur faces --last and sentryblur plates --last work the same way. Pick faces or plates for fast CPU detectors; use prompt "<text>" for arbitrary objects (phone screens, monitors, name tags) — prompt requires an NVIDIA GPU or Apple Silicon. See the SentryBlur README for install instructions and hardware notes.
Managing the index
# Show index info (files marked [missing] no longer exist on disk)
sentrysearch stats

# Remove specific files by path substring
sentrysearch remove path/to/footage

# Wipe the entire index
sentrysearch reset
Failed chunks and retrying
If a chunk cannot be embedded after retries, SentrySearch records it in a
dead-letter queue (DLQ) at ~/.sentrysearch/dlq.json and continues indexing
the rest of your footage. Chunks usually land there because of repeated
transient API/backend failures, decoder errors for a specific file, missing
files, or out-of-memory errors. Permanent-looking failures such as missing
files, decode errors, and OOM are recorded immediately because retrying the
same chunk with the same settings is unlikely to help.
Inspect failed chunks:
sentrysearch dlq list
Retry them on the next index run:
sentrysearch index /path/to/footage --retry-failed
Clear the DLQ without retrying:
sentrysearch dlq clear
By default, future sentrysearch index runs skip chunks already in the DLQ so
you do not repeatedly pay for or wait on failures. Use --retry-failed after
fixing the source problem, changing model/backend settings, or freeing memory.
Cache and state files
SentrySearch keeps local state under ~/.sentrysearch/:
| Path | Written by | Used for | Safe to delete? |
|---|---|---|---|
db/ | sentrysearch index | ChromaDB vector index for your embedded footage. | Yes, but this deletes the index. Re-run sentrysearch index <dir> before searching again. |
.env | sentrysearch init | Stores your Gemini API key for the default backend. | Yes, but Gemini-backed commands will ask you to configure a key again. |
dlq.json | Failed sentrysearch index chunks | Dead-letter queue inspected by sentrysearch dlq list and retried with --retry-failed. | Yes. Deleting it forgets failed chunks, so future index runs may try them again as new work. |
last_clip.json | Commands that save a clip (search, img, highlights, overlay) | Lets SentryBlur consume the most recent saved clip with sentryblur ... --last. | Yes. Only the --last handoff is lost; saved MP4 files are not deleted. |
last_search.json | sentrysearch search, img, and highlights | Lets SentryMerge consume the most recent result list with sentrymerge --last. | Yes. Only the --last handoff is lost; the search index is unchanged. |
history | sentrysearch shell | Readline command history for the interactive shell. | Yes. The shell starts with empty history next time. |
Verbose mode
Add --verbose to either command for debug info (embedding dimensions, API response times, similarity scores).
How is this possible?
Both Gemini Embedding 2 and Qwen3-VL-Embedding can natively embed video — raw video pixels are projected into the same vector space as text queries. There's no transcription, no frame captioning, no text middleman. A text query like "red truck at a stop sign" is directly comparable to a 30-second video clip at the vector level. This is what makes sub-second semantic search over hours of footage practical.
Cost
Gemini
Indexing 1 hour of footage costs ~$2.84 with Gemini's embedding API (default settings: 30s chunks, 5s overlap):
1 hour = 3,600 seconds of video = 3,600 frames processed by the model. 3,600 frames × $0.00079 = ~$2.84/hr
The Gemini API natively extracts and tokenizes exactly 1 frame per second from uploaded video, regardless of the file's actual frame rate. The preprocessing step (which downscales chunks to 480p at 5fps via ffmpeg) is a local/bandwidth optimization — it keeps payload sizes small so API requests are fast and don't timeout — but does not change the number of frames the API processes.
Two built-in optimizations help reduce costs in different ways:
- Preprocessing (on by default) — chunks are downscaled to 480p at 5fps before uploading. Since the API processes at 1fps regardless, this only reduces upload size and transfer time, not the number of frames billed. It primarily improves speed and prevents request timeouts.
- Still-frame skipping (on by default) — chunks with no meaningful visual change (e.g. a parked car) are skipped entirely. This saves real API calls and directly reduces cost. The savings depend on your footage — Sentry Mode recordings with hours of idle time benefit the most, while action-packed driving footage may have nothing to skip.
Search queries are negligible (text embedding only).
Qwen Cloud (DashScope, Qwen3-VL-Embedding)
DashScope bills multimodal embedding in CNY per 1,000 input tokens, by modality. For default model qwen3-vl-embedding, Alibaba’s published rates (check the doc below for your region and any updates) are along the lines of:
- Text input: about ¥0.0007 per 1k input tokens
- Image / video input: about ¥0.0018 per 1k input tokens
Indexing sends video chunks (video modality); each search / img query is mostly text or image tokens, which are cheaper per token than video. Your real cost is the token counts returned by DashScope for each API call (depends on resolution, duration, sampling such as DASHSCOPE_VIDEO_FPS, etc.)—there is no fixed “$ per hour of footage” like Gemini’s published per-frame USD rate without measuring your workload.
Alibaba also documents a free token allowance (e.g. 1M tokens within a limited period after activation); confirm in the DashScope multimodal embedding metering & billing page and in the Model Studio / billing console, since pricing, regions, and promotions change.
Rate limiting (free-tier keys)
Free-tier API keys have low per-minute request ceilings, and indexing a large directory can trip them mid-run. Use --rpm to pace outbound calls:
sentrysearch index /path/to/footage --rpm 10
Or set it once, for every command:
export GEMINI_RPM=10        # gemini backend
export DASHSCOPE_RPM=10     # qwen-cloud backend
--rpm overrides the environment variable, and is available on index, search, img, highlights, and shell. It's ignored by --backend local, which makes no API calls. Embedding and reranking share a single window, since both draw on the same project quota.
--rpm only helps with per-minute limits. Free tiers also have a daily request cap, and no amount of throttling gets you past that — it just spreads the same number of requests over more hours. If you hit the daily quota, indexing stops until it resets at midnight Pacific. Indexing is incremental, so re-running the next day resumes where it left off rather than starting over. Check your project's actual limits in AI Studio.
For reference, at the default 30s chunks with 5s overlap, a 1-minute clip produces 3 requests — so an hour of footage across 4 cameras is roughly 720 requests. For large backlogs, the local backend has no quota at all.
Indexing tuning (both backends)
These flags affect chunking and preprocessing for both Gemini and qwen-cloud:
--chunk-duration/--overlap— longer chunks with less overlap = fewer API calls = lower cost--no-skip-still— embed every chunk even if nothing is happening--target-resolution/--target-fps— adjust preprocessing quality--no-preprocess— send raw chunks to the API
Known Warnings (harmless)
The local backend may print warnings during indexing and search. These are cosmetic and don't affect results:
MPS: nonzero op is not natively supported— A known PyTorch limitation on Apple Silicon. The operation falls back to CPU for one step; everything else stays on the GPU. No impact on output quality.video_reader_backend torchcodec error, use torchvision as default— torchcodec can't find a compatible FFmpeg on macOS. The video processor falls back to torchvision automatically. This is expected and produces identical results.You are sending unauthenticated requests to the HF Hub— The model downloads from Hugging Face without a token. Download speeds may be slightly lower, but the model loads fine. Set aHF_TOKENenvironment variable to silence this if it bothers you.
Limitations & Future Work
- Still-frame detection is heuristic — it uses JPEG file size comparison across sampled frames. It may occasionally skip chunks with subtle motion or embed chunks that are truly static. Disable with
--no-skip-stillif you need every chunk indexed. - Search quality depends on chunk boundaries — if an event spans two chunks, the overlapping window helps but isn't perfect. Smarter chunking (e.g. scene detection) could improve this.
Compatibility
This works with .mp4 and .mov footage, not just Tesla Sentry Mode. The directory scanner recursively finds both file types regardless of folder structure.
Requirements
- Python 3.11+
ffmpegon PATH, or use bundled ffmpeg viaimageio-ffmpeg(installed by default)- Gemini backend: Gemini API key (get one free)
- Local backend:
- GPU with CUDA or Apple Metal (see hardware table for VRAM/RAM requirements)
- macOS:
brew install ffmpeg(required by the video decoder) - Linux/Windows: no extra system dependencies
Contributors


Similar repos


Languages
Python
100.0%
Semantic search over videos using Gemini Embedding 2 or Qwen3-VL.
Python
4,522
181 commits
updated Sep 25, 2026
README
SentrySearch
Semantic search over video footage. Type what you're looking for, get a trimmed clip back.
[!IMPORTANT] Official source: github.com/ssrajadh/sentrysearch is the only official home of SentrySearch. Other sites republishing or mirroring this project are not affiliated with or endorsed by the maintainer, always download from this repository.
Languages: English · 简体中文
New: MLX backend for Apple Silicon: runs the local 2B model twice as fast in under half the memory, at the same accuracy
Table of Contents
- How it works
- Getting Started
- Usage
- How is this possible?
- Cost
- Known Warnings (harmless)
- Limitations & Future Work
- Compatibility
- Requirements
How it works
SentrySearch splits your videos into overlapping chunks, embeds each chunk as video using Google's Gemini Embedding API, Alibaba DashScope (qwen-cloud), or a local Qwen3-VL model, and stores the vectors in a local ChromaDB database. When you search, your text query (or image, see search by image) is embedded into the same vector space and matched against the stored video embeddings. The top match is automatically trimmed from the original file and saved as a clip.
Getting Started
- Install uv (if you don't have it):
macOS/Linux:
curl -LsSf https://astral.sh/uv/install.sh | sh
Windows:
powershell -c "irm https://astral.sh/uv/install.ps1 | iex"
- Clone and install:
git clone https://github.com/ssrajadh/sentrysearch.git
cd sentrysearch
uv tool install .
Requires Python 3.11 or 3.12 (PyTorch wheels don't yet support 3.13+). If your default Python is newer, install a managed 3.12 and pin the tool install:
uv python install 3.12
uv tool install --python 3.12 .
- Set up your API key (or use a local model instead) — only needed for the default Gemini backend; skip if you use
--backend local,--backend mlx, or--backend qwen-cloudwithDASHSCOPE_API_KEYin.env.
sentrysearch init
This prompts for your Gemini API key, writes it to .env, and validates it with a test embedding.
- Index your footage:
sentrysearch index /path/to/footage
- Search:
sentrysearch search "red truck running a stop sign"
ffmpeg is required for video chunking and trimming. If you don't have it system-wide, the bundled imageio-ffmpeg is used automatically.
Manual setup: If you prefer not to use
sentrysearch init, you can copy.env.exampleto.envand add your key from aistudio.google.com/apikey manually.
Usage
Init
$ sentrysearch init
Enter your Gemini API key (get one at https://aistudio.google.com/apikey): ****
Validating API key...
Setup complete. You're ready to go — run `sentrysearch index <directory>` to get started.
If a key is already configured, you'll be asked whether to overwrite it.
Tip: Set a spending limit at aistudio.google.com/billing to prevent accidental overspending.
Index footage
$ sentrysearch index /path/to/video/footage
Indexing file 1/3: front_2024-01-15_14-30.mp4 [chunk 1/4]
Indexing file 1/3: front_2024-01-15_14-30.mp4 [chunk 2/4]
...
Indexed 12 new chunks from 3 files. Total: 12 chunks from 3 files.
Options:
--chunk-duration 30— seconds per chunk--overlap 5— overlap between chunks--no-preprocess— skip downscaling/frame rate reduction (send raw chunks)--target-resolution 480— target height in pixels for preprocessing--target-fps 5— target frame rate for preprocessing--no-skip-still— embed all chunks, even ones with no visual change--rpm 10— cap requests per minute to the cloud API (details below)--backend local— use a local model instead of Gemini (details below)--backend mlx— use the local model through MLX on Apple Silicon, faster and lighter thanlocal(details below)
Search
$ sentrysearch search "red truck running a stop sign"
  #1 [0.87] front_2024-01-15_14-30.mp4 @ 02:15-02:45
  #2 [0.74] left_2024-01-15_14-30.mp4 @ 02:10-02:40
  #3 [0.61] front_2024-01-20_09-15.mp4 @ 00:30-01:00

Saved clip: ./match_front_2024-01-15_14-30_02m15s-02m45s.mp4
If the best result's similarity score is below the confidence threshold (default 0.41, or 0.35 on --backend mlx), you'll be prompted before trimming:
No confident match found (best score: 0.28). Show results anyway? [y/N]:
With --no-trim, low-confidence results are shown with a note instead of a prompt.
Options: --results N, --output-dir DIR, --no-trim to skip auto-trimming, --threshold 0.5 to adjust the confidence cutoff, --save-top N to save the top N clips instead of just the best match, --dedupe to set how similar a result can be to a higher-ranked pick before it's dropped (on by default, so overlapping chunks of the same moment don't fill the list), and --rerank to ask a VLM to re-rank the returned candidates before trimming. Backend and model are auto-detected from the index — pass --backend or --model only to override.
# Save top 5 clips, dropping only near-identical chunks
sentrysearch search "red truck" --save-top 5 --dedupe 0.95

# Re-rank the top 10 embedding matches with a VLM before trimming
sentrysearch search "pedestrian crossing behind the car" --rerank --results 10
The --dedupe value is a cosine similarity ceiling (0–1). Any result whose similarity to an already-kept higher-ranked result exceeds this value is dropped. Lower values are stricter: 0.8 requires results to be very distinct, 0.95 only removes near-identical chunks. The default is 0.9; pass --dedupe 1 to keep every result. Search fetches extra candidates when deduping, so you still get the number of results you asked for.
--rerank extracts each returned candidate clip, sends it to a VLM with the query, and sorts likely visual matches ahead of embedding-only results. Gemini and qwen-cloud searches use Gemini 2.5 Flash for reranking; local searches use a local Qwen3-VL Instruct reranker. If reranking cannot run or a candidate cannot be scored, SentrySearch keeps the embedding-ranked results instead of failing the search.
Search by image
Use a reference image as the query — useful for "find clips that look like this" when describing the scene in words is awkward (a screenshot of a specific car, a reference frame from another video, etc.).
$ sentrysearch img ~/Downloads/image.jpg
  #1 [0.72] 2026-03-12_10-44-17-left_repeater.mp4 @ 00:00-00:30
  #2 [0.69] 2026-03-12_10-44-17-left_repeater.mp4 @ 00:25-00:55
  #3 [0.67] 2026-02-12_20-02-15-front.mp4 @ 00:00-00:18

Saved clip: ./match_2026-03-12_10-44-17-left_repeater_00m00s-00m30s.mp4
The image is embedded into the same vector space as the indexed video chunks and ranked by cosine similarity. Image search supports --results, --threshold, --save-top, --dedupe, --overlay, --no-trim, --backend, and --model.
Supported formats: JPG, PNG, WEBP, GIF, HEIC/HEIF on the Gemini backend; the local backend additionally accepts anything PIL can decode (BMP, TIFF, etc.).
Note: Image search returns visually similar matches, not necessarily the same object. A red sedan query may surface other red sedans of similar shape — calibrate expectations accordingly.
Highlights
Don't know what to search for? sentrysearch highlights ranks the most anomalous clips in your index — chunks whose embeddings sit far from everything else — and trims them automatically. Good for skimming a fresh dump of footage.
$ sentrysearch highlights -n 3
  #1 [0.165] 2026-02-12_20-02-15-back.mp4 @ 00:00-00:18
  #2 [0.163] 2026-02-12_20-02-15-right_repeater.mp4 @ 00:00-00:18
  #3 [0.149] 2026-02-12_20-02-15-front.mp4 @ 00:00-00:18
...
Scoring methods (--method):
knn(default) — mean cosine distance to a chunk's k nearest neighbors. Robust; surfaces clips with no near-twins.centroid— distance from the index mean. Cheapest, biased toward whatever's underrepresented.lof— Local Outlier Factor. Best when the index has multiple distinct "normal" modes (day vs. night vs. garage).
Refinement options:
--against "<query>"— score anomaly relative to a query. With--against-mode within(default), ranks anomalies among the top matches of the query ("the weird pedestrians in pedestrian clips"). With--against-mode global, finds clips that match the query but are unlike the rest of the index ("rare events of this type").--dedupe 0.9— drop results too similar to a higher-ranked pick (default 0.9 cosine similarity). Prevents near-duplicate frames from filling the list.--exclude-baseline— drop the half of the index nearest the centroid before scoring. Useful when the index is dominated by repetitive "boring" footage.-k, --neighbors 10— k forknn/lof.--no-trim— print the ranking without writing clips.
Caveat: Statistically anomalous ≠ interesting. Sensor glitches, lens flare, night frames in a mostly-daytime index, and the lone garage clip all rank high. Use
--exclude-baselineand--dedupeto filter the noise, or--againstto constrain by topic.
Qwen Cloud (Alibaba DashScope)
Use the optional qwen-cloud backend for DashScope / Model Studio multimodal embeddings (default model qwen3-vl-embedding, overridable with --dashscope-model or DASHSCOPE_EMBEDDING_MODEL):
uv tool install ".[qwen-cloud]"
export DASHSCOPE_API_KEY=...
sentrysearch index /path/to/footage --backend qwen-cloud
sentrysearch search "your query" --backend qwen-cloud
Video uploads: local chunk files are sent to DashScope-managed temporary OSS by the official Python SDK before the API consumes them (the HTTP API expects a URL; the SDK handles upload for you).
Local Backend (no API key needed)
Index and search using a local Qwen3-VL-Embedding model instead of the Gemini API. Free, private, and runs entirely on your machine. For the best search quality, use the Gemini backend — the local 8B model is a solid alternative when you need offline/private search, and the 2B model is a fallback when hardware can't support 8B.
The model is auto-detected from your hardware — qwen8b for NVIDIA GPUs and Macs with 24 GB+ RAM, qwen2b for smaller Macs and CPU-only systems. You can override with --model qwen2b or --model qwen8b. Pick an install based on your hardware:
| Hardware | Install command | Auto-detected model | Notes |
|---|---|---|---|
| Apple Silicon, 24 GB+ RAM | uv tool install ".[local]" | qwen8b | Full float16 via MPS |
| Apple Silicon, 16 GB RAM | uv tool install ".[local]" | qwen2b | 8B won't fit; 2B uses ~6 GB. The MLX backend runs the same 2B in ~1.8 GB |
| Apple Silicon, 8 GB RAM | uv tool install ".[local]" | qwen2b | Tight — may swap under load; Gemini API recommended instead. The MLX backend needs far less memory but hasn't been tested on 8 GB |
| NVIDIA, 18 GB+ VRAM | uv tool install ".[local]" | qwen8b | Full bf16 precision (CUDA wheels pulled automatically on Linux/Windows) |
| NVIDIA, 8–16 GB VRAM | uv tool install ".[local-quantized]" | qwen8b | 4-bit quantization (~6–8 GB) |
Won't work well: Intel Macs and machines without a dedicated GPU. These fall back to CPU with float32 — too slow and memory-hungry for practical use. Use the Gemini API backend (the default) instead.
Not sure? On a Mac with less than 24 GB, use the MLX backend (
".[mlx]"): same accuracy as".[local]"at half the time and memory, though it doesn't support--rerankyet. On a larger Mac, use".[local]". On NVIDIA, use".[local-quantized]"— 4-bit quantization works on the widest range of NVIDIA hardware with minimal quality loss. (bitsandbytes requires CUDA and does not work on Mac/MPS.)
Python version: PyTorch wheels lag behind new Python releases, so the local backend requires Python 3.11 or 3.12. If your default Python is 3.13+, install a managed 3.12 and pin the tool install to it:
uv python install 3.12
uv tool install --python 3.12 ".[local]"
Mac prerequisite: Install system FFmpeg (the local model's video processor requires it — the Gemini backend uses a bundled ffmpeg instead):
brew install ffmpeg
Index with --backend local and search — no extra flags needed:
sentrysearch index /path/to/footage --backend local
sentrysearch search "car running a red light"
The search command auto-detects the backend and model from whatever you indexed with. You can also use --model as a shorthand — it implies --backend local:
sentrysearch index /path/to/footage --model qwen2b   # same as --backend local --model qwen2b
sentrysearch search "car running a red light"          # auto-detects local/qwen2b from index
Options:
--model qwen2b— smaller model, lower quality but only ~6 GB memory (also accepts full HuggingFace IDs)--quantize/--no-quantize— force 4-bit quantization on or off (default: auto-detect based on whether bitsandbytes is installed)
Notes:
- First run downloads the model (~16 GB for 8B, ~4 GB for 2B).
- Local
--rerankdownloads a separate Qwen3-VL Instruct model (Qwen/Qwen3-VL-8B-InstructorQwen/Qwen3-VL-2B-Instruct) in addition to the embedding model. - Embeddings from different backends and models are not compatible. Each backend/model combination gets its own isolated index, so they can't accidentally mix. If you search with a model that has no indexed data, you'll be told which model was actually used.
- Speed varies by GPU core count — base M-series chips are slower than Pro/Max but produce identical results.
Why the local model is fast
The local backend stays fast and memory-efficient through a few techniques that compound:
- Preprocessing shrinks chunks before they hit the model. Each 30s chunk is downscaled to 480p at 5fps via ffmpeg before embedding. A ~19 MB dashcam chunk becomes ~1 MB — a 95% reduction in pixels the model has to process. Model inference time scales with pixel count, not video duration, so this is the single biggest speedup.
- Low frame sampling. The video processor sends at most 32 frames per chunk to the model (
fps=1.0,max_frames=32). A 30-second chunk produces ~30 frames — not hundreds. - MRL dimension truncation. Qwen3-VL-Embedding supports Matryoshka Representation Learning. Only the first 768 dimensions of each embedding are kept and L2-normalized, reducing storage and distance computation in ChromaDB.
- Auto-quantization. On NVIDIA GPUs with limited VRAM, the 8B model is automatically loaded in 4-bit (bitsandbytes) — dropping from ~18 GB to ~6-8 GB with minimal quality loss. A 4090 (24 GB) runs the full bf16 model with headroom to spare.
- Still-frame skipping. Chunks with no meaningful visual change (e.g. a parked car) are detected by comparing JPEG file sizes across sampled frames and skipped entirely — saving a full forward pass per chunk.
With all of this, expect ~2-5s per chunk on an A100 and ~3-8s on a T4. On a 4090, the 8B model in bf16 should be in the low single digits per chunk.
MLX Backend (Apple Silicon)
A second local backend that runs the same Qwen3-VL-Embedding model through MLX instead of PyTorch. Apple Silicon only. It exists because MLX can quantize on Metal and PyTorch on a Mac cannot: the local backend's only quantization route is bitsandbytes, which requires CUDA.
uv tool install ".[mlx]"
sentrysearch index /path/to/footage --backend mlx
sentrysearch search "your query" --backend mlx
No --model needed. It defaults to a 4-bit 2B build (arthurcollet/Qwen3-VL-Embedding-2B-mlx-4bit, ~1.8 GB) and downloads it on first use. To use a different model, pass --backend mlx --model with an MLX repo id or a local converted model directory. Keep --backend mlx: --model on its own selects the PyTorch local backend.
Measured against the PyTorch local backend on the same 112 clips and 34 queries, running the same 2B model:
| retrieval top-1 | per 8s clip | weights | |
|---|---|---|---|
--backend mlx (4-bit) | 0.47 | 1.2 s | 1.8 GB |
--backend local (bf16 via MPS) | 0.44 | 2.5 s | ~4 GB |
The two are level on accuracy — the gap is inside the noise of 34 queries — so 4-bit quantization costs nothing here while halving both the time and the memory.
The confidence threshold defaults to 0.35 on this backend, not 0.41, because its scores run lower. On dashcam footage, everyday queries ("a truck", "driving at night") scored 0.37–0.59 with the right clip on top, while unrelated ones ("a plate of sushi") scored 0.17–0.33. Specific queries score lower, and correct matches came in as low as 0.28, so a good result can still be flagged as low confidence. The results are still shown; lower --threshold if that happens often for your queries. The local backends are not calibrated alike, so a threshold tuned on one will misbehave on the other.
No 8B option. An 8B build ties the 2B at best and needs roughly three times the time and memory to do it, so no 8B alias ships here. You can still point --backend mlx --model at your own conversion.
No reranking yet. --rerank is rejected on this backend rather than silently falling back to the Gemini reranker, which would send your results to an API after you chose a local backend. Use --backend local for the PyTorch reranker.
Embeddings from this backend get their own index, separate from local, so the two never mix. If you have both, a search without --backend uses the local index; pass --backend mlx, or clear the old one with sentrysearch reset --backend local once you've switched.
Tesla Metadata Overlay
Burn speed, location, and time onto trimmed clips:
sentrysearch search "car cutting me off" --overlay
This extracts telemetry embedded in Tesla dashcam files (speed, GPS) and renders a HUD overlay. The overlay shows:
- Top center: speed and MPH label on a light gray card
- Below card: date and time (12-hour with AM/PM)
- Top left: city and road name (via reverse geocoding)
Requirements:
- Tesla firmware 2025.44.25 or later, HW3+
- SEI metadata is only present in driving footage (not parked/Sentry Mode)
- Reverse geocoding uses OpenStreetMap's Nominatim API via geopy (optional)
Install with Tesla overlay support:
uv tool install ".[tesla]"
Without geopy, the overlay still works but omits the city/road name.
Source: teslamotors/dashcam
Stitch with SentryMerge
SentryMerge is a sibling tool that auto-cuts a single cross-camera video of one event from a SentrySearch result. Every time sentrysearch search runs, it caches the result list to ~/.sentrysearch/last_search.json; SentryMerge picks that up via --last, picks the best multi-camera clip-set, asks a VLM for sub-second visibility ranges per camera, and stitches one frame-accurate video that follows the subject across cameras:
sentrysearch search "<query>"
sentrymerge --last                      # → merge.mp4
--last works without re-running search; sentrymerge --query "..." re-runs search under the hood. See the SentryMerge README for install instructions, VLM backend options (Gemini / OpenAI / local Qwen), and the modular cam-config system for non-Tesla dashcams.
Redact with SentryBlur
SentryBlur is a sibling tool for local face, license plate, and natural-language redaction of video. Every time sentrysearch search saves a clip, it caches the path to ~/.sentrysearch/last_clip.json; SentryBlur picks that up via --last, so search-then-redact is two commands and no path-passing:
sentrysearch search "car cuts me off"
sentryblur prompt --last "road signs"   # → match_<...>_blurred.mp4
sentryblur faces --last and sentryblur plates --last work the same way. Pick faces or plates for fast CPU detectors; use prompt "<text>" for arbitrary objects (phone screens, monitors, name tags) — prompt requires an NVIDIA GPU or Apple Silicon. See the SentryBlur README for install instructions and hardware notes.
Managing the index
# Show index info (files marked [missing] no longer exist on disk)
sentrysearch stats

# Remove specific files by path substring
sentrysearch remove path/to/footage

# Wipe the entire index
sentrysearch reset
Failed chunks and retrying
If a chunk cannot be embedded after retries, SentrySearch records it in a
dead-letter queue (DLQ) at ~/.sentrysearch/dlq.json and continues indexing
the rest of your footage. Chunks usually land there because of repeated
transient API/backend failures, decoder errors for a specific file, missing
files, or out-of-memory errors. Permanent-looking failures such as missing
files, decode errors, and OOM are recorded immediately because retrying the
same chunk with the same settings is unlikely to help.
Inspect failed chunks:
sentrysearch dlq list
Retry them on the next index run:
sentrysearch index /path/to/footage --retry-failed
Clear the DLQ without retrying:
sentrysearch dlq clear
By default, future sentrysearch index runs skip chunks already in the DLQ so
you do not repeatedly pay for or wait on failures. Use --retry-failed after
fixing the source problem, changing model/backend settings, or freeing memory.
Cache and state files
SentrySearch keeps local state under ~/.sentrysearch/:
| Path | Written by | Used for | Safe to delete? |
|---|---|---|---|
db/ | sentrysearch index | ChromaDB vector index for your embedded footage. | Yes, but this deletes the index. Re-run sentrysearch index <dir> before searching again. |
.env | sentrysearch init | Stores your Gemini API key for the default backend. | Yes, but Gemini-backed commands will ask you to configure a key again. |
dlq.json | Failed sentrysearch index chunks | Dead-letter queue inspected by sentrysearch dlq list and retried with --retry-failed. | Yes. Deleting it forgets failed chunks, so future index runs may try them again as new work. |
last_clip.json | Commands that save a clip (search, img, highlights, overlay) | Lets SentryBlur consume the most recent saved clip with sentryblur ... --last. | Yes. Only the --last handoff is lost; saved MP4 files are not deleted. |
last_search.json | sentrysearch search, img, and highlights | Lets SentryMerge consume the most recent result list with sentrymerge --last. | Yes. Only the --last handoff is lost; the search index is unchanged. |
history | sentrysearch shell | Readline command history for the interactive shell. | Yes. The shell starts with empty history next time. |
Verbose mode
Add --verbose to either command for debug info (embedding dimensions, API response times, similarity scores).
How is this possible?
Both Gemini Embedding 2 and Qwen3-VL-Embedding can natively embed video — raw video pixels are projected into the same vector space as text queries. There's no transcription, no frame captioning, no text middleman. A text query like "red truck at a stop sign" is directly comparable to a 30-second video clip at the vector level. This is what makes sub-second semantic search over hours of footage practical.
Cost
Gemini
Indexing 1 hour of footage costs ~$2.84 with Gemini's embedding API (default settings: 30s chunks, 5s overlap):
1 hour = 3,600 seconds of video = 3,600 frames processed by the model. 3,600 frames × $0.00079 = ~$2.84/hr
The Gemini API natively extracts and tokenizes exactly 1 frame per second from uploaded video, regardless of the file's actual frame rate. The preprocessing step (which downscales chunks to 480p at 5fps via ffmpeg) is a local/bandwidth optimization — it keeps payload sizes small so API requests are fast and don't timeout — but does not change the number of frames the API processes.
Two built-in optimizations help reduce costs in different ways:
- Preprocessing (on by default) — chunks are downscaled to 480p at 5fps before uploading. Since the API processes at 1fps regardless, this only reduces upload size and transfer time, not the number of frames billed. It primarily improves speed and prevents request timeouts.
- Still-frame skipping (on by default) — chunks with no meaningful visual change (e.g. a parked car) are skipped entirely. This saves real API calls and directly reduces cost. The savings depend on your footage — Sentry Mode recordings with hours of idle time benefit the most, while action-packed driving footage may have nothing to skip.
Search queries are negligible (text embedding only).
Qwen Cloud (DashScope, Qwen3-VL-Embedding)
DashScope bills multimodal embedding in CNY per 1,000 input tokens, by modality. For default model qwen3-vl-embedding, Alibaba’s published rates (check the doc below for your region and any updates) are along the lines of:
- Text input: about ¥0.0007 per 1k input tokens
- Image / video input: about ¥0.0018 per 1k input tokens
Indexing sends video chunks (video modality); each search / img query is mostly text or image tokens, which are cheaper per token than video. Your real cost is the token counts returned by DashScope for each API call (depends on resolution, duration, sampling such as DASHSCOPE_VIDEO_FPS, etc.)—there is no fixed “$ per hour of footage” like Gemini’s published per-frame USD rate without measuring your workload.
Alibaba also documents a free token allowance (e.g. 1M tokens within a limited period after activation); confirm in the DashScope multimodal embedding metering & billing page and in the Model Studio / billing console, since pricing, regions, and promotions change.
Rate limiting (free-tier keys)
Free-tier API keys have low per-minute request ceilings, and indexing a large directory can trip them mid-run. Use --rpm to pace outbound calls:
sentrysearch index /path/to/footage --rpm 10
Or set it once, for every command:
export GEMINI_RPM=10        # gemini backend
export DASHSCOPE_RPM=10     # qwen-cloud backend
--rpm overrides the environment variable, and is available on index, search, img, highlights, and shell. It's ignored by --backend local, which makes no API calls. Embedding and reranking share a single window, since both draw on the same project quota.
--rpm only helps with per-minute limits. Free tiers also have a daily request cap, and no amount of throttling gets you past that — it just spreads the same number of requests over more hours. If you hit the daily quota, indexing stops until it resets at midnight Pacific. Indexing is incremental, so re-running the next day resumes where it left off rather than starting over. Check your project's actual limits in AI Studio.
For reference, at the default 30s chunks with 5s overlap, a 1-minute clip produces 3 requests — so an hour of footage across 4 cameras is roughly 720 requests. For large backlogs, the local backend has no quota at all.
Indexing tuning (both backends)
These flags affect chunking and preprocessing for both Gemini and qwen-cloud:
--chunk-duration/--overlap— longer chunks with less overlap = fewer API calls = lower cost--no-skip-still— embed every chunk even if nothing is happening--target-resolution/--target-fps— adjust preprocessing quality--no-preprocess— send raw chunks to the API
Known Warnings (harmless)
The local backend may print warnings during indexing and search. These are cosmetic and don't affect results:
MPS: nonzero op is not natively supported— A known PyTorch limitation on Apple Silicon. The operation falls back to CPU for one step; everything else stays on the GPU. No impact on output quality.video_reader_backend torchcodec error, use torchvision as default— torchcodec can't find a compatible FFmpeg on macOS. The video processor falls back to torchvision automatically. This is expected and produces identical results.You are sending unauthenticated requests to the HF Hub— The model downloads from Hugging Face without a token. Download speeds may be slightly lower, but the model loads fine. Set aHF_TOKENenvironment variable to silence this if it bothers you.
Limitations & Future Work
- Still-frame detection is heuristic — it uses JPEG file size comparison across sampled frames. It may occasionally skip chunks with subtle motion or embed chunks that are truly static. Disable with
--no-skip-stillif you need every chunk indexed. - Search quality depends on chunk boundaries — if an event spans two chunks, the overlapping window helps but isn't perfect. Smarter chunking (e.g. scene detection) could improve this.
Compatibility
This works with .mp4 and .mov footage, not just Tesla Sentry Mode. The directory scanner recursively finds both file types regardless of folder structure.
Requirements
- Python 3.11+
ffmpegon PATH, or use bundled ffmpeg viaimageio-ffmpeg(installed by default)- Gemini backend: Gemini API key (get one free)
- Local backend:
- GPU with CUDA or Apple Metal (see hardware table for VRAM/RAM requirements)
- macOS:
brew install ffmpeg(required by the video decoder) - Linux/Windows: no extra system dependencies
Similar repos
Contributors
Languages
Python
100.0%