
[CVPR 2026 Poster] One-to-All Animation: Alignment-Free Character Animation and Image Pose Transfer
Python
500
15 commits
updated Apr 19, 2026
README
One-to-All Animation: Alignment-Free
Character Animation
and Image Pose Transfer
Shijun Shi1*, Jing Xu2*, Zhihang Li3, Chunli Peng4, Xiaoda Yang5, Lijing Lu3,
Kai Hu1†, Jiangning Zhang5†
1Jiangnan University
2University of Science and Technology of China
3Chinese Academy of Sciences
4Beijing University of Posts and Telecommunications
5Zhejiang University
*Equal contribution †Corresponding authors


🌟 Highlights
We provide a complete and reproducible training and evaluation pipeline:
- ✅ Full Training Code: Three-stage progressive training from scratch
- ✅ Complete Benchmarks: Reproduction code and pre-trained checkpoints
- ✅ Flexible Training Codebase: Multi-resolution, multi-aspect-ratio, and multi-frame training codebase
- ✅ Datasets: Pre-processed open-source datasets + self-collected cartoon data
🔥 Update
- [2026.02.24] 🎉🎉🎉 One-to-All Animation has been accepted by CVPR 2026!
- [2025.12.22] 🔥🔥🔥 GPU-poor? Run One-to-All1.3B + ComfyUI for free on Kaggle’s 16 GB T4. We’ve released a zero-setup guide that runs the One-to-All ComfyUI workflow on Kaggle’s 16 GB T4—completely free😊. It takes 11 minutes to generate a 10-second 832×480 video. Tutorial: https://ncn0ojsozocg.feishu.cn/wiki/J9Ohwmtudin0vtkuyPccIZkhnZz
- [2025.12] kijai's ComfyUI WanVideoWrapper now integrates One‑to‑All Animation 14B! Huge thanks to kijai for the amazing work!!! Note: Our model supports both retargeted pose and direct pose (with reference preprocessing) from the original video. In addition, using lighter colors for the facial skeleton and landmarks helps achieve better identity consistency.
- [2025.11] Paper reproduction and evaluation code released.
- [2025.11] Sample training data and Benchmark on HuggingFace released.
- [2025.11] Inference and Training codes are released.
- [2025.11] 1.3B-v1, 1.3B-v2 and 14B checkpoints are released.
🎭 Showcase
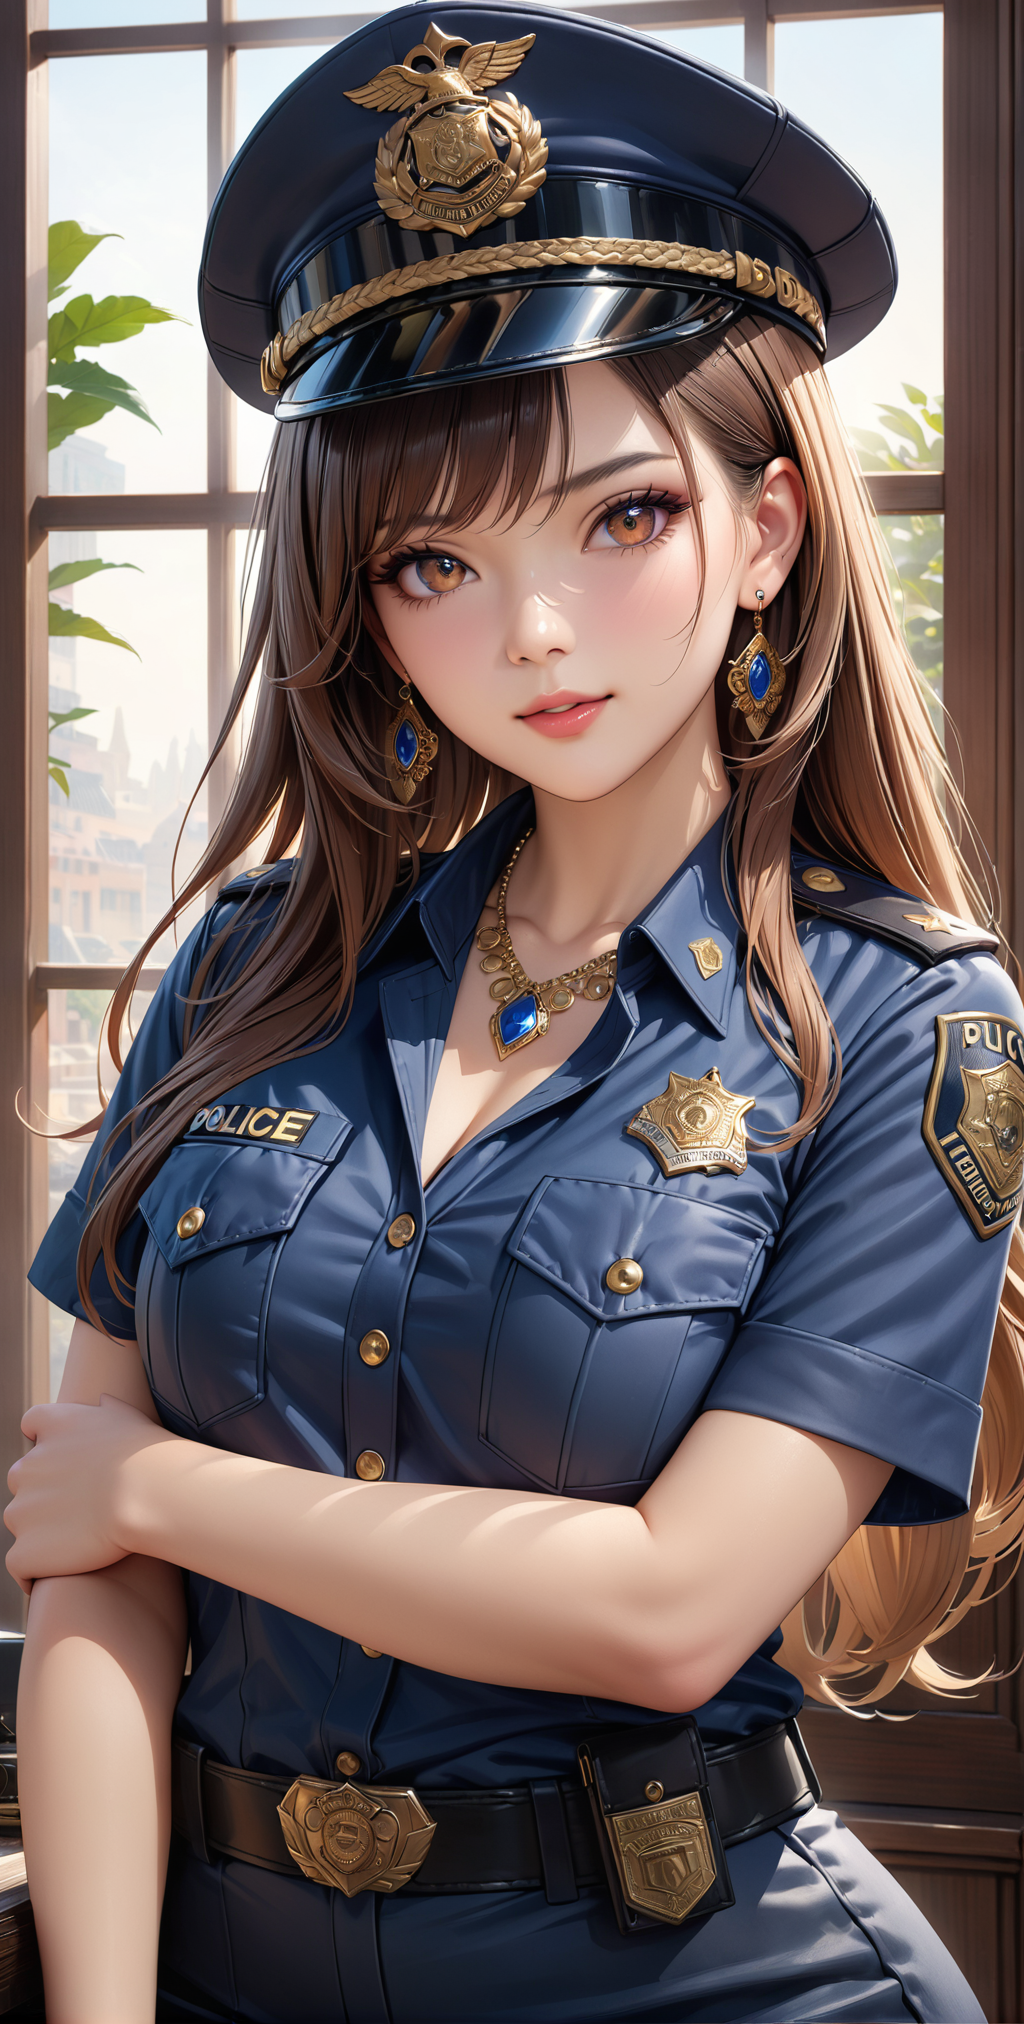
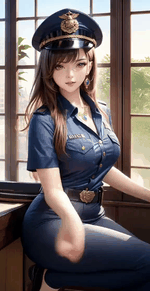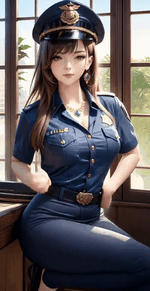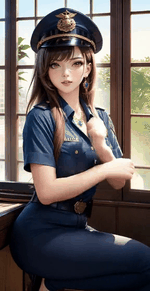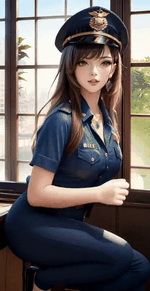
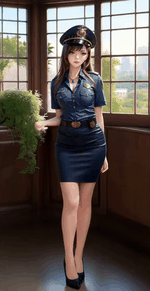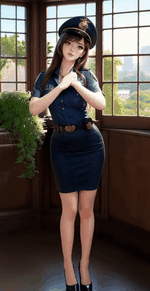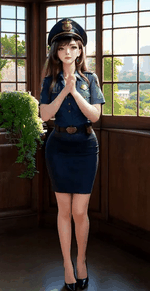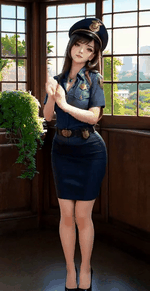
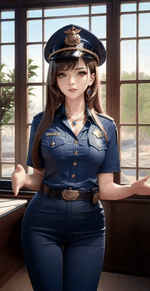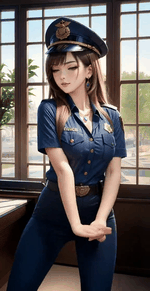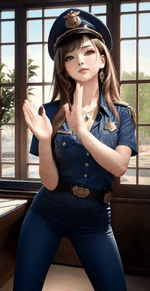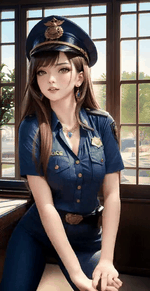
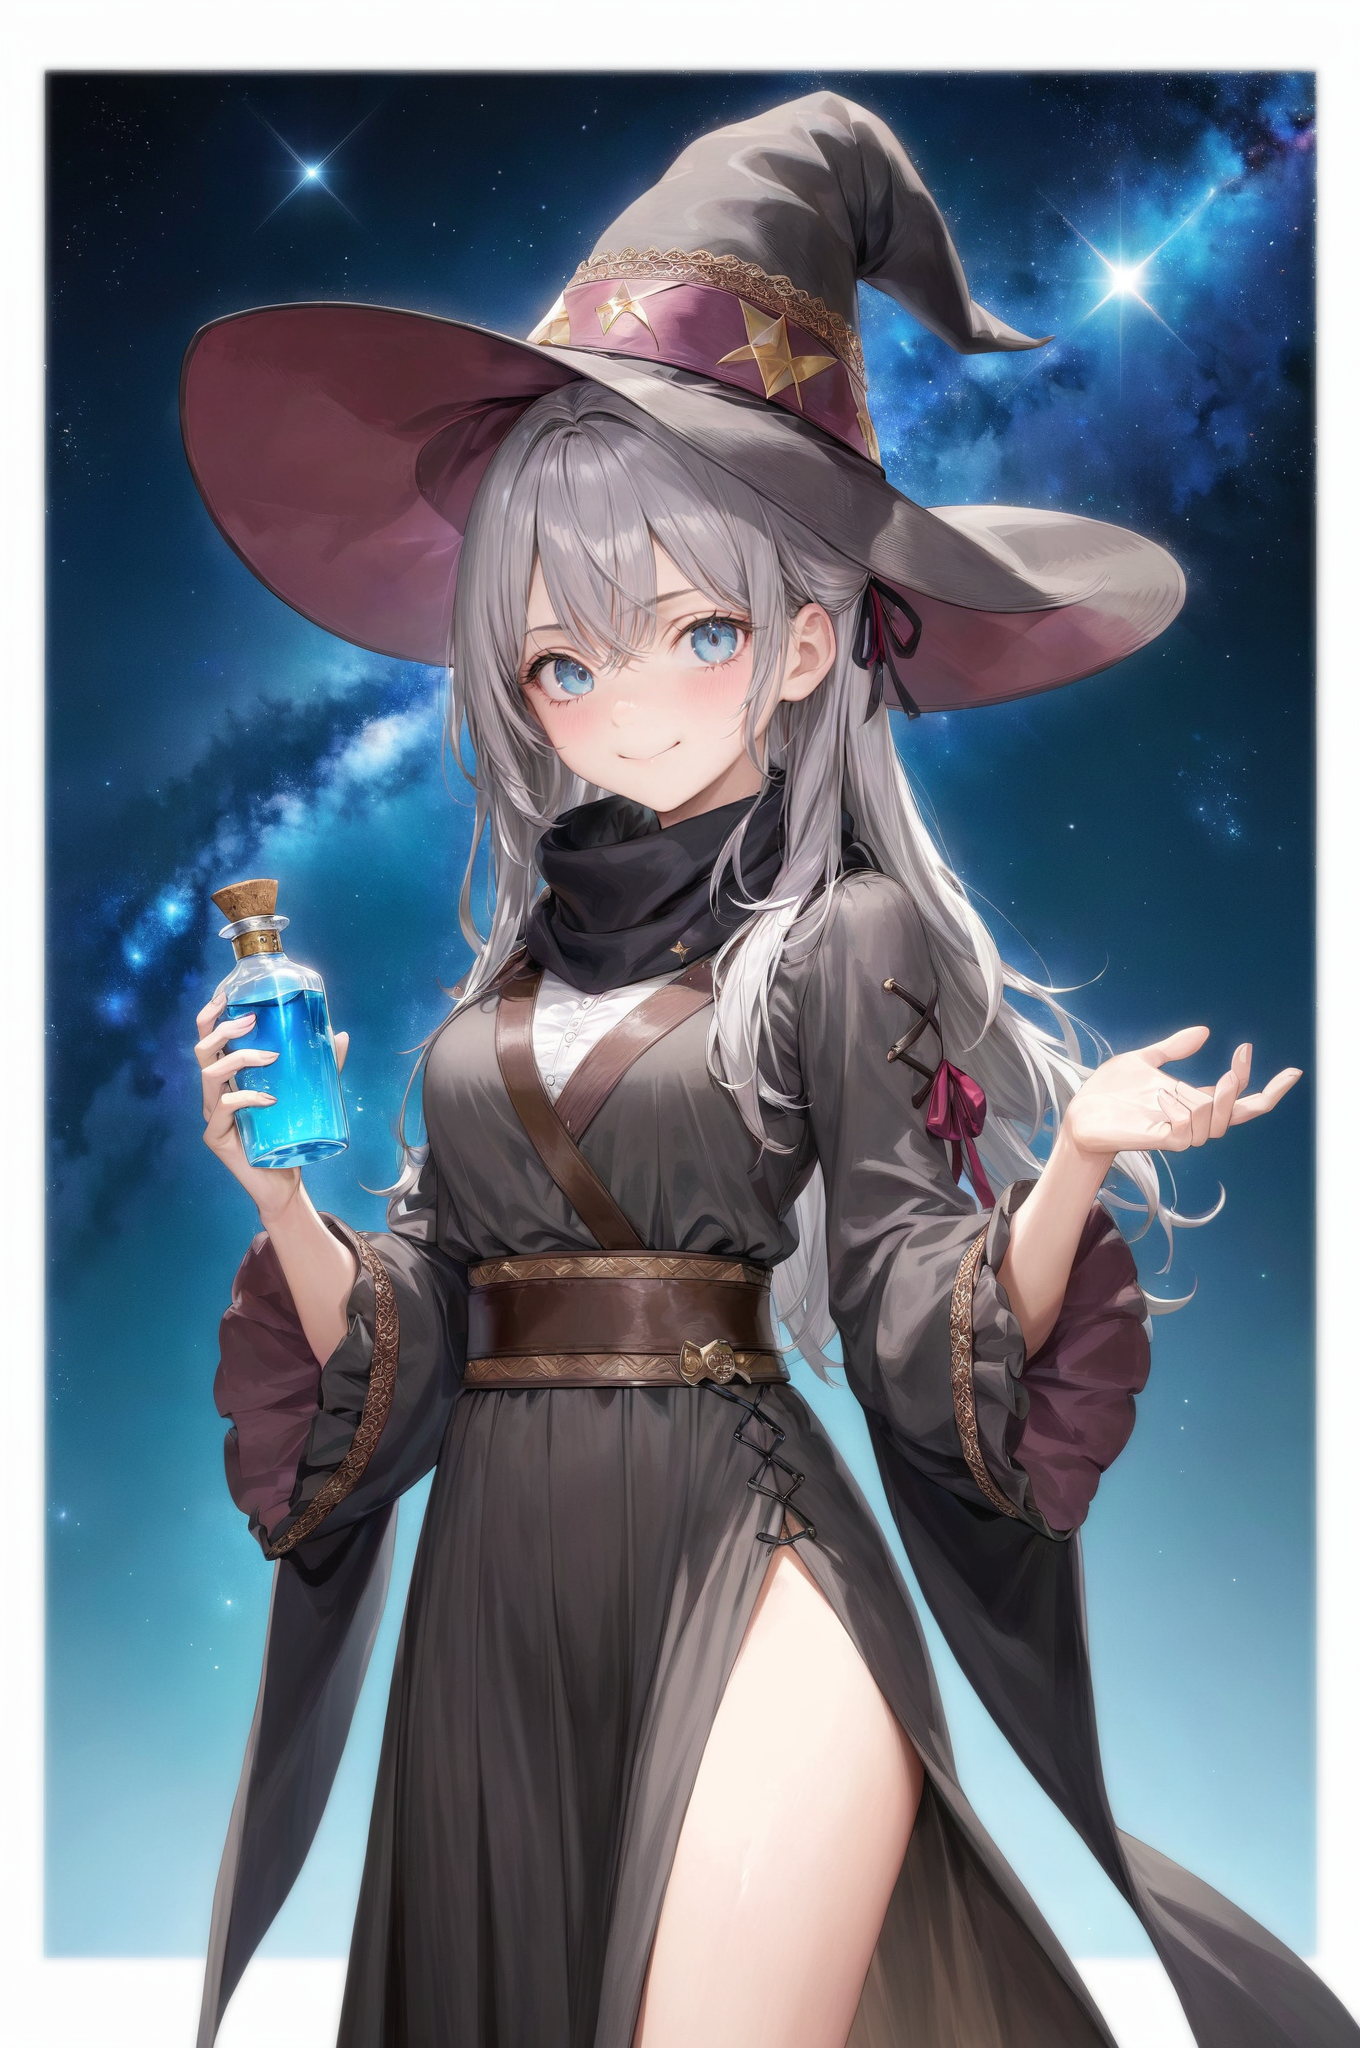
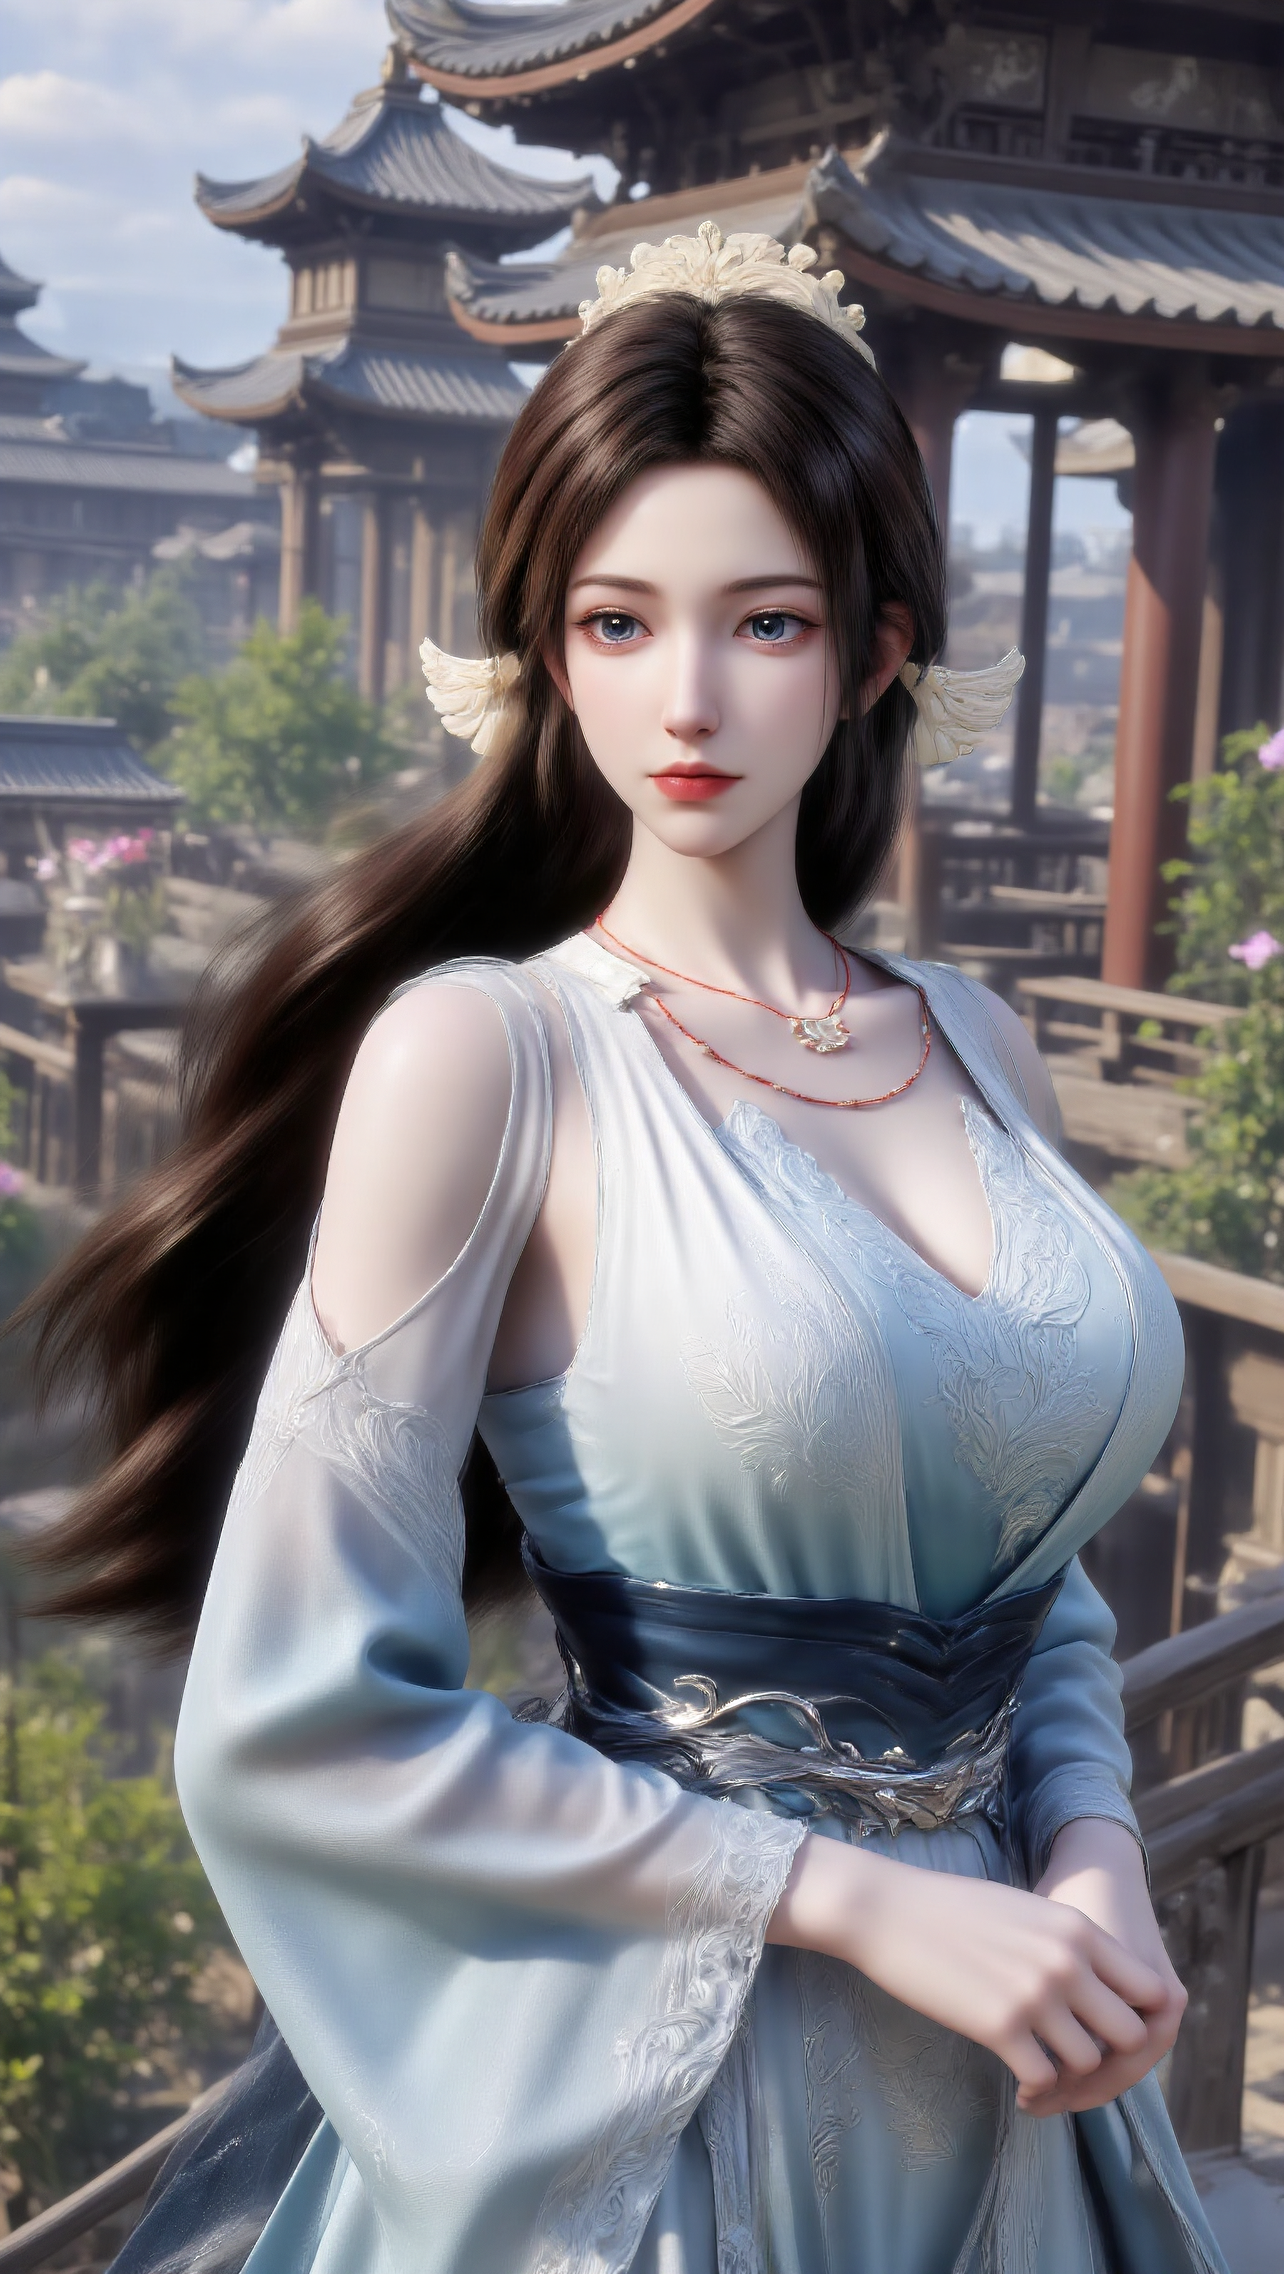
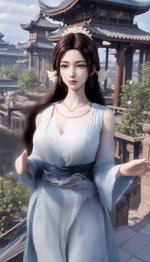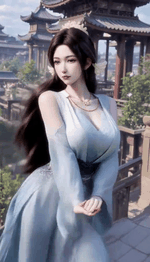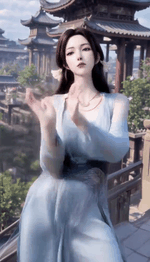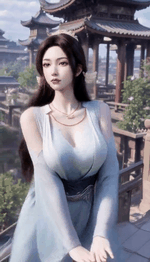
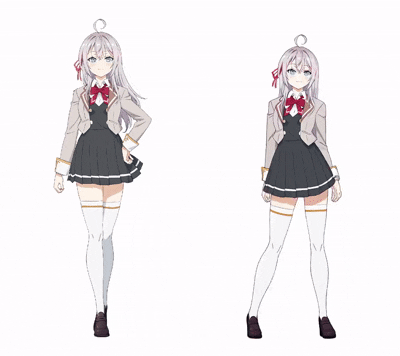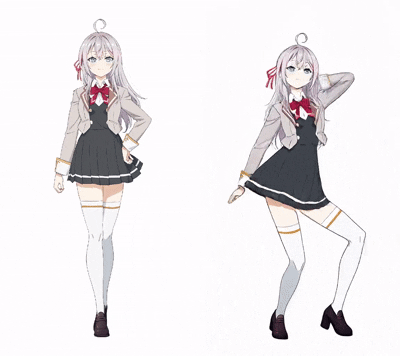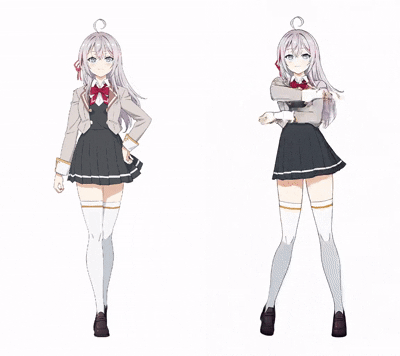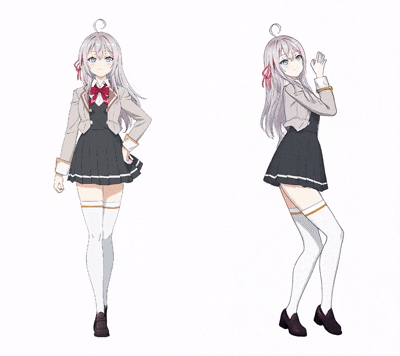
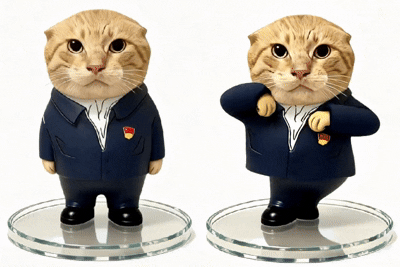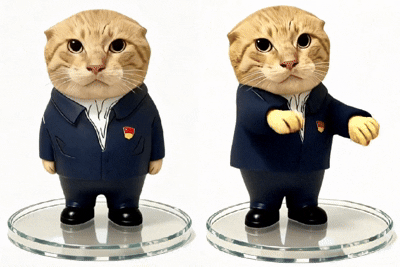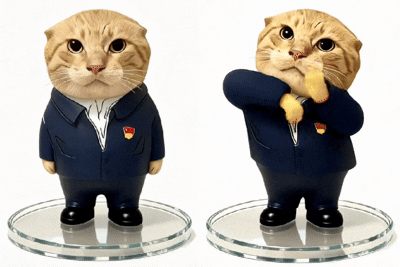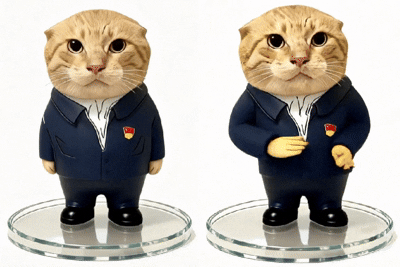
Our model can adapt a single reference image to various motion patterns, demonstrating flexible motion control capabilities.
14B Model
| Reference | Motion 1 | Motion 2 | Motion 3 |
|---|---|---|---|
 |  |  |  |
 |  |  |  |
1.3B Model
The 1.3 B model also delivers strong performance (from 1.3b_2 ckpt).
| Reference | Motion 1 | Motion 2 | Motion 3 |
|---|---|---|---|
 |  |  |  |
Also support longer video & out-of-domain cases
🔧 Dependencies and Installation
-
Clone Repo
git clone https://github.com/ssj9596/One-to-All-Animation.git cd One-to-All-Animation -
Create Conda Environment and Install Dependencies
# create new conda env conda create -n one-to-all python=3.12 conda activate one-to-all # install pytorch pip install torch==2.5.1 torchvision==0.20.1 torchaudio==2.5.1 --index-url https://download.pytorch.org/whl/cu124 # or pip install torch==2.5.1 torchvision==0.20.1 torchaudio==2.5.1 -i https://mirrors.aliyun.com/pypi/simple/ # install python dependencies pip install -r requirements.txt -i https://mirrors.aliyun.com/pypi/simple/ # (Recommended) install flash attention 3 (or 2) from source: # https://github.com/Dao-AILab/flash-attention -
Download Models
- Download pretrained models
cd ./pretrained_models python download_pretrained_models.py- Download checkpoints
cd ./checkpoints
python download_checkpoints.py
💡 Tip: Edit the script and uncomment the specific models you want to download.
- 1.3B_1: Best performance on video benchmark among 1.3B models (paper results).
- 1.3B_2: Further trained on v1 with large camera movement data and increased image ratio. Better for dynamic video generation. Best on image benchmark (paper results).
- 14B: Best overall performance among 14B models (paper results).
☕️ Quick Inference
We provide several examples in the examples folder.
Run the following commands to try it out:
# Step 1: Prepare model input
cd video-generation
python infer_preprocess.py

# Step 2: Run inference with your preferred model
python inference_1.3b.py  # For 1.3B model
# or
python inference_14b.py   # For 14B model
You can enter the script to modify the input path.
🎬 Training from scratch
💡 Data Collection Required: We find current open-source datasets are not sufficient for training from scratch. We strongly recommend collecting at least 3,000 additional high-quality video samples for better results.
We divide the training process into several steps to help you train from scratch (using 1.3B as an example).
-
Download Pretrained Models
Download the base model from HuggingFace: Wan-AI/Wan2.1-T2V-1.3B-Diffusers
-
Download Training Datasets and Pose Pool
cd datasets
bash setup_datasets.sh
This will download and prepare:
- Training datasets (open-source + cartoon):
datasets/opensource_dataset/ - Pose pool for face enhancement:
datasets/opensource_pose_pool/
Manual Download Links
- Training datasets (open-source + cartoon):
-
Training
We provide three-stage training scripts:
- Stage 1: Reference Extractor
cd video-generation bash training_scripts/train1.3b_only_refextractor_2d.sh # Convert checkpoint to FP32 cd outputs_wanx1.3b/train1.3b_only_refextractor_2d/checkpoint-xxx mkdir fp32_model_xxx python zero_to_fp32.py . fp32_model_xxx --safe_serialization # Run inference (update model path in inference_refextractor.py first) cd ../../../ # Edit inference_refextractor.py and change ckpt_path to: # ./outputs_wanx1.3b/train1.3b_only_refextractor_2d/checkpoint-xxx/fp32_model_xxx python inference_refextractor.py- Stage 2: Pose Control
bash training_scripts/train1.3b_posecontrol_prefix_2d.sh- Stage 3: Token Replace for Long video generation
bash training_scripts/train1.3b_posecontrol_prefix_2d_tokenreplace.sh💡 Training Notes:
- Each stage uses different training resolutions - check the scripts for specific resolution settings
- Fine-tuning from our checkpoints: If you want to continue training from our pre-trained models, directly use the Stage 3 script and modify the checkpoint path
📊 Reproduce Paper Results
We provide scripts to reproduce the quantitative results reported in our paper.
-
Download Benchmark
cd benchmark python download_benchmark.py -
Prepare Model Input
cd ../video-generation python reproduce/infer_preprocess.py -
Run Inference
We provide inference scripts for different model sizes and datasets:
# TikTok dataset python reproduce/inference_tiktok1.3b.py # 1.3B model python reproduce/inference_tiktok14b.py # 14B model # Cartoon dataset python reproduce/inference_cartoon1.3b.py # 1.3B model python reproduce/inference_cartoon14b.py # 14B model -
Prepare gt/pred pairs for Judge
cd ../benchmark # TikTok dataset python prepare_eval_frames_tiktok.py # Cartoon dataset python prepare_eval_frames_cartoon.py -
Run judge
# prepare DisCo environment and lpips fvd ckpt for judge
cd DisCo
# TikTok dataset
bash eval_tiktok.sh
python summary.py
Acknowledgments
Our project is based on opensora. Some codes are brought from StableAnimator and Wan-Animate. Thanks for their awesome works.
📝 Citation
If you find our work helpful or inspiring, please feel free to cite it.
@article{shi2025one,
  title={One-to-All Animation: Alignment-Free Character Animation and Image Pose Transfer},
  author={Shi, Shijun and Xu, Jing and Li, Zhihang and Peng, Chunli and Yang, Xiaoda and Lu, Lijing and Hu, Kai and Zhang, Jiangning},
  journal={arXiv preprint arXiv:2511.22940},
  year={2025}
}
📄 License
This repository is released under the Apache License 2.0.
📧 Contact
If you have any questions, please feel free to reach us at ssj180123@gmail.com
Contributors


Similar repos





Languages
Python
97.8%
Cuda
1.1%
[CVPR 2026 Poster] One-to-All Animation: Alignment-Free Character Animation and Image Pose Transfer
Python
500
15 commits
updated Apr 19, 2026
README
One-to-All Animation: Alignment-Free
Character Animation
and Image Pose Transfer
Shijun Shi1*, Jing Xu2*, Zhihang Li3, Chunli Peng4, Xiaoda Yang5, Lijing Lu3,
Kai Hu1†, Jiangning Zhang5†
1Jiangnan University
2University of Science and Technology of China
3Chinese Academy of Sciences
4Beijing University of Posts and Telecommunications
5Zhejiang University
*Equal contribution †Corresponding authors
🌟 Highlights
We provide a complete and reproducible training and evaluation pipeline:
- ✅ Full Training Code: Three-stage progressive training from scratch
- ✅ Complete Benchmarks: Reproduction code and pre-trained checkpoints
- ✅ Flexible Training Codebase: Multi-resolution, multi-aspect-ratio, and multi-frame training codebase
- ✅ Datasets: Pre-processed open-source datasets + self-collected cartoon data
🔥 Update
- [2026.02.24] 🎉🎉🎉 One-to-All Animation has been accepted by CVPR 2026!
- [2025.12.22] 🔥🔥🔥 GPU-poor? Run One-to-All1.3B + ComfyUI for free on Kaggle’s 16 GB T4. We’ve released a zero-setup guide that runs the One-to-All ComfyUI workflow on Kaggle’s 16 GB T4—completely free😊. It takes 11 minutes to generate a 10-second 832×480 video. Tutorial: https://ncn0ojsozocg.feishu.cn/wiki/J9Ohwmtudin0vtkuyPccIZkhnZz
- [2025.12] kijai's ComfyUI WanVideoWrapper now integrates One‑to‑All Animation 14B! Huge thanks to kijai for the amazing work!!! Note: Our model supports both retargeted pose and direct pose (with reference preprocessing) from the original video. In addition, using lighter colors for the facial skeleton and landmarks helps achieve better identity consistency.
- [2025.11] Paper reproduction and evaluation code released.
- [2025.11] Sample training data and Benchmark on HuggingFace released.
- [2025.11] Inference and Training codes are released.
- [2025.11] 1.3B-v1, 1.3B-v2 and 14B checkpoints are released.
🎭 Showcase
Our model can adapt a single reference image to various motion patterns, demonstrating flexible motion control capabilities.
14B Model
| Reference | Motion 1 | Motion 2 | Motion 3 |
|---|---|---|---|
| | | |
| | | |
1.3B Model
The 1.3 B model also delivers strong performance (from 1.3b_2 ckpt).
| Reference | Motion 1 | Motion 2 | Motion 3 |
|---|---|---|---|
| | | |
Also support longer video & out-of-domain cases
🔧 Dependencies and Installation
-
Clone Repo
git clone https://github.com/ssj9596/One-to-All-Animation.git cd One-to-All-Animation -
Create Conda Environment and Install Dependencies
# create new conda env conda create -n one-to-all python=3.12 conda activate one-to-all # install pytorch pip install torch==2.5.1 torchvision==0.20.1 torchaudio==2.5.1 --index-url https://download.pytorch.org/whl/cu124 # or pip install torch==2.5.1 torchvision==0.20.1 torchaudio==2.5.1 -i https://mirrors.aliyun.com/pypi/simple/ # install python dependencies pip install -r requirements.txt -i https://mirrors.aliyun.com/pypi/simple/ # (Recommended) install flash attention 3 (or 2) from source: # https://github.com/Dao-AILab/flash-attention -
Download Models
- Download pretrained models
cd ./pretrained_models python download_pretrained_models.py- Download checkpoints
cd ./checkpoints
python download_checkpoints.py
💡 Tip: Edit the script and uncomment the specific models you want to download.
- 1.3B_1: Best performance on video benchmark among 1.3B models (paper results).
- 1.3B_2: Further trained on v1 with large camera movement data and increased image ratio. Better for dynamic video generation. Best on image benchmark (paper results).
- 14B: Best overall performance among 14B models (paper results).
☕️ Quick Inference
We provide several examples in the examples folder.
Run the following commands to try it out:
# Step 1: Prepare model input
cd video-generation
python infer_preprocess.py

# Step 2: Run inference with your preferred model
python inference_1.3b.py  # For 1.3B model
# or
python inference_14b.py   # For 14B model
You can enter the script to modify the input path.
🎬 Training from scratch
💡 Data Collection Required: We find current open-source datasets are not sufficient for training from scratch. We strongly recommend collecting at least 3,000 additional high-quality video samples for better results.
We divide the training process into several steps to help you train from scratch (using 1.3B as an example).
-
Download Pretrained Models
Download the base model from HuggingFace: Wan-AI/Wan2.1-T2V-1.3B-Diffusers
-
Download Training Datasets and Pose Pool
cd datasets
bash setup_datasets.sh
This will download and prepare:
- Training datasets (open-source + cartoon):
datasets/opensource_dataset/ - Pose pool for face enhancement:
datasets/opensource_pose_pool/
Manual Download Links
- Training datasets (open-source + cartoon):
-
Training
We provide three-stage training scripts:
- Stage 1: Reference Extractor
cd video-generation bash training_scripts/train1.3b_only_refextractor_2d.sh # Convert checkpoint to FP32 cd outputs_wanx1.3b/train1.3b_only_refextractor_2d/checkpoint-xxx mkdir fp32_model_xxx python zero_to_fp32.py . fp32_model_xxx --safe_serialization # Run inference (update model path in inference_refextractor.py first) cd ../../../ # Edit inference_refextractor.py and change ckpt_path to: # ./outputs_wanx1.3b/train1.3b_only_refextractor_2d/checkpoint-xxx/fp32_model_xxx python inference_refextractor.py- Stage 2: Pose Control
bash training_scripts/train1.3b_posecontrol_prefix_2d.sh- Stage 3: Token Replace for Long video generation
bash training_scripts/train1.3b_posecontrol_prefix_2d_tokenreplace.sh💡 Training Notes:
- Each stage uses different training resolutions - check the scripts for specific resolution settings
- Fine-tuning from our checkpoints: If you want to continue training from our pre-trained models, directly use the Stage 3 script and modify the checkpoint path
📊 Reproduce Paper Results
We provide scripts to reproduce the quantitative results reported in our paper.
-
Download Benchmark
cd benchmark python download_benchmark.py -
Prepare Model Input
cd ../video-generation python reproduce/infer_preprocess.py -
Run Inference
We provide inference scripts for different model sizes and datasets:
# TikTok dataset python reproduce/inference_tiktok1.3b.py # 1.3B model python reproduce/inference_tiktok14b.py # 14B model # Cartoon dataset python reproduce/inference_cartoon1.3b.py # 1.3B model python reproduce/inference_cartoon14b.py # 14B model -
Prepare gt/pred pairs for Judge
cd ../benchmark # TikTok dataset python prepare_eval_frames_tiktok.py # Cartoon dataset python prepare_eval_frames_cartoon.py -
Run judge
# prepare DisCo environment and lpips fvd ckpt for judge
cd DisCo
# TikTok dataset
bash eval_tiktok.sh
python summary.py
Acknowledgments
Our project is based on opensora. Some codes are brought from StableAnimator and Wan-Animate. Thanks for their awesome works.
📝 Citation
If you find our work helpful or inspiring, please feel free to cite it.
@article{shi2025one,
  title={One-to-All Animation: Alignment-Free Character Animation and Image Pose Transfer},
  author={Shi, Shijun and Xu, Jing and Li, Zhihang and Peng, Chunli and Yang, Xiaoda and Lu, Lijing and Hu, Kai and Zhang, Jiangning},
  journal={arXiv preprint arXiv:2511.22940},
  year={2025}
}
📄 License
This repository is released under the Apache License 2.0.
📧 Contact
If you have any questions, please feel free to reach us at ssj180123@gmail.com
Similar repos
Contributors
Languages
Python
97.8%
Cuda
1.1%